📦 Hugging Face Transformers
英文标题:📦 huggingface/transformers
🤗 Transformers 是一个模型定义框架,支持文本、视觉、音频及多模态领域的先进机器学习模型,覆盖推理与训练。该库集中管理模型定义,与 Axolotl、vLLM、DeepSpeed 等主流训练与推理框架兼容。Hugging Face Hub 上目前已拥有超过 100 万个模型检查点,开发者可通过简洁的 Pipeline API 快速上手。Transformers 降低了前沿模型的使用门槛,促进了整个生态系统的协作,已成为社区广泛采用的核心库。
 22.4 KB
 22.3 KB
 1.3 KB
 1.3 KB
 1.3 KB
 1.3 KB
 1.3 KB
 1.4 KB
 703.2 KB
 202.7 KB
 61.8 KB
 169.2 KB
 1.4 KB
 8.0 KB
 6.9 KB
 1.5 KB
 1.5 KB
 6.8 KB
 2.8 KB
中文
用于推理和训练的最先进的预训练模型
Transformers 作为一个模型定义框架,用于文本、计算机视觉、音频、视频和多模态模型的最先进机器学习,同时支持推理和训练。
它集中了模型定义,使得这一定义在整个生态系统中达成一致。transformers 是跨框架的枢纽:如果某个模型定义受到支持,它将与大多数训练框架(Axolotl、Unsloth、DeepSpeed、FSDP、PyTorch-Lightning 等)、推理引擎(vLLM、SGLang、TGI 等)以及依赖 transformers 模型定义的邻近建模库(llama.cpp、mlx 等)兼容。
我们承诺帮助支持新的最先进模型,并通过让它们的模型定义简单、可定制和高效来普及其使用。
在 Hugging Face Hub 上拥有超过 100 万个 Transformers 模型检查点,供您使用。
立即探索 Hub,查找模型并使用 Transformers 快速上手。
Transformers 支持 Python 3.10+ 和 PyTorch 2.4+。
使用 venv 或快速的 Rust 版 Python 包和项目管理器 uv 创建并激活虚拟环境。
venv
python -m venv .my-env source .my-env/bin/activate
uv
uv venv .my-env source .my-env/bin/activate
在虚拟环境中安装 Transformers。
pip
pip install "transformers[torch]"
uv
uv pip install "transformers[torch]"
如果您想要库的最新改动或有兴趣参与贡献,可以从源代码安装 Transformers。但请注意,最新 版本可能不稳定。如果遇到错误,欢迎提交 issue。
git clone https://github.com/huggingface/transformers.git cd transformers
pip
pip install '.[torch]'
uv
uv pip install '.[torch]'
立即使用 Pipeline API 快速入门 Transformers。Pipeline 是一个高级推理类,支持文本、音频、视觉和多模态任务。它会处理输入预处理并返回合适的输出。
实例化一个 pipeline 并指定用于文本生成的模型。模型会被下载并缓存,方便您轻松重用。最后,传递一些文本作为提示。
from transformers import pipeline
pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B") pipeline("the secret to baking a really good cake is ") [{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
与模型聊天时,使用模式相同。唯一的区别是您需要构建一段聊天历史记录(作为 Pipeline 的输入),包含您和系统的对话。
提示
您也可以直接从命令行与模型聊天,前提是 transformers serve 正在运行。
transformers chat Qwen/Qwen2.5-0.5B-Instruct
import torch from transformers import pipeline
chat = [ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."}, {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"} ]
pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto") response = pipeline(chat, max_new_tokens=512) print(response[0]["generated_text"][-1]["content"])
请展开以下示例,了解 Pipeline 如何处理不同模态和任务。
自动语音识别
from transformers import pipeline
pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3") pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac") {'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
图像分类
from transformers import pipeline
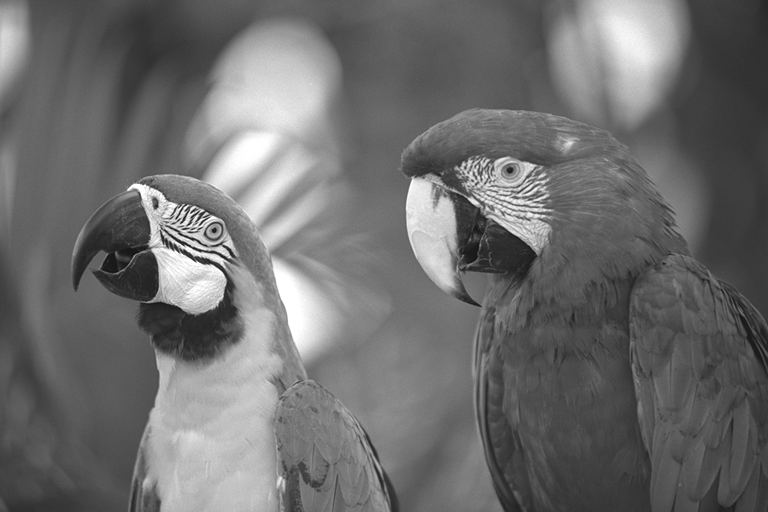
pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer") pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png") [{'label': 'macaw', 'score': 0.997848391532898}, {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita', 'score': 0.0016551691805943847}, {'label': 'lorikeet', 'score': 0.00018523589824326336}, {'label': 'African grey, African gray, Psittacus erithacus', 'score': 7.85409429227002e-05}, {'label': 'quail', 'score': 5.502637941390276e-05}]
视觉问答
from transformers import pipeline
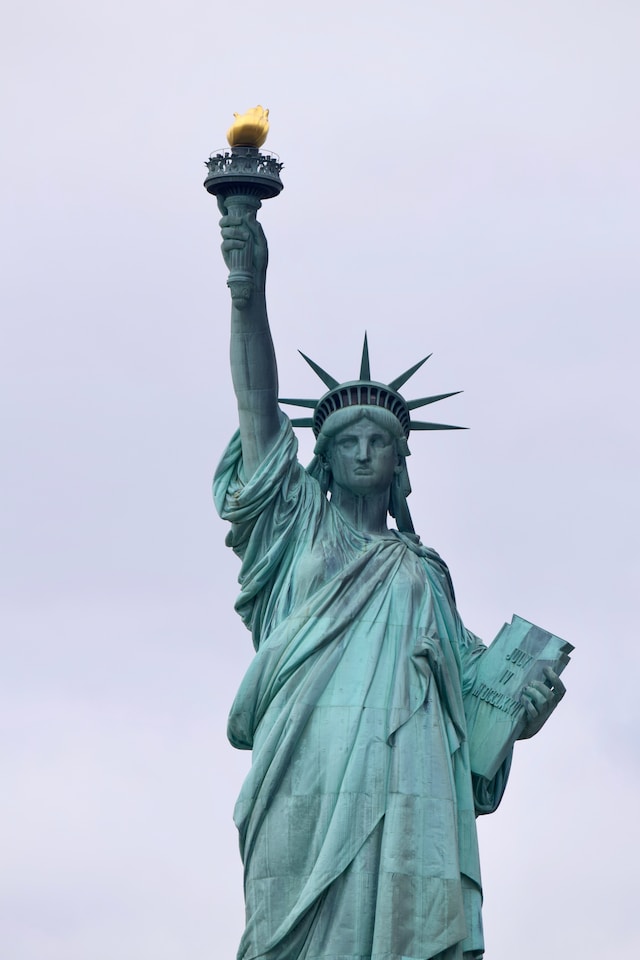
pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base") pipeline( image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg", question="What is in the image?", ) [{'answer': 'statue of liberty'}]
为什么应该使用 Transformers?
- 易于使用的最先进模型:
- 在自然语言理解与生成、计算机视觉、音频、视频和多模态任务上表现优异。
- 为研究人员、工程师和开发者降低了入门门槛。
- 极少的用户抽象,只需学习三个类。
- 统一的 API 用于所有预训练模型。
- 更低的计算成本,更小的碳足迹:
- 共享训练好的模型,而非从头训练。
- 减少计算时间和生产成本。
- 数百种模型架构,超过 100 万个预训练检查点,覆盖所有模态。
- 为模型生命周期的每个环节选择合适的框架:
- 三行代码训练先进模型。
- 在 PyTorch/JAX/TF2.0 框架之间自由移动单一模型。
- 为训练、评估和生产选择最合适的框架。
- 轻松定制模型或示例以满足需求:
- 我们为每种架构提供示例,以复现原作者发表的结果。
- 模型内部结构尽可能一致地暴露出来。
- 模型文件可独立于库用于快速实验。

什么时候不应该使用 Transformers?
- 本库不是一个模块化的神经网络构建块工具箱。模型文件中的代码有意识地不进行额外的抽象重构,以便研究人员能够快速迭代每个模型,而无需深入额外的抽象或文件。
- 训练 API 优化用于 Transformers 提供的 PyTorch 模型。对于通用的机器学习循环,您应该使用其他库,例如 Accelerate。
- 示例脚本 仅仅是示例。它们可能不一定在您的特定用例下开箱即用,您需要调整代码才能使其工作。
100 个使用 Transformers 的项目
Transformers 不仅仅是一个使用预训练模型的工具包,更是一个围绕它和 Hugging Face Hub 构建的社区项目集合。我们希望 Transformers 能够赋能开发者、研究人员、学生、教授、工程师以及任何想构建梦想项目的人。
为了庆祝 Transformers 获得 100,000 颗星,我们希望通过 awesome-transformers 页面将聚光灯投向社区,该页面列出了 100 个使用 Transformers 构建的精彩项目。
如果您拥有或使用了一个您认为应该列入列表的项目,请提交 PR 以添加它!
您可以直接在其 Hub 模型页面 上测试我们的大多数模型。
展开下面的每个模态,查看各种用例的示例模型。
音频 计算机视觉 多模态 自然语言处理
- 使用 ModernBERT 进行掩码词补全
- 使用 Gemma 进行命名实体识别
- 使用 Mixtral 进行问答
- 使用 BART 进行摘要
- 使用 T5 进行翻译
- 使用 Llama 进行文本生成
- 使用 Qwen 进行文本分类
我们现已有一篇可供引用 🤗 Transformers 库的论文:
@inproceedings{wolf-etal-2020-transformers, title = "Transformers: State-of-the-Art Natural Language Processing", author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush", booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations", month = oct, year = "2020", address = "Online", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2020.emnlp-demos.6/", pages = "38--45" }
English / 原文
State-of-the-art pretrained models for inference and training
Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...), and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.
There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.
Explore the Hub today to find a model and use Transformers to help you get started right away.
Transformers works with Python 3.10+, and PyTorch 2.4+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate
Install Transformers in your virtual environment.
# pip
pip install "transformers[torch]"

# uv
uv pip install "transformers[torch]"
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
git clone https://github.com/huggingface/transformers.git
cd transformers

# pip
pip install '.[torch]'

# uv
uv pip install '.[torch]'
Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
Tip
You can also chat with a model directly from the command line, as long as transformers serve is running.
transformers chat Qwen/Qwen2.5-0.5B-Instruct


import torch
from transformers import pipeline

chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]

pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
Expand the examples below to see how Pipeline works for different modalities and tasks.
Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
Image classification
from transformers import pipeline

pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
Visual question answering
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]
Why should I use Transformers?
-
Easy-to-use state-of-the-art models:
- High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
- Low barrier to entry for researchers, engineers, and developers.
- Few user-facing abstractions with just three classes to learn.
- A unified API for using all our pretrained models.
-
Lower compute costs, smaller carbon footprint:
- Share trained models instead of training from scratch.
- Reduce compute time and production costs.
- Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
-
Choose the right framework for every part of a model's lifetime:
- Train state-of-the-art models in 3 lines of code.
- Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
- Pick the right framework for training, evaluation, and production.
-
Easily customize a model or an example to your needs:
- We provide examples for each architecture to reproduce the results published by its original authors.
- Model internals are exposed as consistently as possible.
- Model files can be used independently of the library for quick experiments.
When shouldn't I use Transformers?
- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.
- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like Accelerate.
- The example scripts are only examples. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.
100 projects using Transformers
Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone else to build their dream projects.
In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the community with the awesome-transformers page which lists 100 incredible projects built with Transformers.
If you own or use a project that you believe should be part of the list, please open a PR to add it!
You can test most of our models directly on their Hub model pages.
Expand each modality below to see a few example models for various use cases.
Audio Computer vision Multimodal NLP
- Masked word completion with ModernBERT
- Named entity recognition with Gemma
- Question answering with Mixtral
- Summarization with BART
- Translation with T5
- Text generation with Llama
- Text classification with Qwen
We now have a paper you can cite for the 🤗 Transformers library:
@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2020.emnlp-demos.6/",
    pages = "38--45"
}