📦 Graphify:将任意文件夹转化为可查询的知识图谱
英文标题:📦 Graphify-Labs/graphify
Graphify 是一个 AI 编码助手技能,支持 Claude Code、Codex、Cursor 等 20 余种工具。它能将代码、SQL 模式、文档、图片甚至视频整合为确定性知识图谱,提供 god nodes、社区检测、跨文件链接等功能,且构建过程零 token 成本。用户通过 `/graphify` 命令即可查询、追踪路径或解释概念,无需反复读取文件,对开发者理解和维护复杂项目有重要意义。
 143.4 KB
 5.1 KB
 1.7 KB
 3.1 KB
 2.9 KB
 2.2 KB
 1.2 KB
 1.3 KB
 2.5 KB
 1.3 KB
 1.7 KB
 633.7 KB
 62.6 KB
 80.4 KB
中文

在 AI 编码助手中输入 /graphify,它会将整个项目(代码、文档、PDF、图片、视频)映射为一个知识图谱,让你可以查询而非 grep 文件。
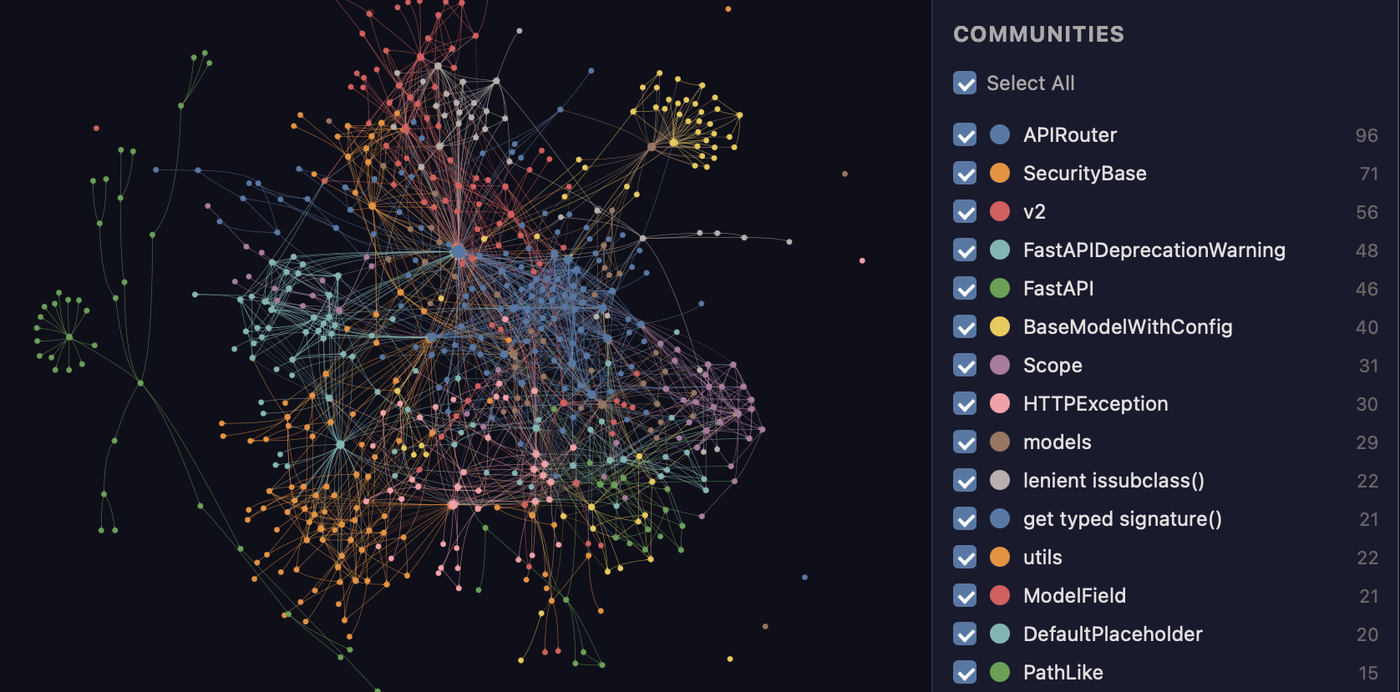
FastAPI 代码库由 graphify 映射。每个节点代表一个概念,颜色代表检测到的社区,整个图在 graph.html 中可点击交互。
适用工具: Claude Code、Codex、OpenCode、Kilo Code、Cursor、Gemini CLI、GitHub Copilot CLI、VS Code Copilot Chat、Aider、Amp、OpenClaw、Factory Droid、Trae、Hermes、Kimi Code、Kiro、Pi、Devin CLI 和 Google Antigravity。
仅此而已。你将得到三个文件:
graphify-out/ ├── graph.html 在任意浏览器中打开——点击节点、过滤、搜索 ├── GRAPH_REPORT.md 亮点汇总:关键概念、令人意外的关联、建议的问题 └── graph.json 完整图谱——随时查询,无需重新读取文件
知识图谱不是向量索引:它是确定性的,每条边都有解释,并且构建零 Token 成本。
| 能力 | 说明 |
|---|---|
| God 节点 | 连接最多的概念,让你看清信息的汇聚点 |
| 社区 | 图谱通过 Leiden 算法划分为子系统,标签无需 LLM |
| 跨文件链接 | 通过 tree-sitter AST 解析约 40 种语言中的 calls / imports / inherits / mixes_in 关系 |
| 查询、路径、解释 | 针对 graph.json 提问、追踪两点之间的路径或解释某个概念 |
| 理据与文档引用 | # NOTE: / # WHY: 注释和 ADR/RFC 引用成为与代码相连的一级节点 |
| 超越代码 | 文档、PDF、图片及视频/音频全部映射到同一图谱中 |
| 本地优先 | AST 加本地嵌入器构建图谱,无需消耗任何 LLM 额度;你的代码不会离开你的机器 |
图谱构建完成后,你查询它而非阅读文件。基于 FastAPI 代码库的真实输出如下:
$ graphify explain "APIRouter" Node: APIRouter Source: routing.py L2210 Community: 2 Degree: 47
Connections (47): --> RequestValidationError [uses] [INFERRED] --> Dependant [uses] [INFERRED] --> .get() [method] [EXTRACTED] <-- init.py [imports] [EXTRACTED] ...
$ graphify path "FastAPI" "ModelField" Shortest path (3 hops): FastAPI --uses--> DefaultPlaceholder <--references-- get_request_handler() --references--> ModelField
每条边都带有置信度标签(EXTRACTED = 源代码中显式出现,INFERRED = 通过解析推导得出),因此你可以区分哪些是直接读取的,哪些是推断的。graphify query "<问题>" 会针对自然语言问题返回一个范围的子图,graphify path A B 则追溯两个事物如何关联。
| 基准测试 | 指标 | graphify | 领域 |
|---|---|---|---|
| LOCOMO (n=300) | recall@10 | 0.497 | mem0 0.048, supermemory 0.149 |
| LOCOMO (n=300) | QA 准确率 | 45.3% | supermemory 49.7%, mem0 27.3% |
| LongMemEval-S (n=50) | QA 准确率 | 76% | 与稠密 RAG 持平 |
| 图谱构建 | LLM 额度 | 0 | 多数系统按 token 计费 |
所有系统在同一测试框架、相同模型和预算下运行,由一名裁判盲评并与第二名裁判交叉验证(一致性 90.6%,Cohen's kappa 0.81)。完整的系统对照表、代码智能结果和复现命令详见:BENCHMARKS.md。
| 要求 | 最低版本 | 检查命令 | 安装方式 |
|---|---|---|---|
| Python | 3.10+ | python --version |
python.org |
| uv (推荐) | 任意 | uv --version |
`curl -LsSf https://astral.sh/uv/install.sh |
| pipx (备选) | 任意 | pipx --version |
pip install pipx |
macOS 快速安装(Homebrew):
brew install python@3.12 uv
Windows 快速安装:
winget install astral-sh.uv
Ubuntu/Debian:
sudo apt install python3.12 python3-pip pipx
或安装 uv:
curl -LsSf https://astral.sh/uv/install.sh | sh
官方包: PyPI 上的包名为
graphifyy(双 y)。PyPI 上其他graphify*包均非官方出品。CLI 命令仍为graphify。
步骤 1——安装包:
推荐(隔离环境;如果安装后找不到 graphify,请执行:uv tool update-shell):
uv tool install graphifyy
备选方案:
pipx install graphifyy pip install graphifyy # 可能需要配置 PATH——见下方说明
步骤 2——将技能注册到 AI 助手:
就这么简单。打开你的 AI 助手,输入 /graphify .
若要将助手技能安装到当前仓库而非用户配置中,请添加 --project:
graphify install --project graphify install --project --platform codex
项目作用域的安装会将文件写入当前目录下,例如 .claude/skills/graphify/SKILL.md 或 .agents/skills/graphify/SKILL.md(外加一个 references/ 辅助目录,该技能会按需加载),并打印一条 git add 提示,告知哪些文件可以提交。支持项目级安装的各平台命令接受相同标志,例如 graphify claude install --project 或 graphify codex install --project。
PowerShell 注意: 使用
graphify .而非/graphify .——在 PowerShell 中,前导斜杠是路径分隔符。
graphify:命令未找到? 通过uv tool install/pipx install安装后,graphify命令位于它们各自的工具 bin 目录(~/.local/bin)中。如果你的 shell 在安装后立即找不到它——这在全新 macOS + zsh 环境中很常见——说明该目录尚未添加到PATH:运行uv tool update-shell(或pipx ensurepath),然后打开新终端。若使用普通pip,请将~/.local/bin(Linux)或~/Library/Python/3.x/bin(Mac)添加到 PATH,或运行python -m graphify。
使用
uvx/uv tool run而非安装? 请指定包名而非命令:uvx --from graphifyy graphify install。直接运行uvx graphify …会失败(No solution found … no versions of graphify),因为uv tool run将第一个单词视为_包名_,而包名是graphifyy——graphify命令只是包含其中。
尽可能避免在 Mac/Windows 上使用
pip install。 该技能在运行时通过graphify-out/.graphify_python解析 Python;如果该路径指向的环境与pip安装包的环境不同,将出现ModuleNotFoundError: No module named 'graphify'。uv tool install和pipx install会将包隔离在自己的环境中,完全避免此问题。
Git 钩子与 uv tool / pipx:
graphify hook install在安装时将当前解释器路径直接嵌入钩子脚本,因此即使在 GUI Git 客户端和 CI 运行器中(其~/.local/bin不在 PATH 中),post-commit 钩子也能正确触发。如果你重新安装或升级 graphify,请重新运行graphify hook install以更新嵌入路径。
选择你的平台(20+ 种助手,点击展开)
| 平台 | 安装命令 |
|---|---|
| Claude Code (Linux/Mac) | graphify install |
| Claude Code (Windows) | graphify install(自动检测)或 graphify install --platform windows |
| CodeBuddy | graphify install --platform codebuddy |
| Codex | graphify install --platform codex |
| OpenCode | graphify install --platform opencode |
| Kilo Code | graphify install --platform kilo |
| GitHub Copilot CLI | graphify install --platform copilot |
| VS Code Copilot Chat | graphify vscode install |
| Aider | graphify install --platform aider |
| OpenClaw | graphify install --platform claw |
| Factory Droid | graphify install --platform droid |
| Trae | graphify install --platform trae |
| Trae CN | graphify install --platform trae-cn |
| Gemini CLI | graphify install --platform gemini |
| Hermes | graphify install --platform hermes |
| Kimi Code | graphify install --platform kimi |
| Amp | graphify amp install |
| Agent Skills (跨框架) | graphify install --platform agents(别名 --platform skills) |
| Kiro IDE/CLI | graphify kiro install |
| Pi 编码代理 | graphify install --platform pi |
| Cursor | graphify cursor install |
| Devin CLI | graphify devin install |
| Google Antigravity | graphify antigravity install |
Codex 用户还需要在 ~/.codex/config.toml 的 [features] 下设置 multi_agent = true 以支持并行提取。CodeBuddy 使用与 Claude Code 相同的 Agent 工具和 PreToolUse 钩子机制。Factory Droid 使用 Task 工具进行并行子代理调度。OpenClaw 和 Aider 使用顺序提取(这些平台上的并行代理支持尚在早期阶段)。Trae 使用 Agent 工具进行并行子代理调度,不支持 PreToolUse 钩子,因此 AGENTS.md 为始终启用的机制。
--platform agents(别名 --platform skills)适用于通用的跨框架 Agent-Skills 位置:全局安装写入 spec 的用户全局路径 ~/.agents/skills/(由 npx skills 及兼容 spec 的框架读取),项目内安装(--project)则写入 ./.agents/skills/。裸命令 graphify install 默认为单一平台(Claude Code)——当你希望技能可被任何读取 .agents/skills 的框架发现时,请使用显式的 agents 平台。
Codex 使用
$graphify而非/graphify。
可选附加组件(按需安装)
| 附加组件 | 功能说明 | 安装命令 |
|---|---|---|
pdf |
PDF 提取 | uv tool install "graphifyy[pdf]" |
office |
.docx 和 .xlsx 支持 |
uv tool install "graphifyy[office]" |
google |
Google Sheets 渲染 | uv tool install "graphifyy[google]" |
video |
视频/音频转录(faster-whisper + yt-dlp) | uv tool install "graphifyy[video]" |
mcp |
MCP 标准输入输出服务器 | uv tool install "graphifyy[mcp]" |
neo4j |
Neo4j 推送支持 | uv tool install "graphifyy[neo4j]" |
falkordb |
FalkorDB 推送支持 | uv tool install "graphifyy[falkordb]" |
svg |
SVG 图谱导出 | uv tool install "graphifyy[svg]" |
leiden |
Leiden 社区检测(仅限 Python < 3.13) | uv tool install "graphifyy[leiden]" |
ollama |
Ollama 本地推理 | uv tool install "graphifyy[ollama]" |
openai |
OpenAI / OpenAI 兼容 API | uv tool install "graphifyy[openai]" |
gemini |
Google Gemini API | uv tool install "graphifyy[gemini]" |
anthropic |
Anthropic Claude API(--backend claude,使用 ANTHROPIC_API_KEY) |
uv tool install "graphifyy[anthropic]" |
bedrock |
AWS Bedrock(使用 IAM,无需 API 密钥) | uv tool install "graphifyy[bedroc |
English / 原文
Type /graphify in your AI coding assistant and it maps your entire project (code, docs, PDFs, images, videos) into a knowledge graph you can query instead of grepping through files.
The FastAPI codebase mapped by graphify. Every node is a concept, colors are detected communities, and the whole thing is clickable in graph.html.
Works in: Claude Code, Codex, OpenCode, Kilo Code, Cursor, Gemini CLI, GitHub Copilot CLI, VS Code Copilot Chat, Aider, Amp, OpenClaw, Factory Droid, Trae, Hermes, Kimi Code, Kiro, Pi, Devin CLI, and Google Antigravity.
That's it. You get three files :
graphify-out/
├── graph.html       open in any browser — click nodes, filter, search
├── GRAPH_REPORT.md  the highlights: key concepts, surprising connections, suggested questions
└── graph.json       the full graph — query it anytime without re-reading your files
A knowledge graph is not a vector index: it is deterministic , every edge is explained , and it costs zero tokens to build.
| Capability | What you get |
|---|---|
| God nodes | The most-connected concepts, so you see what everything flows through |
| Communities | The graph split into subsystems (Leiden), with LLM-free labels |
| Cross-file links | calls / imports / inherits / mixes_in resolved across ~40 languages via tree-sitter AST |
| Query, path, explain | Ask a question, trace the path between two things, or explain one concept, all against graph.json |
| Rationale + doc refs | # NOTE: / # WHY: comments and ADR/RFC citations become first-class nodes linked to the code |
| Beyond code | Docs, PDFs, images, and video/audio all map into the same graph |
| Local-first | AST plus a local embedder build the graph with zero LLM credits; your code never leaves your machine |
Once the graph is built you query it instead of reading files. Real output, graphify run on the FastAPI codebase shown above:
$ graphify explain "APIRouter"
Node: APIRouter
  Source:    routing.py L2210
  Community: 2
  Degree:    47

Connections (47):
  --> RequestValidationError [uses] [INFERRED]
  --> Dependant [uses] [INFERRED]
  --> .get() [method] [EXTRACTED]
  <-- __init__.py [imports] [EXTRACTED]
  ...

$ graphify path "FastAPI" "ModelField"
Shortest path (3 hops):
  FastAPI --uses--> DefaultPlaceholder <--references-- get_request_handler() --references--> ModelField
Every edge carries a confidence tag (EXTRACTED = explicit in the source, INFERRED = derived by resolution), so you can tell what was read directly from what was inferred. graphify query "<question>" returns a scoped subgraph for a plain-language question, and graphify path A B traces how any two things connect.
| Benchmark | Metric | graphify | Field |
|---|---|---|---|
| LOCOMO (n=300) | recall@10 | 0.497 | mem0 0.048, supermemory 0.149 |
| LOCOMO (n=300) | QA accuracy | 45.3% | supermemory 49.7%, mem0 27.3% |
| LongMemEval-S (n=50) | QA accuracy | 76% | tied with dense RAG |
| Graph build | LLM credits | 0 | per-token for most systems |
Every system ran on the same harness with the same model and budgets, scored by a judge blind-validated against a second judge (90.6% agreement, Cohen's kappa 0.81). Full per-system tables, the code-intelligence result, and reproduction commands: BENCHMARKS.md.
| Requirement | Minimum | Check | Install |
|---|---|---|---|
| Python | 3.10+ | python --version |
python.org |
| uv (recommended) | any | uv --version |
`curl -LsSf https://astral.sh/uv/install.sh |
| pipx (alternative) | any | pipx --version |
pip install pipx |
macOS quick install (Homebrew):
brew install python@3.12 uv
Windows quick install:
winget install astral-sh.uv
Ubuntu/Debian:
sudo apt install python3.12 python3-pip pipx
# or install uv:
curl -LsSf https://astral.sh/uv/install.sh | sh
Official package: The PyPI package is
graphifyy(double-y). Othergraphify*packages on PyPI are not affiliated. The CLI command is stillgraphify.
Step 1 — install the package:
# Recommended (isolated env; if 'graphify' isn't found after, run: uv tool update-shell):
uv tool install graphifyy

# Alternatives:
pipx install graphifyy
pip install graphifyy  # may need PATH setup — see note below
Step 2 — register the skill with your AI assistant:
That's it. Open your AI assistant and type /graphify .
To install the assistant skill into the current repository instead of your user profile, add --project:
graphify install --project
graphify install --project --platform codex
Project-scoped installs write under the current directory, for example .claude/skills/graphify/SKILL.md or .agents/skills/graphify/SKILL.md (plus a references/ sidecar the skill loads on demand), and print a git add hint for files that can be committed. Per-platform commands that support project-scoped installs accept the same flag, for example graphify claude install --project or graphify codex install --project.
PowerShell note: Use
graphify .not/graphify .— the leading slash is a path separator in PowerShell.
graphify: command not found?uv tool install/pipx installput thegraphifycommand in their tool bin dir (~/.local/bin). If your shell can't find it right after install — common on a fresh macOS + zsh setup — that dir isn't on yourPATHyet: runuv tool update-shell(orpipx ensurepath), then open a new terminal. With plainpip, add~/.local/bin(Linux) or~/Library/Python/3.x/bin(Mac) to your PATH, or runpython -m graphify.
Running with
uvx/uv tool runinstead of installing? Name the package, not the command:uvx --from graphifyy graphify install. Plainuvx graphify …fails (No solution found … no versions of graphify) becauseuv tool runreads the first word as a package , and the package isgraphifyy— thegraphifycommand lives inside it.
Avoid
pip installon Mac/Windows if possible. The skill resolves Python at runtime fromgraphify-out/.graphify_python; if that points to a different environment than wherepipinstalled the package, you'll getModuleNotFoundError: No module named 'graphify'.uv tool installandpipx installisolate the package in their own env and avoid this entirely.
Git hooks and uv tool / pipx:
graphify hook installembeds the current interpreter path directly into the hook scripts at install time, so the post-commit hook fires correctly even in GUI git clients and CI runners where~/.local/binis not on PATH. If you reinstall or upgrade graphify, re-rungraphify hook installto refresh the embedded path.
| Pick your platform (20+ assistants, click to expand) Platform | Install command |
|---|---|
| Claude Code (Linux/Mac) | graphify install |
| Claude Code (Windows) | graphify install (auto-detected) or graphify install --platform windows |
| CodeBuddy | graphify install --platform codebuddy |
| Codex | graphify install --platform codex |
| OpenCode | graphify install --platform opencode |
| Kilo Code | graphify install --platform kilo |
| GitHub Copilot CLI | graphify install --platform copilot |
| VS Code Copilot Chat | graphify vscode install |
| Aider | graphify install --platform aider |
| OpenClaw | graphify install --platform claw |
| Factory Droid | graphify install --platform droid |
| Trae | graphify install --platform trae |
| Trae CN | graphify install --platform trae-cn |
| Gemini CLI | graphify install --platform gemini |
| Hermes | graphify install --platform hermes |
| Kimi Code | graphify install --platform kimi |
| Amp | graphify amp install |
| Agent Skills (cross-framework) | graphify install --platform agents (alias --platform skills) |
| Kiro IDE/CLI | graphify kiro install |
| Pi coding agent | graphify install --platform pi |
| Cursor | graphify cursor install |
| Devin CLI | graphify devin install |
| Google Antigravity | graphify antigravity install |
Codex users also need multi_agent = true under [features] in ~/.codex/config.toml for parallel extraction. CodeBuddy uses the same Agent tool and PreToolUse hook mechanism as Claude Code. Factory Droid uses the Task tool for parallel subagent dispatch. OpenClaw and Aider use sequential extraction (parallel agent support is still early on those platforms). Trae uses the Agent tool for parallel subagent dispatch and does not support PreToolUse hooks, so AGENTS.md is the always-on mechanism.
--platform agents (alias --platform skills) targets the generic cross-framework Agent-Skills locations: the spec's user-global ~/.agents/skills/ (read by npx skills and spec-compliant frameworks) for a global install, and ./.agents/skills/ for a project (--project) install. The bare graphify install stays single-platform (Claude Code) by design — use the named agents platform when you want the skill discoverable by any framework that reads .agents/skills.
Codex uses
$graphifyinstead of/graphify.
| Optional extras (install only what you need) Extra | What it adds | Install |
|---|---|---|
pdf |
PDF extraction | uv tool install "graphifyy[pdf]" |
office |
.docx and .xlsx support |
uv tool install "graphifyy[office]" |
google |
Google Sheets rendering | uv tool install "graphifyy[google]" |
video |
Video/audio transcription (faster-whisper + yt-dlp) | uv tool install "graphifyy[video]" |
mcp |
MCP stdio server | uv tool install "graphifyy[mcp]" |
neo4j |
Neo4j push support | uv tool install "graphifyy[neo4j]" |
falkordb |
FalkorDB push support | uv tool install "graphifyy[falkordb]" |
svg |
SVG graph export | uv tool install "graphifyy[svg]" |
leiden |
Leiden community detection (Python < 3.13 only) | uv tool install "graphifyy[leiden]" |
ollama |
Ollama local inference | uv tool install "graphifyy[ollama]" |
openai |
OpenAI / OpenAI-compatible APIs | uv tool install "graphifyy[openai]" |
gemini |
Google Gemini API | uv tool install "graphifyy[gemini]" |
anthropic |
Anthropic Claude API (--backend claude, uses ANTHROPIC_API_KEY) |
uv tool install "graphifyy[anthropic]" |
bedrock |
AWS Bedrock (uses IAM, no API key) | uv tool install "graphifyy[bedrock]" |
azure |
Azure OpenAI Service (--backend azure, uses AZURE_OPENAI_API_KEY + AZURE_OPENAI_ENDPOINT) |
uv tool install "graphifyy[openai]" |
sql |
SQL schema extraction | uv tool install "graphifyy[sql]" |
postgres |
Live PostgreSQL introspection (--postgres DSN) |
uv tool install "graphifyy[postgres]" |
dm |
BYOND DreamMaker .dm/.dme AST extraction (may need a C compiler + python3-dev if no wheel matches your platform) |
uv tool install "graphifyy[dm]" |
terraform |
Terraform / HCL .tf/.tfvars/.hcl AST extraction |
uv tool install "graphifyy[terraform]" |
pascal |
Pascal / Delphi .pas/.dpr/.dpk/.inc AST extraction (more accurate calls/inherits edges; falls back to a regex extractor when absent) |
uv tool install "graphifyy[pascal]" |
chinese |
Chinese query segmentation (jieba) | uv tool install "graphifyy[chinese]" |
all |
Everything above | uv tool install "graphifyy[all]" |
Make your assistant always use the graph
Run this once in your project after building a graph:
| Platform | Command |
|---|---|
| Claude Code | graphify claude install |
| CodeBuddy | graphify codebuddy install |
| Codex | graphify codex install |
| OpenCode | graphify opencode install |
| Kilo Code | graphify kilo install |
| GitHub Copilot CLI | graphify copilot install |
| VS Code Copilot Chat | graphify vscode install |
| Aider | graphify aider install |
| OpenClaw | graphify claw install |
| Factory Droid | graphify droid install |
| Trae | graphify trae install |
| Trae CN | graphify trae-cn install |
| Cursor | graphify cursor install |
| Gemini CLI | graphify gemini install |
| Hermes | graphify hermes install |
| Kimi Code | graphify install --platform kimi |
| Amp | graphify amp install |
| Agent Skills (cross-framework) | graphify agents install (alias graphify skills install) |
| Kiro IDE/CLI | graphify kiro install |
| Pi coding agent | graphify pi install |
| Devin CLI | graphify devin install |
| Google Antigravity | graphify antigravity install |
This writes a small config file that tells your assistant to consult the knowledge graph for codebase questions, preferring scoped queries like graphify query "<question>" over reading the full report or grepping raw files.
- Hook platforms (Claude Code, Gemini CLI): a hook fires automatically before search-style tool calls (and, on Claude Code, before reading source files one by one via the Read/Glob tools) and nudges your assistant toward the graph path.
- Instruction-file platforms (Codex, OpenCode, Cursor, etc.): persistent instruction files (
AGENTS.md,.cursor/rules/, etc.) provide the same query-first guidance.
GRAPH_REPORT.md is still available for broad architecture review.
CodeBuddy does the same two things as Claude Code: writes a CODEBUDDY.md section telling CodeBuddy to read graphify-out/GRAPH_REPORT.md before answering architecture questions, and installs PreToolUse hooks (.codebuddy/settings.json) that fire before Bash search commands and file reads, nudging toward graphify query instead.
Codex writes to AGENTS.md and also installs a PreToolUse hook in .codex/hooks.json that fires before every Bash tool call, same always-on mechanism as Claude Code.
Kilo Code installs the Graphify skill to ~/.config/kilo/skills/graphify/SKILL.md and a native /graphify command to ~/.config/kilo/command/graphify.md. graphify kilo install also writes AGENTS.md plus a native tool.execute.before plugin (.kilo/plugins/graphify.js + .kilo/kilo.json or .kilo/kilo.jsonc registration) so Kilo gets the same always-on graph reminder behavior through native .kilo config.
Cursor writes .cursor/rules/graphify.mdc with alwaysApply: true, so Cursor includes it in every conversation automatically, no hook needed.
To remove graphify from all platforms at once: graphify uninstall (add --purge to also delete graphify-out/). Or use the per-platform command (e.g. graphify claude uninstall).
- God nodes — the most-connected concepts in your project. Everything flows through these.
- Surprising connections — links between things that live in different files or modules. Ranked by how unexpected they are.
- The "why" — inline comments (
# NOTE:,# WHY:,# HACK:), docstrings, and design rationale from docs are extracted as separate nodes linked to the code they explain. - Suggested questions — 4–5 questions the graph is uniquely positioned to answer.
- Confidence tags — every inferred relationship is marked
EXTRACTED,INFERRED, orAMBIGUOUS. You always know what was found vs guessed.
| Type | Extensions |
|---|---|
| Code (36 tree-sitter grammars) | .py .ts .mts .cts .js .jsx .tsx .mjs .go .rs .java .c .cpp .cc .cxx .h .hpp .cu .cuh .metal .rb .cs .kt .kts .scala .php .swift .lua .luau .toc .zig .ps1 .psm1 .psd1 .ex .exs .m .mm .jl .vue .svelte .astro .groovy .gradle .dart .v .sv .svh .sql .f .f90 .f95 .f03 .f08 .pas .pp .dpr .dpk .lpr .inc .dfm .lfm .lpk .sh .bash .json .dm .dme .dmi .dmm .dmf .sln .slnx .csproj .fsproj .vbproj .xaml .razor .cshtml (.dm/.dme requires uv tool install graphifyy[dm]; .mts/.cts reuse the TypeScript grammar, .cc/.cxx and CUDA .cu/.cuh and Metal .metal reuse the C++ grammar) |
| Salesforce Apex | .cls .trigger (regex-based; classes, interfaces, enums, methods, triggers, SOQL/DML edges) |
| Terraform / HCL | .tf .tfvars .hcl (requires uv tool install graphifyy[terraform]) |
| MCP configs | .mcp.json mcp.json mcp_servers.json claude_desktop_config.json — extracts server nodes, package refs, env var requirements |
| Package manifests | apm.yml pyproject.toml go.mod pom.xml — one canonical package node per package (by name) plus depends_on edges, so a package referenced from many manifests is a single hub |
| Docs | .md .mdx .qmd .html .txt .rst .yaml .yml (markdown [text](./other.md) links and [[wikilinks]] become references edges between docs) |
| Office | .docx .xlsx (requires uv tool install graphifyy[office]) |
| Google Workspace | .gdoc .gsheet .gslides (opt-in; requires gws auth and --google-workspace; Sheets need uv tool install graphifyy[google]) |
| PDFs | .pdf |
| Images | .png .jpg .webp .gif |
| Video / Audio | .mp4 .mov .mp3 .wav and more (requires uv tool install graphifyy[video]) |
| YouTube / URLs | any video URL (requires uv tool install graphifyy[video]) |
Code is extracted locally with no API calls (AST via tree-sitter). Everything else goes through your AI assistant's model API.
Google Drive for desktop .gdoc, .gsheet, and .gslides files are shortcut pointers, not document content. To include native Google Docs, Sheets, and Slides in a headless extraction, install and authenticate the gws CLI, then run:
uv tool install "graphifyy[google]"  # needed for Google Sheets table rendering
gws auth login -s drive
graphify extract ./docs --google-workspace
You can also set GRAPHIFY_GOOGLE_WORKSPACE=1. Graphify exports shortcuts into graphify-out/converted/ as Markdown sidecars, then extracts those files.
/graphify .                        # build graph for current folder
/graphify ./docs --update          # re-extract only changed files
/graphify . --cluster-only         # rerun clustering without re-extracting
/graphify . --cluster-only --resolution 1.5      # more granular communities
/graphify . --cluster-only --exclude-hubs 99     # suppress utility super-hubs from god-node rankings
/graphify . --no-viz               # skip the HTML, just the report + JSON
/graphify . --wiki                 # build a markdown wiki from the graph
graphify export callflow-html      # Mermaid architecture/call-flow HTML (auto-regenerates on every git commit if hook is installed)

/graphify query "what connects auth to the database?"
/graphify path "UserService" "DatabasePool"
/graphify explain "RateLimiter"

/graphify add https://arxiv.org/abs/1706.03762   # fetch a paper and add it
/graphify add <youtube-url>                       # transcribe and add a video

graphify hook install              # auto-rebuild on git commit
graphify merge-graphs a.json b.json              # combine two graphs

graphify prs                       # PR dashboard: CI state, review status, worktree mapping
graphify prs 42                    # deep dive on PR #42 with graph impact
graphify prs --triage              # AI ranks your review queue (uses whatever backend is configured)
graphify prs --conflicts           # PRs sharing graph communities — merge-order risk
See the full command reference below.
Create a .graphifyignore in your project root — same syntax as .gitignore, including ! negation.
.gitignore is respected automatically. graphify reads the .gitignore in each directory. If a .graphifyignore is also present, the two are merged — .graphifyignore patterns are evaluated last, so they win on conflicts (including ! negations). Adding a .graphifyignore only ever excludes more; it never re-includes a file your .gitignore already excluded. Subdirectory scoping works the same way as git — an ignore file only affects its own subtree.
# .graphifyignore
node_modules/
dist/
*.generated.py

# only index src/, ignore everything else
*
!src/
!src/**
graphify-out/ is meant to be committed to git so everyone on the team starts with a map.
Recommended.gitignore additions:
graphify-out/cost.json        # local only
# graphify-out/cache/         # optional: commit for speed, skip to keep repo small
manifest.jsonis now portable — keys are stored as relative paths and re-anchored on load, so committing it is safe and avoids a full rebuild on first checkout.
Workflow:
- One person runs
/graphify .and commitsgraphify-out/. - Everyone pulls — their assistant reads the graph immediately.
- Run
graphify hook installto auto-rebuild after each commit (AST only, no API cost). This also sets up a git merge driver sograph.jsonis never left with conflict markers — two devs committing in parallel get their graphs union-merged automatically. - When docs or papers change, run
/graphify --updateto refresh those nodes.
# query the graph from the terminal
graphify query "show the auth flow"
graphify query "what connects DigestAuth to Response?" --graph graphify-out/graph.json

# expose the graph as an MCP server (for repeated tool-call access)
python -m graphify.serve graphify-out/graph.json
python -m graphify.serve --graph graphify-out/graph.json  # --graph flag also accepted

# register with Kimi Code:
kimi mcp add --transport stdio graphify -- python -m graphify.serve graphify-out/graph.json

# or serve over HTTP so a whole team points at one URL (no local graphify needed):
python -m graphify.serve graphify-out/graph.json --transport http --port 8080
python -m graphify.serve graphify-out/graph.json --transport http --host 0.0.0.0 --api-key "$SECRET"
The MCP server gives your assistant structured access: query_graph, get_node, get_neighbors, shortest_path, list_prs, get_pr_impact, triage_prs.
--transport stdio (the default) spawns one local server per developer. --transport http serves the same tools over the MCP Streamable HTTP transport, so a single shared process can serve the graph for the whole team — clients point their IDE MCP config at http://<host>:8080/mcp instead of running graphify locally.
| Flag | Default | Purpose |
|---|---|---|
--transport {stdio,http} |
stdio |
Transport to serve on |
--host |
127.0.0.1 |
HTTP bind host (use 0.0.0.0 to expose beyond localhost) |
--port |
8080 |
HTTP bind port |
--api-key |
env GRAPHIFY_API_KEY |
Require Authorization: Bearer <key> (or X-API-Key) |
--path |
/mcp |
HTTP mount path |
--json-response |
off | Return plain JSON instead of SSE streams |
--stateless |
off | No per-session state (for load-balanced / CI deployments) |
--session-timeout |
3600 |
Reap idle stateful sessions after N seconds (0 disables) |
The default 127.0.0.1 bind is loopback-only. Set --host 0.0.0.0 and --api-key together when exposing on a shared host. Run it in a container:
docker build -t graphify .
docker run -p 8080:8080 -v "$(pwd)/graphify-out:/data" graphify \
  /data/graph.json --transport http --host 0.0.0.0 --api-key "$SECRET"
WSL / Linux note: Ubuntu ships
python3, notpython. Use a venv to avoid conflicts:python3 -m venv .venv && .venv/bin/pip install "graphifyy[mcp]"
These are only needed for headless / CI extraction (graphify extract). When running via the /graphify skill inside your IDE, the model API is provided by your IDE session — no extra keys needed.
| Variable | Used for | When required |
|---|---|---|
ANTHROPIC_API_KEY |
Claude (Anthropic) backend | --backend claude |
ANTHROPIC_BASE_URL |
Anthropic-compatible endpoint URL (LiteLLM proxy, gateways, ...) | --backend claude (default: https://api.anthropic.com) |
ANTHROPIC_MODEL |
Model name for the Claude backend — for custom endpoints, use the model name/alias your server exposes | --backend claude (default: claude-sonnet-4-6) |
GEMINI_API_KEY or GOOGLE_API_KEY |
Google Gemini backend | --backend gemini |
OPENAI_API_KEY |
OpenAI or OpenAI-compatible APIs | --backend openai (local servers accept any non-empty value) |
OPENAI_BASE_URL |
OpenAI-compatible server URL (llama.cpp, vLLM, LM Studio, ...) | --backend openai (default: https://api.openai.com/v1) |
OPENAI_MODEL |
Model name for the OpenAI backend — for self-hosted servers, use the model name/alias your server exposes (check its /v1/models endpoint), e.g. LFM2.5-8B-A1B-UD-Q4_K_XL for llama.cpp |
--backend openai (default: gpt-4.1-mini) |
DEEPSEEK_API_KEY |
DeepSeek backend | --backend deepseek |
MOONSHOT_API_KEY |
Kimi Code backend | --backend kimi |
OLLAMA_BASE_URL |
Ollama local inference URL | --backend ollama (default: http://localhost:11434) |
OLLAMA_MODEL |
Ollama model name | --backend ollama (default: auto-detect) |
GRAPHIFY_OLLAMA_NUM_CTX |
Override Ollama KV-cache window size | optional — auto-sized by default |
GRAPHIFY_OLLAMA_KEEP_ALIVE |
Minutes to keep Ollama model loaded | optional — set 0 to unload after each chunk |
AZURE_OPENAI_API_KEY |
Azure OpenAI Service backend | --backend azure |
AZURE_OPENAI_ENDPOINT |
Azure resource endpoint URL | --backend azure (required alongside API key) |
AZURE_OPENAI_API_VERSION |
Azure API version override | optional — default 2024-12-01-preview |
AZURE_OPENAI_DEPLOYMENT or GRAPHIFY_AZURE_MODEL |
Azure deployment name | optional — default gpt-4o |
AWS_* / ~/.aws/credentials |
AWS Bedrock — standard credential chain | --backend bedrock (no API key, uses IAM) |
GRAPHIFY_MAX_WORKERS |
AST parallelism thread count | optional — also --max-workers flag |
GRAPHIFY_MAX_OUTPUT_TOKENS |
Raise output cap for dense corpora | optional — e.g. 32768 for large files |
GRAPHIFY_API_TIMEOUT |
Per-call timeout in seconds for HTTP, claude-cli, and Anthropic SDK backends (default: 600) | optional — also --api-timeout flag |
GRAPHIFY_MAX_RETRIES |
How many times to retry a rate-limited (429) request before giving up (default: 6; honors Retry-After) |
optional — raise for strict per-org limits (e.g. kimi); 0 disables |
GRAPHIFY_FORCE |
Force graph rebuild even with fewer nodes | optional — also --force flag |
GRAPHIFY_GOOGLE_WORKSPACE |
Auto-enable Google Workspace export | optional — set to 1 |
GRAPHIFY_TRIAGE_BACKEND |
Backend for graphify prs --triage |
optional — auto-detected from available keys |
GRAPHIFY_TRIAGE_MODEL |
Model override for triage | optional — e.g. claude-opus-4-7 |
GRAPHIFY_QUERY_LOG |
Override query log path (default: ~/.cache/graphify-queries.log) |
optional — set to empty or /dev/null to silence |
GRAPHIFY_QUERY_LOG_DISABLE |
Set to 1 to disable query logging entirely |
optional |
GRAPHIFY_QUERY_LOG_RESPONSES |
Set to 1 to also log full subgraph responses (off by default) |
optional |
GRAPHIFY_MAX_GRAPH_BYTES |
Override the 512 MiB graph.json size cap — e.g. 700MB, 2GB, or plain bytes |
optional — useful for very large corpora |
GRAPHIFY_LLM_TEMPERATURE |
Override LLM temperature for semantic extraction — e.g. 0.7, or none to omit |
optional — auto-omitted for o1/o3/o4/gpt-5 reasoning models |
- Code files — processed locally via tree-sitter. Nothing leaves your machine. A code-only corpus requires no API key —
graphify extractruns fully offline. - Video / audio — transcribed locally with faster-whisper. Nothing leaves your machine.
- Docs, PDFs, images — sent to your AI assistant for semantic extraction (via the
/graphifyskill, using whatever model your IDE session runs). Headlessgraphify extractrequiresGEMINI_API_KEY/GOOGLE_API_KEY(Gemini),MOONSHOT_API_KEY(Kimi),ANTHROPIC_API_KEY(Claude),OPENAI_API_KEY(OpenAI),DEEPSEEK_API_KEY(DeepSeek), a running Ollama instance (OLLAMA_BASE_URL), AWS credentials via the standard provider chain (Bedrock - no API key needed, uses IAM), or theclaudeCLI binary (Claude Code - no API key needed, uses your Claude subscription). The--dedup-llmflag uses the same key. - Data residency —
graphify extractauto-detects which provider to use based on which API key is set (priority: Gemini → Kimi → Claude → OpenAI → DeepSeek → Azure → Bedrock → Ollama). For code with data-residency requirements, use--backend ollama(fully local) or pass an explicit--backendflag. Kimi (MOONSHOT_API_KEY) routes to Moonshot AI servers in China. - No telemetry , no usage tracking, no analytics.
- Query logging — every
graphify query,graphify path,graphify explain, and MCPquery_graphcall is logged to~/.cache/graphify-queries.login JSON Lines format (timestamp, question, corpus, nodes returned, duration). Full subgraph responses are not stored by default. SetGRAPHIFY_QUERY_LOG_DISABLE=1to opt out, orGRAPHIFY_QUERY_LOG=/dev/nullto silence without disabling the code path.
graphify: command not found after installing The CLI is installed but its bin directory isn't on your shell's PATH. Pick the fix for how you installed:
- uv (
uv tool install graphifyy): the command lands in uv's tool bin dir (~/.local/bin), which a fresh macOS/zsh setup often doesn't have onPATH. Runuv tool update-shell, then open a new terminal. (Find the dir withuv tool dir --bin.) - pipx (
pipx install graphifyy): runpipx ensurepath, then open a new terminal. - pip (
pip install graphifyy): pip installs scripts to a user bin dir that may not be onPATH— add~/Library/Python/3.x/bin(macOS) or~/.local/bin(Linux) to yourPATHin~/.zshrc/~/.bashrc, or just runpython -m graphify.
uvx graphify … or uv tool run graphify … fails to resolve graphify The PyPI package is graphifyy; graphify is only the command it provides. uv tool run treats the first word as a package name , so it looks for a package called graphify and reports No solution found … no versions of graphify. Name the package explicitly: uvx --from graphifyy graphify install (same as uv tool run --from graphifyy graphify install). Or uv tool install graphifyy once and then call graphify directly.
python -m graphify works but graphify command doesn't Your shell's PATH doesn't include the bin directory the command was installed to. Prefer uv tool install / pipx install over plain pip, then run uv tool update-shell / pipx ensurepath and open a new terminal (see the install notes above).
/graphify . causes "path not recognized" in PowerShell PowerShell treats a leading / as a path separator. Use graphify . (no slash) on Windows.
Graph has fewer nodes after--update or rebuild If a refactor deleted files, the old nodes linger. Pass --force (or set GRAPHIFY_FORCE=1) to overwrite even when the rebuild has fewer nodes.
Graph has duplicate nodes for the same entity (ghost duplicates) Ghost duplicates (same symbol appearing twice — once from AST extraction with a source location, once from semantic extraction without) are now automatically merged at build time. If you see this in a graph built before v0.8.33, run a full re-extract to clean up:
graphify extract . --force
Ollama runs out of VRAM / context window exceeded The KV-cache window is auto-sized but may be too large for your GPU. Reduce it:
GRAPHIFY_OLLAMA_NUM_CTX=8192 graphify extract ./docs --backend ollama --token-budget 4000
LLM returned invalid JSON / Unterminated string warnings The model's JSON response hit its output-token limit and was cut off mid-string. graphify auto-recovers (it splits the chunk and re-extracts the halves, and an oversized single document is first sliced at heading/paragraph boundaries so the whole file is still covered), so these warnings are noisy but not data loss. To reduce the churn, raise the output cap or shrink each chunk's output:
GRAPHIFY_MAX_OUTPUT_TOKENS=16384 graphify extract . --mode deep   # lift the cap
graphify extract . --mode deep --token-budget 4000                # smaller input chunks -> smaller output
With a cloud gateway like OpenRouter, prefer --backend openai (set OPENAI_BASE_URL) over the Ollama shim — it's a cleaner OpenAI-compatible path. If the model has its own max-output ceiling, lowering --token-budget is the reliable lever.
Graph HTML is too large to open in a browser ( >5000 nodes) Skip HTML generation and use the JSON directly:
graphify cluster-only ./my-project --no-viz
graphify query "..."
graph.json has conflict markers after two devs commit at once Run graphify hook install — it sets up a git merge driver that union-merges graph.json automatically so conflicts never happen.
Extraction returns empty nodes/edges for docs or PDFs Docs, PDFs, and images require an LLM call — code-only corpora need no key. Check that your API key is set and the backend is correct:
ANTHROPIC_API_KEY=sk-... graphify extract ./docs --backend claude
Skill version mismatch warning in your IDE Your installed graphify version is different from the skill file. Update:
uv tool upgrade graphifyy
graphify install  # overwrites the skill file
Claude Code prompt cache invalidated after everygraphify extract Graphify writes output files (graph.json, graphify-out/) into the workspace. If those paths aren't ignored, every write invalidates Claude Code's prompt cache, forcing a full re-upload at cache-write rates on the next turn. Add them to .claudeignore:
# .claudeignore
graph.json
graphify-out/
/graphify                          # run on current directory
/graphify ./raw                    # run on a specific folder
/graphify ./raw --mode deep        # more aggressive relationship extraction
/graphify ./raw --update           # re-extract only changed files
/graphify ./raw --directed         # preserve edge direction
/graphify ./raw --cluster-only     # rerun clustering on existing graph
/graphify ./raw --no-viz           # skip HTML visualization
/graphify ./raw --obsidian         # generate Obsidian vault
/graphify ./raw --obsidian --obsidian-dir ~/vault  # write into an existing vault (never overwrites your own notes or .obsidian config)
/graphify ./raw --wiki             # build agent-crawlable markdown wiki
/graphify ./raw --svg              # export graph.svg
/graphify ./raw --graphml          # export for Gephi / yEd
/graphify ./raw --neo4j            # generate cypher.txt for Neo4j
/graphify ./raw --neo4j-push bolt://localhost:7687
/graphify ./raw --falkordb         # generate cypher.txt for FalkorDB
/graphify ./raw --falkordb-push falkordb://localhost:6379
/graphify ./raw --watch            # auto-sync as files change
/graphify ./raw --mcp              # start MCP stdio server

/graphify add https://arxiv.org/abs/1706.03762
/graphify add <video-url>
/graphify add https://... --author "Name" --contributor "Name"

/graphify query "what connects attention to the optimizer?"
/graphify query "..." --dfs --budget 1500
/graphify path "DigestAuth" "Response"
/graphify explain "SwinTransformer"

graphify save-result --question "Q" --answer "A" --nodes Foo Bar --outcome useful   # record how a Q&A turned out (work memory; outcome ∈ useful|dead_end|corrected)
graphify reflect                   # aggregate graphify-out/memory/ outcomes into reflections/LESSONS.md
graphify reflect --if-stale        # no-op when LESSONS.md is already newer than every input (cheap to run each session)
graphify reflect --out docs/LESSONS.md    # write the lessons doc somewhere else
graphify reflect --graph graphify-out/graph.json  # group lessons by community + write the work-memory overlay (.graphify_learning.json)
                                   # the overlay tags nodes preferred/tentative/contested (recency-weighted, with provenance);
                                   # graphify explain / query then show a "Lesson:" hint, flagged "code changed — re-verify" when the source moved on

graphify uninstall                 # remove from all platforms in one shot
graphify uninstall --purge         # also delete graphify-out/
graphify uninstall --project --platform codex  # remove project-scoped install files only

graphify hook install              # post-commit + post-checkout hooks
graphify hook uninstall
graphify hook status

# always-on assistant instructions - platform-specific
graphify claude install            # CLAUDE.md + PreToolUse hook (Claude Code)
graphify claude uninstall
graphify codebuddy install         # CODEBUDDY.md + PreToolUse hook (CodeBuddy)
graphify codebuddy uninstall
graphify codex install             # AGENTS.md + PreToolUse hook in .codex/hooks.json (Codex)
graphify opencode install          # AGENTS.md + tool.execute.before plugin (OpenCode)
graphify kilo install              # native Kilo skill + /graphify command + AGENTS.md + .kilo plugin
graphify kilo uninstall
graphify cursor install            # .cursor/rules/graphify.mdc (Cursor)
graphify cursor uninstall
graphify gemini install            # GEMINI.md + BeforeTool hook (Gemini CLI)
graphify gemini uninstall
graphify copilot install           # skill file (GitHub Copilot CLI)
graphify copilot uninstall
graphify aider install             # AGENTS.md (Aider)
graphify aider uninstall
graphify claw install              # AGENTS.md (OpenClaw)
graphify claw uninstall
graphify droid install             # AGENTS.md (Factory Droid)
graphify droid uninstall
graphify trae install              # AGENTS.md (Trae)
graphify trae uninstall
graphify trae-cn install           # AGENTS.md (Trae CN)
graphify trae-cn uninstall
graphify hermes install             # AGENTS.md + ~/.hermes/skills/ (Hermes)
graphify hermes uninstall
graphify amp install               # skill file (Amp)
graphify amp uninstall
graphify agents install            # ~/.agents/skills/ + AGENTS.md (cross-framework; alias: graphify skills)
graphify agents uninstall
graphify kiro install               # .kiro/skills/ + .kiro/steering/graphify.md (Kiro IDE/CLI)
graphify kiro uninstall
graphify pi install                # skill file (Pi coding agent)
graphify pi uninstall
graphify devin install             # skill file + .windsurf/rules/graphify.md (Devin CLI)
graphify devin uninstall
graphify antigravity install       # .agents/rules + .agents/workflows (Google Antigravity)
graphify antigravity uninstall

graphify extract ./docs                        # headless LLM extraction for CI (no IDE needed)
graphify extract ./docs --backend gemini       # explicit backend: gemini, kimi, claude, openai, deepseek, ollama, bedrock, or claude-cli
graphify extract ./docs --backend gemini --model gemini-3.1-pro-preview
graphify extract ./docs --backend ollama       # local Ollama (set OLLAMA_BASE_URL / OLLAMA_MODEL) - no API key needed for loopback
OPENAI_BASE_URL=http://localhost:8080/v1 OPENAI_MODEL=my-model graphify extract ./docs --backend openai   # any OpenAI-compatible server (llama.cpp, vLLM, LM Studio)
ANTHROPIC_BASE_URL=http://localhost:4000 ANTHROPIC_MODEL=my-model graphify extract ./docs --backend claude   # any Anthropic-compatible endpoint (LiteLLM proxy, gateways)
GRAPHIFY_OLLAMA_NUM_CTX=32768 graphify extract ./docs --backend ollama   # override KV-cache window (auto-sized by default)
GRAPHIFY_OLLAMA_KEEP_ALIVE=0 graphify extract ./docs --backend ollama    # unload model after each chunk (saves VRAM on small GPUs)
graphify extract ./docs --backend bedrock      # AWS Bedrock via IAM - no API key, uses AWS credential chain
graphify extract ./docs --backend claude-cli   # route through Claude Code CLI - no API key, uses your Claude subscription
graphify extract ./docs --backend azure        # Azure OpenAI (set AZURE_OPENAI_API_KEY + AZURE_OPENAI_ENDPOINT)
graphify extract ./docs --max-workers 16       # AST parallelism (also GRAPHIFY_MAX_WORKERS)
graphify extract --postgres "postgresql://user:pass@host/db"   # introspect live PostgreSQL schema directly
graphify extract ./my-workspace --cargo        # introspect Rust Cargo workspace dependencies directly
graphify extract ./docs --token-budget 30000   # smaller semantic chunks for local/small models
graphify extract ./docs --max-concurrency 2    # fewer parallel LLM calls (useful for local inference)
graphify extract ./docs --api-timeout 900      # longer HTTP timeout for slow local models (default 600s)
graphify extract ./docs --google-workspace     # export .gdoc/.gsheet/.gslides via gws before extraction
graphify extract ./docs --mode deep            # richer semantic extraction via extended system prompt
graphify extract ./docs --no-cluster           # raw extraction only, skip clustering
graphify extract ./docs --timing               # print per-stage wall-clock timings to stderr (also works on cluster-only)
graphify extract ./docs --force                # overwrite graph.json even if new graph has fewer nodes (use after refactors or to clear ghost duplicates)
graphify extract ./docs --dedup-llm            # LLM tiebreaker for ambiguous entity pairs (uses same API key)
graphify extract ./docs --global --as myrepo   # extract and register into the cross-project global graph
GRAPHIFY_MAX_OUTPUT_TOKENS=32768 graphify extract ./docs --backend claude  # raise output cap for dense corpora

graphify export callflow-html                       # graphify-out/<project>-callflow.html
graphify export callflow-html --max-sections 8      # cap generated architecture sections
graphify export callflow-html --output docs/arch.html
graphify export callflow-html ./some-repo/graphify-out

graphify global add graphify-out/graph.json --as myrepo   # register a project graph into ~/.graphify/global-graph.json
graphify global remove myrepo                         # remove a project from the global graph
graphify global list                                  # show all registered repos + node/edge counts
graphify global path                                  # print path to the global graph file

graphify prs                              # PR dashboard: CI, review, worktree, graph impact
graphify prs 42                           # deep dive on PR #42
graphify prs --triage                     # AI triage ranking (auto-detects backend from env)
graphify prs --worktrees                  # worktree → branch → PR mapping
graphify prs --conflicts                  # PRs sharing graph communities (merge-order risk)
graphify prs --base main                  # filter to PRs targeting a specific base branch
graphify prs --repo owner/repo            # run against a different GitHub repo
GRAPHIFY_TRIAGE_BACKEND=kimi graphify prs --triage   # use a specific backend for triage

graphify clone https://github.com/karpathy/nanoGPT
graphify merge-graphs a.json b.json --out merged.json
graphify --version                                    # print installed version
graphify watch ./src
graphify check-update ./src
graphify update ./src
graphify update ./src --no-cluster  # skip reclustering, write raw AST graph only
graphify update ./src --force       # overwrite even if new graph has fewer nodes
graphify cluster-only ./my-project
graphify cluster-only ./my-project --graph path/to/graph.json  # custom graph location
graphify cluster-only ./my-project --max-concurrency 16 --batch-size 200  # parallel community labeling (large graphs)
graphify cluster-only ./my-project --resolution 1.5            # more, smaller communities
graphify cluster-only ./my-project --exclude-hubs 99           # exclude p99 degree nodes from partitioning
graphify cluster-only ./my-project --no-label                  # keep "Community N" placeholders
graphify cluster-only ./my-project --backend=gemini            # backend for community naming
graphify cluster-only ./my-project --backend=gemini --model gemini-2.5-pro  # specific model
graphify label ./my-project                                    # (re)name communities with the configured backend
graphify label ./my-project --backend=openai --model gpt-4o   # force a specific backend and model
Community names: inside an agent (Claude Code, Gemini CLI) the agent names communities itself. When you run the bare CLI,
cluster-onlyauto-names them with the configured backend (built-in or custom OpenAI-compatible provider) — pass--no-labelto keepCommunity N, or rungraphify labelto (re)generate names on demand.
Built on graphify: Penpax
Penpax is the always-on layer built on top of graphify — it applies the same graph approach to your entire working life: meetings, browser history, emails, files, and code, updating continuously in the background.
Built for people whose work lives across hundreds of conversations and documents they can never fully reconstruct. No cloud, fully on-device.
Free trial launching soon. Join the waitlist →
Contributing
The project uses uv for dev workflow. Install it once, then:
git clone https://github.com/safishamsi/graphify.git
cd graphify
git checkout v8                        # active development branch

# Create the project venv and install graphify + all extras + the dev group
# (pytest). uv installs the dev dependency group by default; pass --no-dev to
# skip it.
uv sync --all-extras
Verify the editable install:
uv run graphify --version
uv run python -c "import graphify; print(graphify.__file__)"


uv run pytest tests/ -q                # run the full suite
uv run pytest tests/test_extract.py -q # one module
uv run pytest tests/ -q -k "python"    # filter by name
macOS note: the test suite includes both
sample.f90andsample.F90fixtures. These collide on case-insensitive HFS+ / APFS file systems. Run on Linux or in a Docker container if you need to test both Fortran variants simultaneously.
- Active development happens on the
v8branch. - Commit style:
fix: <description>/feat: <description>/docs: <description> - Before opening a PR, run
uv run pytest tests/ -qand confirm it passes. - Add a fixture file to
tests/fixtures/and tests totests/test_languages.pyfor any new language extractor.
Worked examples are the most useful contribution. Run /graphify on a real corpus, save the output to worked/{slug}/, write an honest review.md covering what the graph got right and wrong, and open a PR.
Extraction bugs — open an issue with the input file, the cache entry (graphify-out/cache/), and what was missed or wrong.
See ARCHITECTURE.md for module responsibilities and how to add a language.