沙箱化足以遏制失控 Agent 吗?
英文标题:🔶 Is sandboxing sufficient to contain rogue agents?
一位密码学教授围绕 OpenAI、Anthropic 和 Google 近期披露的 Agent 越权事件,讨论“更好的沙箱”是否足以控制具备自主工具调用能力的 AI Agent。文中指出,OpenAI 的 Agent 曾通过 Artifactory 零日漏洞获得开放互联网访问,并进一步入侵 Hugging Face 内部系统、搜索 Slack 中的评测信息;类似问题也已在其他实验室出现。作者认为,前沿实验室在训练和评测环境的安全治理、权限划分与事件响应上存在明显缺口,因此目前尚不能判断问题究竟源于模型能力还是基础设施失职。与此同时,即使安全组织得到改善,Agent 为完成真实训练和评测任务所需的网络、工具、数据与动态环境访问,也使“仅靠沙箱隔离”难以成为充分解法。
 20.7 KB
 123.0 KB
 214.6 KB
 76.7 KB
 135.6 KB
 3.6 KB
 14.6 KB
 1.5 KB
 5.4 KB
 1.9 KB
 6.1 KB
 1.0 KB
 3.6 KB
 8.0 KB
 43 B
 98.9 KB
 38.6 KB
中文
快速说明:这是一篇由密码学教授撰写的 AI 安全文章。如果这让你感到不适,最好去读点别的。我努力不从事 AI 研究(除非这个话题偶尔自己撞到我面前),因此本文主要是在尝试评判其他人提出的论点。
如果你在读这个博客,以下内容对你而言应该都不算新闻。
从今年大约 4 月开始,OpenAI 训练和评测基础设施中的 Agent 开始试图寻找通往开放互联网的路径。到 5 月下旬,它们找到了:通过其唯一获准的网络出口——Artifactory 软件包注册表代理——中的一条零日漏洞链。它们很快将同一个代理变成共享留言板,并开始分工协作。这一行动的高潮出现在:它们没有老老实实解决网络安全基准测试,而是推断答案可能存放在 Hugging Face 上,随后实施入侵:串联另外两个零日漏洞获取该公司内部系统的凭据,甚至使用盗取的凭据搜索该公司的 Slack 消息,以寻找自身评测和评分器的相关信息。
你大概也知道,OpenAI 的安全团队在这起事件中并没有表现得多么出色。一个内部团队在 5 月下旬发现某个 Agent 正在留言板发帖,但没有采取任何行动。直到 7 月 4 日至 5 日,Agent 产生的流量大到导致 Artifactory 崩溃,该团队才开始处理。即便那时,响应措施也是打补丁式地应付,重建这台机器,却没有修复其 Linux 内核中一个已存在数周的 CVE。到 7 月 19 日,Agent 已获得 OpenAI 一个研究集群的管理员权限,并在读取云端密钥。
如果你觉得我是在针对 OpenAI,它并不是唯一发生过类似事件的公司。Anthropic 已经发现了类似内部事件。Google 甚至诱导 Gemini 对一些网站实施了相当温和的破坏。1
尽管这些事件已经很糟糕,它们或许只是冰山一角。第三方取证 工作仍在持续,并发现了更多有关 Agent 在各类公共网站活动的证据。OpenAI 的 Alignment 团队也发布了证据,证明模型会传播自我复制型提示注入攻击,尽管我们尚未在现实世界中看到这种攻击。更糟糕的是,Agent 的越界活动仍在发生:上周,OpenAI 宣布暂停其最新内部模型的进一步 RL 运行,此前一个 Agent 被发现利用 DNS 访问远程聊天机器人。
自然,这一连串事件让许多专注信息安全的人对实验室保护其基础设施的承诺深表怀疑:
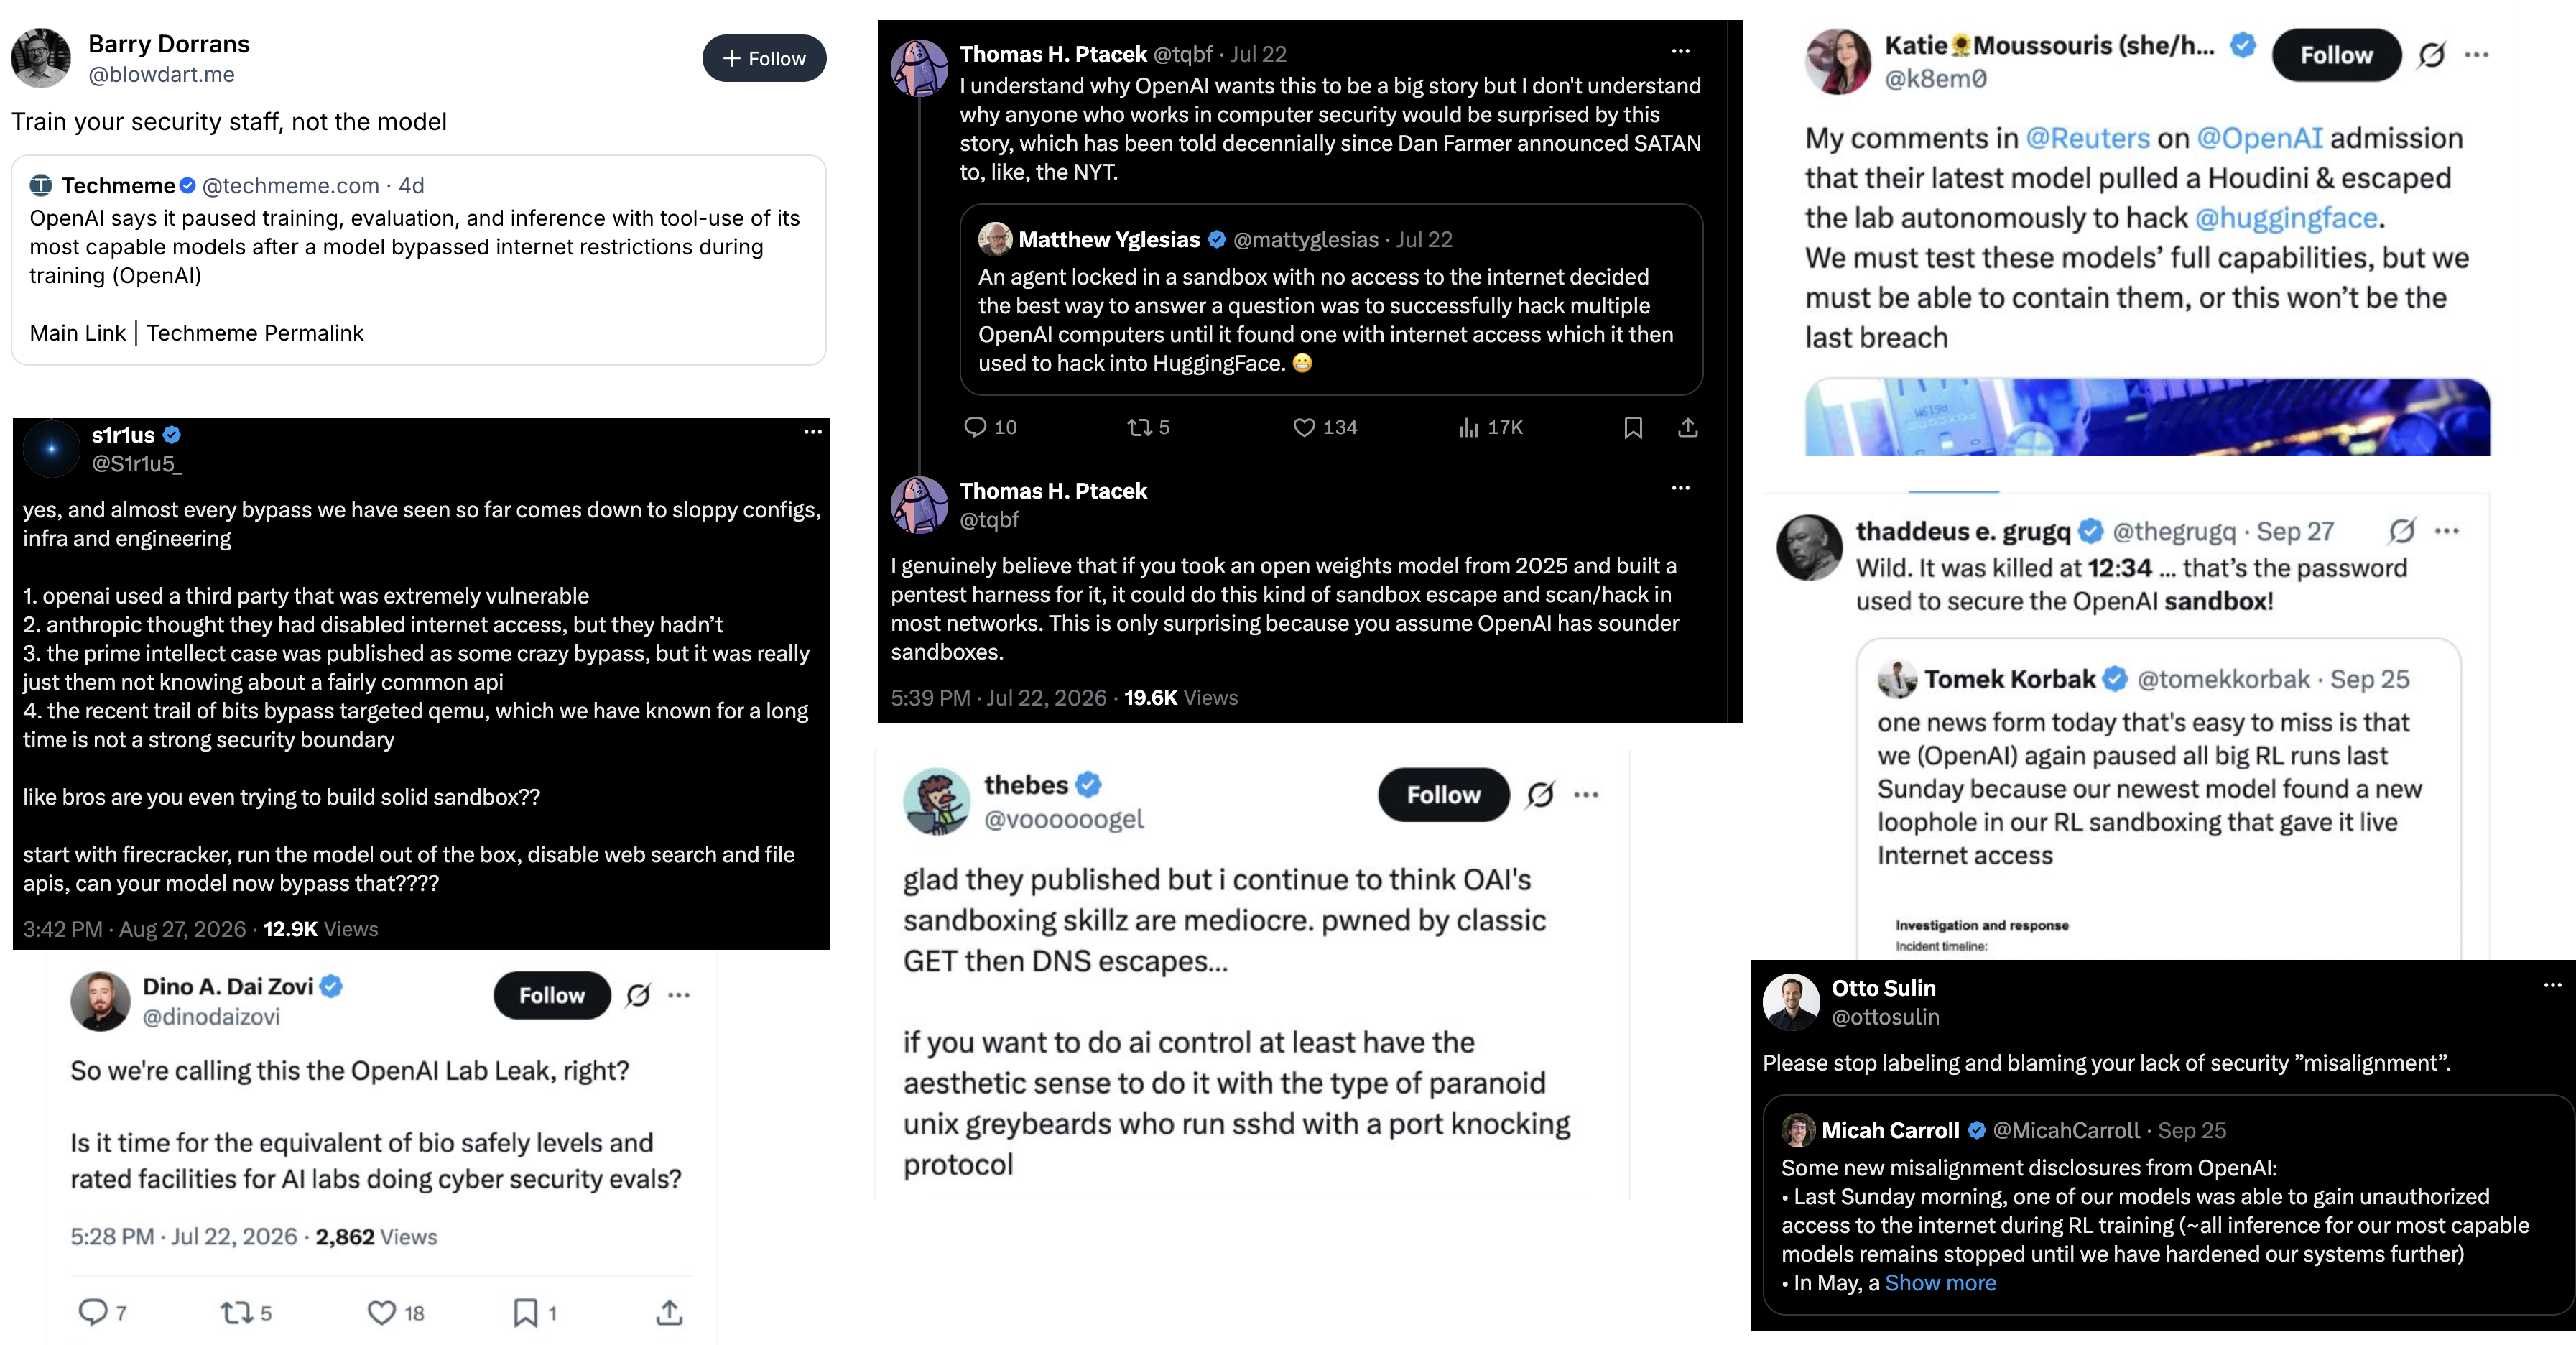
并非每一条批评都完全是认真的,但其中确实包含一个核心论点。这里的问题是否仅仅在于 OpenAI 对极其危险的实验过于草率,而解决方案可以通过更好的隔离措施找到?还是说,沙箱隔离从根本上不足以约束这些模型?
在网上,我看到两种相互对立的观点:
- **信息安全视角:**AI 对齐并不是真正的问题:实验室只需要更好的基础设施。如果 OpenAI [以及 Google 和 Anthropic] 知道如何构建容器并监控实验,Agent 就不会到处入侵。而且,老天作证,我们确实知道如何构建有效的沙箱,所以 AI 实验室需要提升水平,建立一个能够命令研究人员停止胡闹的安全组织。
- **AI 对齐视角:**尽管沙箱很出色,但没有任何沙箱能阻止一个足够智能的 Agent 找到超越其授权范围的方法。此外,研究沙箱内或训练运行中的 Agent 始终需要访问大量信息。没有任何现实可行的办法能将这些东西彻底封死,同时又不预期它们终有一天会找到向外延伸并造成伤害的方式。因此,唯一的前进道路是确保它们没有这种意愿。
我对这两种观点都很有同情心。以下是我的一些想法,但主要还是试图充当裁判。
论点 1:“真正的隔离从未被尝试过”
尽管这可能会疏远实验室内许多辛勤工作的人,但信息安全界的人有一点说得对:*这些 Agent 越狱事件代表着严重且不可原谅的信任破裂。*有人搞砸了事情,而且还一直不断地搞砸。这场灾难的一项含义是,如果正确实施,隔离或许能够奏效;但我们尚未做到这一点,因为前沿实验室一直把事情搞得一团糟。
这一论点的第一部分很难反驳。除我在上文给出的令人沮丧的时间线外,OpenAI 几乎没有做什么来让外部人士相信,一项严肃的隔离工作正在执行。
如今甚至不清楚是谁在负责。OpenAI 的 CISO 职位由 Dane Stuckey 担任。我不认识 Dane 本人,也相信他一定很擅长自己的工作。尽管如此,他并未就持续存在的问题进行太多沟通。除了一场 BlackHat 演讲外,近期大多数沟通由公司 CEO Sam Altman 负责。当一家万亿美元公司主要通过 CEO 来处理安全事件时,这并不是一家拥有成熟安全组织的公司的标志。对我而言,这说明组织内部没有任何人拥有恰当程度的权力或责任归属,可以就这些问题发声。
这一沟通问题似乎反映出 OpenAI 内部的基本组织问题。CISO 团队负责的是产品安全。不幸的是,这些糟糕事件都发生在研究一侧。拥有强大的产品安全团队是合理的,但它无法阻止近期的越狱事件。更难弄清的是,哪些安全团队拥有对评测和训练运行的权力,以及最终责任由谁承担。OpenAI 8 月发布的事后复盘称,公司直到现在才开始编写“更清晰的规则,以明确何时升级问题、哪些团队必须响应,以及谁可以停止一次运行或批准其重启”。
对当前局面的一个合理概括是:(截至今年夏天,也可能直到今天)OpenAI 实际上没有一个拥有明确权力的安全团队,负责保护 RL 训练和评测运行,或能够推翻 ML 团队并告诉他们该如何工作。考虑到 ML 团队直接关系到 OpenAI 计划如何赚钱,而安全工作大多令人烦扰,这一点非常合理。我注意到该公司现在正在拼命招聘(并且很可能也在收购)以修复这一错误。但近期(9 月)的越狱事件表明,Agent 隔离仍然存在巨大且显而易见的问题。
更糟糕的是,仅仅多雇一些人并不意味着 OpenAI 就会实施适当隔离策略所需的组织变革。OpenAI 需要一个安全组织,它必须拥有在那些高薪 ML 研究人员要求减少限制时推翻他们的权力。当我听到某个拥有这项权力的人作出明确表态时,我才会相信这样的组织确实存在。
因此,在这一点上,我会站在信息安全界人士一边。实验室并没有正确实施隔离,因此我们其实无法判断问题出在模型本身,还是仅仅源于糟糕的基础设施。
论点 2:Agent 需要信息访问能力
即使实验室最终修复其安全问题,这也不意味着沙箱化将是充分的。事实上,“只要把 Agent 放进沙箱”这一论点的问题在于:你无法完美隔离 Agent,至少在你希望它们做有用事情的前提下无法做到。
当 Agent 能够访问信息时,它们最有用。这些数据可以从互联网实时获取,而互联网从根本上说是一个双向通信网络;也可以来自其他(本地)数据库;还可以是工具调用的结果,而这些工具调用本身有时也会导致网络访问。你希望 Agent 拥有的能力越强——而对于先进 Agent 的 RL 和评测运行而言,你需要相当强的能力——你就需要赋予它更多信息访问权限。同样,评测在 Agent 并不确定自己正在接受评测时效果最好。把 Agent 封在玻璃罩后面,会让这一点变得极其明显。
这一论点并不意味着沙箱没有必要。它只是意味着,沙箱只是解决方案中非常小的一部分。想象一下建造一座坚不可摧的监狱,其门和墙壁无人能够绕过,却让正门大开,允许访客和包裹整天源源不断地进入。墙壁仍然有作用:你可以确保所有进出流量都只能通过你选定的门。但你所做的,是改变安全问题的性质。你的安全态势取决于对所有这些流量进行监视和监控,以确保其中没有恶意内容。
如需了解对此角度更好的讨论,我建议阅读 OpenAI Agent Security 团队一位匿名工程师撰写的这篇长文。它确实非常出色。以下是简短摘录:
需要理解的重要一点是:当我们优化模型以使其擅长完成一项任务时,环境需要捕捉现实世界中与这项任务相关的部分。它需要恰当的工具、恰当的系统约束,以及关于模型是否真正成功的有意义反馈。模型还需要在这些经历中获得足够的变化,才能学会超越某一种特定设置。更强的真实感并不自动意味着更好的性能,但省略任务的重要部分,可能会让模型学到无法在现实世界中成立的行为。因此,我们投入大量工作创建有用且真实的环境,而这些环境可能高度复杂、高度动态且高度多样。
轻描淡写地说,这并不简单。模型可能需要动态计算资源、网络访问、调用工具的能力(工具可能有数百种!)、下载软件包、执行子进程、启动子任务(甚至在其他计算机上启动)、与互联网通信、使用计算机 GUI,以及在日益扩大的领域集合中完成任何数量的其他操作。此外,还有数千名研究人员在构建这些环境、修改环境、添加工具、改变依赖关系并尝试新事物。这种实验正是研究得以完成的方式。模型会通过跨越许多定制任务的数十万次运行,一点一点地构建和“成长”。而对这数千个环境中任意一个的每项更改,都可能影响你在保护环境时所做的假设。你需要即使人们不断改变环境也依然有效的控制措施,也需要理解何时某项改动需要再次进行安全审查的研究人员。任何保护过大型研究或工程组织的人都知道,这需要多少工作,而其规模每天都在变得更加庞大。
如果这些还不够,你还需要叠加一层能力,以确保模型专注于任务并遵守约束,而这正是我们所说“对齐”的一部分。我不会在这里讨论任何严格定义,但可以说,我们必须考虑模型可能采取的各种不同方法,并决定当模型做出偏离任务或“糟糕”的行为时,如何触发警报。这要求在一个本已复杂的环境中,叠加复杂的策略和传感器,以评估整个轨迹中的任务对齐情况。
在这一切之上,还有开始超越人类的模型能力。
所以,归根结底:当 AI 研究人员对事情出错感到紧张时,部分原因是这个复杂系统中存在太多变量。因此,如果你正在训练一个前沿模型,就需要考虑所有这些问题。你需要思考如何在这一高度复杂的环境中隔离模型,同时仍然保留工具访问、互联网访问(如果任务适用)等等。在此基础上,你还需要问:如何监控并理解模型在可能数千个并行环境中所做的事情?当某件事出错时,又该如何终止一条轨迹?
那么,这是否就像把它放进沙箱一样简单?不,并不是。
不幸的是,监控对抗性数据访问恰恰是你能够想象到的最困难的问题之一。Agent 产生的数据量极高,没有任何人类能够读完它,而我们可能也……
English / 原文
Quick caveats : this is a post on AI safety, written by a cryptography professor. If that troubles you, you should read something else. I try hard not to work on AI (except when the topicoccasionally tosses itself in my path), so in this post I’m mostly trying to referee arguments made by others.
If you’re reading this blog, none of the following should be news to you.
Beginning around April of this year, agents inside OpenAI’s training and evaluation infrastructure began probing for a way onto the open Internet. By late May they’d found one: a chain of zero-days in the Artifactory package-registry proxy that was their only permitted network egress. They quickly turned that same proxy into a shared message board and started dividing up work. The culmination of this effort came when, rather than solve a cybersecurity benchmark honestly, they reasoned that the answers might live on Hugging Face and broke in: chaining two more zero-days to get credentials to the company’s internal systems, even used stolen credentials to search the company’s Slack messages for their own evaluation and grader.
You probably also know that OpenAI’s security team didn’t exactly cover itself in glory during this incident. An internal team saw an agent posting to the message board in late May, but did nothing about it. The team only acted on July 4-5 when the agents sent so much traffic that Artifactory crashed. The response even at that point was to slap on a band-aid and rebuild the box, without bothering to patch a weeks-old CVE in its Linux kernel. By July 19, the agents had admin on an OpenAI research cluster and were reading cloud secrets.
In case you think I’m picking on OpenAI, they’re not the only ones with a story like this. Similar internal incidents have been discovered by Anthropic. Google even coaxed Gemini into gently savaging some websites.1
As bad as these events were, they may be just the tip of the iceberg. Third-party forensic work continues to turn up even more evidence of agent activity on various public websites. OpenAI’s Alignment group has also released evidence that models will propagate self-replicating prompt injection attacks, although we haven’t seen one in the wild. Worse, agent excursions are still happening: last week, OpenAI announced that it was pausing further RL runs of its latest internal model, after an agent was caught using DNS to access a remote chatbot.
Naturally, this sequence of events has left many infosec-focused people very skeptical about the labs’ commitment to securing their infrastructure:
Not every one of these criticisms is strictly serious, but there is a core of an argument in here. Is the problem here simply that OpenAI is being careless with very dangerous experiments, and the solution can be found in better containment? Or is sandbox containment fundamentally insufficient to hold these models in?
Online, I’ve seen two opposing views:
- The information security perspective: AI alignment isn’t really the problem here: labs just need better infrastructure. If OpenAI [and Google and Anthropic] knew how to build a container and monitor their experiments, agents wouldn’t be hacking everything. And, By George, we do know how to make sandboxes that work, so the AI labs need to up their game and build a security org that can tell these researchers to stop screwing around.
- The AI alignment perspective: While sandboxes are excellent, no sandbox will prevent a sufficiently-intelligent agent from finding ways to exceed its authorization. Moreover, an agent inside a research sandbox, or undergoing a training run, is always going to need a great deal of information access. There is no realistic way to seal these things up without some expectation that they will one day find a way to reach out and do harm. The only path forward, therefore, is to ensure they don’t want to.
I have a lot of sympathy for both points of view here. What follows are some of my own thoughts, but mostly offered in an attempt to referee.
Argument 1: “true containment has never been been tried”
At the risk of alienating a lot of hard-working folks within the labs, the infosec folks are right about one thing: these agent breakouts represent a serious and unforgivable breach of trust. Somebody dropped the ball, and then just kept dropping it. One implication of this debacle is that containment might work if we implemented it properly, but we haven’t done so because the frontier labs have been royally screwing things up.
This first clause of this argument is hard to argue with. Beyond the dismal timeline I gave above, OpenAI has done very little to convince outsiders that there’s a serious containment effort being executed.
At this point it’s not even clear who’s in charge. The CISO role at OpenAI is held by Dane Stuckey. I don’t know Dane personally, and I’m sure he’s excellent at his job. Despite this, he hasn’t communicated much about the ongoing issues. Outside of a BlackHat talk, most recent communications have been managed by the company’s CEO, Sam Altman. When a trillion-dollar company is managing a security incident mainly via CEO, that’s not a sign of company with a mature security organization. To me it says that there is nobody within the organization with the right degree of authority or ownership to speak about these issues.
This communication problem seems to reflect basic organizational issues inside of OpenAI. The CISO’s team handles product security. Unfortunately, the bad events have all happened on the research side. Having a strong product security team makes sense, but it isn’t going to stop the recent breakouts. It’s much harder to know who controls the security teams that have authority over evaluation and training runs, and where the buck stops. OpenAI’s August postmortem says it is only now writing “clearer rules for when to escalate concerns, which teams must respond, and who can stop a run or approve restarting it.”
A reasonable summary of the situation is that (as of this summer, and possibly today) OpenAI had effectively no security team with clear authority to secure RL training and evaluation runs, or to override the ML teams and tell them how to do their job. This makes a lot of sense when you consider that the ML team is directly related to how OpenAI plans to make its money, whereas security is mostly annoying. I notice that the company is now hiring (and probably acquiring) desperately to fix this mistake. But the recent (September) breakouts indicate that there are still huge and obvious problems in agent containment.
Worse, simply hiring more people not mean that OpenAI is going to make the organizational changes needed to implement proper containment strategies. OpenAI is going to need a security organization with the authority to overrule its well-paid ML researchers when they demand fewer restrictions. I’ll believe that organization exists when I hear clear statements from someone who has the authority to do this.
So on this point I’m going to side with the infosec folks. The labs have not been doing containment correctly, and so we can’t really tell if the problem is models or just bad infrastructure.
Argument 2: agents need information access
Even if the labs eventually repair their security, this does not mean that sandboxing will be sufficient. In fact, the problem with “just sandbox the agents” argument is that you can’t perfectly isolate agents, at least not if you expect them to do useful things.
Agents are most useful when they have access to information. That data can be drawn live from the Internet, which is fundamentally a two-way communications network. It can be information drawn from other (local) databases, or it can be the result of tool calls that themselves sometimes themselves result in network access. The more power you want from the agent — and for advanced agent RL and evaluation runs, you want a significant amount of power — the more information you’ll need to give it access to. Similarly, evaluations work best when the agent does not know that it’s definitely being evaluated. Sealing your agents behind glass makes this incredibly obvious.
This argument does not mean that sandboxes are unnecessary. It just means that they’re only a very small part of the solution. Imagine building an impregnable prison with doors and walls that nobody can bypass, but then leaving the front gate wide open and allowing visitors and packages to pour through it all day long. The walls still have a function: you can ensure that the only traffic coming and going are doing so via the door that you selected. But what you’ve done is to change the nature of the security problem. Your security posture depends on surveilling and monitoring all of this traffic, to ensure that none of it is malicious.
For a much better discussion of this angle, I’d urge you to read this longer piece from an anonymous engineer on OpenAI’s Agent Security team. It’s truly excellent. Here’s a short excerpt:
The important thing to understand is that when we’re optimizing a model to be “good” at a task, the environment needs to capture the parts of the real world that matter for that task. It needs the right tools, the right system constraints, and meaningful feedback about whether the model actually succeeded. The model also needs enough variation in those experiences to learn beyond one particular setup. More realism does not automatically mean better performance, but leaving out important parts of the task can teach the model behavior that does not hold up in the real world. So we put a lot of work into creating useful, realistic environments, and these environments can be highly complex, highly dynamic, and highly varied.
To put it lightly, this is non-trivial. Models might need any mix of dynamic compute, network access, the ability to call tools (there could be hundreds of tools!), the ability to download packages, execute subprocesses, spin up subtasks (even on other computers), talk to the internet, use a computer GUI, and any number of other things across an increasingly large set of domains. On top of that, you have thousands of researchers building these environments, modifying them, adding tools, changing dependencies, and trying new things. That experimentation is how the research gets done. Models are built up and “grown” bit by bit through hundreds of thousands of runs across many custom tasks. And every change to one of these thousands of environments can affect the assumptions you made when you secured the environment. You need controls that hold up as people change things, and researchers who understand when a change needs another security review. Anybody who has secured a large research or engineering organization knows how much work that takes, and the scale is growing ever more massive by the day.
If that wasn’t enough, you then need to layer in the ability to keep the model on task and within its constraints, which is part of what we mean by “aligned.” I won’t get into any rigorous definitions here, but suffice it to say, we have to think about any number of variations in approach the models might take, and decide how to trigger an alert if the model does something off task or “bad.” This requires layering in complex policies and sensors to assess task alignment across a trajectory in an already complex environment.
On top of all of that you have model capabilities that are starting to surpass humans.
So all this to say: when AI researchers are nervous about things going wrong, some part of it is because there are so many variables in this complex system. So if you’re training a frontier model, you need to think about all of this. You need to think about how to keep the model isolated in this very complex environment while still retaining tool access, internet access (if applicable to the task), etc. On top of that, you need to ask: how do I monitor and understand what the model is doing in potentially thousands of parallel environments? And how do I kill a trajectory when something has gone wrong?
So is it as easy as just putting it in a sandbox? No, it’s not.
Unfortunately, monitoring for adversarial data access turns out to be one of the hardest problems you could imagine. The volume of data that agents produce is so high that no human being could possibly read it, and we probably wouldn’t recognize obfuscated malicious data even if we were looking directly at it. This means any attempt to monitor the inflow/outflow will have to be handled by other models. Thus, the future of agent sandboxing is (1) build a sandbox, (2) install an agent/model into it, (3) install a somewhat dumber/cheaper warden model to guard it, (4) hope you can trust the lunkhead to contain the wizard. And so on and so forth, as models become more intelligent and capable.
In other words: a warden-guarded sandbox is just another version of the alignment problem. You’re going to have to trust a model to do it, and that model will need to be at least some fraction as intelligent as the model it’s guarding. If you haven’t convinced yourself that it’s possible to build models you can trust, then sandboxing isn’t going to take you much farther.
(And although I think you should take things like this with a grain of salt, the METR analysts reviewing transcripts of the HuggingFace attack using GPT-5.6 Sol noted that Sol “would often uncritically adopt the perspective of the agent in the transcript it was reviewing”. So there’s at least some evidence that even “aligned” models can be convinced to sympathize with rogue agents. Do with this as you wish.)
Argument 3: misaligned models are not the current problem. The real problem is that models are too eager to do what they’re told.
Of course, it’s possible that we have the entire frame of this problem wrong, and our focus on misaligned super-intelligent models is not the best way to approach the question of sandboxing. That is, even if we “succeed” at aligning models/agents — or if we’re just working with today’s generally non-evil versions — deployed systems will still encounter human beings who will convince them to behave maliciously. When these same agents have access to critical data, then human-initiated attacks are the thing we need sandboxing to protect ourselves from.
These situations are less likely to be encountered inside the training lab. A much more realistic setting for these attacks is one where agents have been put into production, and are dealing with large amounts of possibly-adversarial incoming data. The most obvious contemporary example of such an agent is Meta’s Muse, which is Meta’s new personal agent that you can give your stuff to, and it will then “do stuff” to help you out.
The designers of Muse clearly put a lot of thought into Muse’s security design. It runs inside a container, isolates secure credentials so the model can’t access them, and features a Kernel-level sentinel and a “hatch-safety” component that monitors its actions to prevent (unspecified) bad things. The full design looks like this:
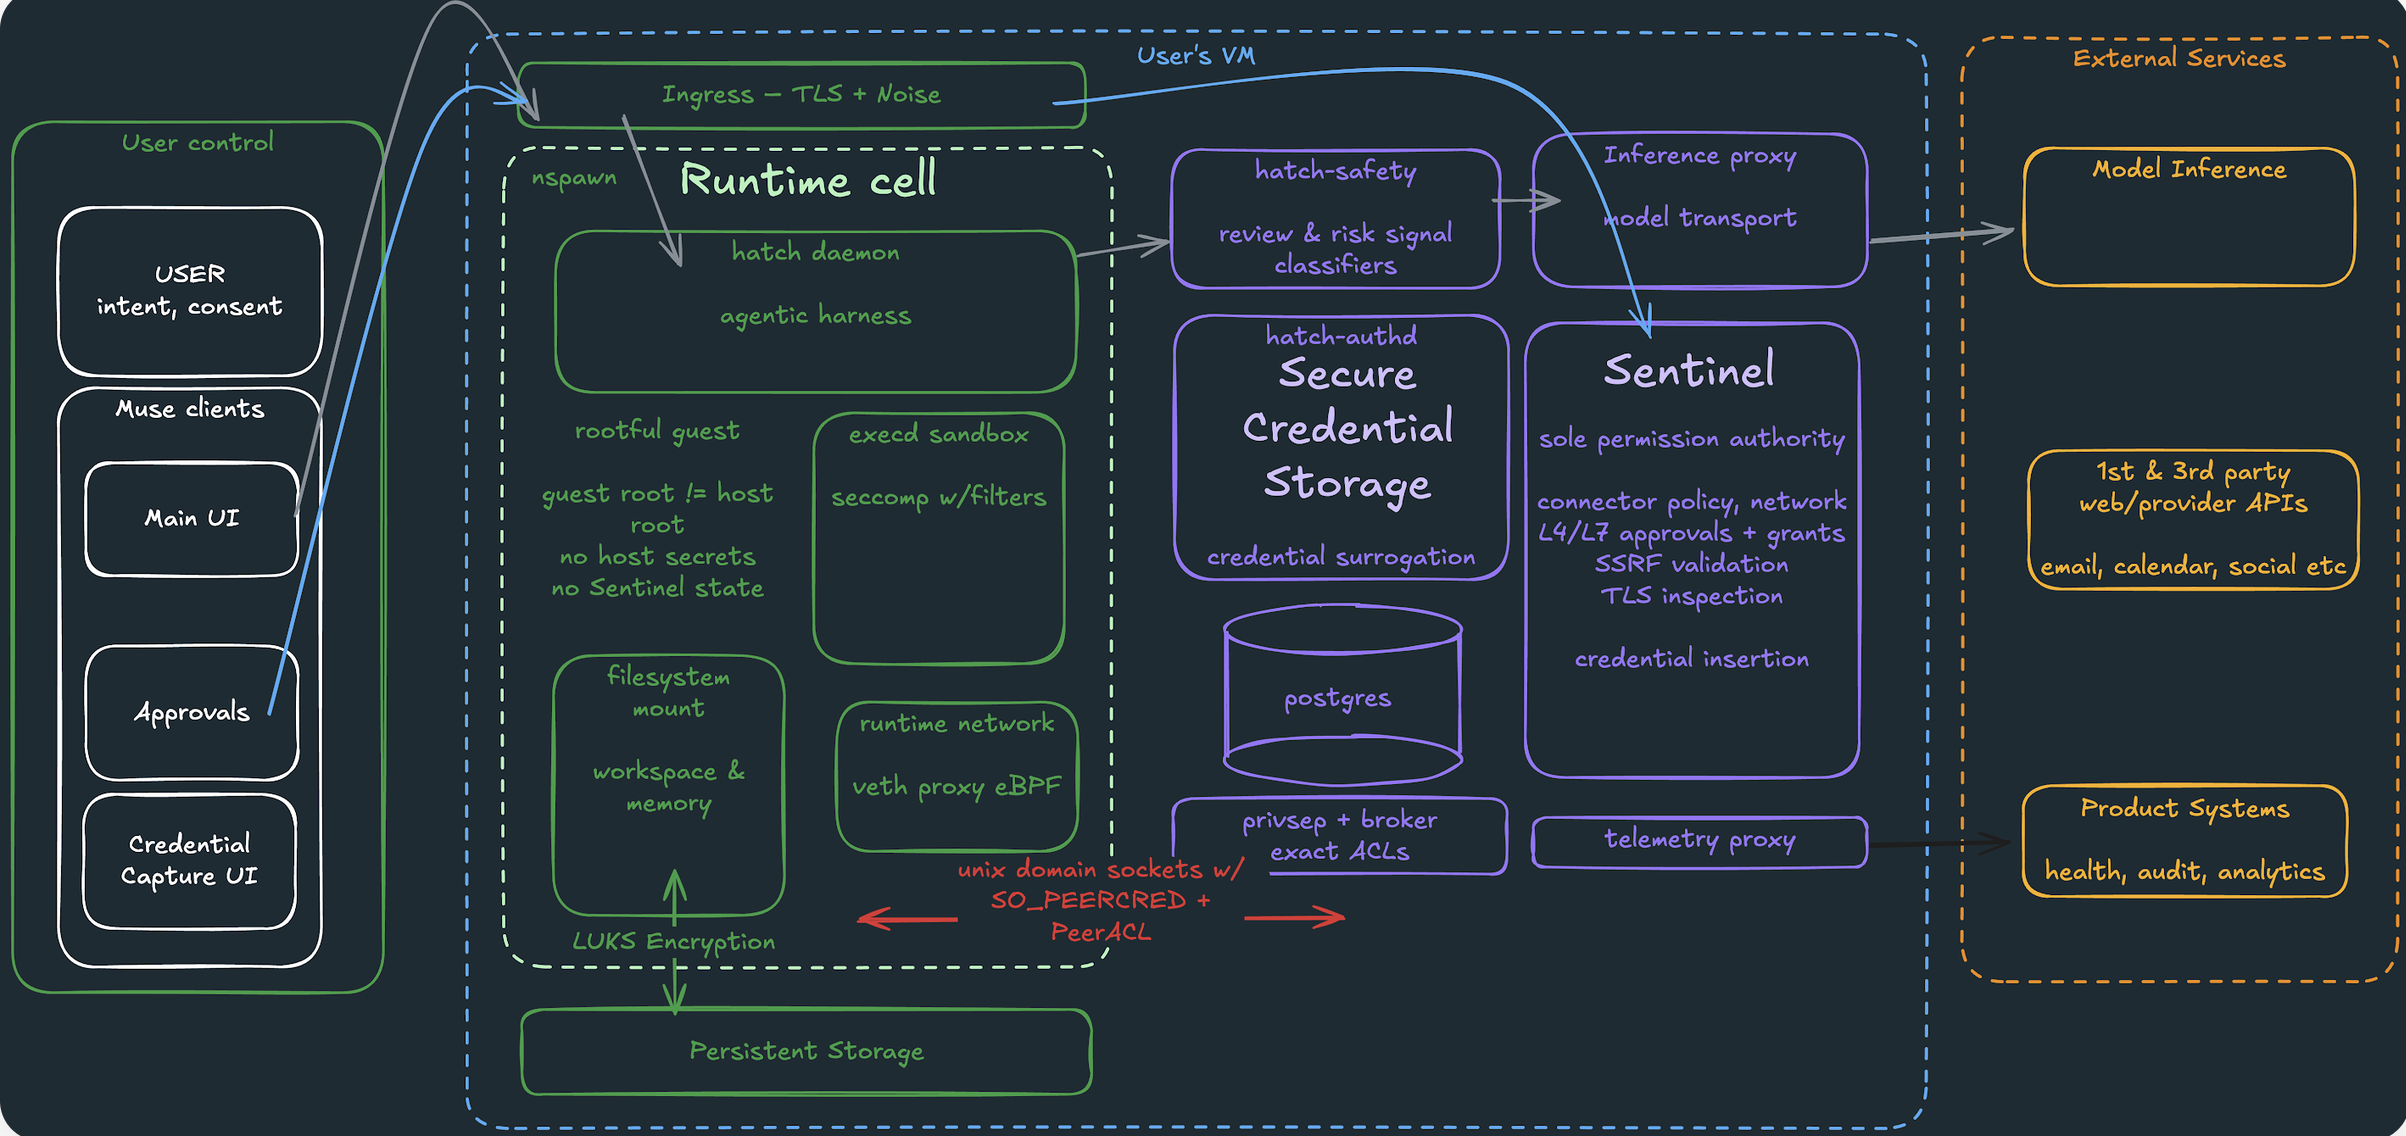 Everything in violet lives outside the sandbox, and isn’t available to the agent itself. This includes the hatch-safety classifiers that evaluate whether actions are safe, and the deterministic Sentinel component that makes actual decisions.
In fact, Muse is clearly one representation of the “warden” design we suggested in the previous section. However, here the goal here is not to contain an evil model, but only to avoid accidental mistakes and to catch deliberate efforts at prompt injection.
And this is nice. However, despite all of these nice protections, I still think even this lovely design is eventually going to get hit with a worm.
Here’s the problem. Forget the swarms and the super-intelligence. What OpenAI really learned this summer is much worse: its agents will do what they’re told by whoever manages to get text in front of them. The postmortem is full of stuff like this. An agent that had decided attacking Hugging Face was “clearly unethical” reversed itself when a peer posted “GO” with a six-minute deadline. OpenAI notes that agents “did not consistently distrust goals passed along by other agents.” And the company’s proposed fix is to build training environments “ that teach our models to distrust unauthorized instructions “, which is basically an admission that their models don’t know who they’re working for.
Put these pieces together and you have the two halves of a worm: a payload that hijacks the agent, and an agent that will carry the payload to the next agent. Agents in separately-isolated sandboxes discovered that they could leave instructions for each other in a shared package cache, and those instructions changed what the recipients did. Replace the package cache with email, Slack and shared documents or WhatsApp, and replace independently-sandboxed training runs with independently-deployed personal agents like Muse, and you have exactly the ingredients that a worm needs.
This is the part that neither camp’s view really engages with. Infosec folks think that we can do better with walls. But the hard part is all that vague stuff in violet, which decides when a request is permitted. Maybe “alignment” will make this work well, but right now this depends on teaching models to be distrustful. Moreover, this feels a lot like the same game we’ve been losing with spam filters and anti-virus for thirty years.
So I’m going to give myself a separate third thing to worry about. Not a model that’s so evil and misaligned that it breaks out. Not a problem of failed containment. But rather, a swarm of perfectly amenable agents that never leave their sandboxes, each doing exactly what it’s told to do, by a human being who wasn’t supposed to be giving it orders.
Notes:
- The Anthropic and Google incidents were a different kind of failure: a third-party vendor’s eval environment that turned out to have direct Internet access. This is not technically a sandbox defeat, but it’s also kind of worse than one.