使用 NVIDIA NeMo Agent Toolkit 和 Amazon S3 Vectors 构建 Agent 记忆
英文标题:Build agent memory with NVIDIA NeMo Agent Toolkit and Amazon S3 Vectors
本文介绍如何将 Amazon S3 Vectors 作为 NVIDIA NeMo Agent Toolkit(NAT)的持久化记忆层,并部署在 Amazon EKS 上以获得完整的运维控制能力。文章说明了 NAT 的记忆子系统和自定义 `MemoryEditor` 插件机制,并通过代码演示如何创建 S3 Vectors 基础设施、实现记忆提供程序及配置 Agent 工作流。该方案使用 Amazon Titan Text Embeddings V2 生成 1024 维向量,并结合元数据过滤实现按用户、Agent、团队、股票代码等范围检索记忆。对于需要强写入一致性、弹性扩展至数十亿向量以及按用量付费的生产级多 Agent 系统,S3 Vectors 可提供适配的长期记忆后端。
 1.3 MB
 1.3 MB
 2.4 KB
 345.0 KB
 141.2 KB
 346.5 KB
 48.2 KB
 24.8 KB
 228.7 KB
中文
在上一篇文章:使用 Amazon S3 Vectors 为多 Agent AI 系统构建持久化记忆中,我们探讨了为何记忆工程是生产级多 Agent 系统的基础性学科。我们展示了 Amazon S3 Vectors——Amazon Simple Storage Service(Amazon S3)的一项能力——如何满足 Agent 记忆的架构要求:语义检索、丰富元数据、强一致性和弹性扩展能力。
本文将从架构转向实现。我们将展示如何将 Amazon S3 Vectors 用作 NVIDIA NeMo Agent Toolkit(NAT) 内的持久化记忆层,并将其部署在 Amazon Elastic Kubernetes Service(Amazon EKS) 上,以实现完整的运维控制。
阅读完本文后,你将了解 NAT 的记忆子系统如何工作,以及如何将 Amazon S3 Vectors 实现为自定义记忆提供程序。你还将学习如何在 Amazon EKS 上部署这套技术栈;文中将以一个多 Agent 投资研究用例作为贯穿始终的示例。
NVIDIA NeMo Agent Toolkit(NAT) 是一个用于构建、分析和优化 AI Agent 的开源框架。它不依赖特定框架,可与 Strands Agents、LangChain、LlamaIndex、CrewAI 及自定义实现配合使用。NAT 提供四项与生产级 Agent 系统相关的能力:
- Agent 编排 —— 将 Agent 定义为可组合的工作流,并配置大语言模型(LLM)、工具和提示词。你可以通过
nat run在本地运行它们,或通过nat serve将其作为持久化服务运行。 - 性能分析 —— 跨 Agent 和单个工具跟踪 Token 使用量、延迟、吞吐量和运行时间,从而识别多 Agent 工作流中的瓶颈。
- 评估 —— 内置回答准确性、上下文相关性、响应有据性和 Agent 轨迹评估器,并支持自定义评估器。
- 优化 —— 自动进行超参数调优(temperature、
top_p、max_tokens),在提升质量的同时尽可能降低成本和延迟。
NAT 的记忆模块
NAT 包含一个专用记忆子系统,用于在多次 Agent 调用之间存储和检索对话历史、用户偏好与长期知识。该记忆模块具有可扩展性:你可以通过实现 NAT 的插件接口来创建自定义记忆提供程序(后端)。主要组件包括:
MemoryEditor—— 所有记忆后端都必须实现的抽象接口。它定义了三个方法:add_items()、search()和remove_items()。MemoryItem—— 表示一条记忆的数据模型,包含对话历史、标签、元数据、user_id以及可选的文本记忆字符串等字段。MemoryBaseConfig—— 自定义记忆配置所扩展的 Pydantic 基类。NAT 通过 YAML 配置中的_type字段发现提供程序。- 自动记忆包装器 ——
auto_memory_agent工作流类型可为 Agent 添加自动记忆捕获和检索能力,而无需 LLM 显式调用记忆工具。
NAT 当前内置的记忆提供程序包括:Mem0、MemMachine、Redis 和 Zep。这些提供程序覆盖了常见用例。但是,对于需要弹性向量存储、强写入一致性,以及以高成本效率扩展至数十亿向量的生产级多 Agent 系统来说,由 Amazon S3 Vectors 支持的自定义提供程序是合适的选择。
为什么选择 Amazon S3 Vectors 作为持久化记忆后端
使用 Amazon S3 Vectors 为多 Agent AI 系统构建持久化记忆深入介绍了其架构依据。下表汇总了使 S3 Vectors 适合作为 NAT 记忆层的特性:
| 需求 | S3 Vectors 能力 |
|---|---|
| 语义检索 | 采用可配置距离度量(余弦、欧几里得)的向量相似度搜索 |
| 范围限定查询 | 每个向量具备可过滤的元数据(字符串、数字、布尔值、列表) |
| 多 Agent 协作 | 强写入一致性。记忆在插入后立即可见 |
| 扩展规模 | 每个索引最多支持 20 亿个向量,无需进行容量规划 |
| 成本效率 | 仅为存储、写入和查询付费,无闲置计算成本 |
| 访问控制 | 可按存储桶和索引配置 AWS Identity and Access Management(IAM)策略。通过每租户独立索引实现硬隔离 |
前提条件
要跟随本文实现操作,你需要:
将 S3 Vectors 实现为 NAT 记忆提供程序
实现包含三个步骤:
步骤 1:创建 S3 Vectors 基础设施
步骤 2:实现自定义 MemoryEditor 插件
步骤 3:配置 Agent 工作流
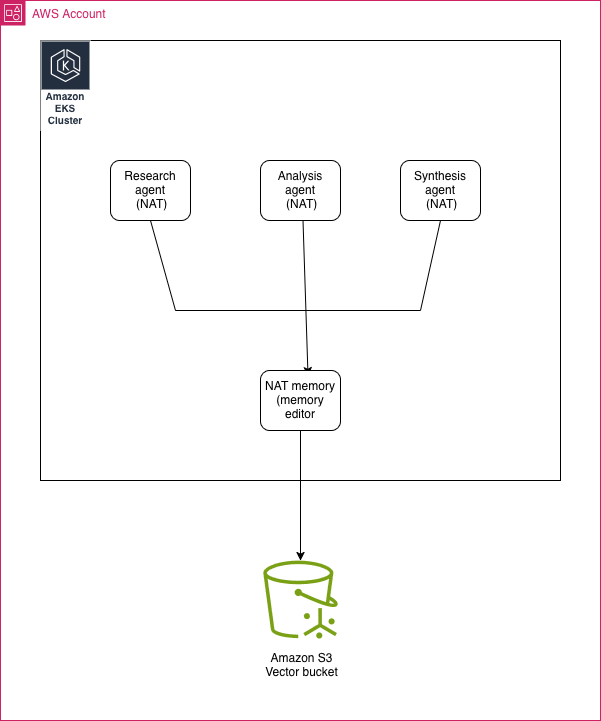
图 1:将 Amazon S3 Vectors 实现为 NAT 记忆提供程序的三个步骤
步骤 1:创建 Amazon S3 Vectors 基础设施
以下代码创建了一个向量存储桶和索引,并使用专为 Agent 记忆设计的元数据架构。该索引采用 1024 个维度,以匹配 Amazon Titan Text Embeddings V2 的输出;同时将较大的内容字段标记为不可过滤元数据:
import boto3

REGION = "us-west-2"
VECTOR_BUCKET = "amzn-s3-demo-research-agent-memory"
INDEX_NAME = "agent-long-term-memory"

s3vectors = boto3.client("s3vectors", region_name=REGION)

# Create the vector bucket
s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)

# Create the index (1024 dimensions matches Amazon Titan Text Embeddings V2)
s3vectors.create_index(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    dataType="float32",
    dimension=1024,
    distanceMetric="cosine",
    metadataConfiguration={"nonFilterableMetadataKeys": ["content"]},
)
创建存储桶和索引后,你可以实现从中读取和向其中写入数据的记忆提供程序。
步骤 2:实现自定义 MemoryEditor 插件
以下代码将 MemoryEditor 接口实现为由 Amazon S3 Vectors 支持的后端,并对其进行注册,以便 NAT 能够发现它:
import boto3
import json
import uuid
from datetime import datetime, timezone
from nat.plugin_api import MemoryBaseConfig, MemoryEditor, MemoryItem, register_memory
from nat.builder.builder import Builder


class S3VectorsMemoryConfig(MemoryBaseConfig, name="s3vectors_memory"):
    """NAT memory provider configuration for Amazon S3 Vectors."""
    vector_bucket: str
    index_name: str
    aws_region: str = "us-west-2"
    default_top_k: int = 5


class S3VectorsMemoryEditor(MemoryEditor):
    """NAT MemoryEditor backed by Amazon S3 Vectors."""

    def __init__(self, config: S3VectorsMemoryConfig):
        self._vector_bucket = config.vector_bucket
        self._index_name = config.index_name
        self._default_top_k = config.default_top_k
        self._s3vectors = boto3.client('s3vectors', region_name=config.aws_region)
        self._bedrock = boto3.client('bedrock-runtime', region_name=config.aws_region)

    def _get_embedding(self, text: str) -> list[float]:
        """Generate embeddings using Amazon Titan Text Embeddings V2."""
        response = self._bedrock.invoke_model(
            modelId='amazon.titan-embed-text-v2:0',
            contentType='application/json',
            accept='application/json',
            body=json.dumps({
                'inputText': text,
                'dimensions': 1024,
                'normalize': True
            })
        )
        return json.loads(response['body'].read())['embedding']

    async def add_items(self, items: list[MemoryItem], **kwargs) -> None:
        """Store memory items as vectors in Amazon S3 Vectors."""
        vectors = []
        for item in items:
            # Build the text to embed from the memory content
            text = item.memory or json.dumps(item.conversation)
            embedding = self._get_embedding(text)
            # Use uuid4 to prevent key collisions within the same second
            key = f"mem_{item.user_id}_{uuid.uuid4().hex[:12]}"
            # Note: S3 Vectors metadata values have size limits.
            # Truncate content to 1024 characters for production use.
            content_for_metadata = text[:1024]
            mem_metadata = {
                'user_id': item.user_id,
                'memory_type': item.metadata.get('memory_type', 'episodic'),
                'agent_id': item.metadata.get('agent_id', ''),
                'team_id': item.metadata.get('team_id', ''),
                'task_id': item.metadata.get('task_id', ''),
                'confidence': item.metadata.get('confidence', 0.8),
                'created_at_epoch': int(datetime.now(timezone.utc).timestamp()),
                'is_shared': item.metadata.get('is_shared', True),
                'source': item.metadata.get('source', 'agent'),
                'content': content_for_metadata,
            }
            # Add domain-specific metadata if present
            if 'ticker' in item.metadata:
                mem_metadata['ticker'] = item.metadata['ticker']
            vectors.append({
                'key': key,
                'data': {'float32': embedding},
                'metadata': mem_metadata
            })
        self._s3vectors.put_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            vectors=vectors
        )

    async def search(self, query: str, top_k: int = None, **kwargs) -> list[MemoryItem]:
        """Retrieve semantically relevant memories from Amazon S3 Vectors."""
        query_embedding = self._get_embedding(query)
        effective_top_k = top_k or self._default_top_k
        # Build metadata filter from kwargs
        filter_expr = {}
        for field in ('agent_id', 'memory_type', 'ticker', 'team_id', 'user_id'):
            if field in kwargs:
                filter_expr[field] = {'$eq': kwargs[field]}
        # Support boolean filter for is_shared
        if 'is_shared' in kwargs:
            filter_expr['is_shared'] = {'$eq': kwargs['is_shared']}
        response = self._s3vectors.query_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            queryVector={'float32': query_embedding},
            topK=effective_top_k,
            filter=filter_expr if filter_expr else None,
            returnMetadata=True
        )
        results = []
        for vec in response.get('vectors', []):
            results.append(MemoryItem(
                conversation=[],
                tags=[vec['metadata'].get('memory_type', '')],
                metadata=vec['metadata'],
                user_id=vec['metadata'].get('user_id', ''),
                memory=vec['metadata'].get('content', '')
            ))
        return results

    async def remove_items(self, **kwargs) -> None:
        """Remove memory items from Amazon S3 Vectors."""
        keys = kwargs.get('keys', [])
        if keys:
            self._s3vectors.delete_vectors(
                vectorBucketName=self._vector_bucket,
                indexName=self._index_name,
                keys=keys
            )


# Register the memory provider so NAT can discover it
@register_memory(config_type=S3VectorsMemoryConfig)
async def build_s3vectors_memory(config: S3VectorsMemoryConfig, builder: Builder):
    yield S3VectorsMemoryEditor(config)
该插件通过 Amazon Titan Text Embeddings V2 生成嵌入向量,将每条记忆作为具有范围限定元数据的向量存储,并将搜索过滤器转换为 Amazon S3 Vectors 元数据查询。
步骤 3:配置 NAT Agent 工作流
定义插件后,在 NAT 的 YAML 配置中对其进行配置,并将其连接到一个 Agent 工作流中:
# config.yml - NAT agent configuration with Amazon S3 Vectors memory
memory:
  agent_memory:
    _type: s3vectors_memory
    vector_bucket: "amzn-s3-demo-research-agent-memory"
    index_name: "agent-long-term-memory"
    aws_region: "us-west-2"

functions:
  add_memory:
    _type: add_memory
    memory: agent_memory
    description: |
      Store important findings, patterns, or facts to long-term memory.
      Use this after discovering new information during research.
  get_memory:
    _type: get_memory
    memory: agent_memory
    description: |
      Retrieve relevant prior knowledge before starting research.
      Query with the current research topic to recall related findings.
  web_search:
    _type: web_search
  financial_data:
    _type: financial_data_api

workflow:
  _type: auto_memory_agent
  inner_agent_name: research_agent
  memory_name: agent_memory
  llm_name: bedrock_llm
  save_user_messages_to_memory: true
  retrieve_memory_for_every_response: true
  save_ai_messages_to_memory: true

llm:
  bedrock_llm:
English / 原文
In my previous post: Building persistent memory for multi-agent AI systems with Amazon S3 Vectors, we explored why memory engineering is the foundational discipline for production multi-agent systems. We showed how Amazon S3 Vectors, a capability of Amazon Simple Storage Service (Amazon S3), meets the architectural requirements for agent memory: semantic retrieval, rich metadata, strong consistency, and elastic scale.
In this post, we move from architecture to implementation. We show you how to use Amazon S3 Vectors as the persistent memory layer within the NVIDIA NeMo Agent Toolkit (NAT), deployed on Amazon Elastic Kubernetes Service (Amazon EKS) for full operational control.
By the end of this post, you will understand how NAT’s memory subsystem works and how to implement Amazon S3 Vectors as a custom memory provider. You will also learn how to deploy the stack on Amazon EKS, using a multi-agent investment research use case as the running example.
NVIDIA NeMo Agent Toolkit (NAT) is an open source framework for building, profiling, and optimizing AI agents. It’s framework-agnostic, working with Strands Agents, LangChain, LlamaIndex, CrewAI, and custom implementations. NAT provides four capabilities relevant to production agent systems:
- Agent orchestration – Define agents as composable workflows with configurable large language models (LLMs), tools, and prompts. You run them locally with
nat runor as persistent services withnat serve. - Profiling – Track token usage, latency, throughput, and run times across agents and individual tools to identify bottlenecks in multi-agent workflows.
- Evaluation – Built-in evaluators for answer accuracy, context relevance, response groundedness, and agent trajectory, with support for custom evaluators.
- Optimization – Automated hyperparameter tuning (temperature,
top_p,max_tokens) that maximizes quality while minimizing cost and latency.
NAT’s memory module
NAT includes a dedicated memory subsystem designed to store and retrieve conversation history, user preferences, and long-term knowledge across agent invocations. The memory module is extensible: you create custom memory providers (backends) by implementing NAT’s plugin interface. Key components include:
MemoryEditor– The abstract interface that all memory backends must implement. It defines three methods:add_items(),search(), andremove_items().MemoryItem– The data model representing a piece of memory, containing fields for conversation history, tags, metadata,user_id, and an optional textual memory string.MemoryBaseConfig– A Pydantic base class that custom memory configurations extend. NAT discovers providers via the_typefield in its YAML config.- Automatic memory wrapper – The
auto_memory_agentworkflow type that wraps agents with automatic memory capture and retrieval, without requiring the LLM to explicitly invoke memory tools.
NAT currently has these built-in memory providers: Mem0, MemMachine, Redis, and Zep. These cover common use cases. However, for production multi-agent systems that require elastic vector storage, strong write consistency, and cost-efficient scaling to billions of vectors, a custom provider backed by Amazon S3 Vectors is the right fit.
Why Amazon S3 Vectors as the persistent memory backend
Building persistent memory for multi-agent AI systems with Amazon S3 Vectors covers the architectural rationale in depth. The following table summarizes the properties that make S3 Vectors the right fit for NAT’s memory layer:
| Requirement | S3 Vectors capability |
|---|---|
| Semantic retrieval | Vector similarity search with configurable distance metrics (cosine, euclidean) |
| Scoped queries | Filterable metadata on each vector (strings, numbers, Booleans, lists) |
| Multi-agent coordination | Strong write consistency. Memories are visible immediately after insertion |
| Scale | Up to 2 billion vectors per index with no capacity planning |
| Cost efficiency | Pay only for storage, writes, and queries with no idle compute |
| Access control | AWS Identity and Access Management (IAM) policies per bucket and index. Per-tenant indexes for hard isolation |
Prerequisites
To follow along with the implementation in this post, you need:
Implementing S3 Vectors as a NAT memory provider
The implementation has three steps:
Step 1: Create the S3 Vectors infrastructure
Step 2: Implement a custom MemoryEditor plugin
Step 3: Configure the agent workflow
Figure 1: The three steps to implement Amazon S3 Vectors as a NAT memory provider
Step 1. Create the Amazon S3 Vectors infrastructure
The following code creates a vector bucket and an index with a metadata schema designed for agent memory. The index uses 1024 dimensions to match the output of Amazon Titan Text Embeddings V2, and it marks the large content field as non-filterable metadata:
import boto3

REGION = "us-west-2"
VECTOR_BUCKET = "amzn-s3-demo-research-agent-memory"
INDEX_NAME = "agent-long-term-memory"

s3vectors = boto3.client("s3vectors", region_name=REGION)

# Create the vector bucket
s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)

# Create the index (1024 dimensions matches Amazon Titan Text Embeddings V2)
s3vectors.create_index(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    dataType="float32",
    dimension=1024,
    distanceMetric="cosine",
    metadataConfiguration={"nonFilterableMetadataKeys": ["content"]},
)
After creating the bucket and index, you can implement the memory provider that reads from and writes to them.
Step 2. Implement a custom MemoryEditor plugin
The following code implements the MemoryEditor interface as an Amazon S3 Vectors backend and registers it so that NAT can discover it:
import boto3
import json
import uuid
from datetime import datetime, timezone
from nat.plugin_api import MemoryBaseConfig, MemoryEditor, MemoryItem, register_memory
from nat.builder.builder import Builder


class S3VectorsMemoryConfig(MemoryBaseConfig, name="s3vectors_memory"):
    """NAT memory provider configuration for Amazon S3 Vectors."""
    vector_bucket: str
    index_name: str
    aws_region: str = "us-west-2"
    default_top_k: int = 5


class S3VectorsMemoryEditor(MemoryEditor):
    """NAT MemoryEditor backed by Amazon S3 Vectors."""

    def __init__(self, config: S3VectorsMemoryConfig):
        self._vector_bucket = config.vector_bucket
        self._index_name = config.index_name
        self._default_top_k = config.default_top_k
        self._s3vectors = boto3.client('s3vectors', region_name=config.aws_region)
        self._bedrock = boto3.client('bedrock-runtime', region_name=config.aws_region)

    def _get_embedding(self, text: str) -> list[float]:
        """Generate embeddings using Amazon Titan Text Embeddings V2."""
        response = self._bedrock.invoke_model(
            modelId='amazon.titan-embed-text-v2:0',
            contentType='application/json',
            accept='application/json',
            body=json.dumps({
                'inputText': text,
                'dimensions': 1024,
                'normalize': True
            })
        )
        return json.loads(response['body'].read())['embedding']

    async def add_items(self, items: list[MemoryItem], **kwargs) -> None:
        """Store memory items as vectors in Amazon S3 Vectors."""
        vectors = []
        for item in items:
            # Build the text to embed from the memory content
            text = item.memory or json.dumps(item.conversation)
            embedding = self._get_embedding(text)
            # Use uuid4 to prevent key collisions within the same second
            key = f"mem_{item.user_id}_{uuid.uuid4().hex[:12]}"
            # Note: S3 Vectors metadata values have size limits.
            # Truncate content to 1024 characters for production use.
            content_for_metadata = text[:1024]
            mem_metadata = {
                'user_id': item.user_id,
                'memory_type': item.metadata.get('memory_type', 'episodic'),
                'agent_id': item.metadata.get('agent_id', ''),
                'team_id': item.metadata.get('team_id', ''),
                'task_id': item.metadata.get('task_id', ''),
                'confidence': item.metadata.get('confidence', 0.8),
                'created_at_epoch': int(datetime.now(timezone.utc).timestamp()),
                'is_shared': item.metadata.get('is_shared', True),
                'source': item.metadata.get('source', 'agent'),
                'content': content_for_metadata,
            }
            # Add domain-specific metadata if present
            if 'ticker' in item.metadata:
                mem_metadata['ticker'] = item.metadata['ticker']
            vectors.append({
                'key': key,
                'data': {'float32': embedding},
                'metadata': mem_metadata
            })
        self._s3vectors.put_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            vectors=vectors
        )

    async def search(self, query: str, top_k: int = None, **kwargs) -> list[MemoryItem]:
        """Retrieve semantically relevant memories from Amazon S3 Vectors."""
        query_embedding = self._get_embedding(query)
        effective_top_k = top_k or self._default_top_k
        # Build metadata filter from kwargs
        filter_expr = {}
        for field in ('agent_id', 'memory_type', 'ticker', 'team_id', 'user_id'):
            if field in kwargs:
                filter_expr[field] = {'$eq': kwargs[field]}
        # Support boolean filter for is_shared
        if 'is_shared' in kwargs:
            filter_expr['is_shared'] = {'$eq': kwargs['is_shared']}
        response = self._s3vectors.query_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            queryVector={'float32': query_embedding},
            topK=effective_top_k,
            filter=filter_expr if filter_expr else None,
            returnMetadata=True
        )
        results = []
        for vec in response.get('vectors', []):
            results.append(MemoryItem(
                conversation=[],
                tags=[vec['metadata'].get('memory_type', '')],
                metadata=vec['metadata'],
                user_id=vec['metadata'].get('user_id', ''),
                memory=vec['metadata'].get('content', '')
            ))
        return results

    async def remove_items(self, **kwargs) -> None:
        """Remove memory items from Amazon S3 Vectors."""
        keys = kwargs.get('keys', [])
        if keys:
            self._s3vectors.delete_vectors(
                vectorBucketName=self._vector_bucket,
                indexName=self._index_name,
                keys=keys
            )


# Register the memory provider so NAT can discover it
@register_memory(config_type=S3VectorsMemoryConfig)
async def build_s3vectors_memory(config: S3VectorsMemoryConfig, builder: Builder):
    yield S3VectorsMemoryEditor(config)
The plugin generates embeddings with Amazon Titan Text Embeddings V2, stores each memory as a vector with scoped metadata, and translates search filters into Amazon S3 Vectors metadata queries.
Step 3. Configure the NAT agent workflow
With the plugin defined, configure it in NAT’s YAML config and wire it into an agent workflow:
# config.yml - NAT agent configuration with Amazon S3 Vectors memory
memory:
  agent_memory:
    _type: s3vectors_memory
    vector_bucket: "amzn-s3-demo-research-agent-memory"
    index_name: "agent-long-term-memory"
    aws_region: "us-west-2"

functions:
  add_memory:
    _type: add_memory
    memory: agent_memory
    description: |
      Store important findings, patterns, or facts to long-term memory.
      Use this after discovering new information during research.
  get_memory:
    _type: get_memory
    memory: agent_memory
    description: |
      Retrieve relevant prior knowledge before starting research.
      Query with the current research topic to recall related findings.
  web_search:
    _type: web_search
  financial_data:
    _type: financial_data_api

workflow:
  _type: auto_memory_agent
  inner_agent_name: research_agent
  memory_name: agent_memory
  llm_name: bedrock_llm
  save_user_messages_to_memory: true
  retrieve_memory_for_every_response: true
  save_ai_messages_to_memory: true

llm:
  bedrock_llm:
    _type: bedrock
    model_id: "anthropic.claude-sonnet-4-20250514"
    temperature: 0.3
With the auto_memory_agent wrapper, you can capture and retrieve memory automatically. User messages and agent responses are stored, and relevant context is injected before each agent call. This design removes the need for the LLM to explicitly invoke memory tools.
Responsible AI and data handling considerations
Because this solution persists conversation history and user memory, plan for how that data is retained and accessed. Set a retention policy for stored memories, and use the memory consolidation and removal paths in this post to expire data you no longer need. Avoid storing personally identifiable information (PII) in memory metadata, and redact or tokenize sensitive fields before you embed them. Scope access with per-tenant indexes and least-privilege IAM policies so that each agent reads and writes only the memory it owns.
Putting Amazon S3 Vectors in practice: Multi-agent investment research
The following use case demonstrates this pattern in practice. Consider three specialized agents collaborating on an investment research tool:
- Research Agent – Gathers market data, earnings reports, and news.
- Analysis Agent – Performs quantitative analysis and identifies patterns.
- Synthesis Agent – Produces reports combining findings from both agents.
With persistent memory, each agent builds on prior work. The Research Agent recalls previously collected data, avoiding redundant API calls. The Analysis Agent builds on patterns identified in prior sessions. The Synthesis Agent accesses cumulative findings to produce progressively richer reports.
Multi-agent memory coordination
Each agent uses the same S3 Vectors index but writes with its own agent_id in the metadata. Agents retrieve shared knowledge using metadata filters:
# Analysis Agent retrieves Research Agent's shared findings
research_findings = await memory_client.search(
    query=f"Recent research findings for {ticker}",
    top_k=10,
    team_id='investment-research',
    is_shared=True
)

# Synthesis Agent queries all team knowledge
all_team_knowledge = await memory_client.search(
    query=f"Complete analysis and research for {ticker} Q2 2026",
    top_k=20,
    team_id='investment-research'
)
NAT’s built-in multi-tenant memory isolation uses user_id to scope memory per user. For multi-agent team coordination, the team_id metadata field provides an additional grouping dimension within the same S3 Vectors index.
Memory consolidation
Over time, episodic memories accumulate. Periodically consolidating them into semantic memories (generalized knowledge) keeps retrieval precise and efficient. You can trigger consolidation through a scheduled cron job, a vector count threshold, or an agent-initiated signal after a configurable number of research cycles:
async def consolidate_memories(ticker: str, memory_client, workflow):
    """Distill episodic memories into durable semantic knowledge."""
    episodes = await memory_client.search(
        query=f"All findings about {ticker}",
        top_k=50,
        memory_type='episodic',
        ticker=ticker
    )
    episode_texts = [e.memory for e in episodes if e.memory]
    consolidation_prompt = f"""Given these {len(episode_texts)} observations
about {ticker}, identify durable patterns and generalized knowledge.

{chr(10).join(episode_texts)}

Return a JSON array of insight strings. Do not include specific dates
or one-time events."""
    response = await workflow.run(consolidation_prompt)
    # Parse the response into a list of insights
    insights = json.loads(response)
    # Store each consolidated insight as semantic memory
    await memory_client.add_items([
        MemoryItem(
            conversation=[],
            tags=['semantic'],
            metadata={
                'memory_type': 'semantic',
                'confidence': 0.9,
                'ticker': ticker,
                'source': 'consolidation',
                'is_shared': True,
                'team_id': 'investment-research'
            },
            user_id='system',
            memory=insight
        )
        for insight in insights
    ])
Deploying agent workloads on Amazon EKS
Amazon EKS is a deliberate choice for teams that need full operational control over their agent workloads. With Amazon EKS, you control scaling, networking, and lifecycle management, and you integrate natively with AWS Identity and Access Management (IAM) for Amazon S3 Vectors access. If you prefer a fully managed runtime, Amazon Bedrock AgentCore provides a managed alternative that removes this operational overhead. You run NAT agents as containerized services using nat serve. Each agent type is a Kubernetes Deployment with IAM access granted through IAM Roles for Service Accounts (IRSA).
Step 1: Build the agent container
The following Dockerfile packages the agent with its configuration and memory plugin:
FROM python:3.12-slim
RUN pip install nvidia-nat[langchain] boto3
COPY config.yml /app/config.yml
COPY s3vectors_memory.py /app/s3vectors_memory.py
WORKDIR /app
CMD ["nat", "serve", "--config_file", "config.yml"]
Step 2: Deploy with Kubernetes manifests
The following manifests deploy the Research Agent with autoscaling:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: research-agent
  namespace: agent-team
spec:
  replicas: 2
  selector:
    matchLabels:
      app: research-agent
  template:
    metadata:
      labels:
        app: research-agent
        team: investment-research
    spec:
      serviceAccountName: agent-sa
      containers:
      - name: agent
        image: ${ECR_REGISTRY}/research-agent:latest # Amazon Elastic Container Registry (Amazon ECR)
        ports:
        - containerPort: 8000
        env:
        - name: VECTOR_BUCKET
          value: "amzn-s3-demo-research-agent-memory"
        - name: INDEX_NAME
          value: "agent-long-term-memory"
        - name: AWS_REGION
          value: "us-west-2"
        resources:
          requests:
            cpu: "500m"
            memory: "1Gi"
          limits:
            cpu: "2000m"
            memory: "4Gi"
---
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: research-agent-hpa
  namespace: agent-team
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: research-agent
  minReplicas: 1
  maxReplicas: 10
  metrics:
  - type: Resource
    resource:
      name: cpu
      target:
        type: Utilization
        averageUtilization: 70
IAM policy for S3 Vectors access
The following IAM policy grants scoped access to the memory layer. Attach it to the IAM role associated with the agent-sa service account through IRSA:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "s3vectors:PutVectors",
                "s3vectors:QueryVectors",
                "s3vectors:GetVectors",
                "s3vectors:DeleteVectors"
            ],
            "Resource": "arn:aws:s3vectors:us-west-2:${ACCOUNT_ID}:vector-bucket/amzn-s3-demo-research-agent-memory/*"
        }
    ]
}
Deploy and verify
After building and pushing the container image, deploy the agents:
# Create the namespace
kubectl create namespace agent-team

# Apply the manifests
kubectl apply -f kubernetes/research-agent-deployment.yaml

# Verify pods are running
kubectl get pods -n agent-team

# Test the agent endpoint
kubectl port-forward -n agent-team svc/research-agent 8000:8000
curl -X POST http://localhost:8000/generate \
  -H "Content-Type: application/json" \
  -d '{"inputs": "What are the latest AAPL earnings trends?"}'
S3 Vectors provides strong write consistency. Pods and agent types can immediately see memories that agent pods store, with no cache invalidation required. The HorizontalPodAutoscaler scales agent replicas based on CPU utilization. Each replica connects to the same S3 Vectors index through IRSA, supporting consistent memory access regardless of which pod handles a given request.
Evaluating memory impact
With NAT’s evaluation harness (nat eval), you can quantify the effect of memory on agent performance. Configure two evaluation runs: one with memory enabled and one without, using the same dataset:
# Evaluate with memory enabled
nat eval --config_file config_with_memory.yml \
  --dataset eval_dataset.jsonl \
  --metrics accuracy,groundedness,token_usage,latency

# Evaluate without memory (baseline)
nat eval --config_file config_no_memory.yml \
  --dataset eval_dataset.jsonl \
  --metrics accuracy,groundedness,token_usage,latency
Based on the architectural properties of this design, you can expect the following qualitative outcomes when comparing these runs. These are directional expectations, not benchmarked measurements:
- Groundedness improves – Recalled memories provide verifiable source context that the agent can cite rather than relying on parametric knowledge alone.
- Token usage decreases – Agents skip re-deriving facts already established in prior sessions. The reduction scales with how much repeated context your workflows involve.
- Latency increases modestly – Each memory recall adds an S3 Vectors query (subsecond at standard access patterns), typically a small fraction of overall LLM inference time.
- Duplicate work drops – With shared memory, agents avoid repeating research or analysis that teammates have already completed.
The magnitude of these effects depends on your workload: how much context is reused across sessions, how many agents coordinate, and how large your retrieval budget (top-k) is. NAT’s hyperparameter optimizer can systematically tune top_k and similarity threshold to find the optimal cost-quality trade-off for your use case.
Clean up resources
To avoid ongoing charges from resources created in this walkthrough, delete the following:
-
Delete the Amazon EKS Deployment and associated resources:
kubectl delete namespace agent-team -
Delete the S3 Vectors index and vector bucket:
s3vectors.delete_index(vectorBucketName='amzn-s3-demo-research-agent-memory', indexName='agent-long-term-memory') s3vectors.delete_vector_bucket(vectorBucketName='amzn-s3-demo-research-agent-memory') -
Remove the IAM role and policy created for IRSA if no longer needed.
Conclusion
This post showed how to implement a custom NAT memory provider backed by Amazon S3 Vectors and deploy it on Amazon EKS. The key building blocks:
- NAT’s
MemoryEditorinterface provides the plugin contract for custom memory backends. - The
auto_memory_agentwrapper handles capture and retrieval automatically. - Amazon S3 Vectors delivers the durable, semantically queryable backend with strong consistency for multi-agent coordination.
- Amazon EKS gives you full operational control over agent lifecycle, scaling, and network isolation.
These patterns apply to domains where agents benefit from accumulated knowledge. They include classifying memory as episodic, semantic, or procedural, sharing memory across agents with metadata filtering, and consolidating memory with an LLM. Examples include customer support, DevOps automation, legal research, and scientific discovery.
For the memory architecture foundations referenced throughout this post, see Building persistent memory for multi-agent AI systems with Amazon S3 Vectors. To get started with NAT, see the NVIDIA NeMo Agent Toolkit documentation and the Adding a Memory Provider guide.