Reka 发布 Rho-1:打破多模态拼接架构,统一理解、推理、生成与物理动作的 19B 全模态模型
英文标题:🔶 Reka Rho-1: Collapsing the multimodal stack
AI 独角兽企业 Reka 正式发布其从零开始训练的 19B 原生全模态推理模型 Rho-1 预览版。与当前依赖多 Agent 串联专用工具的传统拼接管线不同,Rho-1 将文本、视觉潜变量与机器人动作统一作为 Token 纳入单个上下文窗口与 KV 缓存中,消除了跨系统切换的延迟与上下文割裂。其实验展示了在同一会话中完成图像生成、画框定位、视频生成、天气编辑与视频比对问答的全闭环,其蒸馏版本 Rho-1 Flash 生成 5.3 秒视频仅需约 1 秒。这一端到端架构不仅展现了极高的实时交互与可控视频编辑潜力,更被 Reka 视为迈向具身智能与物理 AGI(Physical AGI)的核心基石。
 54.2 KB
 26.8 KB
 23.8 KB
 24.4 KB
 25.8 KB
 26.3 KB
 3.9 KB
 2.9 KB
 95.4 KB
中文
一个能理解、模拟并采取行动的全模态推理模型(Omni-reasoning model)。
今天,我们正式发布 Rho-1 的研究预览版。这是我们从零开始训练的 19B 全模态推理模型。在单一神经网络内,它能够理解并生成文本、图像和视频,对它们展开逻辑推理,并执行具体动作。
当下大多数 AI 系统本质上都是 Agent 流水线:由一个中心模型进行规划与任务分发,将具体工作移交给特定模态的专用模型。每次交接都会增加延迟,而且每个专用模型只能看到狭隘的局部请求,无法掌握完整上下文。Rho-1 则彻底打破了这种层叠架构——文本、视觉和机器人动作均作为 Token 统一整合在单一上下文窗口之中。
会话实录记录
第 1 轮
用户:画一个低空俯视视角:海面上方崎岖的岩石海角上矗立着一座高大的红白相间条纹灯塔,正值晴朗的正午。
Rho-1(思考):好的,用户需要一张以显著灯塔为特色的海岸风景图。重点在于展现海滨的清澈通透与引人瞩目的建筑对比。对我而言,核心创意在于构图:让宏伟的灯塔与下方连绵的海岸景观形成平衡。首先,……
分镜规划(Shot plan):该画面呈现一幅引人入胜的海岸低空俯瞰景象,一座红白相间条纹的高大灯塔高耸于突入海中的崎岖岩石海角之上。灯塔……
(模型渲染生成 image:0)
第 2 轮
用户:给灯塔画一个检测框。
Rho-1(思考):用户希望在 image:0 上标出灯塔。我将在 image:0 上对灯塔进行标记。
(模型在灯塔周围画出边框)
第 3 轮
用户:让画面动起来:无人机缓慢飞向灯塔。
Rho-1(思考):用户希望将 image:0 制作成无人机靠近灯塔的动态视频。我将以 image:0 的帧作为起点生成 video:0,并制作无人机平稳向前推进、在接近高大建筑时略微下降的动画……
分镜规划(Shot plan):一架航拍无人机缓慢且平稳地接近矗立在崎岖岩石露头上的红白条纹高大灯塔,随着下降展现周围的海洋与海岸岩石……
(模型渲染生成 video:0)
第 4 轮
用户:编辑该视频:变成暴风雪天气,白雪以自然的色彩落在岩石和草地上。保持灯塔、房屋和运镜完全一致。
Rho-1(思考):用户希望将 video:0 编辑为暴风雪场景,同时保持其他所有元素完好无损。我将基于与 video:0 相同的场景生成 video:1:海面上方岩石峭壁上的灯塔,旁边有一座白色小建筑。……
分镜规划(Shot plan):编辑 video:0:保留相同场景、灯塔、白色建筑和摄影机运镜,但改为暴风雪场景,白色雪花稳定飘落,覆盖岩石峭壁表面、草地植被……
(模型渲染生成 video:1)
第 5 轮
用户:两段视频之间有什么变化?
Rho-1(思考):用户询问两段视频之间的变化。以文本回答:第一段视频晴朗明媚,第二段是暴风雪版本。
回答:第一段视频展示了一个晴朗明媚的日子,有灯塔、白色房屋和蔚蓝大海。第二段视频则是同一场景的下雪版本,大雪漫天飞舞并堆积在岩石、悬崖和草地上,整体色调更加柔和阴沉。
模型内部机制(Inside the model)
- 状态(KV 缓存):保存文本推理、回答、边界框;
- 解码器(Latents 转为像素):文本 Head 预测下一个 Token,扩散 Head 预测通往清晰画面的去噪路径;
- Block 结构:Block 1 至 Block N 均采用共享注意力(Shared Attention);
- 理解流(Understanding stream):处理文本 Token(包含用户的输入与模型自身的输出)以及视觉 Token(图像、视频);
- 生成流(Generation stream):处理正在生成的图像或视频片段的噪声潜变量(×8)。
整个会话:五轮交互,一个神经网络,一个随每一轮交互不断增长的状态。
01 绘画 ➔ 02 标框 ➔ 03 动画化 ➔ 04 编辑 ➔ 05 提问
每一次响应都来自同一会话中的同一个模型。它并不是一个多 Agent 协作系统。 这里没有工具调用(Tool call),也没有第二个模型:文本、检测框、图像和视频全都是被读取并写入同一个状态中的 Token。为便于回放展示,生成等待时间已做缩短处理,去噪过程展示为蒸馏模型的 8 步通道。
我们相信这种架构指明了智能的发展方向:不再是将狭窄专用的模型拼接缝合在一起,而是用单一基础模型掌控全流程闭环。Rho-1 能够构思环境、追踪其状态、回答关于它的问题,并在从未丢失上下文主线的情况下让环境动起来。由于组件之间毫无缝隙,整个系统可以进行端到端优化,从而为任何跨模态应用奠定更强大的基石。我们认为这种大一统正是通向**物理 AGI(Physical AGI)**的核心前提。
Rho-1 产生的不是单次输出,而是一个不断演变的世界状态:
- 用对话引导它,你会获得流畅自然的交谈;
- 用实时控制引导它,你会获得持久可交互的模拟;
- 用**运动策略(Motor policies)**引导它,你会获得具身机器人控制。
下文将依次探讨这三个前沿方向。
Rho-1 作为多模态助手
图 1 展示了与 Rho-1 的一次未经剪辑的完整会话。在连续五轮交互中,它绘制了静态场景、定位了其中的物体、将场景制作成视频、编辑视频以改变天气,并解释了前后变化,在整个过程中逐步展开逻辑推理。以往通常需要跨多个专用系统才能完成的工作,如今都在单个模型内部得以搞定。
观察模型视图中的状态如何随着每轮交互而增长。生成图像的请求会被路由至扩散模块,而目标边界框请求则停留在理解侧。无论哪种情况,每一轮都在读取并写入同一个 KV 缓存,该缓存充当了持久的世界状态:
- 推理(Reasoning):每次回复上方的模块显示了模型的思维链(Chain of Thought)。这里没有外挂的 Prompt 增强器,同一个模型既规划分镜又负责渲染。
- 定位(Grounding):由于灯塔正是 Rho-1 生成的,该场景已存在于其上下文之中。边界框直接以坐标 Token 的形式输出并关注该状态,无需任何二级检测模型。
- 动画化(Animating):视频的首帧并非重新编码的图像,而是保存在上下文中的原始表征,因此光照、几何结构和物体一致性得以完整保留。
- 理解(Understanding):当被问及片段之间有何不同时,Rho-1 并非对导出的视频帧运行事后标注程序。它直接读取产生变化的潜在状态(Latent state),因此其回答真正立足于它实际生成的内容。
突破性的生成速度
Rho-1 是一款速度极快的模型。基础版 Rho-1 模型以 0.79× 实时速度(中位数)生成视频,大约 6 秒内即可开始输出可观看的流媒体。
- 多 Agent 管线首片段耗时:13.8 秒(路由 ➔ 扩展 Prompt ➔ 排队 ➔ 生成 ➔ 返回,仅作说明示意)
- Rho-1 首片段耗时:7.0 秒(实测值)
其蒸馏版本(Distilled variant)在几乎没有画质损失的前提下,将去噪轨迹从 99 步骤减至 8 步,直接将系统带入实时交互领域。在我们内部测试的所有模态中,它的速度均位居全球顶级模型之列:
- 返回一个 5.3 秒的视频片段仅需约 1 秒,比我们测过的任何其他视频模型都要快;
- 图像生成速度与最快的专用图像模型并驾齐驱;
- 在生成文本回复的首字时间(Time-to-first-token)测试中拔得头筹。
在人类对话耐心的等待窗口内,一个世界现在可以被想象、质询、编辑并持续推进向前。
基于 Prompt 的即时视频编辑(Rho-1 Flash)
Rho-1 Flash 在固定随机种子(Seed 1234)下,通过 Prompt 实现极速视频编辑:
-
版本 1:一只金毛寻回犬戴着红色圣诞帽坐在松树林的雪地里
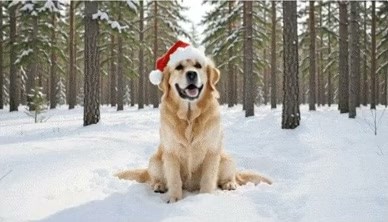
渲染用时 2.01 秒 · 5.3 秒视频 · seed 1234 -
版本 2:一只黑色拉布拉多戴着红色圣诞帽坐在松树林的雪地里
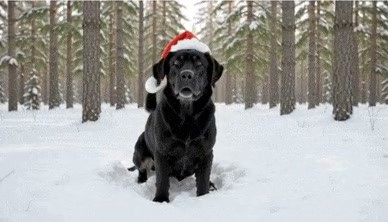
渲染用时 1.11 秒 · 5.3 秒视频 · seed 1234 -
版本 3:一只黑色拉布拉多戴着红色圣诞帽和红色围巾坐在松树林的雪地里

渲染用时 1.11 秒 · 5.3 秒视频 · seed 1234 -
版本 4:一只黑色拉布拉多戴着红色圣诞帽和红色围巾坐在夜晚有极光的松树林雪地里

渲染用时 1.11 秒 · 5.3 秒视频 · seed 1234 -
版本 5:一只哈士奇幼犬戴着红色圣诞帽和红色围巾坐在夜晚有极光的松树林雪地里
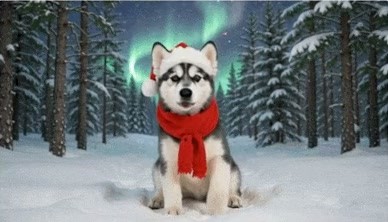
渲染用时 1.15 秒 · 5.3 秒视频 · seed 1234
从 Prompt 输入到视频渲染完成仅需 1.15 秒。蒸馏后的 Rho-1 实现了通过细微 Prompt 修改进行近乎实时的视频编辑。
Rho-1 作为可操控的实时世界模型
单纯的快速生成充其量只是一个更高效的渲染农场。但当生成既实时又具备可控性时,它将解锁本质上完全不同的能力:一个你能够模拟并实施操控的世界模型。
Rho-1 支持连续流式输出,片段接连不断,每一段都严丝合缝地衔接在上一段结束之处,让模拟环境中的时间流永不停歇。新的控制指令可以随时注入:指令进入理解流,更新底层的状态记忆,片刻之后生成流便渲染出新的运动轨迹,整个世界在没有任何剪辑切片痕迹的情况下平滑转变。
例如在连续实时会话中:初始状态设为“放在柜台上的绿色和红色小球”。机械臂在收到指令后进入画面抓取红球,将其抬起,并在被告知放下时将球放回并松手。整个过程实时接收每条控制指令并精准响应。
由于生成过程是一个连续的推演过程(Rollout),我们可以在关键时刻实时监控并操控场景走势:
- 共享开局(0.0 秒):同一初始画面;
- 分支 A(向左倾斜):在半秒时输入“向左倾斜”指令后的演变轨迹;
- 分支 B(向右倾斜):在半秒时输入“向右倾斜”指令后的演变轨迹。
分支发生前的内容完全共享——前半秒两侧是完全一致的帧序列。这两种推演都是有效的,并且可以在规划下一步动作时予以利用。
实时模拟开启的全新应用场景
- 按需生成生成式环境(Generative environments on demand):在实时输入下演进的环境不再是死板的静态资产管线,它转变为一个可交互的模拟器。开发者无需再手动搭建边缘情况(Corner cases)的 3D 世界来评测自动驾驶算法或训练具身机器人策略……
English / 原文
An omni-reasoning model that understands, simulates, and acts.
An omni-reasoning model that understands, simulates, and acts.
Today, we are releasing a research preview of Rho-1 , our 19B omni-reasoning model trained from scratch. Within a single neural network, it understands and generates text, images, and video, reasons over them, and takes actions.
Most AI systems today are agentic pipelines: a central model plans and delegates, handing jobs off to modality-specific specialists. Each handoff adds latency, and each specialist sees only a narrow request, not the full context. Rho-1 collapses that stack. Text, vision, and robotic actions are unified as tokens within a single context window.
Transcript of the recorded session. Turn 1. You: Draw a low aerial view of a tall red-and-white striped lighthouse on a rocky headland above the sea, bright midday. Rho-1, thinking: Okay, so the user wants a scenic coastal image featuring a prominent lighthouse. This is all about crisp maritime clarity and striking architectural contrast. The main creative decision for me is composition: balancing the grand lighthouse with the sweeping coastal landscape below. First, the ⦠Shot plan: This image presents a low-angle aerial view of a striking coastal scene, dominated by a tall, red-and-white striped lighthouse standing on a rugged, rocky headland that juts into the sea. The lighthouse, a ⦠It renders image:0. Turn 2. You: Put a box around the lighthouse. Rho-1, thinking: The user wants the lighthouse marked on image:0. I'll mark the lighthouse on image:0. It draws a box around the lighthouse. Turn 3. You: Animate it: the drone slowly flies toward the lighthouse. Rho-1, thinking: The user wants image:0 animated into a video where the drone approaches the lighthouse. I'll generate video:0 starting from the frame of image:0 and animate the drone moving steadily forward, descending slightly as it approaches the tall ⦠Shot plan: An aerial drone slowly and steadily approaches a tall, red and white striped lighthouse standing prominently on a rugged, rocky outcrop, revealing the surrounding ocean and coastal rocks as it descends ⦠It renders video:0. Turn 4. You: Edit the video: make it a heavy snowstorm, with white snow settling on the rocks and grass in natural colors. Keep the lighthouse, the house and the camera move exactly the same. Rho-1, thinking: The user wants video:0 edited into a heavy snowstorm while keeping everything else intact. I'll generate video:1 from the same scene as video:0: a lighthouse on a rocky cliff above the ocean, with a small white building beside it. The ⦠Shot plan: Edit video:0: keep the same scene, lighthouse, white building, and camera movement, but make it a heavy snowstorm with white snowflakes falling steadily, covering the rocky cliff face, grassy vegetation, and ⦠It renders video:1. Turn 5. You: What changed between the two videos? Rho-1, thinking: The user asks what changed between the videos. Answer in text: the first video was clear, sunny, with falling snow; the second is a snowy storm version. Answer: The first video shows a clear, sunny day with the lighthouse, white house, and blue ocean. The second video is a snowy version of the same scene, with snow falling across the sky and accumulating on the rocks, cliff, and grass, and the overall tone is muted and overcast.
The conversation __Replay
Draw a low aerial view of a tall red-and-white striped lighthouse on a rocky headland above the sea, bright midday.
Rho-1
Thinking Okay, so the user wants a scenic coastal image featuring a prominent lighthouse. This is all about crisp maritime clarity and striking architectural contrast. The main creative decision for me is composition: balancing the grand lighthouse with the sweeping coastal landscape below. First, the â¦
Shot plan This image presents a low-angle aerial view of a striking coastal scene, dominated by a tall, red-and-white striped lighthouse standing on a rugged, rocky headland that juts into the sea. The lighthouse, a â¦
Put a box around the lighthouse.
Rho-1
Thinking The user wants the lighthouse marked on image:0. I'll mark the lighthouse on image:0.
Animate it: the drone slowly flies toward the lighthouse.
Rho-1
Thinking The user wants image:0 animated into a video where the drone approaches the lighthouse. I'll generate video:0 starting from the frame of image:0 and animate the drone moving steadily forward, descending slightly as it approaches the tall â¦
Shot plan An aerial drone slowly and steadily approaches a tall, red and white striped lighthouse standing prominently on a rugged, rocky outcrop, revealing the surrounding ocean and coastal rocks as it descends â¦
Edit the video: make it a heavy snowstorm, with white snow settling on the rocks and grass in natural colors. Keep the lighthouse, the house and the camera move exactly the same.
Rho-1
Thinking The user wants video:0 edited into a heavy snowstorm while keeping everything else intact. I'll generate video:1 from the same scene as video:0: a lighthouse on a rocky cliff above the ocean, with a small white building beside it. The â¦
Shot plan Edit video:0: keep the same scene, lighthouse, white building, and camera movement, but make it a heavy snowstorm with white snowflakes falling steadily, covering the rocky cliff face, grassy vegetation, and â¦
What changed between the two videos?
Rho-1
Thinking The user asks what changed between the videos. Answer in text: the first video was clear, sunny, with falling snow; the second is a snowy storm version.
The first video shows a clear, sunny day with the lighthouse, white house, and blue ocean. The second video is a snowy version of the same scene, with snow falling across the sky and accumulating on the rocks, cliff, and grass, and the overall tone is muted and overcast.
Inside the model
State the KV cache Text reasoning, answers, boxes Decoder latents to pixels Text head predicts the next token Diffusion head predicts the way back to clean Block 1 Block 1 Block 2 Block 2 Block 3 Block 3 Block 4 Block 4 Block 5 Block 5 ⋮ ⋮ Block N Block N shared attention Understanding stream Generation stream Text tokens yours and its own Visual tokens images, video Noisy latents the image or clip being made ×8
The sessionFive turns, one network, one state that grew with every turn.
01Draw __02Box __03Animate __04Edit __05Ask __
Every response comes from the same model in one conversation. It is not an agentic system. There is no tool call and no second model: text, boxes, images and video are all tokens read from and written into one state. Generation waits are shortened for playback, and denoising is drawn as the distilled modelâs 8 passes.
We believe this architecture points toward the future of intelligence: not a patchwork of narrow models wired together, but a single foundation that handles the entire loop. Rho-1 can imagine an environment, track its state, answer questions about it, and set it in motion without ever dropping the thread. With no seams between components, the whole system can be optimized end-to-end, making it a stronger foundation for any application that spans modalities. We see this kind of unification as the core prerequisite for physical AGI.
What Rho-1 produces is not a one-off output but an evolving world state. Steer it with dialogue, and you get fluid conversation. Steer it with real-time controls, and you get a persistent, interactive simulation. Steer it with motor policies, and you get embodied robotic control. This post explores each of these three frontiers in turn.
Rho-1 as a multimodal assistant
Figure 1 shows a single, unedited session with Rho-1. Across five turns, it draws a static scene, locates an object within it, animates the scene into a video, edits the video to change the weather, and explains what changed, reasoning through each step along the way. Work that typically spans several specialized systems is handled within a single model.
Watch the state in the model view grow with each turn. A request to generate a picture routes to the diffusion tower, while a request for a bounding box stays on the understanding side. Either way, every turn reads from and writes to the same KV cache, which acts as a persistent world state:
-
Reasoning: The block above each reply shows the modelâs chain of thought. There is no bolt-on prompt enhancer: the same model plans the shot and renders it.
-
Grounding: Rho-1 generated the lighthouse, so the scene is already in its context. The bounding box is emitted as coordinate tokens attending to that state, with no secondary detection model.
-
Animating: The first video frame isnât a re-encoded image. Itâs the original representation held in context, so lighting, geometry, and object identity carry through.
-
Understanding: When asked what changed between clips, Rho-1 isnât running post-hoc captioning on exported frames. It reads the latent state that produced the change, so its answer is grounded in what it actually generated.
Rho-1 is a fast model. The base Rho-1 model generates video at 0.79Ã real-time (median), with a watchable stream starting in roughly 6 seconds.
Multi-agent pipelinefirst clip13.8 seconds , illustrative
****route
****expand prompt
****queue
****generate
****return
Rho-1first clip7.0 seconds , measured
Bars are to scale with each other; the pipeline row is illustrative.
A distilled variant cuts the denoising trajectory from 99 steps to 8 with minimal quality loss, pushing the system into interactive territory. In our internal testing, it is among the fastest models in the world in every modality we measured. It returned a 5.3-second video clip in about a second, faster than any other video model we timed. It made images as quickly as the fastest dedicated image models. And it was the quickest of the models we tested to the first token of a text response.
A world can now be imagined, interrogated, edited, and carried forward within the window of human conversational patience.
Rho-1 Flash edits a video by prompt with a fixed seed. Version 1: a golden retriever wearing a red santa hat sitting in the snow in a pine forest, rendered in 2.01 seconds. Version 2: a black labrador wearing a red santa hat sitting in the snow in a pine forest, rendered in 1.11 seconds. Version 3: a black labrador wearing a red santa hat and a red scarf sitting in the snow in a pine forest, rendered in 1.11 seconds. Version 4: a black labrador wearing a red santa hat and a red scarf sitting in the snow in a pine forest at night with northern lights, rendered in 1.11 seconds. Version 5: a husky puppy wearing a red santa hat and a red scarf sitting in the snow in a pine forest at night with northern lights, rendered in 1.15 seconds.
Editing by promptRho-1 Flash · Instant · seed 1234
a golden retriever wearing a red santa hat sitting in the snow in a pine forest
rendered in 2.01 s · 5.3 s of video · seed 1234
a black labrador wearing a red santa hat sitting in the snow in a pine forest
rendered in 1.11 s · 5.3 s of video · seed 1234
a black labrador wearing a red santa hat and a red scarf sitting in the snow in a pine forest
rendered in 1.11 s · 5.3 s of video · seed 1234
a black labrador wearing a red santa hat and a red scarf sitting in the snow in a pine forest at night with northern lights
rendered in 1.11 s · 5.3 s of video · seed 1234
a husky puppy wearing a red santa hat and a red scarf sitting in the snow in a pine forest at night with northern lights
rendered in 1.15 s · 5.3 s of video · seed 1234
1.15 s from prompt to video
A distilled Rho-1 enables near-instant video editing through minor prompt modifications.
Rho-1 as a steerable real-time world model
Fast generation alone just yields a faster render farm. But generation that is both real-time and controllable unlocks something fundamentally different: a world model you can simulate and steer.
Rho-1 streams continuously, clip after clip, each picking up exactly where the last left off, so time inside the simulation never stops. New instructions can arrive at any moment. A command enters through the understanding stream, updates the underlying state memory, and moments later the generation stream renders the new trajectory. The world shifts without a single cut.
One continuous real-time session, opened as âgreen and red ball sitting on a counter topâ. A robot arm comes in and grips the red ball when told to, lifts it, then sets it back down and lets go when told to put it down. The panel shows each instruction exactly as it was sent, at the time it was sent.
Because generation is a continuous rollout, a scene can be monitored live and steered at key moments:
Shared · one openingA bank leftB bank right
SharedA · bank left B · bank right
0.0 s
One opening, two continuations. Left, the rollout told to âbank leftâ half a second in; right, told to âbank rightâ. Everything before the split is shared: the first half-second is the same frames on both sides. Both continuations are valid and could be used while planning next steps.
Real-time simulation enables new applications.
Generative environments on demand : An environment that advances under live input is no longer a static asset pipeline, it becomes an interactive simulation. Instead of manually engineering edge-case 3D worlds to benchmark autonomous driving or train embodied robotic policies, developers can spin up reactive environments and perturb them on the fly.
Infinite, steerable livestreams : Running real-time understanding and generation within the same attention context dissolves the boundary between viewer and director. You can watch an uninterrupted stream, adjust the physics or weather mid-frame, inspect object state, and extend the horizon indefinitely, all without a restart.
Rho-1 as a world-language-action model for robotics
Because physical actions and future video frames decode from the same latent state, Rho-1 allows a policy to mentally simulate the next few seconds of an environment and output the trajectory to enact it.
Planning is no longer an external planner querying an auxiliary world model. The network predicting future camera observations is the exact network dictating joint actuation. With actions treated natively as continuous tokens alongside text and pixels, the model does not require an ad-hoc robotics wrapper; the action channels share the core attention space.
One episode with every channel exposed, on a LIBERO simulation task: the observation, the wrist view it predicts against the one it is given, and the seven action channels it emits.
Even under pure text conditioning, Rho-1 exhibits an intuitive grasp of physical contact and rigid-body mechanics. Grippers secure objects that remain solid rather than morphing or clipping into surfaces:
A banana lifted off a plate
A mug carried by its handle
An apple, from the wrist camera
A sponge picked up to wipe
A box lifted off the bench
Folded cloth out of a basket
In practice, to scale beyond scarce teleoperated robot logs, Rho-1 can be paired with our Inverse Dynamics Model. While most internet video lacks logged steering angles or joint torques, an IDM observes raw video and infers the underlying control signals. This unlocks web-scale video as action-labeled pretraining data: Reka IDM reconstructs the implicit actions, and Rho-1 ingests those actions as native tokens within its multi-modal state space.
Limitations
The demos above show what Rho-1 can do today, but real-world deployment requires being candid about the failure modes:
-
Long-Horizon Drift: Extended rollouts degrade structurally before they degrade visually. A 30-second stream may keep photorealistic texture and fine detail while drifting into a structurally incompatible room layout.
-
Grounding Across Time: Object detection and coordinate grounding work reliably on static images, but not yet across video.
-
Editing Stability: Targeted visual editing remains nascent. Our conversational demo shows how an edit works, but consistency across diverse prompts is brittle.
-
Resolution: Native video rollouts are currently capped at 672Ã384.
We believe most of these failures can be attributed to the modest scale of our training compute and data, and we expect them to narrow as we scale both.
One model: a symmetric architecture
Most multimodal systems are asymmetric. Vision-Language Models (VLMs) ingest text, images, and video, but only emit text. Video diffusion models take in multimodal conditioning, but only emit pixels. This input-output imbalance confines each model to half the interactive loop.
Rho-1 restores full symmetry. Every signal entering or leaving the network belongs to one of two native formats:
-
Discrete tokens encode text, symbolic reasoning, and high-level commands.
-
Continuous tokens encode image latents, video frames, robotic actions, and proprioception.
Because outputs share the same formats as inputs, anything the model generates can be fed straight back into its context. And because each modality keeps its natural form, Rho-1 never has to quantize rich continuous dynamics into lossy discrete tokens, or force language into continuous approximations.
video
image
text
actions
proprioception
Rho-1 Predicts what happens next
future video
future image
future text
future actions
future proprioception
The same five channels on both sides. Predicting the next frame, the next instruction and the next action are one operation, not three models sharing a bus.
Within each transformer block, compute is split across two expert weight streams: an understanding stream for language and visual parsing, and a generation stream that denoises latents into images and video. Crucially, these streams do not run in isolation:
-
Shared Attention and State: Tokens from both streams attend to one another, operating over the same KV cache. User instructions, chain-of-thought traces, prior video frames, and emitted motor policies all accumulate in one context.
-
Zero-Latency Handoffs: The understanding stream decides the output modality. When a response requires visual synthesis, it emits a discrete handoff token, and the generation stream immediately begins rendering from the full accumulated state.
State the KV cache text:0 user text:1 assistant image:0 assistant text:2 user text:3 assistant video:0 assistant text:4 user Text reasoning, answers, boxes Decoder latents to pixels Reasoning, shot plan, answers<|content_media|> hands off Noise to latentsin 8 passes(99 for the base model) Text head predicts the next token Diffusion head predicts the way back to clean Block 1 Block 1 Block 2 Block 2 Block 3 Block 3 Block 4 Block 4 Block 5 Block 5 ⋮ ⋮ Block N Block N shared attention Understanding stream Generation stream Text tokens yours and its own Visual tokens images, video Noisy latents the image or clip being made ×8
__Understanding stream · text and visual tokens __Generation stream · noise to pixels
Inputs at the bottom, outputs at the top. Both streams sit in every block and share attention; on the left, the state, colored by the stream that wrote each entry. The generation stream loops from noise to a clean result, in 8 passes for the distilled model and 99 for the base model.
Rho-1 is optimized end-to-end under two concurrent objectives:
-
Next-token prediction for discrete sequences.
-
Flow matching for continuous image, video, and action generation.
Because both streams share attention and a common representation space, improvements do not stay siloed. We hypothesize that when the model sharpens its spatial reasoning during text pretraining, its video consistency improves. When it learns richer physical dynamics from embodied trajectories, its real-time steering becomes more grounded. Progress compounds across the entire network at once.
Early on the compute curve
Every result in this post comes from a checkpoint trained from scratch on just 320 H100 GPUs for three months, a tiny fraction of the compute behind modern frontier language and video models. Rho-1 is a functional proof-of-concept and an architectural direction, not a finished product.
To us, that modest compute budget is the most compelling takeaway. The failure modes highlighted earlier, from structural drift and limited temporal grounding to brittle edits and lower native resolution, are the kinds of problems that have historically improved with scale.
More importantly, scaling a unified architecture yields compounding returns. In a fragmented pipeline, additional compute must be divided among an LLM, an image generator, a video backbone, and an action policy. In Rho-1, every added FLOP goes into one model, so gains in reasoning, visual generation, and physical control can reinforce one another rather than being trained in isolation.
Infrastructure for serving omni models
A unified architecture fundamentally shifts the systems economics of inference. When reasoning, multimodal generation, visual grounding, and motor control collapse into a single set of weights, conventional LLM serving frameworks, designed for autoregressive text generation over a growing KV cache, are no longer enough.
We pursue this research not only to explore frontier model designs, but to build the runtime systems required to serve them at scale. Interleaving continuous diffusion trajectories with discrete autoregressive decoding exposes unprecedented runtime bottlenecks:
-
Heterogeneous Memory Layouts: High-throughput discrete KV caches must coexist in HBM alongside transient continuous latent states without causing fragmentation.
-
Shifting Compute Intensity: Workloads swing between compute-bound dense attention during visual synthesis and memory-bandwidth-bound autoregressive decoding during text generation.
-
Hard Real-Time Latency: Interactive steering leaves little room for pipeline bubbles. The system must ingest new instructions and update trajectories within fractions of a second.
Every finding from Rho-1 feeds directly into our production serving engine on Reka Cloud. The choices behind Rho-1, from token representation to kernel scheduling, shape how we optimize memory bandwidth, schedule execution, and co-locate multimodal workloads in production. Scaling unified models is only half the equation. The other half is building the runtime infrastructure that makes them fast, reliable, and economically viable to deploy.
Sample gallery
Unedited, single-pass outputs across diverse domains, presented at Rho-1âs native runtime resolution. 60 clips, 10 domains, one checkpoint with no per-domain fine-tuning. Each clip represents an active latent state, an entry point into an environment the model can simulate, steer, and carry forward indefinitely.
All 58 Real-world driving 5 Video games 15 Robotics 5 Aerial 5 First person 4 Weather 5 Nature 5 Industrial 5 Urban 4 Interiors 5
Real-world driving
05 clips
Rho-1 simulates real driving conditions from the driverâs seat, on highways, city streets at night, and desert and mountain roads.
Video games
15 clips
Rho-1 renders and moves through game worlds in every style, from photoreal open worlds to voxel and low-poly.
Robotics
05 clips
Rho-1 sees from a robotâs point of view: warehouse vehicles, quadrupeds, rovers and industrial arms at work.
Aerial
05 clips
Rho-1 simulates aerial footage for drone navigation and survey, the flight data that autonomous systems train and test on, without flying a mission.
First person
04 clips
Rho-1 simulates egocentric footage and the movement behind it, the first-person view an embodied agent sees as it rides, skis or paddles.
Weather
05 clips
Rho-1 simulates real weather: supercells, blizzards, sandstorms, storm surf and rolling fog.
Nature
05 clips
Rho-1 renders the natural world in motion, from reefs and waterfalls to wildlife and the aurora.
Industrial
05 clips
Rho-1 models industrial sites and processes, including foundries, data centers, mines and production lines.
Urban
04 clips
Rho-1 moves through cities: rain-soaked streets, alleys, rooftops and transit.
Interiors
05 clips
Rho-1 keeps indoor spaces consistent as the camera moves through libraries, kitchens, corridors and cathedrals.
Get in touch
Rho-1 is currently available as a research preview.
If you are building frontier applicationsâembodied robotics, interactive simulation environments, or closed-loop vision-action systemsâor are looking to deploy optimized omni architectures at scale, weâd love to collaborate: contact@reka.ai.
Reka Cloud
Interested in partnering?
What we learn building Rho-1 goes straight into our serving stack on Reka Cloud. If you want to train, customize or deploy multimodal models on infrastructure engineered for performance, efficiency and scale, tell us about your project.