超越节省工时:构建 Agent 自动化的商业论证
英文标题:Beyond hours saved: Building the business case for agentic automation
传统的 RPA 投资回报率(ROI)模型以节省工时为核心,难以衡量 Agent 自动化在异常处理、决策质量和变更适应性方面创造的价值。本文提出“Agentic Value Model(Agent 价值模型)”,要求企业从释放产能、异常与错误成本、决策质量、维护经济性四个维度评估价值,并将价值实现责任落实到具体负责人。文章还提供了按任务复杂度和决策风险划分工作流的优先级矩阵,帮助 AI CoE 判断应继续使用 RPA、引入 Agent,还是强化控制措施。对开发者和企业管理者而言,关键不在于将 Agent 直接嵌入既有流程,而在于围绕 Agent 重构工作流、持续衡量成本与结果,并设置明确的止损规则。
 1.3 MB
 1.3 MB
 2.4 KB
 345.0 KB
 141.2 KB
 346.5 KB
 106.6 KB
 25.7 KB
 26.8 KB
 61.2 KB
中文
能够通过推理和适应来完成任务的 Agent 自动化软件,正在进入 AI 卓越中心(AI CoE)的路线图。但企业用于论证自动化投资的标准方法——节省工时乘以人工成本,再减去构建成本——是为机器人流程自动化(RPA)等基于规则的工具设计的。这一模型遗漏了 Agent 所创造的大部分价值。
本文介绍一个框架,帮助 AI CoE 负责人构建能够捕捉 Agent 自动化完整价值的商业论证。你将了解为何 RPA 时代的 ROI 模型存在不足、如何衡量它遗漏的价值,以及哪些工作流值得使用 Agent 实现自动化。
为什么传统商业论证存在不足
经典的投资回报率(ROI)模型,是为稳定、高吞吐量、基于规则的工作而构建的:统计交易量、测量处理分钟数、乘以完全成本费率,再减去构建成本。RPA 正是凭借这套标准确立了自身价值。
这一模型假定世界仍与其诞生时一致。它假定流程稳定,因此忽略流程变化时维护自动化的成本;它假定任务基于规则,因此没有为异常情况设置成本项;它假定工作本身就是全部工作,因此从不计算人工监督的成本。它还将节省的一小时视为可直接兑现的价值,但释放出来的产能往往会被积压工作重新填满,永远不会进入损益表(P&L)。麦肯锡指出,企业持续犯下的错误,是没有为将节省工时转化为实际成果的工作投入足够资金:成功的 AI 转型遵循“1:3:5 模式”,即“每在 Agent 技术上投资 1 美元,组织会在流程重构上投入 3 美元,在能力建设和采用上投入 5 美元。然而,大多数公司完全颠倒了这一公式”(McKinsey, “Agentic AI change management: Closing the adoption gap,” 2026)。
我们通常认为自动化的价值存在于任务本身,但对于 Agent 自动化而言,大部分价值存在于任务周边:判断、异常处理以及跨系统协调。真正的收益来自围绕 Agent 重新设计工作流,而非将 Agent 直接放入一个未改变的流程中。
旧模型遗漏的价值维度
更好的商业论证应衡量四个价值维度,以及决定这些价值能否进入 P&L 的一个条件。我们将其称为 Agentic Value Model(Agent 价值模型)。
节省时间。 这一项仍然需要计算,但 Agent 能将其扩展至固定规则的 RPA 难以处理、或只有通过大量异常逻辑才能处理的工作。衡量方式相同,只是 Agent 将其应用于更广泛的工作基础。
异常处理。 异常承载了很大一部分成本。AWS 指导提供了规划区间:纠正一个错误的成本可能达到原始交易成本的 1.5 至 4 倍,而人为错误可能占运营成本的 2% 至 15% (AWS Prescriptive Guidance, “Assessing your current human-process costs”)。返工系数为团队发现的异常定价;错误百分比则为漏网的异常定价。仅计算人工成本的案例会遗漏两者。
决策质量。 Agent 可以大规模执行统一政策,并记录推理依据,但其一致性和错误率需要持续衡量。正如 AWS 所指出的,“低频、高价值决策可能因提升决策质量而非降低成本,足以证明采用 Agent 辅助的合理性”(AWS Prescriptive Guidance, “Understanding agentic AI economics”)。在信贷、定价或风险领域,一次更好的决策所带来的价值,就可能超过一整年节省的处理分钟数。
变更韧性与维护经济性。 这一维度可能向两个方向发展。脚本较为脆弱:当界面或上游系统发生变化时,脚本会失效,必须由人员重建。Agent 可以在无需重写的情况下吸收部分变化,但它们并非消除了维护工作,而是将维护转移到评估、提示词、监控和模型运营中,同时运行 Agent 自身也会产生成本。商业论证应以避免的脆弱脚本维护成本,对冲持续的 Agent 运营成本。因此,对于频繁变化的流程,计算结果可能更支持 Agent;而对于几乎不变的流程,结果可能并非如此。
支配上述四个维度的条件是价值实现:每项收益都需要一个明确机制,将运营改进转化为经济价值,并指定一名负责的所有者。对于释放的人力,这意味着要么减少支出,要么将产能重新分配给一个明确且可衡量的结果。
以一个理赔分流流程为例,以下数字仅用于说明。该流程每年处理 20 万份理赔,每份理赔约需 12 分钟(返工前),完全成本为每小时 45 美元,基础成本约为 180 万美元。若将其中常规的 70% 实现自动化,则可释放约 2.8 万小时,即约 126 万美元的产能,尚未扣除这些理赔仍然需要的监督时间。大多数案例正是在这里出错,因为释放工时不等于节省资金。只有在企业减少人员、削减承包商支出、加班费或外包费用时,企业才真正少花钱。否则,相同员工仍在工资单上,P&L 中不会体现这 126 万美元。若通过自然减员和降低加班费只实现其中一半,案例中应计入约 63 万美元,而不是全额。
更常见的结果是重新部署这些人员,此时其价值取决于他们随后创造的产出。对于每一小时释放出来的工时,应计入重新部署的价值或现金成本降低,不能两者同时计入。 然后再加入仅计算人工成本的案例无法看到的价值。在需要纠正的 8% 理赔中(1.6 万份),若纠正成本为约 9 美元处理成本(按每小时 45 美元、12 分钟计算)的 3.5 倍,则年度纠正风险敞口约为 50.4 万美元。这是基准值,而非 Agent 价值。价值在于 Agent 所消除的份额:若减少 40%,并按 75% 的实现系数调整,模型化收益约为 15.1 万美元。这甚至还未计算一次更优欺诈标记决策的价值。由于 12 分钟的基础时间不包括返工,该成本池不会与释放产能重叠。若你的基准已包含返工时间,则只能在一个成本池中计算这些节省。这样的案例才能给出财务部门能够认可的数字。
为保持计算一致,应以相同方式估算每个价值池并扣除成本,如下表所示。
| 价值池 | 基准 | 预期变化 | 实现系数 | 负责人 |
|---|---|---|---|---|
| 释放产能 | 工时 × 完全成本费率 | 自动化比例 | 仅当产能被重新部署至指定结果或支出下降时计入 | 运营负责人 |
| 异常和错误成本 | 纠正成本 + 错误损失 | 预期降幅 | 实际捕获比例 | 质量负责人 |
| 决策质量 | 更优决策的价值 | 每次决策的提升 | 可归因份额 | 业务领域负责人 |
| 变更韧性与维护经济性 | 脚本故障修复成本 + 停机时间 | 避免的重建工作、更快的变更适应 | 避免重建的比例;Agent 成本在公式中仅净额计算一次 | 工程负责人 |
将完整计算表述为一行,为每项收益分配唯一的价值池,避免重复计算:年度净价值 = 已实现的产能价值 + 避免的纠正和错误成本 + 决策结果提升 + 避免的维护和停机成本,减去年化实施成本,减去 Agent 运行时、集成、评估、监督、治理和变更管理成本,减去 Agent 新引入错误造成的损失。Agent 未消除的错误已经不在“避免成本”项中,因此不要再次扣除。对于多年期项目,应在实际发生实施支出的年份确认实施成本,而不是将其年化;应随着采用率提升逐步增加收益,并将年度现金流折现为净现值(NPV)。
Amazon Quick 内部的自动化服务 Amazon Quick Quick Automate 的三个早期部署案例,展示了这些维度如何发挥作用。Kitsa 是一家临床试验站点选择公司,它实现了从数十万个网站中提取超过 50 个数据点的自动化。该公司报告称,在 96% 覆盖率下实现了 91% 的成本节省和 96% 更快的数据获取速度,并将低置信度案例转交给审核人员处理(节省时间和异常处理)。正如 Kitsa 联合创始人兼 CTO Rohit Banga 在 AWS Machine Learning Blog 的文章中所言,大规模整合高质量站点数据打破了一个核心瓶颈,使其 Site Finder Agent 能够以更高精度权衡更多站点。
dLocal 是一家跨境支付提供商,其在受控评估中实现了多达 75% 商户合规审查的自动化。这使专家能够处理复杂、高风险案例(决策质量),并增加了对政策漂移的持续检查,而这类问题定期人工审查可能会遗漏(变更韧性)。dLocal 表示,过去花费数小时进行例行检查的专家,现在将这些时间用于需要监管判断的案例。
Genpact 则在多个 SAP 系统中实现供应链风险自动化,并报告将中断影响分析时间从 2 至 3 天缩短至数分钟。这类跨系统协调不属于任何单一记录系统所能拥有的范围(节省时间和决策质量)。这些部署没有一个证明了全部四个价值池,这正是商业论证必须分别估算每一项的原因。
用于优先级排序的框架
根据两个维度为每个候选工作流评分。第一个维度是任务复杂度,即任务需要多少推理、上下文和适应能力。第二个维度是决策风险,即决策出错的代价,它决定了能够授予多大程度的自主权。这两个维度均来自 AWS 经济性指导,共同构成一个可供指导委员会使用的二维矩阵。
低复杂度、低风险:继续使用 RPA,因为 Agent 在此类场景只会增加成本而不会增加价值。高复杂度、低风险:这是产能型场景,应为吞吐量和异常吸收能力实现自动化。高复杂度、高风险:这是决策质量型场景,应保留人在回路中,并以更优决策来论证投入。低复杂度、高风险:这是护栏型场景,应加强该步骤周围的控制,而不是增加其不需要的推理能力。
一个实用的捷径是:如果人员需要在多个系统之间操作,并在每一步解读模糊上下文,就应评估 Agent 方法。如果路径保持确定性,RPA 可能仍然更便宜。使用 Agentic Value Model 决定需要衡量什么,使用这个矩阵决定优先处理什么。
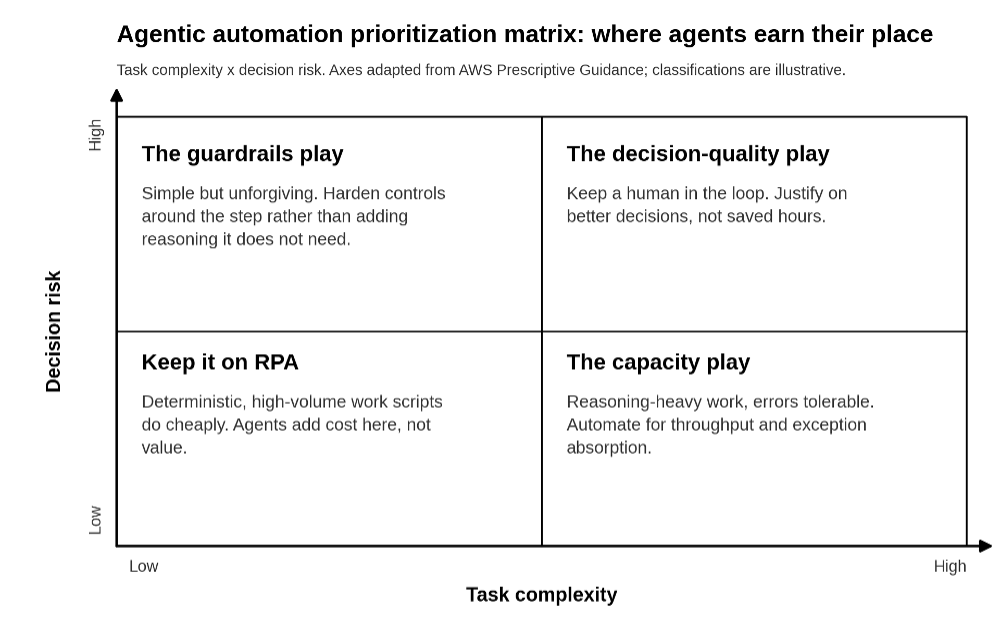
图 1:Agent 自动化优先级矩阵,坐标轴改编自 AWS Prescriptive Guidance,分类仅作示例说明
为管理层构建商业论证
应将投资呈现为工作流组合,而不是单一项目。麦肯锡的研究解释了为何孤立的试点会停滞:近三分之二的企业已尝试使用 Agent,但将其规模化并产生可衡量价值的企业不足 10% (McKinsey, “Scaling agentic AI with data transformations,” 2026)。价值来自于明确结果、将 Agent 深度嵌入核心工作流,并围绕它们重新设计运营模式。应向管理层提出 3 至 5 个已排序的优先领域,每个领域都附带其四维价值论证。
最能说服持怀疑态度 CFO 的一件事,是止损规则:按照明确的盈亏平衡目标分阶段投入,并预先设定停止资助表现不佳 Agent 的节点。将每个领域与管理层已跟踪的关键绩效指标(KPI)联系起来,无论是服务成本、周期时间、净推荐值(Net Promoter Score)还是合规风险敞口。还应将治理视为加快推进的方式:有边界的自主权、高风险场景下的监督,以及设计之初即具备的可审计性,能够让企业随着证据积累扩大 Agent 的自主范围。
开始使用 Amazon Quick
Amazon Quick 将研究、商业智能和自动化整合到统一的 Agent 体验中。通过其自动化服务 Quick Automate,团队可以在企业工作流中编排 UI 操作、API 调用和人工审核。这会产生案例级的执行数据,CoE 可以将其与运营和财务 KPI 相结合,在价值实现过程中进行衡量。
这种衡量可将第一个项目转变为一个项目组合。一旦开始寻找这四类价值池,你往往会在任何需要人员跨系统操作、解读上下文并手动处理异常的地方发现它们。将一个工作流投入生产,建立其价值池和运营成本的基准,指定负责人,并证明数字。随后,随着每个新工作流报告结果,整个项目组合的商业论证将逐步积累。
结论
关键问题是:Agent 自动化能在哪些方面提供现有工具无法创造的价值,以及如何在投入前证明这种价值。本文所描述的纪律——估算每个价值池、采用现实的实现系数、设定止损规则——正是让这种证明具备可信度的基础。能够在一个工作流上证明价值的团队,可以用经衡量的结果而非预测,为下一个工作流提供资金。若要了解其底层经济学,一个良好的起点是 AWS 关于 Agentic AI 经济学的 Prescriptive Guidance。
关于作者
Manish Ballal
Manish 是 AWS Amazon Quick 的产品合作平台主管,负责构建
English / 原文
Agentic automation, software that reasons and adapts to complete tasks, is showing up on AI center of excellence (AI CoE) roadmaps. But the standard way companies justify automation investments, hours saved times labor cost minus build cost, was designed for rule-based tools like robotic process automation (RPA). That model misses most of the value agents create.
In this post, we introduce a framework AI CoE leaders can use to build a business case that captures the full value of agentic automation. You will learn why the RPA-era ROI model falls short, how to measure the value it misses, and which workflows are worth automating with agents.
Why the traditional business case falls short
The classic return on investment (ROI) model was built for stable, high-volume, rule-based work: count the transactions, measure the minutes, multiply by a loaded rate, subtract the build cost. RPA earned its place on those terms.
The model assumes the world it was built for. It assumes processes are stable, so it ignores the cost of maintaining automation as they change. It assumes tasks are rule-based, so it has no line item for exceptions. It assumes the work is the whole job, so it never counts the cost of human oversight. And it treats a saved hour as banked value, when freed capacity often refills with backlog and never reaches the profit and loss statement (P&L). Underfunding the work that turns saved hours into results is the mistake McKinsey says companies keep making: successful AI transformations follow a “1:3:5 pattern,” where “for every dollar invested in agentic technology, organizations spend three on process redesign and five on capability building and adoption. However, most companies invert this formula entirely” (McKinsey, “Agentic AI change management: Closing the adoption gap,” 2026).
We assume the value of automation lives in the task, but in agentic automation most of it lives around the task: the judgment, the exceptions, the coordination across systems. The real gains come from redesigning the workflow around agents, not from dropping an agent into an unchanged process.
The dimensions of value the old model misses
A better business case measures four dimensions of value, plus the condition that determines whether they reach the P&L. We call it the Agentic Value Model.
Time savings. This still counts, but agents extend it to work that fixed-rule RPA handles poorly or only through extensive exception logic. The measure is the same. Agents apply it to a larger base of work.
Exception handling. Exceptions carry much of the cost. AWS guidance gives planning ranges: correcting an error can cost 1.5–4 times the original transaction, and human error can account for 2–15 percent of operational cost (AWS Prescriptive Guidance, “Assessing your current human-process costs”). The rework multiplier prices the exceptions your team catches. The error percentage prices the ones that slip through. Labor-only cases omit both.
Decision quality. Agents can apply a common policy at scale with logged rationale, though consistency and error rates need continuous measurement. As AWS notes, “low-volume, high-value decisions might justify agentic assistance for improved decision quality rather than cost reduction” (AWS Prescriptive Guidance, “Understanding agentic AI economics”). A single better decision in credit, pricing, or risk can dwarf a year of saved minutes.
Change resilience and maintenance economics. This one goes both ways. Scripts are brittle: when a screen or upstream system changes, they break and someone rebuilds them. Agents absorb some variation without a rewrite, but they shift maintenance into evaluations, prompts, monitoring, and model operations rather than removing it, and running them carries its own cost. The case nets brittle-script maintenance avoided against ongoing agent operating cost, so in processes that change often the math may favor agents, and in frozen processes it might not.
The condition that governs all four is value realization: every benefit needs a defined mechanism that converts an operational improvement into economic value, plus an accountable owner. For released labor, that means reducing spend or redirecting capacity to a named, measurable outcome.
Consider a claims-triage process, with illustrative figures. It handles 200,000 claims a year at about 12 minutes per claim (before rework) and $45 an hour fully loaded, a base cost of roughly $1.8 million. Automate the routine 70 percent and you release about 28,000 hours, or roughly $1.26 million of capacity, before the oversight time those claims still need. That’s where most cases go wrong, because freeing hours isn’t the same as saving money. The company only spends less if it employs fewer people or cuts contractor, overtime, or outsourcing spend. Otherwise, the same people stay on the payroll and the P&L never sees the $1.26 million. If attrition and lower overtime capture half of it, the case should carry about $630,000, not the full figure.
Redeploying the people is the more common outcome, and then the value is what they now produce. For each released hour, count redeployed value or a cash cost reduction, not both. Then add what the labor-only case cannot see. Of the 8 percent needing correction (16,000 claims), a correction cost of 3.5 times the roughly $9 handling cost (12 minutes at $45 an hour) gives about $504,000 in annual correction exposure. That is a baseline, not agentic value. The value is the share the agent removes: a 40 percent reduction, adjusted by a 75 percent realization factor, is a modeled benefit near $151,000. That’s before you price a single improved fraud-flag decision. Because the 12-minute base excludes rework, this pool doesn’t overlap with released capacity. If your baseline includes rework time, count those savings in one pool only. That version of the case produces a number finance can defend.
To keep the math consistent, size every value pool the same way and net the costs, as summarized in the following table.
| Value pool | Baseline | Expected delta | Realization factor | Owner |
|---|---|---|---|---|
| Released capacity | Hours × loaded rate | % automated | Only if redeployed to a named outcome or spend falls | Ops lead |
| Exception and error cost | Correction cost + error losses | Expected reduction | Fraction captured | Quality lead |
| Decision quality | Value of better decisions | Uplift per decision | Attributable share | Domain owner |
| Change resilience and maintenance economics | Break-fix cost of scripts + downtime | Avoided rebuilds, faster change accommodation | Share of rebuilds avoided, with agent costs netted once in the formula | Engineering lead |
State the whole thing as one line, assigning each benefit to one pool so double-counting can’t slip through: Net annual value = realized capacity value + avoided correction and error costs + decision-outcome uplift + avoided maintenance and downtime, minus annualized implementation cost, minus agent runtime, integration, evaluation, oversight, governance, and change-management costs, minus losses from any new errors the agent introduces. Errors the agent does not remove already sit outside the avoided-cost term, so do not subtract them a second time. For a multiyear program, book implementation cost in the year you spend it rather than annualizing it, ramp benefits as adoption grows, and discount the yearly cash flows to net present value (NPV).
Three early deployments of Amazon Quick Automate, the automation service within Amazon Quick, show the dimensions at work. Kitsa, a clinical-trial site-selection company, automated extraction of more than 50 data points across hundreds of thousands of websites. It reported 91 percent cost savings and 96 percent faster data acquisition at 96 percent coverage, routing low-confidence cases to reviewers (time savings and exception handling). As Kitsa co-founder and CTO Rohit Banga noted in the AWS Machine Learning Blog post, unifying high-quality site data at scale broke a core bottleneck. That let its Site Finder Agent weigh more sites with greater precision.
dLocal, a cross-border payments provider, automated up to 75 percent of merchant-compliance reviews in controlled evaluations. That freed specialists for complex, high-risk cases (decision quality) and added continuous checks for policy drift that a periodic manual review would miss (change resilience). dLocal reports that specialists who used to spend hours on routine checks now spend that time on cases that need regulatory judgment.
And Genpact, automating supply-chain risk across multiple SAP systems, reports cutting disruption-impact analysis from 2–3 days to minutes. That’s the kind of cross-system coordination that no one system of record owns (time savings and decision quality). None of these deployments proves all four pools, which is why the case has to size each one separately.
A framework for prioritization
Score every candidate workflow on two axes. The first is task complexity, how much reasoning, context, and adaptation it requires. The second is decision risk, the cost of getting it wrong, which sets how much autonomy you can grant. Both axes come from the AWS economics guidance, and together they form a two-by-two matrix a steering committee can use.
Low complexity, low risk: keep it on RPA, since agents add cost here without adding value. High complexity, low risk is the capacity play, so automate for throughput and exception absorption. High complexity, high risk is the decision-quality play, so keep a human in the loop and justify on better decisions. Low complexity, high risk is the guardrails play, so harden controls around the step rather than adding reasoning it doesn’t need.
A useful shortcut: if a person moves across systems and interprets ambiguous context at each step, evaluate an agentic approach. If the path stays deterministic, RPA may still be cheaper. Use the Agentic Value Model to decide what to measure and this matrix to decide what to prioritize.
Figure 1: Agentic automation prioritization matrix, with axes adapted from AWS Prescriptive Guidance and illustrative classifications
Building the case for leadership
Present the investment as a portfolio of workflows rather than a single project. McKinsey’s research shows why isolated pilots stall: nearly two-thirds of enterprises have experimented with agents, but fewer than 10 percent have scaled them to tangible value (McKinsey, “Scaling agentic AI with data transformations,” 2026). Value comes from defining the outcomes, embedding agents deep in core workflows, and redesigning operating models around them. Bring leadership three to five prioritized domains, each with its four-dimension case.
The one thing that wins over a skeptical CFO is a stop rule: stage the investment with explicit break-even targets and predefined points to stop funding agents that underperform. Connect each domain to a key performance indicator (KPI) leadership already tracks, whether cost-to-serve, cycle time, Net Promoter Score, or compliance exposure. And treat governance as a way to move faster: bounded autonomy, oversight where risk is high, and auditability by design let you widen agent autonomy as the evidence builds.
Getting started with Amazon Quick
Amazon Quick brings research, business intelligence, and automation into one agentic experience. With Quick Automate, its automation service, teams orchestrate UI actions, API calls, and human review across enterprise workflows. This produces case-level execution data a CoE can pair with operational and financial KPIs to measure value as it’s realized.
That measurement turns a first project into a portfolio. After you look for the four value pools, you tend to find them wherever a person moves between systems, interprets context, and clears exceptions by hand. Put one workflow into production, baseline its value pools and operating cost, name an owner, and prove the number. Then the portfolio case accrues as each new workflow reports results.
Conclusion
The question is where agentic automation delivers value that your existing tools can’t, and how to prove it before spending. The discipline this post describes, sizing every value pool, applying realistic realization factors, and setting stop rules, is what makes that proof credible. Teams that prove value on one workflow can fund the next from measured results rather than projections. For the underlying economics, a good starting point is the AWS Prescriptive Guidance on agentic AI economics.
About the authors
Manish Ballal
Manish is a Principal, Product Partnerships for Amazon Quick at AWS, where he builds strategic partnerships that bring agentic AI solutions to customers. Previously, as the founding product go-to-market lead for Amazon Quick Automate, he led its commercialization from initial concept through global launch. He has more than 20 years of experience across consulting, enterprise sales, product management, and go-to-market roles in financial services, healthcare and life sciences, and technology. His work has followed the evolution of enterprise automation, from rules-based robotic process automation to AI-powered and agentic workflows.
Sumit Wasuja
Sumit is a product leader whose work has helped shape the evolution of automation from rule-based process orchestration to intelligent, agentic workflows. As the founding product leader for Amazon Quick Automate at AWS, he leads the development of agentic AI systems that help organizations automate complex end-to-end business processes, from natural language descriptions to working workflows that run under human oversight. Over nearly two decades, Sumit has advised and led transformations for some of the world’s largest enterprises across financial services, healthcare, energy, and technology, helping them reimagine how work gets done through the progressive application of automation, AI, and human-machine collaboration.