🔶 85,000 美元 token 之后:我在 Lovable 规模化智能体编程中的收获
英文标题:🔶 $85,000 in tokens later: What I learned from scaling agentic coding at Lovable
自 1 月加入 Lovable 以来,作者个人 token 月支出从 600 美元飙升至 2.5 万美元,累计达 8.5 万美元。他将人工审查聚焦于高影响力决策,引入 AI 风险分类器和本地审查‑修复流水线,使每周合并 PR 数突破 150 个。AI 代码审查已在多数场景优于人工,但需要配套的风险分级、小 PR 拆分以及注意力管理策略。对开发者而言,这意味着应把精力从逐行审码转向系统设计,并建立面向智能体的可扩展工作流。
 1.3 MB
 28.1 KB
 44.2 KB
 23.6 KB
 39.3 KB
 397.3 KB
 75.5 KB
 2.4 MB
 147.2 KB
 225.9 KB
1.3 MB
中文
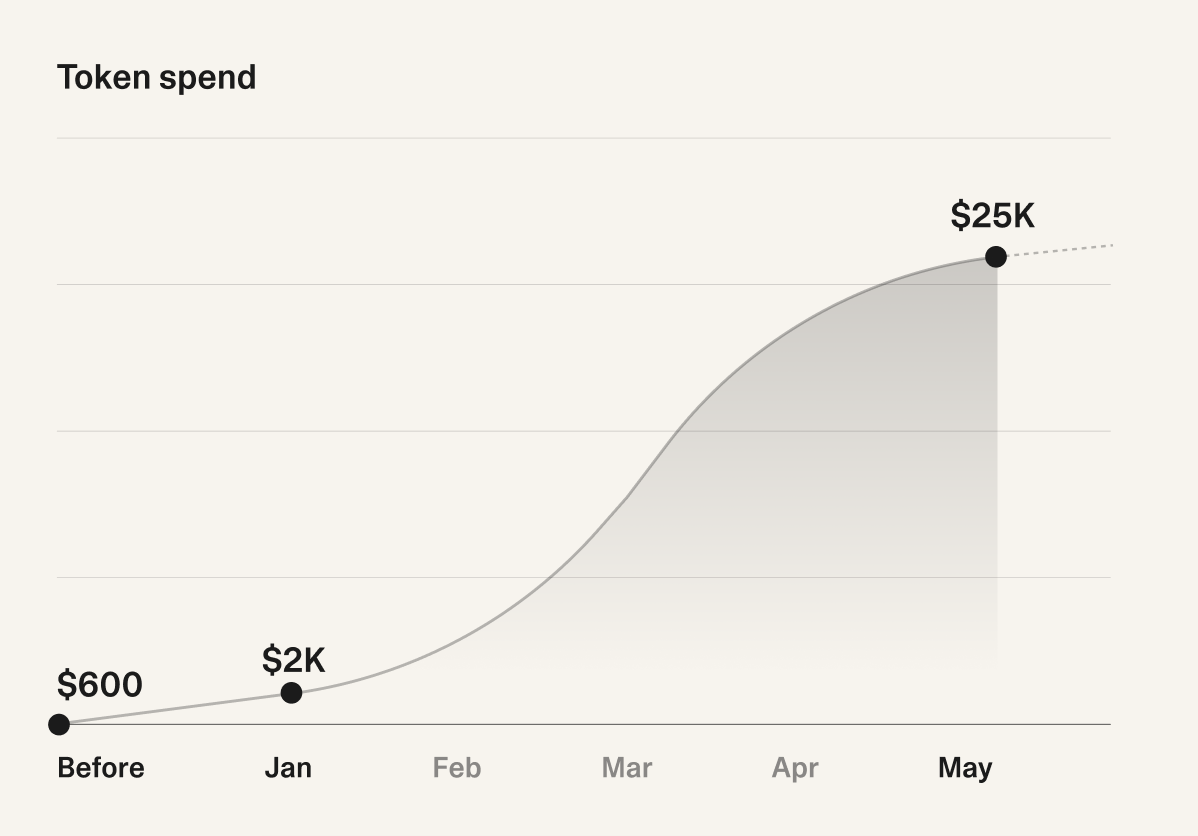
我于今年 1 月加入 Lovable。在此之前,我每月在编程任务上大概使用 600 美元的 token。来到这之后,更大的范围、更大的项目,以及按需使用 token 的自由,让我的个人支出在 5 月时增长到每月约 2.5 万美元,自 1 月以来的总支出约 8.5 万美元。以下是我比大多数人更卖力推进时发生的事,以及我在这个过程中学到的。
开发流程
2026 年 1 月,我的智能体编程流程还包含计划模式、权限请求和传统的代码审查。一个高产周意味着合并 20–30 个 PR。
到了 6 月,我有了一个专门的智能体为其他智能体编写任务,并有多级实现和审查智能体。对于大型变更,工作单元是 10 个 PR 的堆栈,而非单个 PR。人工审查只针对重要决策,很少针对代码。一个高产周现在意味着合并 150 个以上的 PR。
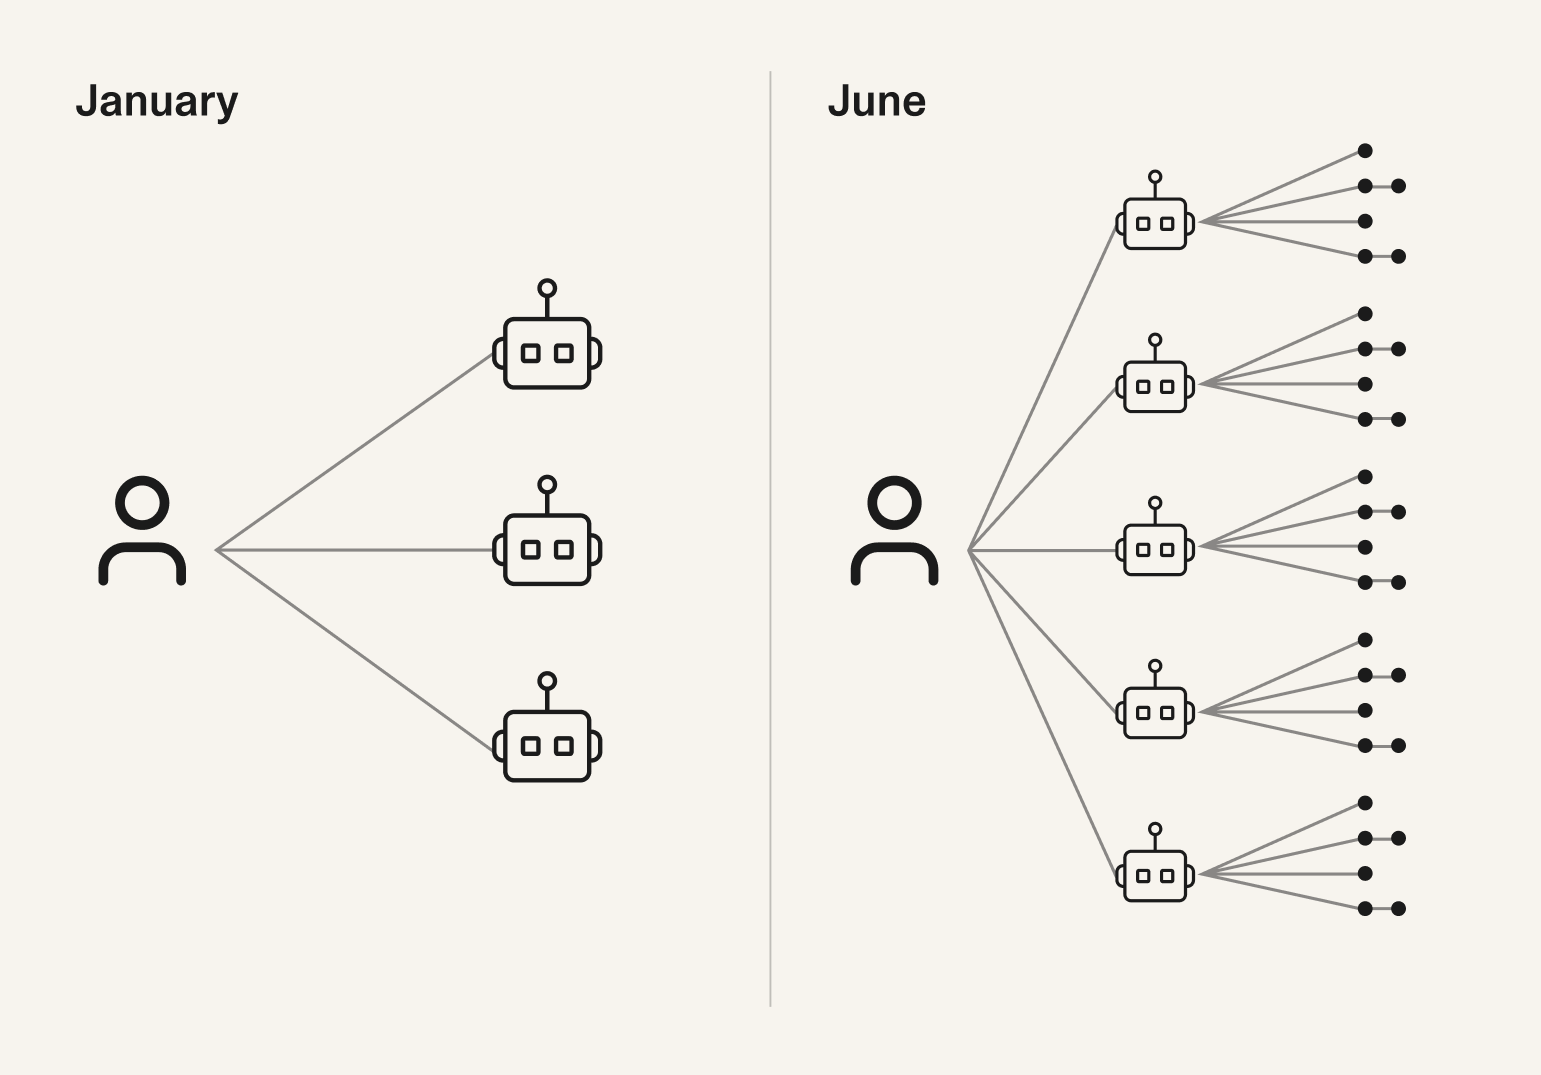
一月:单个开发者加上少量智能体。六月:一个人协调 6–7 个智能体,每个都带领一群子智能体。
花费结构
我的 token 约 75% 直接花在实现上。另外 25%(且仍在增长)花在各类自动化上:开发环境之外的 AI 审查、合并后的 AI 审查,以及各种定期自动任务。我预计随着越来越多工作移出代码创建 PR 循环,这一比例只会增加。
人工审查成了例外
从人写代码到 AI 写代码的转变,在很多方面类似于从汇编语言到高级语言的抽象跃迁。那时,人们很快就不再直接查看编译器的输出。今天,代码审查也在发生同样的事。逐行审查 AI 生成的代码既不现实,也不是对时间的合理利用。而应对 AI 使用中产生问题的通常方法,就是使用更多的 AI,因此你会默认切换到 AI 审查。那些审查正变得越来越好。
我在 Lovable 看到的有效做法是,把人工审查保留给影响最大的变更。不过,这通常不是以针对某个 PR 的传统代码审查形式出现,而是发生在更高的层面,比如通过 RFC 和 ADR。我们经常结对调试难题,或进行面对面白板讨论,以就新计划达成一致。关键在于将人的注意力投到能产生最大影响的地方。例如,一次关于系统设计或基础设施选型的讨论,可能比 50 个实现 PR 对系统的改变更大。这就是为什么我们试图将人工注意力转移到最重要的地方——而不是代码审查。
问题在于,当代码审查消失时,我们会失去许多与其逐行批准无关的附带好处。代码审查曾是一种学习工具,也是知识在组织内传播的方式。它还是风格和架构选择的一种自动发现和对齐机制。作为一门工程学科,我们需要在代码审查基本自动化的世界里,找到保留这些二阶效应的途径。我目前还没看到好的解决方案,只有新实验的空间。
变更风险分级
绕开大多数 PR 的人工审查会引出另一个问题:你能将这种做法扩展到大型组织,让新加入的成员在头几天就把东西发布到生产环境吗?结果证明:不能,至少简单粗暴地做是不行的。系统需要对那些善意且充满热情、但可能不清楚自己不知道什么的开发者具备足够的韧性。我最终构建了一个 AI 工作流,按风险级别对 PR 进行分类,并对高风险 PR 强制执行人工审查,以使整体风险保持在合理水平。
所以,你需要识别哪些变更异常高风险或异常低风险。如何对变更分类?常识加上基于 LLM 的分类器能解决大部分问题。涉及基础设施或认证?总是高风险。发布一篇博客文章?低风险。PR 太大了吗?作者的团队是否拥有变更所涉及的大部分代码?这是一个正式的线上功能还是试验性的?诸如此类。
我们分类器的核心是一个单独的 markdown 策略文件。然后智能体会结合该文件与 PR diff 及元数据进行阅读,判断某个 PR 在规模、风险级别和代码归属上属于哪一类。接下来是一个庞大但无趣的确定性工具,它根据分类决策来执行策略,另有一些 GitHub Action 和规则集管道,用于允许或拒绝在当前状态下合并拉取请求。当然,这一切都是 AI 生成的——一旦你知道想应用什么策略,围绕它设计系统基本已是一个已解决的问题。
如果你能自动化这种风险评估,就可以对高风险变更要求人工审查,对中等风险变更使用较慢的昂贵 AI 审查,对低风险变更使用快速便宜的 AI 审查。而且,越来越多围绕变更的讨论也会集中在那些能带来最大收益的地方。
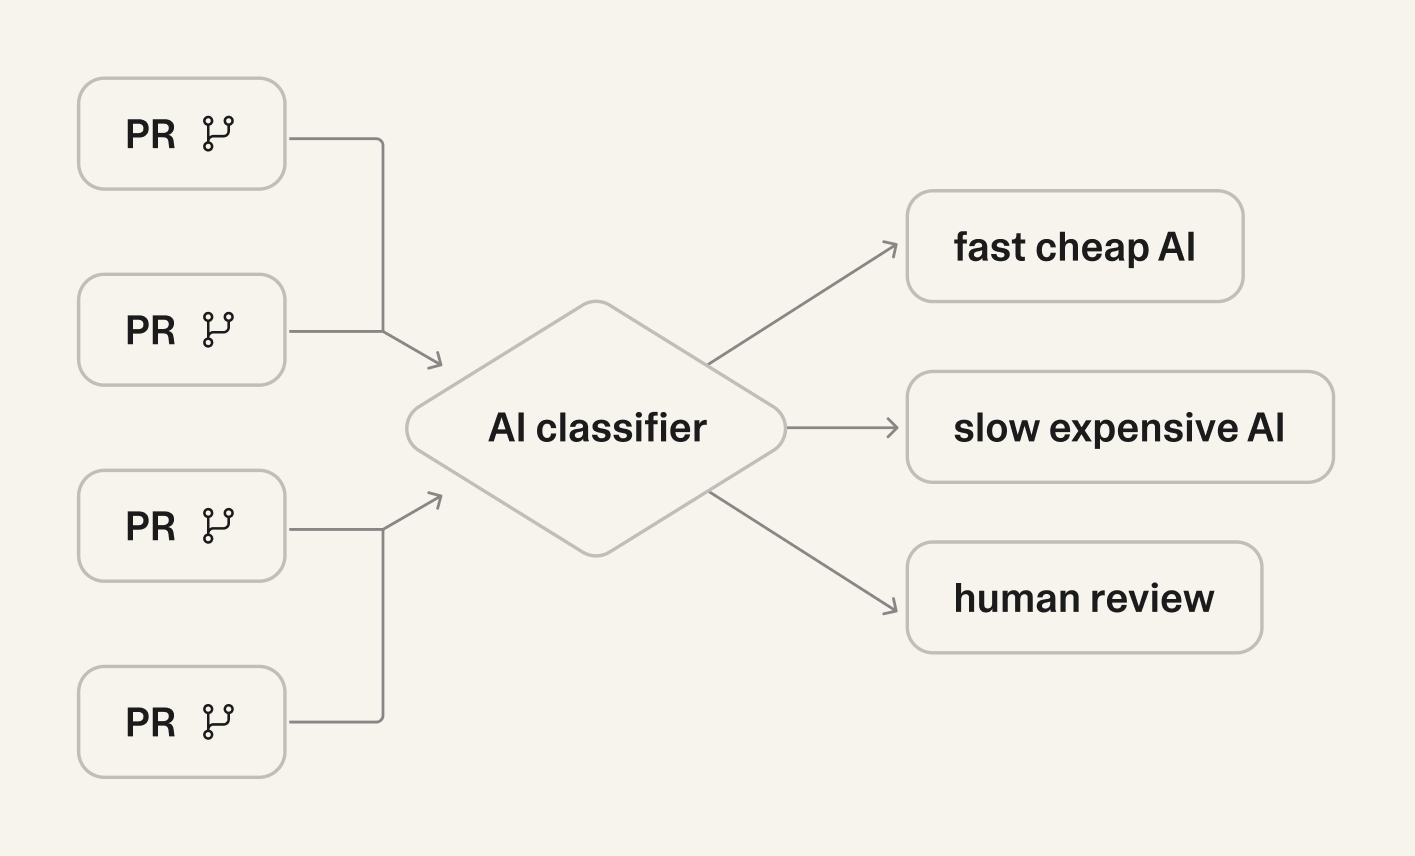
PR 进入分类器,并分成三条通道:快速 AI、慢速 AI,以及在需要升级时引入的人工审查。
AI 代码审查的多种形态
在 Lovable 期间,我们测试了至少 3 种针对 PR 的 AI 审查工具,以及更多在本地开发环境中工作的工具。
CI 上的审查权衡……很有意思。你要么得到某种快速且便宜的结果,但智能体有相当大的概率听起来很蠢和/或漏掉重要问题;要么就是昂贵且耗时(一次通过花 30 分钟并不罕见),但通常更准确。我发现,几个月前慢且昂贵的 AI 审查变体就已比中位水平的人工审查更有用。而且智能体在持续进步。
还有本地审查。它可以简单到一条“review this code”提示,也可以演变成一套精致的技能,包含子智能体、发现项跟踪器,以及各种花哨功能。
相比依赖 CI 检查,最大的好处就是进行本地审查。下一个重大改进是将针对特定方面(如正确性、性能、代码复用)的审查委托给多个子智能体,然后由主智能体汇总并去重它们的发现。我们投入了大量精力向智能体分享“好代码应该是什么样”(通过技能、AGENTS.md、代码旁的风格指南等),然后大家在这些知识的基础上独立试验如何运行本地审查。
我很快注意到,我几乎从不质疑本地审查的发现。因此,自然下一步是:我的审查技能也会对这些发现进行分类和修复,完全自主进行。将发现与评估发现分开,可以改善整体性能,因为每个智能体各司其职。有趣的是,修复受影响的发现不需要自己的上下文——能够准确评估发现的智能体,也能很好地修复它。
如果某些建议的修改是错误的,我更愿意找到并修复根本原因,而不是与智能体纠缠于修复某一次运行。智能体出错通常是因为缺乏足够的上下文,你可以通过改进知识文件、风格指南等来修复。
我认为你需要同时部署这两种 AI 审查。CI 审查是共同基线,也是安全网。本地审查‑修复设置则是真正的主力,它有望完成大部分生产性工作——但尚未解决的问题是,如何最好地在人与人之间共享这一设置。
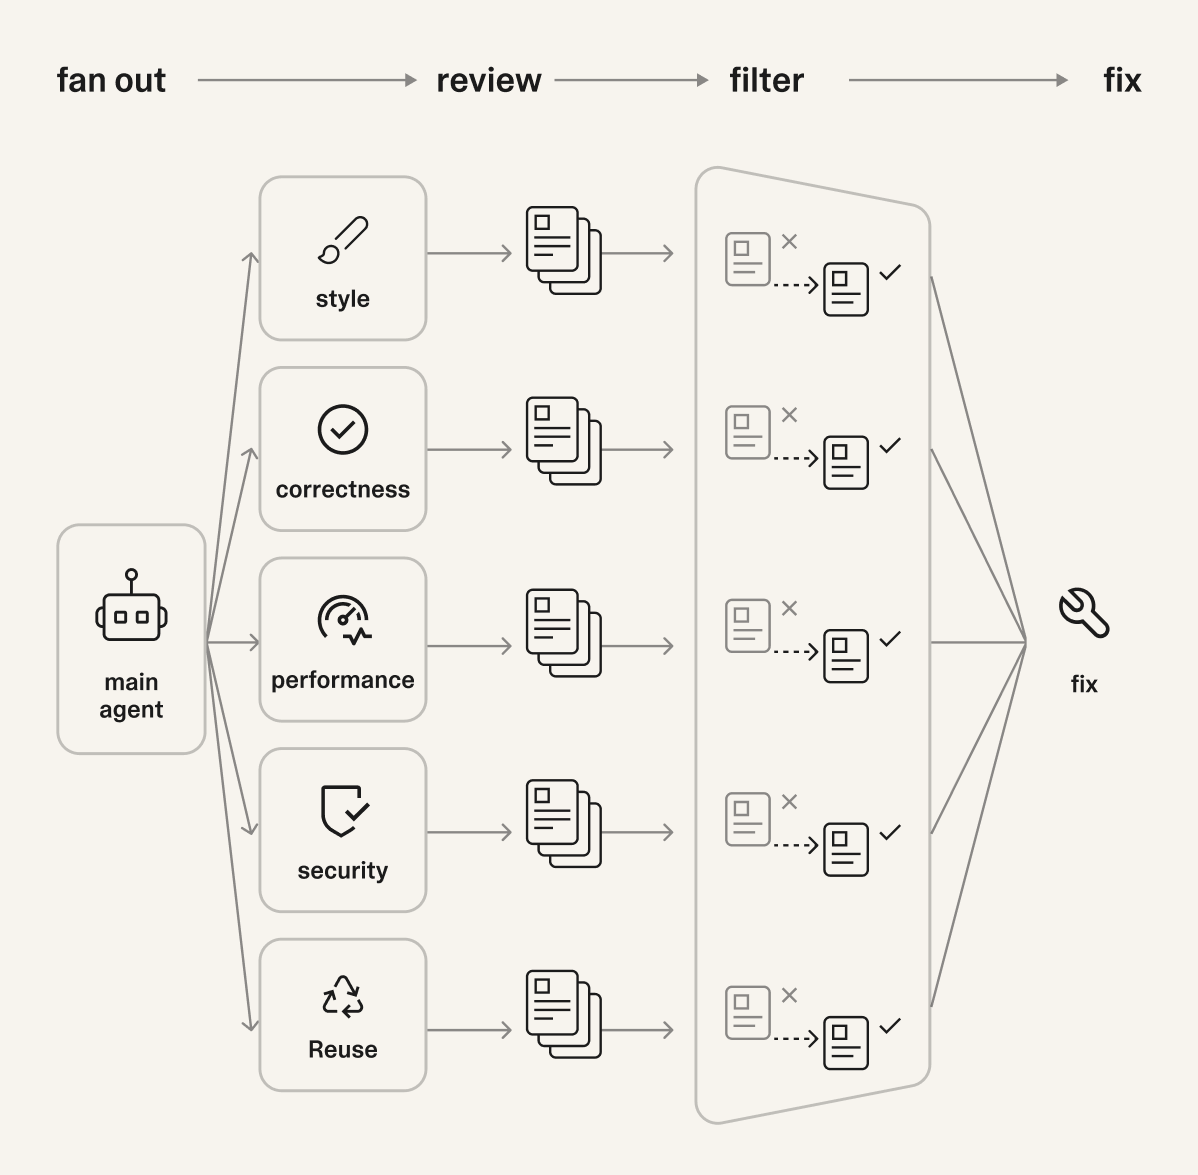
主智能体分派正确性、性能、复用和安全子智能体,然后汇总发现并进行修复。
PR 能在智能体时代存活吗?
我看到过一个说法,称 PR 在 AI 编码时代将被淘汰,堆叠 PR 只有在依赖人工审查时才有意义。就今天而言,我不相信这两个论断中的任何一个。
PR 是未验证变更的良好抽象。CI/CD 基于 PR 工作。几乎所有合并前的测试设置都基于 PR 工作。你还能如何验证变更——靠“我机器上能跑”吗?因此,即使围绕 PR 的流程发生巨大变化,PR 可能仍会是一个有用的抽象。这就像文件系统及其基础抽象可以追溯到 UNIX 为与今天截然不同的底层硬件所做的设计一样。
至于堆叠 PR,我发现它们对于上下文管理和风险管理极其有用。当你的变更足够大时,AI 代码审查的质量会急剧下降。我团队里有一次,一位开发者在一个 6,000 行的大 PR 上获得了 AI 审查批准。我要求把那个 PR 拆成一个堆叠。拆分之后,同一个 AI 审查器开始在生成的小 PR 中发现新的真实问题。自那以后,Lovable 的工程师越来越不信任大型 PR;它们从未能被人类审查,现在我们知道也无法被 AI 审查。也许模型进步会在某天改变这一点,但我们还没到那个阶段。
管理我自己的注意力
当你拥有一个魔法般的认知机器,能喷涌出无限代码时,心智的上下文切换就成了整体生产力的硬限制之一。关于扩展的几点思考。
- 快速模式非常划算,对交互式的来回会话完全合理。例如,我尽量一直在快速模式下进行规划。这比尝试并行处理 5 个交互式会话效率高得多。话虽如此,我看不出对非交互式任务使用快速模式有什么理由。比如,一项夜间任务在凌晨 3 点而不是 5 点完成,价值为零。而在白天,你通常希望一次只专注于一件最重要的事——其他任务可以在后台更慢地进行。
- 任务自主性是关键。 智能体应当拥有足够的上下文和工具,在可行范围内尽可能长时间地推动任务。必须要有某种类似于自动模式或 YOLO 模式的设置;你需要零权限请求。有时这意味着你要添加专门工具,让智能体能安全地执行一些通常有风险的操作。例如,我的智能体不被允许用
ghCLI 合并 PR,但允许使用 Graphite 的 “merge when ready”,并附加上与分支新鲜度、无开放 PR 讨论等相关的保护措施。gtCLI 的调用进而被包装在一个由单元测试覆盖的自定义 Node.js 脚本中,以确保智能体没有犯错余地。所有这些都写成了智能体技能——这花了不少功夫来搭建,但这种投入是值得的,因为我再也不用修复一次错误的合并了。 - 我想验证智能体构建了正确的东西。 我想把尽可能多的验证工作安全地委托给智能体。有时可以全部委派,有时则需要人参与。理想情况下,我希望能批量完成所有验证工作,并恰好每个 PR 堆栈执行一次。这通常意味着在 PR 堆栈的顶部验证最终结果,并确保不需要验证该堆栈中的每一个中间 PR。这就要求你确信,你的流程默认产生的是可以安全单独合并的原子 PR,并且任何例外都会被智能体提请你的注意。
管理智能体的注意力
智能体需要支持才能自主构建大型变更。以下是我为此设置的关键部分。
- 用 Beads 作为外部任务追踪器。 大型任务可能需要超过 100 万 token 的上下文。上下文窗口越大,质量下降且成本上升。我不信任自动压缩能接近手动上下文管理的效果。而且,智能体会不时崩溃,我需要某种持久的交接载体来模拟工头与工人的交互——子智能体不适合这种情况。总之,所有这些都要求某种形式的、具备足够持久力的任务跟踪。我使用 Beads,并采用不同步到 git 的本地设置。也许其他工具也能起到同样作用。
- 子智能体。 我将消费大量上下文以及具有独立目标的清晰子任务委托给子智能体。代码探索。聚焦特定属性的代码审查。智能体在察觉和使用委托机会方面正在改进,但就目前而言,最好是让你的典型工作流以确定性方式使用子智能体。而且,当可以用更小的模型处理简单任务时,你还能节省一些成本。
- 小 PR。 我在上文写过,将 PR 保持在数十到数百行代码,可确保智能体在实现和审查期间不会用尽上下文。在我向我的智能体传授了堆叠 PR 和推荐的 PR 大小(通过共享技能)之后,它能可靠地将较大的任务拆分成多个 PR。
- 每个任务使用新上下文。 依我之见,这是基本规范:绝不在多个任务间复用上下文。
/clear是免费的、可逆的,而且只需敲几秒。
附注:任务跟踪
我坚信这一点:人类的跟踪抽象与智能体的任务跟踪,应该是分离的。我见过充斥着智能体思维链墙状文本的 Linear 工单,那画面并不好看。智能体生成的大部分文本都是短暂的,而且 s
English / 原文
I joined Lovable in January this year. Before that, I used maybe $600 of tokens per month on my coding tasks. Once I started here, a larger scope, a larger project, and the freedom to use as many tokens as a problem warrants brought my individual spend to ~$25K/mo in May and an overall spend of ~$85K since January. Here's what happened when I pushed harder than most, and what I learned along the way.
Development process
In January 2026, my agentic coding process involved plan mode, permission requests, and classic code review. A productive week meant 20-30 merged PRs.
As of June I have a dedicated agent that writes tasks for the other agents, with multiple levels of implementation and review agents. For large changes, the working unit is a 10-PR stack instead of a single PR. Human review happens for the important decisions and rarely for the code. A productive week now means 150+ merged PRs.
January: solo dev plus a few agents. June: one human over 6–7 agents, each with its own swarm of subagents.
Spend structure
About 75% of my tokens are spent directly on implementation. The other 25% (and growing) is spent on all forms of automation: AI reviews outside of my dev environment, post-merge AI reviews, and all kinds of regular automated tasks. I predict that this share will only increase as more and more work shifts out of the code-creation PR loop.
Human review is an exception
The transition from human-written to AI-written code in many ways is a new level of abstraction, like the transition from assembly to higher-level languages. Back then, people pretty quickly stopped looking directly at the output from the compiler. The same is happening with code review today. Reviewing AI-written code line-by-line isn't practical or a good use of anyone's time. And the usual answer to problems created by the use of AI is to use more AI, so you switch to AI reviews by default. Those are getting notably better over time.
What I've seen work at Lovable is reserving human review for the most impactful changes. However, this often doesn't happen in the form of traditional code review on a PR. Instead, it's happening at a higher level with RFCs and ADRs. We often pair debug hard problems or do whiteboard sessions in-person to get aligned on a new initiative. The important thing here is to apply human attention where it gives the most impact. For example, a single discussion of system design or an infrastructure choice may change our system more than 50 implementation PRs would. That's why we try to shift human attention where it matters the most — and it's not code review.
The problem is that when code review goes away, we lose a lot of the secondary benefits that are unrelated to approving changes line by line. Code review used to be a learning tool, and a way that knowledge diffused through an organization. It was an automatic discovery and alignment mechanism for style and architecture choices as well. As a discipline, engineering needs to find a way to preserve these second-order effects in a world where code review is largely automated. I don't see any good solutions yet, only space for new experiments.
Change risk classification
Bypassing human review on most PRs raises another question: can you scale this to a large organization where new joiners are expected to ship something to production in their first days? Turns out: no, at least if you do it in a naive way. The system needs to be reasonably resilient to well-intentioned enthusiastic developers who might not know what they don't know. I ended up building an AI workflow for PR classification by risk level and hard-enforcing human review on high-risk PRs to keep the overall risk levels reasonable.
So, you need to identify which changes have an unusually high and unusually low risk of breaking production. How do you classify your changes? Common sense plus LLM-based classifiers get you quite far. Is it infra or auth related? Always high risk. Is it publishing a blog post? Low risk. Is it too big? Does the author's team own the majority of code containing the change? Is it a production feature or something experimental? And so on.
The core of our classifier is a single markdown policy file. The agent then reads it together with the PR diff and metadata and decides where a particular PR falls on size, risk level, and code ownership. Then there's a large but boring deterministic tool that applies the policy based on classification decisions, and some GitHub action and ruleset piping to allow or deny merging pull requests in their current state. Of course it's all AI-generated — once you know what policy you want to apply, designing a system around it is pretty much a solved problem.
If you automate such risk assessment you can require human review for high-risk changes, slow expensive AI review for medium-risk changes, and quick and fast AI review for low-risk changes. And a larger and larger share of review conversations increasingly happen around changes where discussion would bring the most benefit.
PRs entering a classifier and splitting into three lanes: fast AI, slow AI, and human review when escalation is needed.
All the shapes of AI code review
During my time at Lovable we tested at least 3 AI review tools that work on PRs and a few more that work locally in the development environment.
Tradeoffs on CI review are ... interesting. You either get something quick and cheap, but there's a significant chance the agent sounds stupid and/or it misses something important. Or it's expensive and takes forever (30m per pass is not unusual) but is typically accurate. I find that the slow and expensive variants of AI review were already more useful than the median human review a few months ago. And the agents keep getting better.
There's also local review. It can be as simple as a "review this code" prompt or it can evolve into a sophisticated skill with subagents, a findings tracker, and all sorts of bells and whistles.
The biggest win here is doing local review at all compared to relying on CI checks. The next big improvement is delegating review for specific aspects (like correctness, performance, code reuse) to multiple subagents, then letting the main agent aggregate and deduplicate their findings. We put a lot of effort into sharing what good code should look like with the agents (through skills, AGENTS.md, style guides next to code, etc.), and then people independently experiment with how they run local reviews using this knowledge.
I quickly noticed that I rarely dispute local review findings. Hence the natural next step: my review skill also triages and fixes the findings, all autonomously. Separation between discovery and evaluating the findings improves overall performance, since each agent focuses on its own thing. Fixing affected findings, curiously, does not need its own context — the agent that can evaluate the finding well can fix it well too.
If some suggested change is wrong, I'd rather find and fix the root cause than fight the agent to fix a particular run. The agent is usually wrong when it doesn't have enough context, and you fix it by improving your knowledge files, style guides, etc.
I think you want both kinds of AI reviews in place. CI review is the common denominator and the safety net. The local review-and-fix setup is the real workhorse that hopefully does the bulk of the productive work — but the unsolved problem here is how to best share this setup between people.
Main agent dispatching correctness, performance, reuse, and security subagents, then aggregating findings and fixing them.
Will PRs survive the agent age?
I've seen a claim that PRs will turn obsolete in the age of AI coding. And that stacked PRs are only relevant when you rely on human review. As of today I don't believe either claim.
A PR is a good abstraction for unverified changes. CI/CD works on PRs. Almost all pre-merge testing setups work on PRs. How else are you going to verify changes — "Works on my machine"? So, perhaps PRs will stay a useful abstraction even if the process around them changes a lot. Compare this to how file systems and their base abstraction can be traced to what UNIX developed for very different underlying hardware than what we have today.
As for stacked PRs, I find them incredibly useful for context management and risk management. The quality of AI code review drops sharply when your change gets big enough. One time on my team, a fellow developer got AI review approval on a big, 6K-line PR. I asked to split that PR into a stack. And when it happened, the same AI reviewer started finding new real issues in the resulting smaller PRs. After that story, engineers at Lovable increasingly distrust large PRs; they were never reviewable by humans and now we know they aren't reviewable by AI either. Maybe model advances will change this one day, but we're not there yet.
Managing my own attention
When you have a magic cognition machine that spews out an unlimited amount of code, mental context switching becomes one of the hard limits on overall productivity. Some thoughts on scaling here.
-
Fast mode is a great deal , makes total sense for interactive back-and-forth sessions. For example, I try to always plan in fast mode. You're way more productive than if you try to work with 5 interactive sessions in parallel. That said, I see no reason to run fast mode for non-interactive tasks. There's zero value in an overnight task being done at 3 AM instead of 5 AM, for example. And during the daytime you typically want to focus on one most important thing at a time — other tasks can proceed more slowly in the background.
-
Task autonomy is the key. The agent should have the context and tools to drive the task as long as practical. Some variant of auto mode or YOLO mode is required; you want zero permission requests. Sometimes this means you'll want to add dedicated tools to allow the agent to safely perform some actions that are normally risky. For example, my agents aren't allowed to merge PRs with the gh CLI, but they are allowed to use Graphite's "merge when ready" with additional safeguards related to branch freshness, lack of open PR discussions, etc. gt CLI invocations are then wrapped into a custom Node.js script covered by unit tests to ensure an agent has no room for mistakes. All of it is written down as an agent skill — it was quite a bit of work to set it all up, but this effort pays off in never having to fix a bad merge again.
-
I want to validate that the agent built the right thing. I want to delegate as much verification work to the agents as safely possible. Sometimes it's all of it, sometimes you need a human in the loop. Ideally, I want to batch all the validation work and do it exactly once per PR stack. This usually means validating the end result at the top of the PR stack and making sure you don't need to validate every intermediate PR in that stack. This means you need to be sure that your process produces atomic PRs by default that would be safe to merge individually. And you need to be sure that any exceptions are brought to your attention by the agents.
Managing the agents' attention
Agents need support to be able to build large changes autonomously. Here are the key parts of my setup for this.
-
Beads as external task tracker. Large tasks may need more than 1M tokens of context. Quality degrades and cost grows with the context window. I don't trust that auto-compaction is close enough to manual context management. Also, agents sometimes crash, and I want some durable handoff vessel to simulate foreman-worker interaction — subagents don't work for this. Bottom line, this all requires some form of reasonably durable task tracking. I use Beads with a local setup without syncing to git. Maybe some other tools would work just as well.
-
Subagents. I delegate large context consumers and distinct subtasks with their own goals to subagents. Code exploration. Code review focused on specific properties. Agents are getting better at seeing and using delegation opportunities, but for now it's still better to structure your typical workflow in a way that uses subagents deterministically. And you get some cost savings when simpler tasks can be delegated to smaller models.
-
Small PRs. I wrote about it above, but keeping PRs to tens to hundreds of lines of code makes sure agents don't run out of context during implementation and review. After I taught my agent about stacked PRs and recommended PR size (via a shared skill) it reliably does a good job of separating bigger tasks into multiple PRs.
-
New context per task. Basic hygiene, IMHO: never reuse context for multiple tasks. /clear is free, reversible, and takes just a few seconds to type.
Sidenote: task tracking
One thing that I strongly believe here is that task tracking for humans and task tracking for agents should be separate. I've seen Linear tickets with walls of text from agents' chains of thought in them and it's not a pretty sight. Most of the text agents generate is ephemeral and should be treated as such, staying user-specific and never exposed to other humans. If writing to Linear is deliberate, we'll have less slop there.
A factory that builds itself
How do you improve your development process? You locate the bottleneck, think hard about ways to improve throughput there, apply those ideas, then repeat the loop.
Some observations on this:
-
Agents are good at writing skills. I think the last time I wrote a skill manually was in January. I tried asking the agent to do it and I never looked back since. Try turning every repeated workflow into a skill and try iterating on skills often. One good trick is to ask the agent about skill improvement ideas at the end of the task. Lovable uses a very similar idea for self-improvement already: We gave our agent a vent tool.
-
Longer-form reflection also works. I regularly ask something like "Look at the last 100 PRs I merged, including PR comments and their resolutions, and suggest improvements" and get a lot of good suggestions back, which I then ask the agent to implement.
-
CI/CD and DevEx tools should be ready. A lot of improvements were made by our DevEx team at Lovable to make sure our systems scale to a 10x volume of changes and will continue scaling beyond that.
-
Inspecting your past work is a goldmine. Every time I feed my agentic session logs to an LLM to find insights I get something useful back. Agents overcome some small friction points all the time. Every now and then something derails an agent completely. All of it is a potential fuel for a self-reflection loop that improves your setup over time.
-
Sharing the context is easy. Just put everything into git. Everyone in the development team (and their agents) then automatically gets synchronized up-to-date knowledge about how things work, how code should be written, etc. Written knowledge used to benefit primarily remote team members in the pre-AI age and now the agents become the primary consumers. This means that office-first Lovable has more reasons to write things down than a fully-remote company had a few years ago.
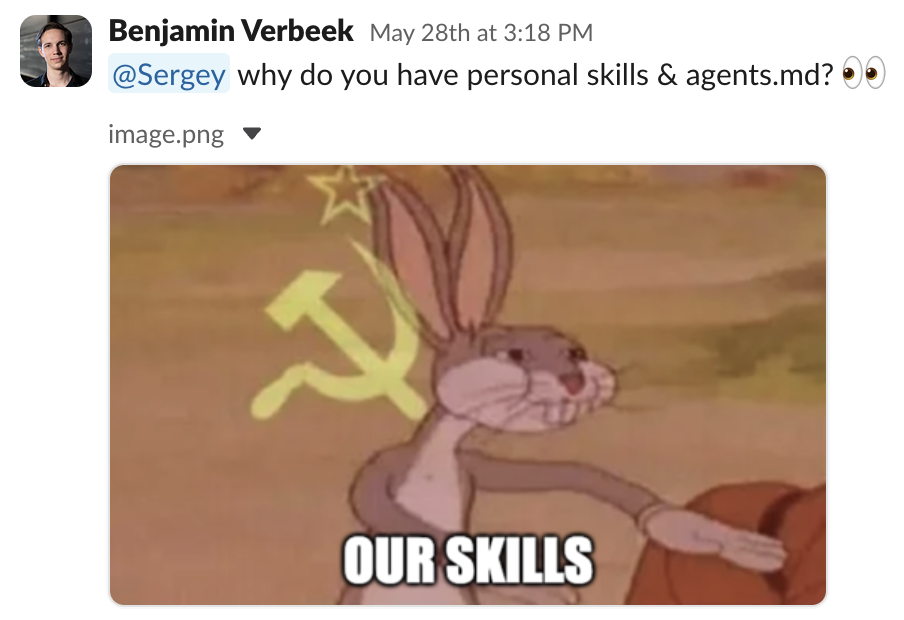
Sharing is culturally encouraged.
- Sharing skills is hard. It's still a largely unsolved problem: how do we share the best ways to do agentic development? There's a Slack channel where people showcase elements of their development workflows; there's a demo session every now and then; knowledge exchange naturally happens when people work next to each other. And yet I feel that we're inventing new workflows and techniques faster than we tell our colleagues about previous ones.
Is it worth it?
During the first week of June I merged 293 PRs, and have found no production defects tracing back to those changes so far. The latter part is a bit of good luck — I think 2-3 minor and 1 major defect would be acceptable for this volume.
Was it worth it? My current productivity is simply beyond the reach of old unassisted development techniques. I feel there's no going back in that sense.
Is it better than hiring proportionally more developers? That's a hard thing to balance and every organization will arrive at its own equilibrium.
Is there a better way to spend money on tokens? Well, tokenmaxxing is a foolish and short-sighted behavior. You have to have a clear purpose. What ultimately matters is outcomes, not how much work you did to get there. And the optimal amount of attention devoted to spend efficiency is not zero. Maybe it's 5% for us right now? 95% should still go to finding new, better ways to solve more problems by applying more tokens to them. Model capabilities evolve so fast that the surface of exploration is growing faster than we can explore it. The opportunity cost of exploring less feels too high to justify even 10% of attention to token efficiency.
Overall it's an amazingly fun ride so far. Can't wait to see what's beyond the horizon. I expect the next $85K of tokens will go towards finding new ways of making our product better. When you can create previously unthought of amounts of software quickly, what do you do with this power?
If this sounds interesting, we're hiring.

About the author
Alexander is a former team lead and engineering manager who joined Lovable and went back to individual work. With agent swarms everyone is somewhat of a manager here. He cannot stop looking for pragmatic solutions to the next technical challenge — even though both have changed a lot since the early 2000s when he wrote his first website.