使用 Amazon Bedrock AgentCore 生成演示文稿
英文标题:Generate presentations with Amazon Bedrock AgentCore
本文介绍如何利用 Amazon Bedrock AgentCore 构建 AI Agent 系统,将企业季度报告、合规文件和市场分析等材料自动转化为 PowerPoint 演示文稿。该方案以部署在 AgentCore runtime 上的监督 Agent 为核心,结合 RAG、Amazon Bedrock Guardrails、Claude Sonnet 4.6、Titan Text Embeddings v2 和 Stable Image Inpaint,在内部测试中可于 90 秒内完成生成。系统通过 .NET 8 REST API、AWS Lambda、Amazon OpenSearch Serverless 和 Amazon S3 组成端到端架构,并提供公开代码仓库。对开发者而言,该方案展示了如何通过工具编排、企业知识库检索和多层安全控制,构建可集成到现有业务系统中的受控文档生成工作流。
 1.3 MB
 1.3 MB
 2.4 KB
 345.0 KB
 141.2 KB
 346.5 KB
 164.3 KB
 151.5 KB
 23.7 KB
 378.4 KB
 24.1 KB
 1.3 MB
 40.5 KB
 20.5 KB
 17.1 KB
 22.0 KB
 57.5 KB
中文
某金融服务团队每周都要花费大量时间,根据季度报告、合规文档和市场分析手动制作客户 PowerPoint 演示文稿。每份演示文稿都需要阅读数百页材料、提取关键数据点、组织幻灯片结构并生成配套视觉素材。本文将介绍如何使用 Amazon Bedrock AgentCore 构建 AI Agent 系统,以自动化这一工作流;在我们的内部测试中,该系统可在 90 秒内完成任务。这种方法可缩短演示文稿的制作时间,同时确保内容以源文档为依据。该解决方案在 AgentCore runtime(Amazon Bedrock AgentCore 的一项能力)上部署监督 Agent,并使用 Strands Agents 框架来编排文档生成和摘要工具。Anthropic Claude Sonnet 4.6(可通过 Amazon Bedrock 使用)负责内容创作,Amazon Titan Text Embeddings v2 用于向量搜索,Stability AI Stable Image Inpaint(可通过 Amazon Bedrock 使用)用于生成幻灯片图像。本文包含一个提供代码资产的公开仓库。
解决方案概述
该解决方案在 Amazon Bedrock AgentCore runtime 上部署一个监督 Agent,根据用户请求在文档生成和摘要工具之间进行选择。检索增强生成(Retrieval Augmented Generation,RAG)管道使用 Amazon OpenSearch Serverless 存储向量,并针对多模态内容执行语义搜索。
该解决方案包含一个使用 .NET 8 minimal API 构建的 REST API,因此你可以通过标准 HTTP 调用将其集成到现有企业应用中。AWS Lambda 提供无服务器计算能力,其中包括用于生成 PowerPoint 的容器化函数。该方案通过 Amazon Virtual Private Cloud(Amazon VPC)隔离、AWS Key Management Service(AWS KMS)加密以及 AWS Identity and Access Management(IAM)最小权限访问控制来保障实现安全。
核心概念
本节介绍 AgentCore runtime、RAG 和内容安全护栏在该解决方案中的应用。
使用 Amazon Bedrock AgentCore 编排 Agent
一个需要从大型知识库生成文档的 AI Agent,必须完成内容检索、提纲组织、文本生成、图像创建和文件组装等任务。与其在一个单体函数中实现这些相互竞争的职责,该解决方案采用基于工具的架构,由监督 Agent 将请求路由至专用工具。
Amazon Bedrock AgentCore runtime 提供了一个平台,可使用任意框架或模型大规模构建、连接和优化 Agent。Agent 代码在隔离容器中运行,具备会话管理、内置身份机制和可观测性功能。该解决方案使用 Strands Agents 框架(一个用于构建 AI Agent 的开源 SDK)来实现监督逻辑。
监督 Agent 暴露两个工具:
- **generate_pptx:**通过调用 PPTX Generator Lambda 函数创建 PowerPoint 演示文稿;该函数从知识库检索内容、生成幻灯片提纲、创建 AI 图像并组装最终文档。
- **generate_summary:**使用 RAG 从知识库提取和综合信息,以提供准确且有据可依的响应。
Agent 会判断请求是否需要文档生成、内容摘要或两者兼有,然后调用相应工具。你可以通过在 Agent 代码中定义新工具来添加新能力,而无须修改现有工具。
面向企业知识的检索增强生成(RAG)
RAG 解决了 AI 系统中的一个根本性挑战:提供基于企业数据的准确、最新信息,而非仅依赖模型训练数据。该实现使用 Amazon Bedrock Knowledge Bases,后者将向量搜索与大语言模型(LLM)结合,在生成响应前检索相关上下文。
RAG 管道的工作流程如下:
- 将企业文档上传至 Amazon Simple Storage Service(Amazon S3)。
- 系统对文档进行分块和解析,并对表格、图表和图像等多模态内容进行特殊处理。
- Amazon Titan Text Embeddings v2 将每个分块转换为能够捕捉语义含义的高维向量。
- Amazon OpenSearch Serverless 存储这些向量,从而创建可搜索的向量数据库。
- 在查询时,系统将用户请求转换为嵌入向量,并执行相似性搜索,以检索相关文档分块。
- 检索到的分块为语言模型提供上下文,使其能够生成基于源材料的响应。
这种方法旨在通过将生成文档建立在企业知识库的源信息之上,帮助减少幻觉内容。
**注意:**Amazon OpenSearch Serverless collection 数据平面必须保持可从公网访问,因为 Amazon Bedrock Knowledge Bases 是从 AWS 托管基础设施访问 Amazon OpenSearch Serverless,而不是通过客户 VPC 终端节点访问。IAM 数据访问策略会保护 collection,而仅限 VPC 的访问控制则会限制 Amazon OpenSearch Serverless 控制台。
用于内容安全的 Amazon Bedrock Guardrails
企业 AI 应用需要内容审核,以满足组织标准和合规要求。Amazon Bedrock Guardrails 提供内置的内容过滤和安全机制,并集成于整个文档生成管道。
Guardrails 在多个阶段发挥作用:
- **输入处理:**过滤用户请求,以帮助防止注入问题和不当内容。
- **输出生成:**监控模型输出,以验证其符合内容策略。
- **个人身份信息(PII)处理:**检测并匿名化或拦截 PII。
该实现通过 AWS Cloud Development Kit(AWS CDK) 创建自定义 Guardrails,并根据企业文档创建场景配置特定策略。Agent 会在模型调用层应用 Guardrails,从而无需为每次部署手动配置,即可提供一致的内容安全保障。
解决方案架构
下图展示了基于 Agent 的文档生成系统。
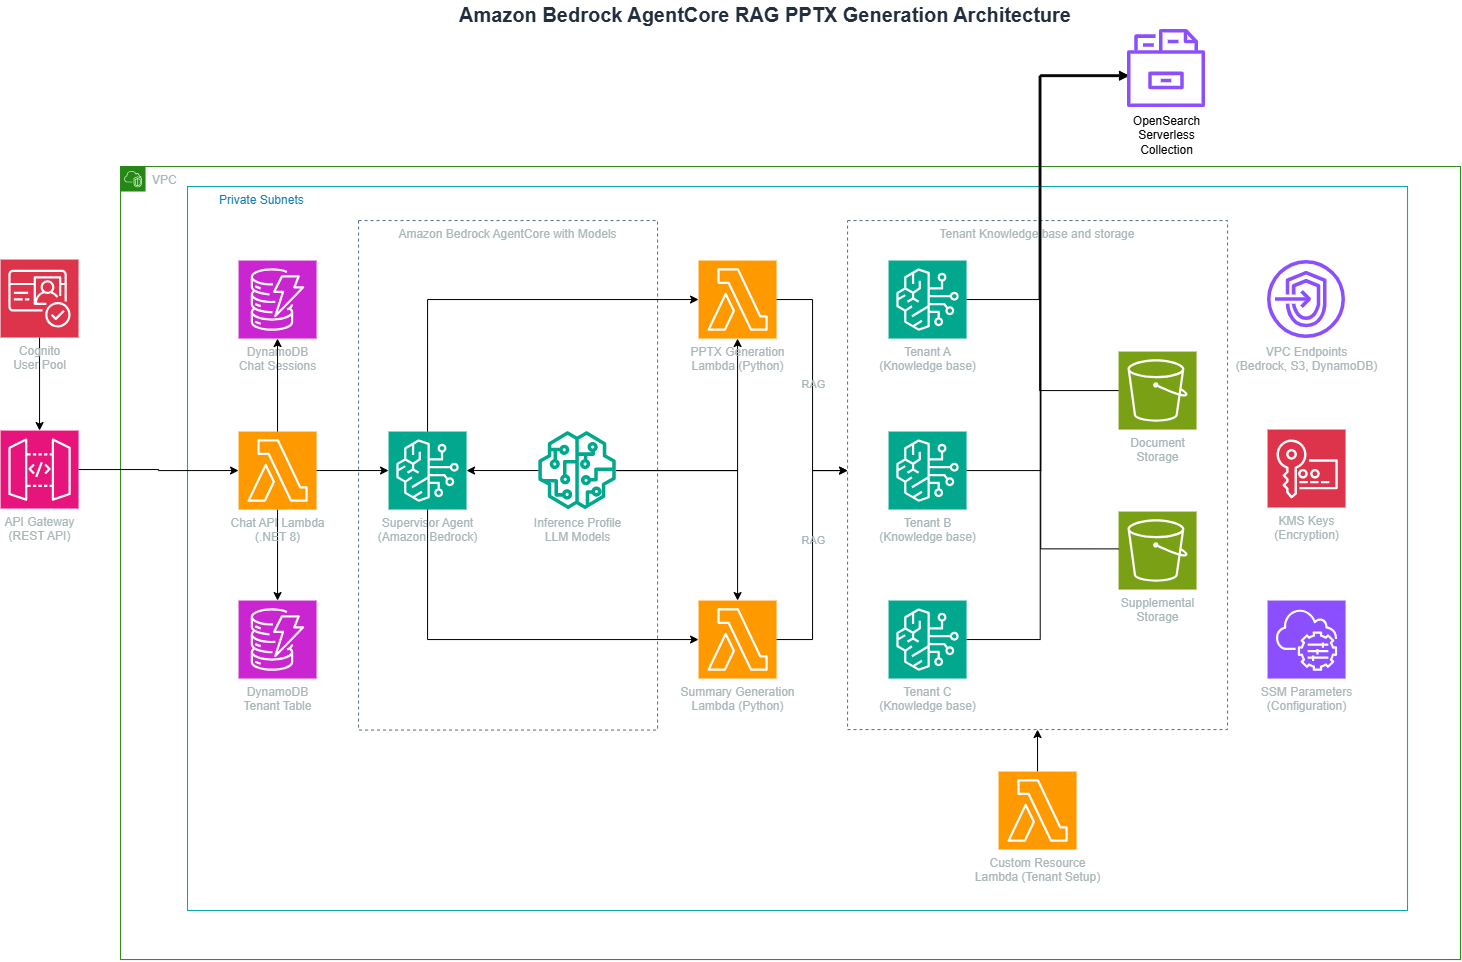
图 1:Amazon Bedrock AgentCore RAG 演示文稿生成系统架构
数据流始于经由 Amazon API Gateway 到达的用户请求,API Gateway 将其路由至运行在 AWS Lambda 上、基于 .NET 的 Chat API。该 API 将会话状态维护在 Amazon DynamoDB 中,随后调用托管在 Amazon Bedrock AgentCore runtime 上的监督 Agent。
监督 Agent 分析请求并选择适当工具。对于文档生成,它会调用 PPTX Generator Lambda(一个容器化 Python 函数)。对于摘要生成,监督 Agent 会调用 Summary Generator Lambda,后者通过 retrieve_and_generate API 查询知识库。
系统使用 Amazon Titan Text Embeddings v2 处理、分块并嵌入存储在 Amazon S3 中的文档。Amazon OpenSearch Serverless 为这些嵌入建立索引,以实现快速语义搜索。当工具查询知识库时,Amazon OpenSearch Serverless 会检索相关分块,随后将其作为上下文提供给 Anthropic Claude Sonnet 4.6(通过 Amazon Bedrock)以生成有据可依的响应。
系统将生成的文档存储在 Amazon S3 中,并返回预签名 URL 以供安全下载。安全措施包括:
- 在 Amazon API Gateway 上使用带托管规则集和基于 IP 的速率限制的 AWS WAF。
- 使用采用 Plus 功能套餐及高级安全模式进行威胁防护的 Amazon Cognito。
- 通过 AWS CDK 预置 Amazon Bedrock Guardrails,以实现一致的内容过滤。
- Amazon DynamoDB 启用时间点恢复、删除保护和客户管理的 AWS KMS 加密。
- Amazon S3 存储桶启用版本控制、服务器访问日志记录和阻止公开访问。
- 在 Lambda 函数上使用 AWS X-Ray 追踪,以进行分布式调试。
- 使用基于正则表达式的租户 ID 和会话 ID 验证进行输入校验。
- 通过按租户进行 AWS Security Token Service(AWS STS) 角色承担实现租户隔离。
先决条件
部署之前,需要在环境中配置以下工具和访问权限:
- AWS 环境:
- 一个具有部署基础设施权限的有效 AWS 账户。
- 已配置凭证的 AWS Command Line Interface(AWS CLI)。
- 具有适当服务访问策略的 IAM 角色。
- 开发工具:
- AWS 服务访问权限:
- Amazon Bedrock 的模型访问权限,包括 Anthropic Claude Sonnet 4.6、Amazon Titan Text Embeddings v2 和 Stability AI Stable Image Inpaint(可通过 Amazon Bedrock 使用)。有关各区域的模型可用性,请参阅 Amazon Bedrock 中按 AWS 区域列出的支持模型。
- 已在你的账户中启用 Amazon Bedrock AgentCore 访问权限。
- 将 Amazon API Gateway Regional REST API 集成超时设置为至少 300 秒。默认值为 29 秒。更多信息请参阅 API Gateway 配额。
- 一个具有私有子网的现有 Amazon VPC。
- 一个用于部署构件的 Amazon S3 存储桶。
设置解决方案
设置过程包括配置部署参数和初始化 AWS CDK 环境。
-
克隆仓库并进入项目目录:
git clone https://github.com/aws-samples/sample-generating-powerpoint-presentations-with-amazon-bedrock.git -
在仓库根目录创建配置文件
pipeline-params.ini:environment=dev awscliprofile= ContainerRegistry=lambda-pptx-gen AgentContainerRegistry=agentcore-supervisor BucketDev=<amzn-s3-demo-bucket> VpcId=<your-vpc-id> ParsingInferenceProfileId=us.anthropic.claude-haiku-4-5-20251001-v1:0 AgentInferenceProfileId=us.anthropic.claude-sonnet-4-6 EmbeddingModelId=amazon.titan-embed-text-v2:0 ImageGenerationModelId=stability.stable-image-inpaint-v1:0 PPTXGenImageTag=latest AgentImageTag=latest
将 awscliprofile 设置为你的 AWS CLI 配置文件名称;或者留空,以使用环境变量凭证。
- 引导 AWS CDK(每个账户和区域只需执行一次):
这将创建 AWS CDK 部署所需的 AWS CloudFormation CDKToolkit stack。
-
使构建脚本可执行:
chmod +x ./pipeline-build.sh
chmod +x ./pipeline-deploy.sh
chmod +x ./deploy-agentcore.sh
构建和部署
部署由三个阶段组成:构建构件、部署基础设施以及部署 AgentCore runtime Agent。
构建阶段
构建阶段会编译应用程序代码并打包部署构件。运行构建脚本:
这一步会编译 .NET 项目(Chat API),并将其打包为 Lambda 部署包。它使用 Docker 或 Finch 构建 PPTX Generator 容器镜像,并向 Amazon Elastic Container Registry(Amazon ECR)进行身份验证。随后,它会推送容器镜像,并将构建构件存储在 asset-output 目录中。
基础设施部署阶段
基础设施部署会创建 AWS 资源并配置服务集成。运行部署脚本:
部署会按依赖顺序创建四个 AWS CloudFormation stack:
- **VPCEndpointsStack:**为包括 Amazon Bedrock AgentCore 在内的 AWS 服务配置 Amazon VPC 终端节点。
- **OpensearchStack:**预置用于向量存储的 Amazon OpenSearch Serverless collection。
- **AgentCoreStack:**创建 Guardrails、Lambda 函数、IAM 角色,并将配置存储在 AWS Systems Manager Parameter Store 中。
- **ChatApiStack:**部署 Amazon API Gateway 和 Chat API Lambda。
AgentCore runtime 部署
基础设施 stack 部署完成后,将监督 Agent 部署至 AgentCore runtime:
该脚本会构建监督 Agent 容器(ARM64)、将其推送至 Amazon ECR、创建 AgentCore runtime 和终端节点,并使用终端节点 Amazon Resource Name(ARN)更新 Systems Manager 参数。Chat API 会引用此终端节点 ARN,将请求路由至该 Agent。
部署完成后,AWS CloudFormation 输出将包括 Amazon API Gateway 终端节点 URL 和资源标识符。
配置
该解决方案提供多个配置点:
Agent 指令
编辑 agent/app.py 以修改监督 Agent
English / 原文
A financial services team spends significant time each week manually creating client PowerPoint presentations from quarterly reports, compliance documents, and market analyses. Each presentation requires reading hundreds of pages, extracting key data points, structuring slides, and generating supporting visuals. This post walks you through building an AI agent system using Amazon Bedrock AgentCore that automates this workflow, completing in under 90 seconds in our internal testing. This approach reduces presentation creation time while grounding content in source documents. The solution deploys a supervisor agent on AgentCore runtime, a capability of Amazon Bedrock AgentCore, using the Strands Agents framework to orchestrate document generation and summarization tools. Anthropic Claude Sonnet 4.6 (available on Amazon Bedrock) handles content creation, Amazon Titan Text Embeddings v2 powers vector search, and Stability AI Stable Image Inpaint (available on Amazon Bedrock) generates slide images. This post includes a public repository with the code assets.
Solution overview
The solution deploys a single supervisor agent on Amazon Bedrock AgentCore runtime that selects between document generation and summarization tools based on user requests. A Retrieval Augmented Generation (RAG) pipeline uses Amazon OpenSearch Serverless for vector storage and semantic search across multimodal content.
The solution includes a REST API built with .NET 8 minimal APIs, so you can integrate with existing enterprise applications through standard HTTP calls. AWS Lambda offers serverless compute, including containerized functions for PowerPoint generation. The solution secures the implementation with Amazon Virtual Private Cloud (Amazon VPC) isolation, AWS Key Management Service (AWS KMS) encryption, and AWS Identity and Access Management (IAM) least-privilege access control.
Key concepts
This section covers AgentCore runtime, RAG, and content safety guardrails as they apply to this solution.
Agent orchestration with Amazon Bedrock AgentCore
A single AI agent generating documents from large knowledge bases must retrieve content, structure outlines, generate text, create images, and assemble files. Rather than implementing these competing responsibilities in a monolithic function, the solution uses a tool-based architecture where a supervisor agent routes requests to specialized tools.
Amazon Bedrock AgentCore runtime provides a platform to build, connect, and optimize agents at scale, with any framework or model. The agent code runs in an isolated container with session management, built-in identity, and observability. The solution uses the Strands Agents framework (an open source SDK for building AI agents) to implement the supervisor logic.
The supervisor agent exposes two tools:
- generate_pptx: Creates PowerPoint presentations by invoking the PPTX Generator Lambda function, which retrieves content from the knowledge base, generates slide outlines, creates AI images, and assembles the final document.
- generate_summary: Extracts and synthesizes information from the knowledge base using RAG to deliver accurate, grounded responses.
The agent determines whether a request requires document generation, content summarization, or both, then invokes the appropriate tool. You can add new capabilities by defining new tools in the agent code without modifying existing ones.
Retrieval Augmented Generation (RAG) for enterprise knowledge
RAG addresses a fundamental challenge in AI systems: delivering accurate, up-to-date information grounded in enterprise data rather than relying solely on the model’s training data. The implementation uses Amazon Bedrock Knowledge Bases, which combine vector search with large language models (LLMs) to retrieve relevant context before generating responses.
The RAG pipeline works as follows:
- You upload enterprise documents to Amazon Simple Storage Service (Amazon S3).
- The system chunks and parses documents, applying special handling for multimodal content including tables, charts, and images.
- Amazon Titan Text Embeddings v2 converts each chunk into high-dimensional vectors that capture semantic meaning.
- Amazon OpenSearch Serverless stores the vectors, creating a searchable vector database.
- At query time, the system converts the user’s request into an embedding and performs similarity search to retrieve relevant document chunks.
- Retrieved chunks supply context to the language model, which generates responses grounded in the source material.
This approach is designed to help reduce hallucinated content by grounding generated documents in source information from the enterprise knowledge base.
Note: The Amazon OpenSearch Serverless collection data plane must remain publicly accessible because Amazon Bedrock Knowledge Bases accesses Amazon OpenSearch Serverless from AWS-managed infrastructure, not through customer VPC endpoints. IAM data access policies protect the collection, and VPC-only access restricts the Amazon OpenSearch Serverless dashboard.
Amazon Bedrock Guardrails for content safety
Enterprise AI applications require content moderation to meet organizational standards and compliance requirements. Amazon Bedrock Guardrails offers built-in content filtering and safety mechanisms integrated throughout the document generation pipeline.
Guardrails operate at multiple stages:
- Input processing: Filters user requests to help prevent injection issues and inappropriate content.
- Output generation: Monitors model outputs to verify compliance with content policies.
- Personally identifiable information (PII) handling: Detects and anonymizes or blocks PII.
The implementation creates custom guardrails through AWS Cloud Development Kit (AWS CDK), configured with specific policies tailored to enterprise document creation. The agent applies guardrails at the model invocation level, providing consistent content safety without requiring manual configuration for each deployment.
Solution architecture
The following diagram illustrates the agent-based document generation system.
Figure 1: Architecture of the Amazon Bedrock AgentCore RAG presentation generation system
The data flow begins with user requests arriving through Amazon API Gateway, which routes them to a .NET-based Chat API running on AWS Lambda. The API maintains conversation state in Amazon DynamoDB. It then invokes the supervisor agent hosted on Amazon Bedrock AgentCore runtime.
The supervisor agent analyzes the request and selects the appropriate tool. For document generation, it invokes the PPTX Generator Lambda (a containerized Python function). For summarization, the supervisor invokes the Summary Generator Lambda, which queries the knowledge base through the retrieve_and_generate API.
The system processes, chunks, and embeds documents stored in Amazon S3 using Amazon Titan Text Embeddings v2. Amazon OpenSearch Serverless indexes the embeddings for fast semantic search. When tools query the knowledge base, Amazon OpenSearch Serverless retrieves relevant chunks, which are then supplied as context to Anthropic Claude Sonnet 4.6 (on Amazon Bedrock) for generating grounded responses.
The system stores generated documents in Amazon S3 and returns presigned URLs for secure download. Security measures include:
- AWS WAF with managed rule sets and IP-based rate limiting on Amazon API Gateway.
- Amazon Cognito with the Plus feature plan and advanced security mode for threat protection.
- Amazon Bedrock Guardrails provisioned through AWS CDK for consistent content filtering.
- Amazon DynamoDB with point-in-time recovery, deletion protection, and customer-managed AWS KMS encryption.
- Amazon S3 buckets with versioning, server access logging, and block public access.
- AWS X-Ray tracing on Lambda functions for distributed debugging.
- Input validation with regex-based tenant ID and session ID verification.
- Tenant isolation through AWS Security Token Service (AWS STS) role assumption per tenant.
Prerequisites
Before deploying, you need the following tools and access configured in your environment:
- AWS environment:
- An active AWS account with permissions for deploying infrastructure.
- AWS Command Line Interface (AWS CLI) configured with credentials.
- IAM role with appropriate service access policies.
- Development tools:
- AWS services access:
- Amazon Bedrock with model access for Anthropic Claude Sonnet 4.6, Amazon Titan Text Embeddings v2, and Stability AI Stable Image Inpaint (available through Amazon Bedrock). For model availability by Region, see Supported models by AWS Region in Amazon Bedrock.
- Amazon Bedrock AgentCore access enabled in your account.
- Amazon API Gateway Regional REST API integration timeout configured to at least 300 seconds. The default is 29 seconds. For more information, see API Gateway quotas.
- An existing Amazon VPC with private subnets.
- An Amazon S3 bucket for deployment artifacts.
Set up the solution
The setup process includes configuring deployment parameters and initializing the AWS CDK environment.
-
Clone the repository and navigate to the project directory:
git clone https://github.com/aws-samples/sample-generating-powerpoint-presentations-with-amazon-bedrock.git -
Create the configuration file
pipeline-params.iniat the repository root:environment=dev awscliprofile= ContainerRegistry=lambda-pptx-gen AgentContainerRegistry=agentcore-supervisor BucketDev=<amzn-s3-demo-bucket> VpcId=<your-vpc-id> ParsingInferenceProfileId=us.anthropic.claude-haiku-4-5-20251001-v1:0 AgentInferenceProfileId=us.anthropic.claude-sonnet-4-6 EmbeddingModelId=amazon.titan-embed-text-v2:0 ImageGenerationModelId=stability.stable-image-inpaint-v1:0 PPTXGenImageTag=latest AgentImageTag=latest
Set awscliprofile to your AWS CLI profile name, or leave empty to use environment variable credentials.
- Bootstrap AWS CDK (one-time per account and Region):
This creates the AWS CloudFormation CDKToolkit stack required for AWS CDK deployments.
-
Make build scripts executable:
chmod +x ./pipeline-build.sh
chmod +x ./pipeline-deploy.sh
chmod +x ./deploy-agentcore.sh
Build and deploy
The deployment consists of three phases: building artifacts, deploying infrastructure, and deploying the AgentCore runtime agent.
Build phase
The build phase compiles application code and packages deployment artifacts. Run the build script:
This compiles the .NET projects (Chat API) and packages them as Lambda deployment packages. It builds the PPTX Generator container image using Docker or Finch and authenticates with Amazon Elastic Container Registry (Amazon ECR). It then pushes the container image and stores build artifacts in the asset-output directory.
Infrastructure deployment phase
The infrastructure deployment creates AWS resources and configures service integrations. Run the deployment script:
The deployment creates four AWS CloudFormation stacks in dependency order:
- VPCEndpointsStack: Configures Amazon VPC endpoints for AWS services including Amazon Bedrock AgentCore.
- OpensearchStack: Provisions Amazon OpenSearch Serverless collection for vector storage.
- AgentCoreStack: Creates guardrails, Lambda functions, IAM roles, and stores configuration in AWS Systems Manager Parameter Store.
- ChatApiStack: Deploys Amazon API Gateway and Chat API Lambda.
AgentCore runtime deployment
After the infrastructure stacks are deployed, deploy the supervisor agent to AgentCore runtime:
This script builds the supervisor agent container (ARM64), pushes it to Amazon ECR, creates the AgentCore runtime and endpoint, and updates the Systems Manager parameter with the endpoint Amazon Resource Name (ARN). The Chat API references this endpoint ARN to route requests to the agent.
After deployment, AWS CloudFormation outputs include the Amazon API Gateway endpoint URL and resource identifiers.
Configuration
The solution offers several configuration points:
Agent instructions
Edit agent/app.py to modify the supervisor agent’s system prompt and behavior. The agent uses Strands Agents with two tools defined in agent/tools.py:
- generate_pptx: Invokes the PPTX Generator Lambda for document creation.
- generate_summary: Invokes the Summary Generator Lambda for knowledge base queries.
Model selection
In pipeline-params.ini, adjust model identifiers:
ParsingInferenceProfileId: Model for knowledge base document parsing (Anthropic Claude Haiku 4.5 recommended for cost efficiency).AgentInferenceProfileId: Model for agent reasoning (Anthropic Claude Sonnet 4.6 recommended).EmbeddingModelId: Embedding model for vector search (Amazon Titan Text Embeddings v2).ImageGenerationModelId: Model for slide image generation (Stability AI Stable Image Inpaint).
With inference profiles instead of direct model IDs, requests draw on a broader multi-Region capacity pool, which increases throughput and helps maintain consistent performance under load.
Lambda configuration
Adjust compute resources in the stack files:
- Chat API: 128 MB memory, 29-second timeout, 100 reserved concurrency (in
api.py). - PPTX Generator: 900 MB memory, 300-second timeout, 50 reserved concurrency (in
pptx_gen.py). - Summary Generator: 512 MB memory, 300-second timeout, 50 reserved concurrency (in
sum_gen.py).
Results
In internal testing with a 90-page Amazon 2024 Annual Report PDF, the solution produced the following performance metrics:
- Presentation generation time: 70–90 seconds end-to-end (including knowledge base retrieval, content generation, image creation, and file assembly).
- Slide count: Six slides with title, bullet points, image+text, image-only, and takeaway formats.
- Image generation: Two AI-generated images per presentation using Stability AI Stable Image Inpaint.
- Cost per generation: Approximately $0.04 in model invocation costs at time of writing in us-east-1 (text and image generation, with image generation accounting for the majority of cost).
- Knowledge base ingestion: Under 2 minutes for a single 1.3 MB PDF document.
PowerPoint presentations
The following figures show example slides from a generated presentation.
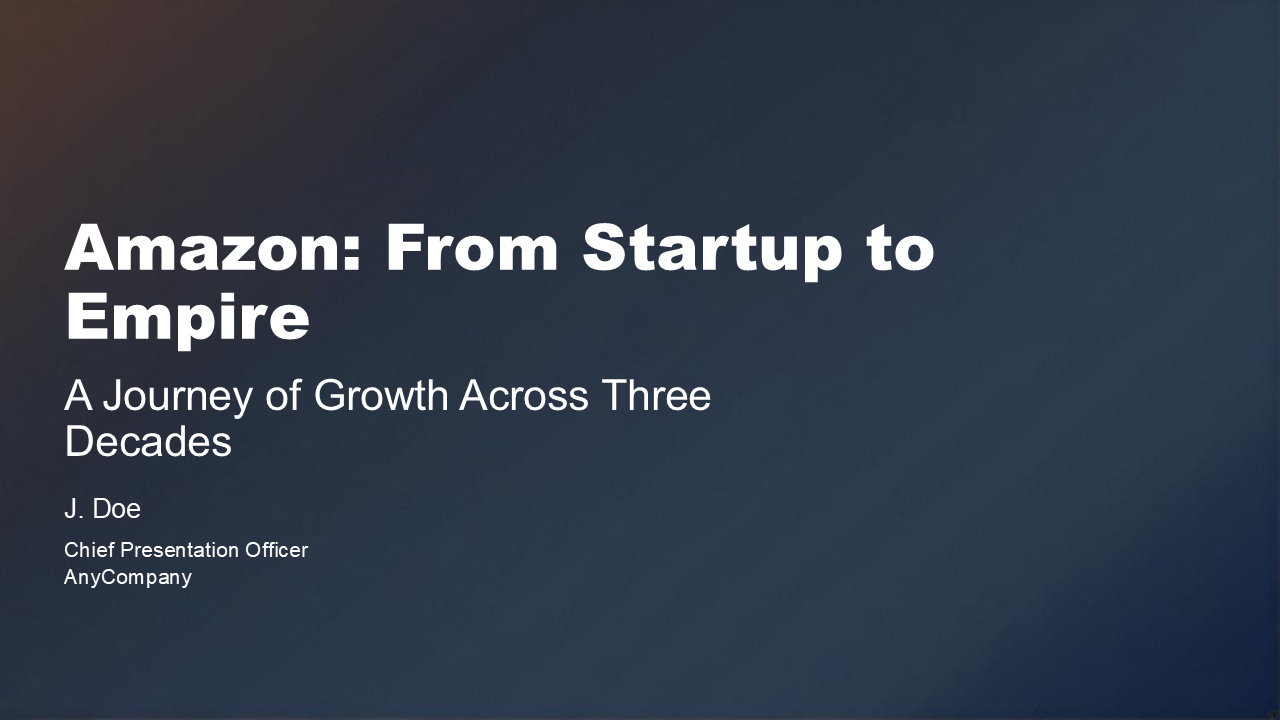
Figure 2: Generated title slide with customizable branding
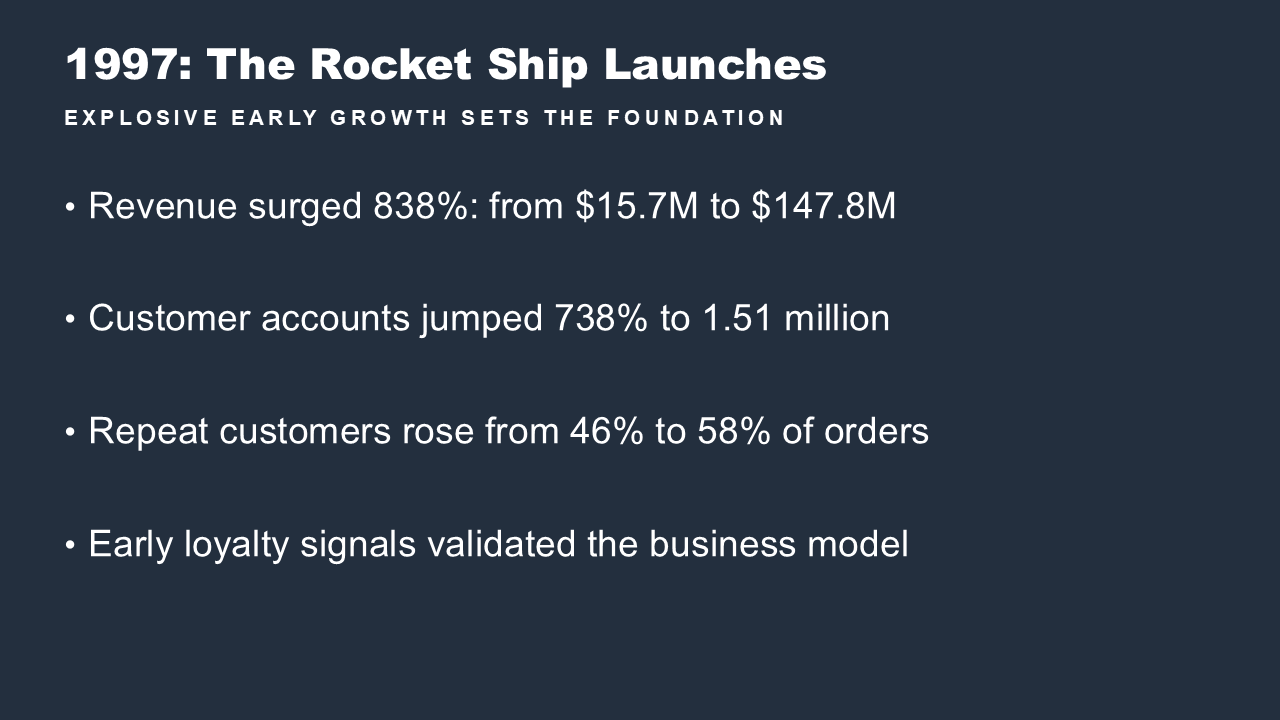
Figure 3: Generated content slide with bullet points
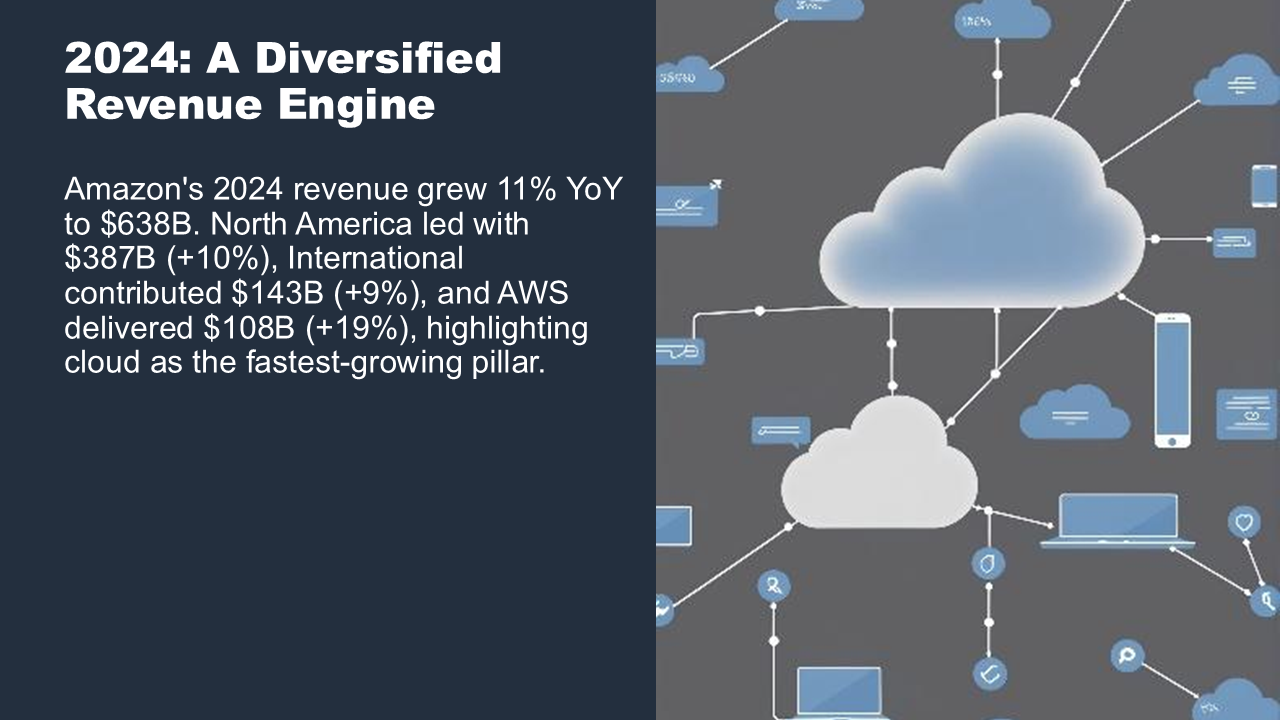
Figure 4: Generated slide combining text with an AI-generated image
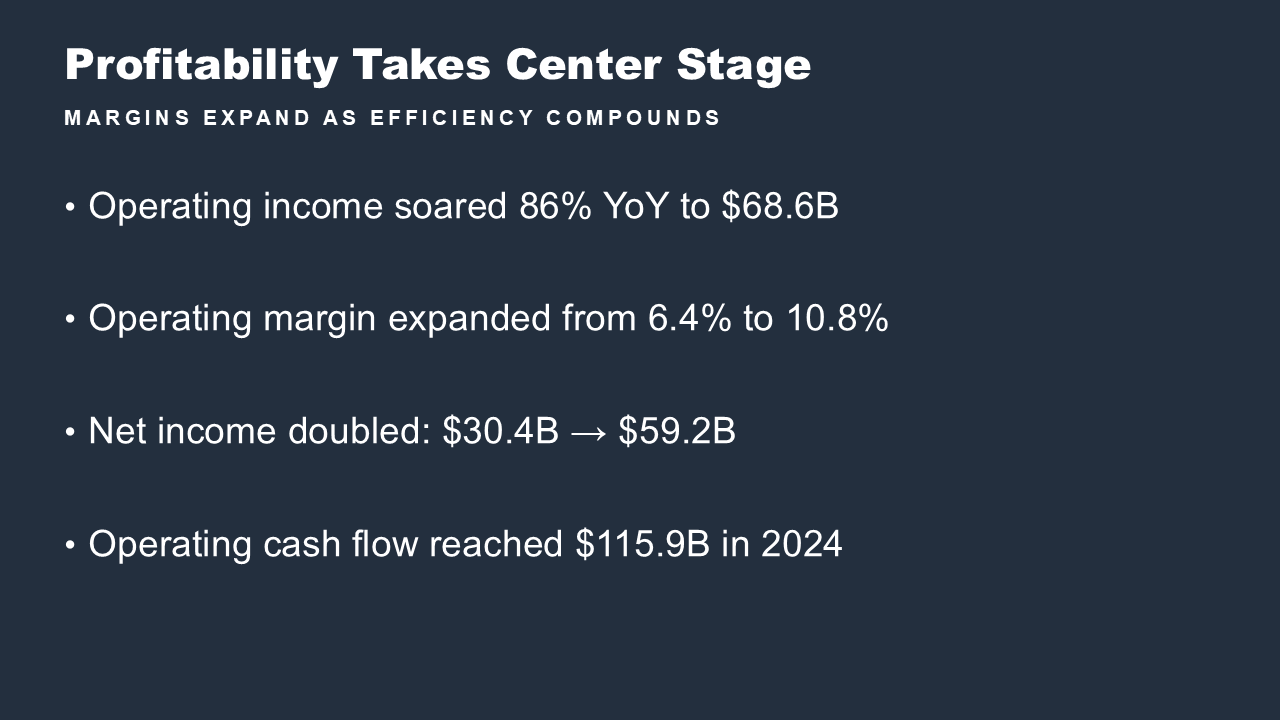
Figure 5: Generated content slide summarizing profitability metrics
Figure 6: Generated image-only slide with an AI-generated visual
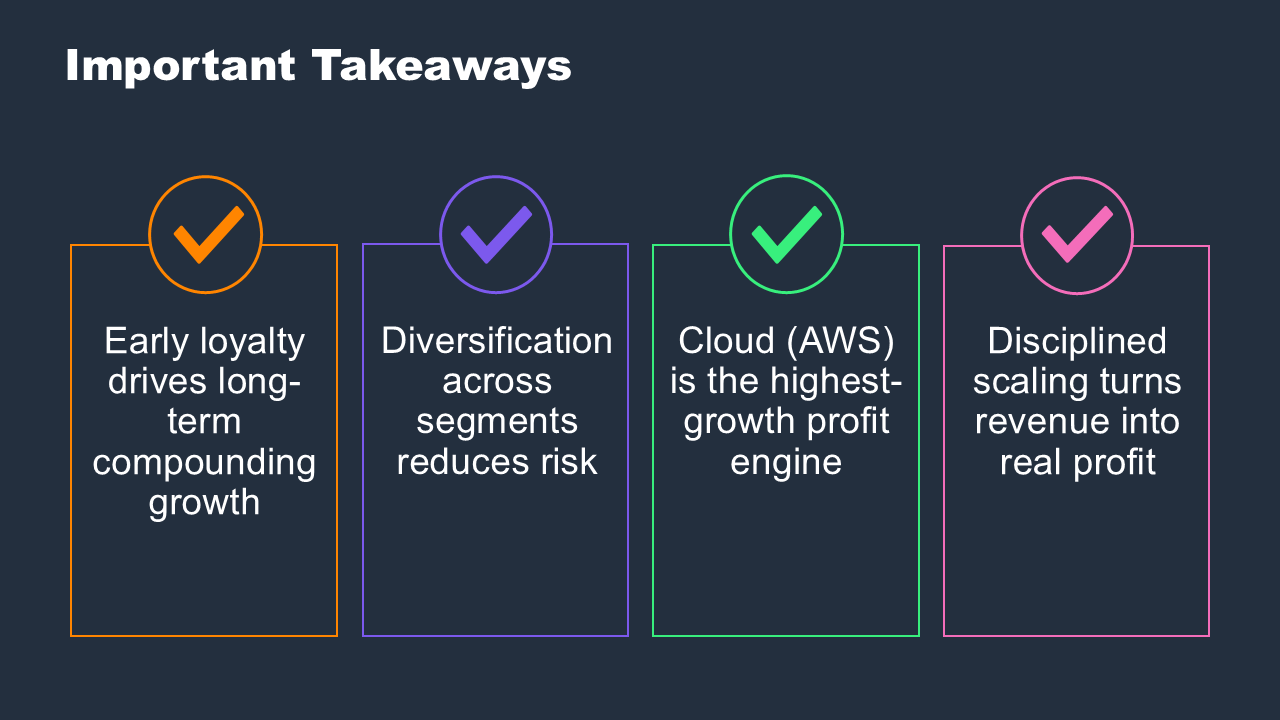
Figure 7: Generated takeaways slide
Generated presentations include:
- Title slides with customizable branding.
- Content slides with bullet points and structured text.
- Image slides with AI-generated visuals from Stability AI Stable Image Inpaint (on Amazon Bedrock).
- Speaker notes with presentation guidance.
- Consistent formatting based on corporate templates.
Summaries
Summary outputs provided to the knowledge base include:
- Concise synthesis of knowledge base content.
- Citation tracking to source documents.
- Structured formatting with key points highlighted.
API responses
The Chat API returns:
- Streaming responses for real-time user feedback. Because internal testing showed that presentation generation takes 70–90 seconds (exceeding the default Amazon API Gateway 29-second integration timeout), the Chat API uses an asynchronous invocation pattern. Use streaming or polling to receive the final result rather than waiting on a synchronous REST call.
- Conversation context maintenance across multiple turns.
- Amazon S3 presigned URLs for document downloads (5-minute expiration).
Generated content undergoes Amazon Bedrock Guardrails validation to verify compliance with content policies before delivery.
Clean up
To avoid ongoing charges, delete the deployed resources:
-
Delete the AgentCore runtime and endpoint:
aws bedrock-agentcore-control delete-agent-runtime-endpoint \ --agent-runtime-id <runtime-id> \ --agent-runtime-endpoint-id <endpoint-id> aws bedrock-agentcore-control delete-agent-runtime \ --agent-runtime-id <runtime-id> -
Turn off Amazon DynamoDB deletion protection (required before stack deletion):
aws dynamodb update-table --table-name chat-sessions-dev --no-deletion-protection-enabled aws dynamodb update-table --table-name tenant-table-dev --no-deletion-protection-enabled -
Delete AWS CloudFormation stacks in reverse dependency order:
aws cloudformation delete-stack --stack-name ChatApiStack aws cloudformation delete-stack --stack-name AgentCoreStack aws cloudformation delete-stack --stack-name OpensearchStack aws cloudformation delete-stack --stack-name VPCEndpointsStack -
Empty Amazon S3 buckets before deletion (AWS CloudFormation cannot delete non-empty buckets):
aws s3 rm s3://amzn-s3-demo-bucket --recursive -
Delete Amazon ECR repositories containing container images:
aws ecr delete-repository --repository-name lambda-pptx-gen --force aws ecr delete-repository --repository-name agentcore-supervisor --force -
Delete tenant knowledge base sub-stacks (created by the tenant provisioner):
aws cloudformation delete-stack --stack-name bedrock-kb-<tenant-id>
Security considerations
This solution uses Lambda environment variables for configuration values such as model IDs, Amazon S3 bucket names, and guardrail IDs. These are resource identifiers, not secrets. For production deployments, use AWS Secrets Manager for sensitive configuration values such as API keys and database credentials.
The AgentCore runtime agent runs in an isolated container with session-level isolation. Each user session operates in a dedicated environment, helping to prevent cross-session data contamination.
Conclusion
In this post, you built an AI agent system with Amazon Bedrock AgentCore that automates enterprise document generation. The supervisor agent deployed on AgentCore runtime routes requests to specialized tools for document creation and summarization, reducing presentation creation to about 90 seconds in an internal test.
The RAG pipeline grounds generated content in source documents, and Amazon Bedrock Guardrails verifies content compliance. You can adapt this architecture for automated report generation in financial services, technical documentation for engineering teams, or proposal creation for sales organizations.
To get started, clone the GitHub repository and follow the setup instructions. For more information about the services used, refer to the Amazon Bedrock AgentCore documentation, Strands Agents SDK, and AWS CDK Developer Guide.
About the authors
Dr. Ian Lunsford
Ian is an Aerospace AI/ML Engineer at AWS Professional Services. He integrates cloud services into aerospace applications and systems. Ian focuses on building AI/ML solutions using AWS services.
Neil Kamin
Neil is a Senior Delivery Consultant AWS Data/AI services at AWS Professional Services. He develops AWS infrastructure.
Stephen Morgan
Stephen is a Delivery Consultant at AWS Professional Services. He develops AWS infrastructure.