Meta 如何以 AI 原生工程打造 Forum
英文标题:How Meta Built Forum With AI-Native Engineering
Meta 为 Facebook Groups 用户推出独立应用 Forum,并以此试验让 AI Agent 深度参与软件工程流程的新工作模式。团队将目标从代码产量转向可验证、可上线的结果,要求变更能够构建、通过测试并完成审核。通过规划规格化、自动化验证、模拟用户测试、Agent 驱动的生产运维,以及针对 Agent 优化的代码与工具环境,Forum 在八周内实现了与 Facebook Groups 的核心功能对等。Meta 表示,持续压力测试在上线前发现并修复了内存问题,使内存占用和页面故障大约减半,也为开发者展示了将 AI 从代码补全工具升级为受监督工程执行者的实践路径。
 8.4 KB
 406 B
 22.1 KB
 120.1 KB
 150.8 KB
 62.0 KB
 136.8 KB
 82.1 KB
 79.3 KB
 117.2 KB
 241.5 KB
 142.2 KB
 207.7 KB
 46.9 KB
 35.3 KB
 13.9 KB
 4.4 KB
中文
- Meta 最新应用 Forum 面向希望更深入参与 Facebook 群组讨论的所有用户。
- 为构建 Forum,Meta 工程师将 AI Agent 引入开发周期,采用了一套全新的工作方式。
- 我们将分享使用 Agentic AI 构建 Forum 的经验:如何调整代码库、测试适用于 Agent 执行的框架与内部工具、哪些方法奏效,以及哪些没有奏效。
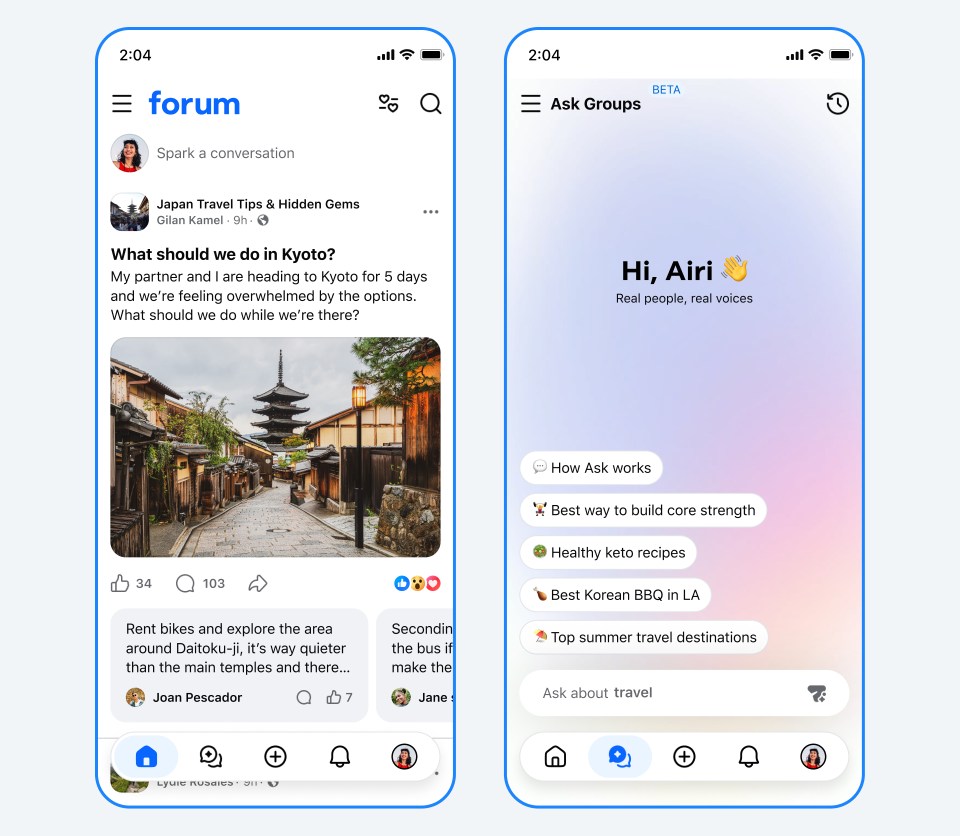
Forum 是一款独立的 Groups 应用,由一个小型团队从零开始构建。它也是我们试验另一种工作方式的场所:不将 AI Agent 仅视为更快的输入工具,而是将其视为工程流程的参与者。
这项实验需要明确成功的定义,而我们的衡量标准并非代码量。我们衡量的是经过验证、可投入生产的结果——能够构建、通过测试并经得起审核的变更。
从 Human-In-The-Loop 到 Human-On-The-Loop
仅仅让 AI 参与编码环节,并不会带来太大改变。当我们将这种方法扩展到实现环节前后的阶段——规划、构建、测试和验证——结果才开始叠加放大。理解这一转变最清楚的方式,是看每一步由谁负责。
在 human-in-the-loop 模式下,工程师主导每一个步骤,AI 则在步骤内部提供辅助,例如自动补全函数、建议修复方案或回答问题。每一轮迭代都以执行者的节奏推进。
在 human-on-the-loop 模式下,Agent 自行运行迭代流程——规划、实现、构建、测试、修正、重复——而工程师负责设定目标、观察执行过程、在其偏离时介入,并批准结果。人的工作从执行具体步骤转为对结果负责,并守住质量标准。这是我们正在迈向的目标,而非已经完成的状态:目前有些阶段能够自主运行,另一些阶段仍需要工程师参与每一轮迭代。
当工程师转为监督角色时,工作不再必须严格按顺序进行。过去一次只能运行一个的周期可以相互重叠,工程师的时间会投入到方向把控和判断,而不是坐等循环完成。但这一点成立的前提是,返回的结果值得信任。没有验证,AI 生成的代码会带来一个熟悉的问题——看似合理的输出,却没人确认它实际可用;工程师随后还得阅读、调试,并且往往将其丢弃。弱信号不会消除约束,只会将约束从编写代码转移到审核那些看起来已完成、实则未完成的代码上。
因此,我们将标准设在验证,而不是编译。编译并不是终点——只有自动化测试和视觉检查均已通过,任务才算完成。Agent 会在工程师看到变更前先检查自己的工作,这意味着进入审核环节的是数量更少、置信度更高的结果,而不是一堆需要筛选的输出。生成的内容更少,被丢弃的内容也更少。每一项发布结果仍需工程师签字确认;我们的工作重点是让这种确认快速且证据充分:变更会附带构建结果、测试结果和录制的验证会话。
当工程师不再参与每一次循环时,这个循环必须能够自行安全运行。以下四项能力使之成为可能:
将规划作为技术规格: Agentic 执行需要极高的精确度。工程师可以凭直觉化解的歧义,会导致 Agent 执行失败。我们投入资源进行严谨的前置拆解,并提供机器可读的上下文;这让工程师和 Agent 的工程循环都更加严密。
循环内的自动化验证是放大器: 我们将自动化的通过/失败信号——构建状态、单元测试和 UI 规格匹配——直接整合到 Agent 循环中。这使异步开发能够产出可供审核的 pull request,其中预先填充了测试计划和录制的验证会话。验证是最难做对的部分;我们能够安全交给循环的工作量,取决于我们对验证器的信任程度。
使用 Agent 模拟用户测试: 我们部署了导航 Agent,它们会像真实用户一样与在线应用交互。这些 Agent 执行操作、读取屏幕并报告回归问题。导航 Agent 能够持续运行相同的验证路径。
Agentic 生产运维: 上线后,Agent 可帮助自动化根因分析。当 Forum 用户提交反馈时,Agent 会利用该反馈调查可能存在的回归问题。随后,Agent 将分析结果转交给工程师,由工程师决定后续行动方案。
运行模型
这种责任归属模型需要一套由五个关键组成部分构成的机制:
- Rules(规则) 是永久性项目指令。当 Agent 重复犯同一个错误超过两次时,我们将纠正方式一次性编码,供所有人使用。
- Skills(技能) 将团队约定转化为 Agent 可调用的可加载步骤。
- Agents(Agent) 自动化此前需要人工完成的检查。
- Commands(命令) 将技能和 Agent 串联为工作流。它们会评估复杂度、复现 Bug、规划并实施修复、创建 pull request,以及运行多阶段审核。
- Hooks(钩子) 是自动触发器,例如在每次 Agent 操作后运行 linter、安装前检查模拟器连接,以及在创建 pull request 前验证测试。
让环境适应模型
最大的收益来自于改变我们的代码和工具,而不是提示词。
架构可理解性优先于历史遗留复杂度: 我们致力于让 Forum 的代码库尽可能直观,并选择对架构中的关键部分进行模块化。这样既能获得久经考验的基础设施优势,也能让 Agent 易于即插即用。在无法轻易实现这一点的地方,我们从头重建,以复用性换取 Agentic 吞吐量;事实证明,这种取舍有利于提升开发速度。Agent 会从其阅读的代码中学习模式。修正一次薄弱模式,未来每次 Agent 会话都会继承这项改进;如果放任不管,相同的捷径就会出现在 Agent 后续编写的所有内容中。
给 Agent 工具,而不是描述: 我们最主要的失败模式是 Agent 丢失自己在应用中的位置——例如,要求修改群组主页时却编辑了首页信息流,或者猜测屏幕坐标。因此,我们不再向 Agent 描述应用,而是给它工具进行检查:从模拟器读取实时视图层级、列出屏幕上实际存在的元素,以及查找目标视图的路径——所有操作都在它采取行动之前完成。错误方向的修改大幅减少。我们在 Agent 接触系统的任何地方都采用了相同方法:让 Agent 能够直接检查状态,而不是根据描述进行推理。
用于安全 AI 原型开发的构建级隔离: 随着 Forum 日趋成熟并面向生产环境,我们希望早期原型和 Agent 生成的实验有足够空间运行,同时确保生产应用严格仅包含已完成、经审核的工作。我们需要比仅依赖功能开关更强的保证,因为在后者中,原型代码仍然存在于生产构建内。我们的解决方案是使用 独立构建变体:这是一个沙盒应用,与生产版本共享完全相同的代码库、框架和设计系统,但通过插件/套接字架构,将原型代码完全从生产构建中编译 出去。
这同时带来了三项能力:
- 设计师和跨职能合作伙伴可以自由使用 AI 工具制作原型,无需工程师参与每一次改动。
- 在沙盒中构建的任何内容都可直接迁移至生产环境,无需重新构建。
- 原型代码无法导致生产应用崩溃,因为它在该构建中根本不存在。
这种模式让我们在应用已经拥有真实用户、需要加以保护之后,仍能保持快速的 AI 迭代。
通过 AI 压力测试发现真实 Bug
改造环境带来的不只是让 Agent 更快地参与构建——它也让 Agent 成为了测试者。我们没有让它只针对某一个特定缺陷,而是设置了可重复的压力测试场景,以模拟真实用户行为(高强度滚动、随机浏览群组、快速导航、反复加载媒体),并在各个构建版本中定期运行。由于这些运行会产生一致的信号(崩溃、内存增长、页面故障、UI 回归),Agent 可以分诊异常、缩小范围至触发序列,然后调查根本原因。
其中一次运行发现了一个内存问题。Agent 在应用触达用户之前、仍处于开发阶段时,完成了问题复现的隔离、修复方案的提出和修复验证。该修复显著降低了设备端内存增长,以及多轮重复压力测试中的页面故障。
工程师负责作出架构决策,而检测和回归监控则实现了自动化和可重复执行;一旦发现异常,Agent 就能借助同一套测试工具完成复现 → 隔离 → 提出修复方案 → 验证。
将同样的纪律应用于 Forum 的信息流
我们在两个方面采用了 human-on-the-loop 方法:
构建技术栈: Agent 梳理架构选项及其权衡;工程师随后进行评估和选择。我们刻意保留由人负责的是目标本身——决定什么样的结果才是好结果,属于产品判断,而不应由系统自行定义。
运行技术栈: 过去需要由熟悉相关代码路径的工程师回答的问题,如今会交给一个调查 Agent。它收集所需信息,并发布包含建议修复方案的分析报告。在人工评分一批真实调查案例后,我们形成了这样一套工作流:Agent 压缩机械性工作,并向工程师交付结构化报告;工程师随后验证某项发现究竟是真实 Bug,还是有意作出的权衡。
提升质量的并不是更好的提示词,而是上下文。在我们向 Agent 提供与新工程师入职第一天会获得的同等信息——相关代码的指针、示例查询和设计文档——之前,某一类反复出现的调查结果始终质量不佳。此后,该类别的质量显著提升。与人工入职不同的是,你只需训练一次,之后的每一次会话都会从中受益。
它奏效了吗?
除了更快发布,我们也发布了更干净的产品。持续验证在开发期间而非上线后暴露出系统性问题——例如上文提到的内存瓶颈。结果体现在性能表现中:
- 质量,及早发现: 自主压力测试循环在开发期间而非上线后发现并修复了前述内存问题,使内存使用量和页面故障大约减半。
- 速度: Forum 在八周内实现了与 Facebook Groups 的核心功能对等;AI 处理了大量常规实现工作,使工程师能够专注于架构、产品决策和质量。
- 持续性的杠杆效应: 上线后,Agent 驱动的调查帮助工程师对用户反馈进行分诊并分析根因。
AI 所做的不只是生成代码。它收紧了我们的质量循环,帮助一个小团队以更少的持续返工交付高质量应用。
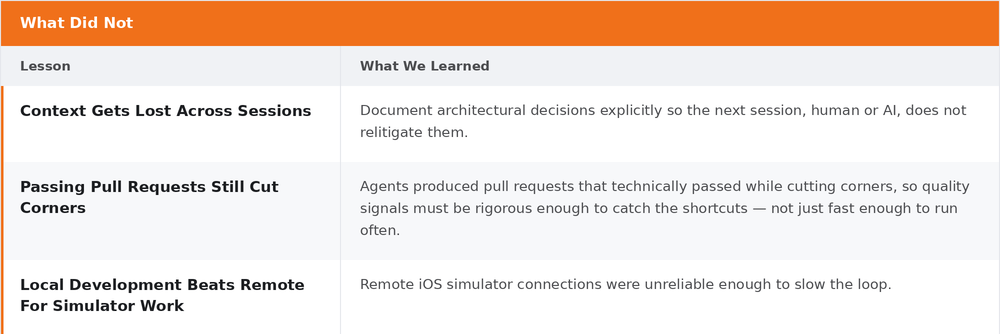
哪些奏效,哪些没有奏效

致谢
我们感谢 Neeharika Sinha 、 Jane Kou 、 Gang Yang 、 Guohao Zhang 、 Zeya Zhang 、 Kinnary Jangla 和 Yonghui Lu 作出的宝贵贡献。
English / 原文
- Meta’s newest app, Forum, is for anyone who wants to go deeper into the conversations in their Facebook groups.
- To build Forum, Meta engineers adopted a whole new way of working by bringing an AI agent into the development cycle.
- We’re sharing insights into what it took to build Forum with agentic AI: how we adapted the codebase, tested frameworks and internal tooling for agentic execution, what worked, and what didn’t.
Forum is a standalone Groups app that a small team built from scratch. It’s also where we tested a different way of working: treating an AI agent as a participant in the engineering process rather than a faster way to type.
That experiment needed a definition of success, and ours wasn’t code volume. We measured verified, production-ready outcomes — changes that build, pass tests, and survive review.
From Human-In-The-Loop to Human-On-The-Loop
Pointing AI at the coding step alone doesn’t change much. Our results compounded as we extended the approach to the stages around implementation — planning, building, testing, and verification. The clearest way to see the shift is in who owns each step.
With human-in-the-loop , the engineer drives every step and the AI assists inside it by autocompleting a function, suggesting a fix, or answering a question. Each iteration advances at the pace of the person driving it.
With human-on-the-loop , the agent runs the iteration itself — plan, implement, build, test, correct, repeat — while the engineer sets the goal, watches the run, steps in when it drifts, and approves the result. The person’s job moves from executing the steps to owning the outcome and holding the quality bar. This is the target we are driving toward, not a finished state: some stages run autonomously today, while others still keep an engineer in each iteration.
When the engineer supervises, work stops being strictly sequential. Cycles that used to run one at a time can overlap, and an engineer’s time goes to direction and judgment rather than to sitting through the loop. But that only holds if what comes back can be trusted. Without verification, AI-generated code creates a familiar problem — plausible output that no one has confirmed actually works, which an engineer then has to read, debug, and often discard. Weak signals don’t remove the constraint; they move it from writing code to reviewing code that looks finished and isn’t.
So we set the bar at verification rather than compilation. Compiling isn’t the finish line — a task is complete only once automated tests and visual checks have passed. Agents check their own work before an engineer sees it, which means what reaches review is a smaller set of higher-confidence results rather than a pile of output to sift through. Less gets generated, and less gets discarded. Every shipped outcome still carries an engineer’s sign-off; our effort went into making that sign-off fast and well-evidenced, with build results, test outcomes, and recorded verification sessions attached to the change.
With the engineer outside of every cycle, the loop has to run safely on its own. Four capabilities make that possible:
Planning as technical specification: Agentic execution requires extreme precision. Ambiguity that an engineer might resolve through intuition results in agent failure. We invested in rigorous upstream decomposition and machine-readable context, which tightened the engineering loop for engineers and agents alike.
Automated verification inside the loop is the force multiplier: We integrated automated pass/fail signals — build status, unit tests, and UI spec matching — directly into the agent loop. This enabled asynchronous development producing ready-to-review pull requests with pre-populated test plans and recorded verification sessions. Verification is the hard part to get right, and how much we can safely hand to the loop is gated by how much we can trust the verifiers.
Simulated user testing with agents: We deployed navigation agents that interact with the live app exactly like a person would. These agents perform actions, read the screen, and report regressions. Navigation agents are able to run the same verification paths continuously.
Agentic production operations: After launch, agents help automate root-cause analysis. When someone using Forum submits feedback, the agents use that feedback to investigate possible regressions. The agents then forward the analysis to engineers who decide the next course of action.
The Operating Model
That ownership model needs machinery with five key components:
- Rules are permanent project instructions. When the agent repeats a mistake more than twice, we encode the correction once, for everyone.
- Skills turn team conventions into loadable steps the agent can invoke.
- Agents automate checks that previously required a manual pass.
- Commands chain skills and agents into workflows. They assess complexity, reproduce a bug, plan and implement a fix, create the pull request, and run a multi-stage review.
- Hooks are automated triggers, such as running a linter after every agent turn, checking simulator connectivity before install, and validating tests before a pull request is created.
Adapting the Environment to the Models
The biggest gains came from changing our code and tooling, not our prompts.
Architectural legibility over inherited complexity: We worked to keep Forum’s codebase as straightforward as possible and chose to modularize key pieces of the architecture in order to get the benefits of battle-tested infrastructure while also letting the agents plug and play easily. Where we couldn’t easily do so, we rebuilt from scratch, trading reuse for agentic throughput, and it proved rewarding in development speed. Agents learn patterns from the code they read. Fix a weak pattern once and every future agent session inherits the improvement; leave it and the same shortcut shows up in everything the agent writes next.
Give agents tools, not descriptions: Our main failure mode was the agent losing track of where it was in the app — editing the home feed when asked to change the group home screen, or guessing at screen coordinates. So instead of describing the app to the agent, we gave it tools to check: read the live view hierarchy from the simulator, list the elements actually on screen, and look up the path to a target view — all before it acts. Misdirected edits dropped sharply. We applied the same approach wherever agents touched our systems: give the agent a way to check state directly rather than a description to reason from.
Build-level isolation for safe AI prototyping: As Forum matured toward production, we wanted early-stage prototypes and agent-generated experiments to have room to run while keeping the production app strictly limited to finished, reviewed work. We wanted a stronger guarantee than feature gating alone, where prototype code still exists inside the production build. Our solution was a separate build flavor , a sandbox app that shares the exact same codebase, frameworks, and design system as production, but compiles prototype code out of the production build entirely via a plugin/socket architecture.
This gave us three things at once:
- Designers and cross-functional partners could prototype freely using AI tools without needing an engineer in the loop for each change.
- Anything built in the sandbox could be ported directly to production with no rebuild.
- No prototype code could crash the production app because it physically didn’t exist in that build.
The pattern let us keep fast AI iteration after we had real people using the app to protect.
Finding Real Bugs With AI Stress Testing
Adapting the environment did more than make the agent faster to build with — it made the agent a tester. We didn’t point it at one specific defect. Instead, we set up repeatable stress scenarios that mimic real user behavior (aggressive scrolling, random group browsing, rapid navigation, repeated media loading) and ran them routinely across builds. Because these runs produce consistent signals (crashes, memory growth, page faults, UI regressions), the agent can triage anomalies, narrow to the triggering sequence, and then investigate the root cause.
One such run surfaced a memory issue. The agent isolated a repro, proposed a fix, and verified it — all during development, before the app reached users. The fix materially reduced on-device memory growth and page faults across repeated stress sessions.
While engineers made the architectural decisions, the detection and regression monitoring were automated and repeatable; once an anomaly was detected, the agent could reproduce → isolate → propose a fix → verify with the same harness.
Applying the Same Discipline to Forum’s Feed
We applied the human-on-the-loop approach in two places:
Building the stack: Agents mapped the architectural options and trade-offs; engineers then evaluated and chose. What we deliberately kept human was the target — deciding what a good outcome looks like is a product judgment, not something the system should define for itself.
Operating the stack: Questions that used to require whichever engineer knew the relevant code path now go to an investigation agent that gathers what it needs and posts a write-up with suggested fixes. After hand-scoring a batch of real investigations we arrived at a workflow where the agent compresses the mechanical work and delivers a structured write-up to an engineer, who then validates whether a finding is a real bug or an intentional trade-off.
What improved quality wasn’t better prompting. It was context. One recurring category of investigation came back weak until we gave the agent the same pointers to the relevant code, example queries, and design docs that we’d give any new engineer on day one. The quality of that category jumped. The difference from human onboarding is that you train once, and every future session starts from it.
Did It Work?
Beyond shipping faster, we shipped cleaner. Continuous verification surfaced systemic issues — like the memory bottleneck above — during development rather than after launch. The results show up in the performance profile:
- Quality, found early: The autonomous stress-testing loop caught and fixed the aforementioned memory issue during development rather than post-launch, roughly halving memory use and page faults.
- Velocity: Forum reached core feature parity with Facebook Groups in eight weeks, with AI handling much of the routine implementation so engineers could focus on architecture, product decisions, and quality.
- Leverage that lasted: After launch, agent-driven investigation helped engineers triage and root-cause user feedback.
The AI did more than generate code. It tightened our quality loop, helping a small team deliver a high-quality app with less ongoing rework.
What Worked, and What Did Not
Acknowledgements
We thank Neeharika Sinha _,_Jane Kou _,_Gang Yang _,_Guohao Zhang _,_Zeya Zhang _,_Kinnary Jangla , and Yonghui Lu for their valuable contributions.