推出 Reflection Beam:面向 AWS Agentic 编程的开放权重模型
英文标题:Introducing Reflection Beam: an open-weight model for agentic coding on AWS
Reflection AI 推出了 Beam,一款面向 Agentic 编程和长周期任务的开放权重稀疏 MoE 模型,拥有 5010 亿总参数、230 亿活跃参数,并支持最高 100 万 token 的有效上下文长度。Beam 权重以 Apache 2.0 许可证在 Hugging Face 发布,提供 BF16、FP8 和 NVFP4 检查点版本。开发者可以通过 Amazon SageMaker JumpStart 快速部署托管实时端点,也可以在 SageMaker HyperPod Inference 上结合 JumpStart、SGLang 或 vLLM 获得 Kubernetes 原生的分布式 GPU 控制能力。该模型的大规模参数量要求开发者重点规划 GPU 容量、权重内存、KV 缓存、分片、并行策略及模型缓存,并根据实测负载配置路由和弹性伸缩。
 1.3 MB
 1.3 MB
 2.4 KB
 345.0 KB
 141.2 KB
 346.5 KB
 141.8 KB
 161.0 KB
 16.1 KB
 13.7 KB
 19.3 KB
 27.8 KB
 20.4 KB
 18.2 KB
 25.1 KB
 49.6 KB
中文
Reflection AI 推出了 Beam,这是一款面向 Agentic 编程和长周期任务的开放权重模型,可用于维护代码、使用工具、解读结果以及完成多步骤工作流。开放权重发布使开发者和研究人员能够控制运行时、部署环境和定制流程。
本文介绍 Reflection 的愿景,并展示如何在 AWS 上部署 Beam。若要采用完全托管的路径,可先从 Amazon SageMaker JumpStart 实时端点开始。当需要对分布式 GPU 基础设施进行 Kubernetes 原生控制时,可将 Amazon SageMaker HyperPod Inference 与 JumpStart、SGLang 或 vLLM 搭配使用。我们还将说明 Beam 的 5010 亿总参数如何影响检查点存储、权重内存、分片和并行化,以及其 230 亿活跃参数如何影响每个 token 的计算量。
在发布时,Beam 已在 Amazon SageMaker JumpStart 的美国东部(弗吉尼亚北部)和美国东部(俄亥俄)区域提供。
Reflection 的开放智能愿景
Reflection 的使命是通过开放模型权重、公开研究成果和开源软件,让所有人都能获得开放且可访问的智能能力。其完整 AI 技术栈涵盖模型、核心软件、生产基础设施和应用程序。Beam 将这一方法带给构建软件工程和 Agentic 系统的开发者。
关于 Reflection Beam
Beam 是一款稀疏混合专家模型,可用于解决软件问题、修改代码、调用工具,以及基于中间结果采取行动。它拥有 5010 亿总参数和 230 亿活跃参数,Reflection 表示其有效上下文长度为 100 万 token。
Reflection 通过 Hugging Face 以 Apache 2.0 许可证发布 Beam 的权重。Beam 1.0 提供 BF16、FP8 和 NVFP4 检查点变体。这些格式具有不同的内存占用和硬件兼容性。你可以使用 AWS 托管的 JumpStart 容器配置部署模型,也可以在 AWS 环境中使用 SGLang 或 vLLM 检查和定制模型。
了解部署架构
请选择满足控制和扩展需求的服务路径。
- 如果希望使用 AWS 托管的模型包、端点和调用 API,且无需运维 Kubernetes,请从 SageMaker JumpStart 实时端点开始。
- 如果希望在由 Amazon Elastic Kubernetes Service(Amazon EKS)编排的 HyperPod 集群上使用 AWS 托管容器和模型配置,请使用 HyperPod Inference 上的 JumpStart。
- 如果需要控制服务镜像、运行时参数、量化或分布式执行,请在 HyperPod Inference 上使用 SGLang 或 vLLM。
- 应根据检查点存储、权重内存、KV 缓存、上下文长度、批处理、运行时开销和支持的并行化方式来确定部署规模。
- 定义预期的并发和延迟目标,然后根据测得的工作负载行为配置副本、缓存、路由和自动扩缩容。
JumpStart 实时路径通过托管部署工作流,将模型、容器和端点打包在一起。HyperPod 路径则开放集群和服务运行时,以便你控制分布式执行、缓存、路由和扩展。
下图展示了 HyperPod 路径使用的组件。Beam 可通过 SageMaker JumpStart、Hugging Face Hub 或可选的 Amazon Simple Storage Service(Amazon S3)镜像获取。分布式工作节点使用 AWS 托管的 JumpStart 容器,或自定义的 SGLang、vLLM 运行时。
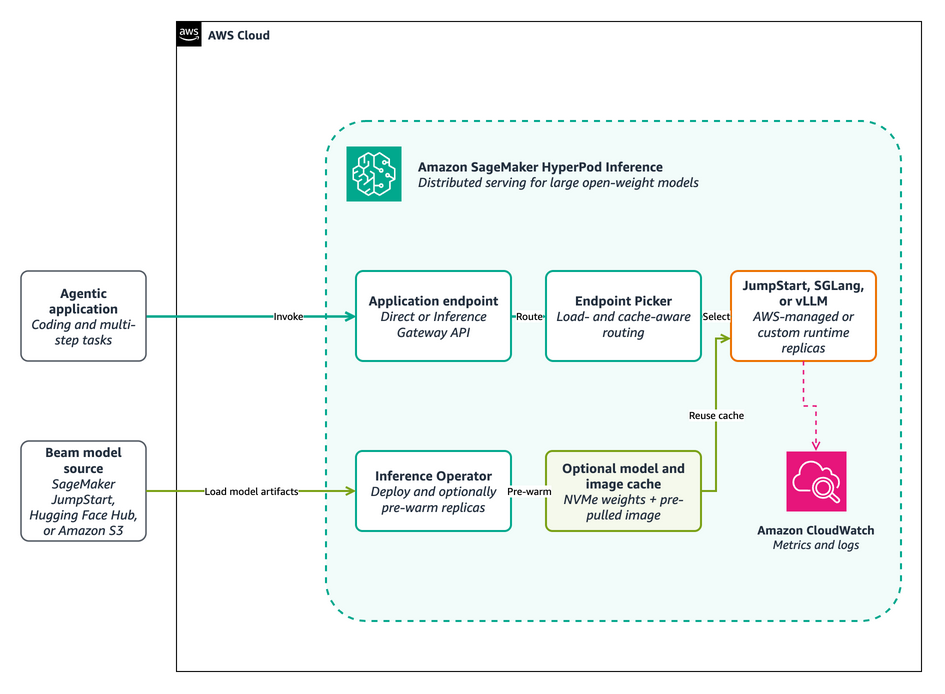
图 1:使用 Amazon SageMaker HyperPod Inference 的分布式 Beam 部署
前提条件
你需要:
- 一个 AWS 账户,并拥有针对所选 SageMaker 部署路径及其相关 AWS Identity and Access Management(IAM)、网络和存储资源的权限。
- 通过 SageMaker JumpStart 或 Hugging Face 上的某个 Beam 1.0 检查点仓库获取 Beam 的访问权限。
- 接受模型条款,安装 AWS Command Line Interface(AWS CLI)和 Python 3.11 或更高版本。
- 拥有适用于受支持 Beam 配置的 GPU 配额和容量。
规划并获取 GPU 容量
Beam 的 5010 亿总参数需要多 GPU 部署。BF16 的权重内存需求最高,因此应规划多节点配置,为权重和运行时开销提供足够的聚合 GPU 内存。对于 FP8,请使用搭载 NVIDIA H100 GPU 的 ml.p5.48xlarge,或搭载 H200 GPU 的 ml.p5e.48xlarge 和 ml.p5en.48xlarge。对于 NVFP4,请使用搭载 NVIDIA B200 GPU 的 ml.p6-b200.48xlarge。请确认发布的检查点、运行时和并行布局支持所选实例类型。
- 计算一个副本的权重、KV 缓存和运行时开销所需内存,然后通过负载测试确认估算结果。
- 选择支持所需加速实例的 AWS 区域。
- 检查所选实例类型的服务配额和可用容量。在可用时使用按需容量,或将 SageMaker 训练计划作为计划任务的短期预留方式。
- 为镜像传输、权重下载、分片加载和运行时初始化预留时间。
路径 1:通过 SageMaker JumpStart 实时端点快速开始
如果希望以最短路径从模型目录获得托管 HTTPS 端点,请首先使用 JumpStart 实时端点。该示例通过一条支持变体感知的命令支持 BF16、FP8 和 NVFP4 模型 ID。其 README 和 Python 文件是有关受支持实例类型、请求架构、部署命令和清理命令的权威来源。
-
克隆示例仓库。
git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git -
进入 SageMaker JumpStart 部署示例目录。
cd sagemaker-genai-hosting-examples/01-models/ReflectionAI/Beam-1.0-501B-A23B-NVFP4/ -
创建并激活 Python 虚拟环境。
python3 -m venv .venv source .venv/bin/activate -
安装示例依赖项。
python -m pip install -r requirements.txt -
针对 FP8 执行受限的部署、调用和清理生命周期。
python jumpstart_real_time.py \
--variant fp8 \
--endpoint-name reflection-beam-fp8-smoke
该命令会部署 FP8 端点、发送一个简短请求、打印响应,并清理端点。使用 bf16 或 nvfp4 可选择其他检查点变体;省略 --variant 时,NVFP4 为默认选项。当需要持续运行端点时,请使用 README 中的 Python 函数。
路径 2:使用 SageMaker HyperPod Inference 部署
当你需要对分布式 GPU 基础设施进行 Kubernetes 原生控制时,请使用 HyperPod Inference。你可以使用 AWS 托管的 JumpStart 容器配置,也可以通过 SGLang 或 vLLM 部署 Beam。HyperPod Inference 部署示例 README及其配置文件是关于已发布清单、模型和镜像标识符、受支持运行时版本以及命令的权威来源。
在开始前,请配置对由 EKS 编排、且安装了 HyperPod Inference Operator 和必要附加组件的 HyperPod 集群的 kubectl 访问权限。你还需要集群的虚拟私有云(VPC)、子网、安全组、对所选 Beam 和运行时工件的访问权限;如果启用模型缓存,还需要本地 NVMe 容量。如果所选仓库要求身份验证,请使用独立的 Hugging Face 访问令牌。
针对开发和实验,可从 Hugging Face Hub 部署固定版本的 Beam。对于生产部署和模型缓存,请将检查点复制到 Amazon S3 或 Amazon FSx。HyperPod 模型和镜像缓存可以将权重预加载到节点本地 NVMe 存储,并预拉取服务镜像。
HyperPod Inference Gateway提供 OpenAI 兼容接口,并在副本之间路由请求。HyperPod Inference 还支持托管分层 KV 缓存和智能路由。这些功能属于2026 年推出的 Amazon SageMaker Inference 能力之一。
下图进一步展示模型准备和运行时请求流程。启用模型缓存后,Inference Operator 会使用所选权重和服务镜像预热符合条件的节点。在运行时,Inference Gateway 和 Endpoint Picker 可将每个请求定向至合适的 JumpStart 托管、SGLang 或 vLLM 副本。
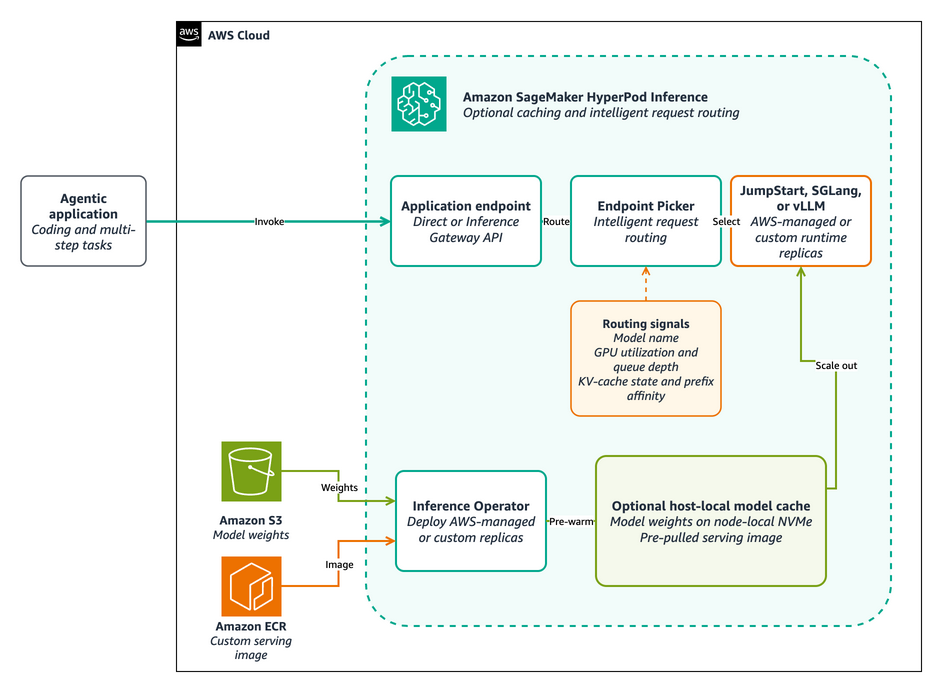
图 2:HyperPod 模型缓存和请求路由
准备部署工件
使用不可变输入,以便复现部署和性能结果。
- 使用部署示例中记录的 JumpStart 模型发布版本。
- 为自定义运行时选择 BF16、FP8 或 NVFP4 检查点。
- 对于自定义运行时,请将公开 Beam commit SHA 和镜像摘要保留在示例发布配置中。
- 仅当集群无法拉取上游镜像,或你的组织要求使用已获批准的镜像仓库时,才将发布的镜像镜像复制到私有 Amazon Elastic Container Registry(Amazon ECR)仓库。
- 不要将令牌、生成的密钥、私有模型 ID、镜像仓库凭证和未发布结果提交到仓库中。
选择服务路径
除非工作负载需要特定的推理运行时或配置,否则应从 SageMaker JumpStart 开始。
| 服务路径 | 适用场景 | 你需要管理的内容 |
|---|---|---|
| SageMaker JumpStart | 希望使用 AWS 托管的容器和模型配置,并降低运行时维护工作。 | 选择 Beam 模型版本、受支持的实例类型、端点配置和扩缩容策略。 |
| SGLang 或 vLLM | 需要特定推理运行时或配置,例如自定义运行时参数、解析器、量化或并行化。 | 固定受支持的运行时镜像、模型版本、解析器配置和分布式执行设置。 |
使用 SageMaker JumpStart 部署
SageMaker JumpStart 可减少容器集成工作,而 HyperPod 则保留对集群容量、扩展和可观测性的控制。
- 在 SageMaker Studio 中,打开 JumpStart 模型目录。
- 在 所有公共模型 下,选择 Beam。
- 选择 SageMaker HyperPod 作为部署目标。
- 选择集群和 Kubernetes 命名空间。
- 输入端点名称,然后选择 部署。
- 在使用已发布的 JumpStart 请求架构调用端点之前,确认部署状态。
对于基础设施即代码工作流,请使用 HyperPod 示例中发布的 JumpStart 配置。你可以在配置部署前检查 reflection-beam-jumpstart.yaml 清单模板。
-
克隆示例仓库,并进入 HyperPod Beam 目录。
git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git cd sagemaker-genai-hosting-examples/SageMakerHyperpod/reflection-beam/ -
创建 README 中说明的本地配置文件。
cp config/deployment.env.example config/deployment.env cp config/release.env.example config/release.env -
在更改集群之前验证 JumpStart 配置。
python hyperpod_tool.py \ --config config/deployment.env \ --config config/release.env \ validate jumpstart -
部署 JumpStart 配置。
python hyperpod_tool.py \
  --config config/deployment.env \
  --config config/release.env \
  deploy jumpstart \
  --timeout-seconds 1800
辅助工具会渲染并应用已发布的 JumpStartModel 资源,而不会将已填充的发布值写入磁盘。
使用 SGLang 或 vLLM 部署
当你需要直接控制服务运行时时,请选择 SGLang 或 vLLM。配置部署前,请检查 reflection-beam-sglang.yaml 清单模板或 [reflection-beam-vllm.yaml 清单模板](https://github.com/aws-samples/sagemaker-gena
English / 原文
Reflection AI introduced Beam, an open-weight model for agentic coding and long-horizon tasks such as maintaining code, using tools, interpreting results, and completing multi-step workflows. The open-weight release gives developers and researchers control over the runtime, deployment environment, and customization process.
In this post, we explain Reflection’s vision and show how you can deploy Beam on AWS. Start with an Amazon SageMaker JumpStart real-time endpoint for a fully managed path. When you need Kubernetes-native control over distributed GPU infrastructure, use Amazon SageMaker HyperPod Inference with JumpStart, SGLang, or vLLM. We also explain how Beam’s 501 billion total parameters shape checkpoint storage, weight memory, sharding, and parallelism, while its 23 billion active parameters influence per-token compute.
At launch, Beam is available in Amazon SageMaker JumpStart in US East (N. Virginia) and US East (Ohio).
Reflection’s vision for open intelligence
Reflection’s mission is to make intelligence open and accessible to all through open model weights, published research, and open source software. Its full AI stack spans models, core software, production infrastructure, and applications. Beam brings this approach to developers building software engineering and agentic systems.
About Reflection Beam
Beam is a sparse mixture-of-experts model for resolving software issues, modifying code, calling tools, and acting on intermediate results. It has 501 billion total parameters and 23 billion active parameters, and Reflection reports an effective context length of 1 million tokens.
Reflection releases Beam’s weights through Hugging Face under the Apache 2.0 license. Beam 1.0 is available in BF16, FP8, and NVFP4 checkpoint variants. These formats provide different memory footprints and hardware compatibility. You can deploy the model with the AWS managed JumpStart container configuration or inspect and customize the model with SGLang or vLLM in your AWS environment.
Understand the deployment architecture
Choose the serving path that meets your control and scaling requirements.
- Start with a SageMaker JumpStart real-time endpoint when you want an AWS managed model package, endpoint, and invocation API without operating Kubernetes.
- Use JumpStart on HyperPod Inference when you want the AWS managed container and model configuration on a HyperPod cluster orchestrated by Amazon Elastic Kubernetes Service (Amazon EKS).
- Use SGLang or vLLM on HyperPod Inference when you need to control the serving image, runtime arguments, quantization, or distributed execution.
- Size the deployment for checkpoint storage, weight memory, KV cache, context length, batching, runtime overhead, and the supported parallelism.
- Define the expected concurrency and latency targets, then configure replicas, caching, routing, and autoscaling from measured workload behavior.
The JumpStart real-time path packages the model, container, and endpoint behind a managed deployment workflow. The HyperPod path exposes the cluster and serving runtime so that you can control distributed execution, caching, routing, and scaling.
The following diagram shows the components used by the HyperPod path. Beam can be sourced through SageMaker JumpStart, Hugging Face Hub, or an optional Amazon Simple Storage Service (Amazon S3) mirror. The distributed workers use the AWS managed JumpStart container or a custom SGLang or vLLM runtime.
Figure 1: Distributed Beam deployment with Amazon SageMaker HyperPod Inference
Prerequisites
You need:
- An AWS account with permissions for your selected SageMaker deployment path and its supporting AWS Identity and Access Management (IAM), networking, and storage resources.
- Access to Beam through SageMaker JumpStart or one of the Beam 1.0 checkpoint repositories on Hugging Face.
- Acceptance of the model terms, the AWS Command Line Interface (AWS CLI), and Python 3.11 or later.
- GPU quota and capacity for a supported Beam configuration.
Plan and obtain GPU capacity
Beam’s 501 billion total parameters require a multi-GPU deployment. BF16 has the largest weight-memory requirement, so plan a multi-node configuration with enough aggregate GPU memory for the weights and runtime overhead. For FP8, use ml.p5.48xlarge with NVIDIA H100 GPUs or ml.p5e.48xlarge and ml.p5en.48xlarge with H200 GPUs. For NVFP4, use ml.p6-b200.48xlarge with NVIDIA B200 GPUs. Confirm that the released checkpoint, runtime, and parallel layout support the selected instance type.
- Calculate memory for weights, KV cache, and runtime overhead for one replica, then confirm the estimate with a load test.
- Choose an AWS Region that supports the required accelerated instance.
- Check the service quota and available capacity for the selected instance type. Use on-demand capacity when available, or use a SageMaker training plan as a short-term reservation for scheduled work.
- Allow time for image transfer, weight download, shard loading, and runtime initialization.
Path 1: Get started with a SageMaker JumpStart real-time endpoint
Use a JumpStart real-time endpoint first when you want the shortest path from the model catalog to a managed HTTPS endpoint. The sample supports the BF16, FP8, and NVFP4 model IDs through one variant-aware command. Its README and Python file are the source of truth for supported instance types, request schema, deployment command, and cleanup command.
-
Clone the sample repository.
git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git -
Enter the SageMaker JumpStart deployment sample directory.
cd sagemaker-genai-hosting-examples/01-models/ReflectionAI/Beam-1.0-501B-A23B-NVFP4/ -
Create and activate a Python virtual environment.
python3 -m venv .venv source .venv/bin/activate -
Install the sample dependency.
python -m pip install -r requirements.txt -
Run the bounded deployment, invocation, and cleanup lifecycle for FP8.
python jumpstart_real_time.py \
--variant fp8 \
--endpoint-name reflection-beam-fp8-smoke
The command deploys the FP8 endpoint, sends a short request, prints the response, and cleans up the endpoint. Use bf16 or nvfp4 to select another checkpoint variant; NVFP4 is the default when you omit --variant. Use the Python functions in the README when you need to keep an endpoint running.
Path 2: Deploy with SageMaker HyperPod Inference
Use HyperPod Inference when you need Kubernetes-native control over distributed GPU infrastructure. You can use the AWS managed JumpStart container configuration or deploy Beam with SGLang or vLLM. The HyperPod Inference deployment sample README and its configuration files are the source of truth for released manifests, model and image identifiers, supported runtime versions, and commands.
Before you begin, configure kubectl access to an EKS-orchestrated HyperPod cluster with the HyperPod Inference Operator and required add-ons. You also need the cluster virtual private cloud (VPC), subnets, security groups, access to the selected Beam and runtime artifacts, and local NVMe capacity if you enable model caching. Use an isolated Hugging Face access token if the selected repository requires authentication.
Deploy a pinned Beam revision from Hugging Face Hub for development and experimentation. For production deployments and model caching, copy the checkpoint to Amazon S3 or Amazon FSx. HyperPod model and image caching can preload weights onto node-local NVMe storage and pre-pull the serving image.
The HyperPod Inference Gateway provides an OpenAI-compatible interface and routes requests across replicas. HyperPod Inference also supports managed tiered KV caching and intelligent routing. These are among the Amazon SageMaker Inference capabilities introduced in 2026.
The next diagram expands the model preparation and runtime request flow. When model caching is enabled, the Inference Operator warms eligible nodes with the selected weights and serving image. At runtime, the Inference Gateway and Endpoint Picker can direct each request to a suitable JumpStart-managed, SGLang, or vLLM replica.
Figure 2: HyperPod model caching and request routing
Prepare deployment artifacts
Use immutable inputs so that you can reproduce deployment and performance results.
- Use the JumpStart model release recorded in the deployment sample.
- Choose the BF16, FP8, or NVFP4 checkpoint for a custom runtime.
- For a custom runtime, keep the public Beam commit SHA and image digest in the sample release configuration.
- Mirror the released image into a private Amazon Elastic Container Registry (Amazon ECR) repository only when your cluster cannot pull the upstream image or your organization requires an approved registry.
- Keep tokens, generated secrets, private model IDs, registry credentials, and unpublished results out of the repository.
Choose a serving path
Start with SageMaker JumpStart unless your workload requires a specific inference runtime or configuration.
| Serving path | Use it when | What you manage |
|---|---|---|
| SageMaker JumpStart | You want an AWS-managed container and model configuration with less runtime maintenance. | Select the Beam model version, supported instance type, endpoint configuration, and scaling policy. |
| SGLang or vLLM | You need a specific inference runtime or configuration, such as custom runtime arguments, parsers, quantization, or parallelism. | Pin the supported runtime image, model revision, parser configuration, and distributed execution settings. |
Deploy with SageMaker JumpStart
SageMaker JumpStart reduces container integration work while HyperPod retains control over cluster capacity, scaling, and observability.
- In SageMaker Studio, open the JumpStart model catalog.
- Under All public models , choose Beam.
- Choose SageMaker HyperPod as the deployment target.
- Select the cluster and Kubernetes namespace.
- Enter an endpoint name, and choose Deploy.
- Confirm the deployment status before invoking the endpoint with the released JumpStart request schema.
For an infrastructure-as-code workflow, use the released JumpStart configuration in the HyperPod sample. You can inspect the reflection-beam-jumpstart.yaml manifest template before configuring the deployment.
-
Clone the sample repository, and enter the HyperPod Beam directory.
git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git cd sagemaker-genai-hosting-examples/SageMakerHyperpod/reflection-beam/ -
Create the local configuration files described in the README.
cp config/deployment.env.example config/deployment.env cp config/release.env.example config/release.env -
Validate the JumpStart configuration before changing the cluster.
python hyperpod_tool.py \ --config config/deployment.env \ --config config/release.env \ validate jumpstart -
Deploy the JumpStart configuration.
python hyperpod_tool.py \
  --config config/deployment.env \
  --config config/release.env \
  deploy jumpstart \
  --timeout-seconds 1800
The helper renders and applies the released JumpStartModel resource without writing populated release values to disk.
Deploy with SGLang or vLLM
Choose SGLang or vLLM when you need direct control over the serving runtime. Before configuring the deployment, inspect the reflection-beam-sglang.yaml manifest template or the reflection-beam-vllm.yaml manifest template. The sample README remains the source of truth for released values and commands.
-
Clone the sample repository.
git clone https://github.com/aws-samples/sagemaker-genai-hosting-examples.git -
Enter the HyperPod Beam directory.
cd sagemaker-genai-hosting-examples/SageMakerHyperpod/reflection-beam/ -
Create the local configuration files described in the README.
cp config/deployment.env.example config/deployment.env cp config/release.env.example config/release.env -
Validate the selected configuration before changing the cluster.
python hyperpod_tool.py \ --config config/deployment.env \ --config config/release.env \ validate sglang -
Deploy Beam, and wait for a terminal deployment state.
python hyperpod_tool.py \
  --config config/deployment.env \
  --config config/release.env \
  deploy sglang \
  --timeout-seconds 1800
Replace sglang with vllm to use vLLM. The helper validates the selected settings, applies the rendered manifest without writing release values to disk, waits with a fixed timeout, and prints diagnostics if deployment fails.
Invoke Beam
Invoke JumpStart endpoints with the released model request schema. For SGLang or vLLM, use the bounded smoke test included in the HyperPod sample.
Invoke the deployed endpoint
-
Install the sample client dependency.
python3 -m venv .venv source .venv/bin/activate python -m pip install -r requirements.txt -
Run a private health check and short request with the recommended starting sampling settings.
python hyperpod_tool.py \
--config config/deployment.env \
smoke sglang \
--prompt "List three checks for a healthy model deployment." \
--temperature 1.0 \
--top-p 0.7
Replace sglang with vllm for a vLLM deployment. The helper selects a ready worker, opens a temporary port-forward, checks endpoint health, sends the request, and closes the port-forward.
The response resembles the following:
1. Confirm that the endpoint reports ready.
2. Send a short inference request.
3. Review the service logs for startup errors.
For an authenticated Inference Gateway, use the bearer-token procedure in the HyperPod sample README. Keep credentials out of source code, manifests, and command history.
Measure and tune performance
- Test each serving path with repeated, representative coding and tool-use requests at the expected concurrency.
- Record the Beam model version, image digest, instance type, precision, context length, parallelism, serving arguments, cache state, and test repetitions.
- Measure request success rate, p50 and p95 time to first token, time per output token, end-to-end latency, and aggregate output tokens per second.
- Tune batch size, KV cache allocation, replica count, autoscaling, and model and image caching from those results.
- Recheck output quality after changing precision or quantization.
Clean up
Delete resources when you finish testing to avoid ongoing charges.
- For a SageMaker JumpStart real-time endpoint, follow the cleanup instructions in the SageMaker JumpStart deployment sample README.
- For JumpStart, SGLang, or vLLM on Amazon SageMaker HyperPod Inference, follow the cleanup instructions in the HyperPod Inference deployment sample README.
- Delete a dedicated HyperPod or Amazon EKS cluster created for the walkthrough.
- Delete unused cached weights, mirrored artifacts, load balancers, log groups, temporary IAM roles, and captured inference data.
Conclusion
Reflection Beam gives developers an open-weight model designed for agentic coding and multi-step tasks. Start with a SageMaker JumpStart real-time endpoint for a fully managed deployment. Use SageMaker HyperPod Inference with JumpStart when you need Kubernetes-native infrastructure control without managing the serving container, or choose SGLang or vLLM when you need a custom runtime.
Use the SageMaker JumpStart deployment sample or the HyperPod Inference deployment sample, then follow the instructions.
To learn more about Reflection AI and its vision for open intelligence, visit Reflection AI and read Introducing Beam.
Resources
About the authors
Clement Perrot
Clement is Founding Applied AI at Reflection AI. Before joining Reflection AI, he worked in the Generative AI Innovation Center at AWS and founded AI and consumer hardware startups, two of which were acquired.
Florent Gbelidji
Florent is Open Source Engineering Lead and Member of Technical Staff at Reflection AI. Before joining Reflection AI, he led Hugging Face’s cloud partnership with AWS and worked as a machine learning engineer helping companies build open-source AI solutions.
Daniel Quang
Daniel is a Solutions Architect on the Frontier AI Startups team at AWS, where he helps the world’s largest and most strategic generative AI startups scale their infrastructure on AWS. He holds a PhD in Computer Science from the University of California, Irvine, with a research focus on machine learning and bioinformatics.
Hadrien Almela
Hadrien is a Senior Frontier AI Account Manager in the AWS Startup team, helping top AI startups build technical integrations and global go-to-market partnerships. He has eight years of experience in the startup landscape. Hadrien lives in San Francisco, California, and enjoys diving, surfing, and traveling to exotic places.
Dan Ferguson
Dan is a Senior Worldwide Specialist Solutions Architect for Generative AI at AWS, based in New York. He helps customers integrate machine learning and generative AI workloads efficiently, effectively, and sustainably.
Daniel Wirjo
Daniel is a Solutions Architect at AWS, focused on AI and SaaS startups. As a former startup CTO, he enjoys collaborating with founders and engineering leaders to drive growth and innovation on AWS. Outside of work, Daniel enjoys taking walks with a coffee in hand, appreciating nature, and learning new ideas.
Sureshkumar Natarajan
Sureshkumar is a Senior Technical Account Manager at Amazon Web Services. He helps enterprise customers accelerate their cloud modernization journeys and is part of the Technical Field Community for Next Generation Developer Experience supporting AWS Transform custom.