面向端侧的原生模型构建:谷歌发布 LiteRT Tensor API
英文标题:Native Model Authoring for Edge with LiteRT Tensor API
谷歌正式发布 LiteRT Tensor API,为端侧 AI 提供轻量级的原生 C++ 模型图构建层,赋予开发者更底层的计算图控制权与跨异构硬件的一致性。该 API 支持从 safetensors 直接读取权重,并通过共享加速器缓冲区实现预处理、推理与后处理的端到端零拷贝;实测在 MacBook Pro GPU 上比 Apple MLX 提速约 1.5 倍。此外,该 API 构成了 AI 编码智能体(Coding Agent)自动化生成与调优计算图的理想编程底座,成功将 WebGPU 上的 SAM 2 运行帧率提升超 3 倍。这一工具为端侧大模型与多模态部署带来了兼具原生灵活性与跨平台便携性的全新开发范式。
 11.7 KB
 416.0 KB
 81.6 KB
 79.9 KB
 327.4 KB
 22.4 KB
 66.5 KB
 66.3 KB
中文
在设备端部署 AI 意味着必须在每台目标硬件上面对严苛的延迟与内存预算限制。生产环境中部署模型最常见的路径是转换已训练好的模型——例如使用 LiteRT Torch 转换 PyTorch 模型,并配合 LiteRT runtime 进行推理运行。这是走向生产环境最快捷、最可靠的路线,也是我们针对绝大多数项目所推荐的做法。然而在某些情况下,开发者希望能完全掌控网络的表示和优化方式,以便支持全新的网络架构,或是尝试新的底层 lowering 逻辑,而无需等待上游框架的更新。
为了获得终极控制权,开发者通常会使用原生 C++ 或着色器语言(Shader languages)手动编写计算逻辑。Apple 的 MLX 使这种“代码优先”(code-first)的方式在 Apple Silicon 上蔚然成风,而 llama.cpp 则展示了量身定制的 C++ 实现在 LLM 推理上所能达到的极限。然而,这种级别的控制伴随着巨大的代价:具体实现往往与特定的后端(如 Metal、OpenCL 或 Vulkan)深度绑定,每迁移到一个新硬件目标就必须重写一次。此外,在 CPU、GPU 和 NPU 之间管理零拷贝缓冲区互操作与同步,同时将预处理、模型推理和后处理拼接串联起来,需要耗费大量的人工工程工作。
为了解决上述难题,我们非常高兴地宣布推出全新的 LiteRT Tensor API。这是 LiteRT 技术栈中专为改进手工构建模型而设计的轻量级构建层。它将原生构建的灵活性与跨平台的可移植性融为一体:开发者可以在 C++ 中逐个算子(op)构建计算图,精确决定运行哪些算子以及如何连接。同一张图既可以通过 LiteRT 运行在 CPU、GPU(由开源项目 ML Drift 驱动)和 NPU 上,也可以完全脱离模型文件或 runtime、直接借助 XNNPACK 在 CPU 上运行,免去了针对每个新硬件目标重写代码的麻烦。模型推理以及预处理/后处理均可使用相同的 API 组装,并通过共享加速器缓冲区进行链接,从而确保数据永远不需要在 CPU 与加速器之间往返拷贝。对于大多数模型,我们依然建议以转换流程作为最佳默认选项;而在需要对计算图进行底层精细控制,或希望整个流水线端到端完全在加速器上运行的时候,Tensor API 则是理想之选。
LiteRT Tensor API 同样构成了 AI 编码智能体(Coding Agent)的理想编程底座,为自动生成、重连和调优模型图提供了结构化原语。在本文接下来的部分,我们将深入探讨其架构设计,并通过具体的代码示例展示如何从零开始构建模型。
真实案例展示:Web 端 Segment Anything
[视频/嵌入内容:浏览器暂不支持播放此视频]
为了展示 Tensor API 的实际威力,我们构建了一个可交互的 Segment Anything 应用,它完全在浏览器端基于 WebGPU 本地运行。该应用能够借助 Meta 的 Segment Anything Model 2 (SAM 2) 实现实时的多目标分割与跟踪,既可以通过简单的鼠标点击触发,也可以使用由 Gemma 4 E2B 驱动的自然语言提示词来引导。
该 SAM 2 模型完全是通过 LiteRT Tensor API 用 C++ 原生编写构建的。AI 编码智能体编写并优化了该模型,使其在 WebGPU 上的 512x512 分辨率处理帧率从不足 10 fps 提升到了 30 fps 以上。完整的代码实现和 Web 应用现已开源,可在 GitHub 仓库 LiteRT Samples 中获取。
什么是 LiteRT Tensor API?
LiteRT Tensor API 提供了用于构建与优化端侧模型的四大核心特性:
- 对图结构的完全控制:开发者可决定模型图中的每一个算子以及算子之间的每一处连接,从逐元素数学运算到面向加速器优化的大语言模型复合算子(如缩放点积注意力 Scaled Dot-Product Attention、RMSNorm 和 KV-cache 更新等)。
- 直接摄取权重:直接从模型权重检查点读取权重(例如 Hugging Face 的 .safetensors 文件),无需中间转换脚本。
- 以张量为中心的缓冲区互操作:预处理、模型各个分区以及后处理之间通过共享加速器缓冲区相互传递张量,使中间数据始终保留在加速器上,实现零数据拷贝。
- 面向 AI Agent 的构建基石:模型是由定义明确的算子构建的纯 C++ 代码,因此 AI 编码智能体可以轻松构建模型、对照参考实现验证结果,并通过在各个设备上测试变体来基准调优性能。
跨平台性能
我们在三款设备的 GPU 上运行了 SAM 2 模型的同一套 C++ 代码:一台 macOS 笔记本(Metal)、一部 iOS 手机(Metal)和一部 Android 手机(OpenCL)。在 MacBook Pro 上的基准测试中,它的运行速度比 Apple MLX 快约 1.5 倍(fp16 精度,图像编码器加掩膜解码器)。SAM 2.1 示例 中包含了基准测试运行命令,以便复现这些结果。
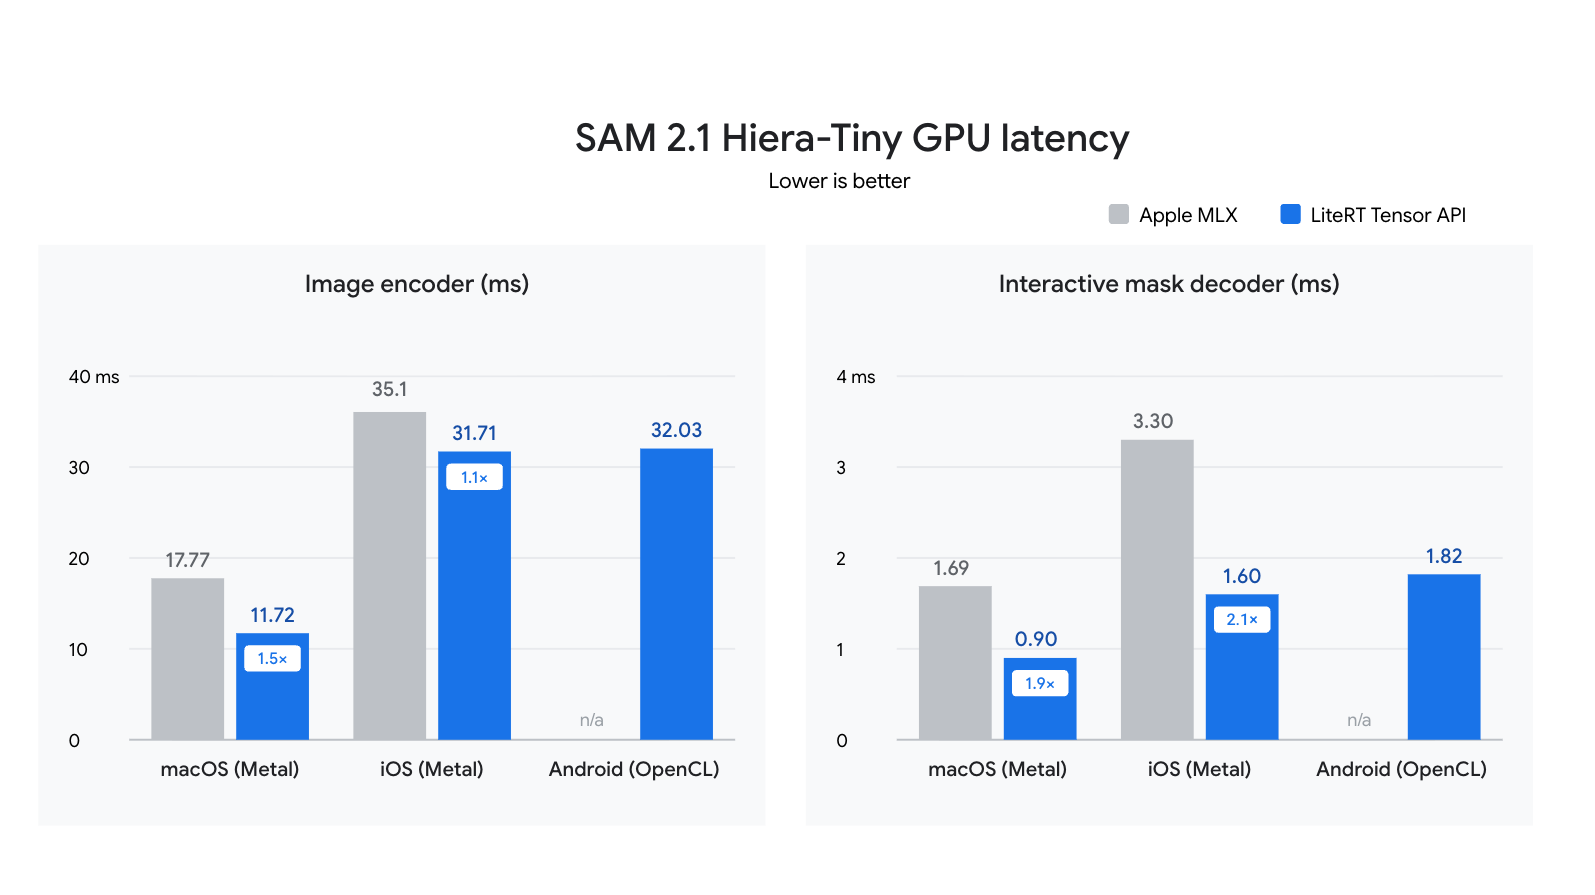
注:测试时间包含图像编码器与掩膜解码器;预处理和后处理额外增加约 0.34 ms。输出的掩膜与 Meta 官方 PyTorch 参考实现逐像素完全吻合。
上手使用 Tensor API
使用原生 C++ 构建模型
在 Tensor API 中,每个层都是一个作用在 Tensor 变量上的 C++ 函数,由高级算子以及直接从权重文件中加载的权重组合而成。例如,下面是一个多头自注意力(Multi-head self-attention)层:
cpp // Multi-head self-attention over x: [batch, tokens, dim]. Tensor Attention(const Tensor& x, const WeightMap& w, int heads) { std::vector s = x.GetShape(); int b = s[0], n = s[1], dim = s[2], d = dim / heads; Tensor q = FullyConnected(x, w.at("q_proj.weight"), w.at("q_proj.bias")); Tensor k = FullyConnected(x, w.at("k_proj.weight"), w.at("k_proj.bias")); Tensor v = FullyConnected(x, w.at("v_proj.weight"), w.at("v_proj.bias")); // Split heads: [b, n, dim] -> [b, heads, n, d]. q = Transpose(Reshape(q, {b, n, heads, d}), {0, 2, 1, 3}); k = Transpose(Reshape(k, {b, n, heads, d}), {0, 2, 1, 3}); v = Transpose(Reshape(v, {b, n, heads, d}), {0, 2, 1, 3}); // softmax(q * k^T / sqrt(d)) * v, for all heads at once. Tensor scores = BatchMatMul(q, k, /adj_x=/false, /adj_y=/true); Tensor attn = Softmax(Mul(scores, 1.0f / std::sqrt(static_cast(d)))); Tensor out = BatchMatMul(attn, v); // Merge heads: [b, heads, n, d] -> [b, n, dim], then project. out = Reshape(Transpose(out, {0, 2, 1, 3}), {b, n, dim}); return FullyConnected(out, w.at("out_proj.weight"), w.at("out_proj.bias")); }
在 SAM 2 示例中,BuildEncoder 和 BuildDecoder 将类似的网络层组合成编码器和解码器图,并通过 ModelFactory 将两者作为同一个 sam2_image.tflite 文件的两个 Signature 导出。
导出 .tflite 文件是运行计算图的两种方式之一。后端通过 Tensor 上的模板参数指定:TfLiteMixinTag 会导出可供 LiteRT 在 CPU、ML Drift (GPU) 或 NPU 上运行的 .tflite;而 XnnpackMixinTag 则直接通过 XNNPACK 在 CPU 上运行相同代码,无需任何模型文件。同时为 Tensor 打上这两种 Tag 即可同时保留两个选项:
cpp // Tag tensors for both backends; ops record one graph either can run. using T = Tensor<TfLiteMixinTag, XnnpackMixinTag>; T y = Attention(x, w, /heads=/8); // The layer above, over T values. // Export a .tflite and run it with LiteRT on CPU, GPU, or NPU. Save({y}, "attention.tflite"); // Or run the same graph directly on the CPU with XNNPACK. auto runner = XnnpackRunner::Create({y}); runner->Run();
SAM 2 采用了 .tflite 路径以便在浏览器中调用 WebGPU,本文余下部分将主要围绕该路径展开。Gemma 4 示例 则采用了直接路径在 CPU 上执行 Prefill 与 Decode,这是运行 Tensor API 代码最轻量级的方式。Tensor API README 对这两种方式均有详细说明。
自然的开发工作流往往结合两者:在开发迭代阶段采用直接的 XNNPACK 路径,直接从 .safetensors 加载权重而无需重复重新打包模型文件;当准备好在移动端或通过 LiteRT.js 在网页端发布部署时,再导出 .tflite。
表达完整的机器学习计算图
真实的应用需要的远不止神经网络本身。在演示中,将摄像头画面与一次点击转化为分割掩膜需要四个步骤:预处理将摄像头帧转换为模型所需的 512x512 图像;图像编码器将图像提取为特征;掩膜解码器结合特征与点击输入预测出掩膜;后处理将掩膜缩放回原始画面的尺寸。要让整个流水线高速运转,需要满足两个条件:在各步骤之间将数据保留在加速器(如 GPU)上,以及控制每一步在各个加速器上的执行方式。
零拷贝:将整个流水线保留在加速器上
在传统应用中,通常只有模型在 GPU 上运行;CPU 负责缩放每一帧画面,将编码器的输出传递给解码器,并对生成的掩膜进行后处理。每一次跨硬件传输都会触发数据拷贝并导致 GPU 等待卡顿。
在 litert-samples/sam2 中,全部四个步骤均以 Tensor API 计算图的形式在 GPU 上运行。例如,预处理是一个使用 CreateLambdaRunner 构建的轻量图。这些图在启动时连接一次以共享缓冲区,之后每帧和每次点击即可直接运行:
cpp // Pre-processing is authored with the same Tensor API ops as the model: // RGBA camera frame [1, H, W, 4] -> normalized pixels [1, 512, 512, 3]. auto pre_runner = CreateLambdaRunner( env, options, {{"frame", Tensor({.type = Type::kU8, .shape = {1, H, W, 4}})}}, [=](const TensorsMap& inputs) { Tensor rgb = Slice(inputs.at("frame"), {0, 0, 0, 0}, {1, H, W, 3}); Tensor resized = ResizeBilinear(Cast(rgb, Type::kFP32), {512, 512}); return TensorsMap{{"pixels", Add(Mul(resized, scale), bias)}}; }); auto model = LitertDynamicRunner::Create(env, "sam2_image.tflite", options); // Connect once: neighboring steps share buffers, so nothing is copied. pre_runner.SetOutput("pixels", model.GetInput("encode_image", "pixels")); for (auto name : {"image_embeddings", "feat_s1", "feat_s0"}) { model.SetInput("decode_mask", name, model.GetOutput("encode_image", name)); } post_runner.SetInput("masks", model.GetOutput("decode_mask", "masks"));
各步骤之间完全没有数据回传至 CPU:全部 522 个编码器算子与 269 个解码器算子均在 GPU 上执行,预处理与后处理每帧仅增加约 0.34 ms 开销。
完全控制:针对各后端调优计算图
由于计算图是纯 C++ 代码,开发者或编码 Agent 能够针对特定后端进行重写。我们的编码智能体 Antigravity 将 SAM 2 的逐帧决策逻辑(如目标是否仍然可见)从原本的 CPU 代码迁移进了计算图中。像 score > 0 这样的比较运算由于输出 true/false 布尔值,在 WebGPU 上原本仍会退化回退(fallback)至 CPU 运算,因此智能体在 StepPos 中将其重写为了算术运算:
cpp // Simplified from StepPos and BuildStep in sam2v_graph.cc. // Before: Greater outputs true/false values, which fall back to the CPU. // Tensor visible = Cast(Greater(score, zero), Type::kFP32); // After: GPU-friendly ops; 0 for score <= 0, 1 for score >= 1e-4. Tensor visible = Sub(1.0f, Relu(Sub(1.0f, Mul(Relu(score), 1e4f)))); // Keep the mask if the object is visible; otherwise, blank it out. Tensor mask = Add(Mul(best_mask, visible), Mul(Sub(1.0f, visible), -1024.0f));
每个目标现在每帧仅需一次 GPU 调用。智能体完成了诸如将注意力缩放(attention scale)折叠进权重等一系列类似优化,并在保留每次改动前均对照 Hugging Face 的 SAM 2 进行精度验证。这就是我们将模型帧率提升 3 倍以上的方法。
未来展望
我们目前正致力于支持直连 ML Drift (GPU) 后端、适配 NPU 友好的算子操作以及全图自动化量化功能。同时,我们也在推进支持通过 .tflite 进行 Python 建模构建。
English / 原文
Shipping on-device AI means meeting tight latency and memory budgets on every device you target. The most common path for deploying models in production is converting a trained model, for example converting a PyTorch model with LiteRT Torch, and running it with the LiteRT runtime. This offers the quickest and most reliable route to production, and it's the path we recommend for most projects. Sometimes, though, developers want full control over how a network is represented and optimized to support new architectures or to try a new lowering logic without waiting for upstream framework updates.
For ultimate control, developers write computations manually in native C++ or shader languages. Apple's MLX made this code-first approach popular on Apple silicon, and llama.cpp showed how far tailored C++ implementations can take LLM inference. However, the level of control comes at a significant cost: implementations are tightly coupled to specific backends (such as Metal, OpenCL, or Vulkan) and must be rewritten for each new hardware target. Furthermore, managing zero-copy buffer interoperability and synchronization across CPU, GPU, and NPU, while gluing together pre-processing, inference, and post-processing, demands substantial manual engineering effort.
To solve the above challenges, we are excited to announce the release of the novel LiteRT Tensor API, a lightweight authoring layer in the LiteRT stack, designed to improve handcrafting models. It combines the flexibility of native authoring with cross-platform portability. You build the computation graph op by op in C++, choosing exactly which ops run and how they connect. The same graph can run through LiteRT on CPU, GPU (powered by open-source ML Drift) and NPU, or without model file or runtime directly on CPU through XNNPACK, so you don't rewrite it for each new hardware target. Model inference and pre/post-processing can be assembled with the same API and chained through shared accelerator buffers, so that data never round-trips through the CPU. Start with the conversion path, which remains the best default for most models. Reach for the Tensor API when you need low-level control over the graph or want the whole pipeline to run end to end on the accelerator.
The LiteRT Tensor API also serves as an ideal programmatic foundation for AI coding agents, providing structured primitives to generate, rewire, and tune model graphs automatically. In the rest of this post, we’ll dive into the design and walk through practical code examples showing how to author models from scratch.
Real-world showcase: Segment Anything on Web
Sorry, your browser doesn't support playback for this video
To show the Tensor API in practice, we built an interactive Segment Anything App, running entirely on-device in the browser on WebGPU. The app enables real-time multi-object segmentation and tracking via Meta's Segment Anything Model 2 (SAM 2), triggered either by simple clicks or natural language prompts powered by Gemma 4 E2B.
The SAM 2 model is fully authored in C++ via the LiteRT Tensor API. A coding agent wrote and evolved it from under 10 to over 30 frames per second at 512x512 on WebGPU. See that the complete implementation and the web app are open source in the LiteRT Samples GitHub repo.
What is the LiteRT Tensor API?
The LiteRT Tensor API provides four key features for authoring and optimizing on-device models:
- Full control over graph structure : you decide every op in the model graph and every connection between them, from elementwise math to accelerator-optimized LLM composite ops, such as scaled dot-product attention, RMSNorm, and KV-cache updates.
- Direct weight ingestion : load weights straight from model checkpoints, such as Hugging Face .safetensors files, without conversion scripts needed in between.
- Tensor-centric buffer interop : pre-processing, model partitions, and post-processing pass tensors to each other through shared accelerator buffers, so intermediate data stays on the accelerator with zero copies.
- Building blocks for AI agents : models are plain C++ built from well-defined ops, so coding agents can construct a model, check its results against a reference, and tune its performance by benchmarking variants on each device.
Cross-platform performance
We ran the same C++ code for the SAM 2 model on the GPUs of three devices: a macOS laptop (Metal), an iOS phone (Metal), and an Android phone (OpenCL). In our tests on the MacBook Pro, it ran about 1.5x faster than Apple MLX (fp16, image encoder plus mask decoder). The SAM 2.1 sample includes the benchmark commands so you can reproduce the results.
Note: Times cover the image encoder and mask decoder; pre- and post-processing add ~0.34 ms. Output masks match Meta's PyTorch reference pixel for pixel.
Get started with Tensor API
Authoring model in native C++
With the Tensor API, each layer is a C++ function over Tensor values, built from high-level operators and weights loaded directly from the checkpoint. For example, here is a multi-head self-attention layer:
// Multi-head self-attention over x: [batch, tokens, dim].
Tensor Attention(const Tensor& x, const WeightMap& w, int heads) {
  std::vector<int> s = x.GetShape();
  int b = s[0], n = s[1], dim = s[2], d = dim / heads;
  Tensor q = FullyConnected(x, w.at("q_proj.weight"), w.at("q_proj.bias"));
  Tensor k = FullyConnected(x, w.at("k_proj.weight"), w.at("k_proj.bias"));
  Tensor v = FullyConnected(x, w.at("v_proj.weight"), w.at("v_proj.bias"));
  // Split heads: [b, n, dim] -> [b, heads, n, d].
  q = Transpose(Reshape(q, {b, n, heads, d}), {0, 2, 1, 3});
  k = Transpose(Reshape(k, {b, n, heads, d}), {0, 2, 1, 3});
  v = Transpose(Reshape(v, {b, n, heads, d}), {0, 2, 1, 3});
  // softmax(q * k^T / sqrt(d)) * v, for all heads at once.
  Tensor scores = BatchMatMul(q, k, /*adj_x=*/false, /*adj_y=*/true);
  Tensor attn = Softmax(Mul(scores, 1.0f / std::sqrt(static_cast<float>(d))));
  Tensor out = BatchMatMul(attn, v);
  // Merge heads: [b, heads, n, d] -> [b, n, dim], then project.
  out = Reshape(Transpose(out, {0, 2, 1, 3}), {b, n, dim});
  return FullyConnected(out, w.at("out_proj.weight"), w.at("out_proj.bias"));
}
C
In the SAM 2 sample, BuildEncoder and BuildDecoder compose layers like this into the encoder and decoder graphs, and ModelFactory exports both as two signatures of one sam2_image.tflite file.
A .tflite file is one of two ways to run your graph. The backend is a template argument on Tensor: TfLiteMixinTag exports a .tflite that LiteRT runs on CPU, ML Drift (GPU), or NPU, and XnnpackMixinTag runs the same code directly on CPU through XNNPACK, with no model file. Tag tensors with both to keep both options:
// Tag tensors for both backends; ops record one graph either can run.
using T = Tensor<TfLiteMixinTag, XnnpackMixinTag>;
T y = Attention(x, w, /*heads=*/8);  // The layer above, over T values.
// Export a .tflite and run it with LiteRT on CPU, GPU, or NPU.
Save({y}, "attention.tflite");
// Or run the same graph directly on the CPU with XNNPACK.
auto runner = XnnpackRunner::Create({y});
runner->Run();
C
SAM 2 takes the .tflite path to reach WebGPU in the browser, and the rest of this post follows it. The Gemma 4 example takes the direct path for prefill and decode on CPU, the lightest way to run Tensor API code. The Tensor API README walks through both.
A natural workflow uses both: iterate on the direct XNNPACK path, loading weights straight from the .safetensors checkpoint with no model file to rebuild, then export a .tflite when you're ready to ship with LiteRT on mobile or on the web through LiteRT.js.
Expressing the full ML computation graph
A real app needs more than the neural network itself. In the demo, turning a camera frame and a click into a mask takes four steps: pre-processing converts the frame into the 512x512 image the model expects; the image encoder turns that image into features; the mask decoder combines those features with the click to predict a mask; and post-processing scales the mask back to the frame's size. Running this whole pipeline fast takes two things: keeping data on the accelerator (such as the GPU) between steps, and controlling how each step runs on each accelerator.
Zero copies: Keep the whole pipeline on the accelerator
In a typical app, only the model runs on the GPU; the CPU resizes each camera frame, passes the encoder's output to the decoder, and post-processes the mask. Each trip copies data and stalls the GPU.
In litert-samples/sam2, all four steps are Tensor API graphs on the GPU. Pre-processing, for example, is a small graph built with CreateLambdaRunner. The graphs are connected once at startup to share buffers, then run for each frame and click:
// Pre-processing is authored with the same Tensor API ops as the model:
// RGBA camera frame [1, H, W, 4] -> normalized pixels [1, 512, 512, 3].
auto pre_runner = CreateLambdaRunner(
    env, options,
    {{"frame", Tensor({.type = Type::kU8, .shape = {1, H, W, 4}})}},
    [=](const TensorsMap& inputs) {
      Tensor rgb = Slice(inputs.at("frame"), {0, 0, 0, 0}, {1, H, W, 3});
      Tensor resized = ResizeBilinear(Cast(rgb, Type::kFP32), {512, 512});
      return TensorsMap{{"pixels", Add(Mul(resized, scale), bias)}};
    });
auto model = LitertDynamicRunner::Create(env, "sam2_image.tflite", options);
// Connect once: neighboring steps share buffers, so nothing is copied.
pre_runner.SetOutput("pixels", model.GetInput("encode_image", "pixels"));
for (auto name : {"image_embeddings", "feat_s1", "feat_s0"}) {
  model.SetInput("decode_mask", name, model.GetOutput("encode_image", name));
}
post_runner.SetInput("masks", model.GetOutput("decode_mask", "masks"));
C
No data returns to the CPU between steps: all 522 encoder and 269 decoder operations run on the GPU, and pre- and post-processing add only about 0.34 ms per frame.
Full control: Tune the graph for each backend
Because the graph is plain C++, you or your coding agent can rewrite it for each backend. Our agent, Antigravity, moved SAM 2's per-frame decisions, such as whether the object is still visible, from CPU code into the graph. Comparisons like score > 0 would still fall back to the CPU on WebGPU, because they output true/false values, so the agent rewrote them as arithmetic in StepPos:
// Simplified from StepPos and BuildStep in sam2v_graph.cc.
// Before: Greater outputs true/false values, which fall back to the CPU.
// Tensor visible = Cast(Greater(score, zero), Type::kFP32);
// After: GPU-friendly ops; 0 for score <= 0, 1 for score >= 1e-4.
Tensor visible = Sub(1.0f, Relu(Sub(1.0f, Mul(Relu(score), 1e4f))));
// Keep the mask if the object is visible; otherwise, blank it out.
Tensor mask = Add(Mul(best_mask, visible), Mul(Sub(1.0f, visible), -1024.0f));
C
Each object now takes a single GPU call per frame. The agent made a series of changes like this, such as folding the attention scale into the weights, and checked each against Hugging Face's SAM 2 before keeping it. That's how we more than tripled the model's frame rate.
What's next
We're working on direct ML Drift (GPU) backends, NPU-friendly operations, and automatic full-graph quantization. We're also adding Python authoring with .tflite export, plus wider dynamic-shape support for varying image sizes, batch sizes, and sequence lengths.
Explore our resources and start your journey with LiteRT:
Acknowledgements
The LiteRT Tensor API and its reference implementations are the result of a collaborative effort across the Google AI Edge and LiteRT teams. Special thanks to Byungchul Kim, Changming Sun, Chenchen Tang, Dillon Sharlet, Jingjiang Li, Lu Wang, Lutz Justen, Matthias Grundmann, Misha Gutman, Ronald Wotzlaw, and Sachin Kotwani.