瘦编排器(Thin Orchestrator):Meta 如何通过“给路由层减负”让 AI Agent 更可靠
英文标题:The Thin Orchestrator: How We Made Our AI Agents More Reliable by Giving the Router Less to Do
Meta 介绍了其在推荐系统数据管道自动化中沉淀出的“瘦编排器”(Thin Orchestrator)模式,核心在于将集中式“全能 Agent”拆解为一个仅 1,300 行代码的确定性路由器和 14 个垂直领域子 Agent。实践数据显示,新数据列的配置接入时间从过去的 3-4 天大幅压缩至 1 小时以内,且约三分之二的代码变更无需人工大幅修改即可顺利落地。研究表明,单体 Agent 容易在过载上下文中发生概念交叉污染与严重幻觉,而通过隔离领域上下文并将调度约束为确定性工作流模板,能显著降低 Token 消耗并提升执行准确率。这一工程实践为开发者构建生产级 Agent 提供了关键启示:明确划定确定性流程与概率性推理的边界,用架构隔离替代过度的 Prompt 调优。
 8.4 KB
 406 B
 435.1 KB
 467.4 KB
 759.9 KB
 117.2 KB
 142.2 KB
 35.0 KB
 42.3 KB
 31.9 KB
 81.2 KB
 75.2 KB
 104.3 KB
 13.9 KB
 4.4 KB
 2.3 KB
 1.0 KB
 487 B
中文
- 有时,给 AI Agent 提供其所需的全部知识反而是错误的做法。
- 在 Meta,我们发现通过刻意精简数据管道 Agent 的编排层(Orchestration Layer),系统在效率和准确率上获得了显著提升:编排层仅负责任务路由和执行可靠性检查,而领域推理则交由专用 Agent 处理。
- 在此,我们分享我们的实践过程与洞察,以及任何团队如何将该模式应用于其生产环境中的 AI Agent。
我们构建了一个 1,300 行代码的编排器,将 20 多个工作流路由至 14 个专用 AI Agent。它本身完全不执行任何领域工作(Domain Work)。而这正是其精髓所在。
起初,当我们部署 AI Agent 来实现 Meta 推荐系统中的数据列接入自动化时——这一过程跨越三个代码仓库、三种编程语言,以及多达六个必须保持同步的管道阶段——我们采取了大多数团队都会选择的做法:构建一个通晓一切的“超级智能 Agent”。
它在 Demo 演示中表现良好。但在生产环境中,它开始频繁产生幻觉。
解决之道并非换用更好的 Prompt,也不是换用更大的上下文窗口(Context Window),而是让中心 Agent 做得更少。我们将这种模式称为**瘦编排器(Thin Orchestrator)**模式:一个只负责把控时序和可靠性检查,并将每一个领域决策完全留给专业人员的路由器。
问题:上下文越多,效果越差
我们的管道采用配置即代码(Config-as-Code)模式:Python 配置驱动 C++ 代码生成,生成的代码馈送至数据处理服务,进而填充分析系统。接入单个数据列需要协调配置注册表、后端服务与数据管道的协同变更,每个数据列在数据正式到达前必须经历多达六个阶段。
我们最初的方案是采用一个单一 AI Agent,给它加载全部领域知识、配置 Schema、代码生成规则、管道路由逻辑、校验要求以及 10 多个数据源的填充模式。
这个 Agent 拥有它所需的一切。但这恰恰成了问题所在。
一旦超过某个上下文阈值,额外的知识不仅未能提升性能,反而导致了性能退化。Agent 会出现概念交叉污染,例如将某个子系统的字段命名规范套用到另一个子系统上,或者在从一个数据源填充数据时错误使用本属于另一个数据源的代码生成模式。西奈山 Windreich 人工智能与人类健康系的一篇预印本论文指出,在 80 个任务的批处理中,经过编排的多 Agent 系统的准确率可保持在 65.3%,而单 Agent 系统则骤降至 16.6%,同时多 Agent 系统的 Token 消耗最多可降低 65 倍。论文作者将此归因于该设计实现了任务隔离,从而避免了上下文干扰。我们当时经历的正是其反面:一个淹没在自身过量知识中的单体 Agent。
我们还评估了另一种单 Agent 方案。在人工针对每个任务进行 Prompt 工程的前提下,其成功率为 70-80%:工程师必须为每个具体任务量身定制 System Prompt。而在没有人工干预的情况下,成功率会暴跌至 10-20%。这显然不再是 Prompt 工程层面的问题,而是系统架构层面的缺陷。
解决方案:轻量级路由器搭配专业工作 Agent
我们将系统拆分为两层:
- 确定性编排器(Deterministic Orchestrator):完全不执行任何领域工作。它负责分类意图、收集必要字段、运行可靠性检查,并将其委托给合适的专业 Agent。它绝不对代码进行推理,不生成配置,也绝不触碰代码库。它本质上就是一个路由器。
- 14 个专用子 Agent(Specialized Subagents):每个子 Agent 都是拥有隔离上下文的垂直领域专家。Schema 管理 Agent 了解配置注册表;填充(Population)Agent 懂得如何针对 10 个数据源分别生成代码;校验(Validation)Agent 了解构建系统与质量检查。没有任何一个 Agent 能看到系统全貌。但这正是设计的特性,而非缺陷。
编排器对每个请求都遵循固定的 7 步协议:
- **读取(Read)**相关子 Agent 的指令文件。
- **检查(Check)**目标是否已存在(防止重复)。
- 向用户**收集(Gather)**必要字段。
- **自动发现(Auto-discover)**可推断的信息(代码库类型、现有配置)。
- 可靠性关卡(Reliability gate):检查是否存在活动告警或必须的审核人员。
- 将完整上下文**委托(Delegate)**给对应的子 Agent。
- **处理(Handle)**返回结果并暴露错误,确认执行成功。
步骤 1–5 和 7 均为确定性逻辑。唯独步骤 6 涉及大语言模型(LLM)推理,且发生在一个仅加载了其自身领域知识的隔离子 Agent 内部。
我们的架构设计:采用工作流模板,而非盲目新增 Agent
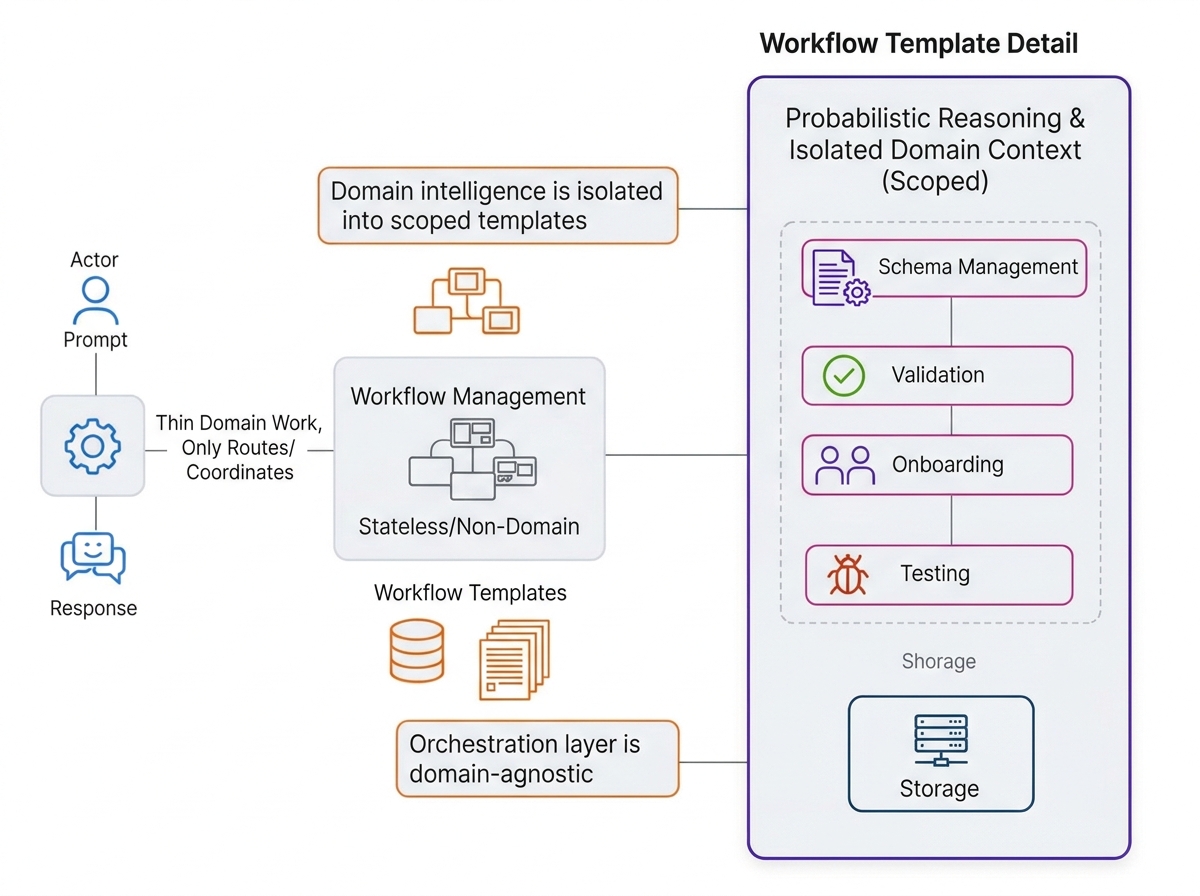
架构设计上的一个重要认知是:将“需要发生什么(What)”与“每个步骤如何执行(How)”分离开来。编排器通过工作流模板来定义阶段顺序——这些确定性的状态机极大地约束了 LLM 的决策空间:
- 数据列接入(Column Onboarding): Schema → 校验(Validation)→ 填充(Population)→ 测试(Testing)
- 事件接入(Event Onboarding): Schema → 填充(Population)→ 校验(Validation)→ 测试(Testing)→ 事件处理(Event Processing)
- 管道迁移(Pipeline Migration): 评估(Assessment)→ 规划(Planning)→ 填充(Population)→ 校验(Validation)→ 监控(Monitoring)
每个工作流模板都以不同的顺序复用同一个包含 14 个子 Agent 的公共池。当我们需要支持管道迁移这一全新用例时,我们并没有构建新的 Agent,而是编写了一个以新顺序调度现有 Agent 的工作流模板。零新增 Agent 代码,即可具备完整的生产能力。
每个子 Agent 都遵循统一的标准结构:
- 知识源(Knowledge sources): 运行时需要加载哪些领域文件(每个文件通常只有几千 Token)。
- 预收集清单(Pre-gathering checklist): 编排器在委托前必须收集哪些信息。
- 分步工作流(Step-by-step workflow): 领域特定的执行计划。
- 发现模式(Discovery patterns): 如何在 Monorepo(单体代码仓)中查找相关的代码模式。
- 故障排除(Troubleshooting): 针对常见错误的“错误-解决方案”映射表。
这种统一性意味着添加新子 Agent 是一项模板化的工作,而非从零开始的系统工程。第 15 个子 Agent 在结构上与第 1 个完全一致。
知识文件是在子 Agent 执行时按需加载的,而非直接嵌入在编排器中。我们维护了 25 多个按工作流领域分类的知识文件。当某个知识文件更新时,下一次会话会自动使用最新版本——无需修改编排器。相同的知识文件还能为我们 Agent 的多种平台实现提供服务。
落地成果
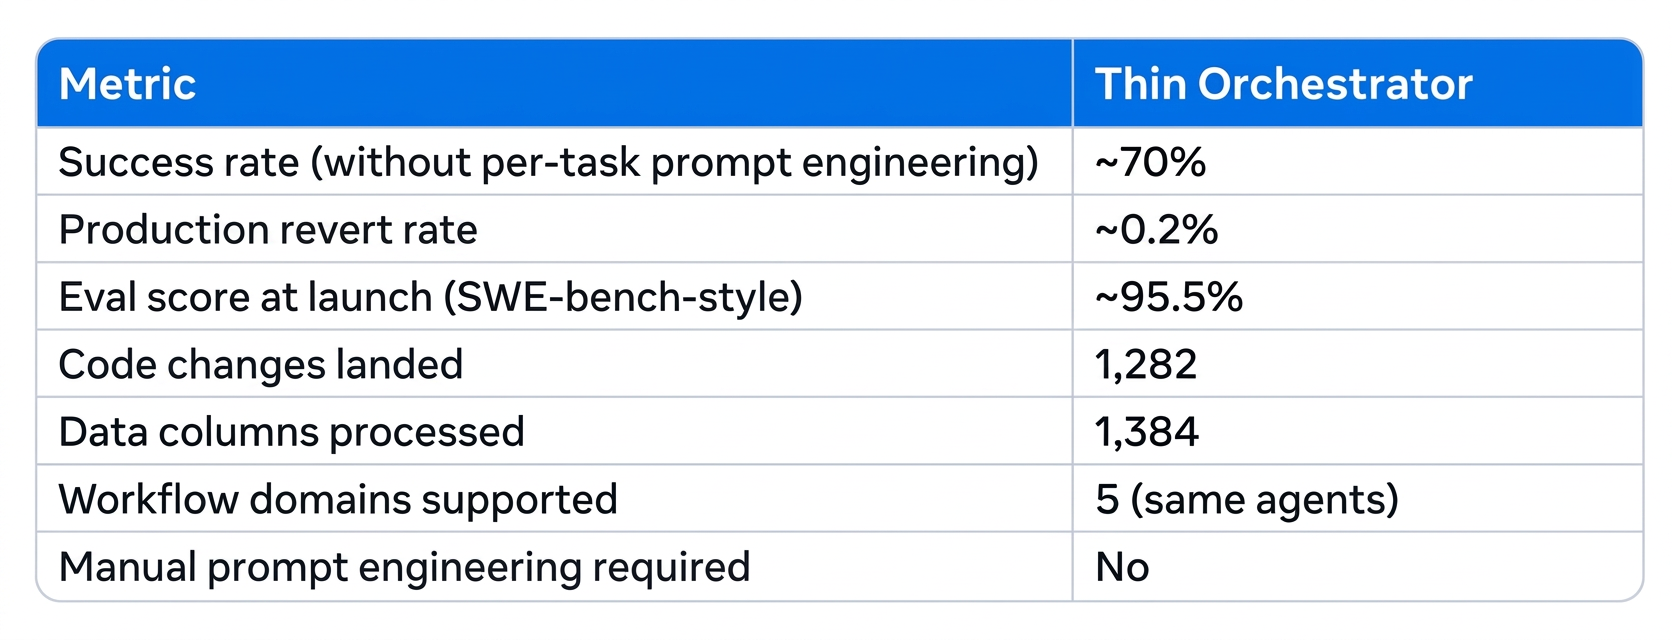 一个新数据列的配置准备工作,人工处理需要三到四天,在我们早期的配置驱动系统中大约需要一天。而采用瘦编排器系统后,耗时缩短到了 1 小时以内。
从更广泛的背景来看:系统提交的变更中,大约有三分之二无需人工大幅修改即可顺利合入。这一成果是通过牺牲通用性来换取深厚的垂直领域知识实现的,这是一个经过深思熟虑的架构抉择:编排器负责通用调度,子 Agent 负责垂直专业领域。
为什么这种模式有效(而笨重的重量级编排器会失效)
传统方法是让编排器成为最聪明的组件——赋予它全部上下文,让它推理应该做什么以及怎么做。这种模式在一开始行得通,直到它在最具挑战的场景下彻底失效——在面临大规模、复杂的多步骤工作流以及异构子系统时,它恰恰会在你最需要它的时候崩溃。
瘦编排器之所以有效,是因为它使架构边界与计算边界保持了一致:
- 确定性决策保持确定性。“由哪个子 Agent 处理此任务?”属于路由决策,而非推理任务。不要使用 LLM 来做这件事。
- 上下文隔离防止交叉污染。 负责数据源 A 的填充 Agent 永远看不到数据源 B 的模式,因此它根本不可能产生混淆并套用错误模式的幻觉。
- 故障被有效隔离。 如果某个子 Agent 执行失败,编排器会执行重试或升级上报。该失败不会污染编排器的状态,也不会污染其他子 Agent 的上下文。
- 系统各层级可独立迭代演进。 底座模型的升级能同时惠及全部 14 个子 Agent;知识文件的更新可即时生效;新增工作流模板可在不改动任何 Agent 的情况下解锁新能力。没有任何单一组件需要背负全部重担。
如何将该模式应用到你的 AI Agent 中
该模式不仅适用于数据管道。任何构建生产级 AI Agent 的团队都可以从中受益:
- 将路由与推理分离。 如果你的编排器正在做领域决策,说明它承担了过多的职责。路由应该是确定性的:关键字匹配、意图分类、字段收集。将所有的领域推理下沉到隔离的子 Agent 中。
- 将子 Agent 设计为结构统一的专家。 每个子 Agent 都应具有相同的结构:知识源、必要输入、执行步骤、错误处理。这使得添加新功能变成了一项模板化工作,而不是架构改造。
- 利用工作流模板而非新增 Agent 来实现系统扩展。 当你需要支持新用例时,首先问自己:能否以不同的顺序编排现有的 Agent?如果你无法在不同工作流之间复用 Agent,说明你的 Agent 与具体用例之间的耦合度过高。
- 在运行时按需加载知识,而非构建时加载。 将知识直接硬编码在编排器中会导致每次更新都需要重新部署。采用按需加载,更新就能立即跨所有平台生效。
- 明确划定确定性与概率性的边界。 对于每个组件,都要严格判定:这属于路由决策(确定性)还是推理任务(概率性)?编排器应站在确定性这一侧,子 Agent 则站在概率性这一侧。切勿将它们混为一谈。
支持瘦编排器的最有力的论据,在于其对立方案在故障模式下的糟糕表现。当一个重量级的编排器产生幻觉时,错误会波及下游的所有环节:它会路由到错误的 Agent、收集错误的字段,或者跳过关键的可靠性检查。而瘦编排器几乎没有给幻觉留下空间,因为它的路由和可靠性步骤完全不依赖 LLM 推理,而是严格遵循固定协议。“创造力”只发生在下游隔离的、受限于特定领域的上下文中,此时幻觉风险被降到了最低,故障也能得到有效控制。
未来展望
我们目前正扩展该架构,以应对新管道领域中数据列的激增。基于组件化的理念预示着这种扩展能够成功,因为扩展仅意味着添加工作流模板和知识文件,无需重构 Agent。我们还在探索系统如何基于生产环境的实际使用实现持续自我优化,即利用自动化反馈闭环来识别失败模式,并为子 Agent 的知识库提供针对性的改进建议,同时始终保留人工审核作为最终把关卡口。
这是一个反直觉的经验:在我们的 AI Agent 系统中,最重要的组件反而是那个干活最少的组件。保持你的编排器精简,让你的专业 Agent 专精,整个系统就会变得更加可靠。
致谢
这项工作是团队协作的成果。其他贡献者包括:Mani Bhushan、Rahul Maliakkal、Jae Ha、Chakrapani Kumar、Vivek Tiwari 和 Amanda Yin。
English / 原文
- Sometimes, giving an AI agent all of the knowledge it needs is the wrong approach.
- At Meta, we’ve seen notable improvements in efficiency and accuracy by keeping the orchestration layer of our data pipeline agents deliberately thin: It routes work and enforces reliability checks, while specialized agents do the domain reasoning.
- We’re sharing our own process and insights, plus how any team can apply this to their production AI agents.
We built a 1,300-line orchestrator that routes 20+ workflows to 14 specialized AI agents. It performs zero domain work itself. That’s the point.
When we first deployed AI agents to automate data column onboarding across Meta’s recommendation systems — a process spanning three code repositories, three programming languages, and up to six pipeline stages that must stay in sync — we did what most teams do: We built one smart agent that knew everything.
It worked in demos. In production, it started hallucinating.
The fix wasn’t better prompts or a bigger context window. It was giving the central agent less to do. We call this the thin orchestrator pattern: a router that owns sequencing and reliability checks, and leaves every domain decision to specialists.
The Problem: More Context, Worse Results
Our pipeline is config-as-code: Python configurations drive C++ code generation, which feeds data processing services, which populate analytics systems. Onboarding a single data column requires coordinated changes across configuration registries, backend services, and data pipelines, and each column moves through up to six stages before its data arrives.
Our first approach was a single AI agent loaded with all domain knowledge, configuration schemas, code generation rules, pipeline routing logic, validation requirements, and population patterns for 10+ data sources.
The agent had everything it needed. That was the problem.
Past a certain context threshold, additional knowledge degraded rather than improved performance. The agent would cross-contaminate concepts, applying field naming conventions from one subsystem to another, or using a code generation pattern meant for one data source when populating from a different one. A preprint from the Windreich Department of Artificial Intelligence and Human Health at Mount Sinai found that orchestrated multiagent systems held 65.3% accuracy at 80-task batches where single agents fell to 16.6%, while reducing token usage up to 65-fold. The authors attribute this to the design’s isolation of tasks, which prevented context interference. We were experiencing the inverse, a single agent drowning in its own knowledge.
We also evaluated an alternative single-agent approach. Its success rate was 70-80% with manual prompt engineering per task: An engineer had to craft a custom system prompt for each specific job. Without that handholding, success dropped to 10-20%. This wasn’t a prompt engineering problem. It was an architectural one.
The Approach: A Thin Router With Specialist Workers
We split the system into two layers:
- A deterministic orchestrator that performs zero domain work. It classifies intent, gathers required fields, runs reliability checks, and delegates to the right specialist. It never reasons about code, never generates configurations, and never touches the codebase. It’s a router.
- Fourteen specialized subagents , each a complete domain expert with isolated context. A schema management agent knows configuration registries. A population agent knows how to generate code for each of 10 data sources. A validation agent knows build systems and quality checks. No agent sees the full picture. That’s the feature, not the bug.
The orchestrator follows a fixed 7-step protocol for every request:
- Read the relevant subagent’s instruction file.
- Check if the target already exists (prevent duplicates).
- Gather required fields from the user.
- Auto-discover what can be inferred (repository type, existing configurations).
- Reliability gate check for active warnings or required reviewers.
- Delegate to the subagent with full context.
- Handle results and surface errors, confirm success.
Steps 1–5 and 7 are deterministic. Only step 6 involves large language model (LLM) reasoning, and it happens inside an isolated subagent with only its domain knowledge loaded.
What We Built: Workflow Templates, Not New Agents
One architectural insight was separating what needs to happen from how each step is performed. The orchestrator defines phase ordering through workflow templates — deterministic state machines that constrain the LLM’s decision space:
- Column Onboarding: Schema → Validation → Population → Testing
- Event Onboarding: Schema → Population → Validation → Testing → Event Processing
- Pipeline Migration: Assessment → Planning → Population → Validation → Monitoring
Each workflow template reuses the same pool of 14 subagents in different sequences. When we needed to support pipeline migration, a completely new use case, we didn’t build new agents. We wrote a new workflow template that sequenced existing agents differently. Zero new agent code. Full production capability.
Each subagent follows a standardized structure:
- Knowledge sources: which domain files to load at runtime (typically a few thousand tokens each).
- Pre-gathering checklist: what the orchestrator must collect before delegation.
- Step-by-step workflow: the domain-specific execution plan.
- Discovery patterns: how to find relevant code patterns in the monorepo.
- Troubleshooting: error-to-resolution mappings for common failures.
This uniformity means adding a new subagent is templated work, not greenfield engineering. The 15th subagent looks structurally identical to the first.
Knowledge files are loaded on demand at subagent execution time, not embedded in the orchestrator. We maintain 25+ knowledge files organized by workflow domain. When a knowledge file is updated, the next session automatically uses the latest version — no orchestrator changes required. The same knowledge files serve multiple platform implementations of our agent.
Results
Configuration prep for a new column took three to four days by hand and about a day with our earlier config-driven system. The thin orchestrator system does it in under an hour.
For broader context: About two-thirds of the system’s changes land without significant human edits. It gets there by trading generality for deep domain knowledge, a deliberate architectural choice. The orchestrator is general; the subagents are specialists.
Why This Works (And Why Heavyweight Orchestrators Don’t)
The conventional approach is to make the orchestrator the smartest component — give it all the context and let it reason about what to do and how to do it. This works until it doesn’t, and it stops working exactly when you need it most — at scale, with complex multi-step workflows, across heterogeneous subsystems.
The thin orchestrator works because it aligns architectural boundaries with computational boundaries:
- Deterministic decisions stay deterministic. “Which subagent handles this?” is a routing decision, not a reasoning task. Don’t use an LLM for it.
- Context isolation prevents cross-contamination. The population agent for data source A never sees data source B’s patterns. It can’t hallucinate the wrong one.
- Failures are contained. If a subagent fails, the orchestrator retries or escalates. The failure doesn’t corrupt the orchestrator’s state or other subagents’ contexts.
- The system improves at every layer independently. A better model improves all 14 subagents simultaneously. A knowledge file update takes effect immediately. A new workflow template unlocks new capabilities without touching agents. No single component carries the full weight.
How to Apply This to Your AI Agents
This pattern isn’t specific to data pipelines. Any team building production AI agents can benefit:
- Separate routing from reasoning. If your orchestrator is making domain decisions, it’s doing too much. Routing should be deterministic: keyword matching, intent classification, field gathering. Push all domain reasoning into isolated subagents.
- Design subagents as structurally uniform specialists. Every subagent should have the same structure: knowledge sources, required inputs, execution steps, error handling. This makes adding new capabilities templated work rather than architecture changes.
- Use workflow templates, not new agents, to scale. When you need a new use case, first ask: Can I sequence existing agents differently? If you can’t reuse agents across workflows, your agents are too coupled to specific use cases.
- Load knowledge at runtime, not at build time. Embed knowledge in the orchestrator and every update requires redeployment. Load it on demand and updates take effect immediately, across all platforms.
- Draw the deterministic/probabilistic boundary explicitly. For every component, decide: Is this a routing decision (deterministic) or a reasoning task (probabilistic)? The orchestrator should be on one side, the subagents on the other. Don’t mix them.
The strongest argument for a thin orchestrator is the failure mode of the alternative. When a heavyweight orchestrator hallucinates, the error spreads to everything downstream: it routes to the wrong agent, gathers the wrong fields, or skips reliability checks. A thin orchestrator leaves little room for hallucination because its routing and reliability steps don’t rely on LLM reasoning. It follows a fixed protocol. The creativity happens downstream, in isolated, domain-scoped contexts where hallucination risk is minimized and failures are contained.
What’s Next
We’re scaling this architecture to handle an increase in data columns across new pipeline domains. The compositional thesis predicts this will work because scaling means adding workflow templates and knowledge files, not rebuilding agents. We’re also exploring how the system can continuously improve from production usage, using automated feedback loops to identify failure patterns and propose targeted improvements to subagent knowledge, with human review always gating any changes.
The counterintuitive lesson: the most important component in our AI agent system is the one that does the least work. Keep your orchestrator thin and your specialists deep, and the whole system becomes more reliable.
Acknowledgements
_This work was a team effort. Some other people who contributed to this effort include:_Mani Bhushan, Rahul Maliakkal, Jae Ha, Chakrapani Kumar, Vivek Tiwari, and Amanda Yin.