基于 Amazon SageMaker HyperPod 微调 GPT-OSS-20B 实现多语言推理:SFT 与 GRPO 实践指南
英文标题:Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod
本文介绍了在 Amazon SageMaker HyperPod 上微调开源大模型 GPT-OSS-20B 以提升多语言思维链(CoT)推理能力的实战方案。针对基础模型默认仅用英语思考、在非英语推理测试中仅有 22% 正确率的缺陷,团队通过监督微调(SFT)将目标推理语言准确率直接提升至 100%,并进一步借助 GRPO 强化学习将最终回答语言准确率从 62% 提高至 70%。实验得出了明确的技术选型结论:SFT 负责向模型注入新行为,而 GRPO 适合在已有上限空间内进行定向优化与强化。该方法为全球化部署开源推理模型的开发者提供了清晰的高性能端到端训练参考架构。
 1.3 MB
 1.3 MB
 2.4 KB
 345.0 KB
 141.2 KB
 346.5 KB
 409.7 KB
 19.3 KB
 28.3 KB
 59.6 KB
中文
GPT-OSS-20B 是一个开源权重的推理模型,但它的思维过程默认使用英语。如果你要求它用法语、德语、西班牙语或意大利语进行推理,它虽然会确认该指令,但仍会使用英语生成思维链(Chain-of-Thought)。在一个包含 50 个样本的多语言推理测试中,基础模型在正确的目标语言中进行推理的概率仅为 22%。而这 22% 几乎全靠英语样本支撑(英语 100%、法语 0%、德语 10%、西班牙语 0%、意大利语 0%)。
对于为非英语用户部署推理模型的团队而言,这一差距至关重要。一个用法文提问的用户期望模型能够用法语进行思考和回答,而不是在思考过程中突然切换为英语。弥合这一差距是一个微调问题。这也引出了每个团队在定制开源权重模型时都会面临的核心疑问:应该采用监督微调(SFT)、基于群体相对策略优化的强化学习(GRPO),还是两者兼备?
在本文中,我们将逐步讲解如何在 Amazon SageMaker HyperPod 上微调 GPT-OSS-20B 以实现多语言推理。我们将展示 SFT 何时单独生效,以及 GRPO 何时能在其基础上带来可衡量的收益。为了更全面地理解 GRPO 在何时能够发挥作用,我们还在具有不同能力差距的两个任务上针对 Qwen2.5-7B 运行了对照实验。简而言之:SFT 承担了大部分核心工作,GRPO 则在存在提升空间时进行精细打磨,将技术与能力差距精准匹配才是决定最终成效的关键。
解决方案概览
本节将介绍多语言推理任务与数据集、SFT 与 GRPO 的互补机制,以及我们在 Amazon SageMaker HyperPod 上运行的训练技术栈。
任务与数据集
训练使用的数据集为 HuggingFaceH4/Multilingual-Thinking —— 这是一个思维链推理数据集,除英语外还翻译为了法语、西班牙语、德语和意大利语,包含大约 949 个训练样本和 50 个验证样本。模型会接收到一个 reasoning language: 系统提示词指令,并且必须克服其强大的英语先验倾向,完全在该目标语言中进行推理和回答。评估集包含 50 个测试用例:涵盖 5 种语言(EN/FR/DE/ES/IT)的 10 道数学/逻辑题。
关键评估指标有两个:
- 推理语言正确率(Reasoning-language correct) —— 思维链是否使用了要求的语言?
- 回答语言正确率(Answer-language correct) —— 最终回答是否使用了要求的语言?
SFT 与 GRPO 如何协同配合
理解这两种技术的最清晰方式是:SFT 负责教会模型原本不具备的行为;GRPO 则优化模型偶尔已经能够产生的行为。GRPO 的运作方式是针对每个提示采样一组响应,并引导策略向高于平均水平的响应靠近。如果期望的行为在基础分布中的生成概率为零,那么 GRPO 几乎没有任何可以强化的信号。这一核心理念解释了本文中的几乎所有实验结果。
训练技术栈
我们在采用 Amazon Elastic Kubernetes Service (Amazon EKS) 编排的 Amazon SageMaker HyperPod 上运行训练。对于 GPT-OSS-20B 的初始 SFT 和 GRPO 运行,我们使用了 PyTorch TRL 库。对于 Qwen 对照实验,我们切换为使用 veRL 作为训练器,使用 Ray 和 KubeRay 进行分布式编排,并使用 vLLM 进行快速 Rollout 生成。检查点和数据集保存在 Amazon FSx for Lustre 上,节点间通信使用 Elastic Fabric Adapter (EFA)。所有微调均采用低秩适应(LoRA),该方法参数高效且非常适合 SFT 和 GRPO。
下图展示了端到端的训练数据路径。来自用户的提交任务到达 Amazon SageMaker HyperPod 集群的 Amazon EKS 控制平面。Amazon EKS 调度一个 Ray head Pod 以及运行 veRL 训练器和 vLLM rollout worker 的 worker Pod。两组 Pod 都挂载 Amazon FSx for Lustre 以读取基础模型、训练数据和保存检查点。节点间集合通信采用 EFA。Rollout 从 vLLM 流式传回 veRL 训练器,训练器再将检查点写回 Amazon FSx for Lustre。
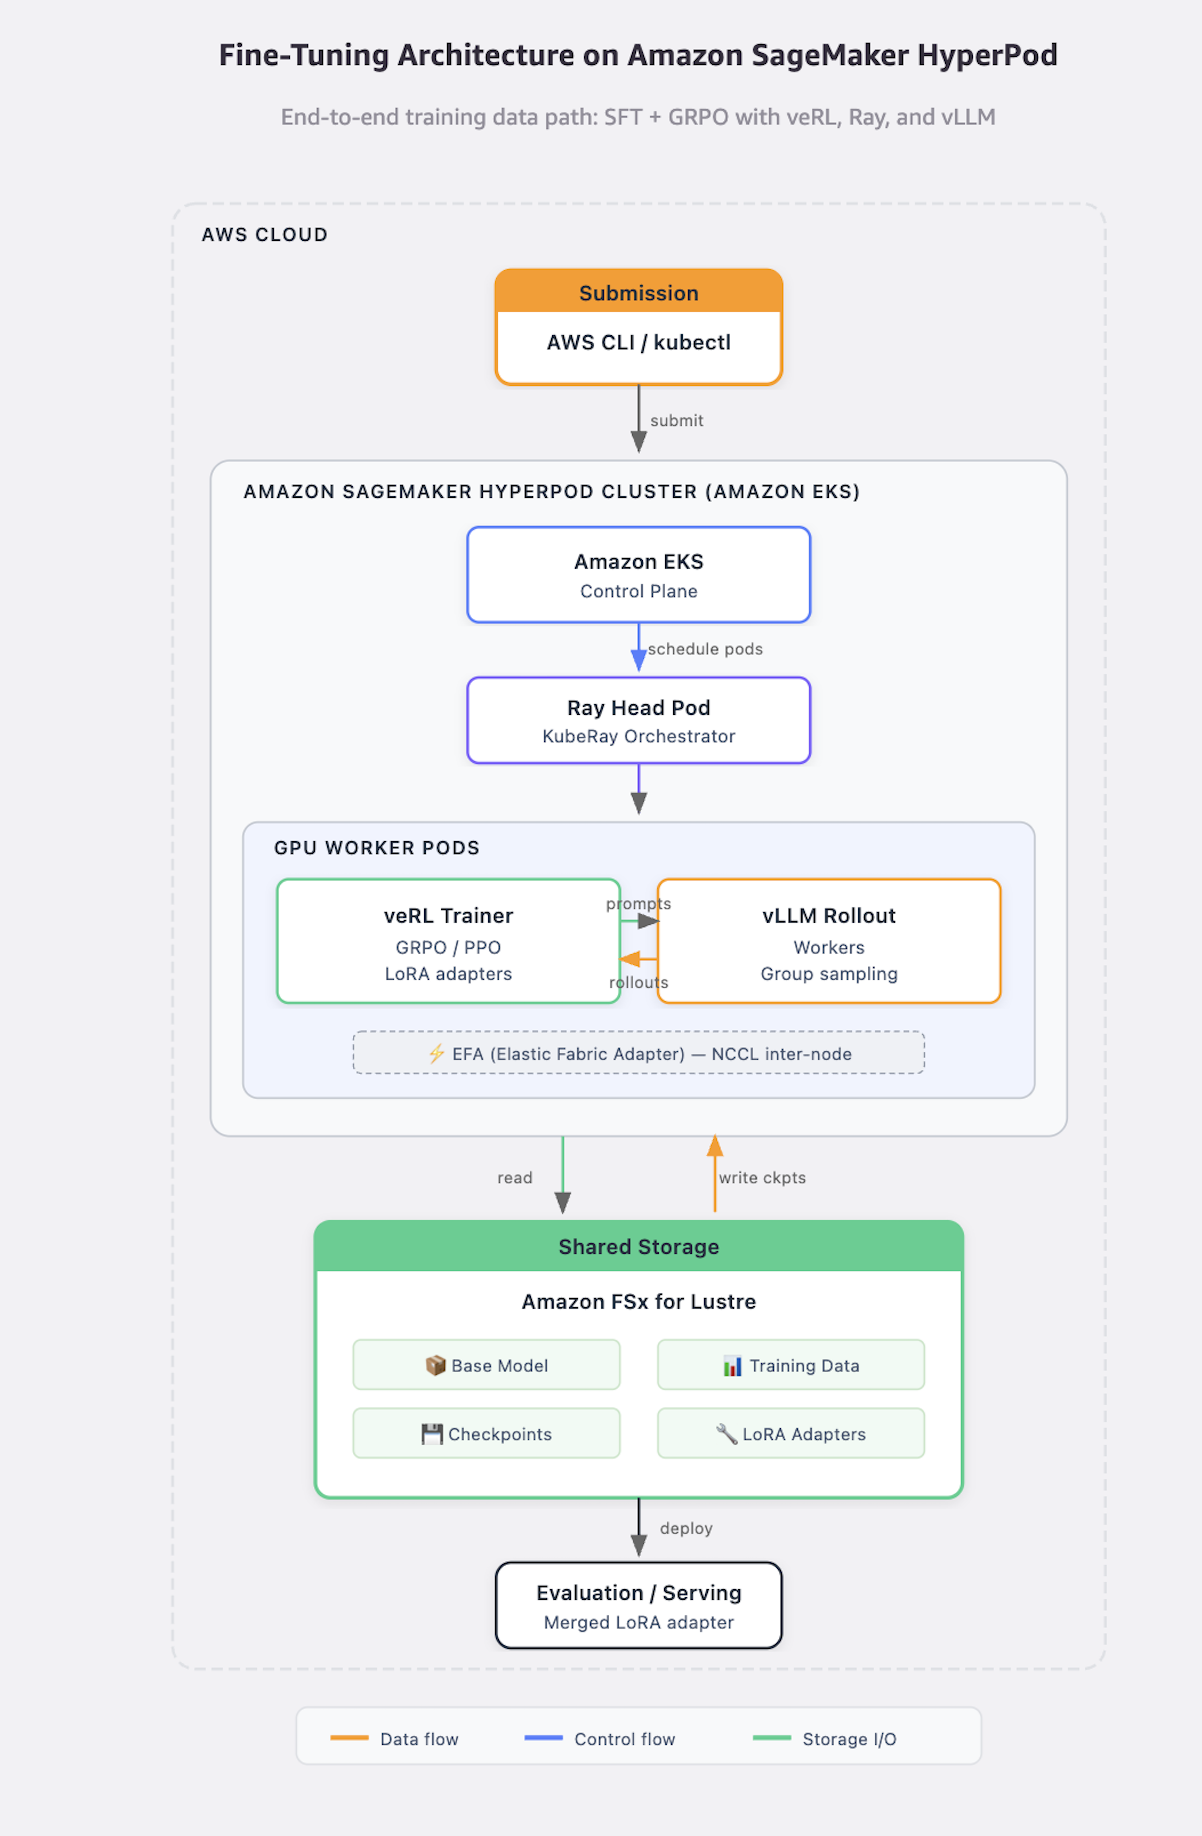
图 1:在 Amazon SageMaker HyperPod 上使用 veRL、Ray、KubeRay、vLLM 和 Amazon FSx for Lustre 进行 SFT 和 GRPO 微调的端到端训练数据路径(Qwen 对照实验)
以下更详细地描述了每个跳转阶段:提交者从 Amazon SageMaker Studio 或 AWS Command Line Interface (AWS CLI) 发起运行任务。Amazon SageMaker HyperPod 上的 Amazon EKS 控制平面将 Pod 放置在 GPU 节点上,并启动一个 Ray head 以及用于 veRL 训练器和 vLLM rollout worker 的 worker Pod。Amazon FSx for Lustre 为基础模型、训练数据和检查点提供共享、高吞吐量的存储。训练完成后,训练器将 LoRA 适配器写回 Amazon FSx for Lustre,以供下游评估或部署使用。
前置要求
若要跟随本文操作,你需要准备:
- 一个采用 Amazon EKS 编排的 Amazon SageMaker HyperPod 集群。GPT-OSS SFT 使用了 4× ml.g6e.12xlarge(16× L40S 48GB)。Qwen 对照实验使用了 2× g6e.48xlarge(16× L40S)。
- 一个挂载在集群上的 Amazon FSx for Lustre 文件系统,其
PersistentVolumeClaim命名为fsx-claim,挂载路径为/fsx。 - 启用了 EFA 的实例,以及适用于多节点 SFT 的正常运行的 NVIDIA Collective Communications Library (NCCL) 和
aws-ofi-nccl技术栈。 - 一个容器镜像仓库(如 Amazon Elastic Container Registry / Amazon ECR),用于存放基于参考仓库构建的训练镜像。
- 用于访问
openai/gpt-oss-20b和HuggingFaceH4/Multilingual-Thinking数据集的 HuggingFace Access Token。 - 工作站上安装好 AWS Command Line Interface (AWS CLI)、
kubectl、docker以及envsubst。
搭建训练环境
下文引用的所有命令、清单文件和脚本均位于 awsome-distributed-ai GitHub 仓库的 3.test_cases/pytorch/trl/gpt-oss-lora-grpo/ 路径下。克隆该仓库并进入测试用例目录:
bash git clone https://github.com/awslabs/awsome-distributed-ai cd awsome-distributed-ai/3.test_cases/pytorch/trl/gpt-oss-lora-grpo
复制环境变量模板,然后编辑 env_vars 设置你的 ECR 仓库、镜像名称、标签以及 HuggingFace Token:
bash cp env_vars.example env_vars source env_vars
构建训练镜像并推送到你的镜像仓库。该镜像打包了 PyTorch、TRL、HuggingFace Transformers、PEFT 以及训练和推理脚本:
bash cd artifacts && ./build_push.sh && cd ..
将 kubectl 指向你的集群并应用 FSx 存储管理 Pod。该存储管理器为你提供进入共享文件系统的 shell,以便进行检查点转换和评估日志检查:
bash
aws eks update-kubeconfig --name <YOUR_CLUSTER_NAME> --region us-east-2
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/fsx-storage-manager.yaml | kubectl apply -f -
使用 SFT 和 LoRA 微调 GPT-OSS-20B
我们首先评估基础模型,然后配置 SFT 运行并分析结果。
基础模型的能力差距
基础模型 GPT-OSS-20B 在 50 个用例的评估中取得了 22% 的推理语言正确率(11/50)。按语言划分:英语 100%、法语 0%、德语 10%、西班牙语 0%、意大利语 0%。无论提示词中如何指示,该模型默认都会使用英语推理。
SFT 配置
SFT 方案采用 LoRA r=8, α=16,在 4× ml.g6e.12xlarge(16× L40S 48GB)上训练 1,000 步,使用完全分片数据并行(FSDP full-shard)、bf16 精度和梯度检查点(Gradient Checkpointing)。作业作为由 Kueue 管理的弹性 HyperPodPyTorchJob 运行,通过 hyperpodrun 启动。
应用 SFT 清单:
bash
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< hyperpod-eks/train-lora-hyperpod-elastic-g6e.yaml | kubectl apply -f -
查看训练进度:
bash kubectl get pods -l app=gpt-oss-lora-elastic kubectl logs -f -l app=gpt-oss-lora-elastic
每一步都会打印 Loss 和梯度范数(gradient norm)。正常的运行日志如下所示:
text {'loss': 1.035, 'grad_norm': 0.163, 'learning_rate': 0.0002, 'mean_token_accuracy': 0.716, 'epoch': 3.25} {'loss': 1.003, 'grad_norm': 0.171, 'lr': 0.0002, 'acc': 0.722, 'epoch': 3.32} {'loss': 0.976, 'grad_norm': 0.159, 'lr': 0.0002, 'acc': 0.726, 'epoch': 3.57}
训练完成后,将 FSDP 检查点转换为 TRL 的 GRPO 训练器和推理脚本所需的参数高效微调(PEFT)格式:
bash
kubectl exec -it fsx-storage-manager -- python /app/convert_fsdp_checkpoint.py
--checkpoint /fsx/checkpoints/checkpoint-1000
--output /fsx/checkpoints/converted-peft/lora-checkpoint-1000-peft
SFT 结果与阶段性学习曲线
经过 SFT 后,模型在所有五种语言中以正确语言进行推理的比例达到了 100%(50/50)。SFT 的学习过程呈现出两个阶段:
- 在第 200 步左右,模型学会了在目标语言中进行推理(推理语言指标达到 100%)。
- 在第 1000 步左右,模型进一步学会了使用目标语言给出最终答案。
最终 SFT 评估(第 1000 步):
- 推理语言正确率:100% (50/50)。
- 回答语言正确率:62% (31/50)。
- 两项均正确率:62% (31/50)。
- 各语言回答正确率:法语 60%、德语 60%、西班牙语 30%、意大利语 60%、英语 100%。
核心结论: 在此场景下 SFT 是必不可少的。基础模型完全无法遵循推理语言指令,而 SFT 将推理语言指标从 22% 提高到了 100%。剩余的短板是仅达到 62% 的回答语言正确率。这也是较难攻关的后半部分,因为最终答案往往很简短,英语先验在此处最为顽固。
使用 GRPO 优化回答语言
回答语言显然是 GRPO 极佳的优化目标。SFT 已经能够 100% 产生正确的推理,并且模型有时能够用正确的语言给出答案,因此已经存在可供强化的信号。
基于 SFT 检查点运行 GRPO
我们从 SFT 检查点出发,使用 TRL 的 GRPOTrainer 运行 GRPO。配置细节:加载 SFT LoRA,调用 merge_and_unload,并添加一个新的 LoRA(r=8, α=16,约占可训练参数的 0.068%,20B 中占 13.6M)。训练使用每个提示采样 K=8 个生成结果,device_map=auto,学习率 1e-6,训练 10 个 Epoch。奖励函数对回答语言打分(±5.0)、对推理语言打分(±1.5),并对简洁性打分(+0.5 或 −1.0),综合奖励范围为 −7.5 到 +7.0。
从转换后的 SFT 检查点启动 GRPO:
bash
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/train-grpo-singlenode.yaml | kubectl apply -f -
kubectl logs -f grpo-single
GRPO 会将检查点写入 /fsx/checkpoints/grpo-singlenode/。根据留出评估集挑选最佳检查点(在此次运行中,回答语言指标很早就达到了峰值),并将其转换为 PEFT 格式以用于推理和评估。
结果(基于 SFT 检查点):
- 推理语言正确率:100%(保持稳定:GRPO 没有破坏 SFT 学到的能力)。
- 回答语言正确率:从 62% 提升到 70%(提升 8 个百分点,35/50)。
- 两项均正确率:70%。
- 各语言回答正确率:法语 70%、德语 80%、西班牙语 60%、意大利语 40%、英语 100%。
GRPO 在保持推理准确率为 100% 的同时,在回答语言指标上实现了实打实的 +8 个百分点提升。这一增益正是在存在提升空间的地方实现的。回答语言是 SFT 尚未完全收敛、但模型偶尔能做对的行为,GRPO 成功对其进行了强化。
基础模型、SFT 与 GRPO 推理效果并排对比
为了直观观察定性差异,可以部署三个共享同一基础模型但加载不同适配器的推理 Pod:
bash
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/inference-g6e-base.yaml | kubectl apply -f -
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/inference-g6e-trained.yaml | kubectl apply -f -
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/inference-g6e-grpo.yaml | kubectl apply -f -
针对每个变体运行相同的法语推理提示词:
bash
kubectl exec -it inference-base -- python /app/inference_g6e.py
--reasoning_language French
kubectl exec -it inference-trained -- python /app/inference_g6e.py
--checkpoint /fsx/checkpoints/converted-peft/lora-checkpoint-1000-peft
--reasoning_language French
kubectl exec -it inference-grpo -- python /app/inference_grpo_new.py
--use_grpo
--grpo_checkpoint /fsx/checkpoints/converted-peft/checkpoint-1470-peft
--reasoning_language French
尽管收到了指令,基础 Pod 依然使用英语推理。SFT Pod 使用法语推理,但通常仍用英语回答。GRPO Pod 则完全使用法语进行推理和回答。若要复现前面给出完整数字的 50 例评估,请运行评估清单并从 FSx 存储管理器中读取结果文件:
bash
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN'
< kubernetes/eval-grpo.yaml | kubectl apply -f -
kubectl logs -f eval-grpo
kubectl exec fsx-storage-manager --
cat /fsx/experiments/grpo_eval_checkpoint1470_*.txt
为了更全面地理解 GRPO 何时能够带来价值,我们在 Qwen2.5-7B 上针对具有不同能力差距的两个任务运行了对照实验。
使用 Qwen2.5-7B 对照实验验证该模式
为了在不同模型和不同任务上验证“根据能力差距匹配技术手段”这一假设,我们在 Qwen2.5-7B-Instruct 上运行了对照实验。第一个任务是相同的多语言推理任务(存在提升空间)。第二个任务是 GSM8K,在该任务上模型已处于性能顶峰。这是一个内部实验,公开仓库尚未发布。
**In
English / 原文
GPT-OSS-20B is an open-weight reasoning model that thinks in English. Ask it to reason in French, German, Spanish, or Italian and it acknowledges the instruction, then produces its chain-of-thought in English anyway. On a 50-example multilingual reasoning test, the base model reasoned in the correct target language only 22 percent of the time. That 22 percent was almost entirely the English examples (English 100 percent, French 0 percent, German 10 percent, Spanish 0 percent, Italian 0 percent).
For teams deploying reasoning models for non-English users, that gap matters. A user who asks a question in French expects the model to reason and answer in French, not to switch to English mid-thought. Closing that gap is a fine-tuning problem. It raises a question every team faces once they start customizing open-weight models: supervised fine-tuning (SFT), reinforcement learning with Group Relative Policy Optimization (GRPO), or both?
In this post, we walk through how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod. We show when SFT alone was sufficient and when GRPO added measurable value on top. To understand more broadly when GRPO helps, we also ran a controlled Qwen2.5-7B experiment across two tasks with different capability gaps. The short answer: SFT does most of the work, GRPO refines when there is headroom to refine, and matching the technique to the capability gap is what decides the outcome.
Solution overview
This section covers the multilingual reasoning task and dataset, how SFT and GRPO complement each other, and the training stack we ran on Amazon SageMaker HyperPod.
The task and dataset
The dataset is HuggingFaceH4/Multilingual-Thinking — a chain-of-thought reasoning dataset translated into French, Spanish, German, and Italian alongside English, roughly 949 training and 50 validation examples. The model receives a reasoning language: system-prompt instruction and must both reason and answer in that target language, overriding its strong English prior. The evaluation is 50 test cases: 10 math/logic problems across 5 languages (EN/FR/DE/ES/IT).
Two metrics matter:
- Reasoning-language correct – is the chain-of-thought in the requested language?
- Answer-language correct – is the final answer in the requested language?
How SFT and GRPO fit together
The clearest way to think about the two techniques: SFT teaches a behavior the model doesn’t have. GRPO optimizes a behavior the model can already sometimes produce. GRPO works by sampling a group of responses per prompt and pushing the policy toward the above-average ones. If the desired behavior has zero probability in the base distribution, there is very little for GRPO to reinforce. That single idea explains almost every result in this post.
The training stack
We ran on Amazon SageMaker HyperPod with Amazon Elastic Kubernetes Service (Amazon EKS) orchestration. For the initial SFT and GRPO runs on GPT-OSS-20B, we used the PyTorch TRL library. For the Qwen control experiment, we switched to veRL as the trainer, with Ray and KubeRay for distributed orchestration and vLLM for fast rollout generation. Checkpoints and datasets lived on Amazon FSx for Lustre, and the inter-node fabric used Elastic Fabric Adapter (EFA). All fine-tuning used Low-Rank Adaptation (LoRA), which is parameter-efficient and well-suited to both SFT and GRPO.
The following diagram shows the training data path end-to-end. A submission from the user lands on the Amazon EKS control plane of the Amazon SageMaker HyperPod cluster. Amazon EKS schedules a Ray head pod plus worker pods that run the veRL trainer and vLLM rollout workers. Both sets of pods mount Amazon FSx for Lustre for the base model, training data, and checkpoints. Inter-node collectives use EFA. Rollouts stream from vLLM back to the veRL trainer, and the trainer writes checkpoints back to Amazon FSx for Lustre.
Figure 1: End-to-end training data path for SFT and GRPO fine-tuning on Amazon SageMaker HyperPod with veRL, Ray, KubeRay, vLLM, and Amazon FSx for Lustre for Qwen control experiments
The following describes each hop in more detail. The submitter starts the run from Amazon SageMaker Studio or the AWS Command Line Interface (AWS CLI). The Amazon EKS control plane on Amazon SageMaker HyperPod places pods on GPU nodes and starts a Ray head with worker pods for the veRL trainer and the vLLM rollout workers. Amazon FSx for Lustre provides shared, high-throughput storage for the base model, the training data, and the checkpoints. When training completes, the trainer writes the LoRA adapter back to Amazon FSx for Lustre for downstream evaluation or serving.
Prerequisites
To follow along, you need:
- An Amazon SageMaker HyperPod cluster with Amazon EKS orchestration. GPT-OSS SFT used 4× ml.g6e.12xlarge (16× L40S 48GB). The Qwen control used 2× g6e.48xlarge (16× L40S).
- An Amazon FSx for Lustre file system mounted on the cluster with a
PersistentVolumeClaimnamedfsx-claimat/fsx. - EFA-enabled instances and a working NVIDIA Collective Communications Library (NCCL) and
aws-ofi-ncclstack for multi-node SFT. - A container registry such as Amazon Elastic Container Registry (Amazon ECR) to hold the training image built from the reference repository.
- A HuggingFace access token for
openai/gpt-oss-20band theHuggingFaceH4/Multilingual-Thinkingdataset. - The AWS Command Line Interface (AWS CLI),
kubectl,docker, andenvsubstavailable on your workstation.
Set up the training environment
All of the commands, manifests, and scripts referenced below live in the awsome-distributed-ai GitHub repository under 3.test_cases/pytorch/trl/gpt-oss-lora-grpo/. Clone the repository and change into the test case directory:
git clone https://github.com/awslabs/awsome-distributed-ai
cd awsome-distributed-ai/3.test_cases/pytorch/trl/gpt-oss-lora-grpo
Copy the environment template, then edit env_vars to set your ECR registry, image name, tag, and HuggingFace token:
cp env_vars.example env_vars
source env_vars
Build the training image and push it to your registry. The image bundles PyTorch, TRL, HuggingFace Transformers, PEFT, and the training and inference scripts:
cd artifacts && ./build_push.sh && cd ..
Point kubectl at your cluster and apply the FSx storage manager pod. The storage manager gives you a shell into the shared file system for checkpoint conversion and eval-log inspection:
aws eks update-kubeconfig --name <YOUR_CLUSTER_NAME> --region us-east-2
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/fsx-storage-manager.yaml | kubectl apply -f -
Fine-tune GPT-OSS-20B with SFT and LoRA
We begin by measuring the base model, then configure the SFT run and examine the results.
The base-model gap
Base GPT-OSS-20B on the 50-case eval scored 22 percent reasoning-language correct (11/50). Per-language: English 100 percent, French 0 percent, German 10 percent, Spanish 0 percent, Italian 0 percent. The model defaults to English reasoning regardless of the instruction.
SFT configuration
The SFT setup used LoRA r=8, α=16, trained for 1,000 steps on 4× ml.g6e.12xlarge (16× L40S 48GB) with Fully Sharded Data Parallel (FSDP) full-shard, bf16 precision, and gradient checkpointing. The job runs as an elastic HyperPodPyTorchJob managed by Kueue, launched with hyperpodrun.
Apply the SFT manifest:
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < hyperpod-eks/train-lora-hyperpod-elastic-g6e.yaml | kubectl apply -f -
Watch training progress:
kubectl get pods -l app=gpt-oss-lora-elastic
kubectl logs -f -l app=gpt-oss-lora-elastic
Loss and gradient norm print each step. A healthy run looks like this:
{'loss': 1.035, 'grad_norm': 0.163, 'learning_rate': 0.0002, 'mean_token_accuracy': 0.716, 'epoch': 3.25}
{'loss': 1.003, 'grad_norm': 0.171, 'lr': 0.0002, 'acc': 0.722, 'epoch': 3.32}
{'loss': 0.976, 'grad_norm': 0.159, 'lr': 0.0002, 'acc': 0.726, 'epoch': 3.57}
When training completes, convert the FSDP checkpoint to the Parameter-Efficient Fine-Tuning (PEFT) format that TRL’s GRPO trainer and the inference scripts expect:
kubectl exec -it fsx-storage-manager -- python /app/convert_fsdp_checkpoint.py \
  --checkpoint /fsx/checkpoints/checkpoint-1000 \
  --output    /fsx/checkpoints/converted-peft/lora-checkpoint-1000-peft
SFT results and the staged learning curve
After SFT, the model reasons in the correct language 100 percent of the time (50/50) across all five languages. SFT learned this in two stages:
- Around step 200, the model learned to reason in the target language (reasoning-language metric hits 100 percent).
- Around step 1000, the model additionally learned to give the answer in the target language.
Final SFT eval (step 1000):
- Reasoning-language correct: 100 percent (50/50).
- Answer-language correct: 62 percent (31/50).
- Both correct: 62 percent (31/50).
- Per-language answer accuracy: FR 60 percent, DE 60 percent, ES 30 percent, IT 60 percent, EN 100 percent.
Takeaway: SFT is not optional here. The base model can’t follow the reasoning-language instruction at all, and SFT takes reasoning-language from 22 percent to 100 percent. The remaining gap is answer-language at 62 percent. That’s the harder half, because the final answer is short and the English prior is strongest there.
Refine answer-language with GRPO
Answer-language was the obvious target for GRPO. SFT already produced correct reasoning 100 percent of the time, and the model sometimes produced the answer in the right language, so there was a signal to reinforce.
Run GRPO on top of the SFT checkpoint
We ran GRPO with TRL’s GRPOTrainer, starting from the SFT checkpoint. The setup: load the SFT LoRA, call merge_and_unload, and add a new LoRA (r=8, α=16, about 0.068 percent trainable parameters, 13.6M of 20B). Training used K=8 generations per prompt, device_map=auto, learning rate 1e-6, and 10 epochs. The reward function scored answer-language (±5.0), reasoning-language (±1.5), and brevity (+0.5 or −1.0), for a combined range of −7.5 to +7.0.
Launch GRPO from the converted SFT checkpoint:
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/train-grpo-singlenode.yaml | kubectl apply -f -
kubectl logs -f grpo-single
GRPO writes checkpoints to /fsx/checkpoints/grpo-singlenode/. Pick the best checkpoint against your held-out eval (the answer-language metric peaked early in this run) and convert it to PEFT format for inference and evaluation.
Result (from the SFT checkpoint):
- Reasoning-language correct: 100 percent (held: GRPO didn’t break what SFT taught).
- Answer-language correct: 62 to 70 percent (+8 points, 35/50).
- Both correct: 70 percent.
- Per-language answer: FR 70 percent, DE 80 percent, ES 60 percent, IT 40 percent, EN 100 percent.
GRPO delivered a real +8 point gain on the answer-language metric while holding reasoning at 100 percent. The gain came where there was headroom to gain. Answer-language was the sometimes-correct behavior that SFT had not fully converged on, and GRPO reinforced it.
Compare base, SFT, and GRPO inference side by side
To see the qualitative difference, deploy three inference pods that share the same base model but load different adapters:
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/inference-g6e-base.yaml    | kubectl apply -f -
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/inference-g6e-trained.yaml | kubectl apply -f -
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/inference-g6e-grpo.yaml    | kubectl apply -f -
Run the same French-reasoning prompt through each variant:
kubectl exec -it inference-base    -- python /app/inference_g6e.py \
  --reasoning_language French

kubectl exec -it inference-trained -- python /app/inference_g6e.py \
  --checkpoint /fsx/checkpoints/converted-peft/lora-checkpoint-1000-peft \
  --reasoning_language French

kubectl exec -it inference-grpo    -- python /app/inference_grpo_new.py \
  --use_grpo \
  --grpo_checkpoint /fsx/checkpoints/converted-peft/checkpoint-1470-peft \
  --reasoning_language French
The base pod reasons in English despite the instruction. The SFT pod reasons in French but often answers in English. The GRPO pod reasons and answers in French. To reproduce the full 50-case eval that generated the numbers earlier, run the evaluation manifest and read the result file from the FSx storage manager:
envsubst '$REGISTRY $IMAGE $TAG $HF_TOKEN' \
  < kubernetes/eval-grpo.yaml | kubectl apply -f -
kubectl logs -f eval-grpo
kubectl exec fsx-storage-manager -- \
  cat /fsx/experiments/grpo_eval_checkpoint1470_*.txt
To understand more broadly when GRPO adds value, we ran a controlled experiment on Qwen2.5-7B across two tasks with different capability gaps.
Test the pattern with a Qwen2.5-7B control
To test the “match technique to capability gap” thesis on a different model and different tasks, we ran controlled experiments on Qwen2.5-7B-Instruct. The first task is the same multilingual reasoning task (where headroom exists). The second task is GSM8K, where the model is already at peak accuracy. This is an internal experiment, and the public repo has not yet been released.
Infrastructure: 2× g6e.48xlarge (16× L40S), EFA 100Gbps, FSx Lustre, Ray 2.44 + KubeRay 1.4.2, veRL v0.6.1, vLLM 0.8.4.
Arms: A = base, B = SFT-only, C = SFT+GRPO.
Multilingual reasoning (50 cases)
| Metric | A base | B SFT | C SFT+GRPO | Δ GRPO |
|---|---|---|---|---|
| Structured format | 0% | 92% | 98% | +6 |
| Reasoning language | 0% | 96% | 98% | +2 |
| Answer language | 0% | 38% | 44% | +6 |
| Both correct | 0% | 38% | 44% | +6 |
GSM8K, a task with no headroom
On GSM8K, base Qwen2.5-7B already scores 90.5 percent (181/200). GRPO at step 30 also scores 90.5 percent. When most sampled groups are all-correct, the group-relative advantage collapses to zero, so there is no learning signal. This is the other half of the thesis: GRPO needs headroom (pass@k >> pass@1) to have anything to optimize. No headroom means no gain.
Best practices
- Start with SFT. GRPO cannot teach a behavior with zero base probability. It can only reinforce responses the model already sometimes produces. SFT took reasoning-language from 22 percent to 100 percent, and every GRPO win in this work was built on that SFT checkpoint.
- Use LoRA for both SFT and GRPO. LoRA r=8/α=16 was parameter-efficient (0.068 percent trainable), and on the Qwen control it stayed numerically stable through GRPO (grad norm 0.23, about 11.7 GB per GPU). It’s a strong default when you want SFT and GRPO to share the same adapter shape.
- Match the technique to the gap. Use SFT for missing behavior. Use GRPO for refining an existing, sometimes-correct behavior. GRPO’s realistic ceiling here was +6 to +8 points.
- Check for reward headroom before spending GPU-hours. If most groups are all-correct (GSM8K 90.5 percent base), the group-relative advantage collapses to zero and GRPO gets no gradient. Verify there is headroom (pass@k >> pass@1) before starting a GRPO run.
Clean up resources
To avoid ongoing charges, delete the workload resources and then the underlying infrastructure:
-
Delete the training and inference pods and jobs:
kubectl delete hyperpodpytorchjob lora-hyperpod-elastic --ignore-not-found kubectl delete pod grpo-single inference-base inference-trained inference-grpo \ eval-grpo fsx-storage-manager --ignore-not-found -
Scale down or delete the Amazon SageMaker HyperPod cluster or its node groups.
-
Delete the Amazon FSx for Lustre file system once you have exported any checkpoints you want to keep.
-
Delete any Amazon Simple Storage Service (Amazon S3) buckets or objects used for training data or checkpoint archives.
Conclusion
We showed how to fine-tune GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between SFT and GRPO. SFT did most of the work: reasoning-language went from 22 percent to 100 percent. GRPO added a real, modest refinement on top (answer 62 percent to 70 percent) where headroom existed. A parallel Qwen2.5-7B control confirmed the pattern. GRPO added +6 percent on multilingual reasoning, where there was room to improve. It added no gain on GSM8K, where the model was already at peak accuracy (90.5 percent).
Decision framework:
- Behavior the model can’t do at all: use SFT.
- Behavior it does sometimes, with headroom: use SFT then GRPO for a few points more.
- Model already at peak accuracy, or target has zero base probability: GRPO won’t help.
To try this yourself, walk through the test cases in the awsome-distributed-ai repository. For more on Amazon SageMaker HyperPod, see the service detail page and the Amazon SageMaker HyperPod documentation. For a walkthrough of Ray on Amazon SageMaker HyperPod, see the related post Running distributed training on Amazon SageMaker HyperPod with Ray and Amazon SageMaker Studio. The link will be added after that post is published. Share your results in the comments.
About the authors
Mijanur Palash
Mijanur is a Specialist Solutions Architect on the AI/ML Infrastructure team at AWS. He focuses on distributed training and reinforcement learning workloads on Amazon SageMaker HyperPod for automotive, pharmaceutical, and generative AI customers. Outside of work, Palash enjoys hiking and photography.
Mark Vinciguerra
Mark was a Worldwide Specialist Solutions Architect for Generative AI at AWS, focused on distributed training and inference on Amazon SageMaker HyperPod. He works with strategic customers on large-scale foundation-model workloads across EKS and Slurm orchestration and contributes reference architectures and workshops for HyperPod, Ray, and SageMaker Unified Studio.