构建 Agent:何时应将子 Agent 整合进主 Agent 循环
英文标题:ArticleOct 22, 2026Building agents: When to fold subagents into your main agent loop When building agents in Claude Platform, using fewer subagents in favor of progressively disclosed context and tools can improve quality while reducing cost and latency. Here’s when and how to migrate.Claude Platform
Anthropic Applied AI 团队发现,在企业级 Agent 部署中,将路由、规划和领域子 Agent 整合进主 Agent 循环,配合渐进式披露技能与工具,能显著优于多 Agent 架构,运行耗时甚至可缩短约 2 倍并降低成本。随着模型推理与自主反思能力跃升,过度拆分子 Agent 反而容易造成上下文丢失、组织康威定律式膨胀及高延迟。该指南为开发者提供了系统化迁移路径,建议通过共享上下文、将子 Agent 降级为工具或技能,并由小规模核心团队统筹评估体系与 System Prompt,实现更高效、敏捷的 Agent 开发。
 819.6 KB
 99.8 KB
 505.9 KB
 42.6 KB
中文
如果您已经在 Claude Platform 中构建了包含多个子 Agent(Subagents)的系统,可以通过我们的迁移工具包(migration kit)评估哪些子 Agent 适合整合进主 Agent 循环。该工具包提供引导式工作流,用于识别架构模式、评估替代方案并验证最佳实现路径;其中还包含演示 Demo,方便您在实际应用前先在模拟系统上进行测试。
子 Agent(Subagent)——即拥有独立上下文窗口、工具与指令,并由协调器(Coordinator)统一调度的 Agent——向来是 Agent 架构设计的核心组件。它们在结果验证、并行工作以及模块化权限控制方面非常有效。在我们使用 Claude Platform 构建的诸多内部 Agent 中,也大量使用了子 Agent,例如我们的多 Agent 研究系统。
然而,Applied AI 团队近期在多个企业级 Agent 部署中发现了一种新趋势:将路由器(Router)、规划器(Planner)以及各领域的子 Agent 整合回收至主 Agent 循环中,往往能带来显著收益。在我们针对多个企业部署的对比测试中,配备技能(Skills)的单 Agent 架构在质量上频繁击败了“单一 Prompt 包揽一切”和“子 Agent 协作”两种设计,并且通常单任务成本更低、延迟更少。
例如,一家企业发现其面向客户的 Agent 内部集成了十几个专业子 Agent,这导致一致的品牌体验难以维持,同时叠加的高延迟也极大地伤害了用户体验。
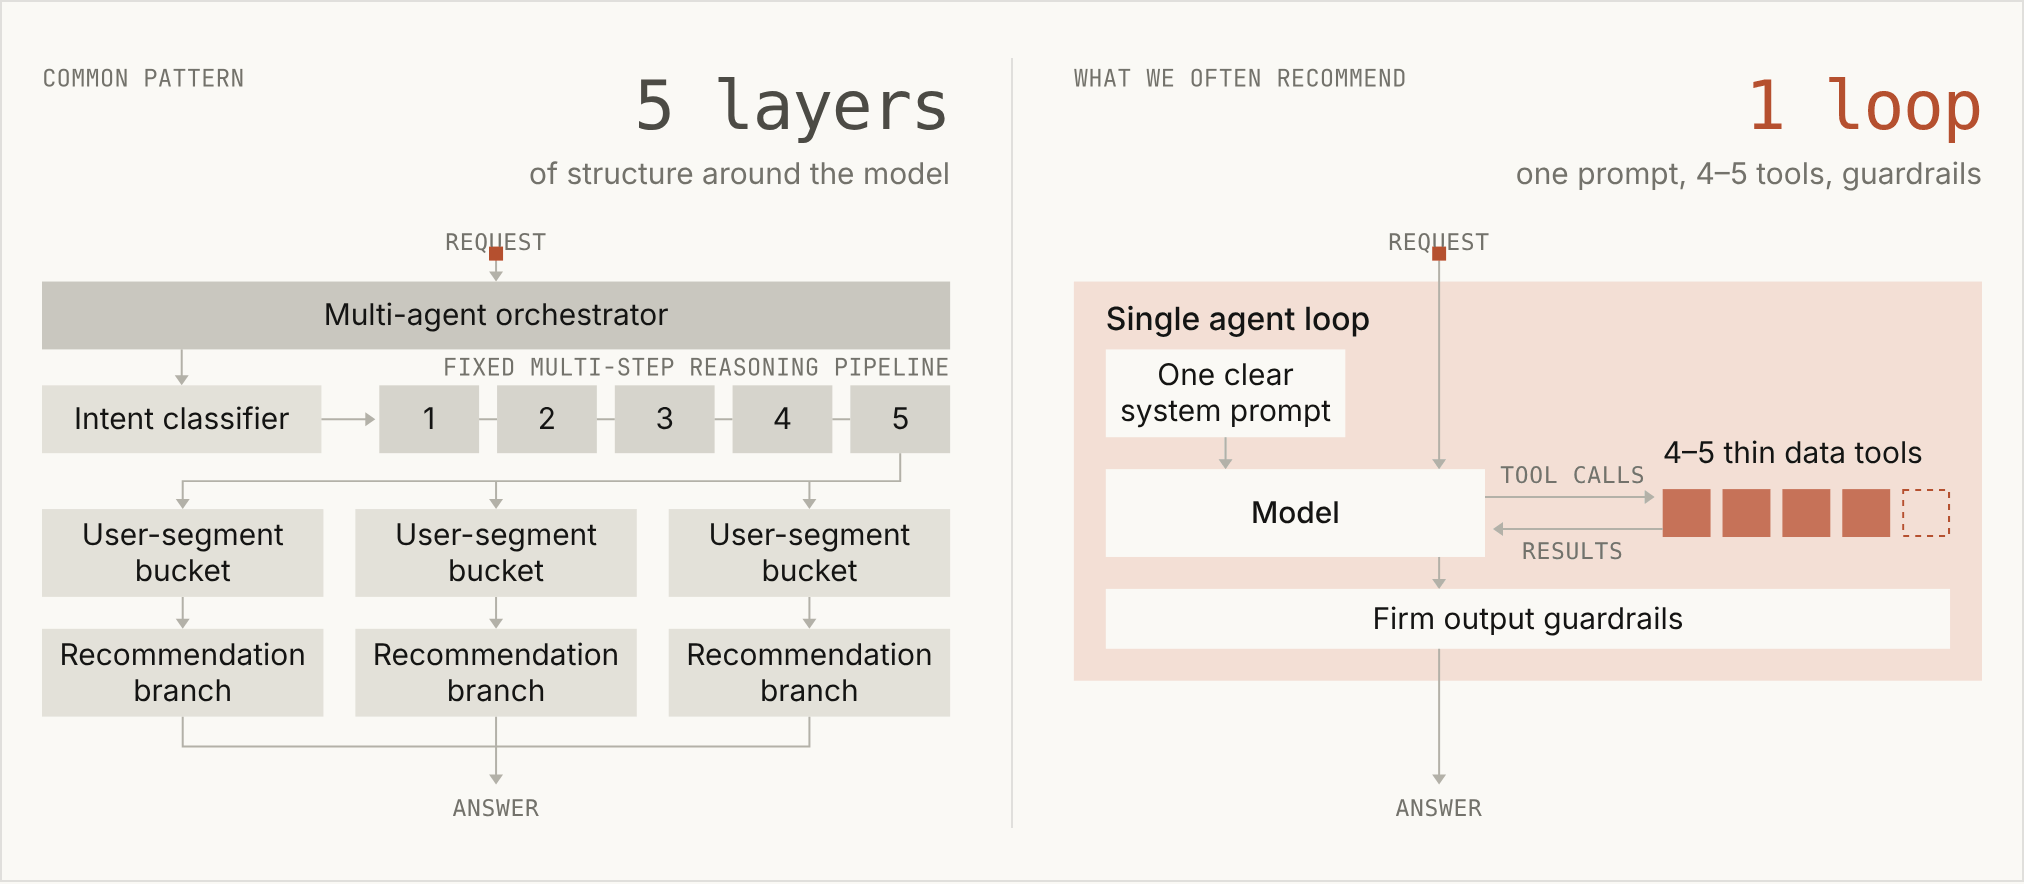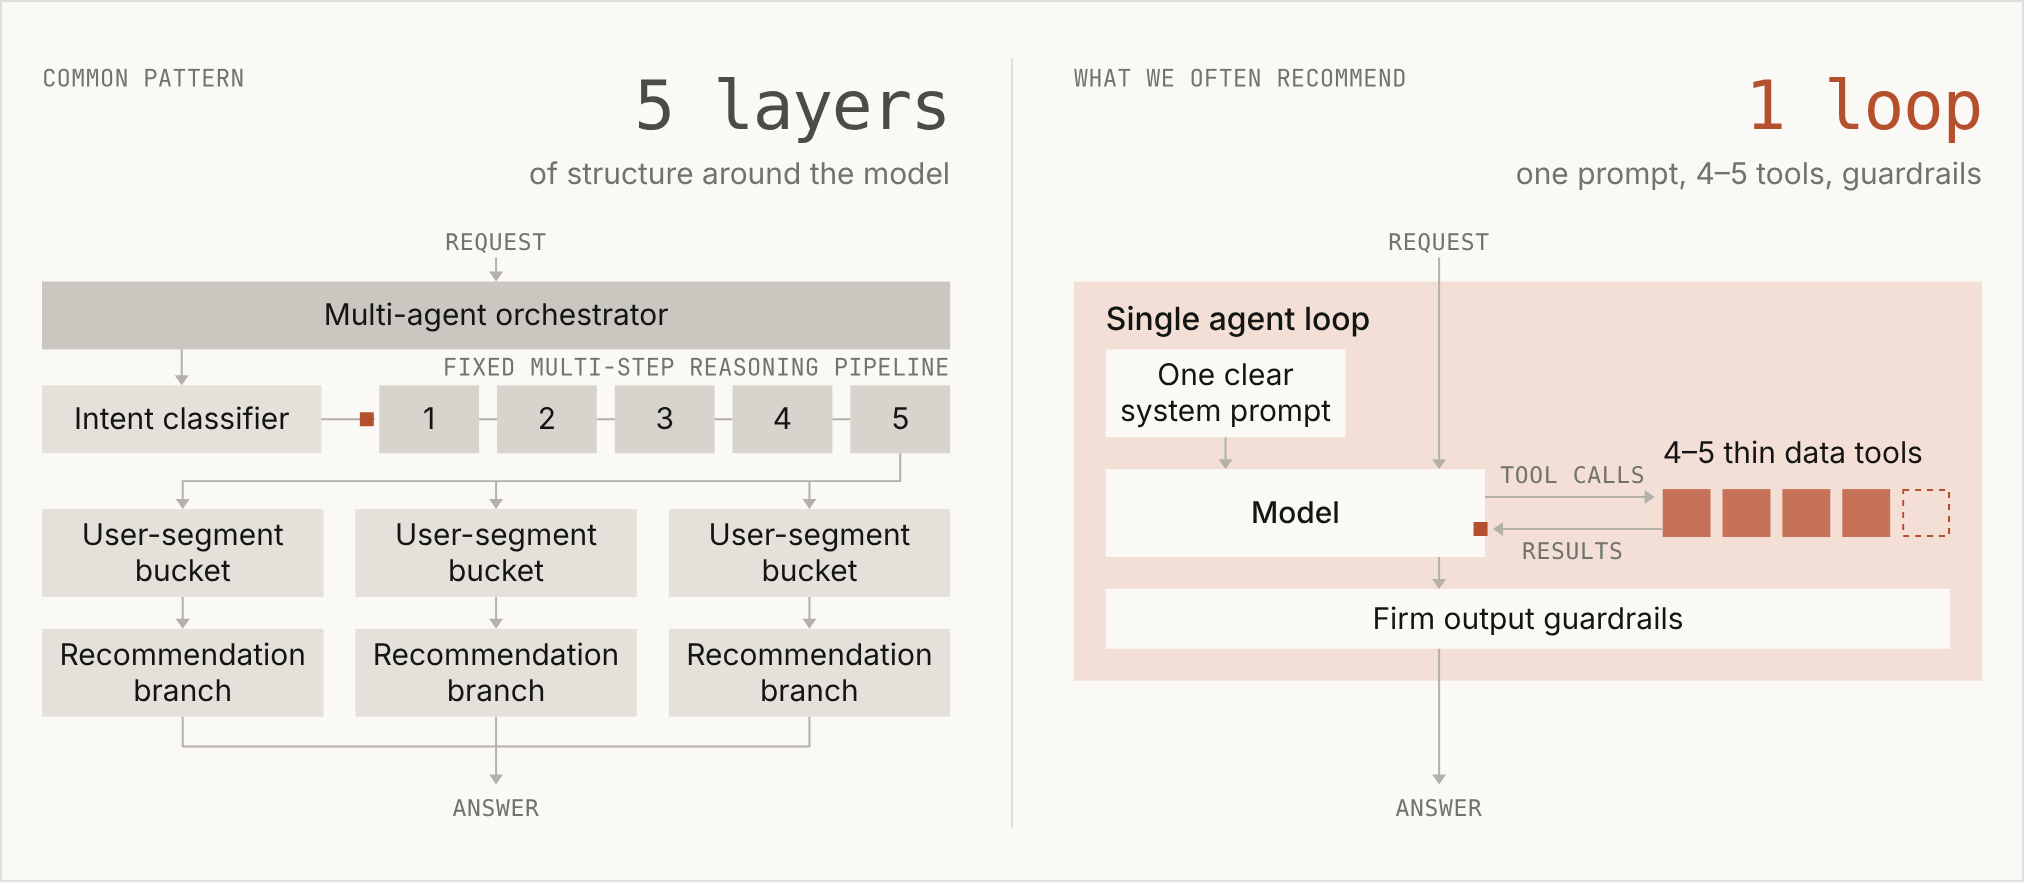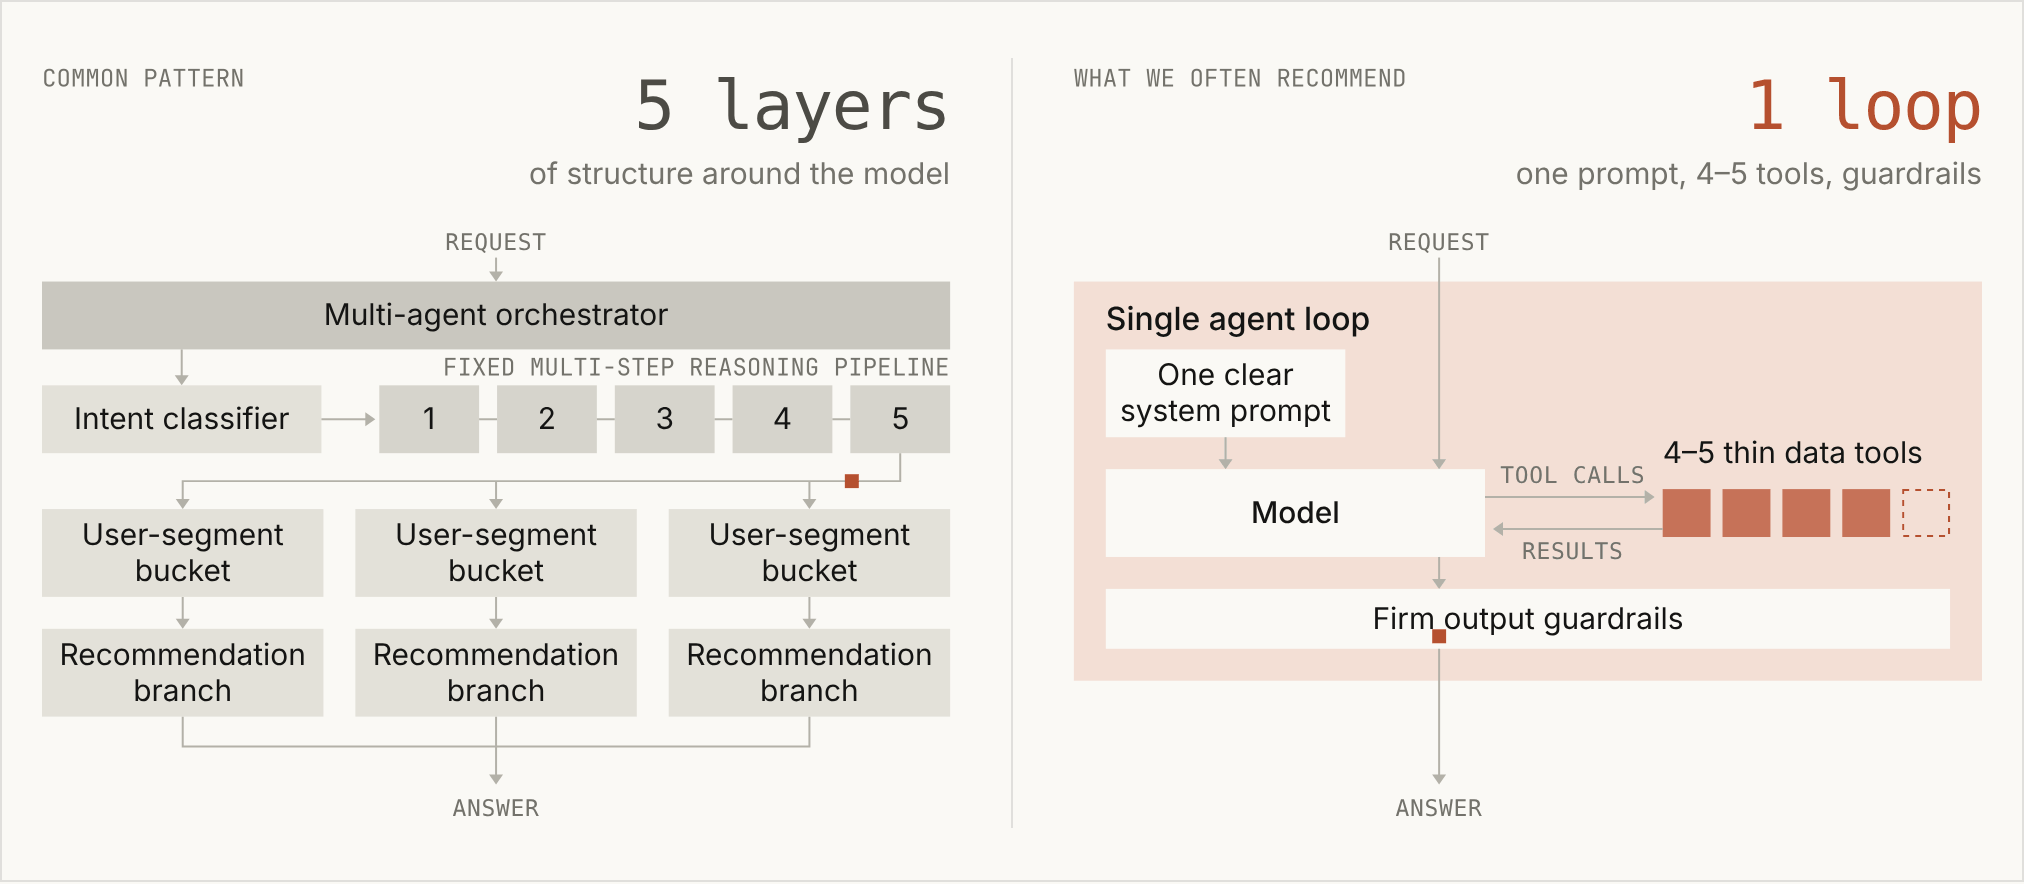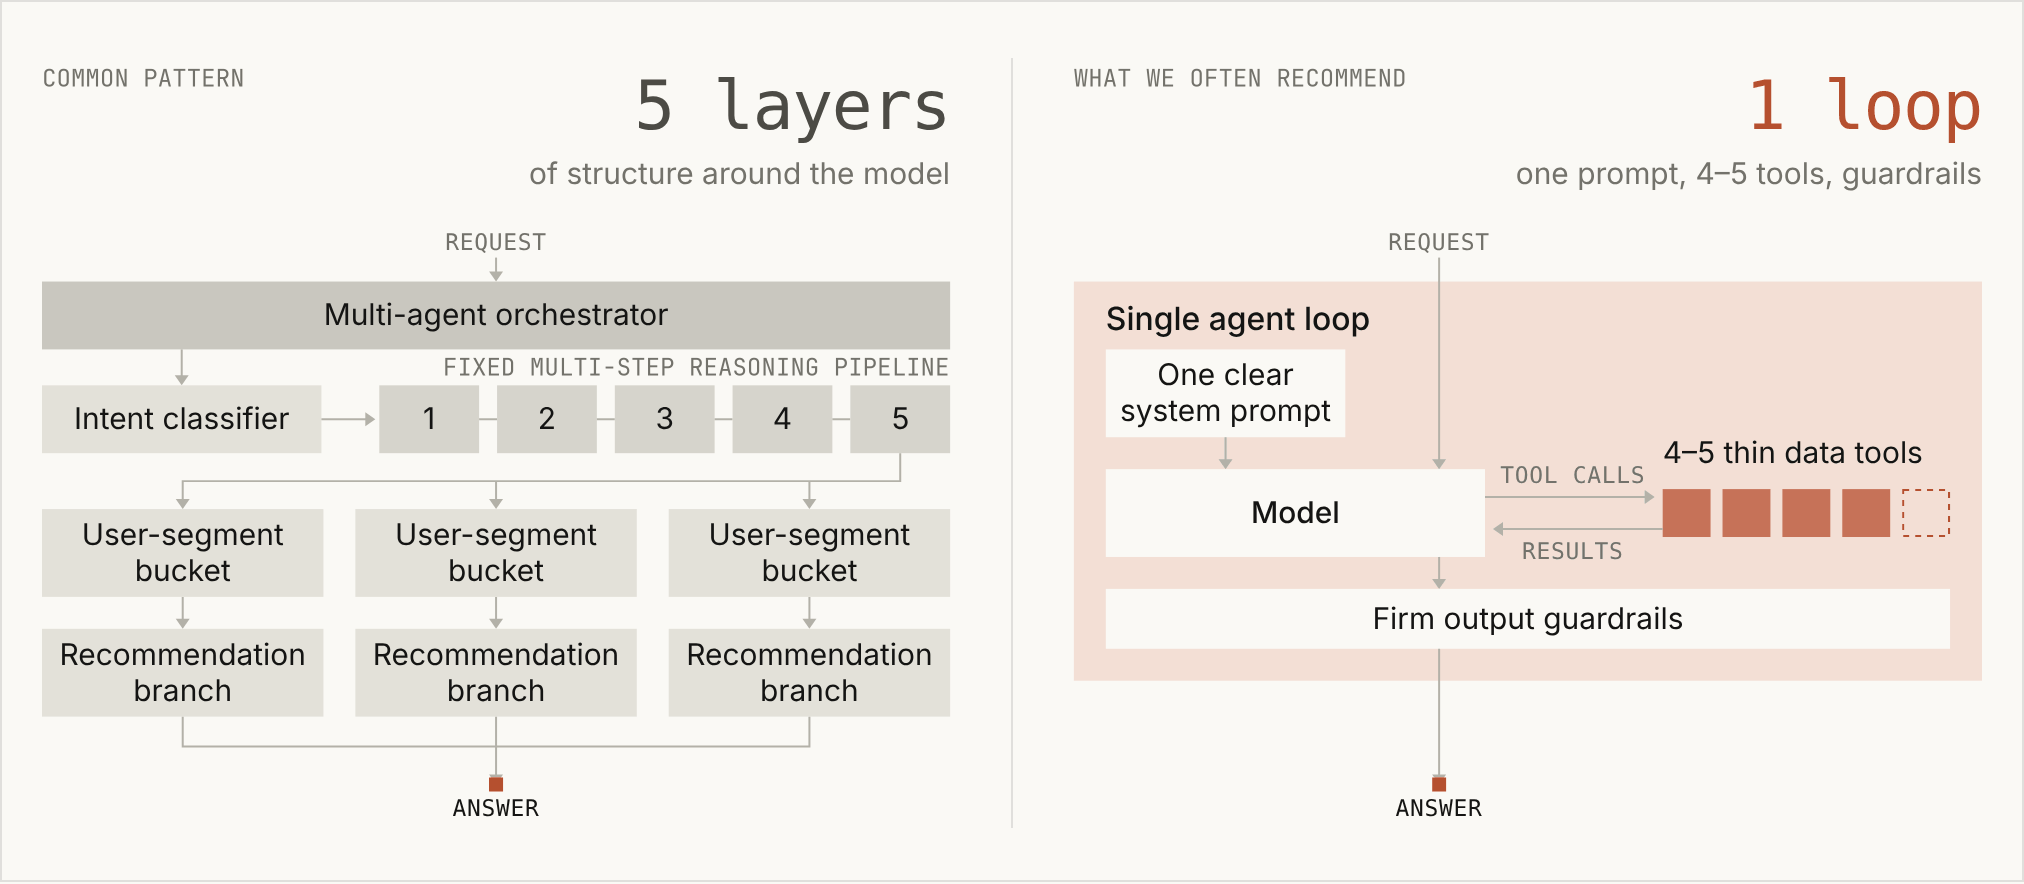
我们还经常看到业内提交的 Agent 设计遵循着一条熟悉的路径:意图分类器、固定的多步推理流水线、用户分群桶、独立的分支推荐逻辑,再加上顶层的多 Agent 编排器。
针对这类系统,实际反馈往往表明:大部分结构所承担的工作,模型本身已经不再需要外部辅助完成;通常只需一个清晰的 System Prompt、4-5 个轻量数据工具以及坚固的输出护栏(Guardrails),便足以覆盖绝大多数业务场景。
需要明确的是,子 Agent 依然有其存在价值,在前沿研究领域更是如此。在以下场景中请继续使用它们:
- 单 Agent 循环因上下文膨胀而出现可量化的性能下降;或
- 需要并行处理多个任务,且每个任务需要干净的上下文窗口,任务完成后即可丢弃;或
- 单 Agent 在选择合适工具时表现挣扎,或 System Prompt 中存在相互冲突的指令。
但我们太常看到企业为每个团队或每种问题类型都分配一个子 Agent,导致 Agent 架构直接退化为其组织架构的翻版(康威定律的典型体现)。
本文结合我们在大型组织中构建 Agent 所沉淀的最佳实践,深入阐述何时应当考虑将子 Agent 整合回主 Agent 循环中。
大型组织构建 Agent 的常见失效模式
企业通常希望构建一个将多种产品与能力整合为单一客户交互界面的 Agent。
由于不同能力往往归属于不同团队,企业通常的做法是让每个团队先构建自己的独立 Agent,随后由中心平台团队在顶层搭建编排器。这会演化出编排器-子 Agent(Orchestrator-Subagent)模式,或是将特定 Agent 作为 MCP 工具暴露给主 Agent 的单 Agent 结构。
这表面上看起来是最简单的方案,但会迅速引入一系列复杂性:
- 上下文管理(Context management):必须决定 Agent 之间传递哪些上下文,而且反复交接往往会导致细节丢失。
- 子 Agent 蔓延(Subagent sprawl):每个团队都发布自己的子 Agent,导致企业内部充斥着数百个缺乏统一标准、权责不清且高度重叠的子 Agent。
- 拼装怪物式 Prompt(The Frankenprompt):每个团队都在 System Prompt 里硬塞一句规则,最终导致规则冲突、人设与表达风格支离破碎。
- 未经审核且过度局部化的评估体系(Unvetted, overly localized evals):每个团队都加入仅针对自身子任务过度优化的 Eval,无人为整套 Eval 的全局效果负责与维护,管理层只能依据被稀释、过度局部化的指标做出错误决策。
- 高延迟(Latency):多 Agent 架构的复杂性不可避免地增加了延迟。一家客户将其多 Agent 框架与单 Agent 循环进行对比评测,发现后者的运行速度大约快了 2 倍。
采用渐进式披露的 Agent 循环
上述编排器-子 Agent 架构虽然是协调各团队专家模块的合理尝试,但通常更高效的做法是通过技能渐进式披露上下文(Progressive disclosure of context via skills),以及通过工具检索渐进式披露工具(Progressive disclosure of tools via tool search)。换句话说,Agent 初始只会看到技能与工具的简短描述,只有在需要调用时才会将它们完全载入。
采用这种方案有三大关键理由:
- 共享上下文产出更高质量的答案:对于运行周期较长的 Agent,我们希望不同任务的上下文都驻留在主上下文窗口中。见证过每个前期步骤结果的 Agent 能够将信息串联起来,相比子 Agent 传回的一组摘要,能产出更丰富、更有洞见的成果。这也意味着更少的上下文窗口与更少的信息损耗交接。
- 渐进式披露可防止上下文膨胀:该技术允许团队构建能完成多样化复杂任务的单 Agent,而无需在初始阶段把所有上下文全盘塞进冗长的主 System Prompt 中。这消除了团队此前将工作拆分到各子 Agent 的主要动因。事实上,我们在面向高阶模型优化时,将 Claude Code 的 System Prompt 缩减了超过 80%,其中很大部分削减正是得益于技能与工具的渐进式披露。
- 模型本身能力大幅提升:从 Opus 4.5 开始,模型在单循环中能处理的复杂度远超大多数团队的预期。在 Opus 5.5 和 Fable 5.1 上,思考过程(Thinking)已无法关闭,近期模型愈发擅长在执行中实时阐述进度并自检工作,这让外围框架中的不少协调逻辑变得多余。每一个新模型推出,都能让你把更多决策权从外层框架移交到模型内部。更简化的循环也更利于向下一代模型迁移;在我们协助客户进行的迁移中,阻碍新模型充分施展能力的恰恰是那些僵化的多 Agent 架构。
单 Agent 循环设计需要工程纪律:精心管理的 System Prompt、在恰当时机触发的技能与工具描述,以及对上下文窗口、记忆与笔记机制的审慎把控。本文后续章节将深入讨论迁移与设计细节。
建议由一个中心团队统一负责端到端质量与主 System Prompt,对上线前的每个新工具与 Eval 进行严格把关。保持该中心团队小而精,有助于提升迭代速度并降低大型组织内部的协作协调成本。
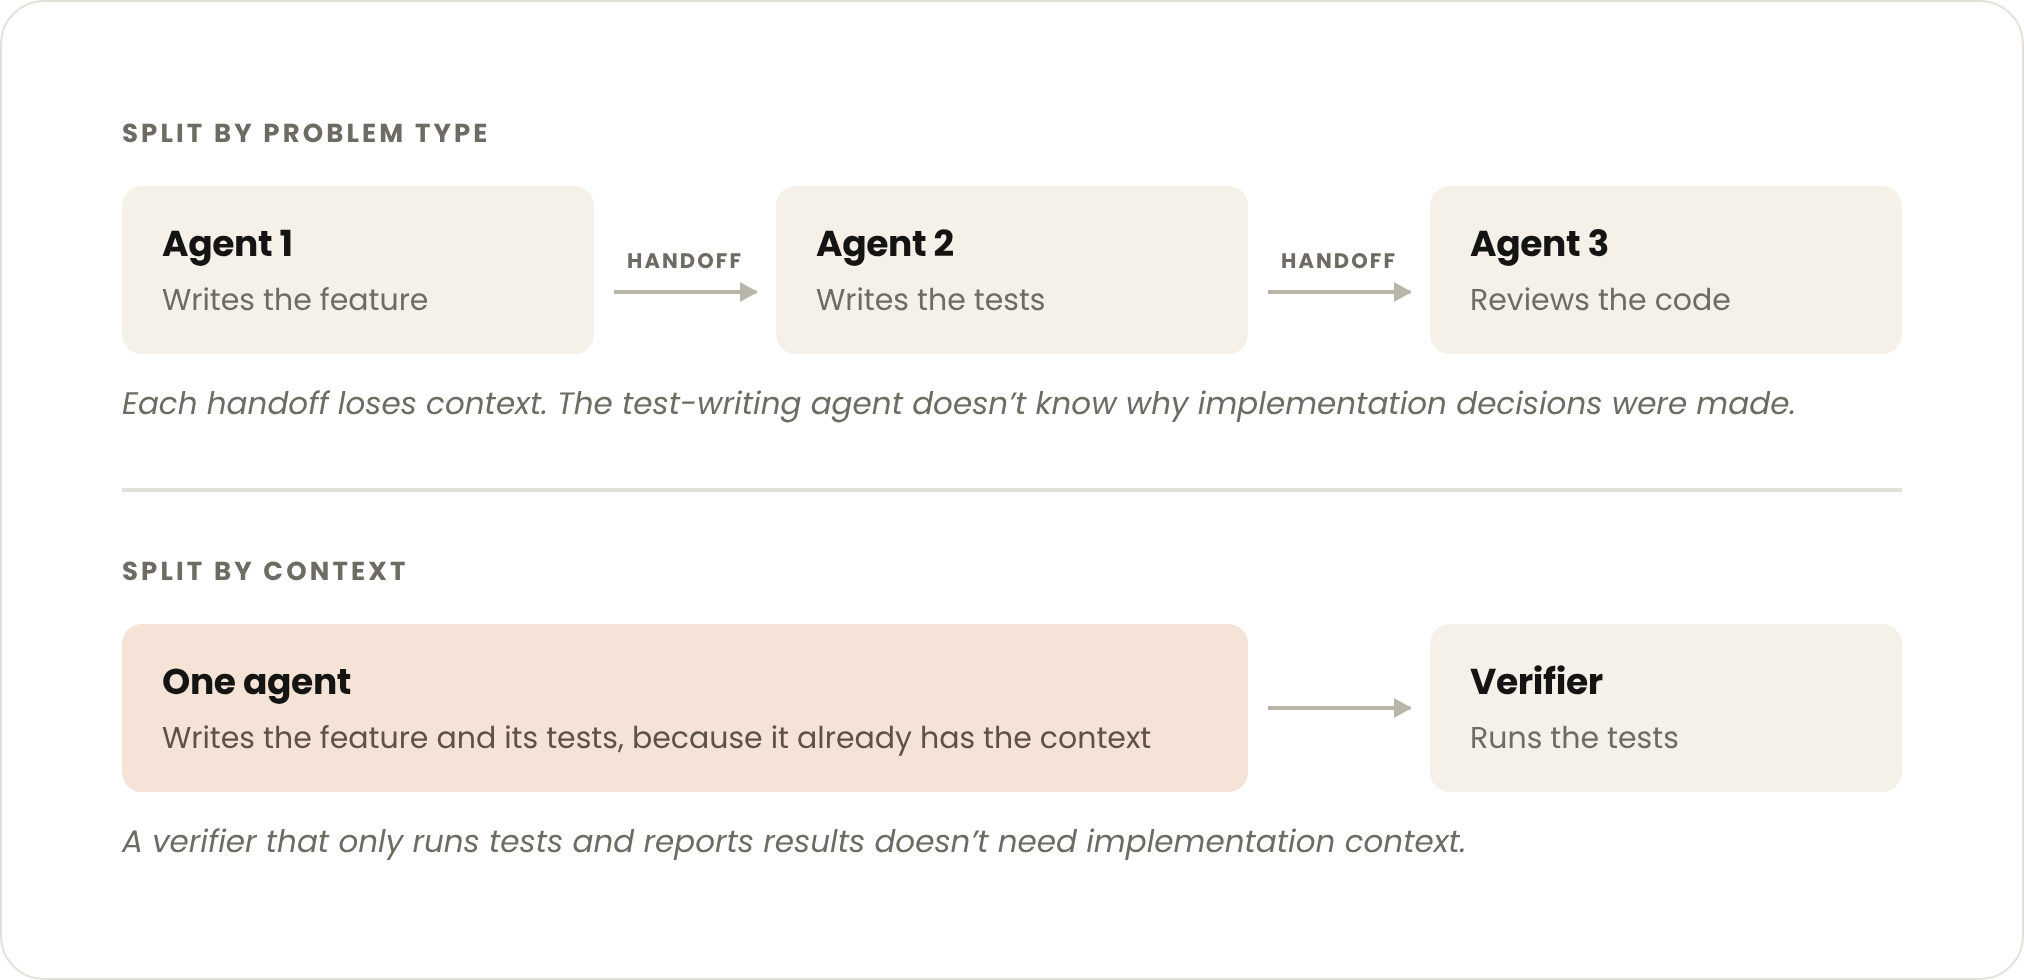
如果确实需要走多 Agent 路线,请从能满足需求的最简单模式(如 Generator-Verifier 生成-验证器、Orchestrator-Subagent 等)起步。划分边界的关键在于按上下文划分:分配给每个子 Agent 的任务应尽量少依赖系统其余部分,并要求其返回高度紧凑的结果(独立的研究路径、具备清晰接口的解耦组件或黑盒验证是理想候选对象)。如果简单按问题类型切分 Agent,就会陷入“传话筒游戏(Telephone Game)”,信息在来回传递中每次交接都会造成精度失真。
如何将子 Agent 整合进主 Agent 循环
许多团队在生产环境中已部署了编排器加一组专家 Agent 的架构。以下是我们建议逐步演进的单循环目标设计:
- 单一模型与单一上下文窗口运行开放式的工具循环,外层框架设置安全上限(轮次预算、费用预算、写操作关卡)。
- 每一轮中,模型输出一批工具调用。框架并行执行它们,并将原始结果返回给同一个模型,由该模型决定下一步:再发起一批调用、向用户提问还是直接输出最终回答。
- 当模型给出最终答复或耗尽预算(Budget)时,循环终止。回答生成后,可按需可选运行目标检查或验证器流程。
- 模型在首轮将规划写入上下文,并在结果返回时动态调整。这是与“编排器+专家 Agent”方案的核心差异:制定规划的模型与执行规划的模型是同一个,因此能够在轮次中途随时纠偏修正。
- 上下文依然会被加载,但由 Agent 自主管理:
- 不再需要专门通过代码从规则目录重写规划,因为每一步均由模型自主决策。
- 执行顺序与领域规范逻辑下沉到**技能(Skills)**中。
- 硬性限制(校验、审批关卡)及会话中途触发的逻辑(如记忆检索)下沉到**工具(Tools)**中。
- 针对低开销且几乎必定相关的逻辑(如实体解析步骤),以及循环调用工具内部的机械性处理(载荷构建、流式解析、恢复澄清流程),仍可保留代码实现。
这种单循环架构对于许多团队追求的终极状态(能够理解用户高阶意图并代其行动的 Agent)大有助益,因为它将 Agent 学到的一切信息保留在统一的上下文中。
以下建议指导团队如何分阶段从多 Agent 系统过渡到单 Agent 循环,以及多团队在这一过程中如何持续协同贡献。
任务完成度评估体系(Task-completion evals)
第一步是构建一套评估数据集,用于衡量是否应当将某个子 Agent 整合回主循环。已被证明有效的 Eval 结构是:由中心团队统筹一套共享的端到端数据集,各领域团队为其负责的每项技能附带小规模专用 Eval。初期哪怕仅有 10 个黄金评测用例(Golden examples)也足以启动。
根据评分准则对 Agent 最终输出的消息进行打分,是跟踪回答质量的良好起点。在编排器保留阶段,还应监测路由准确率(是否挑中了正确的子 Agent?)。当子 Agent 被整合后,监测重点应转换为:Agent 是否加载了正确的技能或调用了正确的工具。随着时间推移逐步转向全流程“任务完成度评估”,这在跨架构对比时最为关键。
在内部系统重放难度大、用户交互难以模拟的环境中,该过程可能会较为复杂。我们在内部验证有效的一种做法是对关键事件打上时间戳,以便后续回放并运行针对性 Eval。
逐步精简子 Agent
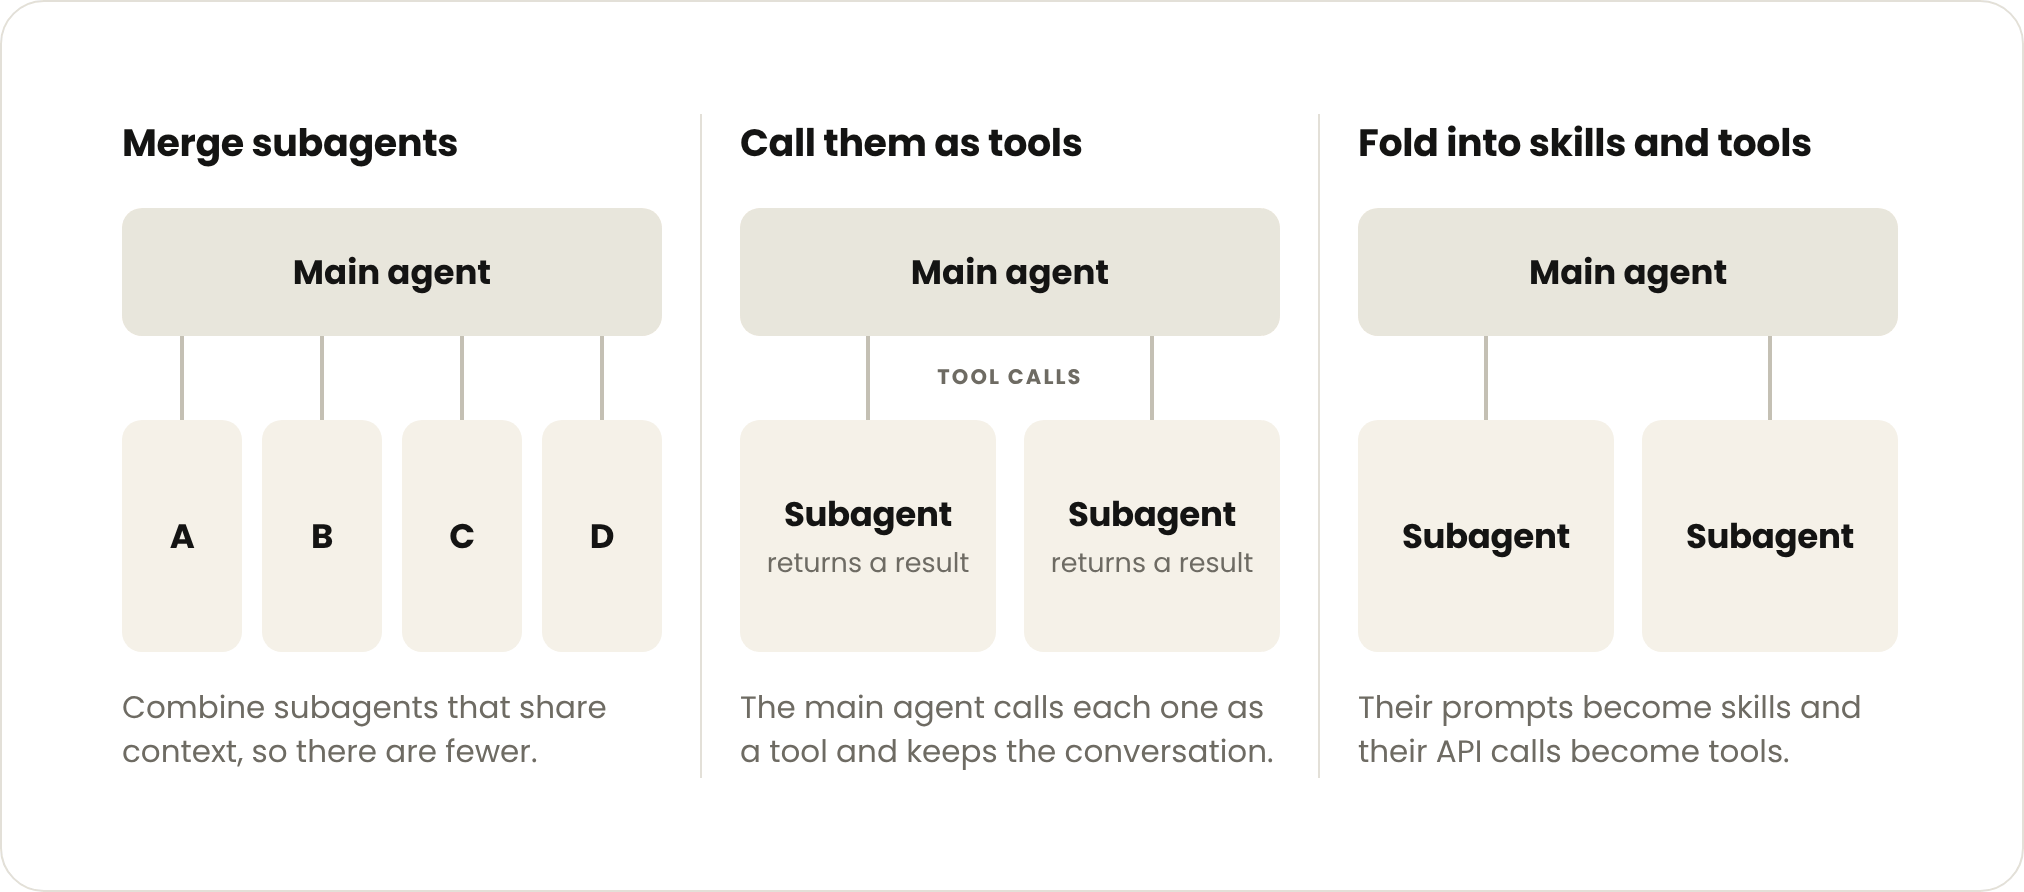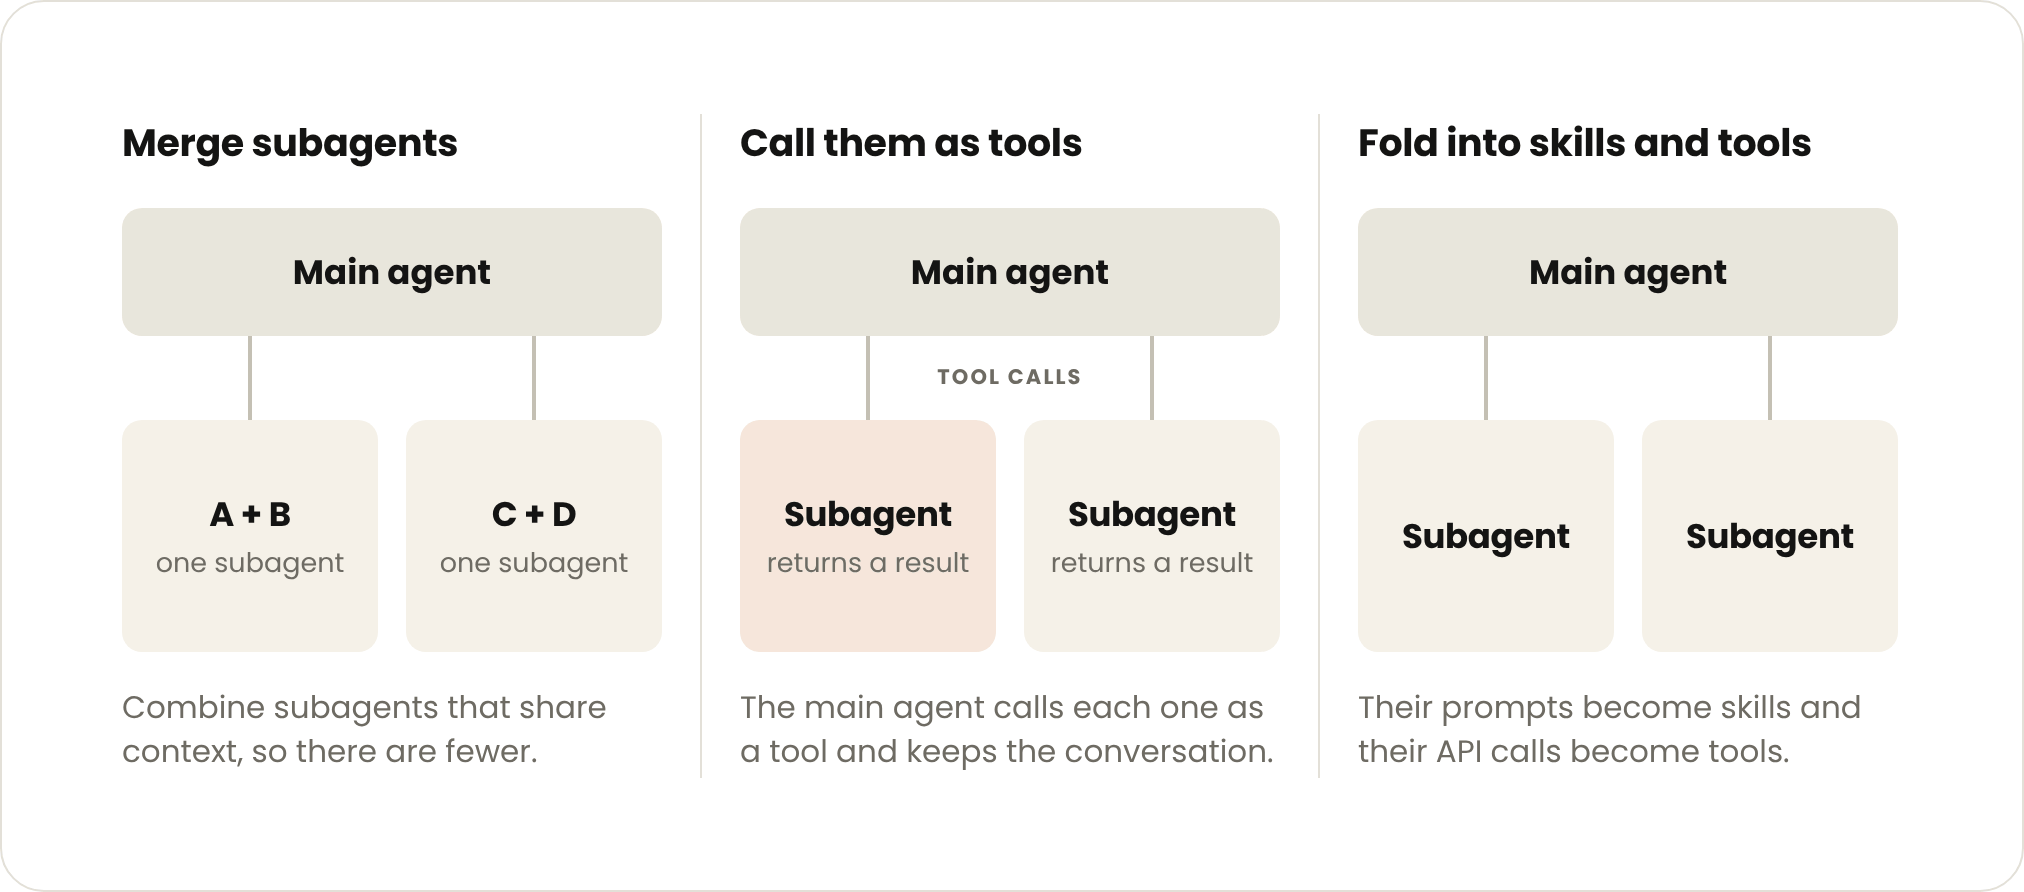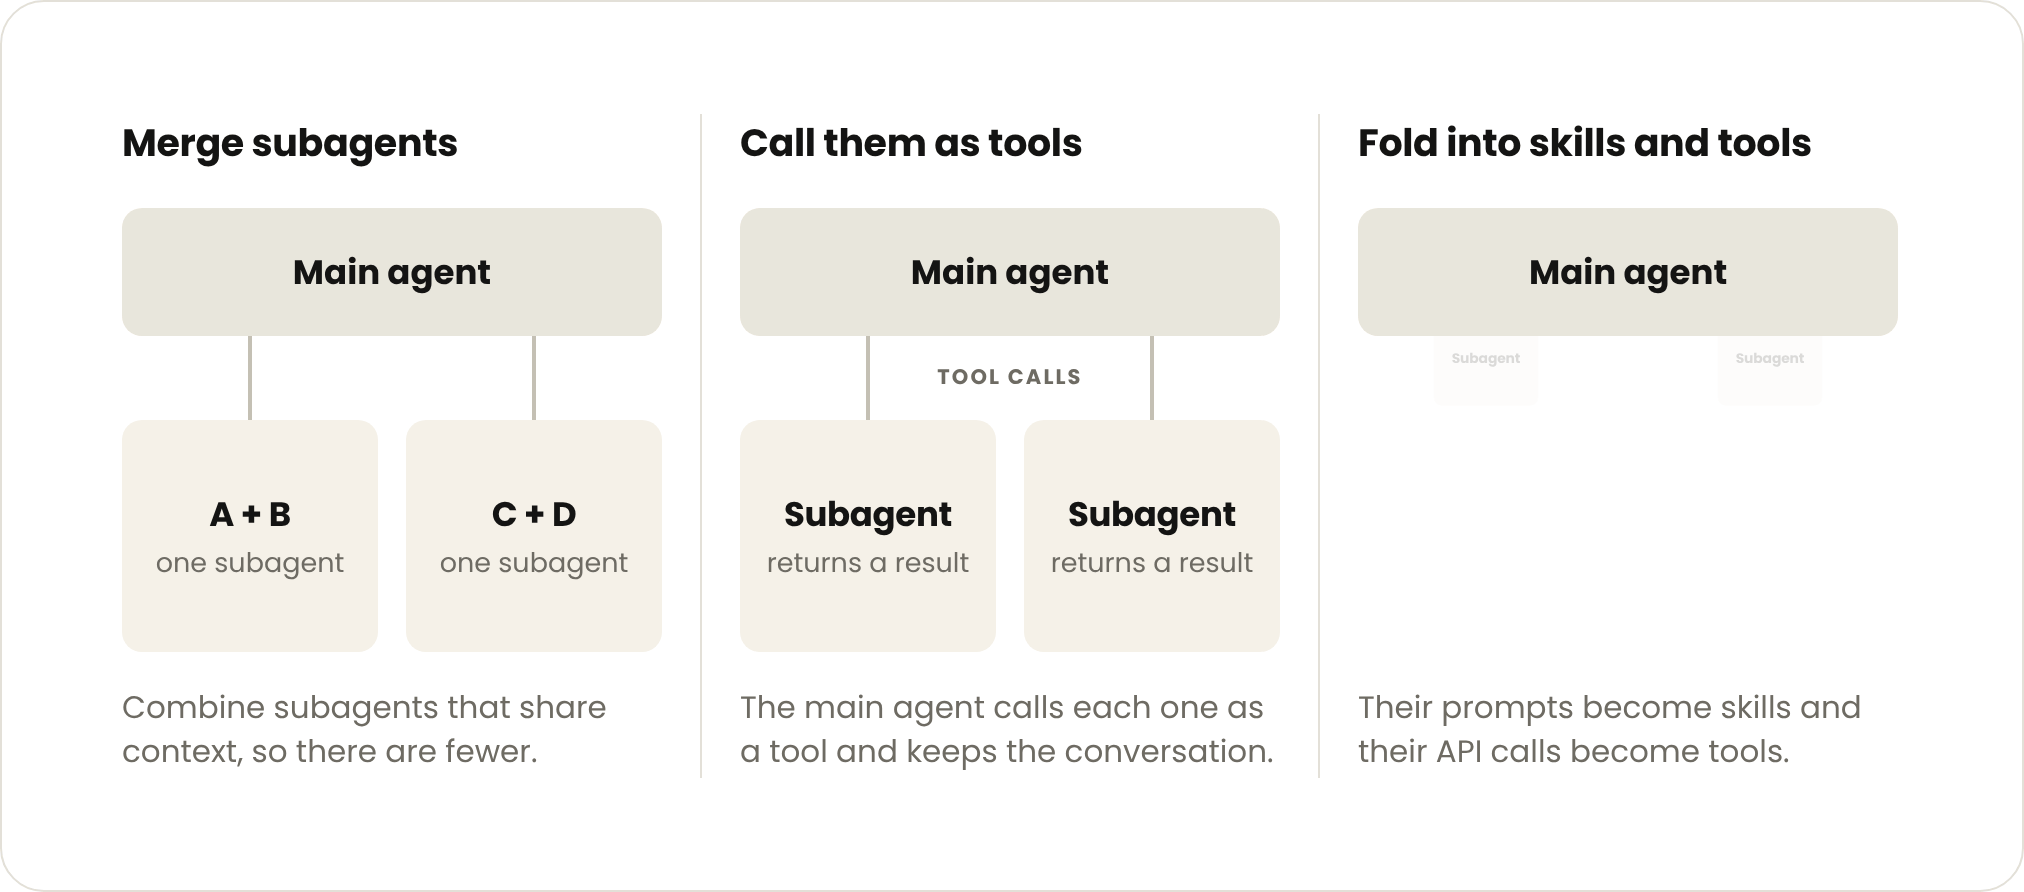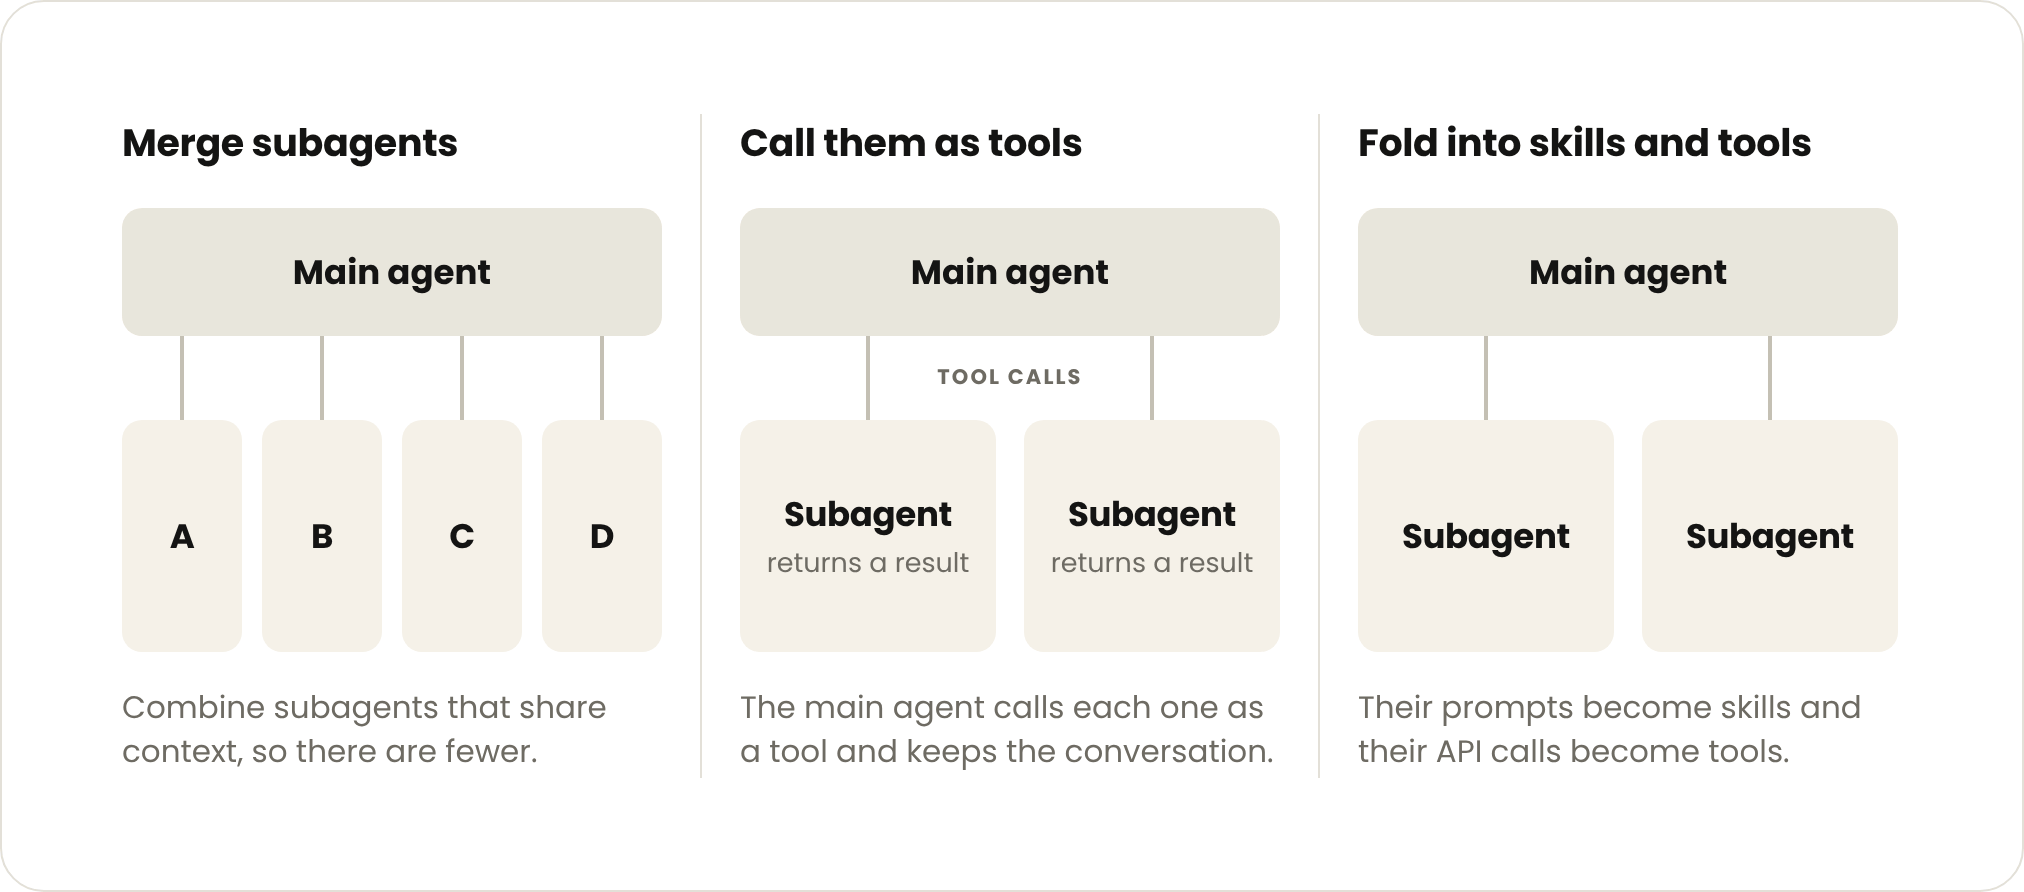
向单 Agent 循环演进的过程,本质上是将子 Agent 逐步整合为工具与技能的过程。这可以通过合并领域子 Agent、将其作为工具调用,或直接用技能与工具取而代之来实现。
合并领域 Agent
在首次合并前,先建立一个小规模端到端 Eval。随后按照共享上下文的维度进行整合,优先从调用频次最高的子 Agent 着手。
合并专家模块(Merge specialists):将彼此输出级联、读写相同数据或经常被连续调用的模块合并。例如,如果线上相当大比例的流量都是先走专家 A 再走专家 B,二者便属于紧密耦合对,非常适合直接合并为单一领域 Agent。
将子 Agent 作为工具调用
当符合上述必须保留子 Agent 的三项条件之一时,让主 Agent 将子 Agent 作为工具调用是一种有效折中,这样主 Agent 可以继续直接维系与用户的会话。
我们仅在子 Agent 确实需要直接与用户沟通时,才建议进行彻底的会话交接(Full handoff)。其余所有场景,均可在主循环中以“技能 + 工具”的形式实现。
这种方式允许你为子 Agent 规范统一的响应 Schema,由主 Agent 结合真实数据验证其结论,并精简输入给最终合成步骤的内容。这是非常稳妥的第一步,因为你不需要重写子 Agent。同时,它能在你决定彻底将子 Agent 整合为主 Agent 前,提供任务完成度 Eval 的基准线(Baseline)。
然而,这种过渡形态仍会残留部分失效模式:
- 每个专家 Agent 仍保留独立的 Prompt、上下文、归属团队与 Eval;
- 每次调用依然返回有损的总结性摘要;
- 每次调用都是一层嵌套的模型循环,会继续累加延迟。
通过技能和工具将子 Agent 彻底整合进主 Agent
通过将每个子 Agent 的 Prompt 改写为技能、将其 API 调用转为 MCP 工具,逐一整合进主 Agent。对比整合前后的 Eval 表现,进而决定保留哪种方案。
对比时,切忌只看整体最终得分,要仔细排查哪些具体任务发生了翻转(从通过变为失败)。在我们在客服 Agent 样例上的测试中,将一个子 Agent 整合到另一个 Agent 虽降低了延迟,却导致原本能通过的一个流程出现异常:主 Agent 掌握了订单查询工具后自行作出了回答,而没有按规范向物流专家索取确切交货日期。
在每次变更前,务必确保你的 Eval 覆盖了线上常协同运行的 Agent 链路,以及 Agent 绝对不可违背的硬性规则;每个测试用例应重复运行多次,因为类似上述的回归问题有时在两轮运行中仅会出现一次。
多个团队如何向单一 Agent 协同贡献
领域推理逻辑可以从知识库、技能和 MCP 工具中检索获取。各业务团队的职责边界可以从“维护独立 Agent”转变为“维护技能与工具”,并由一个小规模的中心团队统筹负责主 System Prompt 与全局评估体系。
English / 原文
If you’ve built an agent in Claude Platform that includes multiple subagents, see which may make sense to fold into the main agent loop using ourmigration kit. It runs a guided workflow to identify your patterns, evaluate alternatives, and verify the best approach. It includes a demo that you can try on a mock system before running on your agent.
Subagents – agents with their own context window, tools, and instructions, orchestrated by a coordinator – are a core component of agent design. They are effective at verification, parallel work, and modular permissioning. We use them in many of our own agents that we build using Claude Platform, for example our multi-agent research system.
However, recently the Applied AI team has found a pattern of enterprise agent deployments that have benefited from folding routers, planners, and domain subagents into the main agent loop. In our comparisons across several enterprise deployments, a single agent with skills frequently outperformed both the one-prompt-for-everything design and the subagent design on quality, and often at a lower cost and latency per task.
For example, one company found the dozen of specialist subagents within its customer-facing agent made a consistent on-brand experience difficult to maintain and added latency that hurt the user experience.
We also often see proposed agent designs that follow a familiar progression: an intent classifier, a fixed multi-step reasoning pipeline, user-segment buckets, separate recommendation branches, and a multi-agent orchestrator on top.
In these cases feedback is often that most of this structure was doing work the model no longer needed done for it, and that one clear system prompt, 4-5 thin data tools, and firm output guardrails would cover most of the use case.
To be clear, subagents still have their place, including at the research frontier. Use them when:
- A single agent loop hits measurable performance degradation from context bloat, or
- Multiple tasks need to be tackled in parallel with fresh context windows that can be discarded once the task is done, or
- A single agent struggles to select appropriate tools or there are conflicting instructions in the system prompt.
But too often we see enterprises give each team or problem type its own subagent, with the agent architecture becoming a copy of their org chart (Conway’s law at work).
This post explains when to consider folding subagents into your main agent loop with best practices we’ve learned from building agents in large organizations.
Agent building failure modes for large organizations
Companies often want to build an agent that unites multiple products and capabilities into a single customer interface.
Typically, each capability is owned by a separate team, so companies start by letting each individual team build their own agent, then a central platform team builds an orchestrator on top. This can take on several structures including orchestrator-subagent or a single agent with specific agents exposed as MCP tools.
This looks like the simplest solution but introduces immediate complexity around:
- Context management: You need to decide what context is exchanged between agents and often lose details in the back and forth.
- Subagent sprawl : Every team ships its own subagent, so companies end up with hundreds of overlapping subagents with no enforced standards and no specific owner.
- The Frankenprompt : Every team adds a sentence to the system prompt, resulting in conflicting rules and no consistent voice.
- Unvetted, overly localized evals : Everyone adds their own evals that are overly optimized for their subtask. No one owns or maintains the whole set, and leadership makes decisions based on watered-down, overly localized scores.
- Latency : Multi-agent architectural complexity adds latency. One customer that evaluated their multi-agent harness against a single agent loop saw a roughly 2x faster runtime with the latter.
Using an agent loop with progressive disclosure
The orchestrator-subagent design described above is a reasonable approach to coordinating specialists built across teams, but often a more effective approach can be progressively disclosing context via skills and progressively disclosing tools via tool search. In other words, the agent sees short descriptions of the skills and tools, which are fully loaded only when needed.
There are three reasons why this approach can make sense:
- Shared context produces better answers: for longer-running agents, we want the context from several different tasks to sit in the main context window. An agent that has seen the result of each earlier step can connect them, which leads to richer outputs and better insights than a set of summaries handed back by subagents. It also means fewer context windows and fewer lossy handoffs.
- Progressive disclosure prevents context bloat: this technique**** allows teams to build single agents that can accomplish a wide variety of tasks without requiring all of the context to be immediately loaded into one long system prompt. This removes the main reason teams previously split work across subagents. In fact, we reduced Claude Code’s system prompt for more advanced models by over 80% which included cuts related to progressively disclosing skills and tools.
- Models are more capable: starting with Opus 4.5, models became capable of managing far more in a single loop than most teams expected. You cannot turn off thinking on Opus 5.5, and Fable 5.1, and recent models increasingly narrate their progress and check their work as they go, which makes some harness elements redundant. Each new model lets you move more of the decision-making out of the harness and into the model itself. A simpler loop is also easier to move to the next model; in migrations we have helped customers with, rigid multi-agent structures were often what stopped the new model from doing more of the work.
The single agent loop design requires discipline: a carefully managed system prompt, skill and tool descriptions that trigger at the right times, and deliberate handling of context windows, memory, and note-taking. This article goes deeper into migration and design considerations in subsequent sections.
One central team should own end-to-end quality and the system prompt, vetting every new tool and eval before it ships. Keeping that central team small helps iteration move quickly and lowers coordination cost across a large org.
If you go the multi-agent route, start with the simplest pattern (generator-verifier, orchestrator-subagent, or other) that could work. Decompose boundaries effectively bydividing by context: give each subagent a piece of work that needs little from the rest of the system and have it hand back a compact result(good candidates are independent research paths, separate components with clean interfaces, or black-box verification). When agents are split by problem type, they engage in a "telephone game,"**** passing information back and forth with each handoff degrading fidelity.
How to fold subagents into the main agent loop
Many teams already have an orchestrator and a set of specialist agents in production. The following is the single loop design we'd suggest working toward:
- One model and one context window running an open-ended tool loop, with limits (turn and cost budgets, write gates) set in the harness.
- Each turn, the model emits a batch of tool calls. The harness runs them in parallel and returns raw results to the same model, which decides the next step: another batch, a question to the user, or an answer.
- The loop stops when the model answers or hits a budget. A goal or verifier check can optionally run after the answer.
- The model writes its plan in context on the first turn and revises it as results arrive. This is the main change from the orchestrator and specialist agents setup: the model that writes the plan is also the one carrying it out, so it can change the plan mid-turn.
- Context still gets loaded, and is managed by the agent itself:
- A code step that rewrites the plan from a catalog of rules is no longer needed, since the model decides each step.
- Ordering and domain procedure move into skills.
- Hard limits (validation, approval gates) and anything else that comes up mid-conversation (e.g. memory lookup) move into the tools.
- Code can still be used to load anything cheap and almost always relevant (e.g. an entity resolution step), and to handle any mechanical parts (payload construction, stream parsing, resuming a clarification) inside tools the loop calls.
This single loop design also helps with the end state many teams are working toward (an agent that understands a user's high-level goals and acts on their behalf), since it keeps everything the agent has learned in one context.
The suggestions below are how a team could get from a multi-agent system to a single agent loop in stages, and how several teams can keep contributing to that agent along the way.
Task-completion evals
The first step is to create an eval set that can help you determine whether you should fold a subagent into the main agent loop. The eval structure we’ve seen work is one shared end-to-end set owned by a central team with smaller eval sets shipped with each skill by the team that owns it. Even a set of 10 golden examples is enough to start.
Grading the agent's final message against a rubric is a good starting point for tracking answer quality. While you still have an orchestrator, you should also track routing accuracy (did it pick the right subagent?). Once a subagent is folded in, check instead whether the agent loaded the right skill or called the right tool. Working toward task-completion evals over time is helpful as this matters most when comparing architectures.
This can be complex in environments where internal systems are difficult to replay and user engagement is difficult to simulate. One approach that has worked for us internally is to record timestamps on important events, so they can be replayed later to run as targeted evals.
Reducing subagents over time
Evolving toward a single agent loop involves folding the subagents into tools and skills. This can be done by merging domain subagents, calling them as tools, or replacing them with skills and tools.
Combining domain agents
Build a small end-to-end eval before the first merge. Then fold in by shared context starting with subagents that have the most use.
Merge specialists that chain on each other's output, touch the same data, or are often called together. For example, if a significant share of production traffic is one specialist followed by a second, that is a tightly coupled pair, which makes it a candidate to merge into one domain agent.
Subagents called as tools
When one of the three conditions above applies and you keep a subagent, it can be effective to have the main agent call subagents as tools so it can continue holding the conversation with the user.
We’d only recommend a full handoff, where the subagent takes over the conversation, when it needs to talk to the user directly. Everything else can be a skill plus tools in the main loop.
This will allow you to define a shared response schema for subagents, verify the conclusion against real data with the main agent, and trim the input to any final synthesis step. This is a good first step, as you don’t need torewrite the subagents. It also gives you abaseline on the task-completion eval before deciding to fold any subagents into the main agent.
However, some failure modes will remain:
- Each specialist has its own prompt, context, owner team, and evals
- Each call still hands back a lossy summary
- Every call is a nested model loop that adds latency
Folding subagents into the main agent via skills and tools
Fold subagents into the main agent one at a time by turning each one’s prompts into skills and API calls into MCP tools. Compare eval performance with and without the subagent. Then decide which to keep.
When you compare, don’t just examine the final score, take a look at which tasks flipped. When we tested this on a sample support agent, folding one subagent into another lowered latency, but also broke a process that had been passing. The main agent was holding the order lookup tool and answering on its own, without asking the shipping specialist for the delivery date.
Before each change, make sure your eval has a task for every chain of agents that runs together in production and for every rule the agent must not break, and run each task more than once, since a break like this one only showed up in one run out of two.
How several teams can contribute to a single agent
Domain reasoning can be retrieved from knowledge bases, skills, and MCP tools. Individual teams can shift their ownership from agents to skills and tools, with one small central team keeping ownership of the system prompt and end-to-end quality. This involves vetting new skills, tools, and evals before they ship.
MCP tools
Tools are the right fit when the agent needs to take an action, read live data from a system, or return a result in a fixed shape. You can also use tools as a way to keep calling subagents while you migrate. We recommend tools grouped by user intent (not one tool per API) because once you exceed 30-50 tool definitions in the system prompt, tool choice tends to degrade.
Use tool search with deferred loading, limit hard preconditions, and move any needed ones into the tools. For example, if Y needs X's output, Y's tool checks for it and returns an instruction the model can act on. Per-user permissions work the same way. Each tool checks what the calling user may see or do and returns a plain refusal the model can read, so one loop can serve users with different access without a separate agent per permission level.
Skills
Skills are the right fit when the agent needs to know how a team does work, like the steps, rules, and judgment calls a specialist subagent's prompt used to hold.
Our approach to growing skill libraries is to give the maintenance work back to the people writing the skills. Claude can do the heavy lifting with skills that can build, test, and prune other skills.
To prevent skill sprawl, you can have DRIs per team own their skills and make sure they are well crafted, distinct, and shipped with appropriate evals.
- /skill-creator allows you to author new skills that start well-formed, and audit existing ones to trim, deduplicate, and restructure them.
- /skill-doctor allows you to see what each skill in your library costs and how often it’s actually used, and delete dead weight.
Knowledge bases
Knowledge bases are the right fit for reference material the agent only needs some of the time. Facts and reference material (policies, metric definitions, product specs) can sit behind a search or lookup tool the model calls, or ship as reference files inside a skill. Avoid having code retrieve and paste this context into prompts.
We recently released a set of Claude API skills that can help with most of the work mentioned above. Our migration kit chains these skills together in one guided workflow for assessing and moving multi-agent systems to a single agent loop. It includes a demo you can try before running it on the real thing:
- /claude-api build-eval: can help create a first end-to-end set owned by the central team or small evals each team ships with its skill
- /claude-api prompt-audit: can flag instructions written for older models in your prompts, skills, and tool descriptions and propose fixes as a diff. This can be run on your system prompts to find any rules that were added for an earlier model and are now making the agent slower or more rigid. Each team's DRI can also run it on their own skills and tool descriptions.
- /claude-api hillclimb: can iteratively improve an app against an existing eval. This can be used for the "folded in vs kept" comparison (after folding one subagent into a skill plus tools, let it iterate on the skill and tool descriptions and see if the folded version matches or beats the subagent), as well as your system prompt.
- /claude-api cost-optimize: profiles where your calls go and proposes savings from options such as prompt caching, trimming unneeded input and output tokens, effort, and model choice, one change at a time. This can help bring cost and latency down on a given design.
As models evolve, our understanding of how to best use them and guidance around best practice evolve as well. That makes any one architecture less important than the principle behind it: measure, change one thing at a time, and keep what holds up.
This is one of those cases. As models get more capable and agents get longer running, more of your subagents can be skills and tools. You don’t have to make that move in one step, though. Build a small end-to-end eval, fold in one subagent, and keep it as a subagent only if the folded version scores worse, then rinse and repeat.