Kimi 正式发布 K3.1 Pro:100万 Token 上下文 3T 级开源权重模型,全面强化 Coding、3D 与金融 Agent 能力
英文标题:🔶 Kimi K3.1 Pro
Moonshot AI 推出 K3.1 系列首款模型 Kimi K3.1 Pro 及响应速度提升 2 至 3 倍的 Highspeed 版本。作为支持 100 万 Token 上下文的 3T 级开源权重模型,K3.1 Pro 在长程编程、3D 空间建模与端到端金融分析等 Agent 任务上表现逼近乃至超越顶级专有模型。在 Terminal-Bench 4.0 测试中其得分达 65.7%,领先 GPT-6 Astra 并紧咬 Claude Opus 5.5;同时团队引入了针对性的网络安全风险数据清洗与管控机制。模型已即刻上线 Web 端与 API,完整权重将在 11 月 4 日全面开源,为全球开发者提供高可用且可控的底层开源基础设施。
 402.1 KB
 217.4 KB
 30.9 KB
 92.9 KB
 45.6 KB
 49.0 KB
 55.3 KB
 71.5 KB
 42.3 KB
中文
我们正式推出 Kimi K3.1 Pro——这是全新 K3.1 系列的首款模型,也是我们迄今为止能力最强的 3T 级开源权重模型,具备 100 万 Token 上下文窗口。它在代码编写、3D 创作、金融投研以及其他 Agent 能力方面均带来了实质性提升。
同时,我们还发布了 Kimi K3.1 Pro Highspeed,其推理速度达到 K3.1 Pro 的 2 至 3 倍,可带来响应更加迅速的交互体验。
Kimi K3.1 Pro 与 Kimi K3.1 Pro Highspeed 即日起已在 Kimi.ai、Kimi Work、Kimi Code 以及 Kimi API 上线。完整模型权重将于 11 月 4 日前正式发布。
推进开源智能的前沿边界
Kimi K3.1 Pro 是 Kimi K3 的后训练(Post-trained)升级版本,投入了显著增加的后训练算力。为了在数百个下游领域实现大规模联合强化学习(Joint RL),我们对技术栈的每一层都进行了深度优化——涵盖强化学习框架、长上下文推理、训练效率、沙盒基础设施、Rollout 调度,以及用于环境质量校验的统一平台,确保每一份新增的强化学习算力都能带来稳定、可预期的性能提升。得益于此,K3.1 Pro 在各个领域均取得了持续稳定的能力跃迁。
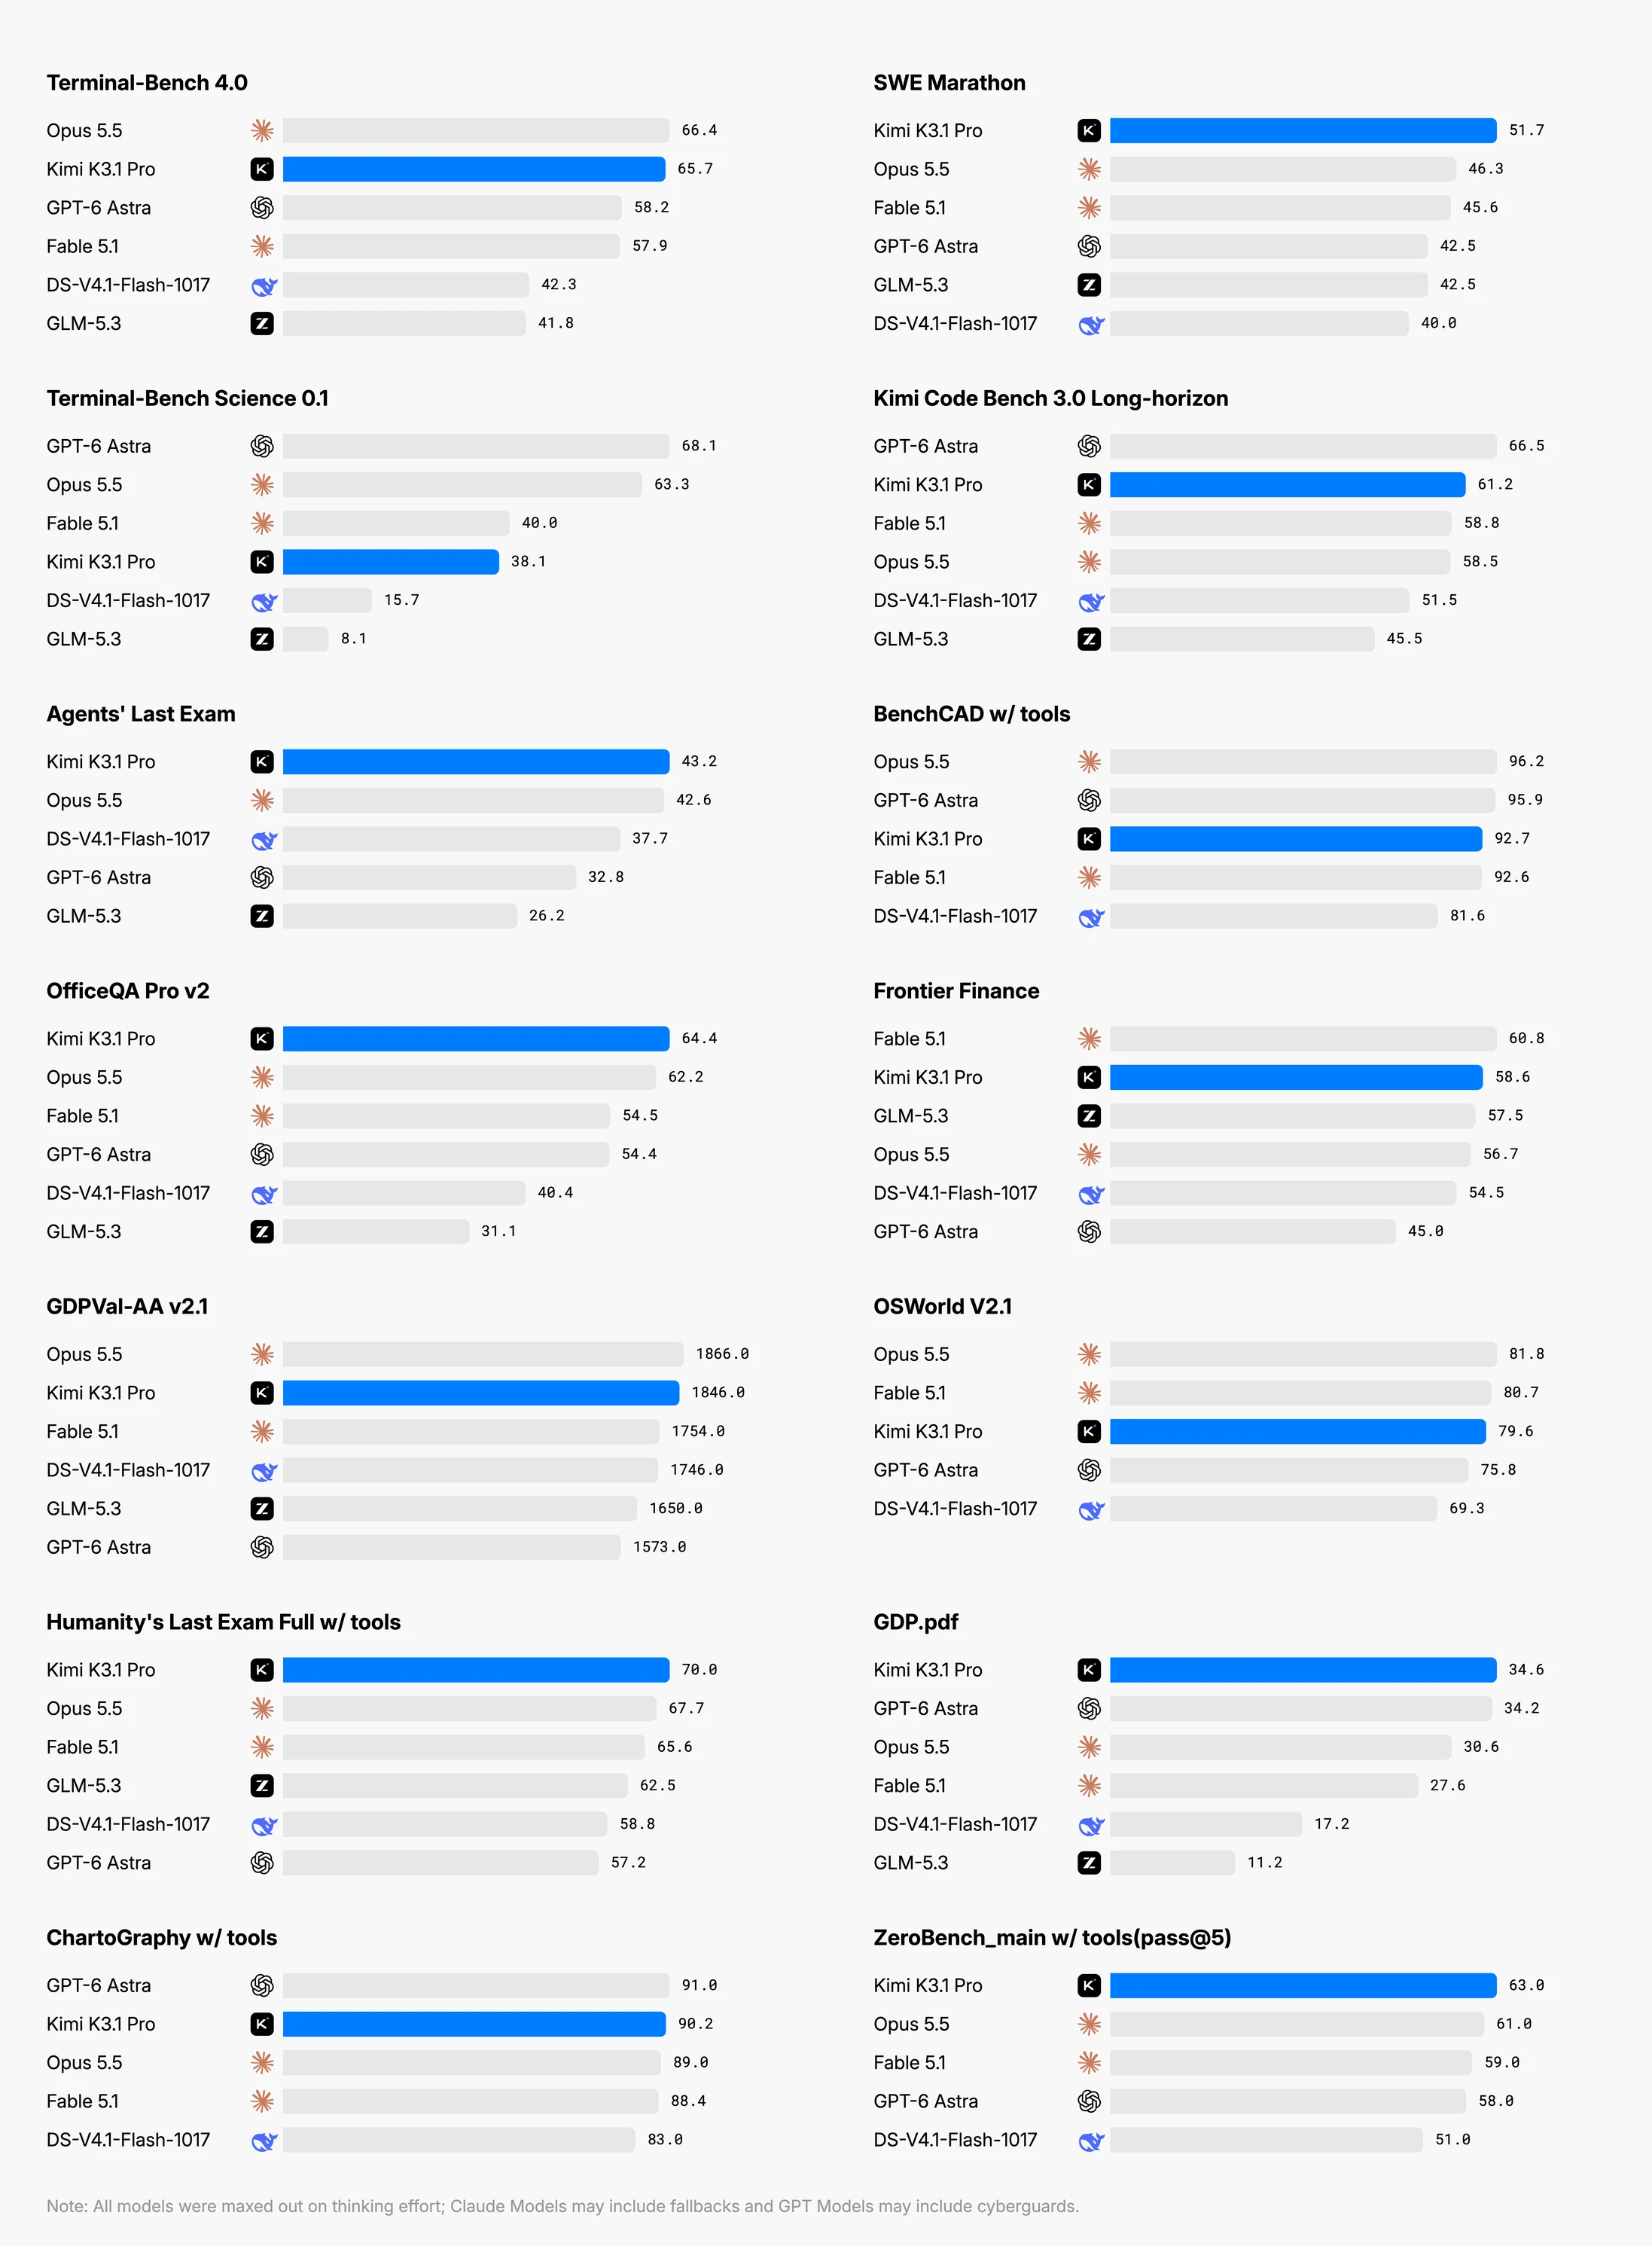
在代码、Agent 及知识类基准测试中,K3.1 Pro 已能比肩或迫近当前最强大的闭源商业模型。在采用严格定制化测试、评估真实资源受限终端任务的代码 Agent 评测 Terminal-Bench 4.0 上,K3.1 Pro 取得了 65.7% 的成绩,领先于 GPT-6 Astra(58.2%),并紧咬 Claude Opus 5.5(66.4%)。而在 Kimi Code Bench 3.0 Long-horizon(用于测试代码 Agent 在多样化工程领域中多步执行、工具调用和端到端解决复杂问题能力的内部基准测试)中,K3.1 Pro 获得了 61.2% 的得分,明显超越了 K3 的 55.95%。
代码与编程
K3.1 Pro 覆盖了全方位的编程工作,从真实代码库中的快速 Bug 修复到完整项目的端到端构建均能胜任。它还为游戏与 Web 体验注入了更成熟的视觉风格,并擅长选用合适的工具集进行构建。
K3.1 Pro 能够高效协同各类游戏引擎(如 Unity、Unreal Engine 和 Godot),将其与联网搜索和 3D 生成技术相结合,打造完整的交互体验。其构建的前端页面、Three.js 交互式场景和 3D 资产展现出更出色的构图、排版、动效表现与打磨水准。以下示例均由 K3.1 Pro 端到端生成:
得益于大规模强化学习,K3.1 Pro 的长程代码执行(Long-horizon coding)能力同样获得了大幅增强。 在一项内部实验中,它基于开源人体解剖模型 human-atlas(包含软骨在内的 296 个骨骼组件和 402 个肌肉组件),构建了一套集成训练与评估流水线的人体行走动力学仿真系统。在历经 167 项任务与 420 次独立评估后,模型自主分析了实验数据、诊断故障并反复调优行走控制器,成功让仿真人体从几秒内倒地提升至能够连续交替迈步稳定行走 11.2 秒。当单纯调整奖励函数(Reward Shaping)无法改善手臂运动时,K3.1 Pro 并未一味盲目调参,而是对模拟器的动力学模型进行了开环探测,准确定位并修复了肩部肌肉力臂计算中的 36 处错误,随后重新完成了控制器的训练。
3D 建模与设计
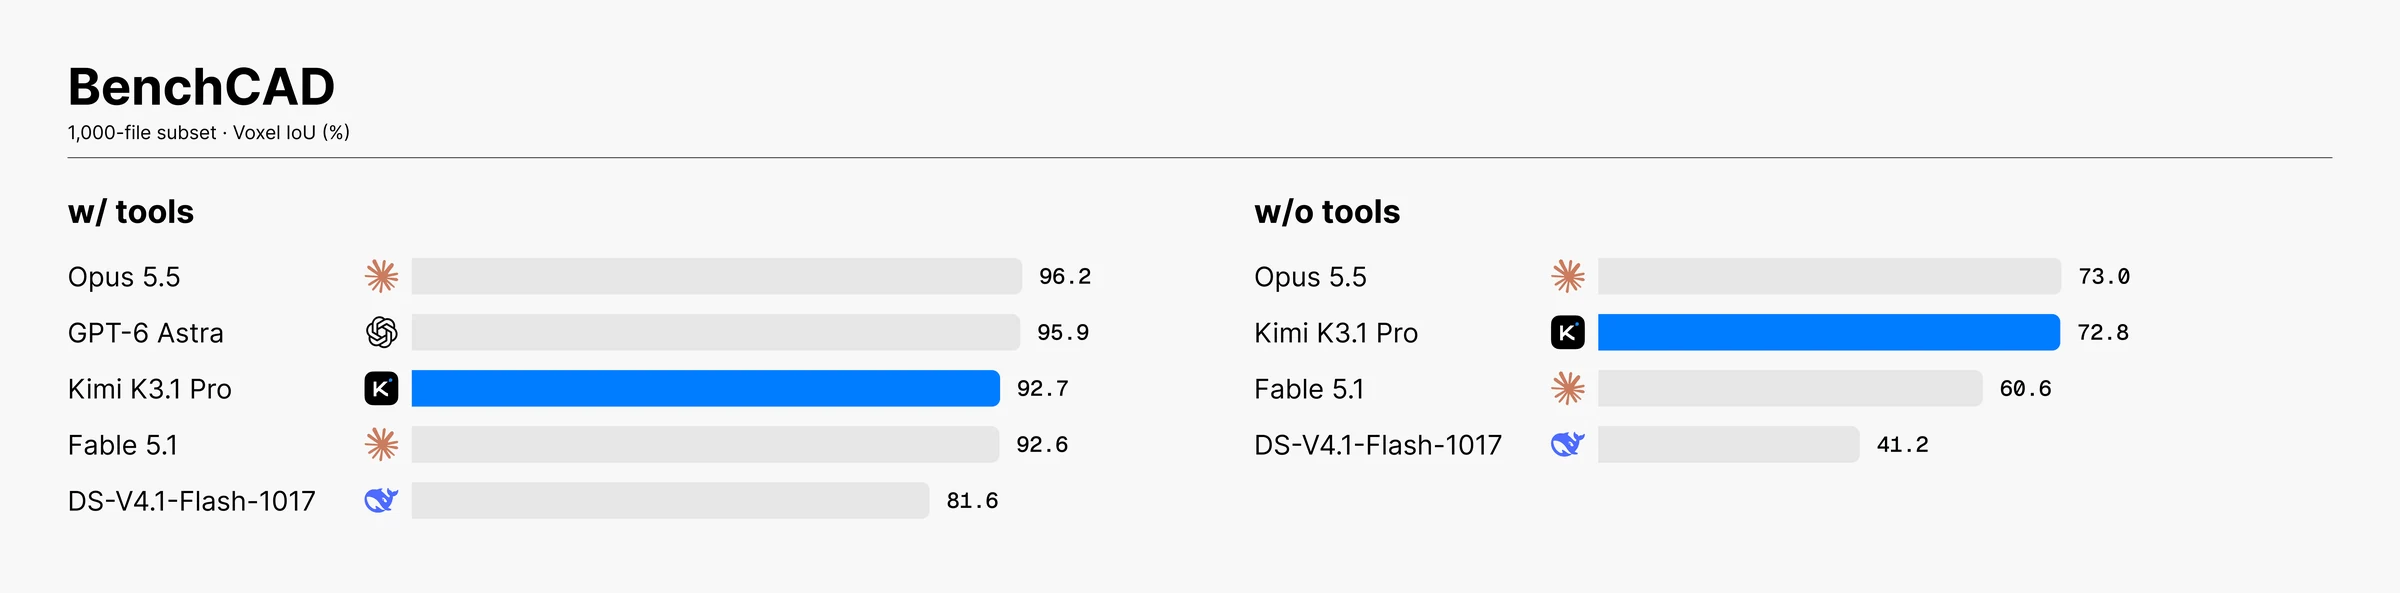
K3.1 Pro 在 3D 创作与空间推理方面表现尤为强劲。 在 BenchCAD(通过 CAD 代码生成测试多视角渲染图 3D 重建的基准)上,K3.1 Pro 在使用工具时取得了 92.7% 的分数,逼近 Claude Opus 5.5(96.2%) 与 GPT-6 Astra(95.9%)。无论是简要的文本需求、草图还是参考图像,它都能精准推断形态、比例和空间关联,从而构建可直接使用的 3D 模型。同时,它对现有资产库与模型资产集的理解与调用能力也更为敏锐。
K3.1 Pro 尤其擅长参数化建模,涵盖机械零部件、建筑模型、可配置商品以及定制家具等场景。 即便在没有 MCP 连接器的情况下,它也能自主编写并运行 Blender 及 CAD 软件的自动化脚本,从而生成和精修资产、编辑组件、调整几何构型、材质及场景布局。
以下是 K3.1 Pro 为品牌短片、游戏和交互式 Web 体验所制作的 3D 资产示例:
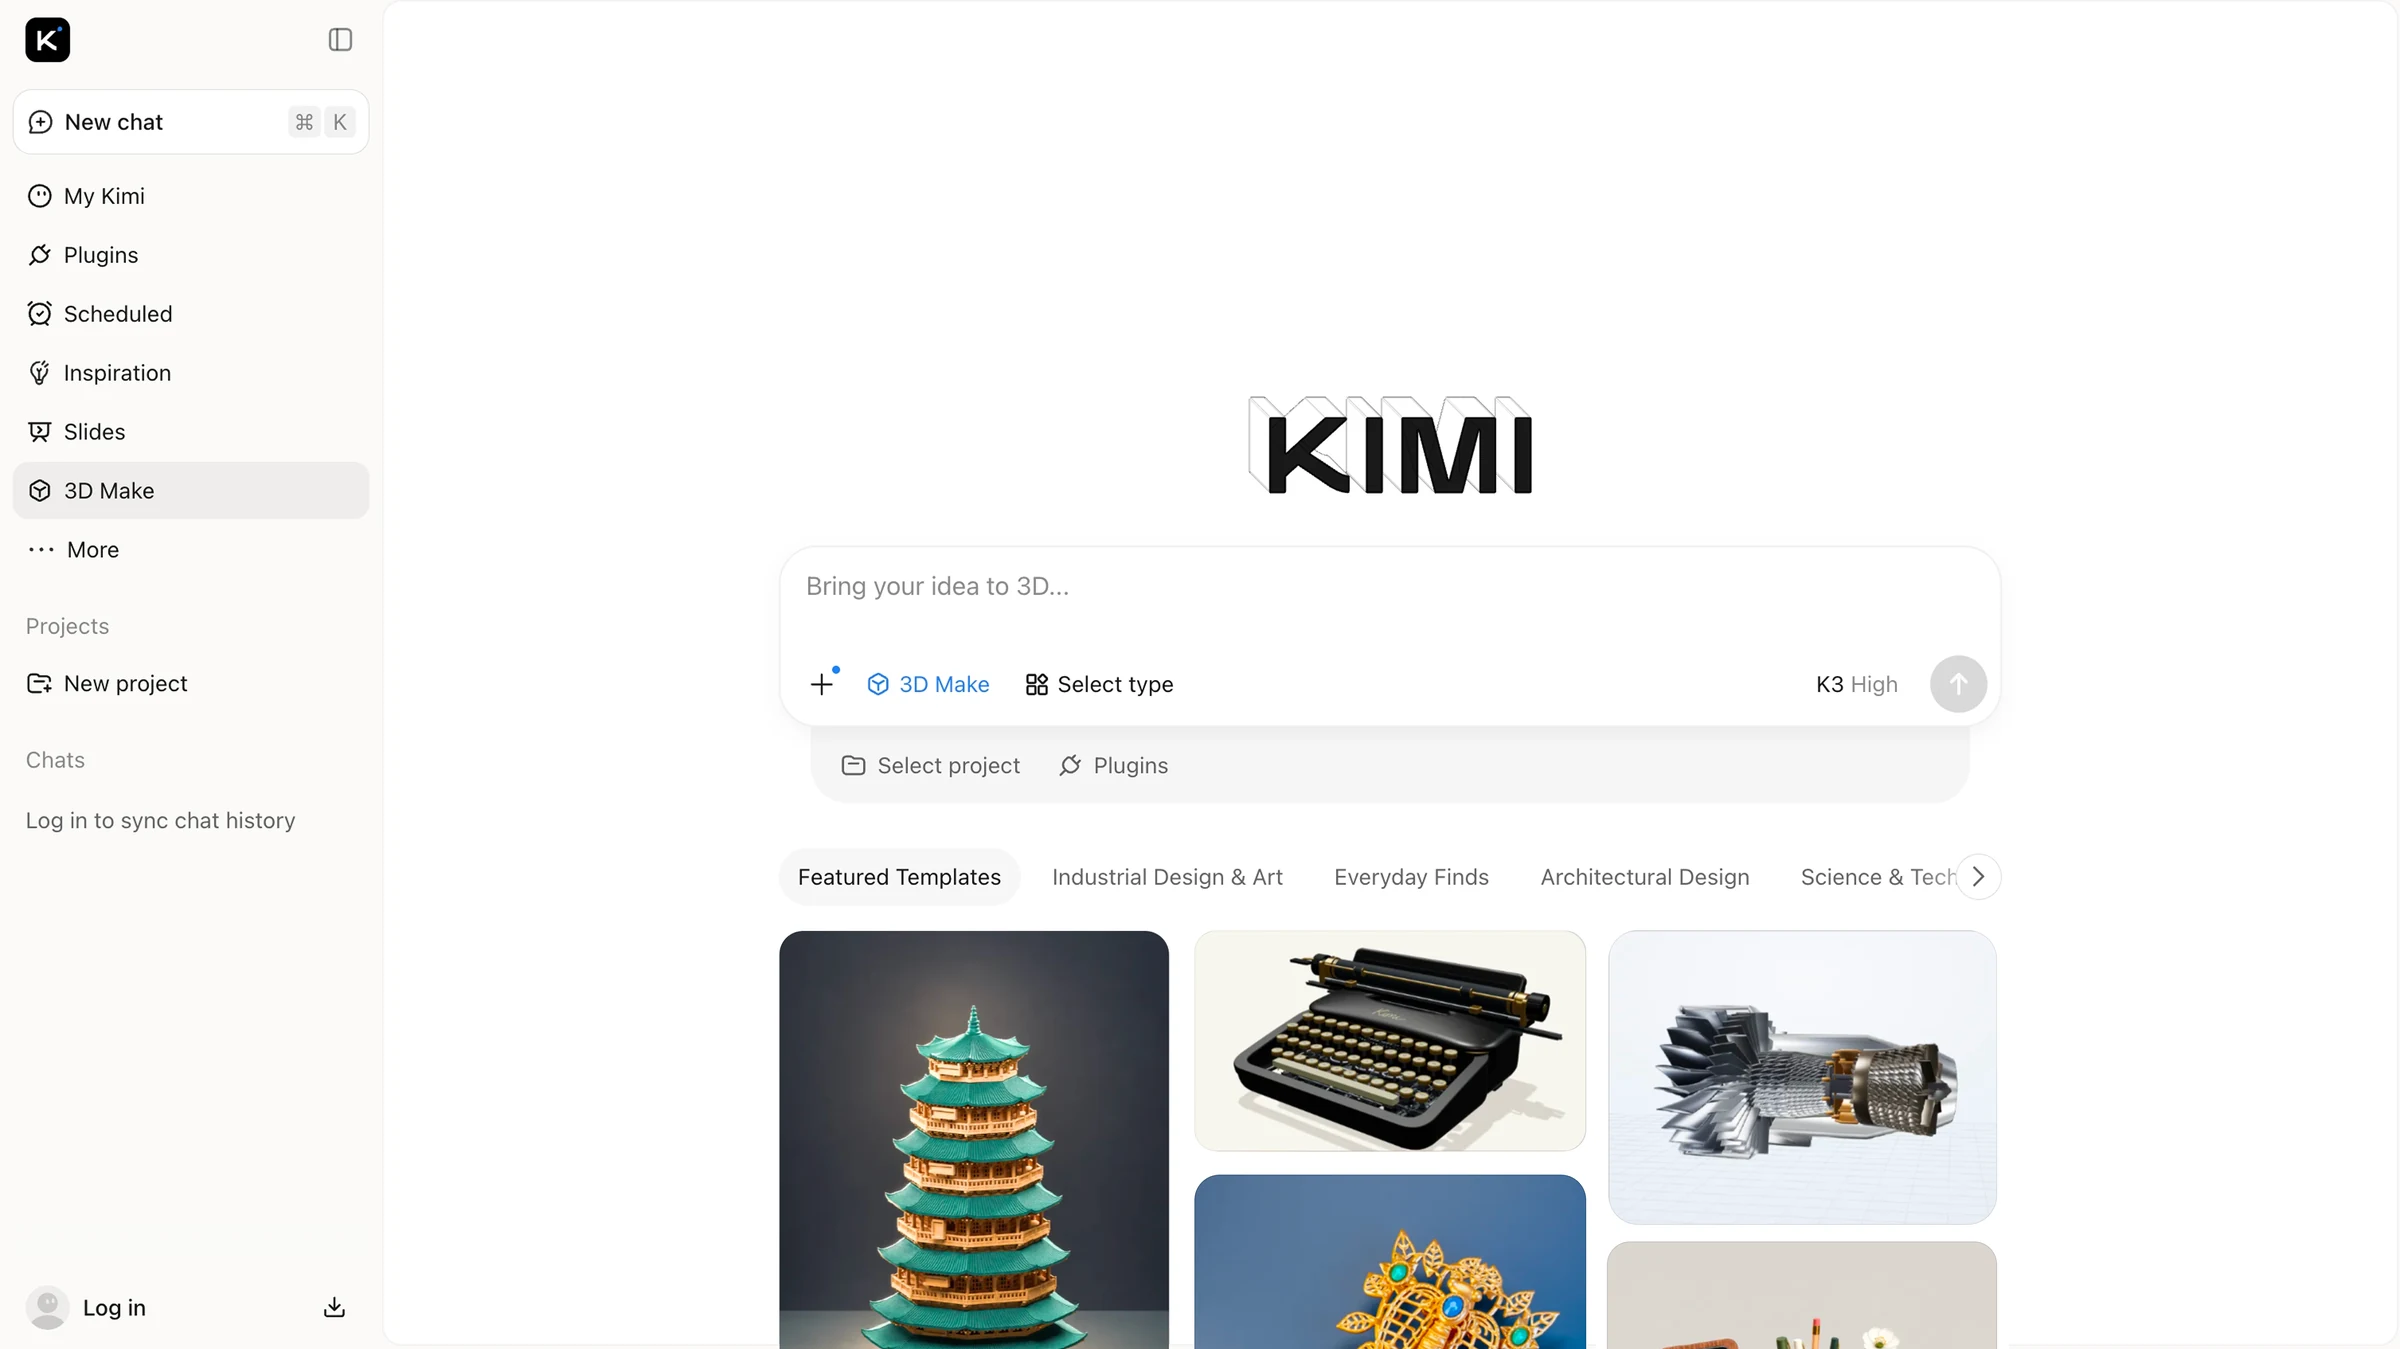
3D Make 现已在 kimi.ai 及 Kimi App 正式上线——用户可在线预览并编辑 3D 模型,直接导出符合 3D 打印标准的文件,或导出为视频、实况照片(Live Photos)以便随时分享。
金融
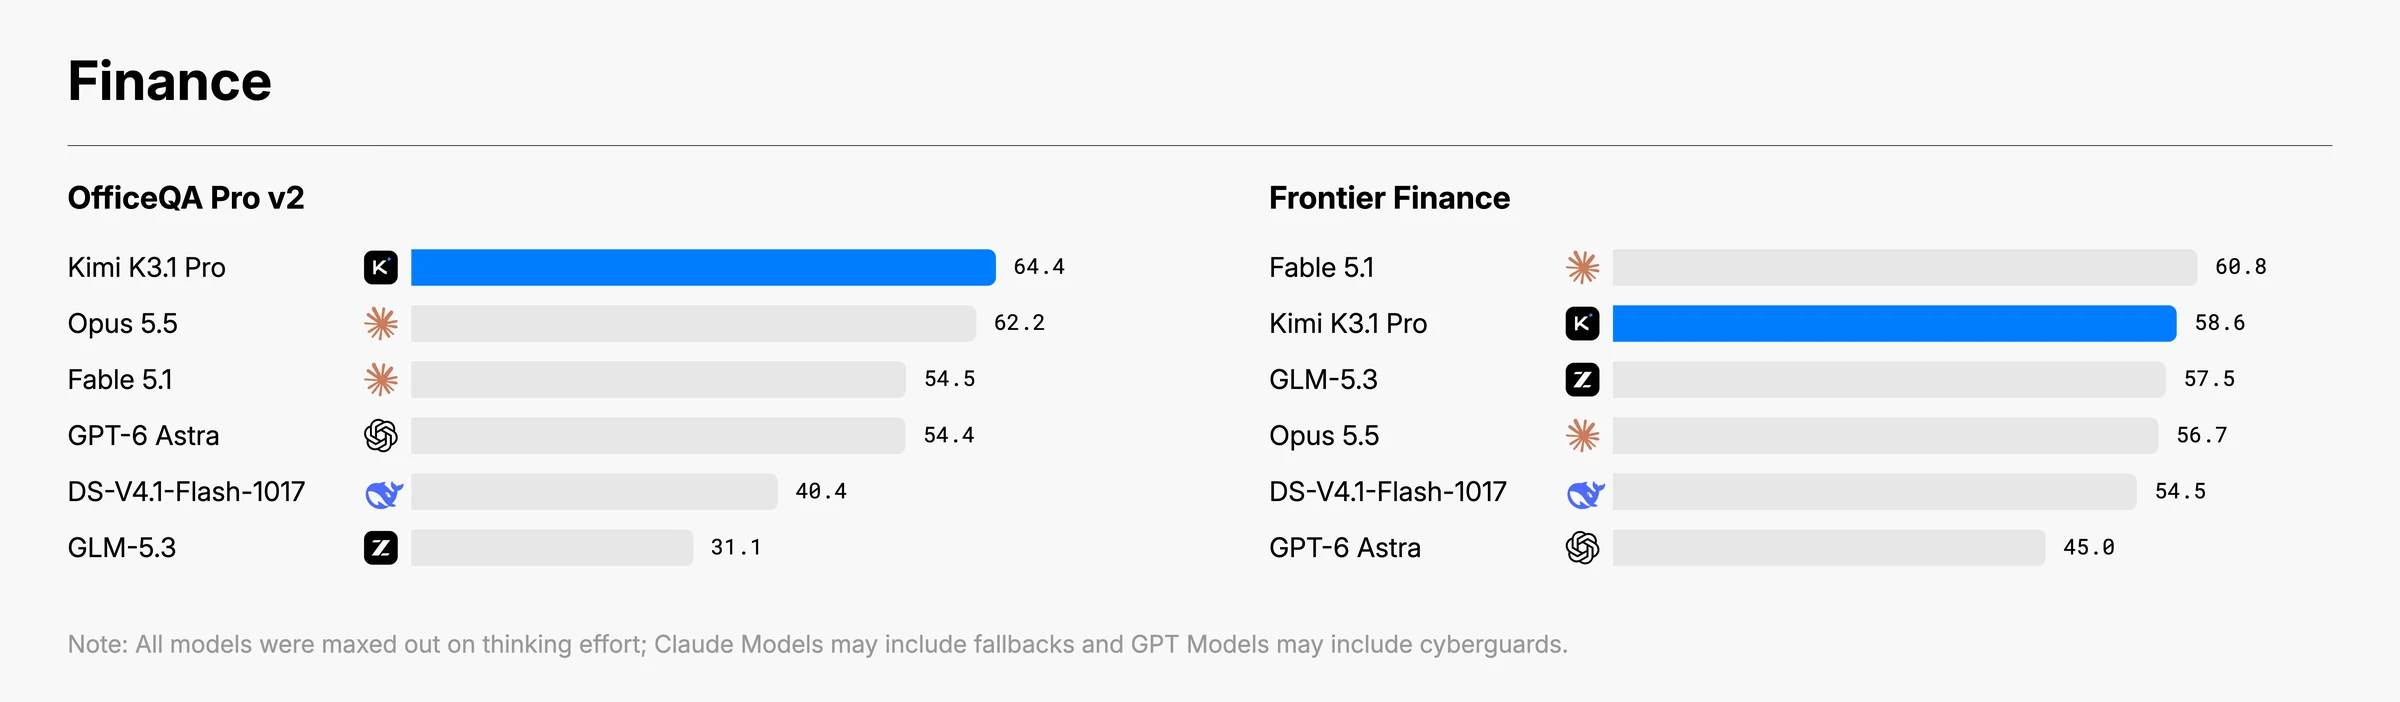
凭借更强的推理深度与 Agent 能力,K3.1 Pro 具备端到端完成整套复杂金融业务流的能力。K3.1 Pro 在 OfficeQA Pro v2 上刷新了行业最优表现(SOTA 评分 64.4),该评测专门检验模型在真实财务文档上,通过检索、跨文档核验与多步数值计算来应对复杂财务数据分析的能力。在衡量全流程投资支持能力(从标的筛选到盈利预测)的 Frontier Finance 测试中,K3.1 Pro 相比 K3 亦有长足进步。
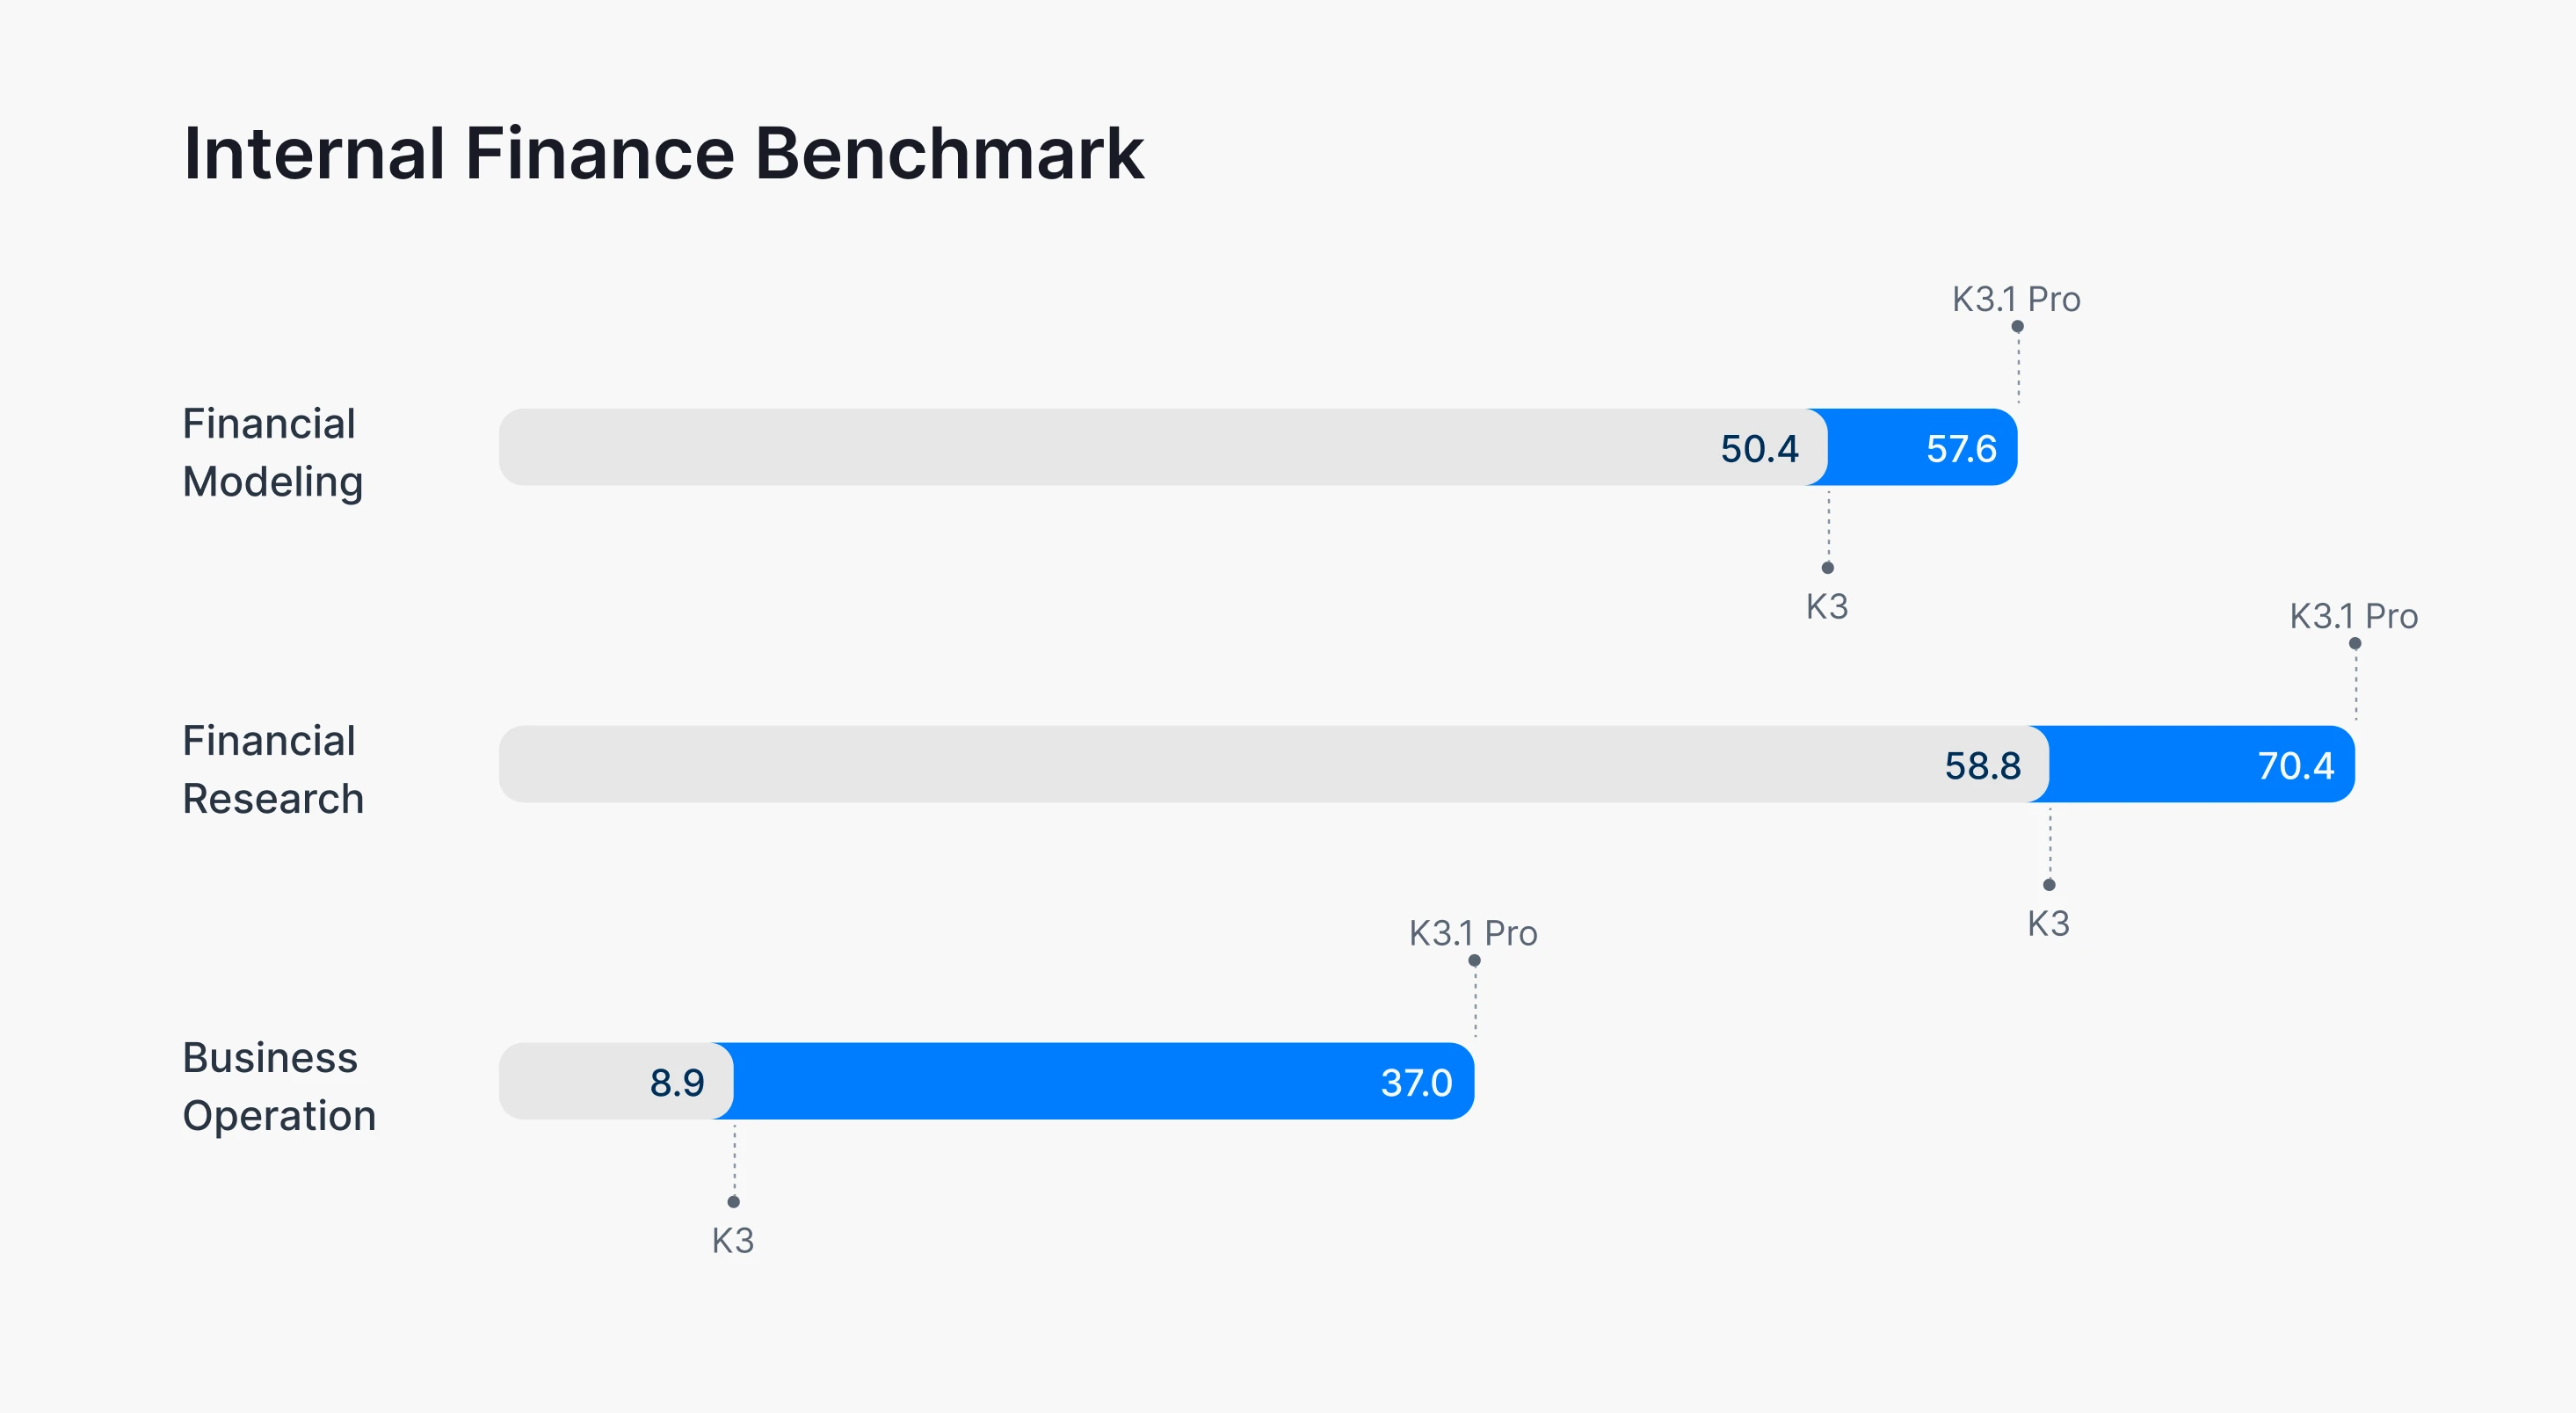
K3.1 Pro 在我们所有的内部金融基准测试中也展现出显著进步:
- 财务建模(Financial Modeling): 评估真实建模任务中的公式关联完整性、财务勾稽逻辑以及最终表格工件质量。K3.1 Pro 较 K3 提升了 7.2 分。
- 金融研报(Financial Research): 评估模型在给定证据和事实截断限制下生成可审计合规研报的能力。K3.1 Pro 较 K3 提升了 11.6 分。
- 商业运营决策(Business Operation): 评估在虚拟商业环境下的长程管理与商业决策能力。K3.1 Pro 达到了 K3 性能的约 4.2 倍。
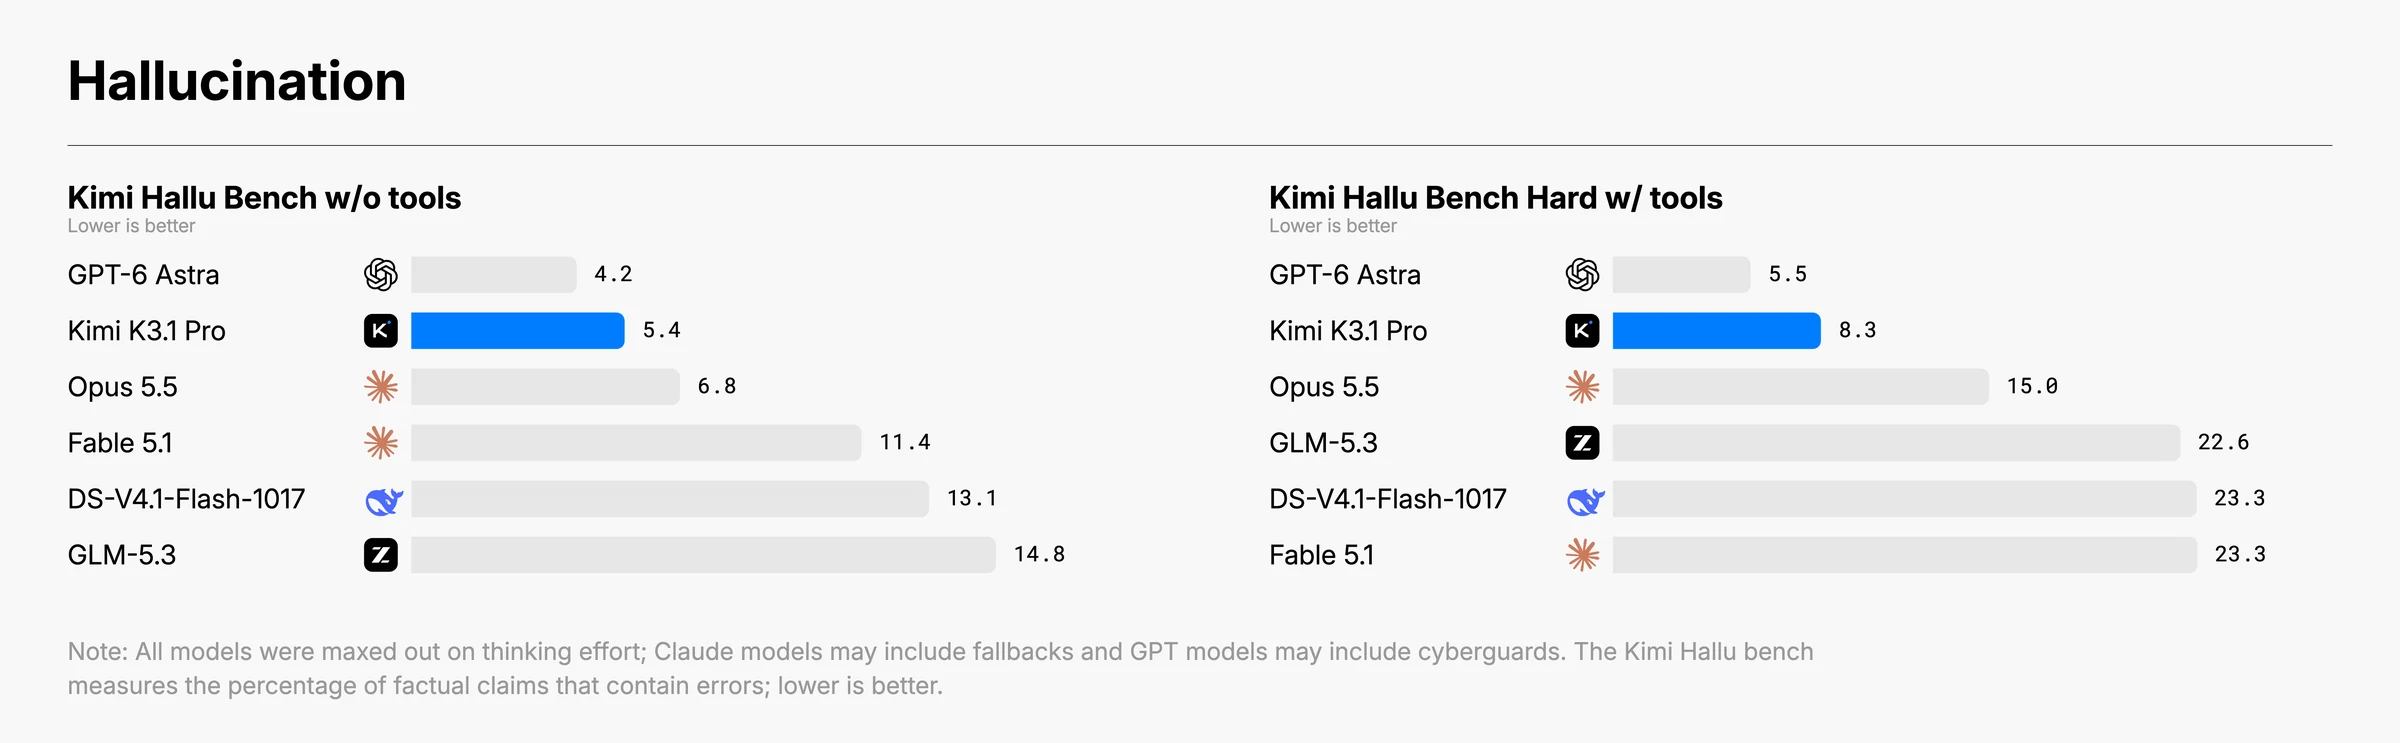
金融分析和投资研究对事实准确性有着极高要求。为此,我们针对真实任务与高难度提示词对 K3.1 Pro 的事实准确度进行了针对性强化。在专门用于极限压测事实准确性的内部评测 Kimi Hallu Bench Hard 上,其断言级(Claim-level)幻觉率从 K3 的 23.4% 骤降至 8.3%,且包含至少一处事实错误的回答比例仅为前代模型的 42.4%。(注:该评测为极端压力测试,样本经过刻意设计以激发模型易错点,公布数据并不代表日常通用场景下的总体错误率。)
下方案例展示了 K3.1 Pro 在实践中如何处理财务建模、投资分析以及附带信源依据的深度研究:
网络安全
随着 K3.1 Pro 能力的提升,我们投入了更多精力去理解其网络安全能力的来源,以及我们在多大程度上能够对其进行控制。因此,我们系统评估了 K3.1 Pro 的漏洞挖掘能力,并在训练过程中实施了精准的风控措施,以在保持通用实用价值的前提下降低潜在的滥用风险。
识别并剔除网络安全相关数据。 在研发过程中,我们发现随着后训练规模扩大,模型的漏洞挖掘性能出现了同步稳步提升。顺藤摸瓜后发现,安全相关内容天然存在于通用中间训练语料中,且强化学习环境中也混杂了部分安全任务——这是基于海量广泛数据训练的自然副产物。在内部模型的预备实验中我们观察到:若不在中间训练或强化学习阶段主动剔除数据,下游模型的网络攻击能力将大幅暴增。这一发现为我们提供了具体的控制抓手。针对 K3.1 Pro 的开源权重版本,我们在两个训练阶段均识别并剥离了攻击性安全数据,同时完整保留了维持模型实用性所需的通用编程任务。我们将在后续各个训练阶段持续推行此类针对性控制措施。
评测与实验结论。 在完成数据清洗后,我们在 xdev-bench-hard(我们自研的基于源代码的漏洞挖掘与利用评测基准,由专家精心整理,能在当前能力层级提供明确的区分度)上对 K3.1 Pro 进行了全面测试。该基准中绝大多数任务均真实复现了近期披露于 Linux 内核、Node.js、JavaScriptCore、Exim 与 VirGL 等开源软件中的真实漏洞,且均开启了缓解措施。每道任务提供存在漏洞的源代码、简明 Bug 提示以及对应编译二进制文件;Agent 必须独立构建有效利用链、在独立沙盒内实现任意代码执行并回传私密校验字符。我们统计随机子集运行下的 pass@3 表现,且不设硬性超时或输出 Token 限制。
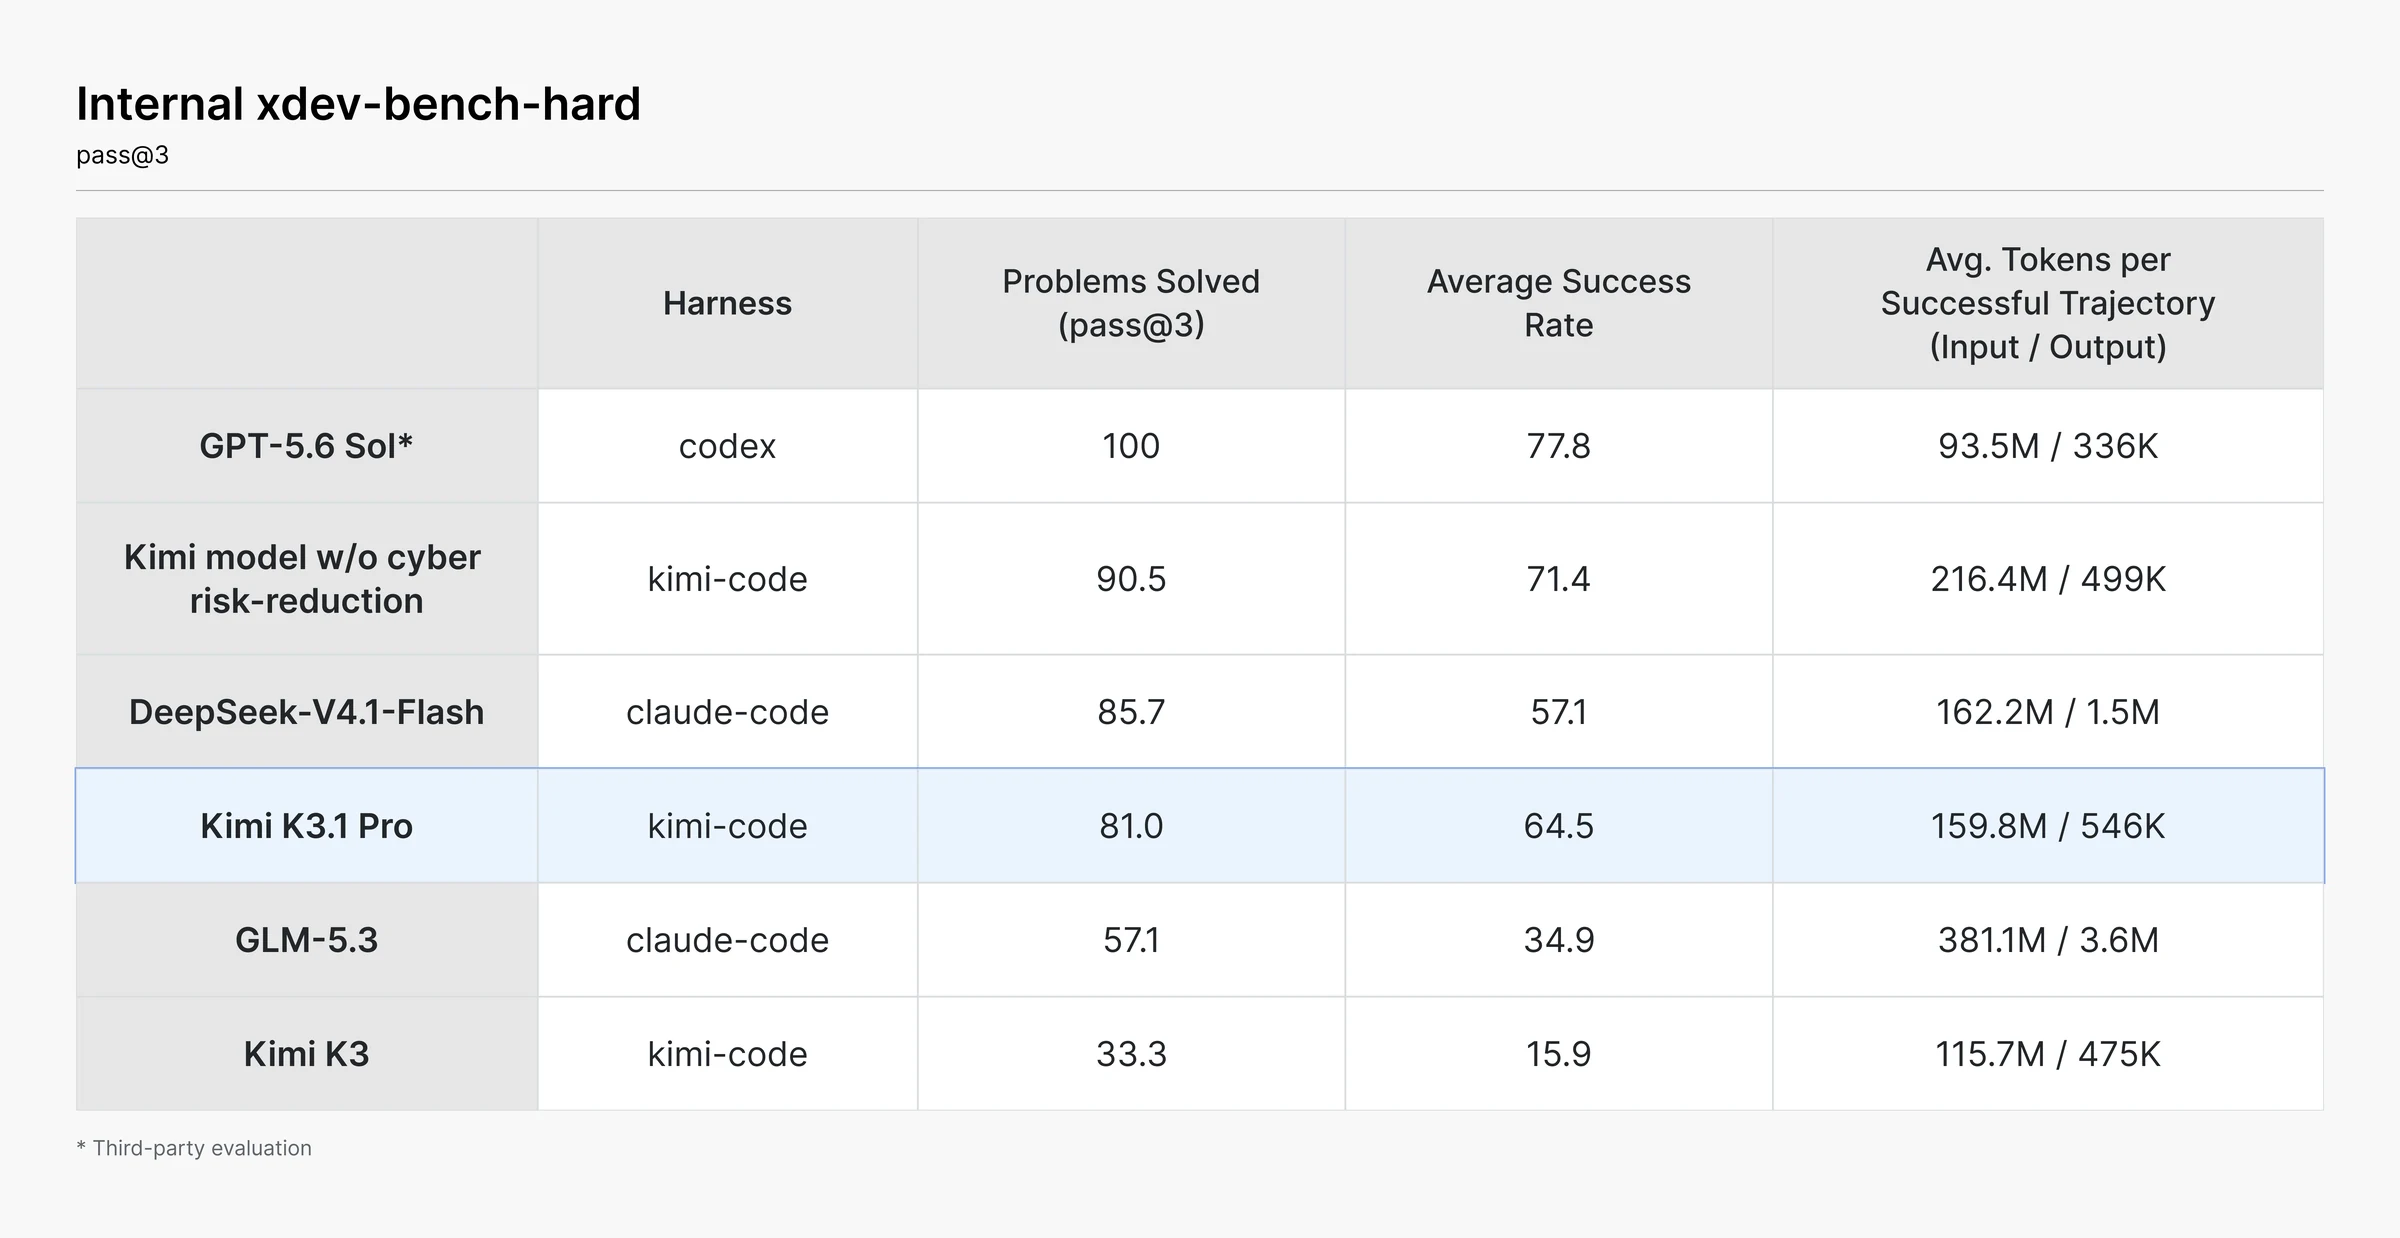
在 xdev-bench-hard 测试中,未采取任何降险措施的对照 Checkpoint(即在中间训练中未过滤安全数据、强化学习阶段亦未过滤安全环境)的 pass@3 解题率高达 90.5%;而最终发布的 K3.1 Pro 则降至 81.0%。这一对比证实:相较于同一训练管线本可达到的上限,数据清洗确实有效削减了模型的进攻性网络能力。与此同时,K3.1 Pro 的表现仍显著优于前代模型,这表明更强的通用编程与长程 Debug 能力在剔除特定数据后仍会泛化至网络安全任务。整体来看,K3.1 Pro 的网络安全能力依然处于已公开发布至少三个月的前沿专有商业模型之后。我们将持续演进内部基准测试,确保评测能够精准映射前沿能力的演进。
开源权重准则。 上述评测确立了我们开放模型权重的决策准则:第一,我们坚持不发布会突破进攻性网络安全绝对技术边界的开源权重。在设计上,K3.1 Pro 的进攻性网络能力被刻意压制在我们现有管线能力之下,并持续落后于顶尖闭源商业模型。第二,我们致力于逐步提升开源生态中可获取的安全防御能力。我们相信,以非歧视性方式开放 K3.1 Pro,能够惠及那些需要双重用途(Dual-use)能力来进行安全防御的用户。当一款高能力模型得以开源并在用户完全自主可控的基础设施上运行时,更多开发团队将有能力对其维护的代码开展深度安全审计——尤其是那些极少能获得专门安全团队审计的遗留系统。我们坚信,让这种技术能力有序扩散,而非垄断在少数专有系统手中,最终将让整个软件世界更加安全。
产品可用性
Kimi K3.1 Pro 即日起已在 Kimi 全系列产品矩阵上线:覆盖 Kimi.ai 与 Kimi 移动客户端、Kimi Work、Kimi Code 以及 Kimi API。
完整模型权重将于 2026 年 11 月 4 日前正式对外发布。
Kimi 企业版管理员 可在后台为主体组织启用 K3.1 Pro;该权限在上线初期默认处于关闭状态。
各渠道获取详情:
- Kimi Agents: 可在各大手机应用商店下载或更新至最新版 Kimi App(支持 iOS、Android 及 HarmonyOS),或直接访问 kimi.ai 使用。
English / 原文
We're introducing Kimi K3.1 Pro , the first model in our new K3.1 series and our most capable 3T-class open-weight model to date, with a 1-million-token context window. It delivers substantial improvements across coding, 3D creation, financial research, and other agentic capabilities.
We are also releasing Kimi K3.1 Pro Highspeed , which delivers 2-3× the speed of K3.1 Pro for more responsive interactions.
Kimi K3.1 Pro and Kimi K3.1 Pro Highspeed are available today on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API. The full model weights will be released by Nov 4.
Advancing the Frontier of Open Intelligence
Kimi K3.1 Pro is a post-trained version of Kimi K3, with substantially larger post-training compute. To enable large-scale joint RL across hundreds of downstream domains , we optimized every layer of the stack — the RL framework, long-context inference, training efficiency, sandbox infrastructure, rollout scheduling, and a shared platform for environment quality checks — so that each increment of RL compute delivers stable, predictable returns. As a result, K3.1 Pro achieves consistent gains in every domain.
Across coding, agentic, and knowledge benchmarks, K3.1 Pro matches or approaches the strongest proprietary models. On Terminal-Bench 4.0 , which evaluates coding agents on realistic, resource-constrained terminal tasks using strict task-specific tests, K3.1 Pro scores 65.7%, ahead of GPT-6 Astra (58.2%) and narrowly behind Claude Opus 5.5 (66.4%). And on Kimi Code Bench 3.0 Long-horizon , our internal benchmark that tests coding agents' multi-step execution, tool use, and end-to-end problem solving across diverse engineering domains, K3.1 Pro scores 61.2% , above K3's 55.95%.
Coding
K3.1 Pro covers the full range of coding work, from quick fixes in real codebases to full-project builds. It also brings a more considered visual style to games and web experiences, and knows how to build them with the right tools.
K3.1 Pro works effectively across game engines such as Unity, Unreal Engine, and Godot , combining them with web search and 3D generation to create complete experiences. Its front-end pages, interactive Three.js scenes, and 3D assets show stronger composition, typography, animation, and polish. The examples below were created end to end by K3.1 Pro:
K3.1 Pro's long-horizon coding capabilities are also strengthened through large-scale reinforcement learning. In one internal test, it built a human walking dynamics simulator with integrated training and evaluation pipelines on top of human-atlas, an open-source anatomical model of the human body comprising 296 skeletal components, including cartilage, and 402 muscle components. Across 167 missions and 420 independent reviews, it analyzed experimental results, diagnosed problems, and iteratively refined the walking controller, enabling the simulated human to go from collapsing within seconds to walking continuously with alternating strides for 11.2 seconds. When reward shaping failed to improve arm motion, K3.1 Pro did not simply keep adjusting the reward: it ran open-loop probes of the simulator's dynamics, identified and corrected 36 errors in shoulder-muscle moment-arm calculations, and then retrained the controller.
3D Modeling and Design
K3.1 Pro is strong at 3D creation and spatial reasoning. On BenchCAD , which tests 3D reconstruction from multi-view renderings through CAD code generation, K3.1 Pro scores 92.7% with tools , approaching the performance of Claude Opus 5.5 (96.2%) and GPT-6 Astra (95.9%). From a text brief, sketch, or reference image, it can infer shape, proportions, and spatial relationships to create usable 3D models. It also has a stronger grasp of existing asset libraries and model collections.
K3.1 Pro particularly excels at parametric modeling, from mechanical parts and architectural models to configurable products and custom furniture. Without MCP connectors, it can write and run scripts for tools like Blender and CAD software to build and refine assets, edit components, and adjust geometry, materials, and scene layout.
Below are examples of 3D assets K3.1 Pro created for brand films, games, and interactive web experiences:
3D Make is now live on kimi.ai and the Kimi app — preview and edit your 3D models online, download them ready for 3D printing, or export them as videos or Live Photos to share anywhere.
Finance
With stronger reasoning and agentic capability, K3.1 Pro is capable of end-to-end delivery of complete financial workflows. K3.1 Pro achieves state-of-the-art results on OfficeQA Pro v2 (64.4), which tests complex fiscal data analysis over real financial documents through retrieval, cross-document verification, and multi-step numerical reasoning. K3.1 Pro also improves over K3 on Frontier Finance, which measures support for complete investment workflows from screening to profitability analysis.
K3.1 Pro also improves significantly across all our internal finance benchmarks:
- Financial Modeling evaluates formula linkage, financial logic, and final workbook quality in real-world modeling tasks. K3.1 Pro improves on K3 by 7.2 points.
- Financial Research evaluates whether models can produce auditable research under evidence and cutoff constraints. K3.1 Pro improves on K3 by 11.6 points.
- Business Operation evaluates long-horizon management and decision-making in a simulated business environment. K3.1 Pro achieves about 4.2× K3's performance.
Financial analysis and investment research demand a high degree of factual accuracy. To address this, we made targeted improvements to K3.1 Pro's factual accuracy on real-world tasks and challenging prompts. On Kimi Hallu Bench Hard bench, an internal benchmark designed to stress-test factual accuracy, its claim-level hallucination rate fell from 23.4% for K3 to 8.3%, while the share of responses containing at least one factual error was just 42.4% of its predecessor's rate. (The evaluation is a stress test for factual accuracy, with examples deliberately crafted to probe situations where models are prone to errors. The reported rates do not represent overall error rates in daily use.)
The cases below show how K3.1 Pro handles financial modeling, investment analysis, and source-grounded research in practice:
Cybersecurity
As K3.1 Pro became more capable, we spent a correspondingly larger share of our effort understanding where cyber capability comes from, and how much of it we can control. We therefore analyzed and evaluated K3.1 Pro's vulnerability research capabilities, and applied targeted controls during training to reduce potential misuse risk while preserving general usefulness.
Identifying and removing cyber-related data. During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.
Evaluation and results. After data cleaning, we evaluated K3.1 Pro on xdev-bench-hard, our in-house benchmark of expert-curated, source-code-based vulnerability discovery and exploitation tasks, calibrated to provide meaningful differentiation at our current capability level. Most tasks faithfully reproduce recently disclosed vulnerabilities in software such as the Linux kernel, Node.js, JavaScriptCore, Exim, and VirGL, with mitigations enabled. Each task provides the vulnerable source code, a short bug hint, and the corresponding binary; the agent must develop an exploit, achieve arbitrary code execution in a separate sandbox, and retrieve a secret string for automated verification. We report pass@3 over a random subset of runs, with no hard timeouts or output token limits.
On xdev-bench-hard, the checkpoint without these risk-reduction measures — no cyber-related data removal at mid-training and no cyber-related RL environment filtering — solves 90.5% of problems at pass@3; the final K3.1 Pro reaches 81.0%. The comparison shows that data removal meaningfully reduces cyber capability relative to what the same training pipeline would otherwise produce. At the same time, K3.1 Pro improves substantially over its predecessor, indicating that stronger general coding and long-horizon debugging capabilities generalize to cyber tasks even after targeted data removal. K3.1 Pro's cyber capability remains behind that of frontier proprietary models that have been publicly available for at least three months. We will keep evolving our internal benchmarks so that evaluation stays informative as model capabilities continue to advance.
Open-weight principles. These evaluations frame our open-weight release decision. First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes. When a capable model is open and runs on infrastructure its users control, many more teams gain the means to audit the code they maintain — including legacy systems that rarely receive dedicated security reviews. We believe that letting this capability diffuse gradually — rather than concentrating it in a few proprietary systems — ultimately makes all software more secure.
Availability
Kimi K3.1 Pro rolls out today across the Kimi product family: on Kimi.ai and the Kimi mobile apps, Kimi Work and Kimi Code, and through the Kimi API.
Full model weights will be released by Nov 4, 2026.
Kimi Enterprise administrators can enable K3.1 Pro for their organization; access is off by default at launch.
Details for each channel:
- Kimi Agents: Download or update to the latest Kimi app from your mobile app store, available on iOS, Android, and HarmonyOS, or visit kimi.ai.
- Work with Kimi K3.1 Pro: Download the latest Kimi Work desktop app, version 3.1.0 or later, available for Windows and Apple silicon Macs.
- Code with Kimi K3.1 Pro: Run Kimi Code and select Kimi K3.1 Pro using the
/modelcommand. - Build with the Kimi API: Visit the Kimi API Platform and select kimi-k3.1-pro / kimi-k3.1-pro-highspeed. Zero Data Retention is available for API customers.
- Bring Kimi to your organization: Kimi Business provides enterprise-grade data privacy and member management, with complete separation between personal and organization accounts. Visit the pricing page and select “Get Kimi Business” to subscribe for your team.
Benchmarks
Unless otherwise specified, all Kimi K3.1 Pro results reported below are obtained with the reasoning effort set to 'max', temperature = 1.0, and top-p = 0.95.
Coding benchmarks
- Terminal-Bench 4.0. Kimi K3.1 Pro is evaluated with the Claude-Code harness. The DeepSeek-V4.1-Flash-1017 is taken from the release blog (https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017). All remaining scores are taken as the maximum value reported in either their blog posts or the official Terminal-Bench 4.0 leaderboard (https://www.tbench.ai/).
- Terminal-Bench Science 0.1. Kimi K3.1 Pro is evaluated with the Claude-Code harness. Our internal evaluation of DeepSeek-V4.1-Flash-1017 yields a score of 9.3; However, an older version, DeepSeek-V4.1-Flash, scores 15.7 on the official Terminal-Bench Science, so we report 15.7 here; all remaining scores are from the official Terminal-Bench Science leaderboard (https://www.terminal-bench-science.ai/).
- DeepSWE v1.1. Kimi K3.1 Pro is evaluated with the Claude-Code harness. All scores are taken from each model's respective technical report. GPT-6 Astra(https://openai.com/index/gpt-6-astra/). Claude Opus 5.5 and Claude Fable 5.1(https://www.anthropic.com/claude-opus-5-5-system-card and https://www.anthropic.com/claude-fable-5-1-mythos-5-1-system-card); DeepSeek-V4.1-Flash-1017 (https://api-docs.deepseek.com/news/news261017/); GLM-5.3 (https://z.ai/blog/glm-5.3).
- SWE-Marathon v1.1. Kimi K3.1 Pro is evaluated with the Claude-Code harness. DeepSeek-V4.1-Flash-1017 is evaluated with the ClaudeCode harness. All other scores are taken from the official SWE-Marathon leaderboard (https://www.swe-marathon.org/).
- PostTrainBench. Kimi K3.1 Pro and DeepSeek-V4.1-Flash-1017 were evaluated internally on v1.2 using the Claude-Code harness and H20 GPUs instead of H100 GPUs. For stable evaluation, all judge models used DeepSeek-V4.1-Flash-1017 at maximum effort, which best matched the official GPT-5.6-Terra (xhigh) judge in testing. Other scores are from the official leaderboard (https://posttrainbench.com/).
- ProgramBench (binary score). We report binary scores rather than raw ProgramBench scores: a task receives a score of 1 if its ProgramBench score is ≥95%, and 0 otherwise. Kimi K3.1 Pro is evaluated with the Claude-Code harness. The DeepSeek-V4.1-Flash-1017 and GLM-5.3 scores are taken from the release blog (https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017); all remaining scores are from the Vals ProgramBench leaderboard (https://www.vals.ai/benchmarks/programbench).
- Internal Coding Bench: Kimi Code Bench 2.0 and Kimi Code Bench 3.0 Long-horizon. Kimi K3.1 Pro is evaluated with Claude-Code harnesses; All other models are evaluated at their max-effort setting. Note that proprietary model testing may involve some fallback behavior.
- BenchCAD. Open models are evaluated by us on 1,000-case subsets randomly sampled from the full 17,900-case Vision2Code dataset, at maximum reasoning effort. With-tools results use the Claude Code harness; without-tools results use single-shot generation with the official BenchCAD prompts and scoring pipeline. Scores for Claude Fable 5.1 and Claude Opus 5.5 are taken from the Claude Opus 5.5 System Card; GPT‑6 Astra’s with-tools score is taken from its official report. GPT‑6 Astra has not reported a without-tools score and is marked “—”.
Agentic benchmarks
- BioMysteryBench dataset is drawn from the official v11 release, with Kimi K3 as the judge model. We evaluate Kimi K3.1 Pro with Kimi Code, GLM-5.3 and DeepSeek-V4.1-Flash-1017 with Claude Code, and GPT-6 Astra with Codex. Scores for the Claude models are taken directly from their official system cards.
- Our Agents’ Last Exam dataset is drawn from the official v1.1 release, comprising 122 tasks, including 86 CLI tasks, with environment images aligned with the official Hugging Face release. We additionally assign a score of zero to runs that bypass the task’s stated requirements, such as retrieving answers online instead of performing the required analysis in Wireshark. DeepSeek and Kimi are evaluated using Claude Code and Kimi Code, respectively. All other results are taken from the official benchmark website.
- OfficeQA Pro, OfficeQA Pro v2. GPT-6 Astra is evaluated with Codex, while all other models are evaluated with Claude Code. Each task provides the agent with the entire PDF corpus, with all PDFs rendered as images and no machine-readable text available. We observed instances in the trajectories of certain external models where they retrieved reference answers online; Consequently, we assigned a score of zero to these tasks.
- Frontier Finance is evaluated with the official finance agent v2 harness.
- HANDBOOK.md is evaluated using the official harness built on OpenHands, with evaluation tasks drawn from the benchmark’s early open-source v1 release.
- Harvey Legal Agent is evaluated on a public dataset of 1,251 tasks using Artificial Analysis’s Stirrup harness, with performance reported as the all-pass rate (i.e., the percentage of tasks that pass all rubric criteria).
- OSWorld V2.1 is evaluated with the Kimi Agent harness in the official OSWorld v2 repo, while GPT-6 Astra's score is taken from Muse Wonder's technical report.
- DECK-Arena evaluates presentation generation on real-world queries, while Design Bench covers graphic design via direct and reference-image few-shot prompting; Both run models across python-pptx, pptxjs, and Kimi's in-house DSL in a harness with integrated search and image generation, using an automated grader calibrated on 10,000+ human judgments.
- MCP Atlas. All models are evaluated on the 500-task public subset with a 100-turn limit, using Gemini 3.1 Pro as the judge.
- BrowseComp. We adopt the context-compaction strategy used in the Claude model cards, triggered at 200K tokens. We allow a maximum of 500 steps; if this limit is reached before a task is completed, we force the agent to provide an answer, which is then judged. All BrowseComp runs are conducted with temperature=1.0 and top-p=1.0.
- GDPval-AA v2.1, AA-Briefcase v1.1 and AutomationBench-AA scores are cited from https://artificialanalysis.ai/, Apex Agents scores are cited from https://www.mercor.com/apex/apex-agents-leaderboard/
- GDP.pdf w/ python, ZeroBench w/ python and ChartoGraphy w/ python are averaged over five runs. Other multimodal benchmarks (w/ python) are averaged over four runs. For GDP.pdf w/ python: Each original PDF file is sent to the sandbox, where the model can use IPython tool to process it. Final responses are graded against each rubric criterion using Gemini-3.5-Flash (medium reasoning effort) and the official judging prompt. We report the task-macro mean rubric pass rate: for each task, we average the fraction of rubric criteria passed over five independent runs, then average these task-level scores equally across all tasks.
Reasoning & Knowledge & Multimodal benchmarks
- GDP.pdf. Each PDF is provided as page images resized to a longest edge of 1,152 pixels, interleaved with Docling-extracted text in page order. Responses are graded against each rubric criterion using Gemini-3.5-Flash Medium and the official judging prompt. We report the strict pass rate among fully scored responses.
- HLE and HLE-Diamond evaluate general knowledge and reasoning capabilities. We report accuracy on the full evaluation sets, with 2,500 questions for HLE and 1,000 questions for HLE-Diamond. For models marked with an asterisk (*), accuracy is reported on the text-only subset of questions.
- GDP.pdf, ZeroBench and ChartoGraphy are averaged over five runs. Other multimodal benchmarks are averaged over four runs. GDP.pdf scores of GLM-5.3 Max and DeepSeek-V4.1-Flash-1017 Max is cited from https://artificialanalysis.ai/.
- MMMU-Pro is evaluated following the official protocol, preserving the original input order and prepending images to the text input.
- Kimi Hallucination Benchmark evaluates factual accuracy on an internal set of challenging, de-identified prompts drawn from practical work tasks. We report the claim-level hallucination rate assessed by fact-checking agents.
Cybersecurity benchmarks
- ExploitBench. Kimi K3.1 Pro is evaluated with the official ExploitBench harness under the 300-turn budget. We report the pass@5 max capability score: for each environment, the best run across 5 seeds, scored by the number of capability flags reached out of 16, where achieving arbitrary code execution counts as achieving all 16 capabilities. The GPT-6 Astra score is taken from https://openai.com/index/gpt-6-astra/; the Claude Opus 5.5 and Claude Mythos 5.1 scores are taken from https://www.anthropic.com/claude-opus-5-5-system-card; the GLM-5.3 score is taken from https://z.ai/blog/glm-5.3.
- ExploitGym. Kimi K3.1 Pro is evaluated with the KimiCode harness under a 6-hour wall-clock budget per task. The GPT-6 Astra score is taken from https://openai.com/index/gpt-6-astra/; the Claude Opus 5.5 and Claude Mythos 5.1 scores are taken from https://www.anthropic.com/claude-opus-5-5-system-card at the 6-hour budget; the GLM-5.3 score is taken from https://z.ai/blog/glm-5.3.
- xdev-Bench-hard: Kimi K3.1 Pro is evaluated with the KimiCode harness. GLM-5.3 and DeepSeek-V4.1-Flash-1017 are evaluated with the Claude Code harness.