Kimi K3.1 Pro 正式发布:性能紧咬前沿模型,全量权重即将开源
英文标题:Introducing Kimi K3.1 Pro
月之暗面(Moonshot)今日在 Kimi API 正式上线全新模型 Kimi K3.1 Pro,并承诺将在 2026 年 11 月 4 日前开源全量权重。该模型定价为输入 2 美元/百万 tokens、输出 10 美元/百万 tokens,价格仅为 Claude Opus 5.5 的一半,且在第三方机构 Artificial Analysis 评测中以 55 分超过了 GPT-6 Astra 与 Gemini 4 Argon。这是即将开源权重的模型首次在前沿水平测试中取得如此接近顶级闭源旗舰的成绩,为开发者提供了极具性价比的高性能模型新选项。
 197.8 KB
 90.5 KB
中文
2026 年 10 月 23 日 - 链接博客
Kimi K3.1 Pro 正式发布(来源)Kimi K3.1 Pro 今日已正式登陆 Kimi API——目前尚未开源权重,但月之暗面(Moonshot)承诺“全量模型权重将于 2026 年 11 月 4 日前发布”。
他们还提供了一个“高速”(Highspeed)版本,速度提升 2 至 3 倍,价格翻倍(但输入 token 缓存命中的计费保持一致)。
其美元定价为输入 2.00 美元/百万 tokens,输出 10 美元/百万 tokens——与 GPT-6.1 Sol 持平,且仅为 Claude Opus 5.5 的一半。
月之暗面自家的基准测试显示,Kimi 的水平大致与 Opus 5.5 和 GPT-6 Astra 相当——在少数几项测试中击败了它们,在其余测试中也紧随其后。
Artificial Analysis 给 Kimi 评分为 55 分——领先于 Claude Fable 5.1、GPT-6 Astra 和 Gemini 4 Argon(三者均为 53 分),仅次于 Claude Opus 5.5(58 分)。
这是(即将)开源权重的模型首次在前沿模型对比测试中取得如此高的分数。
我通过 Moonshot API 试用了该模型,使用的是我早在 8 月份添加到 LLM 0.32 中的 llm openai endpoint 命令:
llm openai endpoint
https://api.moonshot.ai/v1
--key kimi
-m kimi-k3.1-pro
"Generate an SVG of a pelican riding a bicycle"
--responses
-o reasoning_effort low \
kimi-k3.1-pro-pelican-low.stdout.txt
2> kimi-k3.1-pro-pelican-low.stderr.txt
llm openai endpoint 可以针对任何兼容 OpenAI 的端点运行提示词,但默认不记录结果,因此需要额外的参数来保存 stdout 和 stderr(即推理思考过程 trace)。
这里是 Kimi K3.1 Pro 在其支持的三种推理级别(低、中、最高)下生成的鹈鹕骑自行车 SVG 图像。以下是最高(max)级别的输出结果:
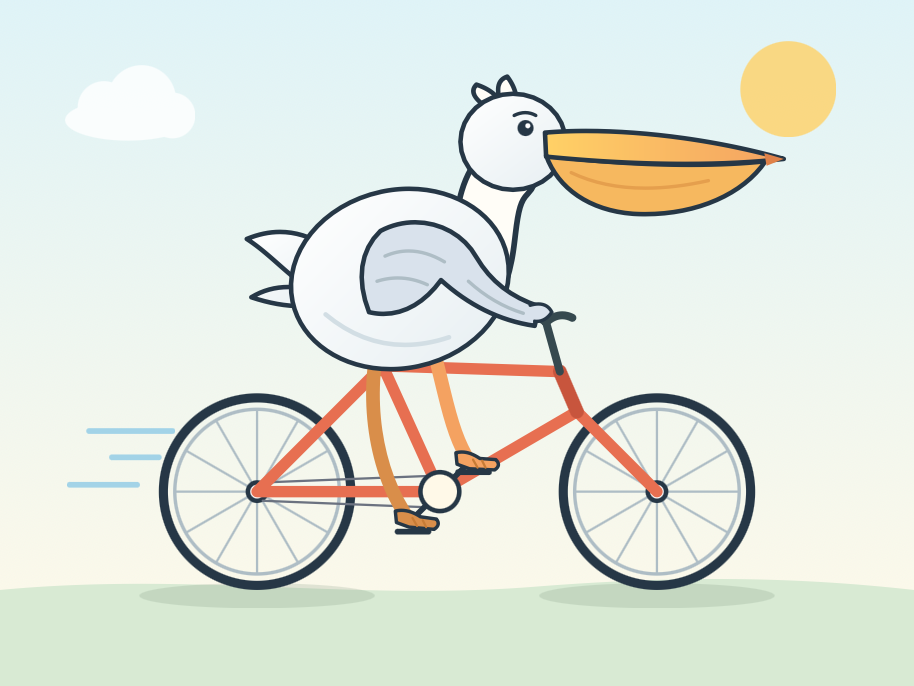
作为对比,我也让 Kimi K3 在这三个推理级别下生成了全新的鹈鹕图像。
English / 原文
23rd October 2026 - Link Blog
Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".
They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).
The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.
Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.
I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:
llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt
llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).
Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:
For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.