🔶 上下文图:AI 代理如何存储和利用过往决策
英文标题:🔶 Context graphs: how AI agents can store and use past decisions
文章指出AI代理在处理复杂业务决策时,常因上下文腐烂和缺乏决策痕迹而失败。上下文图将企业实体、关系及决策原因以图结构存储于代理记忆,使模型能遍历关联而非依赖扁平文本,从而解决信息分散和推理缺失问题。文中通过续费折扣等案例,展示了如何捕获决策时刻并形成可复用的决策痕迹,让代理能自主处理异常。该思路被风投机构视为万亿美元级机会,对开发者构建可靠的AI代理具有重要实践意义。
 1.9 KB
 411.7 KB
 116.4 KB
 73.6 KB
 118.1 KB
 174.5 KB
 412.5 KB
 29.9 KB
中文
在AI代理中,上下文图是代理记忆的一部分,专门用于捕获决策。
本文解释了为什么代理需要捕获决策、上下文图如何实现这一点,以及代理如何使用这些图。
一个代理失败案例
现在是季度的最后一周。一位续费代理正在处理一笔48万美元的账户。客户要求8折否则就走人。代理的指令规定>10万美元的账户不应流失,但代理的策略将续费折扣上限设定为10%。现在该怎么办?
如果是人类处理这件事,他们很可能会借助经验和记忆来解决。
我们上季度不是和Globex做过一模一样的事吗?情况差不多。他们威胁要流失,然后有人签字批准了20%的折扣,因为 这位CEO想留住财富500强的Logo,为了一笔30万美元的账户值得承担风险。结果成功了,Globex很快就续费了。
这个得出决策的推理链条并没有写在你代理能读取的任何地方。代理会在Salesforce里找到Globex的例外案例,但Salesforce不会告诉它那个数字是一个例外,是谁批准的、为什么批准,以及当前情况是否完全相同。
原因存在于——
- 旧的Slack聊天记录里,财务团队承认30万美元的账户值得冒这个风险。
- Zoom通话中,销售老兵提到这类账户最终都会付款。
- CEO的邮件里说保留财富500强Logo至关重要。
这些都是做出决策所需的关键信息,但代理无法访问它们。
于是你的代理会做以下两件事之一——
- 它发邮件告知策略上限是10%,然后你丢了账户。
- 它升级给人类,由人花24小时做Slack考古,重新组合出公司已经做过一次的决策。
无论哪种情况,组织都没有因采用AI代理而获益。
这是一个普遍问题。组织每年因以下原因损失数十亿美元——
- 重复犯同样的错误,
- 重复发明同样的解决方案,
- 在已解决的问题上浪费时间,
- 新员工入职极其缓慢,
- 在AI原生世界中艰难应对合规与审计缺口。
这是因为我们极其擅长记录发生了什么,却系统性地丢弃了为什么发生,而这恰恰是你的代理在此刻唯一需要的东西。
上下文图将原因存储在代理记忆中。
Foundation Capital将其称为「万亿美元级的AI机会」,这种措辞常让人想点返回按钮。但还是请留下来。这个术语虽然新且含义有些过载,但它指向某种真实存在。如果你使用或构建代理,你很快就会用上上下文图。
扁平上下文很糟糕
给AI代理提供上下文的糟糕方式,就是把所有数据、记录、文档、规则、策略一股脑塞进一个扁平的上下文窗口。
假设你有一个发票处理代理。你把发票、采购订单、供应商记录、合同、策略文档扔进上下文中。然后看代理失败。为什么?
1. 上下文腐烂
当代理问自己“我能支付发票#842吗?”,为了回答,它必须跳跃式地查询——这张发票引用了哪个采购订单?那个采购订单还有预算吗?送货是否已收货?供应商是否被暂停支付?12,400美元是否越过审批门槛?合同的支付条款怎么规定?策略文档是否准确且最新?目前Slack消息和Zoom通话记录里是否存在与这张发票支付相关的未记录的细微考量?
扁平检索试图将这些海量信息以一堆积木式的断块交给LLM模型。一段发票文字在这里,一段采购订单文字在那里,一些来自随机文档和Slack频道的语句,全部呈现为一面平直的文字墙。
“我能支付发票#842吗?”
______收件箱
A
Acme Billing
billing@acme.com · 周二 09:14
发票 #842 — $12,400.00 到期
您好,随函附上本月发票。条款按合同。
📎 invoice_842.pdf · 84 KB
SAP采购订单 · ME23N
PO编号7731
供应商Acme Corporation Ltd
净金额12,400.00
预算剩余3,600.00
收货已过账 · 3月12日
状态未清
W policy_v4.docx
应付账款审批政策
▸ 发票 ≥ $10,000 需经理签字
ap-ops
D
Dana 10:21
Acme总是季末付款——别催他们。
W
Wes 10:22
收到 👍 #842 先不动
▦ payment_hold.csv
| A · 供应商 | B · 暂停支付 |
|---|---|
| 1 | Acme Corporation Ltd |
| 2 | Globex LLC |
| 3 | Initech |
● REC 续费通话 · 转录 14:02
销售本次续费给了Acme Net-60。
应付主管 晚付了两次……但这是4万美元的账户。已批准。
代理在每一轮都被迫从零重新推导这些数据块之间的每一个联系。将业务数据压扁成松散文本,精确破坏了它所需的结构。
而随着上下文变得庞大,LLM难以应对这种体量,开始在任务中失败。它们不遵循指令,随机丢弃规则,误解相距较远的两段信息之间的关系,忽略中间-上下文数据,规则与约束的应用顺序错乱。
Surge AI在其指令遵循基准测试中记录了这一点。最好的前沿模型在此类复杂任务上的正确率<41%。
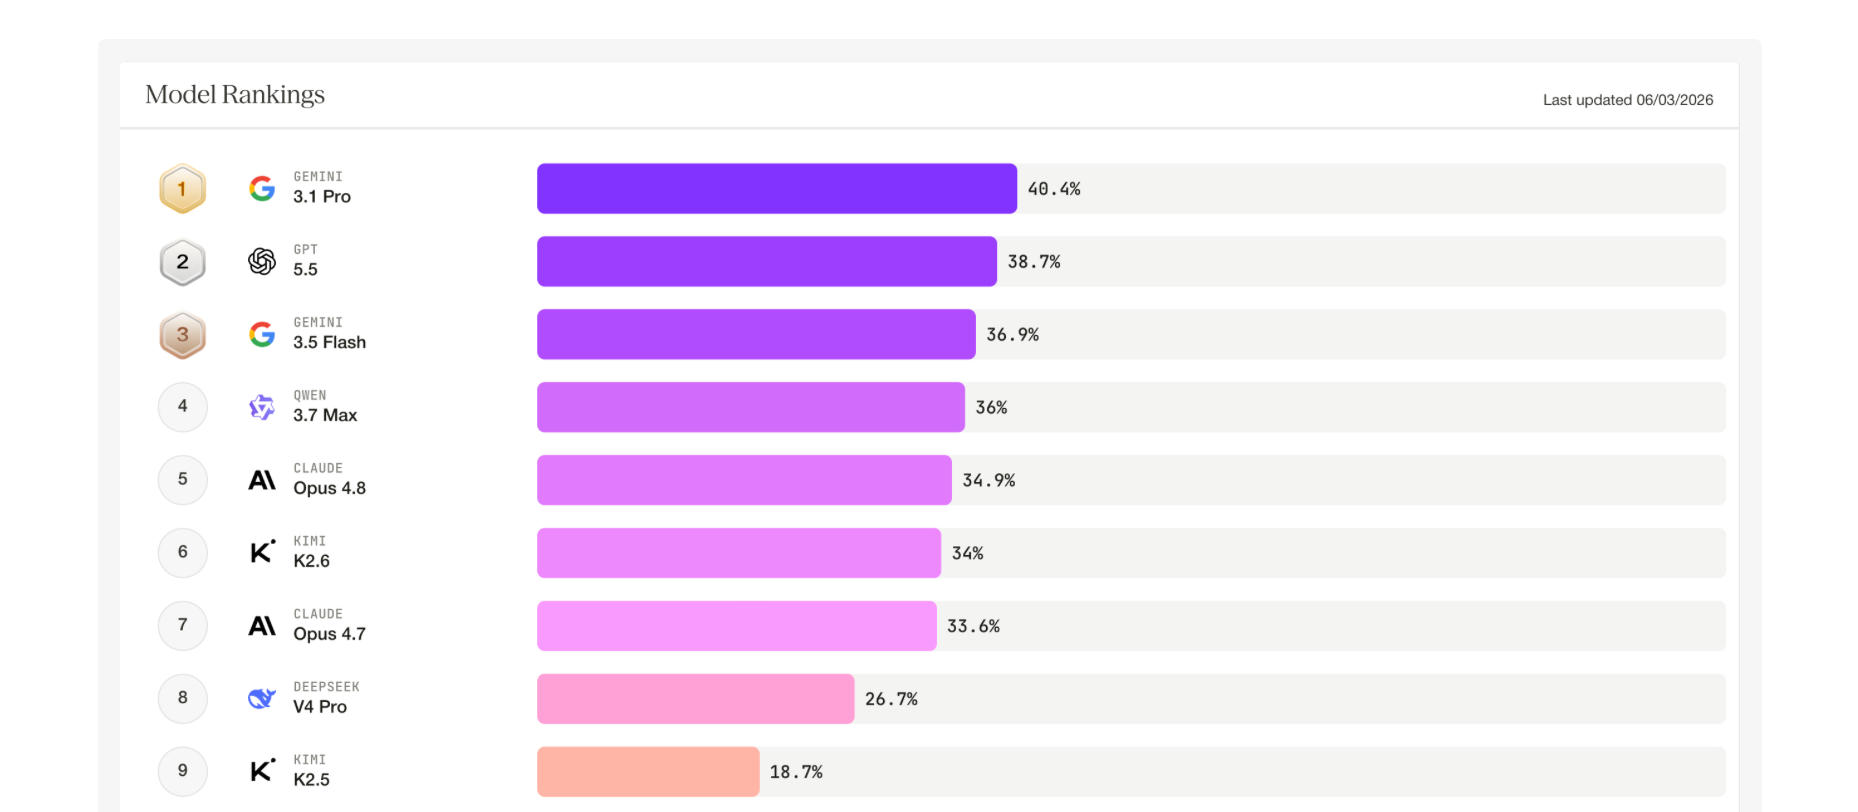 复杂任务指令遵循基准测试
2. 缺乏决策痕迹
就像我们在第一个例子中看到的那样,AI代理会遇到与人类每天用先例、经验、组织记忆解决的相同歧义。但你无法将这些一股脑塞进扁平的上下文窗口交给代理。
- 隐性知识。 “我们通常免除物流公司5千美元的上线费用,但仅限他们先在时间线上提出异议的情况下。”这不在CRM里。这是通过内部交流流传下来的隐性知识。
- 过往决策。 “我们为客户X构建了一个分期付款的交易。我们应该给类似的客户Y提供同样的方案。”没有系统将两笔交易联系起来,以传达Y的合同为何这样拟定。
- 跨记录系统的上下文。 客户经理在产品仪表盘看到用量下滑,在NetSuite看到未付发票,还有一封冷淡的单行邮件。他们在CRM中将账户标记为“流失风险”。推理发生在他们脑中,但CRM记录只显示“流失风险”。
- 人工审批。 一位VP在Zoom通话中批准了一个折扣。HubSpot记录显示了更改后的价格。它没有显示为什么做出这个决策。
数据、决策、行动背后的推理,并未被捕获进扁平的上下文窗口。
如果你是开发者,这个概念的冲击更强烈。为什么我们在2019年选了那个队列而不是这个?为什么重试路径里有一个 sleep(200),去掉它就会搞垮一切?写这段代码的人一清二楚,但这些信息现在消失了。
还记得架构决策记录吗?它们早在2011年就被发明来修复这一问题。但大多数ADR文件夹在三条记录后就止步了,因为编写它们是种摩擦,而且之后没人再读。
这是一个普遍问题。公司擅长存储发生了什么,却不擅长存储为什么发生。这是因为原因是非结构化的,分散在各系统间,即使你存了也没人会读。
这两个问题——上下文腐烂和缺乏决策痕迹——都由上下文图解决。
什么是上下文图?
上下文图是一种将代理记忆结构化为图的方式,其中节点承载信息片段,边承载它们之间的关系。它被优化用于代理读取,而非人类浏览。
今天大多数代理记忆是扁平的。AI代理嵌入你的数据,将它们分割成块,并返回与当前任务看起来最相似的几个块。LLM拿到一堆文字,却无从得知这些块如何彼此关联。这就是向量RAG,如今AI代理使用的标准记忆。
上下文图保留了这些连接。它不是“这儿有五个相似的段落”,而是能说“服务A –依赖于–> 服务B”,“这次发布 –导致–> 那次故障”,或者“这张发票 –遵循–> 那条策略”。边承载着含义,模型可以遍历它们。
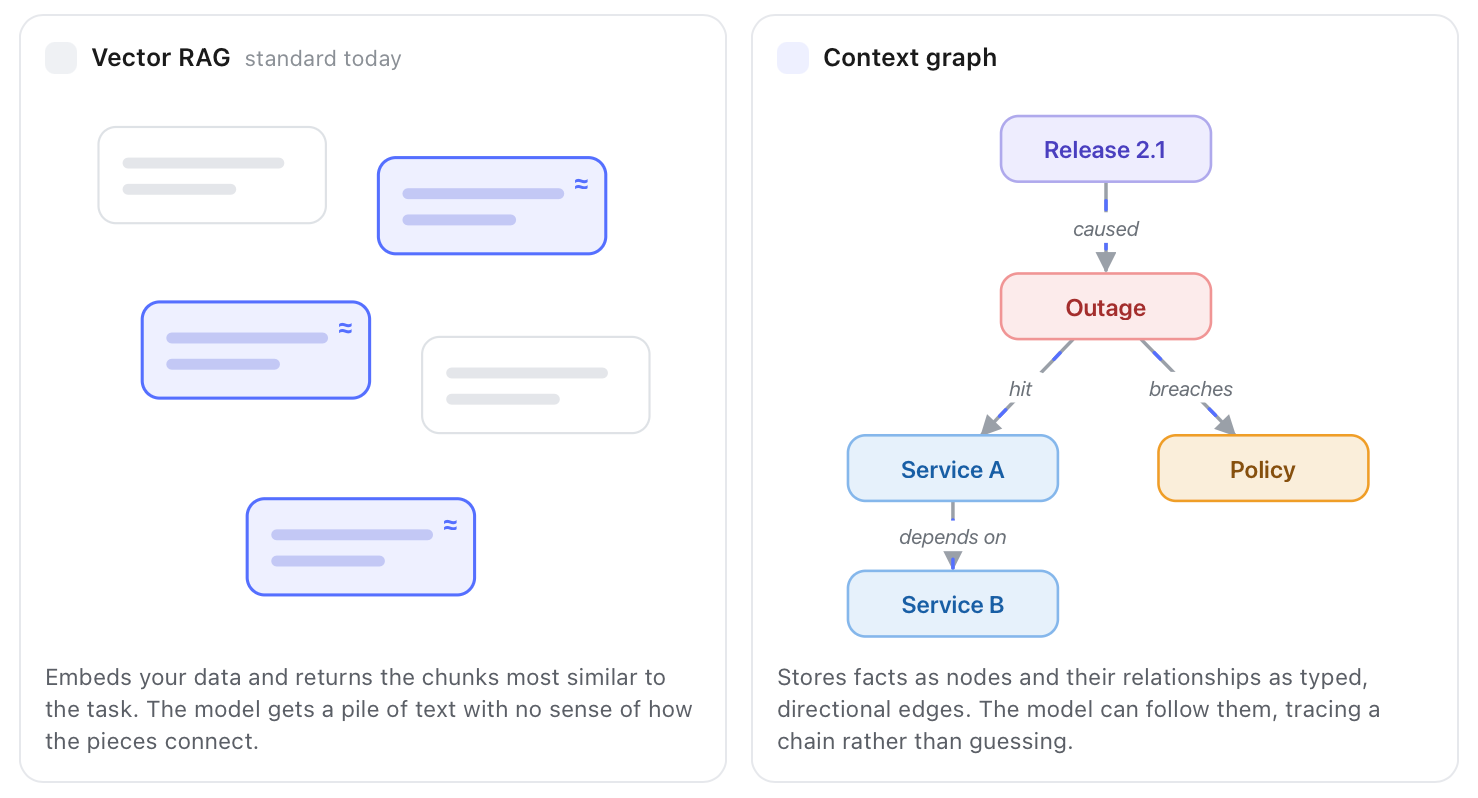
这很重要,因为相似不等于相关。两个块可以与你的任务共享词汇,却与你的实际任务毫无关系。另外两个块可以与你的任务没有任何共同词汇,却在语义上仍与你的任务相关。
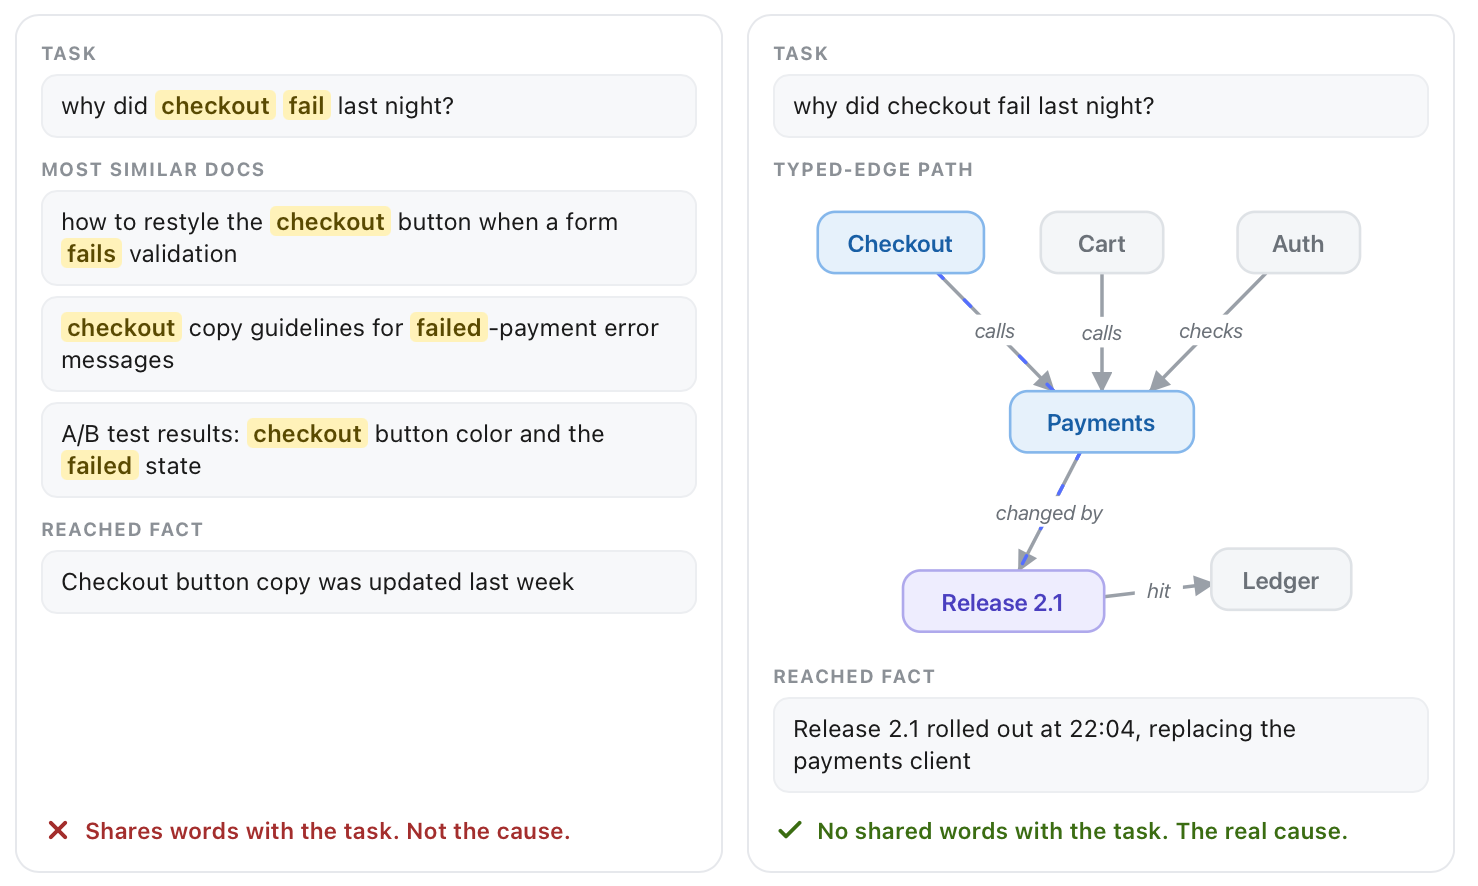 带类型的边告诉代理两个事物如何相关,这样它就能追踪一条链条,而不必从词汇重叠中推断关系。
如何创建上下文图?
上下文图通过改变你存储的内容和方式,来解决上下文腐烂和缺乏决策痕迹这两大失败。
从“如何存储”开始。你将业务存储为一个图。实体,比如发票、采购订单、账户、供应商、合同、策略、审批人,都是上下文图中的节点。它们之间的关系是边。这张发票 –引用–> 那个采购订单。这个采购订单 –提取自–> 那个预算。这个预算 –由……批准–> 那个人。这个供应商 –受治于–> 那个合同。
“我能支付发票#842吗?”
你将每个链接只存储一次,而不是每次需要时都让模型从文字块中重新推导。对每一个任务/子任务,代理拉取一个小个子图,把其他一万条记录留在窗口之外。上下文腐烂消失了,因为窗口保持小巧且切中要点。
现在来看“存储什么”。你现在也将每一个决策存储在上下文图中。这个上下文图的单位将是一个决策痕迹。扁平记录止步于结果“Initech以20%续签”。而一个决策痕迹保留其背后的故事:触发它的问题、权衡过的选项、被拒绝选项落选的原因、约束条件、例外、决策者以及推理过程。
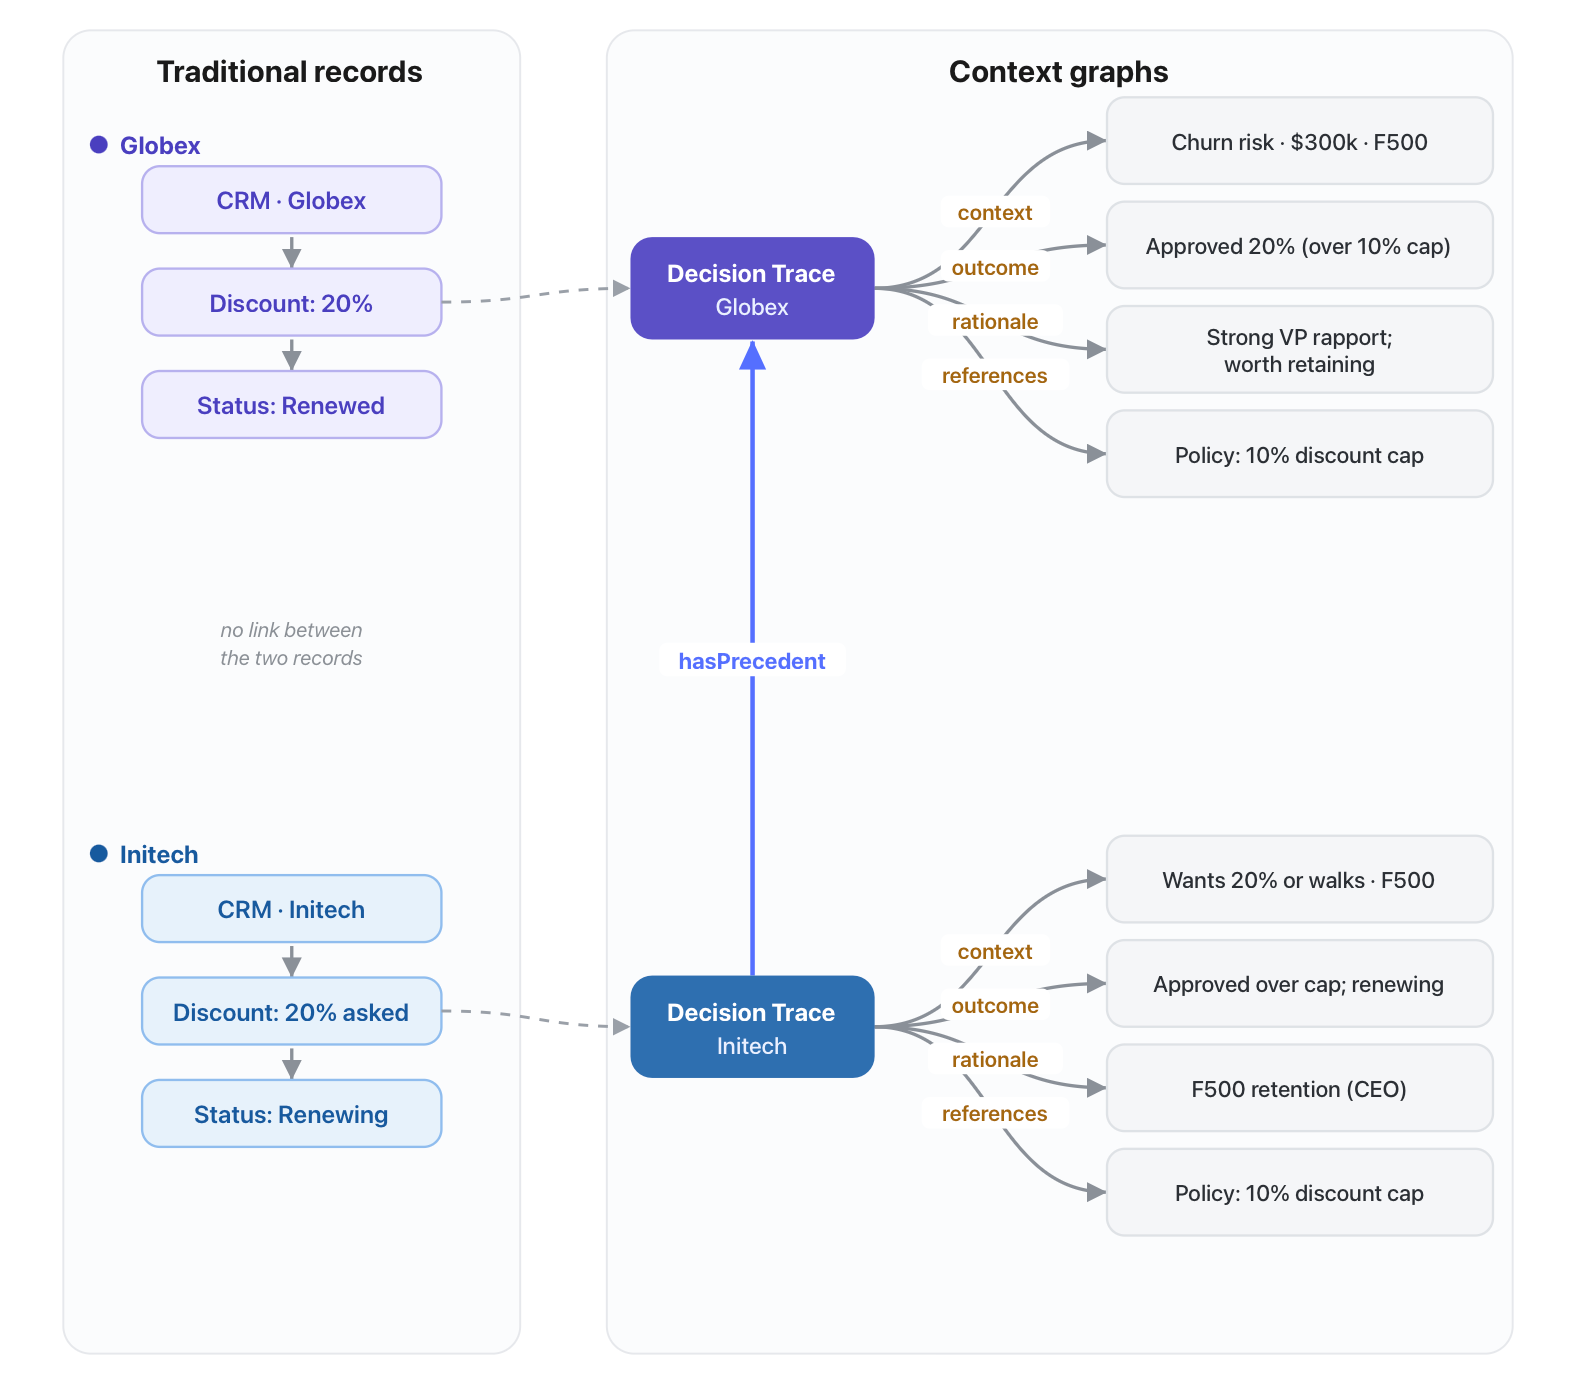 这也是员工头脑中保留的东西。但借助决策痕迹构成的上下文图,代理可以读取它。
实体及其关系,加上决策及其与实体和其他决策的关系,跨越记录系统和时间被创建出来。Foundation Capital对其的一句话概括是「决策的记录系统」。你的多数系统已经存储了事物的当前状态。上下文图存储了状态是如何变成这样的。
你为决策痕迹使用一个最适合你用例的schema。
现在,后半部分是将旧决策转化为代理可以依靠的资源。
如何使用上下文图?
使用上下文图时的一些实现细节——
在入口处捕获
拥有上下文图的代理需要低摩擦,否则没人愿意维护它们。在决策做出的那一刻就将其捕获,而不是以后。
在决策之后重建上下文将是丢失信息的猜测,而且成本高昂且耗时。会议结束了,Slack讨论串滑走了,当事人离开了公司。代理的大部分上下文已经溜走,没有被保存到代理记忆中。
在决策做出时就捕获它,几乎无需额外努力。所有上下文已经存在于活跃的上下文窗口中。此外,如果人类覆盖了代理的决策,那个覆盖瞬间正是询问原因并以最小人工摩擦存储答案的时机。
在入口处捕获决策
场景 1 / 4
事后重建
决策时刻
ZOOM · 续费电话
“这么大的账户值得冒风险。批准20%。”
SLACK · #续费
“Globex威胁要走除非我们打破10%上限。” · 3条回复
EMAIL · CEO
“保留所有财富500强客户。不要因为折扣丢一个。”
此时的上下文
SLACK
讨论串滑走
已埋没
审批人已离职
已消失
→
依靠记忆编写的维基页面
Globex以20%续签。
理由:
“已批准,见Slack”
批准人:
???
代理 · 在执行路径中
活跃上下文窗口
CRM
Initech · 500强 · 30万美元续费 · 流失风险
SLACK
“他们要20%否则就走”
先例
DEC-2025-118 · Globex · 20% 已批准
→
决策已定
批准20%,高于10%上限。引用 DEC-2025-118。标记为500强留存。
→
上下文图
DEC-2026-042
上下文:
500强 · 流失风险 · 30万美元
结果:
20%(上限例外)
理由:
保留Logo值得冒风险
链接:
DEC-2025-118, 策略 v4
工作的副作用 ✓
代理提议
提议
按10% (策略上限)续签Initech。
→
人类覆盖
覆盖 · 销售VP
改为20% 并批准。
代理:为什么覆盖? “500强Logo。30万美元值这个风险。”
→
已存储、已关联、可复用
DEC-2026-042 · 人类覆盖
代理提议:
10%(上限)
人类决定:
20%
理由:
500强Logo留存,CEO指令
决策人:
销售VP
下个季度,代理自己提议20%。
旧的组织记忆
维基
上次编辑14个月前
CONFLUENCE
47页,本季度0次浏览
事后复盘
从未被再次打开
ADR文件夹
2022年止步于3条记录
编写是摩擦没人回读
vs
执行路径中的代理
0
每次运行参考的过往决策
捕获: 工作的副作用 读取: 每次运行,不知疲倦
最小摩擦有人读取
这也是为什么代理改变了组织记忆的经济学。我们一直
English / 原文
In AI agents, a context graph is the part of agent memory that captures decisions.
This post explains why agents need to capture decisions, how context graphs achieve this, and how agents can use these graphs.
An agent failure case
It's the last week of the quarter. A renewal agent is working a $480k account. The customer wants 20% off or they walk. The agent's instructions state >$100k accounts should not churn, but the agent's policy caps renewals at 10%. Now what?
If a human was handling this, they'll probably use experience and memory to resolve.
Didn't we do this exact thing with Globex last quarter? It was a similar story. They were threatening to churn, and someone signed off on 20% because the CEO wanted to retain Fortune 500 logos and the risk was worth taking on a $300k account. It worked and Globex renewed shortly after.
This reasoning chain that makes the decision is not written down anywhere your agent can read. The agent will find Globex's exception case in Salesforce, but Salesforce will not tell it that the number was an exception, who approved it, why it was approved, whether the current situation is identical or not.
The why lives in -
- Old slack threads where finance team admits a $300k account is worth the risk.
- Zoom calls where sales veterans mention these kind of accounts pay eventually.
- Emails from the CEO saying retaining Fortune-500 logos is critical.
These are critical pieces of information needed to make the decision, but the agent cannot access them.
So your agent does one of two things -
- It sends an email informing the policy caps at 10%, and you lose the account.
- It escalates to a human, who spends 24 hours doing Slack archaeology to reconstruct a decision the company already made once.
Either way, the organization failed to benefit by adopting an AI agent.
This is a universal problem. Organizations lose billions each year -
- making the same mistakes,
- reinventing the same solutions,
- wasting time on previously solved problems,
- being incredibly slow at onboarding new employees,
- struggling with compliance and audit gaps in an AI-native world.
This is because we have gotten extremely good at recording what happened, but we systematically throw away why it happened, which is the one thing your agent needed here.
Context graphs store the why in an agent's memory.
Foundation Capital called it "a trillion-dollar AI opportunity", which is the kind of phrase that sends people reaching for the back button. But stick around anyway. The term is new and a little overloaded, but it points at something real. If you use or build agents, you'll end up using a context graph soon.
Flat context is bad
The bad way to give your AI agents context is to just give them all the data, records, documents, rules, policies in a flat context window.
Say you have an invoice processing agent. You dump the invoice, PO, vendor record, contract, policy document into the context. Then watch the agent fail. Why?
1. Context rot
When the agent asks itself “can I pay invoice #842?” To answer, it has to hop - which PO does this invoice reference? does that PO still have budget? was the delivery received? is the vendor on payment hold? does $12,400 cross the approval threshold? what do the contract's payment terms say? is the policy doc accurate and up-to-date? are there undocumented nuances related to this invoice payment currently living on Slack messages and Zoom call transcripts?
Flat retrieval tries to hand this massive amount of information to the LLM model in a pile of disconnected chunks. Some invoice text here, some PO text there, some language from random docs and slack channels, all given as a flat wall of text.
“Can I pay invoice #842?”
______Inbox
A
Acme Billing
billing@acme.com · Tue 09:14
Invoice #842 — $12,400.00 due
Hi, attaching this month’s invoice. Terms per contract.
📎 invoice_842.pdf · 84 KB
SAPPurchase Order · ME23N
PO Number7731
VendorAcme Corporation Ltd
Net Amount12,400.00
Budget left3,600.00
Goods receiptPosted · 12 Mar
StatusOpen
W policy_v4.docx
AP Approval Policy
▸ Invoices ≥ $10,000 need manager sign-off
ap-ops
D
Dana 10:21
Acme always pays end of quarter — don’t chase them.
W
Wes 10:22
noted 👍 leaving #842 as-is
▦ payment_hold.csv
| A · Vendor| B · On hold
---|---|---
1| Acme Corporation Ltd| No
2| Globex LLC| Yes
3| Initech| No
● REC Renewal call · transcript 14:02
Sales Gave Acme Net-60 this renewal.
AP lead Paid late twice… but it’s a $40k account. Approved.
The agent is forced to re-derive every one of those connections between these pieces of data from scratch on each turn. Flattening business data into loose text destroys exactly the structure it needs.
And as context becomes large, LLMs struggle to cope up with the size and start failing in their tasks. They fail to follow instructions, drop rules randomly, misunderstand the relation between two pieces of information far apart, ignore middle-of-context data, apply rules and constraints out of order.
Surge AI documents this in their instruction-following benchmark. The best frontier model solves <41% of such complex tasks.
Instruction-following benchmark on complex tasks
2. Lack of decision traces
Like we saw in our first example, AI Agents run into the same ambiguity humans resolve every day with precedents, experiences, organizational memory. But you can't give these things to an agent in a flat context window.
- Tribal knowledge. "We always waive the $5k onboarding fee for logistics companies but only if they push back on the timeline first." That's not in the CRM. It's tribal knowledge passed down through internal conversations.
- Past decisions. "We structured a deal for account X where they split payments into installments. We should offer this similar account Y the same." No system links the two deals to convey why Y's contract was drafted this way.
- Context across systems of record. An account manager sees usage sliding in the product dashboard, an unpaid invoice in NetSuite, a cold one-line email. They flag the account as "churn risk" in the CRM. The reasoning happened in their head, but the CRM record just shows "churn risk".
- Manual approvals. A VP approves a discount on a Zoom call. The Hubspot record shows the changed price. It doesn't show why this decision was made.
Reasoning behind data, decisions, actions isn't captured in a flat context window.
If you are a developer, this concept hits even harder. Why did we pick this queue over that one in 2019? Why is there a sleep(200) in the retry path that breaks everything when you remove it? It was obvious to whoever wrote it, but that information is gone now.
Remember Architecture Decision Records? They were invented back in 2011 to fix exactly this. But most ADR folders die at three entries, because writing them is friction and nobody reads them later.
This is a universal problem. Companies are good at storing what happened, and bad at storing why they happened. This is because the why is unstructured, spread across systems, and nobody reads it even if you store it.
Both problems, context rot and lack of decision traces, are solved by context graphs.
What is a context graph?
A context graph is a way of structuring an agent's memory as a graph, where nodes hold pieces of information and edges hold the relationships between them. It's optimized for the agent to read, not for a human to browse.
Most agent memory today is flat. AI agents embed your data, split them into chunks, and return the few chunks that look most similar to the ongoing task. The LLM gets a pile of text with no sense of how these chunks connect to one another. This is vector RAG, the standard memory used in AI agents today.
A context graph keeps those connections. Instead of "here are five similar paragraphs," it can say "Service A –depends on–> on Service B," "this release –caused–> that outage," or "this invoice –follows–> that policy." The edges carry meaning, and the model can traverse them.
This matters because similarity is not relevance. Two chunks can share words with your task and still have nothing to do with your actual task. Two other chunks can share no words with your task and still relate to your task semantically.
A typed edge tells the agent how two things relate, so it can trace a chain instead of inferring the relationship from word overlap.
How to create a context graph?
A context graph goes after both failures, context rot and lack of decision traces, by changing what you store and how.
Start with "how you store". You store your business as a graph. Entities, for example, the invoice, the PO, the account, the vendor, the contract, the policy, the approver, are all nodes in the context graph. The relationships between them are edges. This invoice –references–> that PO. This PO –draws on–> that budget. This budget –approved by–> that person. This vendor –governed by–> that contract.
“Can I pay invoice #842?”
You store each of those links once, instead of leaving the model to re-derive them from chunks of text every time it needs them. For each task/subtask, the agent pulls a small subgraph and leaves the other ten thousand records out of the window. Context rot goes away, because the window stays small and on-point.
Now the "what you store". You now also store each decision in a context graph. The unit of this context graph will be a decision trace. A flat record stops at the outcome "Initech renewed at 20%". A decision trace keeps the story behind it. The problem that triggered it, the options weighed, why the rejected ones lost, the constraints, the exceptions, who decided, and the reasoning.
This is also what an employee keeps in their head. But with a context graph of decision traces, an agent can read it.
Entities and their relationships, plus decisions and their relationships to entities and other decisions, created across systems of record and time. Foundation Capital's one-liner for it is a "system of record for decisions ". Most of your systems already store the current state of things. A context graph stores how the state got that way.
You use a schema for the decision trace that is ideal for your use case.
Now the second half is turning old decisions into something the agent can lean on.
How to use a context graph?
Few implementation details when using context graphs -
Capture it on the way in
Agents with context graphs need to be low friction, otherwise no one will want to maintain them. Capture the decision the moment it is made, not later.
Reconstructing context after the decision will be lossy guesswork, and also costly and time consuming. The meeting is over, the Slack thread scrolled away, the person left the company. Most of the agent's context has slipped away without getting saved in the agent memory.
Capture it when the decision is made, at almost no extra effort. All of the context is already there in the active context window. Also if a human overrides the agent's decision, that override is the moment to ask why and store the answer with minimal friction from the human.
Capture the decision on the way in
SCENE 1 / 4
Reconstructing it later
THE DECISION MOMENT
ZOOM · RENEWAL CALL
"Accounts this big are worth the risk. Approve 20%."
SLACK · #RENEWALS
"Globex is threatening to walk unless we beat the 10% cap." · 3 replies
EMAIL · CEO
"Retain all our Fortune 500 accounts. Don't lose one over a discount."
THE CONTEXT NOW
SLACK
thread scrolled away
buried
approver left the company
gone
→
THE WIKI PAGE, WRITTEN FROM MEMORY
Globex renewed at 20%.
Rationale:
"approved, see Slack"
Approved by:
???
AGENT · IN THE EXECUTION PATH
ACTIVE CONTEXT WINDOW
CRM
Initech · F500 · $300k renewal · churn risk
SLACK
"they want 20% or they walk"
PRECEDENT
DEC-2025-118 · Globex · 20% approved
→
DECISION MADE
Approve 20%, above the 10% cap. Cites DEC-2025-118. Logged as F500 retention.
→
CONTEXT GRAPH
DEC-2026-042
context:
F500 · churn risk · $300k
outcome:
20% (exception to cap)
rationale:
logo worth the risk
links:
DEC-2025-118, policy v4
a side effect of the work ✓
AGENT PROPOSES
PROPOSAL
Renew Initech at
10%
(policy cap).
→
HUMAN OVERRIDES
OVERRIDE · VP SALES
Changed to
20%
and approved.
Agent: why the override?
"F500 logo. Worth the risk at $300k."
→
STORED, LINKED, REUSABLE
DEC-2026-042 · human override
agent proposed:
10% (cap)
human decided:
20%
rationale:
F500 logo retention, CEO directive
decided by:
VP Sales
Next quarter, the agent proposes 20% itself.
OLD ORGANIZATIONAL MEMORY
WIKI
last edited 14 months ago
CONFLUENCE
47 pages, 0 views this quarter
POST-MORTEMS
never reopened
ADR FOLDER
died at 3 entries in 2022
writing it is friction nobody reads it back
vs
AGENT IN THE EXECUTION PATH
0
past decisions consulted per run
capture: side effect of the work
reading: every run, tirelessly
minimal friction someone reads it
This is also why agents change the economics of organizational memory. We have always known we lose the why. Wikis, Confluence, post-mortems, ADRs: every one of them tries to save it, and every one decays, for the same two reasons. Writing it down is friction, and nobody reads it back.
Agents break both at once. The agent sits in the execution path, so capture is a side effect of doing the work, not an extra task bolted on afterward. And the agent is a tireless reader that will happily consult ten thousand past decisions before making the next one. Organizational memory finally has a reader worth writing for.
Use stored decisions as precedent
Once decisions live in the graph, search turns them into precedent.
- a new decision choice shows up
- the agent pull the direct context (entities and their relationships)
- the agent pulls the closest precedents (past decisions)
- the agent reasons on the direct context and precedents
- the agent takes a decision (or suggests it)
- decision is taken
- decision is stored as a decision trace in the context graph
- decision is linked to similar past decisions in the context graph
You can use vector embeddings to find semantically similar decisions, and then apply graph-based filters to narrow by entity properties.
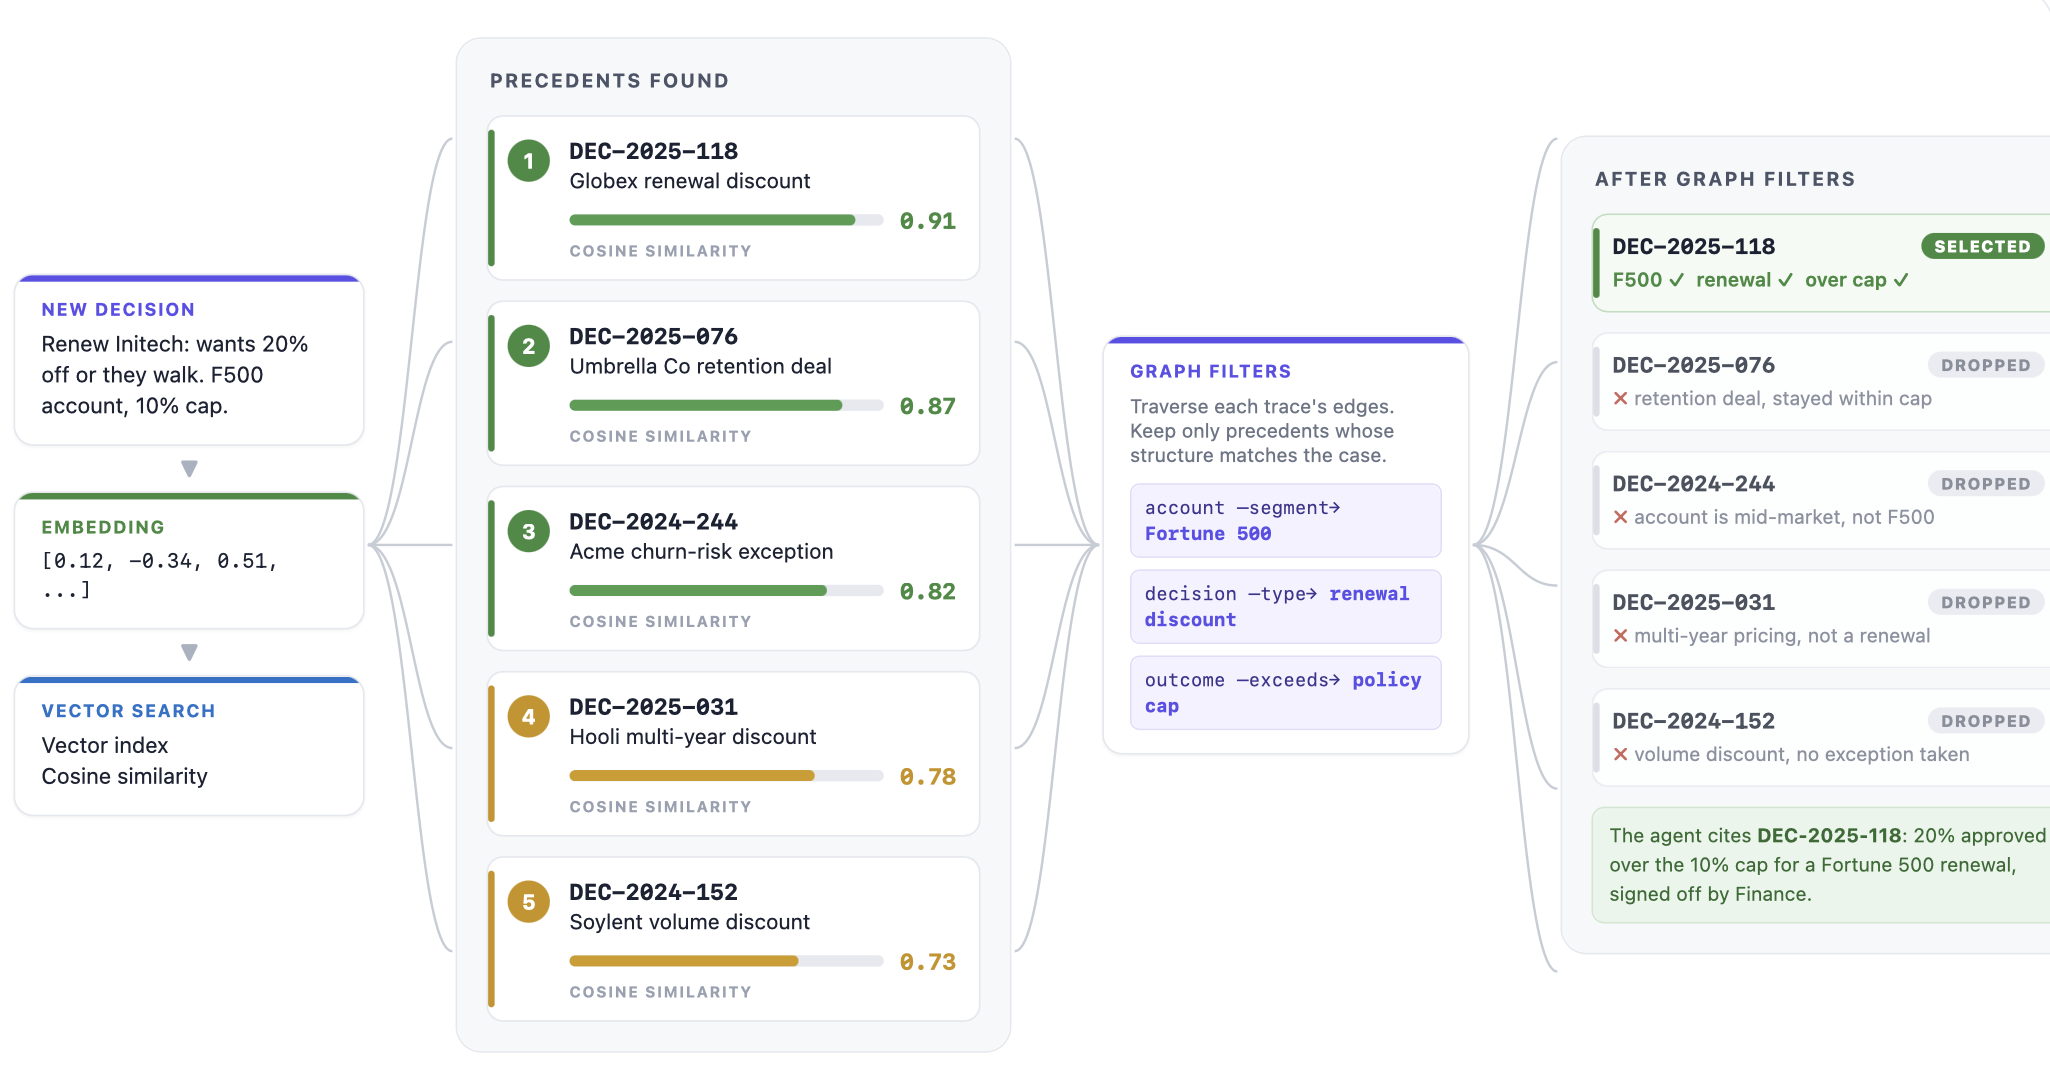
A pile of old decisions becomes memory the agent can actually use. This is also how an agent enter a mode of self-learning without anyone fine-tuning it or updating rules/instructions.
new case
Globex wants Net-60
- paid late once last year
- $500k renewal at risk
- #348 on the Fortune 500
precedent · Decision Trace 118
Acme → Net-60
- late twice but still granted
- $540k judged worth the risk
- #211 on the Fortune 500. Great logo.
↳ The agent reads the precedent and proposes to grant Net-60 under the exception rule.
There's a second payoff here. Because traces record exceptions, not just the clean path, you can see when a rule keeps getting overridden. If AP grants the same late-payment exception to twenty vendors, the policy is wrong, not the vendors. The graph can turn this pattern into a signal to fix the underlying policy itself.
0 times the Net-60 exception
was granted this quarter
⚑ Pattern detected
→ raise the Net-60 threshold
Over time, the context graph becomes the real source of truth for autonomy, and your company can easily audit and debug this autonomy.
The recent ACE paper, "Agentic Context Engineering", makes the mechanism concrete:
Treat the accumulated context as a playbook that grows through generation, reflection, and curation, and let real outcomes refine it. The agent gets better by editing what it knows, not by touching a single weight. A correction today becomes a rule tomorrow. A trace today becomes precedent next quarter. This feedback loop enables learning in agents.
Example of an agent using context graphs
An agent resolving the Initech renewal with a context graph
STEP 1 / 7
Open decision: Initech renewal
AgentOPEN DECISIONInitech renewalAccountInitech · Fortune 500Renewal$300k ARR · Q4Customer ask20% off, or they churnPolicy cap10% maximumEMBEDDING SPACEcosine similarity radiusAccount · Initech0.94name: Initechtype: renewal accountsegment: Fortune 500BEST MATCHAccount · HooliAccount · GlobexAccount · SoylentAccount · InitrodeAccount · Umbrella"initech renewal"VECTOR SEARCHFind the accountquery: "initech renewal"cosine > 0.901entity caughtOne record clears the radius.The rest stay outside.GRAPH TRAVERSALhasChampionhasOpportunitygovernedByChampionVP, OperationsOpportunityQ4 renewal · $300k ARRPolicyDiscount cap 10%Account · Initechmatched entityAgentworking setpulled inEMBEDDING SPACEcosine similarity radiusDEC-2025-1180.91Globex renewalF500 · over-cap askBEST MATCHDEC-2025-0760.87Umbrella retentionF500 accountDEC-2024-2440.82Acme churn riskexception approvedDEC-2025-0310.78DEC-2024-1520.73DEC-2023-089DEC-2024-017"renew initech: 20% ask"VECTOR SEARCHFind precedentsquery: the open decisioncosine > 0.803traces caughtThree past decisions clearthe radius; others fall short.Churn risk · $300k · F50020% approved (over 10% cap)Strong VP rapport; retainSam Okafor · FinancePolicy: 10% discount capDecisionTraceGlobex · DEC-2025-118contextoutcomerationaledecidedByreferencesPRECEDENTGlobex · DEC-2025-11820% exception (over 10% cap)F500 · churn risk · VP rapportSigned off by FinanceRenewed for the terminformsDECISION IN PLAYInitech · $300k · 20% ask · 10% capApprove 20%, above the 10% capCites DEC-2025-118 · logged as F500 retention.Mailby AgentTo:champion@initech.comSubject:Renewal: 20% discount approvedHi Dana,Glad to keep the partnership going. We haveapproved your renewal at a 20% discount forthe coming term, matching the value you placeon reliability. Contract to follow shortly.Best, RenewalssignatureR. AlvarezDocusign signature done · VP SalesApprovedexception signed offsent
Use ← / → or the arrows to step through.
Similar to knowledge graphs?
The parts are the same, but the implementation is new.
Knowledge graphs have been around since Google shipped one in 2012. Event sourcing, storing the sequence of events instead of just the latest state, is a pattern any backend engineer already knows. A context graph is close to event sourcing for decisions, where each event drags along its rationale and its links to everything.
So there's no new primitive here. What's new is that you capture the why on the write path as structured data, because for the first time there's a consumer, i.e. the agent, hungry and tireless enough to read it.
 Agents finally give the "why" records purpose.
Standard RAG, for contrast, retrieves documents that look similar to your question. A context graph retrieves decisions, with their reasoning and their edges to everything they affected. One hands the model text to read. The other hands it structure to walk and precedent to reason from.
Isn't agentic search enough?
There's a sentiment these days that agent memory and retrieval methods are outdated, and agentic search works better. Give the model simple tools (grep, file read, SQL queries, list directories, search) in the agent loop, and let the model itself decide what to look up, look at the result, and search again.
Claude Code initially shipped like this. It just gave the model grep, glob, file-read tools, and the model navigated codebases like a human developer would. And the surprising result was it worked better than Cursor who were using standard RAG.
A recent paper (AgenticRAG) measured retrieval. One-shot search on the BRIGHT benchmark got 8.4% recall, and the same retriever inside an agentic search loop got 49.6%. On FinanceBench, agentic search hit 92% answer correctness, where handing the model perfect evidence gets 94%.
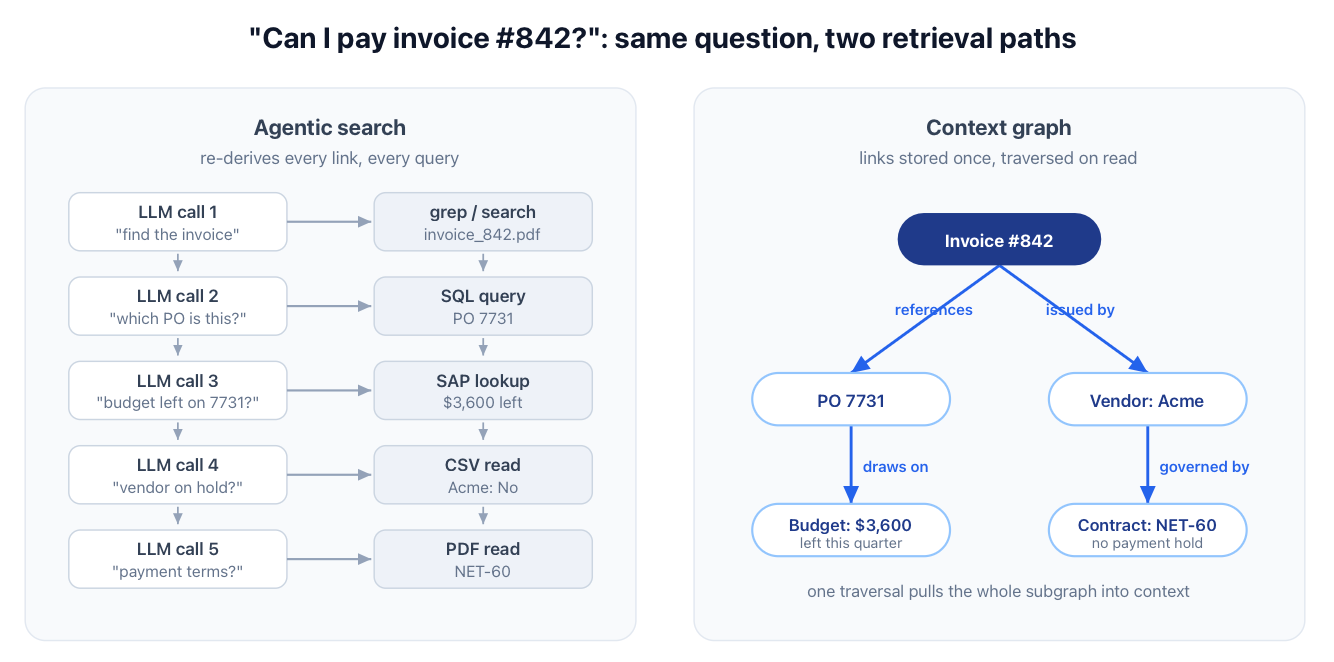
Agentic search works. Given enough turns, the agent finds almost everything that exists in the data.
So why bother with a graph? Two reasons.
1. Agentic search is a brute-force loop, and you pay for it on every query.
That 92% on FinanceBench cost 115K tokens per query, about 8x the single-shot cost. Every hop is another LLM call, so latency stacks the same way. And the agent re-derives the same links every time. Which PO does this invoice reference? Is the vendor on hold? It answered that yesterday, and it will need to answer it again tomorrow.
| Accuracy| Tokens/query| Latency
---|---|---|---
Agentic search| very high| very high (multiple LLM calls)| seconds
Context graph| high| very low| microseconds
The graph employs memoization. It stores each link once, and the agent traverses instead of re-deriving. Other benchmarks bear this out.
- A2RAG put a graph under an agent loop and cut tokens and latency by ~50% while gaining ~10 points of recall.
- GRASP got the highest multi-hop accuracy while spending 40-50% fewer tokens than the strongest search-only baseline.
- A benchmark paper literally titled "Do We Still Need GraphRAG?" found that agentic search narrows the gap, but the graph still wins on hard multi-hop questions and makes the agent's search behavior more stable.
2. Agentic search can only find what was written down.
The Initech decision wasn't in any text. Salesforce shows Globex renewed at 20%. It doesn't say that was an exception, who signed off, or why. The reasoning lived in a Zoom call and three Slack replies, and half of it never left anyone's head.
An agent with search tools will find the what and might still miss the why, because the why was never stored. No search method fixes a write-path problem. But a context graph mandates the storage of every decision trace the moment it is made.
To summarize, agentic search is the correctness baseline, and it's probably still the best method for some tasks. But the context graph does two things on top of it.
- It caches the hops the agent would otherwise recompute on every query, which is a cost, latency, and in some cases, accuracy optimization.
- It forces the capture of reasoning at decision time, which search alone can never recover after the fact.
Maybe we let the agent search when the graph comes up empty, and write what it learns back into the graph so the next run doesn't have to?
System-of-record agents won't work
Systems of record probably have it wrong. Salesforce released Agentforce, ServiceNow released Now Assist, Workday is doing something similar. Their reasoning is to add intelligence where the data resides.
But their agents will inherit the exact same limitations as their parents.
- Systems of record capture what changed, not why. Salesforce tracks field history, but only for a limited set of fields, and only for a while. And when someone approves a discount, no field anywhere stores the reasoning. The context of the decision is gone the moment it's made.
- These systems also miss data. A support ticket doesn't just live in Zendesk. It needs user tiers from CRM, SLA terms from billing, recent outages from PagerDuty, Slack thread flagging churn risk. No single system of record sees the whole picture. And each vendor's agent treats its own system as the center of the universe.
Systems of record are building their own agents, locking down APIs (ahem ahem), and slapping egress fees, but they can't insert themselves into an orchestration layer they were never part of.
When an agent triages an escalation, responds to an incident, or decides on a discount, it pulls context from multiple systems and time periods. The orchestration layer alone sees the full picture - what inputs were gathered, what policies applied, what exceptions were granted, and why decisions were taken.
Because it's executing the workflow, it can capture that context at decision time instead of bolting on governance afterwards.
This is the essence of a context graph, and that will be the single most valuable asset for your company in the era of AI.
The hard parts
Before you get too excited -
- Garbage in, garbage precedent. If the captured rationale is lazy ("approved, see Slack"), your precedents are landfill. The graph is worth exactly the quality of the why you put in it, and writing a good why is real work. But this time, it is certain this work will reap benefits.
- Who writes the trace. If a human has to type thoughtful rationale every time, it might rot the same way as a wiki. If the agent infers the rationale, you have to trust the inference, and "the model guessed why we did this" is a shaky base. The real answer is somewhere in between, and getting that right is not trivial.
- The decision swamp. A better name today for data lakes that exist in organizations would be data swamps. We dump everything in them with no schema and no curation. A graph of millions of contradictory, half-true traces is the same failure with extra edges. Without curation, more traces make precedent search worse, not better.
- This is early. Most vendor decks make it sound shipped. It isn't. The pattern is sound and the early results are unbelievably good. There is something here, definitely. But "great early results" is not "proven," and anyone who tells you otherwise is pitching.
The full stack
An AI-native workflow with context graphs has four layers -
1. Systems of record. Salesforce, SAP, Zendesk, GitHub, Slack, the Zoom transcript from this morning's call. They hold the state of your business - every record, ticket, commit, and message. What they don't hold is the reasoning that connects them. But they're still the ground truth for what is.
2. The harness. It sits in the execution path and runs the reason → act → observe loop. It holds the tools, picks what goes into the model on each step, stores corrections as memory, checkpoints long runs, enforces permissions, logs every decision, and catches errors before they crash the run. This engine turns a stateless LLM into a system that finishes work.
3. The context graph. As the harness runs, every decision leaves a trace: what inputs it gathered, which rule it applied, what exception it took, who approved, and why. The graph stitches those traces across entities and time. Your systems of record stay the truth for what happened. The graph becomes the truth for why.
4. Agents and humans. Agents execute the routine cases end to end. Humans handle the cases the agent flags as uncertain. Every correction a human makes flows back into memory and the graph, so future agent runs are better.
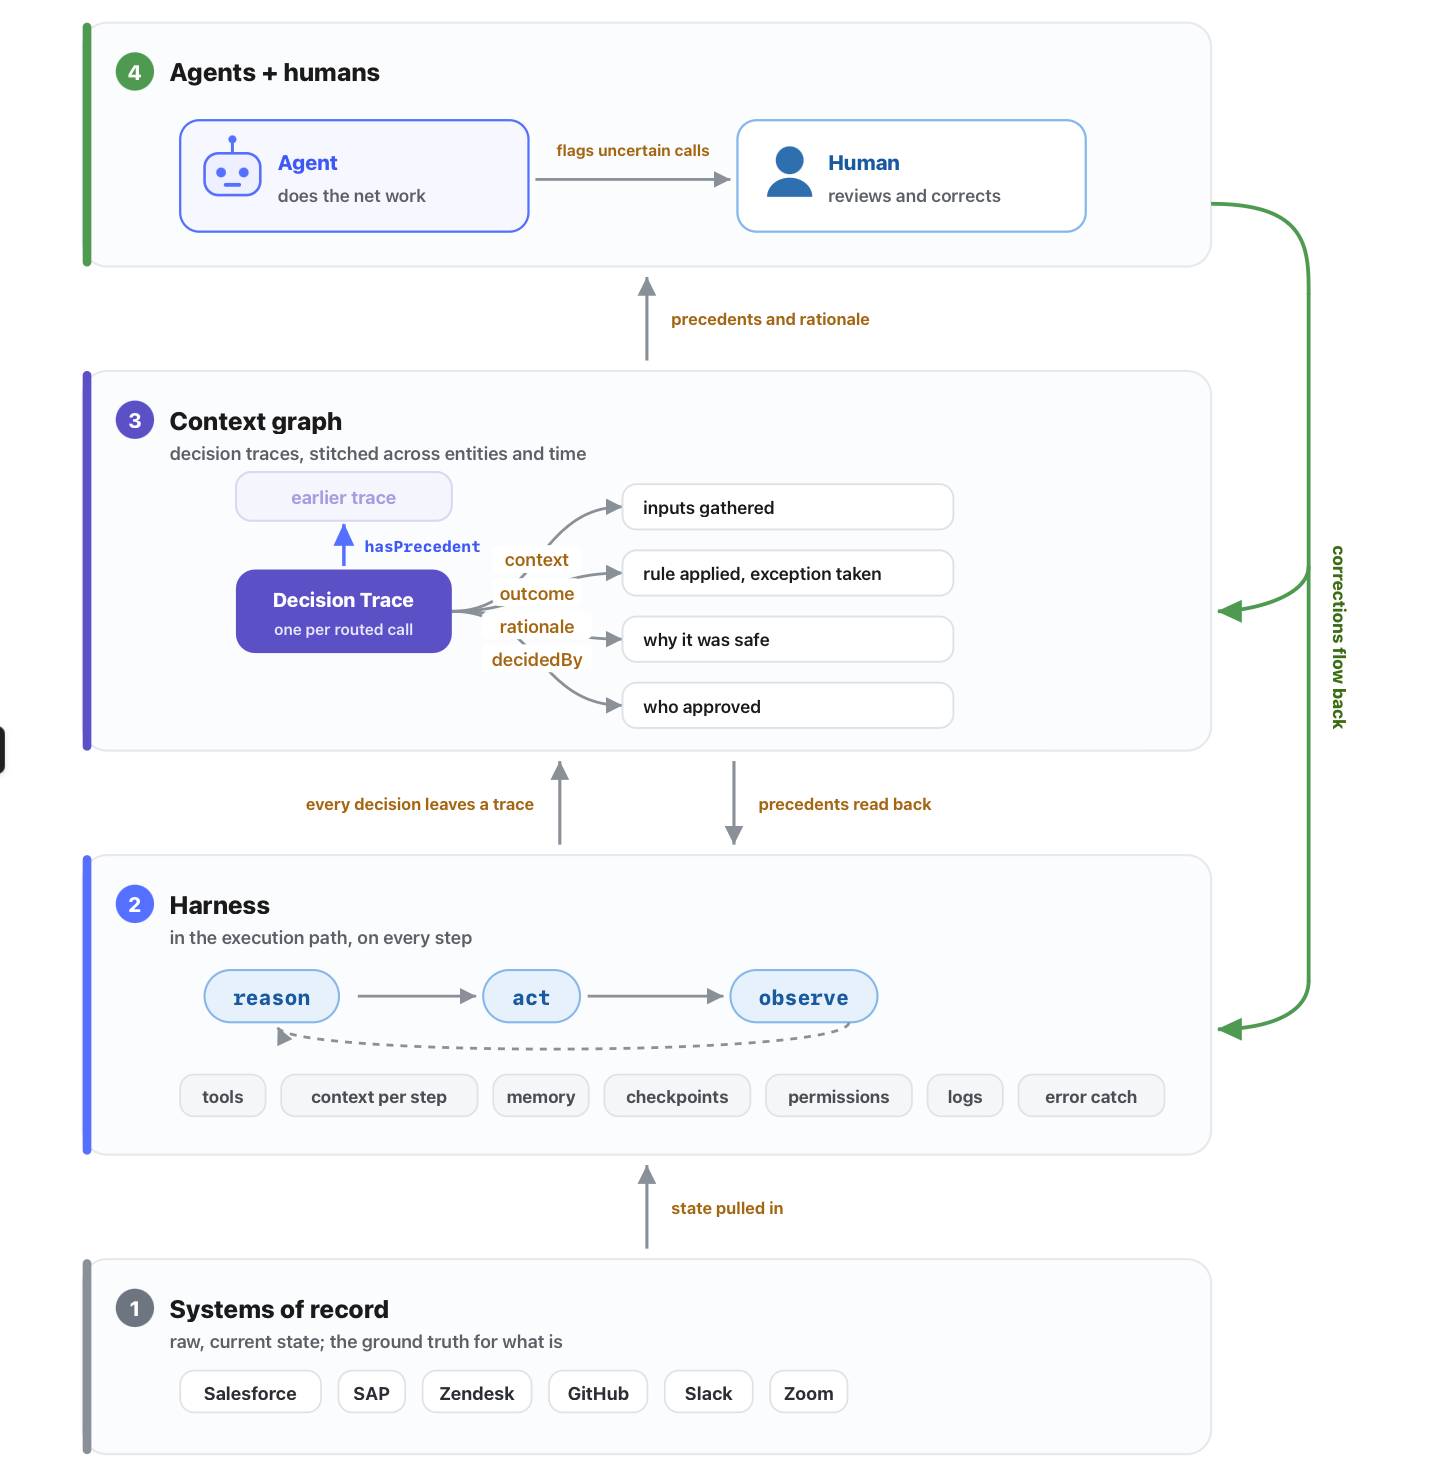
This maps to the two core features of AI-native organizations, Universal context and Loops.
- Universal context is your systems of record made queryable through the context graph. The agent doesn't re-derive the links between an invoice, a PO, a contract, and a Slack message on every turn. The graph already holds them.
- Loops are the harness closing feedback on every run. A correction today becomes a rule tomorrow. A decision trace today becomes precedent next quarter.
Where to start
Build a context graph when your agents run long, decisions made early have to survive many turns, and questions chain facts together. That's most multi-agent work.
Enterprises and startups we work with use context graphs to automate processes with -
- High team size. If you have 50 people running a workflow manually. The headcount is high only because the decision logic is too complex to automate with traditional AI tools.
- Exception-heavy decisions. Think about procurement, insurance claims, deal desks, compliance. In these jobs, the answer is always "it depends."
- Cross-functional roles. RevOps, FinOps, DevOps, Security Ops. These roles emerge precisely because no single system of record owns the cross-functional workflow. Your company creates a role to carry the context.
Procurement, finance, claims, deal desk, underwriting, escalation management are few examples.
Context graph as a map
A clean way to hold all of this in your head:
The model is your brain, the agent / agentic harness is your limbs, and the context graph is the map of your specific world (or company). A superb body with no map of your world stalls at every fork in the road that requires knowing the map, and enterprise processes are nothing but those forks.