Kimi K3,以及我们从鹈鹕基准测试中仍能学到什么
英文标题:Kimi K3, and what we can still learn from the pelican benchmark
月之暗面(Moonshot AI)发布了其最强大的模型 Kimi K3,拥有 2.8 万亿参数,承诺在 2026 年 7 月 27 日前开放权重。该模型在部分基准测试中超越了 Claude Opus 4.8 和 GPT-5.5,并与顶尖模型竞争,但其 API 定价较高,每百万输入/输出 token 分别为 3 美元和 15 美元。作者通过经典的“鹈鹕骑自行车” SVG 生成测试发现,该模型推理消耗巨大(一次生成需 25 美分),但视觉效果良好。这一测试虽已过时,却仍能反映模型成本、推理特征及基本空间能力,并提醒开发者代理工具调用能力才是当今更重要的评测维度。
 76.7 KB
中文
Kimi K3,以及我们从鹈鹕基准测试中仍能学到什么
2026年7月16日
中国 AI 实验室月之暗面(Moonshot AI)今早发布了 Kimi K3,将其描述为“迄今为止能力最强的模型,拥有 2.8 万亿参数”。目前可通过其网站和 API 使用,但开放权重版本承诺“在 2026 年 7 月 27 日前”发布。
月之暗面称这是首个“开放 3T 级别模型”(我猜他们将 2.8 万亿四舍五入到了 3 万亿),从 DeepSeek 的 1.6T V4 Pro 手中夺过了王冠。其自报的基准测试显示,K3 在大多数情况下超越了 Claude Opus 4.8 max 和 GPT-5.5 high,但落后于 Claude Fable 5 和 GPT-5.6 Sol。
Artificial Analysis 报告中的一些亮点:
- “在我们私有的长周期知识工作评估中,Kimi K3 的总体 Elo 达到 1547,比 Kimi K2.6 高出 732 分,仅次于 Claude Fable 5。”
- “每任务成本(0.94 美元)与 GPT-5.6 Sol(1.04 美元)相近,约为 Opus 4.8(1.80 美元)的一半,但高于开源权重同类模型”
- “在 Artificial Analysis 智能指数上,Kimi K3 的 token 使用量显著下降,输出 token 数比 K2.6 减少了 21%。”
该模型目前也是 Arena.ai 前端代码竞技场上的领先模型,甚至超越了 Claude Fable 5。
新模型引人注目的是其定价:每百万输入 token 3 美元,每百万输出 token 15 美元,与 Anthropic 的 Claude Sonnet 系列持平,成为中国 AI 实验室迄今发布的最昂贵模型。这比他们早期模型(如 Kimi K2.6 的 0.95 美元/4 美元)有了显著提升。而且 2.8 万亿参数也是那个 1T 模型的两倍多。
但它的鹈鹕画得怎么样?
我通过 OpenRouter(以免注册月之暗面 API 密钥)配合 llm-openrouter 插件 生成了一个骑自行车的鹈鹕 SVG:
llm -m openrouter/moonshotai/kimi-k3 'Generate an SVG of a pelican riding a bicycle'
这是生成过程的完整记录。看起来是这样的:
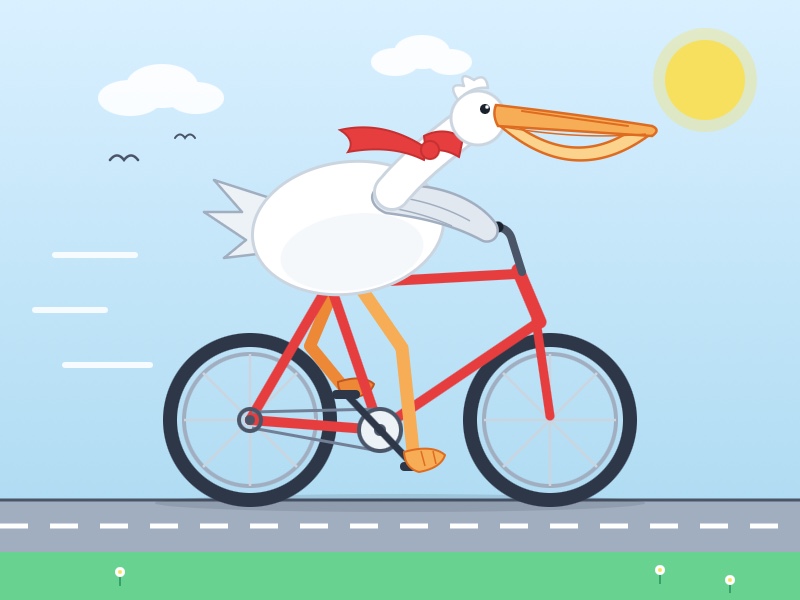
那只鹈鹕花费了 95 个输入 token 和 16,658 个输出 token(其中 13,241 个是推理 token),总成本为 25 美分!
由于 K3 支持图像输入,我将渲染好的 SVG 图片(配合我的替代文本提示词)输入给它,并得到了(花费 0.6 美分):
一幅卡通风格的插画,一只戴着红围巾的白色鹈鹕,正骑着一辆红色自行车沿灰色道路(带白色虚线)前行;鹈鹕有一个橙色的大喙和有蹼的橙色脚掌在踩踏板,身后有白色的动态线条;背景是浅蓝色的天空,飘着白云,有一轮黄色的太阳,两只小黑鸟在飞翔,前景是绿草和微小的白花。
我们能从鹈鹕身上学到什么?
我的“生成一个骑自行车的鹈鹕 SVG” 测试已经有 21 个月的历史了。它从来都不是一个特别好的基准测试。最初只是一个关于比较这些模型有多荒谬的笑话,但在第一年里,它出人意料地与模型实际质量高度相关。
这种关联现在已基本断裂。GPT-5.6 和 Claude Fable 5 的鹈鹕被 GLM-5.2 比了下去,尽管我很喜欢 GLM,但我认为它并非 Fable 级别的模型。
(我仍然不相信实验室正在针对这项基准进行训练——如果他们这么做,我会期待更好的结果。不过,Gemini 有可能对“任意动物骑乘交通工具”的组合做过优化!)
鹈鹕测试最大的局限在于,它完全无法触及当今模型最重要的能力:代理工具调用以及在对话变长时可靠地操作工具。
所以,别用鹈鹕来比较模型了!
尽管如此,我仍然通过亲自运行这个基准获得了不少价值。
首先,它是促使我真正试用模型的强制函数。如果我给你看一只鹈鹕,那就意味着我已经成功通过该模型运行了提示词。如果模型有官方 API,我会使用;如果它是开放权重(并且小到足以在 128GB M5 MacBook Pro 上运行),我会尝试在自己的机器上运行,通常通过 llama.cpp、LM Studio 或 Ollama。我也经常使用 OpenRouter,因为它通常能提供官方 API 的代理,而无需新的 API 密钥。
我大部分鹈鹕都是通过我的 LLM CLI 工具生成的,这有助于促使我确保新模型能通过其插件得到支持。
但更重要的是,即便只是“生成一个骑自行车的鹈鹕 SVG”这样一次简单的提示,也能揭示出有趣的模型特性。
以今天 Kimi K3 的结果为例。运行这些简单提示有助于强调该模型的几个要点。
- 目前它只有一种推理强度,“max”——而且这很明显。模型消耗了 13,241 个推理 token 才输出 3,417 个响应 token。这很昂贵——这只鹈鹕花了 25 美分!
- “Generate an SVG of a pelican riding a bicycle”这个提示词怎么会占 95 个输入 token?OpenAI 的分词器计为 10 个,Anthropic 的分词器对 Opus 4.6 计为 10 个,Opus 4.7 为 30 个,Sonnet 5/Fable 5 为 25 个。向 Kimi K3 输入“hi”计为 86 个 token,暗示可能存在一个 85 token 的隐藏系统提示。不过它拒绝泄露这个提示。
- 视觉能力表现良好:它生成的替代文本非常出色。
K3 目前只有一个思考强度级别,但我最近通过在不同强度级别上运行相同的鹈鹕提示,获得了不少收获,能快速了解这些级别的影响。例如,这是我针对 GPT-5.6 模型家族制作的矩阵。
不过,我从鹈鹕测试中获得的主要内容其实是:
- 它是为模型撰写提示词的“hello world”练习
- 对简单任务的大致成本和推理估算
- 确认模型能输出有效的 SVG,并具备基本的几何和空间感知能力。这对那些能在我笔记本上运行的小型模型来说意义重大。
- 比较同一模型家族不同版本间的鹈鹕仍然很有趣。K3 的鹈鹕比起 Kimi 2.5 有显著进步。
- 这是我能分享、证明我已试用过它的东西。而且,在 Hacker News 上,带着鹈鹕的评论差不多是一种传统了,每当我迟到时,就会有人留言问鹈鹕在哪!
English / 原文
Kimi K3, and what we can still learn from the pelican benchmark
16th July 2026
Chinese AI lab Moonshot AI announced Kimi K3 this morning, describing it as their “most capable model to date, with 2.8 trillion parameters”. It’s currently available via their website and API, but an open weight release is promised “by July 27, 2026”.
Moonshot are calling this the first “open 3T-class model” (I guess they’re rounding 2.8 trillion up to 3 trillion), taking the crown from DeepSeek’s 1.6T v4 Pro. Their self-reported benchmarks have K3 mostly beating Claude Opus 4.8 max and GPT-5.5 high, while losing out to Claude Fable 5 and GPT-5.6 Sol.
A few highlights from the Artificial Analysis report on the model:
- “On our private long-horizon knowledge work evaluation, Kimi K3 reaches an overall Elo of 1547, +732 points from Kimi K2.6 and behind only Claude Fable 5.”
- “Cost per task ($0.94) is similar to GPT-5.6 Sol ($1.04), ~1/2 the price of Opus 4.8 ($1.80) and higher than open weights peers”
- “Kimi K3’s token usage on the Artificial Analysis Intelligence Index decreased significantly, using 21% fewer output tokens than K2.6.”
The model is also now the leading model on Arena.ai’s Frontend Code arena, surpassing even Claude Fable 5.
The new model is notable for the pricing: $3/million input tokens and $15/million output tokens, putting it at the same level as Anthropic’s Claude Sonnet series and making it the most expensive model released by a Chinese AI lab to date. This is a significant increase on their earlier models such as Kimi K2.6 at $0.95/$4. 2.8 trillion parameters is also more than twice the size of that 1T model.
But how does it pelican?
I used OpenRouter (to avoid signing up for a Moonshot API key) with the llm-openrouter plugin to generate an SVG of a pelican riding a bicycle:
llm -m openrouter/moonshotai/kimi-k3 'Generate an SVG of a pelican riding a bicycle'
Here’s the transcript. It looks like this:
That pelican took 95 input tokens and 16,658 output tokens (13,241 were reasoning tokens), for a total cost of 25 cents!
Since K3 accepts image input I ran it against that rendered SVG above (with my alt text prompt) and got back (for 0.6 cents):
Cartoon illustration of a white pelican wearing a red scarf, riding a red bicycle along a gray road with white dashed lines; the pelican has a large orange beak and webbed orange feet pedaling, with white motion lines behind it; the background shows a light blue sky with white clouds, a yellow sun, two small black birds in flight, and green grass with tiny white flowers in the foreground
What can we learn from the pelican?
My Generate an SVG of a pelican riding a bicycle test is 21 months old now. It was never a particularly great benchmark. It started out as a joke on how absurdly difficult it is to compare these models, but then for the first year it turned out to have a surprising correlation to how good the models actually were.
That connection has been mostly severed now. The GPT-5.6 and Claude Fable 5 pelicans are outclassed by GLM-5.2, and much as I love GLM I don’t think that’s a Fable-class model.
(I’m still not convinced that labs are training for the benchmark—if they were, I’d expect much better results. There’s a chance that Gemini has optimized for any combination of an animal on a vehicle though!)
The biggest limitation of the pelican is that it doesn’t touch at all on the thing that matters most for today’s model: agentic tool calling and the ability to operate tools reliably as conversations grow in length.
So don’t go using pelicans to compare models!
All of that said, I still get a decent amount of value out of running the benchmark myself.
Firstly, it’s a forcing function for actually trying the model. If I show you a pelican, that means I’ve managed to run a prompt through it. If the model has an official API I’ll use that, if it’s open weight (and small enough to fit a 128GB M5 MacBook Pro) I’ll try running it on my own machine, usually via llama.cpp or LM Studio or Ollama. I’ll frequently use OpenRouter since that usually provides a proxy to an official API without me needing a new API key.
Most of my pelicans are generated using my LLM CLI tool, which helps encourage me to ensure the latest models are supported by that (via one of its plugins).
More importantly though, even the act of a single prompt to “Generate an SVG of a pelican riding a bicycle” can reveal interesting model characteristics.
Consider the result for Kimi K3 today. Running those simple prompts helped emphasize several points about the model.
- It only has one reasoning effort right now, “max”—and it shows. The model consumed 13,241 reasoning tokens to output 3,417 tokens of response. This is expensive—the pelican cost 25 cents!
- How does the prompt “Generate an SVG of a pelican riding a bicycle” add up to 95 input tokens? OpenAI’s tokenizer counts 10, Anthropic’s counts 10 for Opus 4.6, 30 for Opus 4.7 and 25 for Sonnet 5/Fable 5. Prompting “hi” to Kimi K3 counted 86 tokens, suggesting there may be an 85 token hidden system prompt. It refused to leak it though.
- Vision works well: the alt text it generated is very good.
K3 currently only has one thinking effort level, but I’ve been deriving quite a bit of value recently from running the same pelican prompt through different effort levels to get a quick idea for what impact those have. Here’s my matrix for the GPT-5.6 model family, for example.
Really though the main things I gain from the pelican test are:
- It’s a “hello world” exercise for prompting a model
- A rough cost and reasoning estimate for a simple task
- Confirmation that the model can output valid SVG and has a basic idea of geometry and spatial awareness. This is a much bigger deal for the smaller models that run on my laptop.
- It’s still interesting to compare pelicans between releases in the same model family. K3’s pelican is a notable improvement from Kimi 2.5.
- It’s something I can share that demonstrates I’ve tried it. Plus a comment with a pelican in it is kind of a tradition on Hacker News at this point, any time I’m late I get comments asking where it is!