构建面向 Agent 的企业搜索:Amazon Bedrock 托管知识库
英文标题:Build enterprise search for agents with Amazon Bedrock Managed Knowledge Base
本文介绍 Amazon Bedrock 托管知识库(Managed Knowledge Base)的三大核心支柱:简化设置、更智能的检索和生产就绪。该服务通过原生企业连接器、多模态解析和服务管理的存储,将搭建知识检索管道的时间从数天缩短至几分钟,并内置实时 ACL 访问控制。开发者可使用 Retrieve 和 Agentic Retrieval 两种 API 应对不同复杂度的查询,其中 Agentic Retrieval 能自动分解多跳推理并跨知识库迭代检索。对于需要大规模部署 RAG 的团队,该服务集成了 AgentCore Gateway,提供开箱即用的可观测性、安全性与文档级访问控制。
 101.6 KB
 197.7 KB
 217.3 KB
 428.3 KB
 25.4 KB
 9.2 KB
 8.9 KB
 9.9 KB
 158.8 KB
中文
建立在企业数据上以支撑 Agent 和生成式 AI 应用的知识库,在大规模场景下极难构建。团队通常需要将连接器、解析器、向量存储、知识图谱和检索引擎拼凑在一起,再将整套系统投入生产环境。每个环节都伴随自身的挑战:你需要决定连接哪些数据源、如何解析多模态文档类型;你需要在图数据库和向量数据库之间做选择,然后配置和扩展它们;你还要处理跨异构内容的复杂查询,并叠加生产环境所要求的文档级访问控制、可观测性和安全性。
Amazon Bedrock 现在正式发布托管知识库(Managed Knowledge Base),这是一套全托管的智能体级检索解决方案,可以代你处理扩展、高精度检索和文档访问控制。你可以连接企业数据源或抓取网页并开始摄取数据。通过 AWS 管理控制台 入门无需选择模型。合理的默认设置让你能在几分钟内完成从零到首次检索的全过程,而从头搭建一条同等水平的管线路通常需要数天甚至数周。当你需要自定义时,可以掌控嵌入模型、重排序器、分块策略等选项。
在本文中,我们将深入探讨实现这一切的三大支柱:简化设置、更智能的检索和生产就绪。我们还会展示搭建知识库并从中检索的代码示例。
简化设置
如今的开发者通常需要分别采购和构建数据摄取管道、向量或图存储以及检索基础设施。这意味着管理独立的基础设施、独立的计费模型、独立的速率限制,以及将各个部分拼凑成一条连贯管道所带来的复杂性。
托管知识库将这种复杂性抽象掉。你只需配置一个知识库,服务便会处理往后的一切,包括通过原生连接器摄取企业数据,以及代你管理向量存储。
支持 ACL 的原生企业连接器
托管知识库包含六个原生连接器(Amazon Simple Storage Service(Amazon S3)、Microsoft SharePoint、Atlassian Confluence、Google Drive、Microsoft OneDrive 和 Web Crawler)。此外还提供直接摄取 API,用于存放不在支持的数据源中的文档。在后续同步时,服务仅处理修改过或新增的文档,从而缩短时间、降低成本并减少数据过时。
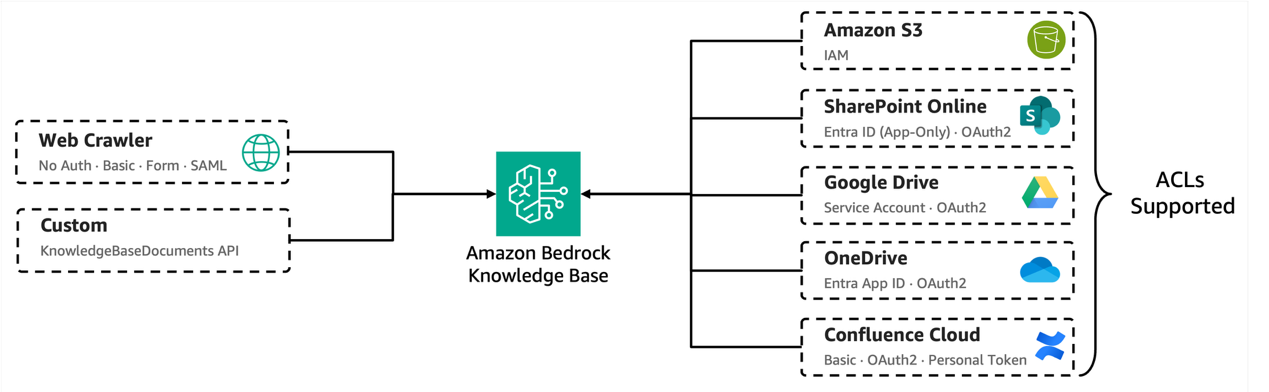
托管知识库使用实时访问控制列表(ACL)检查,作为现有检索前 ACL 过滤之上的额外安全层。预过滤的文档仅在 API 调用生命周期内存在,对大语言模型(LLM)或用户不可见。这种方式通过在查询时直接向权威源检查权限来维持最新的访问控制,而不是依赖可能陈旧或错误映射的 ACL 数据。
Syngenta Group 使用 Bedrock 托管知识库,使员工能按需创建知识库,从 SharePoint 和 Confluence 同步数据,用于内部知识搜索和智能体级 RAG 应用。
– Jason Krohn,数据与 AI 技术主管MRH Trowe 正在使用 Bedrock 托管知识库支撑内部 AI Copilot,让员工能从公司知识库中获得即时、有据可依的答案,知识库涵盖 Confluence 和 SharePoint 中数千份英德双语文档。借助原生连接器和内置的访问控制,我们团队可以搜索保单、客户文档和运营内容,无需搭建自定义检索管道,从而加快员工获取服务客户所需知识的速度。
– Dr. Malte Polley,数据分析与 AI 团队负责人
跨多模态数据的解析
你的数据分散在多种格式中:Web 应用中的机器可读内容、包含嵌入图像的 PDF、PPTX 和 DOCX 等数字文件、扫描文档以及音视频等媒体内容。与其为每种格式构建单独的管道,托管知识库提供了全托管解析,能够自动对每种内容类型选择最合适的策略。它无需你配置即可处理表格、图表、图示、混合布局和媒体。该服务支持的视觉内容文档(PDF、PPT/PPTX、DOCX)最大 500 MB,音频文件最大 2 GB,视频文件最大 10 GB。
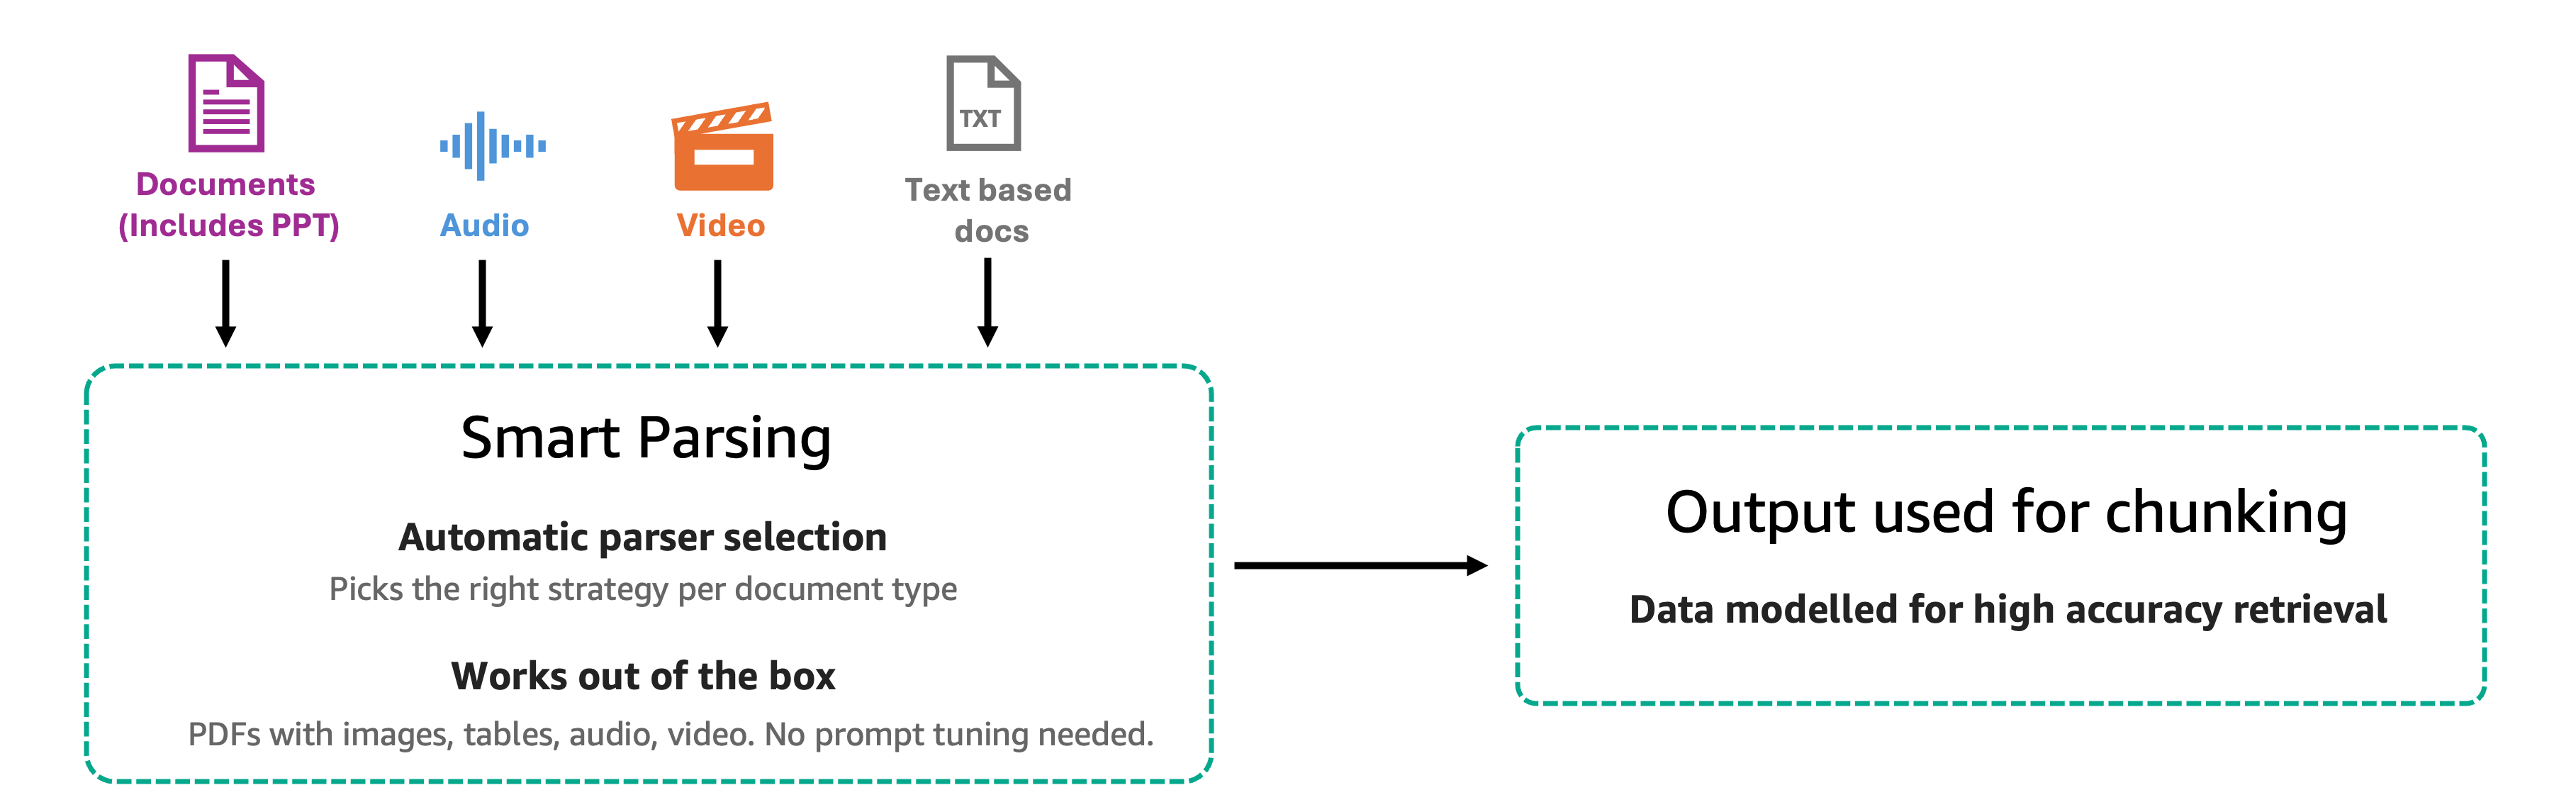
服务解析内容后,会将其拆分为用于检索的片段。默认情况下,托管知识库会代你决定最适合的分块策略。如果你了解自己的数据并希望更多控制,可选择自定义策略,例如固定大小分块(可设置近似 token 量),或对已预处理或预先切分的文档选择不拆分。
服务管理的数据存储
选择语义检索数据库是知识检索管道中最复杂的决策之一。每种选项拥有不同的性能特征、定价模型、扩展行为和功能组合。即便选定之后,你仍需配置容量、设置索引、管理备份并持续调优性能。
托管知识库通过统一存储层彻底消除了这些工作。服务自动配置存储,因此你无需决定向量维度或相似度算法,并且能从 GB 级到 TB 级自动扩缩,无需人工干预。结合关键词和语义检索的混合搜索始终处于开启状态,无需单独配置索引。数据在静态存储和传输过程中使用 AWS Key Management Service(AWS KMS)密钥加密,可以是 AWS 托管密钥或客户托管密钥。
你无需与底层存储打交道。AWS 服务为你处理监控、调优、备份、补丁和容量管理。
OpenAI 正在使用 Bedrock 托管知识库的 RAG 能力,为百万级用户可靠且大规模地联结推理和模型回答,并提供恰当的客户上下文。
– Lavanya Singh,OpenAI 技术人员
三步完成设置
让我们看看如何通过编程方式搭建托管知识库。仅需三步 API 调用:创建知识库、添加数据源和启动摄取。以下示例使用 Amazon S3 作为数据源,搭配全托管嵌入模型,无需配置模型 Amazon Resource Name (ARN)、向量存储或分块。
python import boto3
bedrock_agent = boto3.client('bedrock-agent', region_name='us-west-2')
Step 1: Create a fully managed knowledge base (zero-config)
kb_response = bedrock_agent.create_knowledge_base( name='my-managed-kb', description='Product documentation knowledge base', roleArn='arn:aws:iam::123456789012:role/BedrockKBRole', knowledgeBaseConfiguration={ 'type': 'MANAGED', 'managedKnowledgeBaseConfiguration': { 'embeddingModelType': 'MANAGED' } } ) kb_id = kb_response['knowledgeBase']['knowledgeBaseId']
Step 2: Add an S3 data source
ds_response = bedrock_agent.create_data_source( knowledgeBaseId=kb_id, name='my-s3-docs', dataSourceConfiguration={ 'type': 'S3', 's3Configuration': { 'bucketArn': 'arn:aws:s3:::amzn-s3-demo-bucket', 'inclusionPrefixes': ['documents/'] } } ) data_source_id = ds_response['dataSource']['dataSourceId']
Step 3: Start ingestion
bedrock_agent.start_ingestion_job( knowledgeBaseId=kb_id, dataSourceId=data_source_id )
更智能的检索
单次检索步骤无法回答所有问题。直接查找可以独立运行良好,但比较分析、多跳推理和研究型查询需要更强的能力。托管知识库提供两种检索 API,每种适用于不同的复杂度级别:
- Retrieve 返回带相关性分数和元数据的排序来源片段。用于直接查找、常见问答类问题以及对低延迟要求严格的场景。你可以控制返回结果的数量,并应用元数据过滤器来缩小搜索范围。
- Agentic Retrieval 使用基础模型(FM)将复杂查询分解为多个子查询。它在一个或多个知识库中迭代检索,并评估结果是否足够后再返回。Agentic Retrieval 还可使用托管的编排 LLM 或 Amazon Bedrock 上可用的模型生成综合回答。用于比较分析、多跳问题、研究型查询以及需要综合多个来源或文档信息的场景。
Agentic Retrieval 的工作原理
比较两个产品、跨多个文档追溯决策或综合不同来源的研究信息,需要多次检索步骤。你还需要评估中间结果并判断何时已拥有足够的信息。
Agentic Retrieval 可自动处理这些,并且支持跨一个或多个知识库。当查询传入时,服务会:
- 规划:分析查询并将其分解为子查询,每个子查询针对你已配置知识库的特定检索器。
- 检索:对一个或多个知识库并行执行子查询。
- 评估:判断结果是否足够。如果不够,它会规划并执行额外的检索回合(默认最多五次)。
- 返回:返回所有迭代的去重片段,过程中持续流式输出追踪事件以实现完全可观测性。
你可以根据用例平衡准确性和延迟。maxAgentIteration 参数控制模型执行的回合数,你还可以选择用于规划和评估的基础模型。
以下代码展示了调用 Agentic Retrieval 并处理其流式响应的示例。请求中指定了用户查询、要搜索的知识库、用于规划和评估的基础模型以及最大检索迭代次数。当服务运行时,它会流式输出追踪事件,显示每一个规划步骤和正在执行的子查询,最后输出检索结果:
python bedrock_runtime = boto3.client('bedrock-agent-runtime', region_name='us-west-2')
response = bedrock_runtime.agentic_retrieve_stream( messages=[{ 'role': 'user', 'content': [{'text': 'Compare the pricing tiers of Product A and Product B'}] }], retrievers=[{ 'knowledgeBaseRetriever': { 'knowledgeBaseId': kb_id, 'maxResults': 10 } }], agenticRetrieveConfiguration={ 'foundationModel': { 'modelArn': 'arn:aws:bedrock:us-west-2::foundation-model/anthropic.claude-sonnet-4-20250514' }, 'maxAgentIteration': 5 # 1-10, default 5 } )
Trace events stream in real time, then final results arrive
for event in response['stream']: if 'trace' in event: trace = event['trace'] if 'planning' in trace: print(f"Planning: {len(trace['planning'].get('actions', []))} sub-queries") elif 'retrieval' in trace: print(f"Retrieving: {trace['retrieval'].get('input', {}).get('text', '')}") elif 'retrievalResults' in event: results = event['retrievalResults']['results'] print(f"\n{len(results)} deduplicated results returned") for i, r in enumerate(results[:5], 1): print(f" {i}. {r['content']['text'][:150]}...")
生产就绪
将检索增强生成(RAG)原型跑通是一回事,在生产环境中大规模运行并具备合适的访问控制、可观测性和安全性则是另一回事,许多团队在此处陷入困境。托管知识库开箱即用地集成了 AgentCore Gateway、文档级访问控制和可观测性,使你可以直接部署而无需自行构建这些层。
原生 AgentCore Gateway 集成
托管知识库与 AgentCore Gateway 原生集成,为你提供了一种将知识库暴露给 Agent 的简化方式。当你在网关上将知识库添加为目标时,它会变成一个支持 Model Context Protocol (MCP) 的 Agent 能够自动发现和调用的工具。AWS 身份与访问管理(IAM)、路由和可观测性均在网关处集中管理。如果更适合你的用例,你也可以将托管知识库作为独立服务,直接从应用程序调用检索 API。
AgentCore Gat
English / 原文
Knowledge bases that ground agents and generative AI applications over your enterprise data are hard to build at scale. Teams typically stitch together connectors, parsers, vector stores, knowledge graphs, and retrieval logic, then operationalize all of it for production. Each piece brings its own challenges. You must decide which data sources to connect and how to parse multimodal document types. You must choose between graph and vector databases, then provision and scale them. You must also handle complex queries that reason across diverse content, and layer on the document-level access control, observability, and security that production demands.
Amazon Bedrock now offers Managed Knowledge Base in general availability, a fully managed agentic retrieval solution that handles scaling, high-accuracy retrieval, and document access control on your behalf. You can connect your enterprise data sources or crawl the web and start ingesting. Getting started through the AWS Management Console requires no model selection. Sensible defaults take you from zero to your first retrieval in minutes, compared to the days or weeks typically needed to assemble a comparable pipeline from scratch. When you’re ready to customize, you have control over embedding models, rerankers, chunking strategies, and more.
In this post, we walk through the three pillars that make this possible: simplified setup, smarter retrieval, and production readiness. We also show you code examples for setting up a knowledge base and retrieving from it.
Simplified setup
Developers today typically procure and build data ingestion pipelines, vector or graph storage, and retrieval infrastructure separately. This means managing separate infrastructure, separate billing models, separate rate limits, and the complexity of piecing it all together into a coherent pipeline.
Managed Knowledge Base abstracts this complexity away. You configure a knowledge base, and the service handles everything downstream, from ingesting enterprise data through native connectors to managing vector stores on your behalf.
Native enterprise connectors with ACL support
Managed Knowledge Base includes six native connectors (Amazon Simple Storage Service (Amazon S3), Microsoft SharePoint, Atlassian Confluence, Google Drive, Microsoft OneDrive, and Web Crawler). It also includes a direct ingestion API for documents that don’t live in a supported source. On subsequent syncs, the service processes only modified or new documents, reducing time, cost, and staleness.
Managed Knowledge Base uses real-time access control list (ACL) checks as an additional layer of security on top of existing pre-retrieval ACL filtering. The pre-filtered documents are transient for the life of the API call and are not visible to large language models (LLMs) or users. This maintains current access controls by checking permissions directly with the authoritative source at query time, rather than relying on potentially stale or incorrectly mapped ACL data.
Syngenta Group uses Bedrock Managed Knowledge Bases to enable employees to create knowledge bases on demand, syncing data from SharePoint and Confluence for internal knowledge search and agentic RAG applications.
– Jason Krohn, Head of Data and AI TechnologyMRH Trowe is using Bedrock Managed Knowledge Bases to power an internal AI Copilot that gives employees instant, grounded answers from across our corporate knowledge base — spanning thousands of documents in Confluence and SharePoint, in both English and German. With native connectors and built-in access controls, our teams can search across policies, client documentation, and operational content without building custom retrieval pipelines — accelerating how our employees access the knowledge they need to serve clients.
– Dr. Malte Polley, Teamleader Data Analytics & AI
Parsing across multimodal data
Your data fragments across many formats: machine-readable content in web applications, digital files containing embedded images like PDFs, PPTX, and DOCX, scanned documents, and media content such as audio and video. Rather than building separate pipelines for each format, Managed Knowledge Base provides fully managed parsing that automatically selects the right strategy per content type. It handles tables, charts, diagrams, mixed layouts, and media without configuration from you. The service supports visual content documents (PDFs, PPT/PPTX, DOCX) up to 500 MB, audio files up to 2 GB, and video files up to 10 GB.
After the service parses content, it splits the content into segments for retrieval. By default, Managed Knowledge Base decides on the most suitable chunking strategy on your behalf. If you understand your data and want more control, you can choose a custom strategy like fixed-size chunking, where you set the approximate token size, or no chunking, for documents that are already pre-processed or pre-split.
Service-managed data storage
Choosing a semantic retrieval database is one of the most complex decisions in a knowledge retrieval pipeline. Each option has different performance profiles, pricing models, scaling characteristics, and feature sets. After you choose, you must still provision capacity, configure indices, manage backups, and tune performance over time.
Managed Knowledge Base removes that work entirely with a unified storage layer. The service auto-provisions storage so you don’t decide on vector dimensions or similarity metrics, and it auto scales from gigabytes to terabytes without intervention. Hybrid search combining keyword and semantic retrieval is continuously on, with no separate index configuration to manage. Data is encrypted at rest and in transit using AWS Key Management Service (AWS KMS) keys, either AWS managed or customer managed.
You don’t interact with the underlying storage. Your AWS services handle monitoring, tuning, backups, patching, and capacity management for you.
OpenAI is using Bedrock Managed Knowledge Bases’ RAG capabilities to ground inference and model responses, reliably and at scale for millions of users, with the right customer context.
– Lavanya Singh, Member of Technical Staff, OpenAI
Setup in three steps
Let’s look at how to set up a managed knowledge base programmatically. Three API calls are all it takes: create the knowledge base, add a data source, and start ingestion. The following example uses Amazon S3 as the data source with a fully managed embedding model, with no model Amazon Resource Name (ARN), vector store, or chunking configuration required.
import boto3

bedrock_agent = boto3.client('bedrock-agent', region_name='us-west-2')

# Step 1: Create a fully managed knowledge base (zero-config)
kb_response = bedrock_agent.create_knowledge_base(
    name='my-managed-kb',
    description='Product documentation knowledge base',
    roleArn='arn:aws:iam::123456789012:role/BedrockKBRole',
    knowledgeBaseConfiguration={
        'type': 'MANAGED',
        'managedKnowledgeBaseConfiguration': {
            'embeddingModelType': 'MANAGED'
        }
    }
)
kb_id = kb_response['knowledgeBase']['knowledgeBaseId']

# Step 2: Add an S3 data source
ds_response = bedrock_agent.create_data_source(
    knowledgeBaseId=kb_id,
    name='my-s3-docs',
    dataSourceConfiguration={
        'type': 'S3',
        's3Configuration': {
            'bucketArn': 'arn:aws:s3:::amzn-s3-demo-bucket',
            'inclusionPrefixes': ['documents/']
        }
    }
)
data_source_id = ds_response['dataSource']['dataSourceId']

# Step 3: Start ingestion
bedrock_agent.start_ingestion_job(
    knowledgeBaseId=kb_id,
    dataSourceId=data_source_id
)
Smarter retrieval
A single retrieval step can’t answer every question. Direct lookups work fine on their own, but comparative analysis, multi-hop reasoning, and research queries need more. Managed Knowledge Base offers two retrieval APIs, each designed for different complexity levels:
- Retrieve returns ranked source chunks with relevance scores and metadata. Use it for direct lookups, FAQ-style questions, and scenarios where low latency is critical. You control the number of results and can apply metadata filters to narrow the search.
- Agentic Retrieval uses a foundation model (FM) to decompose complex queries into sub-queries. It retrieves iteratively across one or more knowledge bases and evaluates whether the results are sufficient before returning them. Agentic Retrieval can also generate a synthesized response using the managed orchestration LLM or a model available on Amazon Bedrock. Use it for comparative analysis, multi-hop questions, research queries, and scenarios that require synthesizing information from multiple sources or documents.
How Agentic Retrieval works
Comparing two products, tracing a decision across multiple documents, or synthesizing research from different sources requires multiple retrieval steps. You also need to evaluate intermediate results and recognize when you have enough information.
Agentic Retrieval handles this automatically, across one or more knowledge bases. When a query comes in, the service:
- Plans by analyzing the query and decomposing it into sub-queries, each targeting a specific retriever across your configured knowledge bases.
- Retrieves by executing sub-queries in parallel against one or multiple knowledge bases.
- Evaluates whether the results are sufficient. If not, it plans and executes additional retrieval rounds (up to five by default).
- Returns deduplicated chunks from all iterations, with trace events streaming throughout for full observability.
You can balance accuracy and latency for your use case. The maxAgentIteration parameter controls how many rounds the model performs, and you select the foundation model used for planning and evaluation.
The following code shows an example of invoking Agentic Retrieval and processing its streaming response. The request specifies the user’s query, the knowledge base to search, the foundation model to use for planning and evaluation, and the maximum number of retrieval iterations. As the service runs, it streams trace events that show each planning step and sub-query being executed, followed by the final retrieval results:
bedrock_runtime = boto3.client('bedrock-agent-runtime', region_name='us-west-2')

response = bedrock_runtime.agentic_retrieve_stream(
    messages=[{
        'role': 'user',
        'content': [{'text': 'Compare the pricing tiers of Product A and Product B'}]
    }],
    retrievers=[{
        'knowledgeBaseRetriever': {
            'knowledgeBaseId': kb_id,
            'maxResults': 10
        }
    }],
    agenticRetrieveConfiguration={
        'foundationModel': {
            'modelArn': 'arn:aws:bedrock:us-west-2::foundation-model/anthropic.claude-sonnet-4-20250514'
        },
        'maxAgentIteration': 5  # 1-10, default 5
    }
)

# Trace events stream in real time, then final results arrive
for event in response['stream']:
    if 'trace' in event:
        trace = event['trace']
        if 'planning' in trace:
            print(f"Planning: {len(trace['planning'].get('actions', []))} sub-queries")
        elif 'retrieval' in trace:
            print(f"Retrieving: {trace['retrieval'].get('input', {}).get('text', '')}")
    elif 'retrievalResults' in event:
        results = event['retrievalResults']['results']
        print(f"\n{len(results)} deduplicated results returned")
        for i, r in enumerate(results[:5], 1):
            print(f"  {i}. {r['content']['text'][:150]}...")
Production ready
Getting a Retrieval Augmented Generation (RAG) prototype working is one thing. Operating it at scale with proper access control, observability, and security is where many teams stall. Managed Knowledge Base includes AgentCore Gateway integration, document-level access control, and observability out of the box, so you can deploy without building these layers yourself.
Native AgentCore Gateway integration
Managed Knowledge Bases integrates natively with AgentCore Gateway, giving you a streamlined way to expose your knowledge base to agents. When you add your knowledge base as a target on the gateway, it becomes a tool that agents compatible with the Model Context Protocol (MCP) can discover and invoke automatically. AWS Identity and Access Management (IAM), routing, and observability are centralized at the gateway. You can also use Managed Knowledge Bases standalone by calling the retrieval APIs directly from your application if that better suits your use case.
AgentCore Gateway adds the following to your Managed Knowledge Bases integration:
- Abstracted infrastructure : Knowledge base IDs are hidden behind the gateway, so agents simply discover and call tools by name, decoupling your agent code from underlying infrastructure.
- Framework compatibility : Agents interact through a standardized MCP endpoint, making your knowledge bases instantly compatible with MCP-aware frameworks, including Strands, LangChain, and CrewAI.
- Unified access point : A single gateway URL becomes the access point for your knowledge bases across your organization, simplifying agent configuration and governance.
- Centralized security : IAM policy at the gateway level replaces per-knowledge-base permissions management, giving you one place to enforce security, audit access, and manage scale.
- Transparent operations : Built-in observability, routing, and authentication are handled for you, so you can add, swap, or scale knowledge bases without changing a single line of agent code.
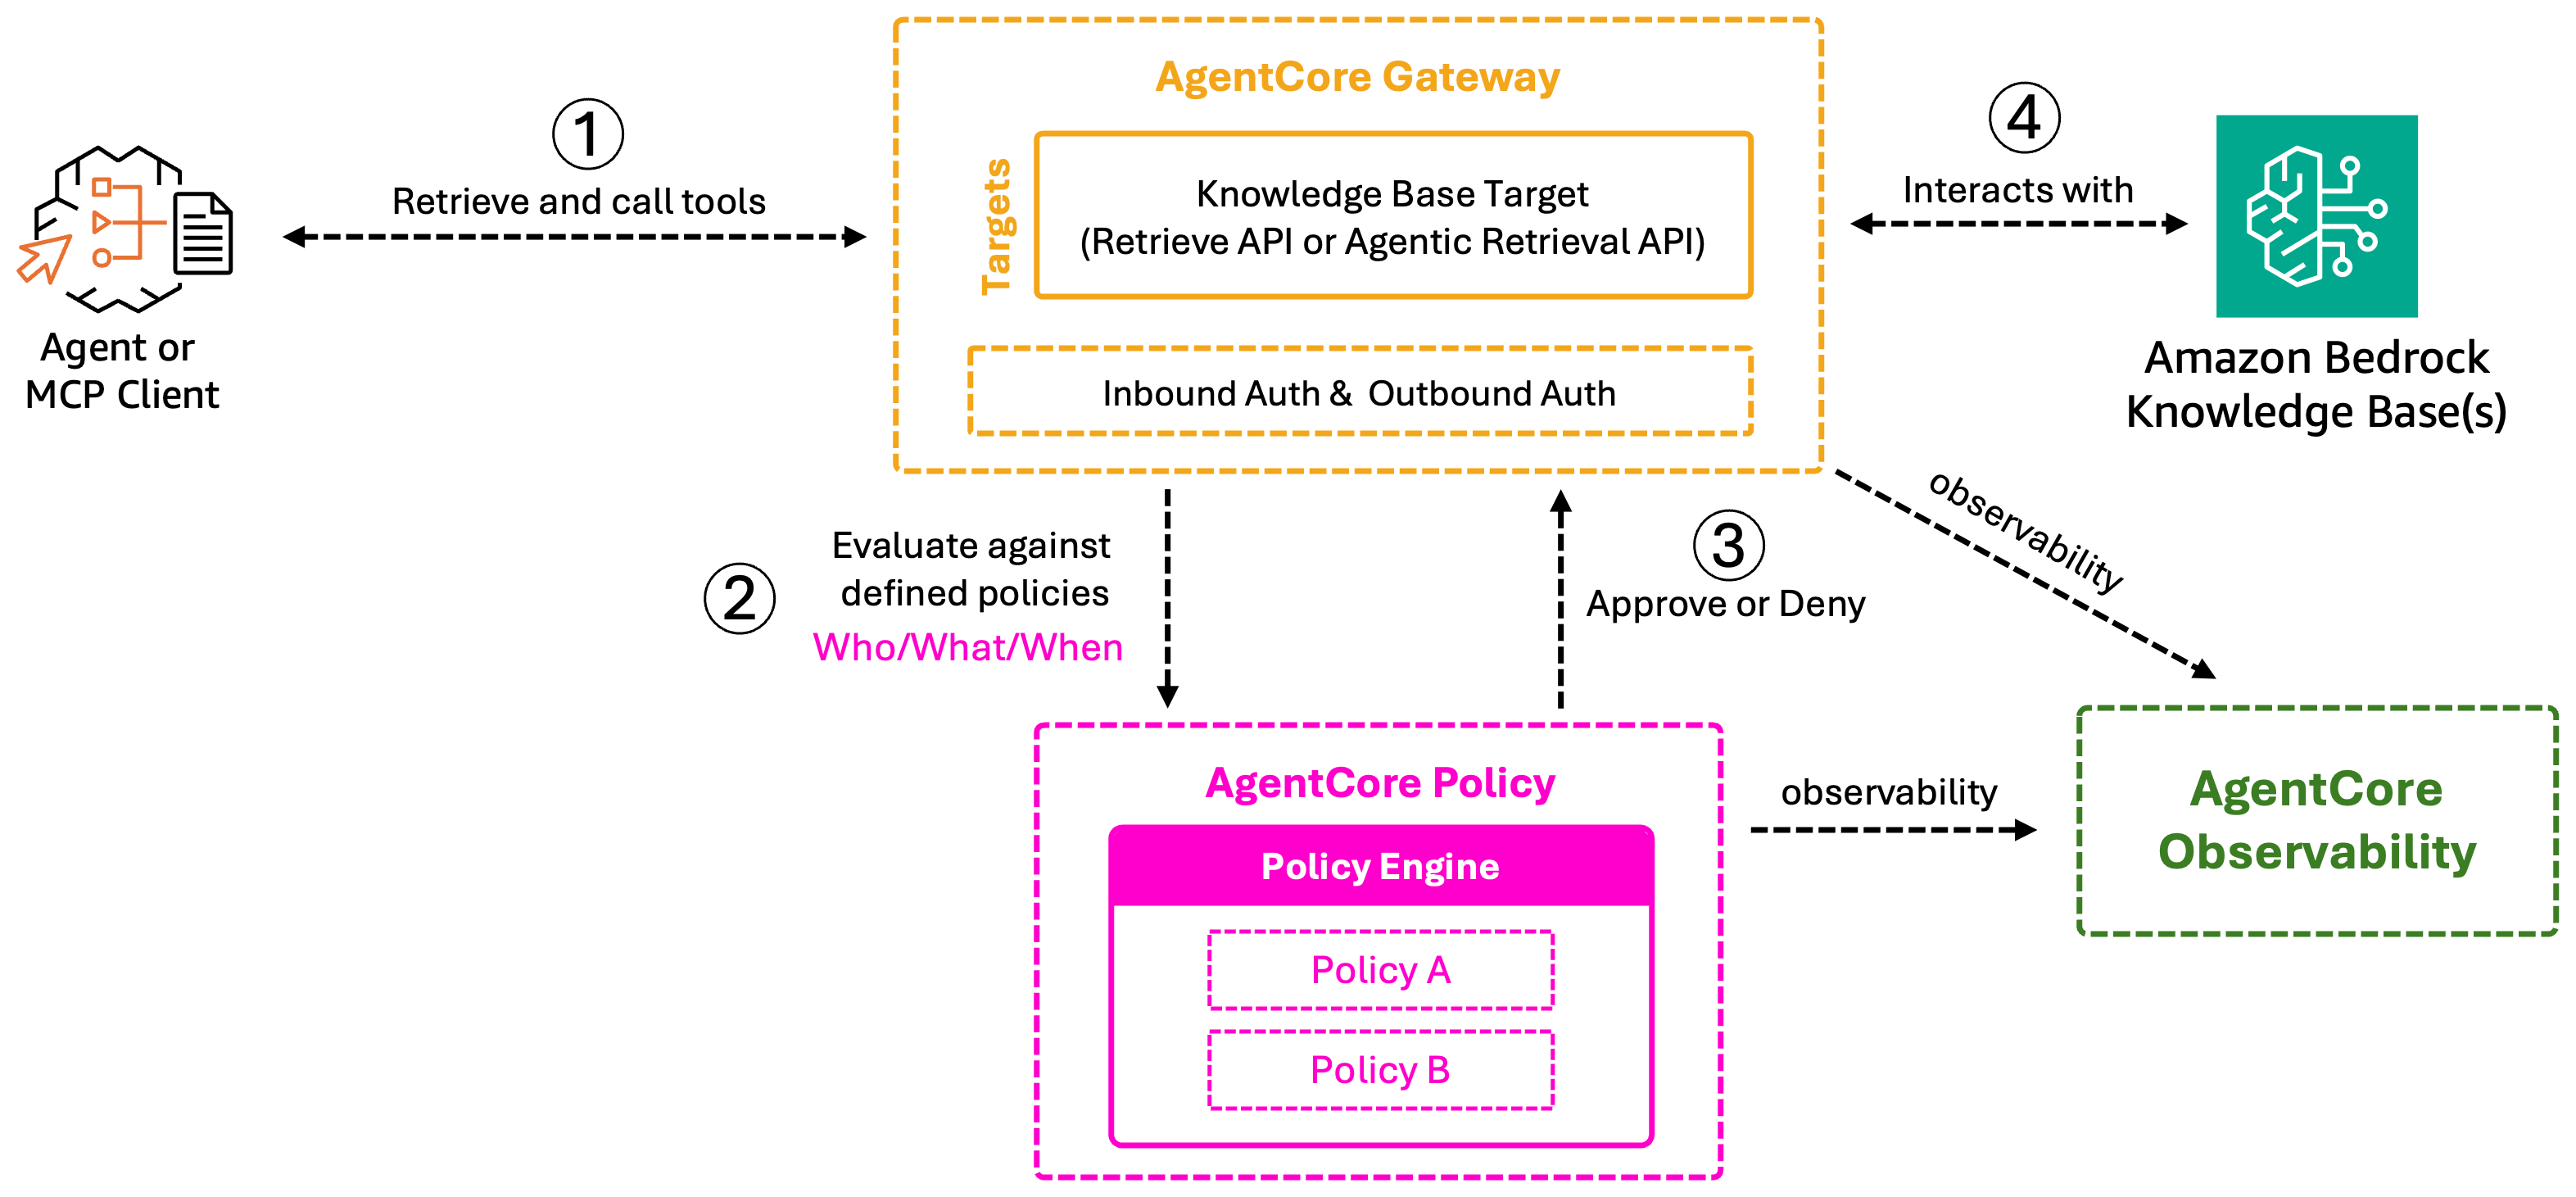
After you create a gateway and add your knowledge base as a target, MCP-compatible agent frameworks can discover and invoke it without knowing the underlying knowledge base ID:
from strands.tools.mcp import MCPClient
from mcp_proxy_for_aws.client import aws_iam_streamablehttp_client

mcp_client = MCPClient(lambda: aws_iam_streamablehttp_client(
    endpoint=gateway_url,
    aws_region='us-west-2',
    aws_service='bedrock-agentcore',
))

with mcp_client:
    # KB tools are auto-discovered via MCP
    tools = mcp_client.list_tools_sync()
    print(f"Available tools: {[t.tool_name for t in tools]}")

    # Retrieve (the agent never sees the KB ID)
    result = mcp_client.call_tool_sync(
        'tool_call_1',
        tools[0].tool_name,
        {'retrievalQuery': {'text': 'What is our total revenue?'}},
    )
This pattern works with Strands, LangChain, CrewAI, or other MCP-compatible frameworks. The gateway handles IAM, routing, and observability transparently.
AtSony , we’re building an agentic chat platform on Amazon Bedrock AgentCore to help teams get trusted answers from complex enterprise content and live web information. With Bedrock Managed Knowledge Base and Web Search now available as tools in AgentCore, our agents can reason across internal PDFs, presentations, spreadsheets, charts, and tables, going beyond simple vector retrieval, and ground responses in current web information while keeping our data within AWS. The result is a single experience for answering questions across internal knowledge and the web
– Masahiro Oba, Senior General Manager, Sony Group Corporation
Observability
Every knowledge base query, whether through the SDK or the gateway, automatically publishes metrics to Amazon CloudWatch under the AWS/Bedrock/KnowledgeBases namespace, including invocations, client and server errors, and throttles. For Agentic Retrieval, trace events stream in real time, showing each planning step, sub-query, and evaluation round. This gives you full visibility into the retrieval process without writing instrumentation code.
For a complete end-to-end walkthrough, check out the notebook on GitHub.
Where Managed Knowledge Base fits
AWS offers multiple options for building the knowledge retrieval that grounds agents, generative AI applications, and RAG pipelines. The right choice depends on how much control you need versus how much you want managed for you. The following diagram shows where Managed Knowledge Base sits along that spectrum, from the highest level of abstraction (Amazon Quick) to building your own RAG pipeline from scratch.
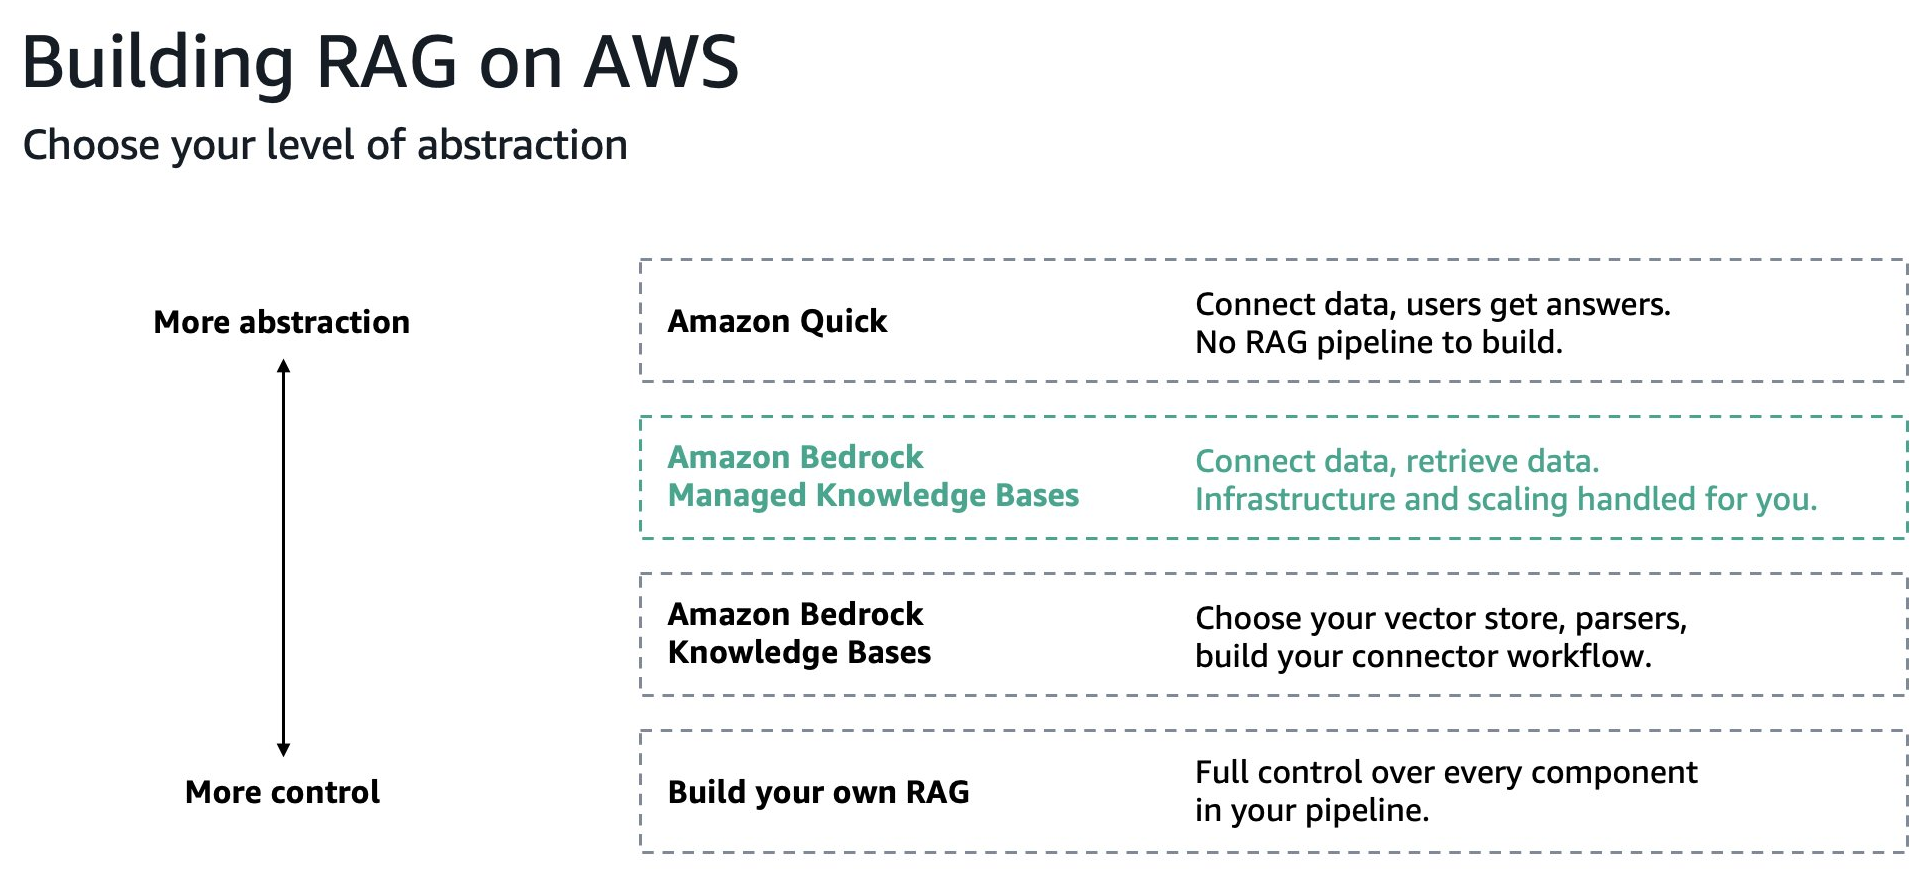
If you need to choose your own vector store and assemble the connector workflow yourself, Amazon Bedrock Knowledge Bases remains available. Managed Knowledge Base is for teams that want to focus on their application rather than the underlying infrastructure, with the service handling storage, scaling, and retrieval on your behalf.
Pricing
Managed Knowledge Bases consolidates pricing into a straightforward, usage-based model rather than spreading costs across multiple capacity units. You pay for storage of your raw data, standard retrieval API calls, and Agentic Retrieval when you need multi-hop reasoning. The multimodal document parser, managed embedding model and managed re-ranker are all included at no extra cost. If you choose to use a different Amazon Bedrock model for embeddings, re-ranking, or orchestration, standard Bedrock pricing applies for those models.
For complete pricing details and worked examples, see the Amazon Bedrock pricing page.
Conclusion
Amazon Bedrock Managed Knowledge Base removes the infrastructure work that sits between your enterprise data and a working retrieval-augmented generation application. Connect your data sources, let the service handle parsing, storage, and indexing, and retrieve using the mode that matches your query complexity.
Document-level access control, real-time ACL checks, and native observability through Amazon CloudWatch are built in, so your knowledge base is ready for production workloads at launch. With native AgentCore Gateway integration, your knowledge bases become tools that MCP-compatible agents can discover and use without custom code.
Managed Knowledge Base is now available in us-east-1 (N. Virginia), us-west-2 (Oregon), eu-west-1 (Dublin), eu-central-1 (Frankfurt), ap-southeast-2 (Sydney), eu-west-2 (London), ap-northeast-1 (Tokyo), and us-gov-west-1 (AWS GovCloud US-West).
To get started, see the documentation or try it out on the AWS Management Console.
About the authors
Dani Mitchell
Dani is a Sr GenAI Specialist Solutions Architect at AWS and the SA lead for Amazon Bedrock Knowledge Bases. He helps enterprises across the world design and deploy generative AI solutions using Amazon Bedrock and Anthropic’s models and capabilities to build scalable, production-ready applications.
Sandeep Singh
Sandeep is a Senior Generative AI Data Scientist at AWS, helping large enterprises innovate with generative AI. He specializes in generative AI, Agentic AI, machine learning, and system design, delivering AI/ML-powered solutions to solve complex business problems across diverse industries.
Siddhant Sahu
Siddhant is a Sr Product Manager at Amazon Web Services, where he focuses on Bedrock Managed Knowledge Bases. He builds agentic search products that help ISVs and enterprises connect generative AI to their enterprise data.
Amit Choudhary
Amit is a Principal Product Manager at AWS, where he currently leads Knowledge Bases for Amazon Quick and leads data ingestion capabilities for Amazon Bedrock Knowledge Bases. His work enables secure AI interactions grounded in enterprise knowledge, transforming how organizations use their data for AI-powered insights and decision-making. Previously, he enabled enterprises to securely connect their data sources to Amazon Q Business for user productivity, and built AWS Clean Rooms Differential Privacy, helping enterprises protect user privacy with mathematical guarantees in just a few steps. Outside of work, he enjoys traveling.