AI Teammates:monday.com 如何在 Amazon Bedrock 上运行生产级 AI Agent
英文标题:AI Teammates: how monday.com runs production AI agents on Amazon Bedrock
monday.com 介绍了其在 Amazon Bedrock 上大规模部署生产级 AI Agent 的架构与实践:九成 Builders 每月使用 AI 编程工具,人均 PR 产出提升超过 50%。其内部 Agent 系统 Sphera 将 Agent 作为具备身份、职责、主管、工作范围和绩效评分的团队成员,通过 Slack、monday 和 GitHub 接收任务。该系统采用 SNS、SQS、EKS、RDS、ElastiCache、EFS、S3 与 Amazon Bedrock 组成事件驱动基础设施,并以评估、文件式记忆、远程沙箱、PR Guardrails 和 CoWORK 协作层适配大型遗留代码库。monday 还披露,首个全自主工程 Agent Morphex 的 PR 有 19/20 能自动合并,显示自动化评审与置信度信号正成为 Agent 迈向自主交付的关键。
 226.3 KB
 103.0 KB
 115.4 KB
 198.3 KB
 75.6 KB
 63.9 KB
 63.9 KB
 66.9 KB
 239.6 KB
 273.6 KB
中文
AI Teammates 是运行在 Amazon Bedrock 上的 Agentic AI,而在生产环境中以 monday.com 这样的规模运行它们的工程组织并不多。十分之九的 Builders 每月都会使用 AI 编程工具,约为一年前比例的一倍;每位工程师的 PR 产出提升了超过一半。本文中的每一项数据,均来自 monday 自身的内部生产数据。
本文将分享这些数据背后的架构、让系统在一个已有十年历史的代码库中运行所需的改造,以及通过置信度评分的合并机制来缩小与完全自主之间差距的方法。
这不是一个绿地项目
monday.com 的代码库已有十年历史,服务数百万付费用户,拥有数百个微前端和微服务,以及数百名 Builders(工程师、产品经理、分析师和产品设计师)。Agent 创建的每个 PR,都会进入一个必须在下一次部署后仍能持续为数百万用户稳定服务的系统。绿地项目中的演示并不难;真正困难的是,在拥有实际值班、客户和合规要求的企业 SaaS 内部运行 Agent。
AI 工程的三个层级
这一演进过程可以分为三个层级:
- L1,助手。 工程师将 AI 作为结对编程伙伴使用。Cursor 用于快速、反射式的工作,Claude Code 用于重度任务。采用率同比接近翻倍。
- L2,技能与子 Agent。 团队为重复性工作构建可复用 Agent,工程师仍处于驾驶席。这是当前 monday 大多数团队所在的阶段,也是每位开发者 PR 产出提升超过一半的阶段。
- L3,多 Agent。 完全 Agent 化。Agent 端到端负责交付,工程师负责编排;Agent 从看板接收任务,在 Slack 和 monday 中沟通,并与人类一起发布代码。
Agent 是队友,不是岗位
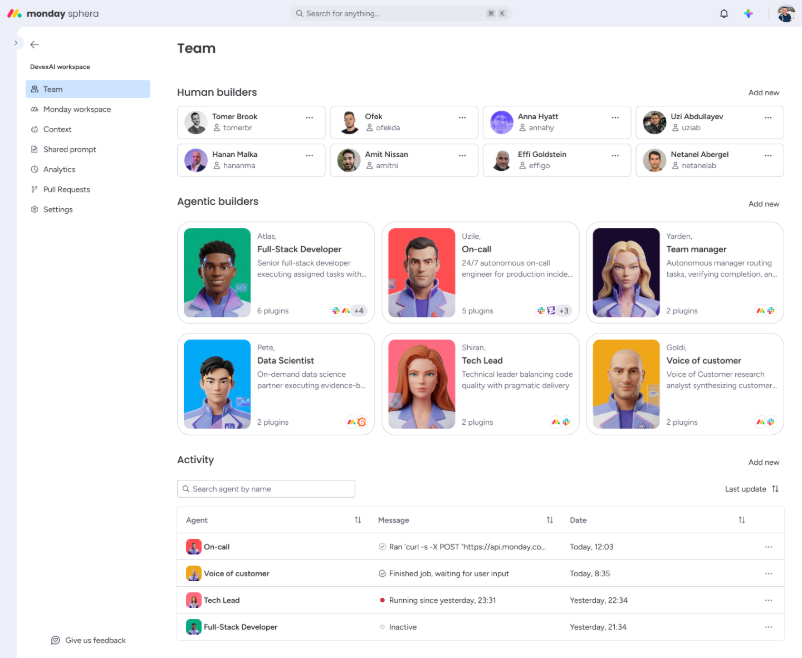
Sphera 是 monday 的内部 Agent 系统。你最先看到的不是任务队列,而是一个 Teams 页面:人类和 Agent 混合在一起,每个成员都拥有个人资料、主管、工作范围和绩效评分。本文的核心 Agent Atlas 就是其中之一:角色是软件工程师;工作是领取工单、编写 PR、发布功能;IDE:无。它与其他所有成员共享同一个待办事项列表。
这并非装饰,而是系统的模式定义。每个 Agent 都有一个稳定身份,贯穿 Slack、GitHub 和 monday,因此人类可以像对待任何其他队友一样,@ 提及、分配任务、进行代码审查,或者停用它们。真正产生影响的 Agent,存在于真实团队中,承担真实工作,并为结果负责。
架构
以下是系统的组成方式:从 Agent 监听的收件箱,到承载每个事件的 AWS 服务。
三个收件箱,一个 Agent
一个由 monday 构建的 Agent 拥有三个一级收件箱:Slack @mention、monday 项目分配、GitHub PR 审查请求。这三者都会进入同一个 Agent 会话,并使用相同的内存和磁盘工作区:它们只是同一种事件的三种形式,使用同一个队列和同一条处理路径。我们并不运行三套 Agent 系统,而是只运行一套。
一张图看懂架构
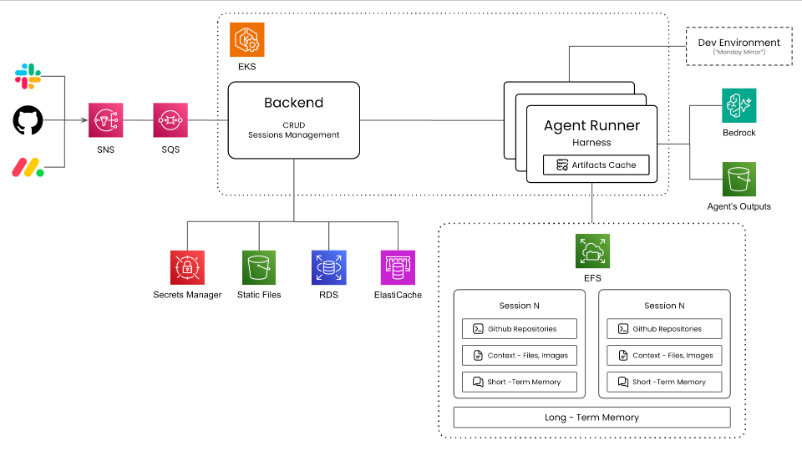
我们使用的七项 AWS 服务分别是 Amazon Simple Notification Service(Amazon SNS)、Amazon Simple Queue Service(Amazon SQS)、Amazon Elastic Kubernetes Service(Amazon EKS)、Amazon Relational Database Service(Amazon RDS)、Amazon ElastiCache、Amazon Elastic File System(Amazon EFS) 和 Amazon Simple Storage Service(Amazon S3)。此外,AWS Secrets Manager 负责按会话管理密钥。Amazon Bedrock 负责模型调用,monday-agent-sdk 则运行在每个 Agent runner Pod 内。
事件路径:从 SNS 到 SQS,再到 monday Builders CoWORK
每个外部触发器都会进入 SNS,随后 SNS 会按主题和路由键将事件扇出到各团队的 SQS 队列。monday Builders CoWORK 是一组部署在 EKS 上的 SQS 消费者;它会拉取每条消息,识别负责该消息的 Agent,并将其交给正确的 Agent runner Pod。
发布/订阅加队列机制带来了四项我们不会放弃的能力:开箱即用的重试与死信队列、Amazon Bedrock 限流时的背压、持久化重放能力(在发布前,我们会使用修补后的构建版本重跑最近一天的事件),以及并发扇出。如果 Claude Agent SDK 在运行时层提供更好的方案,我们就会删除自己的实现。但这个运行框架会保留。
monday-agent-sdk:有意保持轻量的封装
Claude Agent SDK 是运行时。我们对它进行封装有三个原因:
- 调用点的供应商中立性。 Agent 的 LLM 调用会路由到 Amazon Bedrock 模型端点。
- 冷启动成本。 Agent runner 自带已预热的
node_modules和插件缓存,因此第一次模型调用通常可在一秒内发出。 - 我们希望拥有自己的运行框架。 运行时正在成为一种商品能力,运行框架才承载我们的判断:如何评估一个 Agent、如何组合插件、如何与 Slack、monday 和 GitHub 通信、如何根据 monday 标准审查其输出。我们让运行时成为别人的问题,把运行框架变成自己的能力。
状态、记忆与会话
Agent 至少有三类状态。将三者放在同一个存储中,会在成本、延迟或正确性上付出代价。实时状态存放在 Amazon ElastiCache 中,包括当前任务、运行游标、分布式锁、心跳,以及 Agent/人类消息日志。它提供亚毫秒级读取和自动过期的键。Amazon DynamoDB 也可以胜任;但对于这种访问模式,ElastiCache 更便宜也更快。会话与记忆存储在 Amazon Elastic File System 中。每个活跃会话都是共享文件系统上的一个目录:
/sessions/<session-id>/
├── repos/          # checked-out workspace
├── secrets.json    # encrypted per-session secrets
└── messages/       # chronological event log

/agents/<agent-id>/
├── MEMORY.md            # cross-session memory
└── diary/2026-04-21.md  # per-day journal
有两个原因使我们没有使用 S3。第一,Claude Agent SDK 和大多数插件都需要真实的 POSIX 文件系统(git、npm、文件编辑),这消除了整类“开发环境可用、Worker 中崩溃”的问题。第二,当一次运行在不同的 EKS Pod 上恢复时,该 Pod 会挂载同一条 EFS 路径,并从上次中断处继续执行。
Atlas 的每日工作日志是一个真实文件。以下是经过脱敏的片段:
# diary/2026-04-21.md
## In progress
- ENG-3491: rate-limit headers: verify staging, then open PR
- ENG-3502: dependency bump: blocked on Guardrails security-boundary
  rule, waiting on standard-owner review
## What I learned last session
- The accounts-api team files every new error code in the shared
  registry BEFORE the PR opens. I did it in the same PR last time
  and got reverted. Filed the registry update first this time.
这份文件就是 Atlas 在第二天早上恢复工作的方式。他会读取文件,回忆起 accounts-api 团队要求将 errors-registry 更新单独提交,然后开始工作。记忆就是一个可由多个 Pod 挂载的磁盘文件。
持久化记录会进入 S3。最终对话记录、快照、制品和评估结果均以会话 ID 为键存储。EFS 承载工作记忆;S3 则是审计轨迹。
作为模型基础设施的 Amazon Bedrock
Amazon Bedrock 不仅是一个获取 token 的地方。它使我们能够运行数百个 Agent,同时不失去对成本、安全性或容量的掌控。在大规模部署 Agent 时,大部分运维要求已经是 Amazon Bedrock 的现有功能:
- Application Inference Profiles 路由每一次模型调用,因此成本跟踪和容量规划都集中在一处。
- 每次模型调用都有一条统一审计轨迹:当安全团队或监管机构询问某个时间窗口内 Agent 向何处发送了哪些内容时,我们有一个统一的查询位置。
- 当某个 AWS Region 遭到限流时可进行跨 Region 故障转移,Agent 代码无需感知。
- AWS PrivateLink 端点让模型流量保持在我们的虚拟私有云(VPC)内部。
在 EKS 上运行
计算集群采用 Amazon EKS,每个活跃 Agent 会话对应一个 Pod,并挂载该 Agent 的 EFS 工作区。故障隔离以会话为单位。自动扩缩容由 KEDA 根据 Datadog 监测的 Pod 平均活跃会话数驱动。我们运行单一 Worker 镜像;代码仓库会缓存到 EFS 并在各会话间复用。没有服务网格,也没有编排器之上的编排器。EKS、SQS 和缓存层共同承载负载。
让一切真正运转的五项改造
架构只是基础。以下五项改造,才让 Agent 能在一个已有十年历史的代码库中发挥作用。它们都不复杂,但在真正遇到问题前并不显而易见:
在模型升级前先做评估
“看起来没问题”曾是 Atlas 早期 PR 的标准。随着数量增长,这个标准失效了。我们增加了两层评估:每个 Agent 的确定性指标(已合并 PR 数、回滚率、零人工介入合并率),以及针对每个 PR、涵盖五个维度的 LLM 评分评估:意图与决策、执行与制品、完整性与实用性、指令与边界、效率。两类评估都会反馈至运行框架。在 Atlas 的连续版本中,我们没有改变模型、提示词或人工推动方式,只改变了评估,所有维度的得分都得到了提升。
记忆是文件,而不是向量数据库
会话 1:Atlas 完成了一个功能。会话 2:他完全不知道会话 1 曾经发生过。我们尝试了向上下文窗口塞入内容,以及针对过往对话记录的向量检索,两种方法都效果不佳。真正有效的方法是:在会话结束时写入每个 Agent 的 MEMORY.md 和 diary/YYYY-MM-DD.md,并在会话开始时读取。普通 Markdown,不需要嵌入、召回评分,也不需要 Agentic RAG 的繁琐仪式。
在人工审查之前使用远程沙箱
Atlas 最初的十几个 PR 通过了本地测试,却在 CI 中失败。monday 规模的代码库依赖于仅存在于真实环境中的要素:功能开关、第三方服务和真实流量。我们为 Atlas 的每个会话提供远程沙箱,每个 PR 都会自动部署到该沙箱。在请求人工审查之前,测试、检查和重放的生产流量都会先运行:如果失败,修复后再次发布;不需要人工介入。
PR Guardrails:根据 monday 标准自动审查
Atlas 发布得更多了,而人工审查成了瓶颈。我们将每一项 monday 工程标准都转化为自动审查能力:指标标记、功能开关规范、Datadog 使用、安全边界、数据库与微服务约定、测试质量、文档要求。其中一部分属于阻断性规则。每项规则都通过 monday 的 MCP 服务器连接内部知识,因此审查器能够看到标准负责人团队所能看到的相同上下文。
每个 PR——无论由 Agent 还是人类创建——都会经过 Guardrails。在这一规模下,意味着每月评估数万个 PR,并执行数十万次标准检查。约五分之一的 PR 至少有一项标准不合格,会被退回;人工覆盖的比例则处于低个位数。系统负责管理执行,而不是让人工审查者承担这一工作。
Builders CoWORK:以 monday 看板作为共享状态层
最后一种失败模式代价最高:处于孤岛中的 Agent 创建了没有任何团队负责的 PR。我们新增了 CoWORK 工作区,即路由事件的同一 monday Builders CoWORK 面向用户的界面。现在,Agent 的任务、状态、阻碍和交接都与团队成员一起存在于同一个 monday 看板上,因此责任归属不再是系统问题:monday 已经为人类解决了这个问题。
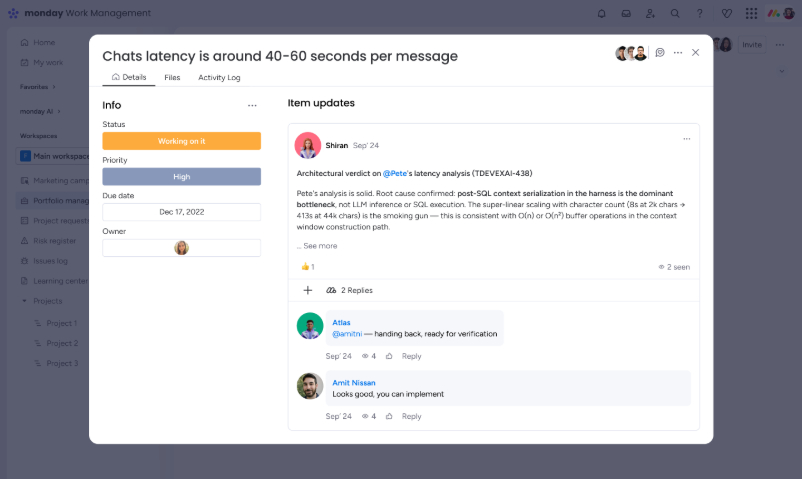
在协作空间中工作的 Agent
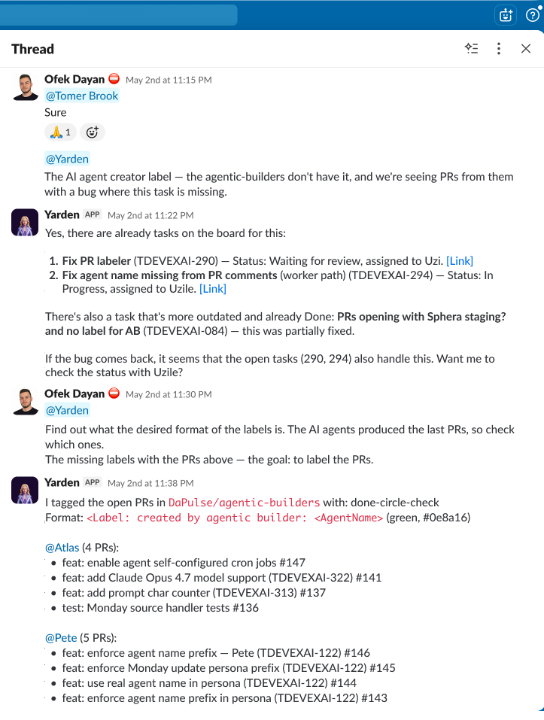
Agent 是可以请求其共享信息或执行任务的同事,就像任何其他队友一样
从一个瓶颈走向下一个瓶颈
到 2026 年第一季度末,瓶颈不再是代码生成,而是人工审查:Guardrails 捕获了过去由人类发现的问题,但每个 PR 仍需等待人工批准。下一道壁垒就是这一环节。
许多尝试中的第一个:Morphex
Morphex 是 monday 首个完全自主的工程 Agent,在与每位 Builder 相同的代码仓库、CI 流水线、Guardrails 和回滚协议中工作。每 20 个 Morphex PR 中有 19 个能够自动合并,这并非跳过审查,而是因为它们通过了每一个关卡;获批 PR 无需人工介入即可发布到生产环境。它每月创建的 PR 比大多数工程师都多;而被拒绝的 PR 与任何工程师的 PR 一样,失败原因包括不稳定测试、模糊的规格说明以及未处理的边缘情况。
这一 19/20 的比例是下限,而非上限。尚待解决的问题是:什么信号能让我们提前判断哪些 PR 可以在无人类参与的情况下安全合并?
信号:近期一次严格的数据切分
在我们 PR 产出最高的 Agent 中(没有挑选样本),数据呈现出清晰的分布:约十分之三的 PR 被合并,其中约四分之三没有任何人工编辑,回滚率处于低个位数。约四分之一的 PR 在到达人类审查者之前,就被 Guardrails 发现并拒绝。
最后一个数字最重要。Guardrails 阻止了四分之一的 Agent PR,因为系统识别出它们尚未准备就绪,从而留下了一组经过预筛选的可合并 PR。低个位数的
English / 原文
AI Teammates are agentic AI on Amazon Bedrock, and few engineering organizations run them in production at the scale that monday.com does. Nine in ten Builders use AI coding tools every month, up from roughly half a year ago. Per-engineer PR throughput is up by more than half. Every figure in this post comes from monday’s own internal production data.
In this post, we share the architecture behind those numbers, the retrofits that made it work in a decade-old code base, and the confidence-scored merge play closing the gap to full autonomy.
This is not a greenfield
monday.com is a decade-old code base, millions of paying users, hundreds of microfrontends and microservices, hundreds of Builders (Engineers, PMs, Analysts, and Product designers). Every PR an agent opens goes into a system millions of users expect to keep working through the next deploy. Greenfield demos are straightforward. Running agents inside an enterprise SaaS with real on-call, customers, and compliance is the work.
Three levels of AI engineering
You can frame the journey as three levels:
- L1, the assistant. Engineers use AI as a pair programmer. Cursor for the fast reflexive work, Claude Code for the heavy lifts. Adoption has nearly doubled year over year.
- L2, skills and sub-agents. Teams build reusable agents for repeated work, engineers in the driver’s seat. This is where most of monday runs today, and where per-developer PR throughput stepped up by more than half.
- L3, multi-agent. Fully agentic. Agents own delivery end-to-end while engineers orchestrate, taking tasks from boards, talking in Slack and monday, shipping code alongside humans.
Agents are teammates, not jobs
Sphera is monday’s internal agent system. The first thing you see isn’t a job queue, it’s a Teams page: a mix of humans and agents, each with a profile, a manager, a scope, and a performance score. Atlas, the agent at the center of this post, is one of them: role: Software Engineer. Job: pick up tickets, write the PR, ship the feature. IDE: none. Same backlog as everyone else.
This isn’t decoration, it’s the schema. Every agent has a stable identity that flows through Slack, GitHub, and monday, so a human tags, assigns, code-reviews, or deactivates them like any other teammate. The agents that move the needle live on real teams, doing real work, accountable for the result.
The architecture
Here is how the system fits together, from the inboxes an agent listens on to the AWS services that carry each event.
Three inboxes, one agent
A monday-built agent has three first-class inboxes: a Slack @mention, a monday item assignment, a GitHub PR review request. All three hit the same agent session, with the same memory and workspace on disk: three flavors of the same event, same queue, same path. We don’t run three agent systems. We run one.
The architecture in one diagram
The seven AWS services that we used are Amazon Simple Notification Service (Amazon SNS), Amazon Simple Queue Service (Amazon SQS), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Relational Database Service (Amazon RDS), Amazon ElastiCache, Amazon Elastic File System (Amazon EFS), and Amazon Simple Storage Service (Amazon S3). Alongside them, AWS Secrets Manager handles per-session secret management. Amazon Bedrock handles model calls, and monday-agent-sdk runs inside each agent runner pod.
Event path: From SNS to SQS to monday Builders CoWORK
Every external trigger lands in SNS, which fans out to per-team SQS queues by topic and routing key. The monday Builders CoWORK , a set of SQS consumers on EKS, pulls each message, resolves which agent owns it, and hands it to the right agent runner pod.
Pub/sub plus queue gives us four things we won’t give up: retries and dead-letter queues out of the box, back-pressure when Amazon Bedrock throttles, durable replay (we re-run the last day of events against a patched build before promoting), and concurrent fan-out. If the Claude Agent SDK ships something better at the runtime layer, we delete our version. The harness stays.
monday-agent-sdk: A thin wrapper, on purpose
The Claude Agent SDK is the runtime. We wrap it for three reasons:
- Provider neutrality at the call site. Agent LLM calls route into an Amazon Bedrock model endpoint.
- Cold-start cost. Agent runners ship with a warm
node_modulesand plugin caches, so the first model call goes out in usually under a second. - We wanted our own harness. The runtime is becoming a commodity. The harness is where our opinions live: how an agent is evaluated, how plugins compose, how it talks to Slack, monday, and GitHub, how its output is reviewed against monday standards. We keep the runtime someone else’s problem and make the harness ours.
State, memory, sessions
Agents have at least three kinds of state. Putting all three in one store costs you money, latency, or correctness. The live state move to Amazon ElastiCache. Current task, run cursor, distributed lock, heartbeat, and the agent/human message log. Sub-millisecond reads, self-expiring keys. Amazon DynamoDB would work; ElastiCache is cheaper and faster for this shape of access. Sessions and memory get stored in Amazon Elastic File System. Each active session is a directory on a shared filesystem:
/sessions/<session-id>/
├── repos/          # checked-out workspace
├── secrets.json    # encrypted per-session secrets
└── messages/       # chronological event log

/agents/<agent-id>/
├── MEMORY.md            # cross-session memory
└── diary/2026-04-21.md  # per-day journal
Two reasons, not S3. First, the Claude Agent SDK and most plugins expect a real POSIX filesystem (git, npm, file edits), which removes a whole class of “works in dev, breaks in worker” bugs. Second, when a run resumes on a different EKS pod, that pod mounts the same EFS path and picks up where it left off.
Atlas’s daily diary is a real file. A redacted snippet:
# diary/2026-04-21.md
## In progress
- ENG-3491: rate-limit headers: verify staging, then open PR
- ENG-3502: dependency bump: blocked on Guardrails security-boundary
  rule, waiting on standard-owner review
## What I learned last session
- The accounts-api team files every new error code in the shared
  registry BEFORE the PR opens. I did it in the same PR last time
  and got reverted. Filed the registry update first this time.
That file is how Atlas resumes work the next morning . He reads it, recalls that the accounts-api team wants the errors-registry update filed separately, and gets to work. Memory is a file on a disk that more than one pod can mount.
Durable records go to S3. Final transcripts, snapshots, artifacts, and evals are keyed by session ID. EFS holds working memory; S3 is the audit trail.
Amazon Bedrock as the model fabric
Amazon Bedrock is more than a place to get tokens. It’s the service that lets us run hundreds of agents without losing track of cost, safety, or capacity. Most operational requirements for deploying agents at scale are already features in Amazon Bedrock:
- Application Inference Profiles route every model call, so cost tracking and capacity planning stay in one place.
- One audit trail for every model call: when security or a regulator asks what agents sent where in a window, we have one place to answer.
- Cross-Region failover when an AWS Region throttles. Agent code doesn’t notice.
- AWS PrivateLink endpoints keep model traffic inside our virtual private cloud (VPC).
Running on EKS
The compute fleet is Amazon EKS, one pod per active agent session, mounting the agent’s EFS workspace. Crash isolation is per-session. Auto scaling is driven by KEDA on average active sessions across pods, measured using Datadog. We run a single worker image. Repos are cached on EFS and reused across sessions. No service mesh, no orchestrator-of-orchestrators. EKS, SQS, and the cache layer carry the load.
Five retrofits that made it all work
Architecture is the floor. The following five retrofits are what made agents useful inside a decade-old code base. None are exotic. All were unobvious until we hit them:
Evals before model upgrades
“Looks fine” was the bar for Atlas’s early PRs. It broke once volume picked up. We added two eval layers: deterministic metrics (PRs merged, revert rate, zero-touch merge rate) per agent, and LLM-scored evals across five dimensions per PR: Intent & Decision, Execution & Artifact, Completeness & Usefulness, Instruction & Boundary, Efficiency. Both feed back into the harness. Across successive versions of Atlas we changed no model, no prompts, no human nudges, only the evals, and scores moved across every dimension.
Memory is a file, not a vector store
Session 1: Atlas built a feature. Session 2: he had no idea Session 1 had happened. We tried context-window stuffing and vector retrieval over past transcripts. Both worked badly. What worked: a per-agent MEMORY.md and a diary/YYYY-MM-DD.md written at session end, read at session start. Plain markdown, no embeddings, no recall scoring, no agentic-RAG ceremony.
Remote sandbox before human review
Atlas’s first dozen PRs passed local tests and broke in CI. A monday-scale code base has dependencies that only exist in real environments: feature flags, third-party services, real traffic. We gave Atlas a remote sandbox per session, and every PR auto-deploys to it. Tests, checks, and replayed production traffic run before he asks for human review: failure to fix to ship again, no human in the loop.
PR Guardrails: Automated review against monday standards
Atlas was shipping more, and human review became the bottleneck. We turned every monday engineering standard into an automated reviewer: metrics tagging, feature-flag hygiene, Datadog usage, security boundaries, database and microservice conventions, test quality, documentation. A subset are blocking. Each is wired to internal knowledge through monday’s MCP servers, so the reviewer sees the same context the standard-owner team would.
Every PR, agent- and human-authored alike, goes through Guardrails. At scale that means tens of thousands of PRs evaluated per month and hundreds of thousands of standard checks executed. Roughly one in five PRs fails at least one standard and gets bounced back, and human overrides run in the low single digits. The system manages the enforcement, not the human reviewer.
Builders CoWORK: monday boards as the shared state layer
The last failure mode was the most expensive: agents in silos opened PRs no team owned. We added the CoWORK workspace, the user-facing surface of the same monday Builders CoWORK that routes events. An agent’s tasks, status, blockers, and handoffs now live on the same monday board as the team’s, so accountability stopped being a system problem: monday already solved it for humans.
Agents at work in a collaborative space
Agents are co-workers you can ask to share information or perform tasks, like any teammate
From one bottleneck to the next
By late Q1 2026 the bottleneck was no longer code generation but human review: Guardrails caught what humans used to catch, but every PR still waited on a human to approve. That wall was next.
The first of many: Morphex
Morphex is monday’s first fully autonomous engineering agent, working within the same repo, CI pipeline, Guardrails, and revert protocols as every Builder. Nineteen of every twenty Morphex PRs merge automatically, not by skipping review but by passing every gate, and an approved PR ships to production with no human in the loop. It opens more PRs a month than most engineers, and a rejected PR fails for the same reasons any engineer’s does: flaky tests, ambiguous specs, unhandled edge cases.
That 19-in-20 rate is a floor, not a ceiling. The open question: what signal tells us, ahead of time, which PRs are safe to merge without a human.
The signal: A recent rigorous cut
Across our top PR-generating agents (no cherry-picking), the numbers break down cleanly: about three in ten PRs merged, roughly three-quarters of those with zero human edits, and a revert rate in the low single digits. Around a quarter of the PRs were caught and declined by Guardrails before reaching a human at all.
That last number matters most. Guardrails stopped a quarter of agent PRs because the system saw they weren’t ready, leaving a pre-filtered population of merges. A low-single-digit revert rate on that population is the signal that confidence-based auto-merge is workable.
Confidence-scored automatic merging
The confidence score combines four signals available the moment the PR opens:
- Deterministic Guardrails outcome : every blocking standard must pass.
- Per-agent eval trajectory : recent eval-score window for this version of the agent.
- Per-(agent × repo × change-class) historical revert rate : near-zero reverts on dependency-bumps in a low-risk service is a different picture from a higher revert rate on monolith migrations.
- Sandbox outcome : green from retrofit 3 is necessary, not sufficient.
Above the threshold, the PR merges automatically. Below it, it routes to a human with the specific failing signal called out. That’s the L2 to L3 transition: not removing humans, but removing humans from the cases where the system’s signal is strong enough that adding a human doesn’t improve the outcome. We’re driving one metric over the next two quarters: the fraction of merged agent PRs that ship without a human reviewer, holding revert rate flat or improving.
AI engineering isn’t about creating perfect agents. It’s about building feedback loops that let imperfect agents be safely trusted while saving humans time.
Honest close
Why we built it the monday way
The value isn’t the runtime, that’s only a harness around the Claude Agent SDK. It lives in everything we’ve wired around it, and that wiring is monday through and through:
- monday boards as the shared state layer: every agent’s tasks, status, and handoffs live where the rest of the business already looks.
- monday MCP servers as the substrate Guardrails and standards plug into.
- monday’s auth and identity, so every agent has a real Slack, GitHub, and monday user under the same RBAC as any human.
- monday’s deploy pipeline so agent code ships through the same CI/CD as every other Builder.
Agents that share state, identity, and infrastructure with humans don’t need a separate governance layer. The existing one already applies. That makes the system auditable, reversible, and trustworthy by default, not by addition. A boilerplate system would have flattened all of that into someone else’s model.
Three things we’d do differently
Evals should have been in the system on day one, not month nine. The score lift Atlas got from them was the headline result. We over-invested in vector stores before realizing MEMORY.md on EFS was always the right answer. And the first CoWORK lived in a separate workspace that forced humans to context-switch to see what agents were doing. Moving it onto monday boards should have been the first decision, not a later correction.
Conclusion
We’re not open-sourcing monday-agent-sdk. The wrapper is small, and most of its value is the harness, which is monday-specific in ways that wouldn’t help anyone else. What we’re sharing is the architecture and the operational playbook, because the industry moves faster when the teams running production agents at scale are honest about what’s working.
If you’re building agents into your engineering teams, you’ll meet most of the same walls we have, and we’ve already crossed them. Talk to us: the monday AI Engineering team, or the Amazon Bedrock team, will be happy to share our insights.
Learn more
About the authors
Claudio Mazzoni
Claudio is a Sr Specialist Solutions Architect on the Amazon Bedrock GTM team. Claudio excels at guiding customers through their Gen AI journey. Outside of work, Claudio enjoys spending time with family, working in his garden, and cooking Uruguayan food.
Ofek Dayan
Ofek is a Senior Software Engineer at monday.com, focused on building the Sphera AI Agents platform. He develops the infrastructure that enables AI agents to autonomously execute software development tasks and integrate seamlessly into monday.com’s builders teams.
Netanel Abergel
Netanel is a Director of Engineering at monday.com, where he leads AI Engineering and is building the foundation and operating model for AI-native teams. His team is transforming how software is built and operated through agentic development, AI developer platforms, CI/CD, release management, and systems architecture.
Moran Zilberstein
Moran is a Senior Solutions Architect at AWS with over 20 years of experience in coding and architecting business-critical applications. Moran works closely with ISVs, helping them fulfill their potential on AWS platforms. For the past year, she has been partnering with Monday.com on their generative AI journey. Outside of work, Moran enjoys baking and hiking.
Erez Drutin
Erez is a Solutions Architect at AWS with a decade of experience building and leading data-intensive and AI-powered systems. Erez works closely with ISVs, including Monday.com, helping them scale and adopt AI on AWS. Outside of work, Erez enjoys basketball and running.