将 Amazon Bedrock Guardrails 应用于代码生成工作流的最佳实践
英文标题:Best practices for applying Amazon Bedrock Guardrails to code generation workflows
本文介绍如何为 Claude Code、Kiro 和 OpenAI Codex 等编码助手配置 Amazon Bedrock Guardrails,以在大规模代码生成场景中兼顾安全、吞吐和延迟。代码生成通常具有长流式输出、高并发开发会话和重复上下文评估等特点,若直接采用默认内联扫描,可能导致 ThrottlingException、成本上升和响应延迟。文章指出,Guardrails 的文本单元消耗会随内容长度和启用的不同防护策略数量相乘,因此容量规划至关重要。核心建议是采用类似 Git pre-commit hook 的模式,在用户输入、最终代码产物和代码写入或提交等信任边界进行选择性验证,而非持续扫描每个流式输出片段。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 195.7 KB
 67.5 KB
 48.9 KB
 42.9 KB
 14.7 KB
 44.0 KB
中文
本文延续 Amazon Bedrock Guardrails 最佳实践系列。上一篇文章请参阅像专业人士一样构建安全的生成式 AI 应用:Amazon Bedrock Guardrails 最佳实践。
由 AI 驱动的编码助手和代码生成工作流,例如 Claude Code、Kiro 和 OpenAI Codex,正在改变开发者编写软件的方式。这些工具通过流式响应实时生成代码,通常会在较长的会话中产生数千个字符。随着组织借助这些助手大规模采用包含代码的生成式 AI 工作流,必须能够在需要时检测并阻止不安全的代码模式。Amazon Bedrock Guardrails 可帮助检测和过滤不安全及不需要的代码内容,其防护机制包括:用于内容审核的内容过滤器、针对越狱、提示注入和提示泄露的提示攻击防护、用于脱敏和阻止个人身份信息(PII)的敏感信息过滤器等。
但是,编码工作流及其中的 Agent 循环具有独特的吞吐特征,包括较长的流式输出、并发开发者会话以及重复的上下文评估。如果未进行适当配置便将 Amazon Bedrock Guardrails 应用于具有这些特征的工作流,可能会导致限流错误、成本增加和非最优延迟等限制。本文将说明如何为采用编码助手的代码生成工作流配置 Amazon Bedrock Guardrails,以克服这些限制。借助这些最佳实践,您可以构建高效的蓝图,在实现稳健安全覆盖的同时,帮助您进行有效的容量规划。
为什么 Guardrails 对代码生成工作流至关重要
Amazon Bedrock Guardrails 提供全面的防护能力,可检测并过滤用户输入和模型响应中的有害及不需要内容,帮助构建安全的生成式 AI 应用。虽然这些防护能力可以在各种应用中进行配置和实施,但其中一些特定防护措施可用于防范有害代码模式,例如:
- 检测提示攻击 – 阻止试图操纵模型生成恶意代码或绕过指令的行为。
- 过滤敏感信息 – 可帮助阻止或掩盖用户输入和模型响应中的敏感信息,例如个人身份信息(PII)和自定义正则表达式;还能在硬编码的 AWS 访问密钥、数据库连接字符串或私钥出现在生成代码中之前将其捕获。
- 内容审核 – 检测并过滤用户提示和模型响应中的有害内容,包括违反组织可接受使用策略的内容。
- 阻止被拒绝主题 – 定义自定义主题,作为阻止与禁止活动相关对话的依据,例如生成用于绕过身份验证机制的代码,或协助未授权访问模式。
当 AI 生成的代码被用于生产系统时,这些防护措施至关重要。
一个场景:当有效的 Guardrails 适得其反
某客户系统团队刚刚为 15 名开发者部署了 Amazon Bedrock 上的 Claude Code。他们配置了一个包含三项防护措施的 guardrail:用于帮助防止注入的提示攻击检测、用于脱敏或阻止泄露凭证的敏感信息过滤器,以及用于阻止不安全代码模式的内容过滤器。在只有两名开发者参与的试点期间,一切运行良好。试点成功后,全部 15 名开发者同时开始编码会话。几分钟内,团队开始报告错误:Amazon Bedrock 模型推理返回 ThrottlingException。代码补全在流式输出过程中停滞。开发者感到沮丧,Slack 频道也迅速被消息刷屏。
发生了什么? 每个开发者的会话平均会为每个函数生成约 5,000 个字符的代码。采用默认流式配置时,Amazon Bedrock 每生成 50 个字符就会评估一次 guardrails,因此每位开发者、每个函数会触发 100 次 API 调用。将其扩展至 15 个并发会话,系统每秒会生成 1,500 个评估请求。更糟糕的是,由于启用了 3 项防护措施,每次评估消耗 3 个文本单元而非 1 个,使吞吐消耗增加至三倍。
根本原因并非配额不足,而是架构不匹配。他们将为简短对话交互设计的模式应用到了高吞吐代码生成管道中。本文将提供解决这一问题的架构模式。
文本单元:Guardrails 的计量货币
在深入架构之前,了解 guardrail 消耗的计算方式非常重要,因为这是后续每项优化的关键。
一个文本单元定义为文本中的 1,000 个字符。一次 ApplyGuardrail API 调用若对 1,000 个字符的文本使用 3 项防护措施进行评估,则会产生 3 个文本单元的消耗。
关键在于,消耗具有乘法效应。它会同时随内容长度和启用的防护措施数量增长。
对于输出通常较长的代码生成工作流(每个函数可达数千个字符),这种乘法关系是容量规划中的关键因素。配置了内容过滤器、被拒绝主题和敏感信息过滤器的 guardrail,会根据每项防护措施或过滤器处理的文本单元数量进行计量。
注意: 无论在内容过滤器中启用了多少类别(仇恨、侮辱、色情、暴力、不当行为、提示攻击),内容过滤器每处理 1,000 个字符均仅计为一个文本单元。例如,即使启用全部六个内容过滤类别,仍只计为一个文本单元,而不是六个。乘法关系适用于不同策略类型之间(内容过滤器、被拒绝主题、敏感信息过滤器),而不适用于同一策略类型中的不同类别。
挑战:代码生成工作流可能触发限流
传统对话式 AI 工作流涉及简短、离散的用户提示和模型响应。代码生成工作流在以下方面有所不同,并会直接影响 guardrail 架构:
下表展示了代码生成工作流为何具有独特的高要求:
| 特征 | 对话式 AI | 代码生成 |
|---|---|---|
| 输出长度 | 100-500 个字符 | 5,000-50,000+ 个字符 |
| 会话时长 | 单轮或少数几轮 | 长时间多轮会话 |
| 并发用户 | 通常为异步 | 团队成员同时编码 |
| 上下文复用 | 极少 | 每一轮都会重新发送系统提示、工具定义和先前代码 |
| 中间输出 | 极少 | 大量链式思维推理 |
这些差异意味着,内联扫描方式——即 guardrails 在流式输出生成时评估每个输出块——会产生与实际安全价值不成比例的大量评估请求。
最佳实践:代码生成工作流的架构模式
为应对这些挑战,我们建议采用一组优化代码生成工作流中 guardrail 使用方式的架构模式。每种模式都针对问题的特定方面,从降低评估频率到仅选择性扫描高风险内容。您可以根据工作负载特征和安全要求,单独使用这些模式,或将其组合使用。
架构模式 1:pre-commit hook 模型
理解内联扫描:默认方法
当您使用 Converse 或 InvokeModel API,通过 guardrailConfig 将 guardrails 直接附加到模型调用时,使用的就是所谓的_内联扫描_。在这种模式下,Amazon Bedrock Guardrails 会在 token 生成期间,持续实时地根据已启用的防护措施自动评估完整输入提示和流式输出。对于传统对话式 AI,这种方法效果良好:提示很短、响应简洁,评估开销可以忽略不计。
但对于代码生成工作流,内联扫描会成为低效的额外负担。它会增加成本并消耗配额,却无法显著改善您的安全态势。编码助手生成的不只是简短响应,它还会流式输出数千个字符的代码,其间穿插推理、注释和迭代式优化。启用内联评估后,每个输出块都会针对每项已配置防护措施进行扫描,其中包括自上次评估后未发生变化的静态系统提示和先前生成的上下文。结果便是重复工作:相同的样板指令、工具定义和先前对话历史会在一轮又一轮中被重复评估,消耗文本单元却不增加安全价值。
核心最佳实践是从持续内联扫描转向在战略性检查点进行选择性验证,这类似于 Git 工作流中的 pre-commit hook。不要在每个 token 流式输出时进行扫描,而应在风险特征发生变化的明确定义边界进行内容验证。
为什么“pre-commit hook”思维有效
软件开发者不会在每输入一行代码后就运行 linter、格式化工具和安全扫描器,而是在提交时进行验证。他们不会验证每一次中间编辑、每一条删除的代码或每一个尚未写完的函数,而是在_最重要的时刻_对_最终完成的结果_进行验证。
在 Git 工作流中,pre-commit hook 是一个会在特定且明确定义的边界自动运行的脚本:即您尝试将代码提交到代码仓库的时刻。它是您的变更成为共享代码库一部分之前的最后一道关卡。在这个检查点,您会针对即将持久化的最终产物,一次性执行全部验证和测试。
这种模式之所以有效,是因为它平衡了两项相互竞争的需求:全面性(每项已提交的变更都会得到完整验证)和效率(仅当风险特征发生变化,即代码从“进行中的草稿”变为“即将持久化的产物”时,才进行验证)。
将该模式应用于 Amazon Bedrock Guardrails
核心最佳实践是将相同原则应用于 Amazon Bedrock Guardrails:从持续内联扫描转向在战略性检查点进行选择性验证。
您可以将代码生成管道视为具有自然提交点的流程,也就是内容从一个信任级别转变为另一个信任级别的时刻:
- 接收用户输入 – 内容从不受信任的来源进入系统(在此处验证)。
- 最终代码产物组装完成 – 模型的完整响应已准备好呈现或保存(在此处验证)。
- 代码写入文件或提交至代码仓库 – AI 生成的内容即将成为持久化且可能可执行的内容(在此处验证)。
在这些检查点之间,当模型正在推理、生成中间 token 或输出链式思维说明时,内容是暂时性的,尚未跨越信任边界。持续扫描这些内容会增加成本并消耗配额,却无法显著改善您的安全态势。
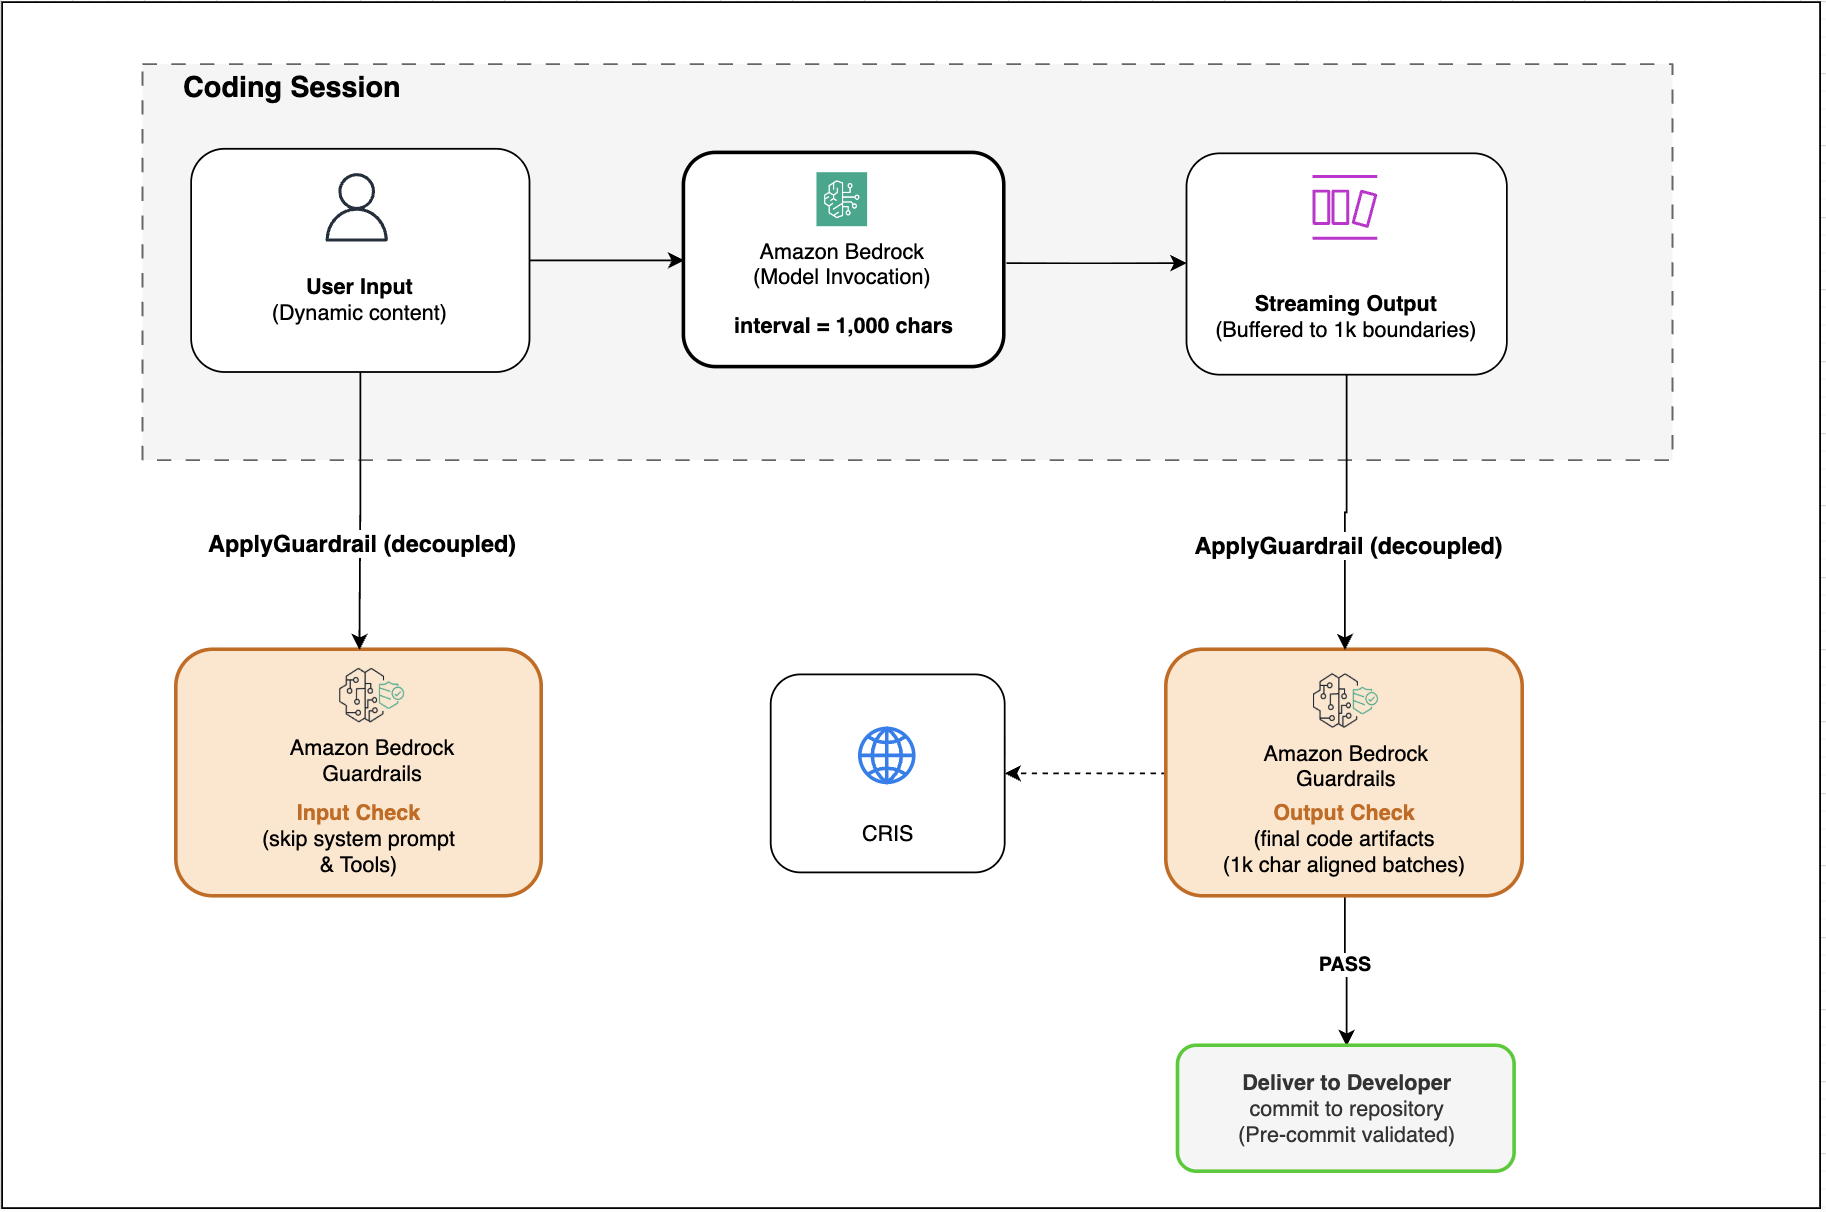
关键原则:使用解耦的 ApplyGuardrail API,在用户提供的输入到达模型之前对其进行评估;并在汇总后的最终代码产物被提交前进行验证,而不是评估每一个中间推理 token。
实施:针对文件操作的 pre-commit 验证
针对风险最高的检查点——即 AI 生成的代码即将写入文件或提交到代码仓库时——应执行全面的 guardrail 评估。这是直接应用的 pre-commit hook 模式:
import hashlib
from pathlib import Path

class CodeCommitGuardrail:
    """
    Validates all AI-generated code changes before they are persisted.
    Analogous to running security scanners in a Git pre-commit hook.

    Use this when:
    - A coding assistant writes code to disk
    - AI-generated changes are staged for commit
    - Generated code is about to be deployed
    """

    def __init__(self, client, guardrail_id, guardrail_version):
        self.client = client
        self.guardrail_id = guardrail_id
        self.guardrail_version = guardrail_version
        self.validated_hashes = {}  # Cache: don't re-validate unchanged files

    def validate_file_changes(self, staged_files: dict) -> dict:
        """
        Evaluate all staged AI-generated code changes before commit.

        Args:
            staged_files: Dict of {file_path: file_content} for all changed files

        Returns:
            Dict with 'safe' boolean and any violations found
        """
        violations = []
        skipped = []

        for file_path, content in staged_files.items():
            # Skip files that haven't changed since last validation
            content_hash = hashlib.sha256(content.encode()).hexdigest()
            if self.validated_hashes.get(file_path) == content_hash:
                skipped.append(file_path)
                continue

            # Evaluate in 1,000-char aligned chunks
            file_violations = self._evaluate_file(file_path, content)

            if file_violations:
                violations.extend(file_violations)
English / 原文
This post continues our series on best practices with Amazon Bedrock Guardrails. For the previous post, seeBuild safe generative AI applications like a pro: best practices with Amazon Bedrock Guardrails.
AI-powered coding assistants and code generation workflows, such as Claude Code, Kiro, and OpenAI Codex, are transforming how developers write software. These tools generate code in real time through streaming responses, often producing thousands of characters across extended sessions. As organizations adopt generative AI workflows with code at scale using these assistants, it is important that unsafe code patterns are detected and blocked whenever required. Amazon Bedrock Guardrails helps detect and filter unsafe and undesired code content with safeguards such as content filters for content moderation, prompt attack prevention with jailbreaks, prompt injection, and prompt leakage, sensitive information filters to redact and block personally identifiable information (PII), and more.
However, coding workflows along with agentic loops have unique throughput characteristics including long streaming outputs, concurrent developer sessions, and repetitive context evaluation. Applying Amazon Bedrock Guardrails to workflows with these characteristics without proper configuration could potentially lead to constraints such as throttling errors, increased costs, and less than optimal latency. In this post, we explain how Amazon Bedrock Guardrails can be configured for code generation workflows with coding assistants to overcome these constraints. With these best practices, you can build an efficient blueprint helping you with effective capacity planning with robust safety coverage.
Why guardrails are important for code generation workflows
Amazon Bedrock Guardrails offers comprehensive safeguards that detect and filter harmful and undesirable content from both user inputs and model responses, to help build safe generative AI applications. While these safeguards can be configured and implemented across a variety of applications, there are specific safeguards that can be used to protect harmful code patterns such as:
- Detect prompt attacks – block attempts to manipulate the model into generating malicious code or bypassing instructions.
- Filter sensitive information – can help block or mask sensitive information such as personally identifiable information (PII), custom regex in user inputs and model responses, catch hardcoded AWS access keys, database connection strings, or private keys before they appear in generated code.
- Content moderation – detect and filter harmful content in user prompts and model responses, including content that violates your organization’s acceptable use policies.
- Block denied topics – define custom topics that are used as a basis for blocking conversations related to prohibited activities, such as generating code to bypass authentication mechanisms or assisting with unauthorized access patterns.
These safeguards are essential when AI-generated code is used in production systems.
A scenario: When good guardrails go sideways
A customer system team has just rolled out Claude Code on Amazon Bedrock to 15 developers. They’ve configured a guardrail with three safeguards: prompt attack detection to help prevent injection, a sensitive information filter to redact or block leaked credentials, and a content filter to block unsafe code patterns. Everything worked perfectly during the pilot with two developers. After a successful pilot, all 15 developers start their coding sessions simultaneously. Within minutes, their team starts reporting errors: ThrottlingException responses from Amazon Bedrock model inference. Code completions stall mid-stream. Developers are frustrated, and their Slack channel lights up.
What happened? Each developer’s session generates roughly 5,000 characters of code per function on average. With the default streaming configuration, Amazon Bedrock evaluates guardrails for every 50 characters, triggering 100 API calls per function, per developer. Multiply across 15 concurrent sessions, and the system generates 1,500 evaluation requests per second. Worse, because they have 3 safeguards active, each evaluation consumes 3 text units instead of 1, tripling throughput consumption.
The root cause wasn’t insufficient quota. It was an architectural mismatch. They applied a pattern designed for short conversational exchanges to a high-throughput code generation pipeline. This post provides architectural patterns to solve this problem.
Text units: The guardrails currency
Before diving into architecture, it’s important to understand how guardrail consumption is calculated, because it’s the key to every optimization that follows.
A text unit is defined as 1,000 characters in the text. An ApplyGuardrail API call with 1,000 characters of text evaluated against 3 safeguards generates 3 text units of consumption.
Critically, consumption is multiplicative. It scales with both content length and the number of active safeguards.
For code generation workflows where outputs are typically verbose (thousands of characters per function), this multiplicative relationship is a critical factor in capacity planning. A guardrail configured with content filters, denied topics, and sensitive information filters is metered based on the number of text units processed by each safeguard or filter.
Note: Content filters are charged as a single text unit per 1,000 characters regardless of how many categories (Hate, Insults, Sexual, Violence, Misconduct, Prompt Attack) are enabled within the filter. For example, if you enable all six content filter categories, it still counts as one text unit, not six. The multiplicative relationship applies across distinct policy types (content filters, denied topics, sensitive information filters), not across categories within a single policy type.
The challenge: Code generation workflows could trigger throttling
Traditional conversational AI workflows involve short, discrete user prompts and model responses. Code generation workflows differ in ways that directly impact guardrail architecture:
The following table shows why code generation workflows are uniquely demanding:
| Characteristic | Conversational AI | Code Generation |
|---|---|---|
| Output length | 100-500 characters | 5,000-50,000+ characters |
| Session duration | Single turn or few turns | Extended multi-turn sessions |
| Concurrent users | Typically, asynchronous | Teams coding simultaneously |
| Context reuse | Minimal | System prompts, tool definitions, and prior code resent every turn |
| Intermediate output | Minimal | Extensive chain-of-thought reasoning |
These differences mean that an inline scanning approach, where guardrails evaluate every chunk of streamed output as it’s generated, creates a volume of evaluations that’s disproportionate to the actual safety value delivered.
Best Practices: Architecture Patterns for Code Generation Workflows
To address these challenges, we recommend a set of architecture patterns that optimize guardrail usage for code generation workflows. Each pattern targets a specific aspect of the problem — from reducing evaluation frequency to selectively scanning only high-risk content. You can apply these patterns individually or combine them based on your workload characteristics and safety requirements.
Architecture pattern 1: The pre-commit hook model
Understanding inline scanning: the default approach
When you attach guardrails directly to model invocation using guardrailConfig with the Converse or InvokeModel APIs, you’re using what’s known as inline scanning. In this mode, Amazon Bedrock Guardrails automatically evaluates both the full input prompt and the streaming output against active safeguards continuously, in real time, as tokens are generated. For traditional conversational AI, this approach works well: prompts are short, responses are concise, and the evaluation overhead is negligible.
But for code generation workflows, inline scanning becomes inefficient overhead. It adds cost and consumes quota without meaningfully improving your security posture. A coding assistant doesn’t produce only a brief response. It streams thousands of characters of code, interspersed with reasoning, comments, and iterative refinements. With inline evaluation active, every chunk of that output is scanned against every configured safeguard, including the static system prompt and previously generated context that hasn’t changed since the last evaluation. The result is redundant work: the same boilerplate instructions, tool definitions, and prior conversation history are re-evaluated turn after turn, consuming text units without adding safety value.
The core best practice is to shift from continuous inline scanning to selective validation at strategic checkpoints , analogous to a pre-commit hook in a Git workflow. Rather than scanning every token as it streams, validate content at well-defined boundaries where the risk profile changes.
Why “pre-commit hook” thinking works
Software developers don’t run linters, formatters, and security scanners after every line they type. They validate at commit time. They don’t validate every intermediate edit, every deleted line, or every half-written function, but validate the finished result at the moment it matters.
In a Git workflow, a pre-commit hook is a script that runs automatically at a specific, well-defined boundary: the moment you attempt to commit code to your repository. It’s the last gate before your changes become part of the shared code base. At this checkpoint, you run your validations and tests all at once, against the final artifact that’s about to be persisted.
This pattern works because it balances two competing needs: thoroughness (every committed change is fully validated) and efficiency (validation only happens when the risk profile changes, as code moves from “draft in progress” to “artifact being persisted”).
Applying the pattern to Amazon Bedrock Guardrails
The core best practice is to apply this same principle to Amazon Bedrock Guardrails: shift from continuous inline scanning to selective validation at strategic checkpoints.
Think of your code generation pipeline as having natural commit points, moments where content transitions from one trust level to another:
- User input received – Content enters your system from an untrusted source (validate here).
- Final code artifact assembled – The model’s complete response is ready to be presented or saved (validate here).
- Code written to file or committed to repository – AI-generated content is about to become persistent and potentially executable (validate here).
Between these checkpoints, while the model is reasoning, generating intermediate tokens, or producing chain-of-thought explanations, the content is ephemeral. It hasn’t crossed a trust boundary. Scanning it continuously adds cost and consumes quota without meaningfully improving your security posture.
Key principle : Use the decoupled ApplyGuardrail API to evaluate user-supplied inputs before they reach the model, and validate aggregated final code artifacts before they are committed, not every intermediate reasoning token.
Implementation: pre-commit validation for file operations
For the highest-risk checkpoint, when AI-generated code is about to be written to a file or committed to a repository, perform comprehensive guardrail evaluation. This is the pre-commit hook pattern applied directly:
import hashlib
from pathlib import Path

class CodeCommitGuardrail:
    """
    Validates all AI-generated code changes before they are persisted.
    Analogous to running security scanners in a Git pre-commit hook.

    Use this when:
    - A coding assistant writes code to disk
    - AI-generated changes are staged for commit
    - Generated code is about to be deployed
    """

    def __init__(self, client, guardrail_id, guardrail_version):
        self.client = client
        self.guardrail_id = guardrail_id
        self.guardrail_version = guardrail_version
        self.validated_hashes = {}  # Cache: don't re-validate unchanged files

    def validate_file_changes(self, staged_files: dict) -> dict:
        """
        Evaluate all staged AI-generated code changes before commit.

        Args:
            staged_files: Dict of {file_path: file_content} for all changed files

        Returns:
            Dict with 'safe' boolean and any violations found
        """
        violations = []
        skipped = []

        for file_path, content in staged_files.items():
            # Skip files that haven't changed since last validation
            content_hash = hashlib.sha256(content.encode()).hexdigest()
            if self.validated_hashes.get(file_path) == content_hash:
                skipped.append(file_path)
                continue

            # Evaluate in 1,000-char aligned chunks
            file_violations = self._evaluate_file(file_path, content)

            if file_violations:
                violations.extend(file_violations)
            else:
                # Cache successful validation
                self.validated_hashes[file_path] = content_hash

        return {
            'safe': len(violations) == 0,
            'violations': violations,
            'files_evaluated': len(staged_files) - len(skipped),
            'files_skipped_cached': len(skipped)
        }

    def _evaluate_file(self, file_path: str, content: str) -> list:
        """Evaluate a single file's content against guardrails."""
        violations = []

        for offset in range(0, len(content), 1000):
            chunk = content[offset:offset + 1000]

            response = self.client.apply_guardrail(
                guardrailIdentifier=self.guardrail_id,
                guardrailVersion=self.guardrail_version,
                source='OUTPUT',
                content=[{'text': {'text': chunk}}]
            )

            if response['action'] == 'GUARDRAIL_INTERVENED':
                violations.append({
                    'file': file_path,
                    'offset': offset,
                    'length': len(chunk),
                    'assessments': response['assessments'],
                    'snippet': chunk[:200] + '...' if len(chunk) > 200 else chunk
                })

        return violations


# Example: Integration with a coding assistant's file-write operation
def write_ai_generated_code(file_path: str, content: str, guardrail: CodeCommitGuardrail):
    """
    Wrapper for file writes that validates content before persisting.
    """
    result = guardrail.validate_file_changes({file_path: content})

    if not result['safe']:
        print(f"Guardrail blocked write to {file_path}")
        for v in result['violations']:
            print(f"  Violation at offset {v['offset']}: {v['assessments']}")
        return False

    # Safe to write
    Path(file_path).write_text(content)
    print(f"{file_path} validated and written successfully")
    return True
Architecture pattern 2: Increase the streaming interval to 1,000 characters
When you do need real-time streaming evaluation, for example interactive coding sessions where you want to halt generation immediately upon detecting a violation, optimize the streaming interval. Increasing the guardrail interval from the default 50 characters to 1,000 characters can reduce your API call volume by 20x. See the following configuration:
# When using InvokeModelWithResponseStream with guardrails
response = bedrock_runtime.invoke_model_with_response_stream(
    modelId='anthropic.claude-sonnet-4-20250514',
    body=json.dumps(request_body),
    guardrailIdentifier='your-guardrail-id',
    guardrailVersion='1',
    # Key configuration: increase streaming interval
    streamingConfigurations={
        'guardrailStreamingInterval': 1000  # Default is 50!
    }
)
Impact : A 5,000-character function goes from 100 evaluations to 5. A 50,000-character file goes from 1,000 evaluations to 50.
Architecture pattern 3: Use the decoupled ApplyGuardrail API for selective evaluation
With the standalone ApplyGuardrail API, you can use Amazon Bedrock Guardrails irrespective of the foundation model. You can evaluate text without invoking the foundation model.
Pattern: Input-only validation with unguarded inference
When your primary concern is preventing prompt injection and blocking malicious inputs, validate only the dynamic user content before it reaches the model. In that case, invoke the model without inline guardrails:
import boto3
import json

bedrock_runtime = boto3.client('bedrock-runtime')

def process_coding_request(user_input: str, system_prompt: str, conversation_history: list):
    """
    Validate user input with guardrails, then invoke model without inline scanning.
    The system prompt and conversation history are NOT re-evaluated every turn.
    """

    # Step 1: Evaluate ONLY the new dynamic user input
    guardrail_response = bedrock_runtime.apply_guardrail(
        guardrailIdentifier='your-guardrail-id',
        guardrailVersion='1',
        source='INPUT',
        content=[
            {
                'text': {
                    'text': user_input  # Only the new content - not the full prompt
                }
            }
        ]
    )

    if guardrail_response['action'] == 'GUARDRAIL_INTERVENED':
        return {
            'blocked': True,
            'message': guardrail_response['outputs'][0]['text'],
            'assessments': guardrail_response['assessments']
        }

    # Step 2: Safe to proceed - invoke model WITHOUT inline guardrails
    # The system prompt and history bypass redundant evaluation
    messages = conversation_history + [{'role': 'user', 'content': user_input}]

    response = bedrock_runtime.converse(
        modelId='anthropic.claude-sonnet-4-20250514',
        messages=messages,
        system=[{'text': system_prompt}]
        # Note: No guardrailConfig here - we've already validated input
    )

    return {
        'blocked': False,
        'response': response['output']['message']['content'][0]['text']
    }
Why this matters for coding workflows: In a typical coding session, the system prompt (often 2,000-5,000 characters of tool definitions and instructions) and conversation history (growing with each turn) are resent on every invocation. With inline evaluation, this static content is re-scanned every single turn. With the decoupled approach, you evaluate only the ~200-character user message that actually changed.
Pattern: Output-only validation at completion
When you need to scan generated code for sensitive information (leaked credentials, hardcoded secrets) but trust that the user input is benign (for example, internal developer tools behind authentication), validate only the final output:
def generate_and_validate_code(user_input: str, system_prompt: str):
    """
    Generate code without inline guardrails, then validate the complete output.
    Ideal for detecting secrets, PII, or unsafe patterns in generated code.
    """

    # Step 1: Generate code without inline guardrail overhead
    response = bedrock_runtime.converse(
        modelId='anthropic.claude-sonnet-4-20250514',
        messages=[{'role': 'user', 'content': user_input}],
        system=[{'text': system_prompt}]
    )

    generated_code = response['output']['message']['content'][0]['text']

    # Step 2: Validate the COMPLETE code artifact - not intermediate chunks
    guardrail_response = bedrock_runtime.apply_guardrail(
        guardrailIdentifier='your-guardrail-id',
        guardrailVersion='1',
        source='OUTPUT',
        content=[
            {
                'text': {
                    'text': generated_code
                }
            }
        ]
    )

    if guardrail_response['action'] == 'GUARDRAIL_INTERVENED':
        return {
            'blocked': True,
            'message': 'Generated code contains sensitive content that was blocked.',
            'assessments': guardrail_response['assessments']
        }

    return {
        'blocked': False,
        'code': generated_code
    }
Pattern: Bidirectional validation with selective scope
For maximum coverage, validate inputs for injection attacks and outputs for sensitive content while still avoiding the overhead of inline scanning:
def secure_code_generation_pipeline(user_input: str, system_prompt: str, history: list):
    """
    Full bidirectional validation without inline scanning overhead.
    Input: Check for prompt injection/manipulation
    Output: Check for leaked secrets and unsafe patterns
    """

    # Step 1: Validate input for prompt injection
    input_check = bedrock_runtime.apply_guardrail(
        guardrailIdentifier='your-guardrail-id',
        guardrailVersion='1',
        source='INPUT',
        content=[{'text': {'text': user_input}}]
    )

    if input_check['action'] == 'GUARDRAIL_INTERVENED':
        return {'blocked': True, 'stage': 'input', 'reason': input_check['outputs'][0]['text']}

    # Step 2: Generate code - no inline guardrails needed
    messages = history + [{'role': 'user', 'content': user_input}]
    response = bedrock_runtime.converse(
        modelId='anthropic.claude-sonnet-4-20250514',
        messages=messages,
        system=[{'text': system_prompt}]
    )
    generated_code = response['output']['message']['content'][0]['text']

    # Step 3: Validate output for sensitive information
    output_check = bedrock_runtime.apply_guardrail(
        guardrailIdentifier='your-guardrail-id',
        guardrailVersion='1',
        source='OUTPUT',
        content=[{'text': {'text': generated_code}}]
    )

    if output_check['action'] == 'GUARDRAIL_INTERVENED':
        return {'blocked': True, 'stage': 'output', 'reason': output_check['outputs'][0]['text']}

    return {'blocked': False, 'code': generated_code}
Architecture pattern 4: Batch output to text unit aligned boundaries
Since a 600-character chunk still costs one full text unit (1,000 characters), always batch to multiples of 1,000 characters to avoid partial-unit waste:
import asyncio

class GuardrailBatcher:
    """Accumulates streaming output and evaluates at 1,000-char boundaries."""

    def __init__(self, client, guardrail_id, guardrail_version):
        self.client = client
        self.guardrail_id = guardrail_id
        self.guardrail_version = guardrail_version
        self.buffer = ""
        self.BATCH_SIZE = 1000  # Align to TextUnit boundary

    async def process_chunk(self, chunk: str):
        """Buffer chunks and evaluate when we hit a TextUnit boundary."""
        self.buffer += chunk

        while len(self.buffer) >= self.BATCH_SIZE:
            # Extract exactly 1,000 characters for evaluation
            batch = self.buffer[:self.BATCH_SIZE]
            self.buffer = self.buffer[self.BATCH_SIZE:]

            response = self.client.apply_guardrail(
                guardrailIdentifier=self.guardrail_id,
                guardrailVersion=self.guardrail_version,
                source='OUTPUT',
                content=[{'text': {'text': batch}}]
            )

            if response['action'] == 'GUARDRAIL_INTERVENED':
                raise GuardrailViolation(response)

    async def flush(self):
        """Evaluate any remaining content at end of stream."""
        if self.buffer:
            response = self.client.apply_guardrail(
                guardrailIdentifier=self.guardrail_id,
                guardrailVersion=self.guardrail_version,
                source='OUTPUT',
                content=[{'text': {'text': self.buffer}}]
            )
            self.buffer = ""
            return response
Architecture pattern 5: Risk-based evaluation depth
Not all generated code carries the same risk. Code that touches IAM policies, secrets, or authentication deserves more thorough scanning than UI layout code. Implement adaptive evaluation depth based on content signals:
import re

class RiskBasedGuardrail:
    """
    Adjusts guardrail evaluation strategy based on the risk profile
    of the code being generated.

    High-risk code: Full evaluation with all safeguards
    Standard code: Lightweight evaluation (sensitive info only)
    Low-risk code: Skip intermediate evaluation; validate at commit only
    """

    # Patterns that indicate high-risk code
    HIGH_RISK_PATTERNS = [
        r'iam[_\.]',                           # IAM policy manipulation
        r'(access_key|secret_key|password)',   # Credential handling
        r'(exec|eval|subprocess|os\.system)',  # Code execution
        r'(BEGIN.*PRIVATE KEY)',               # Cryptographic keys
        r'(security_group|nacl|firewall)',     # Network security
        r'(grant|revoke|permission)',          # Authorization
        r'(encrypt|decrypt|kms)',              # Encryption operations
    ]

    # Patterns that indicate low-risk code
    LOW_RISK_PATTERNS = [
        r'(\.css|style|className|fontSize)',   # Styling
        r'(render|component|jsx|tsx)',         # UI components
        r'(test|spec|mock|fixture)',           # Test files
        r'(README|docs|comment)',              # Documentation
    ]

    def __init__(self, client, guardrail_id_full, guardrail_id_lightweight):
        self.client = client
        self.guardrail_id_full = guardrail_id_full                # All safeguards active
        self.guardrail_id_lightweight = guardrail_id_lightweight  # Sensitive info only

    def classify_risk(self, code: str, file_path: str = "") -> str:
        """Determine risk level of generated code."""
        combined = code + " " + file_path

        for pattern in self.HIGH_RISK_PATTERNS:
            if re.search(pattern, combined, re.IGNORECASE):
                return 'HIGH'

        for pattern in self.LOW_RISK_PATTERNS:
            if re.search(pattern, combined, re.IGNORECASE):
                return 'LOW'

        return 'STANDARD'

    def evaluate(self, code: str, file_path: str = "") -> dict:
        """
        Evaluate code with appropriate depth based on risk classification.
        """
        risk_level = self.classify_risk(code, file_path)

        if risk_level == 'LOW':
            # Low-risk: defer to commit-time validation
            return {
                'action': 'PASS',
                'risk_level': 'LOW',
                'evaluation': 'deferred_to_commit',
                'reason': 'Content classified as low-risk (UI/tests/docs)'
            }

        # Choose guardrail based on risk
        guardrail_id = (
            self.guardrail_id_full if risk_level == 'HIGH'
            else self.guardrail_id_lightweight
        )

        response = self.client.apply_guardrail(
            guardrailIdentifier=guardrail_id,
            guardrailVersion='1',
            source='OUTPUT',
            content=[{'text': {'text': code}}]
        )

        return {
            'action': response['action'],
            'risk_level': risk_level,
            'evaluation': 'full' if risk_level == 'HIGH' else 'lightweight',
            'assessments': response.get('assessments', [])
        }


# Example: Using risk-based evaluation in a coding pipeline
risk_guardrail = RiskBasedGuardrail(
    client=bedrock_runtime,
    guardrail_id_full='guardrail-all-safeguards',
    guardrail_id_lightweight='guardrail-sensitive-info-only'
)


# High-risk: IAM policy code → full evaluation (3 safeguards)
# WARNING: The following is an example of an INSECURE anti-pattern used here
# solely to demonstrate guardrail detection. Never use wildcard permissions
# (Action: '*', Resource: '*') in production. Always follow the principle of
# least privilege. See: https://docs.aws.amazon.com/IAM/latest/UserGuide/best-practices.html#grant-least-privilege
iam_code = """
policy = iam.create_policy(
    PolicyName='AdminAccess',
    PolicyDocument=json.dumps({
        'Statement': [{'Effect': 'Allow', 'Action': '*', 'Resource': '*'}]
    })
)
"""
result = risk_guardrail.evaluate(iam_code, "deploy/iam_policies.py")
# → risk_level: HIGH, evaluation: full

# Low-risk: React component → deferred to commit
ui_code = """
function Button({ label, onClick }) {
    return <button className="btn-primary" onClick={onClick}>{label}</button>;
}
"""
result = risk_guardrail.evaluate(ui_code, "src/components/Button.tsx")
# → risk_level: LOW, evaluation: deferred_to_commit
Architecture pattern 6: Multi-stage agent pipeline
Agentic coding workflows (where the model uses tools, reasons over multiple steps, and produces intermediate outputs) require a different evaluation strategy than single-turn generation:
class AgentPipelineGuardrail:
    """
    Guardrail architecture for multi-step agentic coding workflows.

    Key insight: In an agent loop, the model may take 5-10 reasoning steps
    (tool calls, observations, reflections) before producing final code.
    Evaluating every intermediate step is wasteful - most contain internal
    reasoning that never reaches the user or a file system.

    Strategy:
    - INPUT: Validate user request before agent starts
    - INTERMEDIATE: Skip chain-of-thought and tool-use reasoning
    - TOOL INPUTS: Validate when agent writes to file or executes code
    - FINAL OUTPUT: Validate the complete response shown to the user
    """

    def __init__(self, client, guardrail_id, guardrail_version):
        self.client = client
        self.guardrail_id = guardrail_id
        self.guardrail_version = guardrail_version

    def run_agent_with_guardrails(self, user_request: str, agent):
        """
        Execute an agentic coding workflow with strategic guardrail placement.
        """

        # Gate 1: Validate user input BEFORE agent starts working
        input_check = self._evaluate(user_request, 'INPUT')
        if input_check['action'] == 'GUARDRAIL_INTERVENED':
            return {'blocked': True, 'stage': 'input', 'response': input_check}

        # Run the agent - NO guardrail evaluation during reasoning steps
        agent_steps = []
        final_output = None

        for step in agent.run(user_request):
            if step['type'] == 'thinking':
                # Skip: internal reasoning doesn't need evaluation
                agent_steps.append(step)
                continue

            elif step['type'] == 'tool_call':
                # Gate 2: Validate ONLY dangerous tool inputs
                if self._is_dangerous_tool(step['tool_name']):
                    tool_check = self._evaluate(
                        json.dumps(step['tool_input']), 'OUTPUT'
                    )
                    if tool_check['action'] == 'GUARDRAIL_INTERVENED':
                        return {
                            'blocked': True,
                            'stage': f"tool_call:{step['tool_name']}",
                            'response': tool_check
                        }
                agent_steps.append(step)

            elif step['type'] == 'final_response':
                final_output = step['content']

        # Gate 3: Validate final output before showing to user
        if final_output:
            output_check = self._evaluate(final_output, 'OUTPUT')
            if output_check['action'] == 'GUARDRAIL_INTERVENED':
                return {'blocked': True, 'stage': 'output', 'response': output_check}

        return {
            'blocked': False,
            'output': final_output,
            'steps_taken': len(agent_steps),
            'steps_evaluated': sum(
                1 for s in agent_steps
                if s['type'] == 'tool_call' and self._is_dangerous_tool(s.get('tool_name', ''))
            )
        }

    def _is_dangerous_tool(self, tool_name: str) -> bool:
        """Tools that write to disk or execute code need guardrail evaluation."""
        dangerous_tools = {
            'write_file', 'execute_code', 'run_command',
            'create_file', 'edit_file', 'bash'
        }
        return tool_name in dangerous_tools

    def _evaluate(self, content: str, source: str) -> dict:
        return self.client.apply_guardrail(
            guardrailIdentifier=self.guardrail_id,
            guardrailVersion=self.guardrail_version,
            source=source,
            content=[{'text': {'text': content}}]
        )
The complete decision framework
The following table shows the decision framework for various checkpoints:
| Checkpoint | What to validate | How | Text unit impact |
|---|---|---|---|
| User input (each turn) | Dynamic user content only | ApplyGuardrail (source=INPUT) | Low – only new content evaluated |
| Streaming output | Active content as it streams | Set interval to 1,000 chars | Potential 20x reduction compared to default |
| Completed response | Final aggregated code artifact | ApplyGuardrail (source=OUTPUT) | One-time comprehensive pass |
| Pre-commit / file save | AI-generated code changes | ApplyGuardrail (source=OUTPUT) | Comprehensive but infrequent |
| Agent tool calls | Only dangerous tools (write/execute) | ApplyGuardrail (source=OUTPUT) | Targeted – skip benign tools |
| Intermediate reasoning | Skip entirely | Don’t evaluate CoT tokens | Zero |
Key takeaways
- Shift from inline scanning to selective evaluation – Use the decoupled
ApplyGuardrailAPI to control exactly what gets scanned and when. Evaluate at trust boundaries, not continuously. - Set the streaming interval to 1,000 characters – When streaming evaluation is needed, this single change can deliver up to a 20x reduction in evaluation frequency.
- Evaluate only dynamic content – Don’t re-evaluate system prompts, tool definitions, and conversation history every turn. Use hash-based caching for content that must be re-evaluated.
- Apply risk-based evaluation depth – Scan IAM policies and credential-handling code with the safeguards. Defer UI component scanning to commit time.
- Skip intermediate reasoning tokens – In agentic workflows, evaluate only when content crosses a trust boundary (user input, dangerous tool calls, final output).
- Batch to 1,000-character boundaries – A 600-character chunk costs the same as 1,000 characters. Align your evaluations to text unit boundaries to reduce waste.
- Guard at the commit boundary – Like a Git pre-commit hook, perform comprehensive validation when AI-generated code is about to become persistent and executable.
Conclusion
In this post, we proposed best practices to optimize AI-assisted code generation workflows with Amazon Bedrock Guardrails. Here is the overall summary on how you can effectively implement Guardrails for your coding workflows.
- Audit your current configuration: Open the Amazon Bedrock console and review your existing guardrails. Check your streaming interval setting. If you haven’t changed it from the default 50 characters, you’re leaving a potential 20x efficiency gain on the table.
- Check your account quotas: Before scaling your coding workflows, verify your actual allocated limits in the AWS Service Quotas console. Don’t assume published defaults apply, especially for newer accounts. Refer to the Amazon Bedrock endpoints and quotas documentation for the latest regional limits.
- Implement the decoupled ApplyGuardrail API: Shift from inline evaluation to selective validation using the ApplyGuardrail API. Review the Configure streaming response behavior documentation to fine-tune your streaming interval.
- Explore the full Guardrails feature set: Dive into the Amazon Bedrock Guardrails documentation to learn about content filters, denied topics, sensitive information detection, and how to create and modify guardrails for your use case.
About the authors
Sandeep Singh
Sandeep is a Senior Generative AI Data Scientist at AWS, helping large enterprises innovate with generative AI. He specializes in generative AI, Agentic AI, machine learning, and system design, delivering AI/ML-powered solutions to solve complex business problems across diverse industries.
Denis Batalov
As a 21-year Amazon veteran and a PhD in Machine Learning, Denis worked on exciting projects such as Search Inside the Book, Amazon Mobile apps and Kindle Direct Publishing. Since 2013 he has helped AWS customers adopt AI/ML technology as a Solutions Architect. Currently, Denis is leading a team that helps customers build Gen AI applications with Amazon Bedrock and is also personally focusing on advancing the practice of Responsible AI by contributing to ISO and EU standardization efforts in that space. Denis is a frequent public speaker; you can follow him on LinkedIn.
Shyam Srinivasan
Shyam Srinivasan is a Principal Product Manager with the Amazon Bedrock team. He cares about making the world a better place through technology and loves being part of this journey. In his spare time, Shyam likes to run long distances, travel around the world, and experience new cultures with family and friends.
Antonio Rodriguez
Antonio is a Principal Generative AI Specialist Solutions Architect at Amazon Web Services. He helps companies of all sizes solve their challenges, embrace innovation, and create new business opportunities with Amazon Bedrock. Apart from work, he loves to spend time with his family and play sports with his friends.