构建交易助手:Jefferies 如何借助 AI 优化前台交易运营
英文标题:Building trade assistant: How Jefferies optimized front office trading operations with AI
Jefferies 基于 AWS 构建了面向股票交易前台的 Agentic AI 交易助手,让交易员能够以自然语言实时查询客户行为、交易模式和市场趋势。该方案采用 Strands Agents、Amazon Bedrock、Claude、Amazon Bedrock Knowledge Bases 与 MCP 工具,将自然语言问题转换为 SQL,并在内存数据库、SQL 数据库和 FIX 消息等多类数据源中执行查询。系统通过 Guardrails、PII 过滤、行级权限控制和会话审计日志满足金融行业的安全与合规要求。Jefferies 表示,该助手减少了手工数据处理和重复仪表板开发工作,使交易员能将更多时间投入客户关系和战略决策,并计划将其扩展至全球更多产品和交易台。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 21.6 KB
 50.1 KB
 188.3 KB
 5.8 KB
 39.2 KB
 2.7 KB
 277.5 KB
中文
如果你负责投资银行的前台交易台,就会了解其中的挑战:交易员需要从海量数据中实时获取客户行为、交易模式和市场趋势洞察,以便在瞬息之间作出决策。然而,他们在日常工作中很少有时间,也通常不具备编码能力,来构建和维护能够交付这些洞察的系统。数百万行数据分散在多种可视化工具中,因此很难实现端到端的可见性。传统方法迫使交易员依赖领域专家进行分析,并与 IT 团队协作构建定制仪表板。这个过程可能需要数天甚至数周。最终,数据可得性与其本应支撑的决策之间的鸿沟不断扩大。
Jefferies 是一家全球性全服务投资银行。该公司将这一挑战视为运用 Agentic AI 优化股票交易台运营方式的机会。Jefferies 在 AWS 上构建了一款 Agentic AI 交易助手,旨在将实时数据分析能力直接交到交易员手中,无需编码、无需排队等待 IT 支持,同时不牺牲准确性。
本文将探讨 Jefferies 如何借助基于 Strands Agents 构建的解决方案克服这些挑战。Strands Agents 是一个 Agent harness SDK,可用于构建能够通过编排对基础模型(FM)和外部工具的调用来进行推理、规划和行动的 AI Agent。该方案采用大语言模型(LLM)、Amazon Bedrock 和 Amazon Bedrock Knowledge Bases。它还采用了 Model Context Protocol(MCP),这是一项开放标准,可帮助 AI Agent 通过统一接口安全连接至多种数据源和工具。我们将介绍该方案概览、选择底层技术栈的理由、经验教训,以及该方案为 Jefferies 创造的业务影响。
解决方案概览
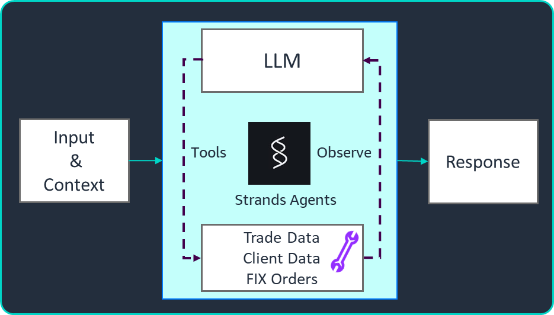
前台交易助手代表了资本市场前台股票交易员与数据交互方式的一次转变。该解决方案的核心是一个领域专用 Agent,它通过自然语言文本驱动与交易员之间的对话。一组 MCP 工具使 Agent 能够连接至数据源,包括交易数据存储库、金融信息交换(FIX)消息文件以及内存数据库。当交易员向交易助手提交查询时,Amazon Bedrock 会调用 LLM(Anthropic Claude)来理解自然语言意图、生成相应的 SQL,并在底层数据源上运行查询以呈现回答。该方案具备对话式界面,使交易员能够深入特定主题,并以对话方式探索数据洞察。该方案会在整个会话生命周期内维护对话上下文,从而提供相关洞察以及进一步分析的建议。
方案工作原理
该方案通过如下架构图所示的八步流程,与 Jefferies 现有交易基础设施集成。从安全角度看,方案使用 Amazon Bedrock Guardrails 提供内容审核和个人身份信息(PII)过滤,以确保方案符合 Jefferies 的政策;同时使用行级数据权限,通过智能访问控制来帮助防止意外访问客户敏感数据。该方案还使用对话日志来建立审计追踪,以满足合规要求。
用户交互始于 Jefferies 的前端交易界面,该界面现已嵌入 AI 助手小组件。当交易员提出问题时,请求将通过精心编排的工作流流转。
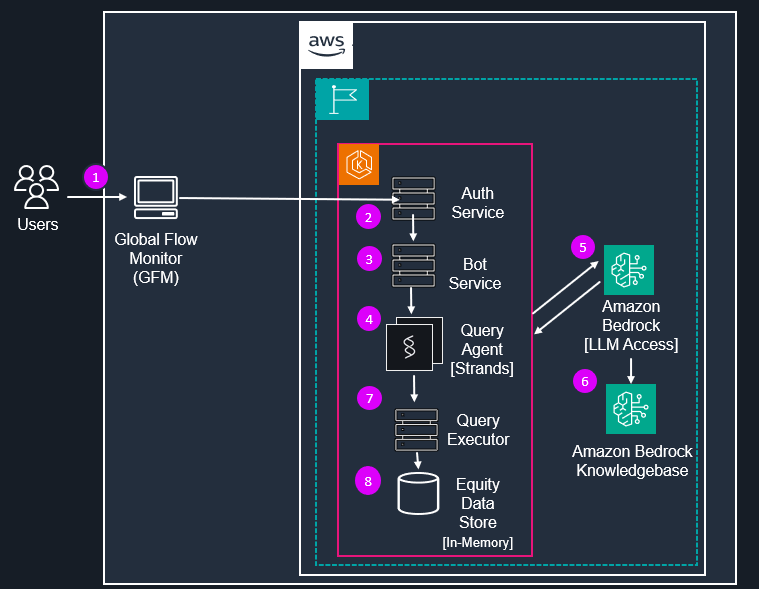
- UI 小组件: 首先,交易员使用其凭据登录 Jefferies 的本地部署商业智能系统 Global Flow Monitor(GFM)。交易员登录 GFM 后,即可通过一个 UI 小组件与 Trade Assistant Agent 进行交互。
- 身份验证服务使用 Amazon Elastic Kubernetes Service(Amazon EKS)。该服务验证只有获准的交易员才能访问敏感交易数据。
- Bot Service 构建并管理用户会话,在多次查询之间维护上下文。
- **Query Agent(Strands)**充当方案的智能编排层。当交易员提出自然语言问题时,Agent 会先查询 Amazon Bedrock Knowledge Bases。该知识库使用 Amazon Titan Embeddings 进行语义检索,以呈现相关数据库架构、表关系和查询模式。获得这些上下文后,Claude Sonnet 会针对交易员意图进行推理,并生成语法正确的 SQL 查询。随后,Agent 会评估可用的 Model Context Protocol(MCP)工具,以确定执行所需的正确数据源:可能是用于实时头寸的内存数据网格,也可能是用于时间序列分析的历史数据存储。
- Amazon Bedrock 为 Query Agent 提供对 LLM 的访问,用于规划和执行 Agent 步骤。LLM 的高级推理能力支持自然语言理解、SQL 生成和多步骤工具编排。团队还选择 Amazon Bedrock,是因为随着交易助手的发展,可以灵活选择不同的 LLM。
- Amazon Bedrock Knowledge Bases 提供托管式检索增强生成(RAG)管道,用于存储底层数据模型元数据的嵌入表示,包括表架构、列定义和查询模式。当 Query Agent 收到交易员问题时,它会从 Knowledge Base 中检索相关架构上下文,以辅助准确构建 SQL。
- Query Executor 会在 Query Agent 确定正确数据源并创建 SQL 查询后,对底层数据执行查询。查询执行器会拦截用户请求并注入 SQL 过滤器,以为数据访问提供行级安全性。LLM 负责选择要展示的可视化形式,而我们使用 Markdown UI 库来渲染这些可视化内容。
- 数据存储: 即 Query Executor 所查询的实际数据源,包括内存数据库、SQL 数据库以及包含底层交易和执行数据的 FIX 消息。
让我们进一步探讨选择 Strands Agents 和基于 MCP 工具架构的理由。
Strands Agents
Strands Agents 是一个开源 Agent harness SDK,采用模型驱动的方法,仅用几行代码即可构建和运行 AI Agent。Strands 可扩展至从简单到复杂的 Agent 用例,也可覆盖从本地开发到生产部署的场景。它通过充分利用 LLM 的规划、思维链衔接、工具调用和反思能力,简化了 Agent 开发。借助 Strands,开发者可以在代码中定义提示词和工具列表来构建 Agent,随后在本地进行测试并部署至云端。Strands 利用模型的高级推理能力规划 Agent 的下一步并执行工具。对于更复杂的 Agent 用例,开发者可以在 Strands 中自定义 Agent 的行为。例如,可以指定工具的选择方式、自定义上下文管理方式、选择会话状态和记忆的存储位置,以及构建多 Agent 应用程序。
Model Context Protocol(MCP)工具
该方案实现了基于 Model Context Protocol(MCP)工具的架构,其中每个数据源都作为一个独立工具暴露出来,供 Strands Agents 调用。这一方法带来三项优势,为系统长期成功奠定基础。
首先,该方法具备可扩展性:可以将新的数据源作为额外工具加入,无需重构核心架构。团队有意作出这一设计选择,以适应未来的功能扩展。其次,它实现了关注点分离:与每个特定系统交互的逻辑被封装在各自工具中,使整体架构更易于维护和测试。第三,该设计具备灵活性:Strands Agent 可依据每次查询动态选择使用哪些工具,从而支持跨越多个数据源的工作流。
多源数据处理
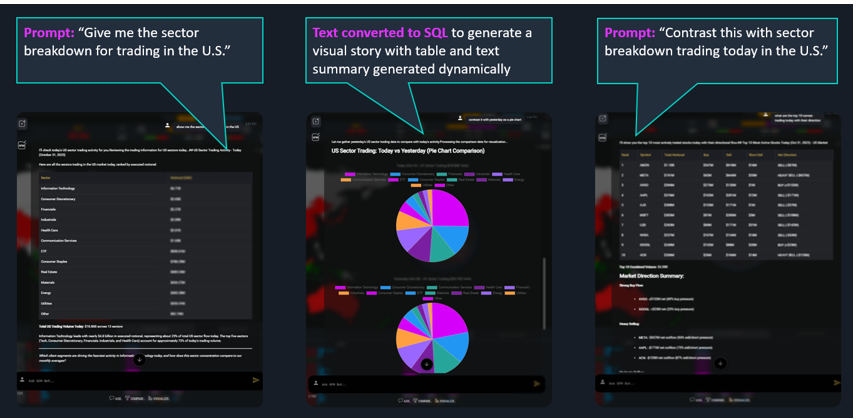
该方案提供了直观的用户体验。交易员可以输入屏幕上所示的问题,例如:“Give me the sector breakdown for trading in the U.S.”(请给出美国交易的行业细分)。在幕后,助手使用 LLM 生成适当的 SQL 查询,在托管于内存数据网格中的相关数据源上运行查询,并即时获取结果。
交易助手并不止于简单的数据检索。它可以生成动态可视化内容,将文本查询转换为 SQL,并据此生成由图表构成的可视化叙事。当交易员需要比较今日的行业交易情况与昨日活动时,助手会自动生成带有颜色编码图例的饼图,使他们能够快速、直观地发现趋势和异常情况。
经验教训
在交付前台交易助手 Agent 的过程中,Jefferies 团队发现了多项关键经验,这些经验塑造了其企业 AI 战略和实施路线图。这些洞察可为大规模构建 Agentic AI 应用的资本市场机构提供有价值的指引。
首先,团队通过有意不依赖 LLM 生成可视化内容来降低幻觉风险。相反,他们采用混合方法:LLM 负责自然语言理解和查询生成,而专用可视化引擎负责渲染实际的图表。这种关注点分离在保留交易员所期望的对话式界面的同时,也保障了数据准确性。
其次,团队采用内存数据库以最大化响应速度。交易员需要即时了解客户行为、交易模式和市场趋势。若没有这一架构选择,针对底层数据集的查询将带来无法接受的延迟,无法满足实时交易决策需求。
第三,团队认识到必须预期用户行为会不断变化。实际使用情况证明,用户行为是动态的。交易员以意想不到的方式与系统交互,其使用模式也会随时间推移而变化。对可观测性和用户反馈闭环进行投入,对于快速适应这些变化中的行为至关重要。最后,团队采用了审慎的语言策略。鉴于 Python 拥有丰富的人工智能和机器学习(AI/ML)生态,他们使用 Python 进行 LLM 交互和快速实验;同时以 Java 实现复杂的业务处理,以利用其在高吞吐量数据处理以及与现有交易系统集成方面的性能特性。
业务影响
自上线以来,该交易助手方案已在全球销售和交易运营中带来可衡量的效率提升,使交易员能够将时间从手动整理数据中转移到客户关系和战略决策上。这些效率提升直接转化为竞争优势,因为交易台如今可以投入更多能力来引入客户并深化现有客户关系。该方案可针对每位客户的查询进行适配:通过 MCP 工具访问结构化、非结构化和内存数据源,并动态生成图形和图表,从而提供个性化体验。
除交易台外,该方案还显著减少了此前耗费于重复创建仪表板的 IT 时间和精力,使技术团队能够聚焦于更高价值的战略性计划。尤其值得注意的是,借助自然语言安全查询数百万行股票交易数据的能力,数据访问得以普及。这推动形成了数据驱动型文化,使决策基于实时分析,而非直觉或滞后的报告。
展望未来
Jefferies 的路线图表明了这一 Agentic AI 方法的可扩展性和雄心。团队计划面向多种产品类型和交易台在全球范围内推出 Trade Assistant;借助使用自然语言处理(NLP)的代码生成工具增强审计能力;并为其企业 AI 系统添加 Amazon Bedrock AgentCore 功能。这些投入显示出其致力于在整个组织内扩展 AI 驱动能力。与现有股票业务智能(BI)应用的集成,以及查询多个结构化、非结构化和内存数据源的能力,使 Jefferies 处于 AI 驱动交易创新的前沿。
结论
本文介绍了 Jefferies 与 AWS 如何合作构建一款 Agentic AI 交易助手,从而改变交易员在全球销售和交易业务中与股票数据交互的方式
English / 原文
If you manage a front office trading desk at investment banks, you know the challenge: traders need real-time insights into client behavior, trade patterns, and market trends from vast amounts of data to make split-second decisions. However, they rarely have the time during the day, nor the coding ability, to build and maintain systems capable of delivering those insights. With millions of rows of data spread across multiple visualization tools, achieving end-to-end visibility is difficult. Traditional approaches force traders to rely on subject matter experts for analysis and collaborate with IT teams to build custom dashboards. The process can take days or weeks. The result is a widening gap between the data available and the decisions it should be informing.
Jefferies, a global full-service investment banking firm, recognized this challenge as an opportunity to apply agentic AI to optimize how its equities trading desks operate. By building an agentic AI trade assistant on AWS, Jefferies set out to put the power of real-time data analysis directly in traders’ hands without the requirement of coding, waiting in IT queues, and with no compromise on accuracy.
In this post, we explore how Jefferies overcame these challenges with a solution built on Strands Agents, an agent harness SDK for building AI agents that can reason, plan, and act by orchestrating calls to foundation models (FMs) and external tools. The solution uses large language models (LLMs), Amazon Bedrock, and Amazon Bedrock Knowledge Bases. It also uses Model Context Protocol (MCP), an open standard that helps AI agents securely connect to diverse data sources and tools through a unified interface. We cover the solution overview, the rationale for selecting the underlying technology stack, lessons learned, and the business impact the solution created at Jefferies.
Solution overview
The Front Office trade assistant represents a shift in how Capital Markets’ Front Office Equity traders interact with data. At the core of the solution is a domain-specific agent that drives conversation with traders through natural language text. A set of MCP tools lets the agent connect with data sources, including trade data repositories, Financial Information Exchange (FIX) message files, and in-memory databases. When a trader submits a query to the trade assistant, Amazon Bedrock invokes an LLM (Anthropic Claude) to interpret the natural language intent, generate the corresponding SQL, and run it against underlying data sources to surface the response. The solution has a conversational interface, which allows traders to drill down on topics and explore data insights conversationally. The solution maintains conversation context to provide relevant insights and suggestions for deeper analysis over the entire lifetime of the session.
How the solution works
The solution integrates with Jefferies’ existing trading infrastructure through an eight-step process depicted in the following architecture diagram. From a security perspective, the solution uses Amazon Bedrock Guardrails to provide content moderation, personally identifiable information (PII) filtering to align the solution with Jefferies policies, and row-level data entitlements to help prevent accidental access to customer-sensitive data through intelligent access controls. It also uses conversation logging for audit trails to meet compliance requirements.
The user interaction begins with the Jefferies front-end trading interface, which now includes an embedded AI assistant widget. When a trader poses a question, the request flows through a carefully orchestrated workflow.
- UI Widget: First, the trader logs in using their credentials on Jefferies’ on-premises Business Intelligence system: Global Flow Monitor (GFM). Once a trader logs into GFM, they have a UI widget to interact with the Trade Assistant Agent.
- The Authentication Service uses Amazon Elastic Kubernetes Service (Amazon EKS). The service verifies that only allowed traders can access sensitive trading data.
- Bot Service builds and manages the user session, maintaining context across multiple queries.
- The Query Agent (Strands) serves as the intelligent orchestration layer of the solution. When a trader poses a natural language question, the agent first queries the Amazon Bedrock Knowledge Bases, which uses Amazon Titan Embeddings for semantic retrieval to surface relevant database schemas, table relationships, and query patterns. With this context, Claude Sonnet reasons over the trader’s intent and generates a syntactically correct SQL query. The agent then evaluates its available Model Context Protocol (MCP) tools to determine the right data source for execution, whether that’s the in-memory grid for real-time positions or a historical data store for time-series analysis.
- Amazon Bedrock provides the Query Agent with access to an LLM for planning and executing the agent’s steps. The LLM’s advanced reasoning capabilities enable natural language understanding, SQL generation, and multi-step tool orchestration. The team also chose Amazon Bedrock for its flexibility to choose different LLMs as the trade assistant evolves.
- Amazon Bedrock Knowledge Bases provides a managed Retrieval Augmented Generation (RAG) pipeline that stores embedded representations of the underlying data model metadata (table schemas, column definitions, and query patterns). When the Query Agent receives a trader’s question, it retrieves relevant schema context from the Knowledge Base to inform accurate SQL construction.
- Query Executor queries the underlying data once the Query Agent identifies the right data source and creates the SQL query. The query executor intercepts user requests and injects SQL filters to provide row-level security for data access. The LLM chooses the visualization to display, and we used a markdown UI library to render the visualizations.
- Data Stores: The actual data sources queried by the Query Executor, including in-memory, SQL databases, and FIX messages that contain the underlying trade and execution data.
Let’s explore the rationale behind our selection of Strands Agents and MCP tools-based architecture.
Strands Agents
Strands Agents is an open source agent harness SDK that takes a model-driven approach to building and running AI agents in a few lines of code. Strands scales from straightforward to complex agent use cases, and from local development to deployment in production. It simplifies agent development by embracing the capabilities of LLMs to plan, chain thoughts, call tools, and reflect. With Strands, developers can define a prompt and a list of tools in code to build an agent, then test it locally and deploy it to the cloud. Strands plans the agent’s next steps and executes tools using the advanced reasoning capabilities of models. For more complex agent use cases, developers can customize their agent’s behavior in Strands. For example, you can specify how tools are selected, customize how context is managed, choose where session state and memory are stored, and build multi-agent applications.
Model Context Protocol (MCP) tools
The solution implements a Model-Context-Protocol (MCP) tool-based architecture where each data source is exposed as a distinct tool that Strands Agents can invoke. This approach delivers three advantages that position the system for long-term success. First, the approach provides extensibility by enabling new data sources to be added as additional tools, requiring no restructuring of the core architecture, a design choice the team made deliberately to accommodate future functional expansion. Second, it provides separation of concerns by encapsulating the logic for interacting with each specific system within its own tool, which makes the overall architecture more maintainable and testable. Third, the design offers flexibility by allowing the Strands Agent to dynamically select which tools to use based on each query, enabling workflows that span multiple data sources.
Multi-source data processing
The solution provides an intuitive user experience. A trader can type a question like the one on the screen: “Give me the sector breakdown for trading in the U.S.” Behind the scenes, the assistant uses an LLM to generate the appropriate SQL query, runs it against the relevant data sources hosted in our in-memory data grid, and retrieves the results instantly.
The trade assistant goes beyond simple data retrieval. It can generate dynamic visualizations, converting text queries into SQL that produces visual stories with charts and graphs. When traders need to compare today’s sector trading with yesterday’s activity, the assistant automatically generates pie charts with color-coded legends, making it straightforward to spot trends and anomalies quickly.
Lessons learned
Throughout the journey to deliver the Front Office trade assistant agent, the Jefferies team uncovered several key lessons that shaped its enterprise AI strategy and implementation roadmap. These insights serve as valuable guidance for capital markets organizations building agentic AI applications at scale.
First, the team mitigated the risk of hallucinations by deliberately not relying on LLMs to generate visualizations. Instead, they implemented a hybrid approach in which the LLM handles natural language understanding and query generation while dedicated visualization engines render the actual charts and graphs. This separation of concerns preserves data accuracy while maintaining the conversational interface traders expect.
Second, the team used in-memory databases to maximize response times. Traders require split-second insights into client behavior, trade patterns, and market trends. Without this architectural choice, queries against the underlying dataset would have introduced unacceptable latency for real-time trading decisions.
Third, the team learned to expect user behavior to evolve. Real-world usage proved dynamic. Traders interacted with the system in unexpected ways, and their patterns shifted over time. Investing in observability and user feedback loops proved essential for adapting quickly to these changing behaviors. Finally, the team adopted a deliberate language strategy. They relied on Python for LLM interactions and rapid experimentation, given its rich artificial intelligence and machine learning (AI/ML) landscape. They implemented complex business processing in Java to capitalize on its performance characteristics for high-throughput data processing and integration with existing trading systems.
Business impact
Since launch, the trade assistant solution has delivered measurable efficiency gains across global sales and trading operations, allowing traders to redirect time toward client relationships and strategic decision-making rather than manual data wrangling. These efficiency gains translate directly into a competitive advantage, as trading desks can now dedicate more capacity to onboarding clients and deepening existing relationships. The solution delivers a personalized experience by adapting to each client’s query using MCP tools to access structured, unstructured, and in-memory data sources and dynamically generating graphs and charts in response. Beyond the trading desk, the solution has materially reduced the IT time and effort previously consumed by repetitive dashboard creation, freeing technology teams to focus on higher-value strategic initiatives. Perhaps most notably, the ability to securely query millions of rows of equities trading data using natural language has democratized data access. This fosters a data-driven culture where decisions are informed by real-time analytics rather than intuition or delayed reports.
Looking ahead
Jefferies’ roadmap signals the scalability and ambition of this agentic AI approach. The team plans to roll out the Trade Assistant globally for multiple product types and desks, enhance audit capabilities with code generation tools that use natural language processing (NLP), and add Amazon Bedrock AgentCore features to their enterprise AI system. These investments show a commitment to expanding AI-powered capabilities across the organization. The integration with existing Equities business intelligence (BI) applications and the ability to query multiple structured, unstructured, and in-memory data sources positions Jefferies at the forefront of AI-driven trading innovation.
Conclusion
In this post, we walked through how Jefferies and AWS collaborated to build an agentic AI trade assistant that transforms how traders interact with equities data across global sales and trading operations. The Jefferies Equities Trade Assistant exemplifies how agentic AI is reshaping capital markets by turning every trader into a data scientist capable of extracting sophisticated insights through simple conversation. These agentic AI systems act as intelligent collaborators that understand context, learn from interactions, and proactively guide users toward better outcomes. The shift from reactive data retrieval to proactive intelligence marks a new era in trading operations. As this technology scales globally and across asset classes, it promises to redefine competitive advantage in front office operations for years to come.
To get started building your own agentic AI applications, explore Strands Agents, learn more about the MCP integration patterns used in this solution, or contact your AWS account team to discuss engagement tailored to your use case.
About the authors
Sanjay Nagraj
Sanjay is a technology leader leading the delivery of solutions in Equities Front Office. Key initiatives include leveraging the services available on the cloud to deliver hybrid solutions.
Vipul Parekh
Vipul is a Senior Customer Solutions Manager at AWS, guiding FinTech and capital markets customers in accelerating their business transformation journey on the cloud. He is a generative AI ambassador and a member of the AWS AI/ML technical field community. Prior to joining AWS, Vipul played various roles in top financial services organizations, leading transformations.
Saby Sahoo
Saby is a senior solutions architect at AWS. Saby has 20+ years of experience in the design and implementation of IT solutions, data analytics, and AI/ML/GenAI.