🔶 Wattage:面向 AI Agent 的 Token 消耗分析器与成本回归门禁
英文标题:🔶 Wattage: A token-spend profiler and cost-regression gate for AI agents
Wattage 是一款离线运行的 AI Agent Token 消耗分析工具,可读取 OTLP JSON trace,为每次模型调用定价,并识别 Token 浪费模式。其核心的 `nonconvergence` 收敛引擎在一组含 10 个标注合成循环的基准中取得 1.00 的 Precision、Recall 和 F1,优于 SHA-256 精确匹配基线的 0.25 F1。该工具提供八类检测器,可发现提示词前缀重复发送、缓存利用不足、冗余工具调用、检索无效循环、模型规格不匹配等问题,并对修复方案估算实际美元成本影响。开发者还可通过 `wattage ci` 将 Token Efficiency 分数和成本变化接入 CI,在 Agent 成本显著回归时阻断构建,并输出 PR 评论、SARIF 与 JUnit XML。
 737 B
 737 B
 2.2 KB
 1.2 KB
 1.2 KB
 1.2 KB
 1.3 KB
 1.3 KB
 95.6 KB
 347.6 KB
中文


AI Agent 的 Kill-A-Watt 电表。 将 trace 交给它,它会精确告诉你 Token 在哪里被消耗和浪费,为每种浪费模式换算实际美元成本,给出修复建议;当一次变更可量化地增加 Agent 成本时,它还可以让你的 CI 失败。
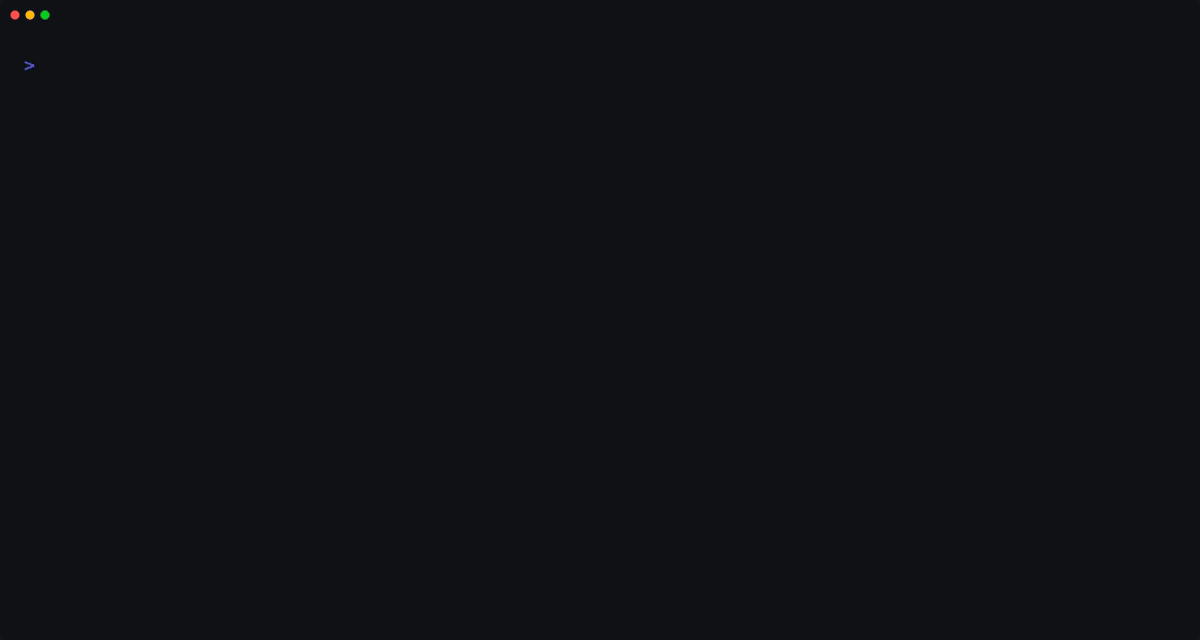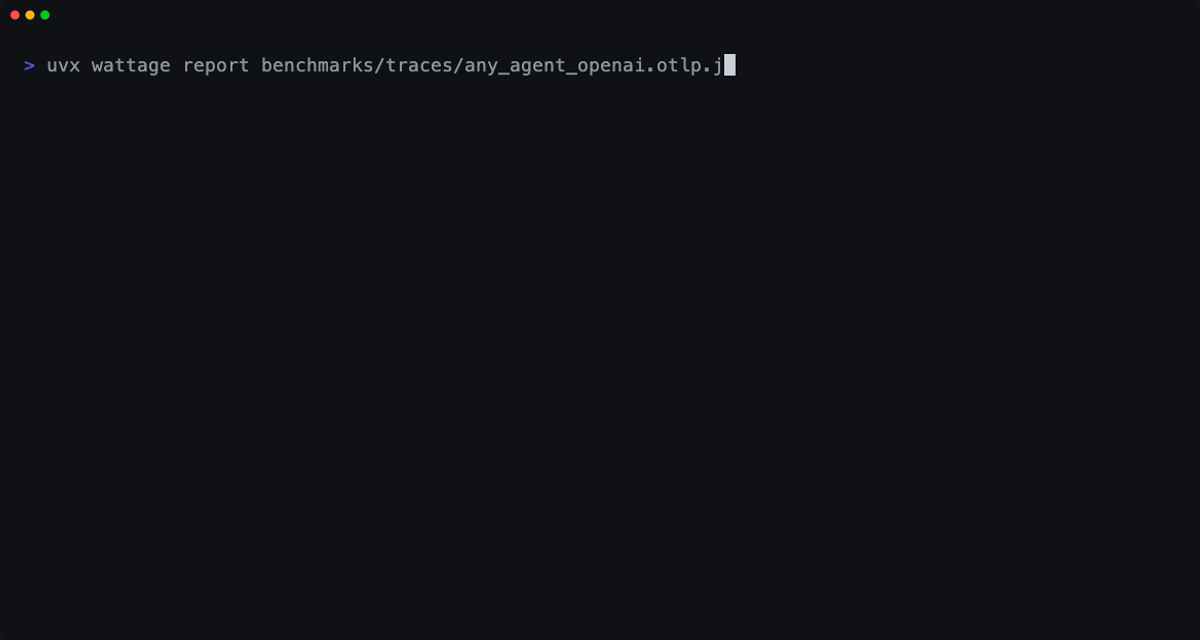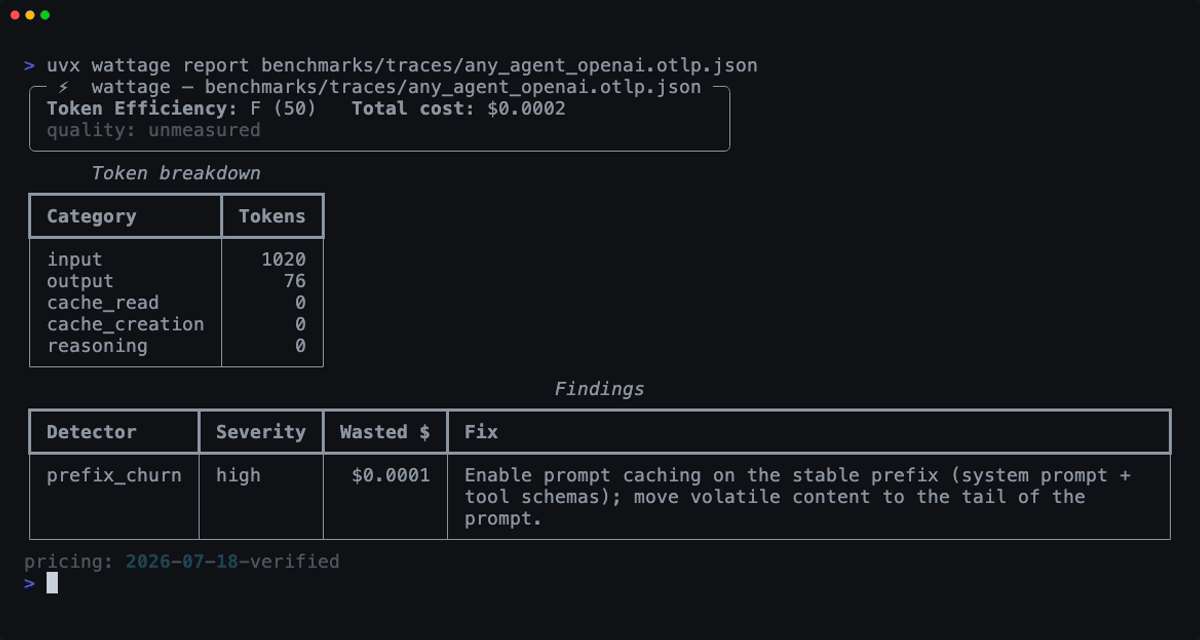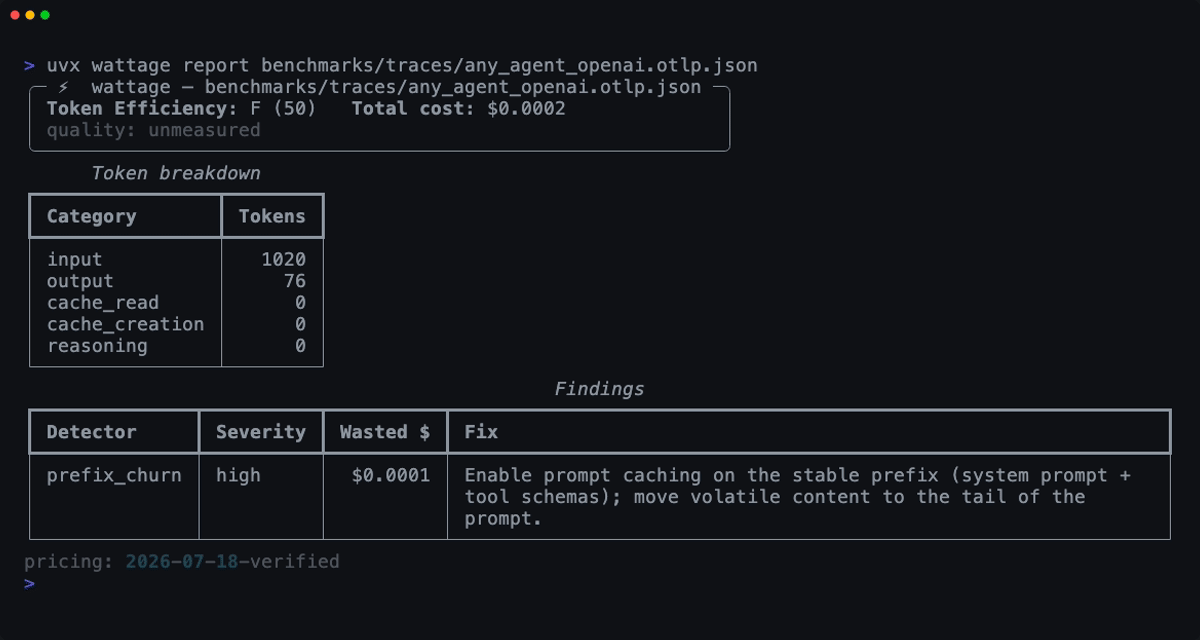
一条真实捕获的 Agent trace(参见来源说明)——Wattage 发现一个稳定的提示词前缀被重复发送而非缓存,计算了浪费成本,并给出修复建议。可通过 vhs docs/assets/demo.tape 重新生成该 GIF(精确命令请参阅 tape 文件)。
text uvx wattage report trace.json
无需配置文件、无需 API 密钥、完全离线——将 OTLP JSON trace 导出文件交给它,它便会为每次调用定价并运行全部检测器。还没有 trace?获取第一条 trace 同时涵盖“我已经有 OTel trace”和“我完全没有埋点”两种情况(提供从零开始、5 分钟生成真实定价报告的可运行路径)。你也可以立刻使用此仓库附带的示例数据进行体验:
text git clone https://github.com/faizannraza/wattage cd wattage && uv sync uv run wattage report examples/sample_trace.json
╭──── ⚡ wattage — examples/sample_trace.json ────╮ │ Token Efficiency: A (100) Total cost: $0.0602 │ │ quality: unmeasured │ ╰─────────────────────────────────────────────────╯ Token breakdown ┏━━━━━━━━━━━━━━━━┳━━━━━━━━┓ ┃ Category ┃ Tokens ┃ ┡━━━━━━━━━━━━━━━━╇━━━━━━━━┩ │ input │ 18450 │ │ output │ 320 │ │ cache_read │ 0 │ │ cache_creation │ 0 │ │ reasoning │ 0 │ └────────────────┴────────┘ No findings — this trace looks efficient. pricing: 2026-07-18-verified
或者,不使用终端视图,而是生成一份可独立分享的 HTML 火焰图:
text uv run wattage report examples/sample_trace.json --html report.html
证据,而非营销说辞
Wattage 最突出的功能是收敛引擎(convergence engine)——即 nonconvergence 检测器。它能够发现 Agent 在循环中反复消耗却没有实际进展的情况,包括朴素的精确匹配重复检测器在结构上无法识别的模式:每次重试都带有新时间戳、在两种策略之间振荡,或“看似有产出”的停滞——即每次调用在技术上都是唯一的,但实际上没有学到任何新信息。
我们没有仅仅声称这一点,而是构建了一组经人工审查、包含 10 个标注合成循环的测试集,并将 Wattage 的分类器与真实的 SHA-256 精确匹配基线实现进行了基准对比:
| 分类器 | Precision | Recall | F1 |
|---|---|---|---|
| Wattage | 1.00 | 1.00 | 1.00 |
| SHA-256 精确匹配 | 1.00 | 0.14 | 0.25 |
你可以自行复现——没有选择性挑选数据,也没有隐藏配置:
text uv run python -m benchmarks.harness
在一条真实捕获的 Agent trace 上(并非合成数据——来源参见 benchmarks/traces/README.md),Wattage 的 prefix_churn 修复模拟显示:通过为稳定前缀启用提示词缓存,成本可降低 44.7%($0.000199 → $0.000110)。由于这是一条仅有 3 轮的演示 trace,美元金额较小,但其机制在生产规模下完全相同。请对你自己的 trace 运行测试,以获得真正重要的数据:
text uv run python -c "from benchmarks.frontier import build_frontier; print(build_frontier())"
完整方法论:收敛引擎。
text uv run wattage badge trace.json --out wattage-badge.svg

将 --badge-out 接入你的 CI 任务(见下文),使其在默认分支的每次合并后重新生成,这样 README 中的徽章就能保持最新状态。
基于 OpenTelemetry GenAI 语义约定 trace 构建,底层采用统一的数据模型(sessions → tasks → loops → iterations → calls),并提供三类功能界面:
wattage report——导入 trace,依据内置且带日期标记的价格快照为每次调用定价,并运行八种检测器:
| 检测器 | 可发现的问题 |
|---|---|
prefix_churn |
稳定上下文被重复发送而不是使用缓存 |
cache_gap |
已尝试缓存,但后续读取的收益不足 |
verbosity |
输出远超该步骤实际所需 |
redundant_tool_calls |
相同工具调用被重复执行(精确或模糊匹配) |
nonconvergence |
无进展地反复尝试、振荡或停滞的循环 |
retrieval_thrash |
重复检索却始终未得到相关结果 |
model_mismatch |
更昂贵的模型在执行更便宜模型也能完成的工作 |
reasoning_overspend |
简单步骤上消耗过多推理 Token |
每项发现都会以实际美元金额定价,附带具体修复方案,并标记 quality_risk 等级(none / low / review)。可能影响输出质量的修复方案(如降级模型、减少推理)只有在通过 --quality 映射获得真实证据支持后,才会计入你的分数。完整详情参见:检测器。
-
wattage score/wattage badge——生成单一的 0–100 Token Efficiency 等级,可用于 README 徽章或 CI 门禁。 -
wattage ci——成本回归门禁(见下文)。
Wattage 绝不编造数字:未定价的模型会让该调用成本保持为零(并使 wattage ci 明确失败,退出码为 4),而不是猜测;未测量的质量信号会被报告为 unmeasured,而不会被假定为没有问题。
yaml
.github/workflows/wattage.yml
name: Wattage on: pull_request: paths: ["agents/", "prompts/", "src/**"] concurrency: group: wattage-${{ github.ref }} cancel-in-progress: true jobs: token-efficiency: runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 - name: Generate trace fixture run: python scripts/run_agent_fixture.py > trace.json - name: Wattage cost-regression gate uses: faizannraza/wattage/action@v0.1.0 with: source: trace.json baseline: .wattage/baseline.json fail-on: "score_below:80,cost_delta_pct_above:5,any_critical:true" pr-comment: "true"
当你的 Agent 回归并超过设定阈值时,工具会令构建失败(退出码 1);它还会将按检测器划分的差异表发布为 PR 评论,并输出 SARIF(会出现在 GitHub 的 Security 标签页中)和适用于其他 CI 系统的 JUnit XML。基线是一个已提交的小型 JSON 文件——其噪声下限保护是结构性的,而非统计性的:只有真正通过门禁的运行才会更新基线。
这只是配置的一半。 PR 任务运行在一次性 checkout 环境中,因此无法负责更新磁盘上的 .wattage/baseline.json;你还需要第二个工作流,在推送至默认分支时触发,并在每次合并后将更新后的基线(及徽章)提交回仓库。跳过这一步,意味着每个 PR 都会永远与同一份过时基线比较。包含两个工作流的完整参考配置见:CI 集成。
检测器通过 Python entry-point group 自动发现,因此新增检测器无需修改本仓库的核心管道——完整的“编写检测器”指南参见 CONTRIBUTING.md,可使用 cache_gap 作为参考示例。
English / 原文
A Kill-A-Watt meter for your AI agents. Point it at a trace and it tells you exactly where your tokens are being burned and wasted, prices each waste pattern in real dollars, prescribes a fix, and can fail your CI when a change makes your agent measurably more expensive.
A real captured agent trace (seeprovenance) — Wattage catches a stable prompt prefix being re-sent instead of cached, prices the waste, and prescribes the fix. Regenerate this GIF with vhs docs/assets/demo.tape (see the tape file for the exact command).
uvx wattage report trace.json
No config file, no API key, fully offline — point it at an OTLP JSON trace export and it prices every call and runs every detector. Don't have a trace yet? Getting your first trace covers both "I already have OTel traces" and "I have zero instrumentation" (a runnable, 5-minute path from nothing to a real, priced report). Or try it right now against the fixture shipped in this repo:
git clone https://github.com/faizannraza/wattage
cd wattage && uv sync
uv run wattage report examples/sample_trace.json


╭──── ⚡ wattage — examples/sample_trace.json ────╮
│ Token Efficiency: A (100)   Total cost: $0.0602 │
│ quality: unmeasured                             │
╰─────────────────────────────────────────────────╯
      Token breakdown
┏━━━━━━━━━━━━━━━━┳━━━━━━━━┓
┃ Category       ┃ Tokens ┃
┡━━━━━━━━━━━━━━━━╇━━━━━━━━┩
│ input          │  18450 │
│ output         │    320 │
│ cache_read     │      0 │
│ cache_creation │      0 │
│ reasoning      │      0 │
└────────────────┴────────┘
No findings — this trace looks efficient.
pricing: 2026-07-18-verified
Or get a self-contained, shareable HTML flame graph instead of the terminal view:
uv run wattage report examples/sample_trace.json --html report.html
The evidence, not a marketing claim
Wattage's standout feature is the convergence engine — the nonconvergence detector, which catches an agent thrashing through a loop without making real progress, including patterns a naive exact-match duplicate detector structurally cannot see (a retry with a fresh timestamp each time, an oscillation between two strategies, a "productive-looking" stall where every call is technically unique but nothing is actually learned).
Rather than assert that, we built a hand-reviewed set of 10 labeled synthetic loops and benchmarked Wattage's classifier against a real SHA-256 exact-match baseline implementation:
| Classifier | Precision | Recall | F1 |
|---|---|---|---|
| Wattage | 1.00 | 1.00 | 1.00 |
| SHA-256 exact-match | 1.00 | 0.14 | 0.25 |
Reproduce it yourself — no cherry-picking, no hidden setup:
uv run python -m benchmarks.harness
And on a genuine captured agent trace (not synthetic — see benchmarks/traces/README.md for provenance), Wattage's prefix_churn fix simulation shows a 44.7% cost reduction ($0.000199 → $0.000110) from enabling prompt caching on the stable prefix — small dollar figures because it's a 3-turn demo trace, but the mechanism is identical at production scale. Run it against your own traces for numbers that matter:
uv run python -c "from benchmarks.frontier import build_frontier; print(build_frontier())"
Full methodology: The Convergence Engine.
uv run wattage badge trace.json --out wattage-badge.svg

Wire --badge-out into your CI job (see below) so it regenerates on every merge to your default branch, and the badge in your README stays live.
Three surfaces, one normalized data model underneath (sessions → tasks → loops → iterations → calls), built from OpenTelemetry GenAI semantic-convention traces:
wattage report— ingests a trace, prices every call against a vendored, dated pricing snapshot, and runs eight detectors:
| Detector | Catches |
|---|---|
prefix_churn |
Stable context re-sent instead of cached |
cache_gap |
Caching attempted but under-redeemed by later reads |
verbosity |
Output far beyond what the step needed |
redundant_tool_calls |
The same tool call repeated (exact or fuzzy) |
nonconvergence |
Loops that thrash, oscillate, or stall without progress |
retrieval_thrash |
Repeated retrieval that never yields relevant results |
model_mismatch |
A pricier model doing work a cheaper one could handle |
reasoning_overspend |
Heavy reasoning-token spend on a simple step |
Every finding is priced in real dollars, includes a concrete fix, and is tagged with a quality_risk tier (none / low / review) — a fix that could plausibly change output quality (a model downgrade, less reasoning) only counts toward your score once a --quality map backs it with real evidence. Full detail: Detectors.
-
wattage score/wattage badge— a single 0–100 Token Efficiency grade for a README badge or a CI gate. -
wattage ci— the cost-regression gate (below).
Wattage never fabricates a number: an unpriced model leaves that call's cost at zero (and fails wattage ci loudly, exit code 4) rather than guessing; an unmeasured quality signal is reported as unmeasured, not assumed fine.
# .github/workflows/wattage.yml
name: Wattage
on:
  pull_request:
    paths: ["agents/**", "prompts/**", "src/**"]
concurrency:
  group: wattage-${{ github.ref }}
  cancel-in-progress: true
jobs:
  token-efficiency:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Generate trace fixture
        run: python scripts/run_agent_fixture.py > trace.json
      - name: Wattage cost-regression gate
        uses: faizannraza/wattage/action@v0.1.0
        with:
          source: trace.json
          baseline: .wattage/baseline.json
          fail-on: "score_below:80,cost_delta_pct_above:5,any_critical:true"
          pr-comment: "true"
Fails the build (exit code 1) when your agent regresses past the threshold you set, posts a per-detector delta table as a PR comment, and emits SARIF (shows up in GitHub's Security tab) and JUnit XML for any other CI system. The baseline is a small committed JSON file — noise-floor protection is structural, not statistical: it only ever updates on a run that actually passed the gate.
This is only half the setup. A PR job runs on a throwaway checkout, so it can't be the thing that updates .wattage/baseline.json on disk — that update needs a second workflow, triggered on push to your default branch, that commits the refreshed baseline (and badge) back after each merge. Skipping it means every PR compares against the same stale baseline forever. Full reference, with both workflows: CI Integration.
Detectors are discovered through a Python entry-point group, so adding one doesn't require touching this repo's core pipeline — see CONTRIBUTING.md for the full "write a detector" walkthrough, using cache_gap as the reference example.