从数周缩短至数分钟:Formula 1® 如何在 AWS 上利用 Agentic AI 加速数据运营
英文标题:From weeks to minutes: How Formula 1® uses agentic AI on AWS to accelerate data operations
Formula 1® 与 AWS 在 2026 年初共同打造了 Data Accelerator,基于 Amazon Bedrock AgentCore 的 Agentic AI 将其 MarTech 数据平台从人工维护系统升级为可自主管理、可观测且统一的数据资产体系。该方案将新数据源接入时间从每个数据源 6 至 8 周缩短为约 40 分钟的代码生成,加上数小时的部署与审核,AI Agent 可自主完成约 95% 的工作。平台还能够自动检测并修复生产环境中的 Schema 变化,通过统一数据血缘、根因分析和上下文图谱提升故障排查效率。对开发者和数据团队而言,这一实践展示了如何以声明式治理、模块化 Agent 技能和端到端可观测性,安全地扩大数据产品自助服务能力。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 1.5 MB
 215.3 KB
 409.9 KB
 223.0 KB
 151.8 KB
 34.2 KB
 3.4 KB
 74.6 KB
 89.5 KB
 70.9 KB
中文
Formula 1®(F1)通过数字平台、F1 TV、社交媒体、票务和商品销售等渠道,全年触达全球超过 8 亿名车迷。比赛每两周举行一次,车迷互动窗口以分钟计,商业决策也必须以赛车发车格般的速度推进。在幕后,F1 的营销技术(MarTech)平台 Customer 360 会捕获这些触点中的互动数据,为个性化、用户分群和商业战略提供支持。
然而,该平台面临严峻的运营挑战。Formula 1 IT 总监 Chris Roberts 表示:“我们的 MarTech 平台是 F1 车迷互动的神经系统。但每增加一个新数据源,都需要 6 到 8 周的人工工程工作。仅集成 12 个新数据源,我们就积压了 18 个月的工作量。”业务产生数据的速度超过了工程团队接入这些数据的速度。因此,F1 数据运营负责人 Matt Kemp 着手提升效率和数据质量。“手工接入数据源耗时长,会造成解决方案差异,最终导致数据完整性问题。我希望有一种可重复、稳健且可靠的解决方案。AWS 从我们的需求出发反向设计,实施了一套端到端运行、并在每个步骤应用业务逻辑的 Agentic 解决方案。”
2026 年初,F1 与 AWS 共同构建了 Data Accelerator。该解决方案利用 Amazon Bedrock AgentCore 上的 Agentic AI,将 F1 的 MarTech 数据平台从人工维护的系统转变为可自主管理、可观测且统一的数据资产体系。本文将介绍 Data Accelerator 如何将数据源接入从最长 8 周缩短至约 40 分钟的代码生成时间,加上数小时的部署时间。它还能够识别并修复生产环境中的数据源异常,在一个窗口中跟踪数据平台运营和 Agent 血缘,并为分析师、工程师和科学家开启协作通道。Roberts 表示:“我们首次获得了覆盖整个 MarTech 平台的端到端可见性,包括数据血缘和根因分析,而不再只是面对满屏告警的仪表板。”
挑战
F1 的 Customer 360 平台接入来自票务合作伙伴、流媒体集成、赞助商激活数据流、社交媒体和商品销售系统的数据。运营如此广泛且高速的数据资产体系,暴露出团队希望解决的三个摩擦点。
首先,每个新数据源的接入都是高度依赖人工的工作:工程师需手动编写 Schema 映射、构建数据接入管道、配置数据质量检查、定义《通用数据保护条例》(GDPR)分类并制定治理策略。每个数据源的这一流程需要 6 至 8 周。
其次,平台必须跟上持续演进的上游数据流。提供商经常在未通知的情况下更改列名、添加字段,或重新组织和调整载荷的发送时间。这些变化往往会在最糟糕的时刻暴露出来,例如比赛周末进行期间,或关键营销活动上线期间。
第三,可见性是碎片化的。日志分散在各项服务中,没有统一的数据血缘。当利益相关方质疑某项指标时,工程师需要花费数小时,手动在 Amazon Simple Storage Service(Amazon S3)路径、Amazon Redshift 控制表、Airflow 日志和 DBT 输出之间追踪问题。
解决方案概览
Data Accelerator 通过同时交付的五个工作流解决了这些挑战:
- 利用 Amazon Bedrock AgentCore 进行 Agentic 数据源接入,并在其运行时容器中托管 Agent。
- 自动化 Schema 演进检测与修复。
- 通过 Amazon SageMaker Unified Studio 实现统一数据访问。
- 借助根因分析(RCA)工具和上下文图谱实现端到端可观测性。
- 自动识别可观测性仪表板和 Agentic 操作中的故障,并在可通过代码变更修复时自动处理。
第六个工作流优化了客户身份解析算法,用于统一车迷跨渠道的触点。以下各节将详细介绍每个工作流。
Agentic 数据源接入
Data Accelerator 的核心是一组平台 Agent:它们接收一份仅包含有限数据源信息的业务需求文档(Business Requirements Document,BRD),并生成完整、可投入生产的数据接入管道。其中包括基础设施代码、数据转换、治理策略和 GDPR 分类,无需人工编写任何样板代码。Agent 分两个阶段工作:
阶段 1:配置生成
当需要接入一个新数据源时,团队成员会将 BRD 上传到 Amazon S3 存储桶。上传操作会触发 AWS Lambda 函数,后者调用 Amazon Bedrock AgentCore Runtime——Amazon Bedrock AgentCore 的一项能力。Agent 读取 BRD 并生成一组配置文件。随后,它通过 GitHub App 访问 GitHub,将这些文件作为 Pull Request 推送至标准化 Git 代码库;同时通过 Jira REST API 访问 Jira,创建引用该 PR 的工单。所有 Agent 对话和操作都会通过 AgentCore 内置的可观测性功能在 Amazon CloudWatch 中被追踪。被分配的工程师会进行审核、必要时调整并批准。
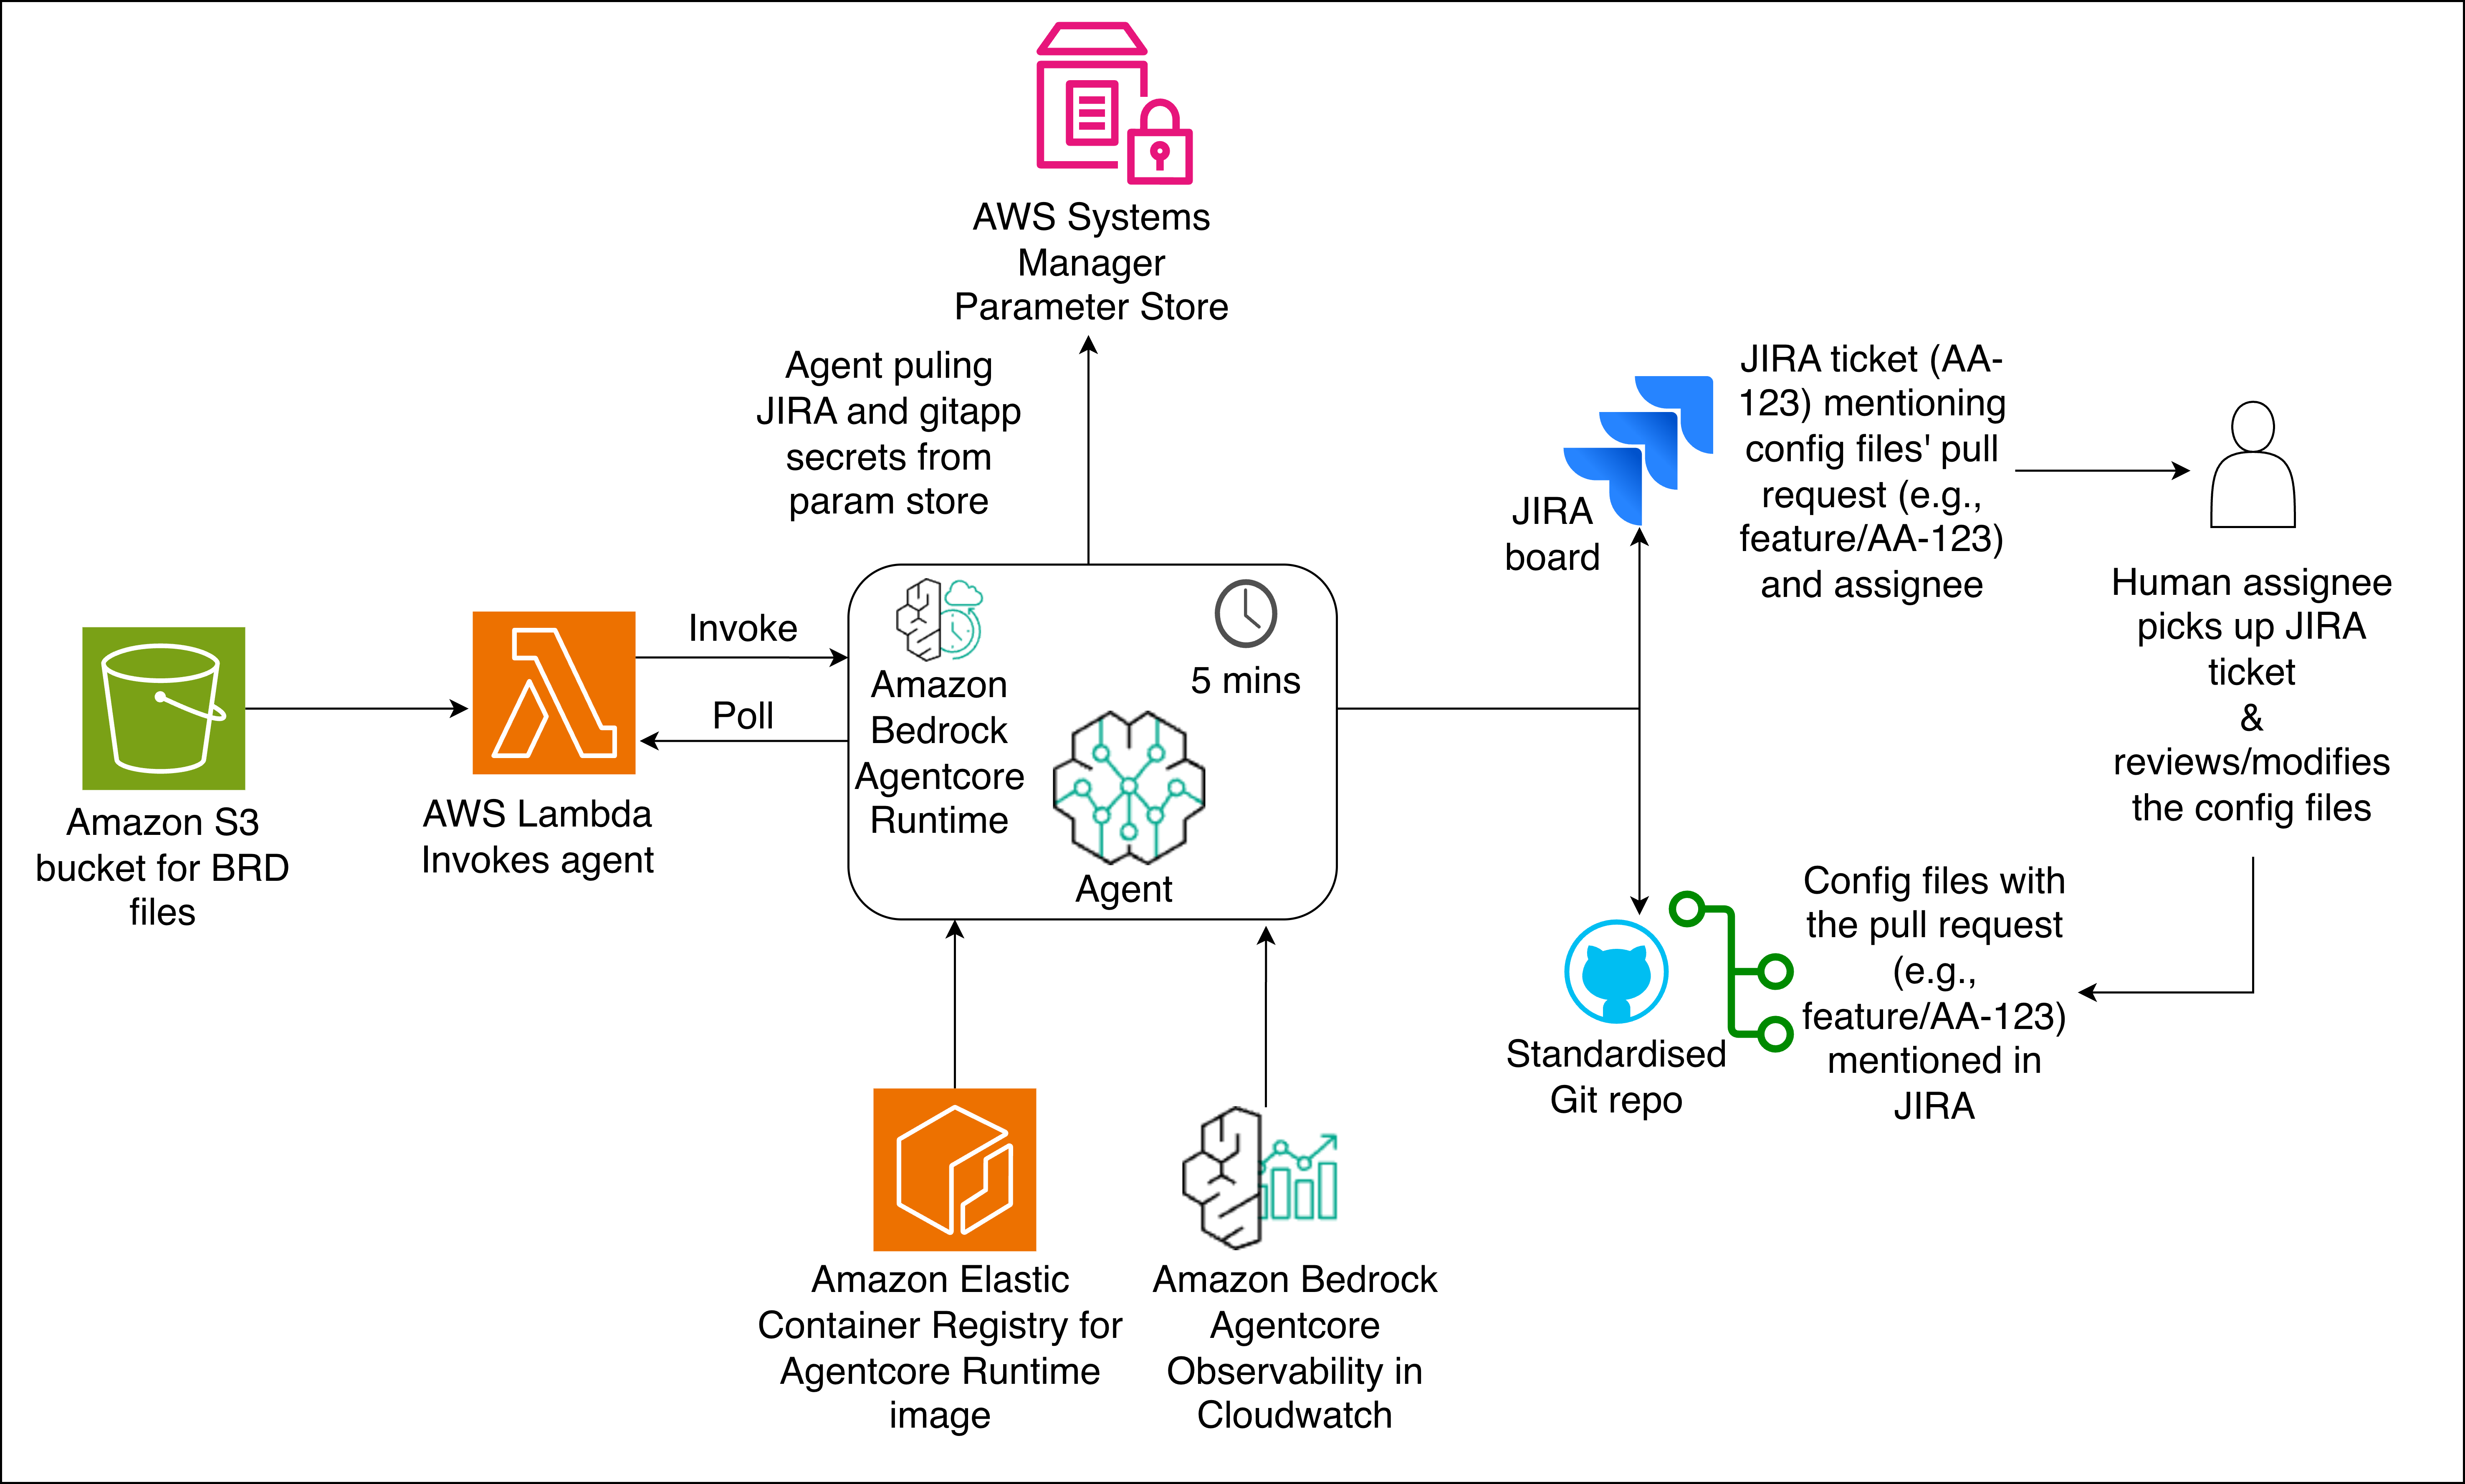
阶段 1 工作流:上传 BRD 将触发 Agent 生成配置文件并创建 Pull Request
阶段 2:完整管道生成
配置文件获批后,由人工触发下一阶段。Agent 采用已批准的配置,生成三个独立的 Pull Request:
- AWS Glue 应用程序和基础设施代码。
- DBT 转换框架。
- 包括 GDPR 标记在内的治理策略。
所有三个 PR 都关联到同一个 Jira 工单,以确保可追溯性。工程师会在基础设施、DBT 和治理代码库中分别审核并批准它们。
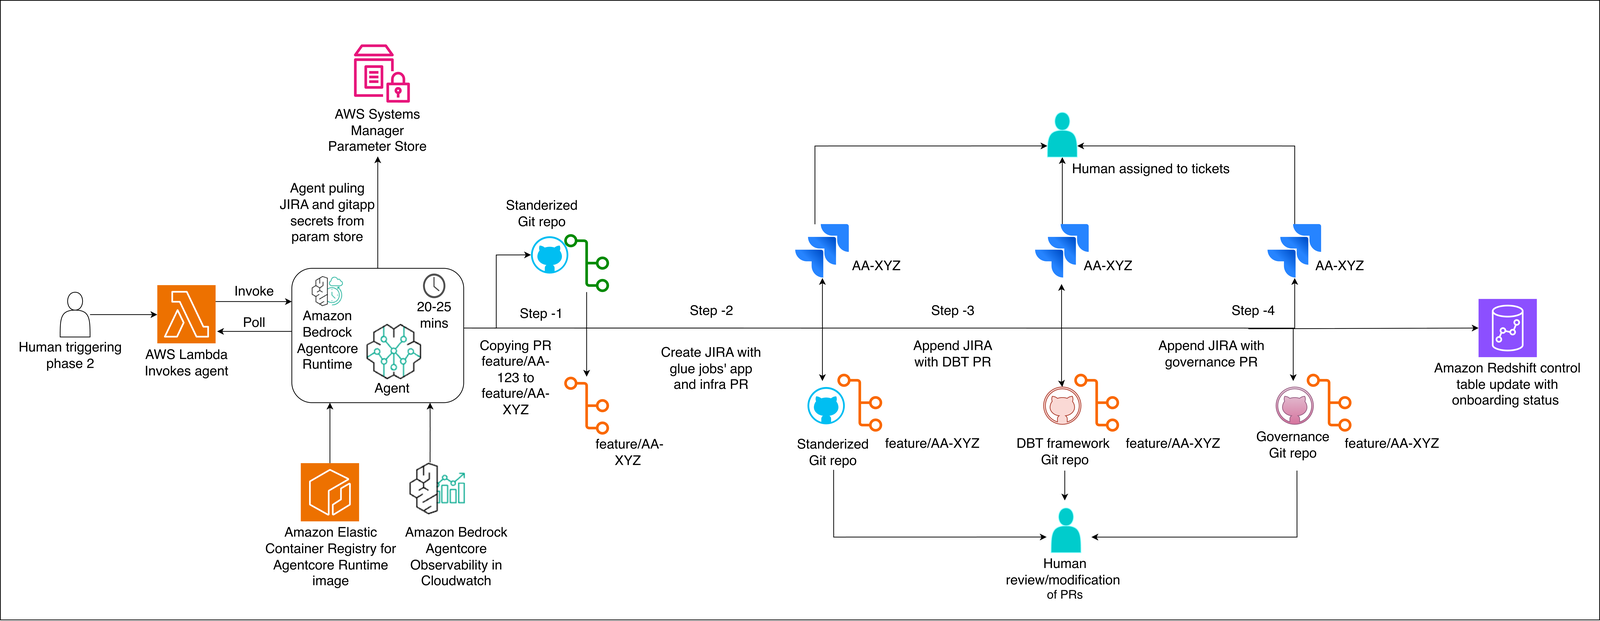
阶段 2 工作流:Agent 生成基础设施、转换和治理 Pull Request
自动化 GDPR 分类
这套系统区别于基础代码生成器之处,在于其集成了 GDPR 分类能力。Agent 会主动分析每个数据列,判断其是否包含个人数据、敏感个人数据或假名化数据,并为其标记相应的 GDPR 类别。这些标记会直接发布至 SageMaker Unified Studio 中的治理注册表,使合规团队无需经历人工审核周期即可立即获得可见性。
模块化技能架构
该系统并非紧耦合的 Agent 图谱。单个 Agent 使用模块化技能定义运行,每种定义都封装了一项独立能力:Schema 映射和数据类型推断、数据质量验证、治理执行以及敏感数据分类。在运行时,Agent 会评估传入的需求并激活相关技能,通过多轮推理过程将这些技能组合起来。第 0 轮(Pass-0)通过清洗处理 Token 管理;第 1 轮(Pass-1)汇总工具输出;第 2 轮(Pass-2)则汇总整体评估,通过逐步优化准确性和完整性,而非依赖一次性响应。新能力以新的技能模块形式交付,无需变更核心 Agent 循环,使架构能够随着平台增长保持可维护性和可组合性。
最终,接入时间从 6 至 8 周降至约 40 分钟的代码生成时间,加上数小时的部署和审核时间。AI Agent 现在可自主完成 95% 的工作。
自动化 Schema 演进
接入新数据源是一项挑战,而保持现有集成健康则是另一项挑战。上游提供商经常修改其数据结构,从重命名一列到创建新字段。此前,F1 团队通常在管道失败时才发现这些变化,而且往往发生在直播比赛周末期间。
如今,负责接入的同一套 Agent 架构会持续监控上游 Schema 变化。当提供商修改数据结构时,Agent 会通过 AWS Lambda 和 Amazon EventBridge 的事件驱动触发器检测变化。它会评估下游影响,识别哪些管道受到影响,以及哪些消费者依赖发生变更的字段。随后,它会在所有受影响的代码库中生成必要的代码更新,并创建一张包含完整上下文和关联 PR 的 Jira 工单。工程师会收到通知,其中解释变更内容、说明影响范围,并提供建议修复方案供审核。端到端解决时间现已从数天缩短至数小时。
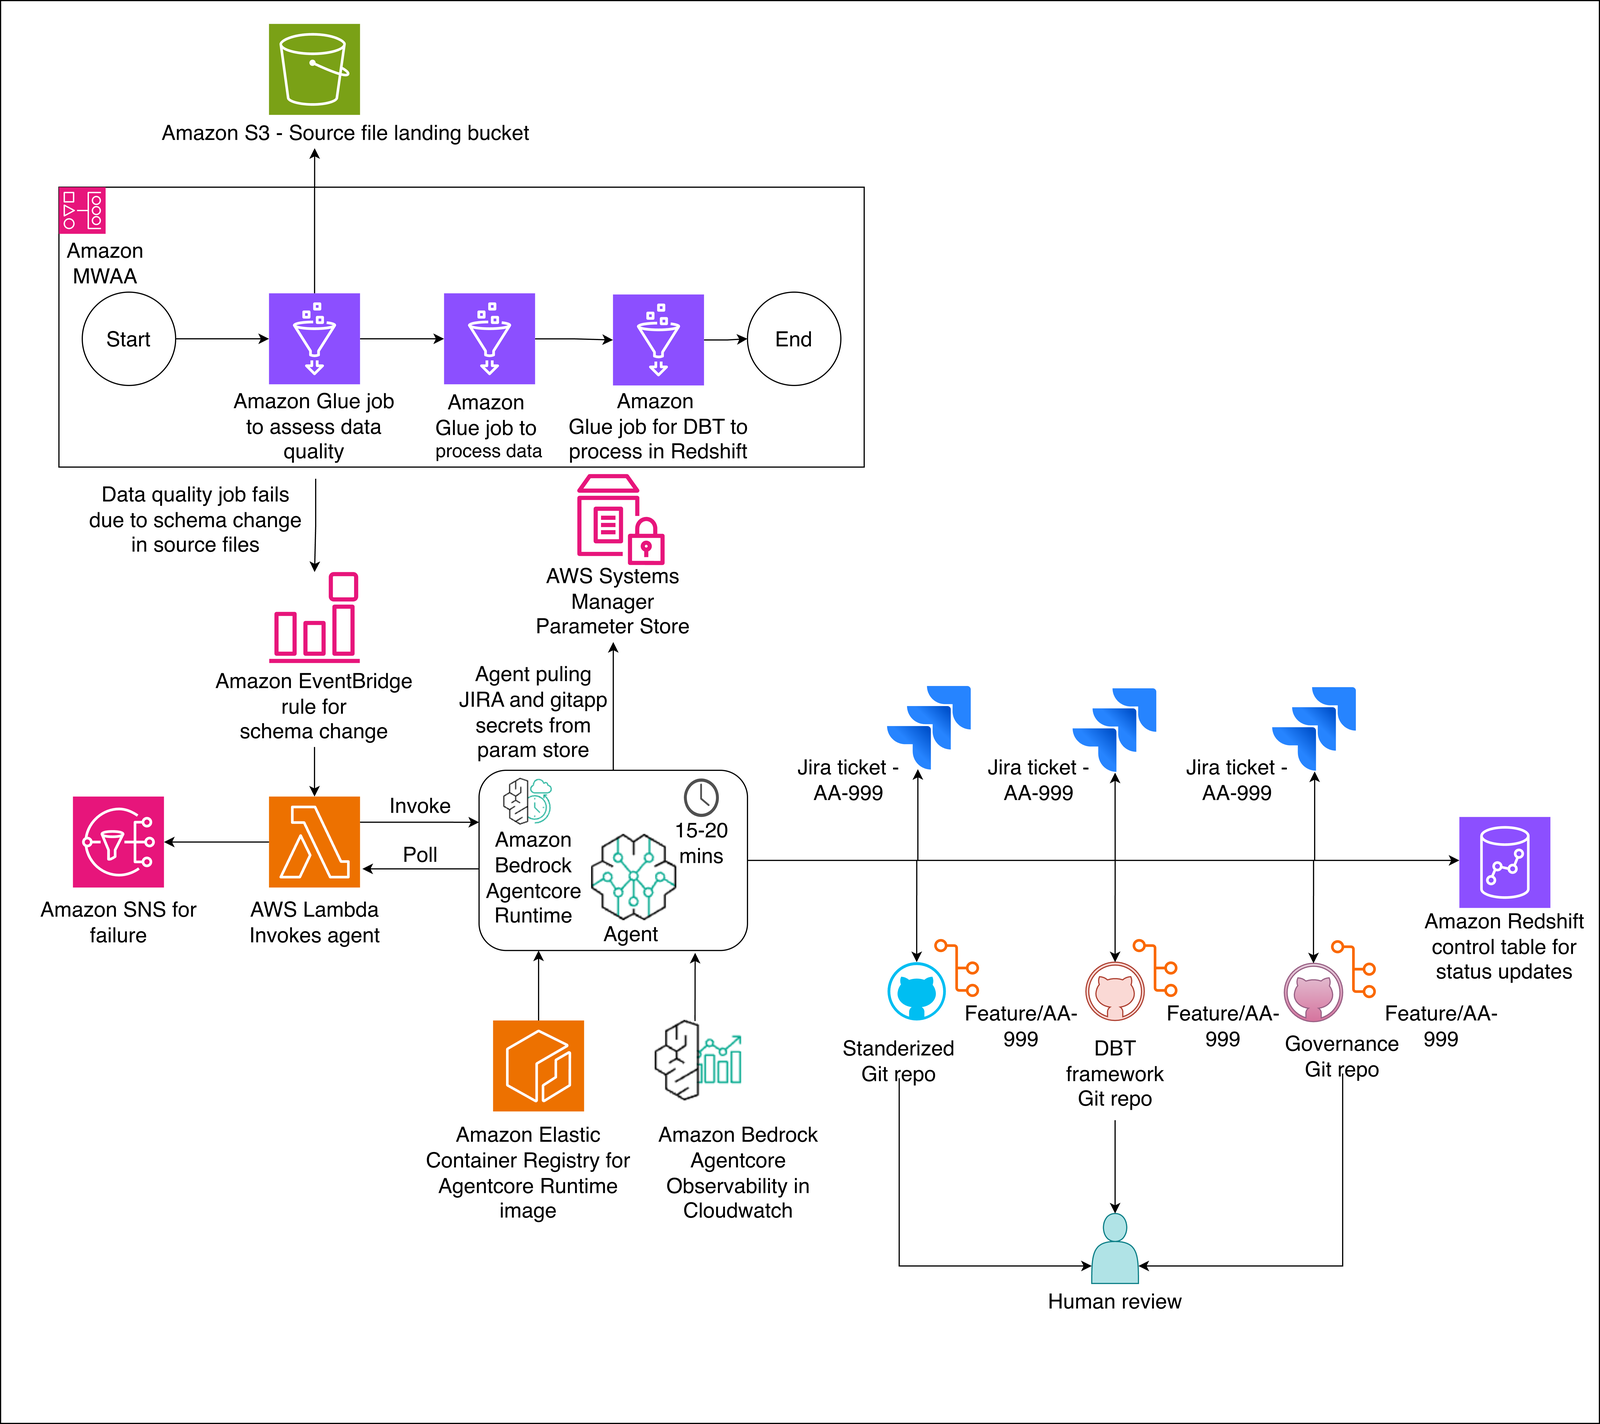
Schema 演进 Agentic 工作流
使用 Amazon SageMaker Unified Studio 实现统一数据访问
在 Data Accelerator 之前,使用 Customer 360 数据需要在多个相互割裂的环境中切换。数据工程师在一个账户中维护数据管道;希望为车迷行为建模的数据科学家需要访问另一个账户;分析师则在完全不同的第三个环境中工作。没有人共享工具或上下文,在任何分析开始前,从提出问题到获得答案都要经过数天协调。
该解决方案以 Amazon SageMaker Unified Studio 为基础,构建数据网格框架:一个中央治理账户负责在多个生产者团队之间代理数据发现和访问。关键推动因素是:治理被编码为声明式配置,而非手动控制台操作。单个数据源定义可同时将数据发布到数据目录,并配置消费者订阅所需的访问控制。这意味着 Agent 可以安全地端到端接入新数据产品,从存储、目录到受治理的访问均可完成,因为该框架从设计上强制执行安全约束。无需人工审核 IAM 策略或 AWS Lake Formation 授权。平台通过结构化设计保证正确性。这正是实现“一个统一入口”的基础。
数据工程师可在一个地方维护和治理数据集,数据科学家也可以在同一环境中找到这些数据集:它们经过治理、具备文档,并已准备好用于建模。构建车迷分群模型或优化客户身份算法的数据科学家,无需知道数据存放位置、由谁负责管道,或应使用哪个 S3 前缀。他们只需打开 Unified Studio,找到经过整理的 Customer 360 数据集,然后开始建模。由于声明式治理在不牺牲控制力的前提下实现了安全自助服务,他们能够获得共享 Notebook、一致的工具和受治理的访问。数据整理和数据消费终于并存于同一环境。
使用 RCA 和上下文图谱实现端到端可观测性
数据平台的可信度取决于团队回答一个问题的能力:此时此刻,数据是否正确?在 Data Accelerator 之前,回答这一问题意味着登录 Apache Airflow、检查 Amazon S3 路径、查询 Amazon Redshift 控制表并阅读 DBT 日志。Roberts 补充道:“没有人拥有完整视图。当利益相关方问‘为什么这个数字看起来不对?’时,回答总是‘给我们几个小时’。可观测性仪表板彻底改变了这一点。”
可观测性层将从 S3 Raw 接入,经由 Processed 层,再到 Amazon Redshift DBT 阶段的完整数据血缘,呈现为一张按健康状态着色的交互式图谱。用户可单击任意节点,深入查看各个数据源和数据表;每项内容都会显示通过/失败状态、最近运行时间和持续时间。如果管道失败,血缘可视化会准确显示故障发生位置及受影响的下游数据。
根因分析(RCA)是 F1 平台内的一项 Agentic 工具,可读取系统日志并识别整个数据资产体系中的故障点。仅使用 RCA 时,它能够告诉你哪里失败了。我们通过以 JSON 编码的方式传入业务上下文和系统拓扑,对 RCA 工具进行了增强。S3 中缺失文件可能是错误本身,但借助上下文图谱,RCA 会告诉你上游提供商重新安排了交付窗口,因此在管道运行时文件并不存在。这正是“知道什么失败了”与“理解为什么失败”之间的差异。
F1 首次在同一处获得了完整血缘、因果根因分析和业务上下文定义,且该仪表板每 15 分钟自动刷新一次。
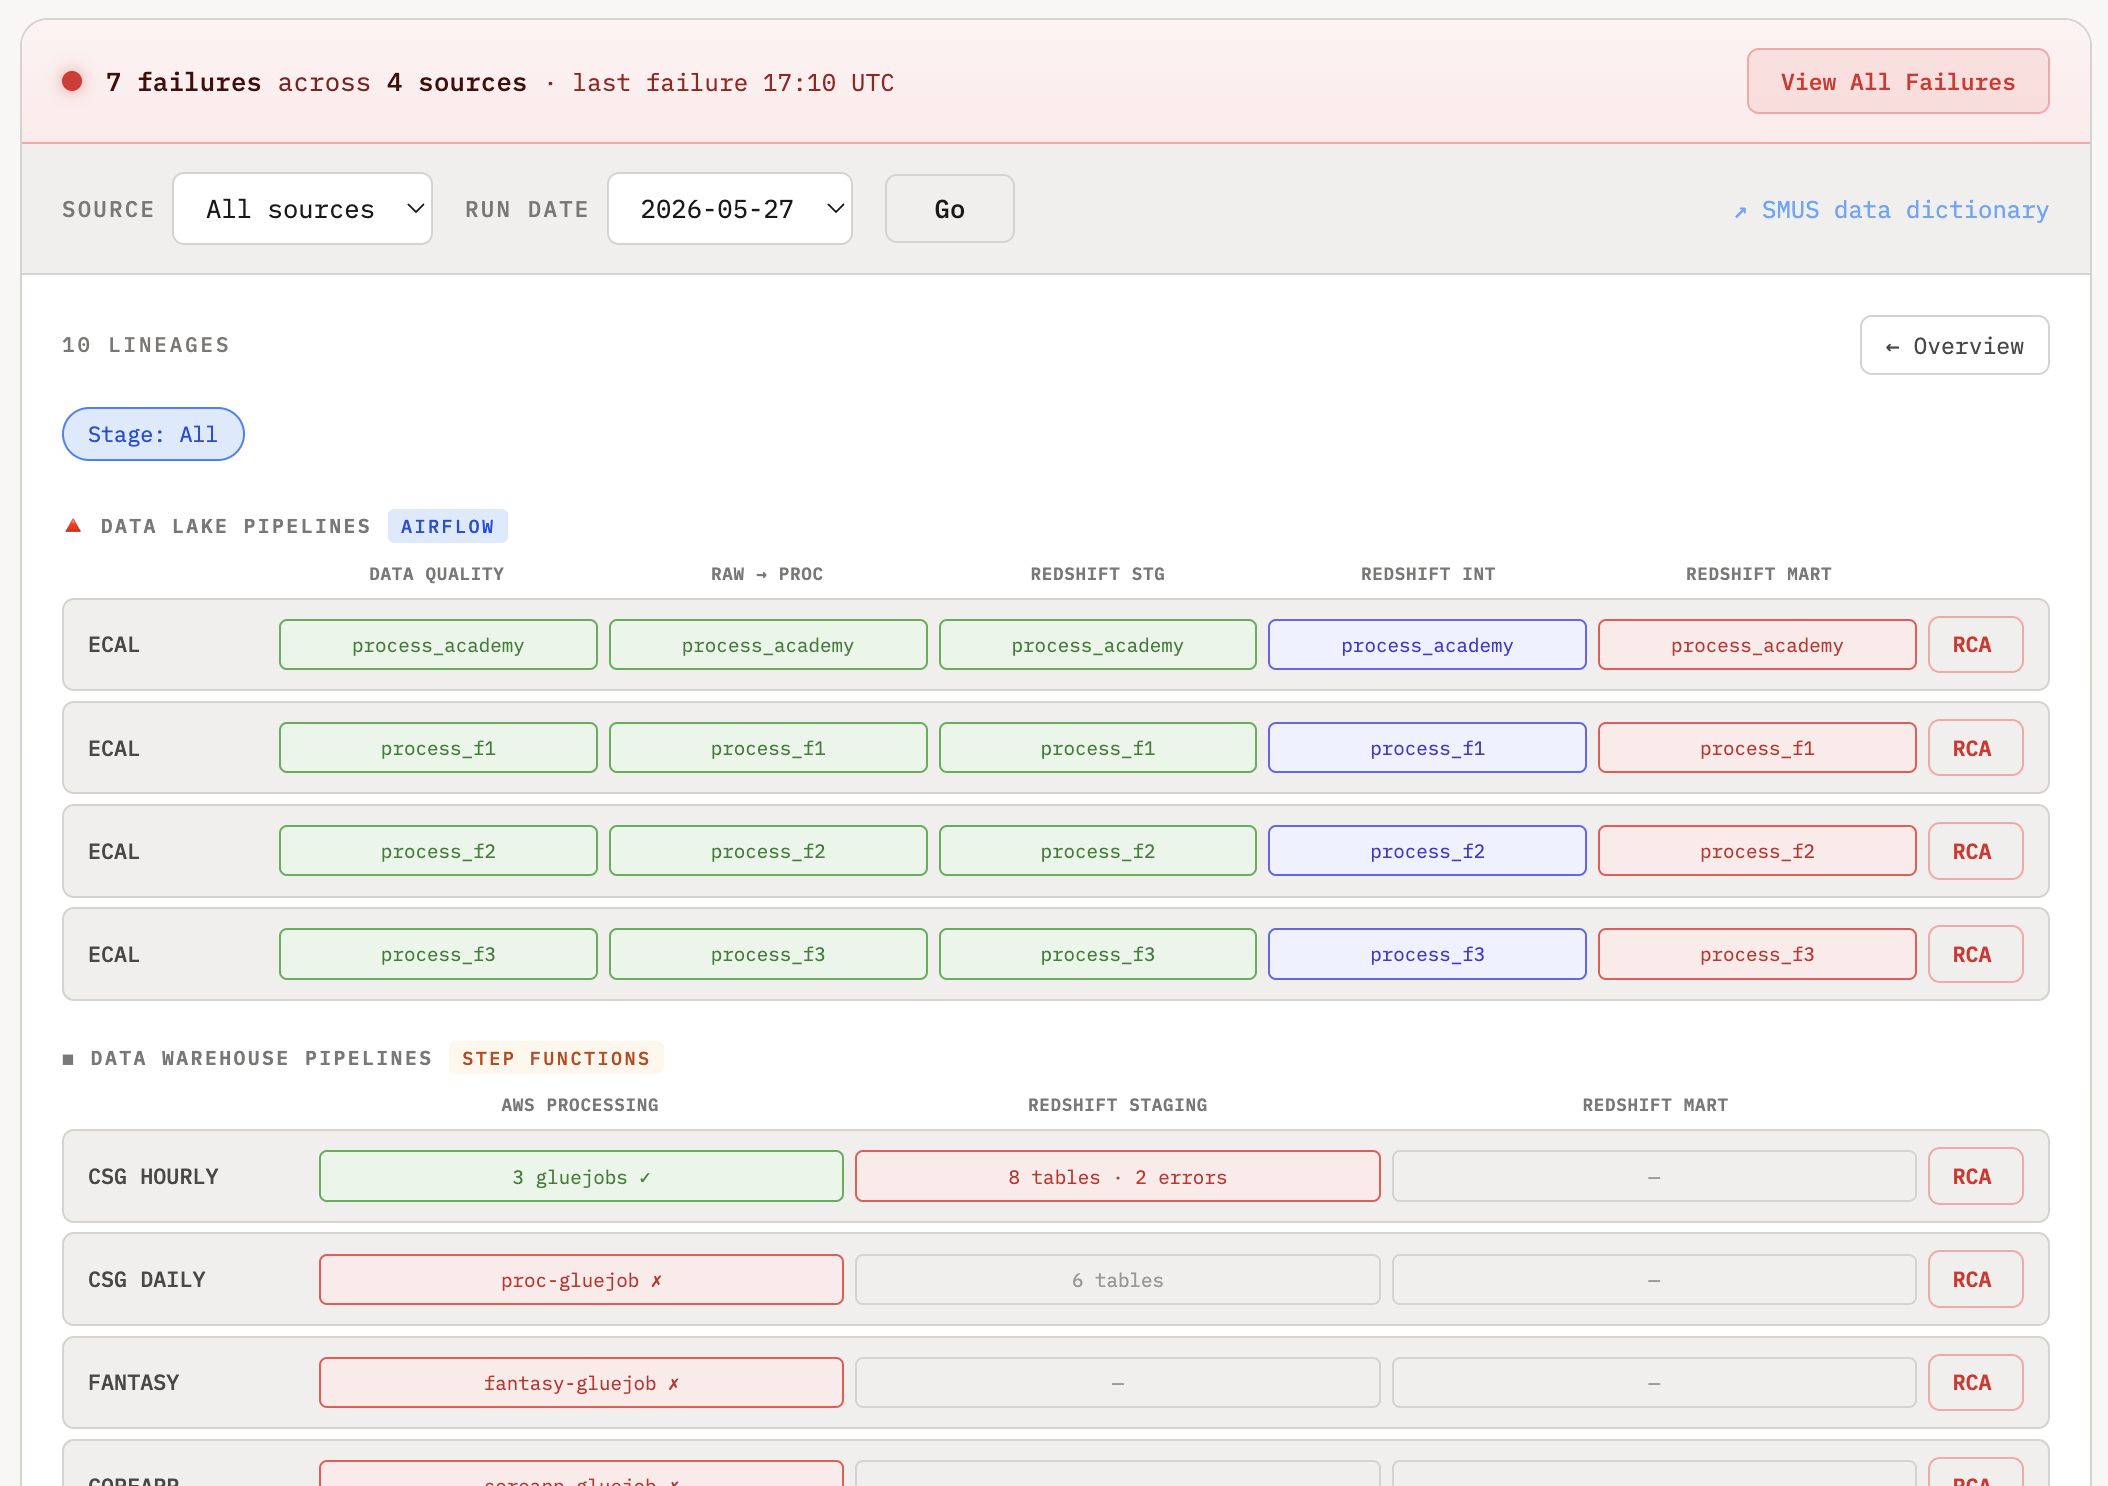
展示跨数据源和处理阶段管道健康状态的数据血缘可视化
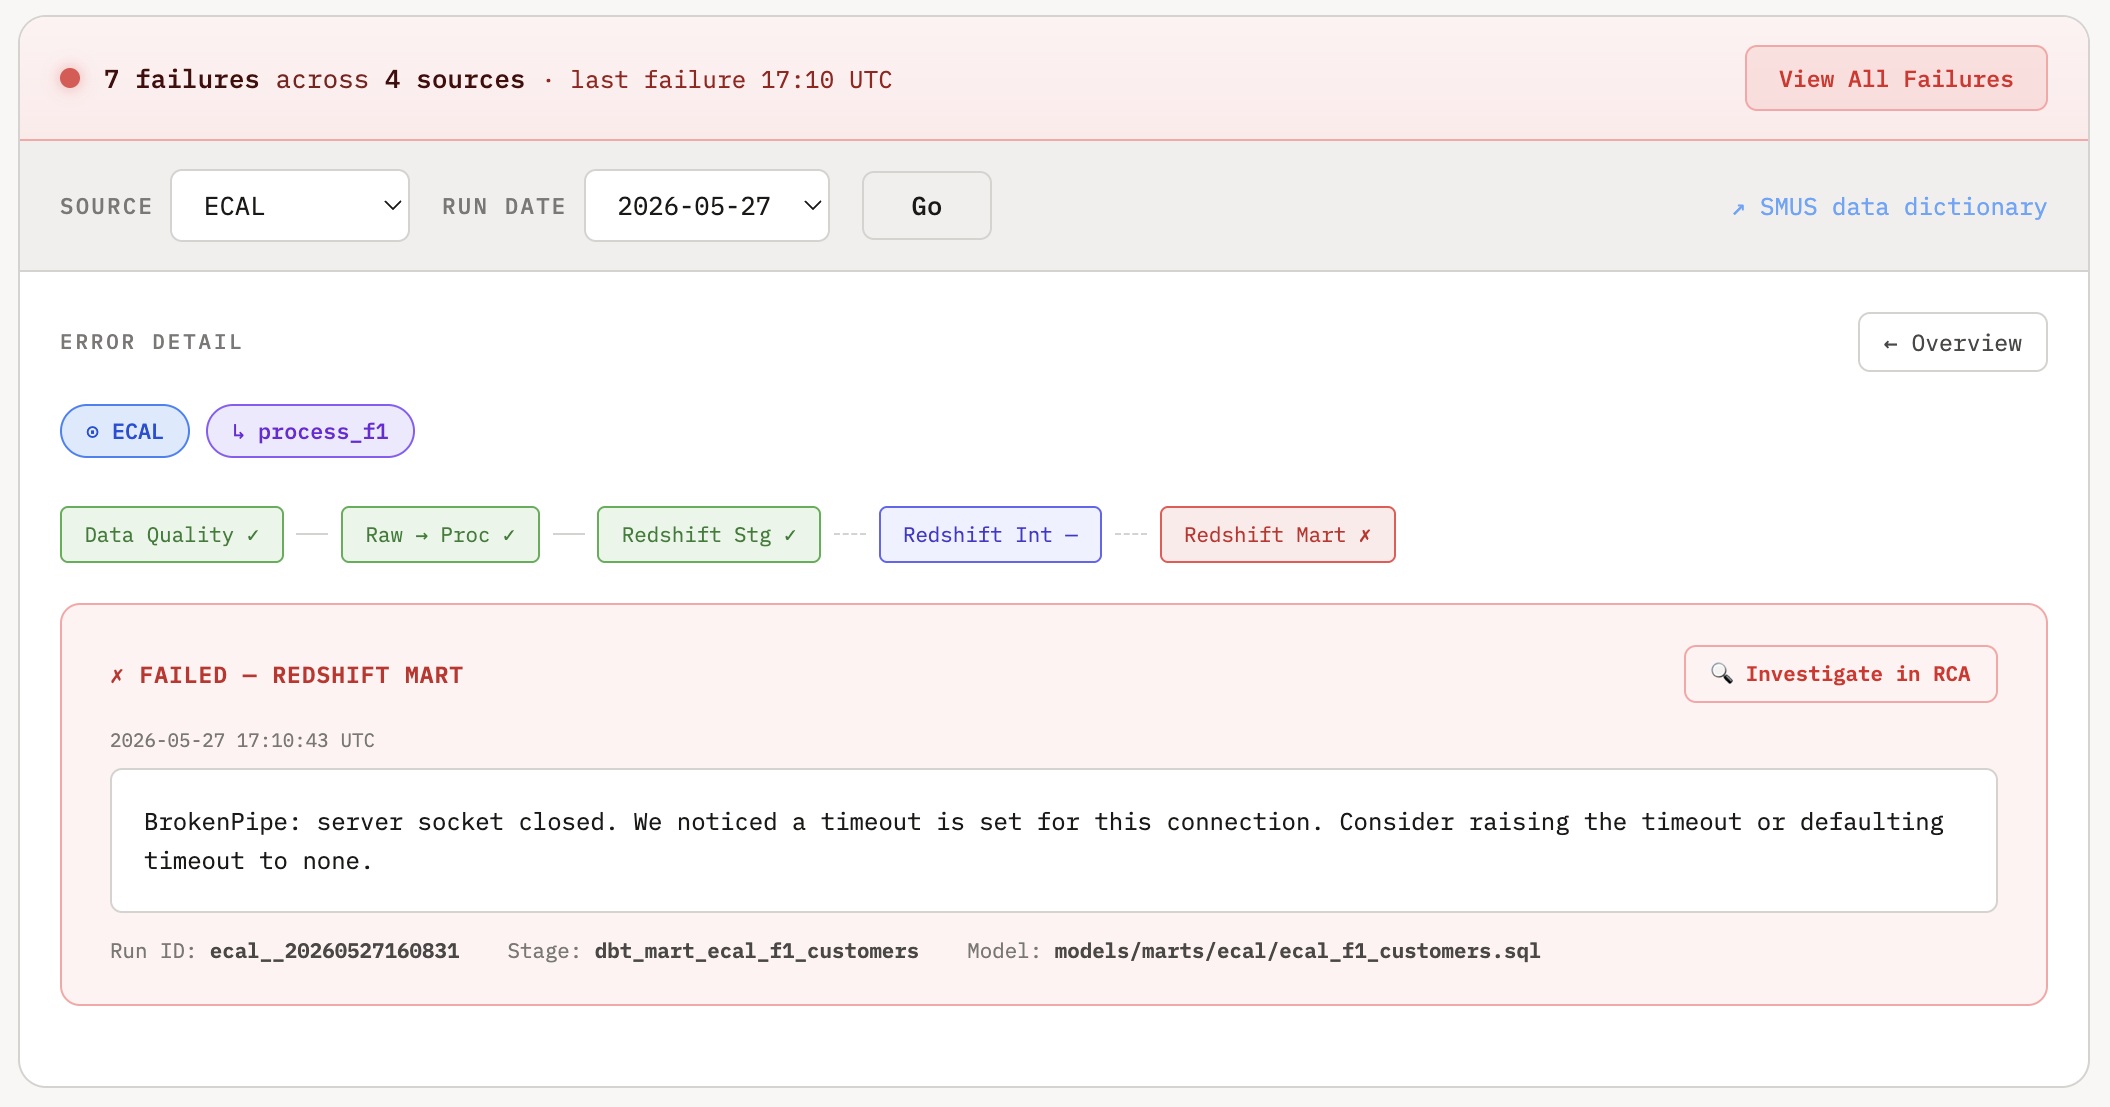
包含故障详情的可观测性仪表板
客户身份解析
最后一个工作流优化了用于解析 F1 车迷触点间客户身份的算法。一名车迷可能通过应用互动、在网站购买门票、观看 F1 TV,并在社交媒体上参与互动。要将这些互动统一为单一身份,同时避免错误合并或漏匹配,正是在车迷个性化平台(Fan Personalization Platform,FPP)中实现有效个性化的关键。
F1 已有一套可运行的身份解析流程,但其速度很慢,而且 st
English / 原文
Formula 1® (F1) engages an audience of over 800 million fans globally across digital platforms, F1 TV, social media, ticketing, and merchandise year-round. Races happen every two weeks. Fan engagement windows are measured in minutes and commercial decisions need to move at the speed of the grid. Behind the scenes, F1’s marketing technology (MarTech) platform, Customer 360, captures interactions across all of these touchpoints to power personalization, segmentation, and commercial strategy.
However, the platform faced a significant operational challenge. According to Chris Roberts, Director of IT at Formula 1, “Our MarTech platform is the nervous system of F1’s fan engagement. But every new data source required 6 to 8 weeks of manual engineering. We had an 18-month backlog just to integrate 12 new sources.” The business was generating data faster than the engineering team could wire it up. As a result, Matt Kemp, F1 Head of Data Operations, set to improve efficiencies and data quality. “Manually ingesting data sources is time consuming, creates solution variances, and ultimately results in data integrity issues. I wanted a solution that was repeatable, robust and reliable. AWS worked backwards from our needs to implement an agentic solution that worked end to end, applying business logic at each step.”
In early 2026, F1 and AWS worked together to build the Data Accelerator, a solution that uses agentic AI on Amazon Bedrock AgentCore to transform F1’s MarTech data platform from a manually maintained system into a self-managed, observable, and unified data estate. In this post, we show how the Data Accelerator reduced data source onboarding from up to 8 weeks to approximately 40 minutes of code generation plus hours of deployment. It also identified and fixed data source anomalies in production, tracked data platform operations and agent lineage in a single window, and opened a gateway for analysts, engineers, and scientists to collaborate. “For the first time, we have end-to-end visibility across the entire MarTech platform with data lineage and root cause analysis, not just dashboards full of alerts,” says Roberts.
The challenge
F1’s Customer 360 platform ingests data from ticketing partners, streaming integrations, sponsor activation feeds, social media, and merchandise systems. Operating a data estate of this breadth and velocity surfaced three areas of friction the team set out to solve. First, onboarding each new data source was a heavily manual effort: engineers wrote schema mappings, built ingestion pipelines, configured data quality checks, defined General Data Protection Regulation (GDPR) classifications, and set governance policies by hand. This process took 6 to 8 weeks per source. Second, the platform had to keep pace with constantly evolving upstream feeds. Providers frequently changed column names, added fields, or restructured and rescheduled payloads without notice. Those changes often surfaced at the worst possible moment, such as mid race-weekend or during a mission-critical campaign launch. Third, visibility was fragmented. Logs were scattered across services with no unified data lineage. When a stakeholder questioned a metric, engineers spent hours manually tracing the issue across Amazon Simple Storage Service (Amazon S3) paths, Amazon Redshift control tables, Airflow logs, and DBT outputs.
Solution overview
The Data Accelerator addressed these challenges through five workstreams delivered simultaneously:
- Agentic data source onboarding using Amazon Bedrock AgentCore, hosting agents in its runtime containers.
- Automated schema evolution detection and remediation.
- Unified data access through Amazon SageMaker Unified Studio.
- End-to-end observability with root cause analysis tool (RCA) and context graph.
- Automated identification of a failure in observability dashboard and agentic operation if they could be fixed with code changes.
A sixth workstream optimized the customer identity resolution algorithms that unify fan touchpoints across channels. The following sections describe each workstream in detail.
Agentic data source onboarding
The centerpiece of the Data Accelerator is a set of platform agents that take a Business Requirements Document (BRD) with limited information about the data source and produce a fully production-ready onboarding pipeline. This includes infrastructure code, data transformations, governance policies, and GDPR classification without a human writing a single line of boilerplate. The agents work in two phases:
Phase 1: Configuration generation
When a new data source needs onboarding, a team member uploads a BRD to an Amazon S3 bucket. The upload triggers an AWS Lambda function, which invokes Amazon Bedrock AgentCore Runtime, a capability of Amazon Bedrock AgentCore. The agent reads the BRD and generates a set of configuration files. It then accesses GitHub through a GitHub App to push these files as a pull request to the standardized Git repository, and accesses Jira through its REST API to create a ticket referencing the PR. All agent conversations and actions are traced in Amazon CloudWatch through built-in AgentCore observability. The assigned engineer reviews, adjusts if necessary, and approves.
Phase 1 workflow: a BRD upload triggers the agent to generate config files and open a pull request
Phase 2: Full pipeline generation
Once the configuration files are approved, a human triggers the next stage. The agent takes the approved configuration and generates three separate Pull Requests:
- AWS Glue application and infrastructure code.
- DBT transformation framework.
- Governance policies including GDPR tagging.
All three PRs link to a single Jira ticket for traceability. Engineers review each one across the Infrastructure, DBT, and Governance repositories and approve.
Phase 2 workflow: the agent generates infrastructure, transformation, and governance pull requests
Automated GDPR classification
What distinguishes this from a basic code generator is the integrated GDPR classification. The agent proactively analyzes every data column, determines whether it contains personal data, sensitive personal data, or pseudonymized data, and tags it with the appropriate GDPR category. These tags publish directly to the governance registry in SageMaker Unified Studio, giving the compliance team immediate visibility without manual review cycles.
Modular skill architecture
The system is not a tightly coupled agent graph. A single agent operates with modular skill definitions, each encapsulating a distinct capability: schema mapping and data type inference, data quality validation, governance enforcement, and sensitive data classification. At runtime, the agent evaluates incoming requirements and activates the relevant skills, composing them through a multi-pass reasoning process. Pass-0 handles token management through scrubbing, Pass-1 summarizes tool outputs, and Pass-2 rolls up an overall assessment, refining accuracy and completeness progressively rather than relying on a one-shot response. New capabilities ship as new skill modules without changing the core agent loop, keeping the architecture maintainable and composable as the platform grows.
The result is onboarding time dropped from 6 to 8 weeks to approximately 40 minutes of code generation plus hours of deployment and review. AI agents now handle 95% of the work autonomously.
Automated schema evolution
Onboarding new data sources is one challenge, but keeping existing integrations healthy is another. Upstream providers frequently modify their data structures, from renaming a column to creating a new field. Previously, the F1 team discovered these changes when a pipeline failed, often during a live race weekend. The same agent architecture that handles onboarding now continuously monitors for upstream schema changes. When a provider modifies their data structure, the agent detects it through event-driven triggers using AWS Lambda and Amazon EventBridge. It assesses the downstream impact, identifying which pipelines are affected, and which consumers depend on the changed fields. It then generates the necessary code updates across all affected repositories and creates a Jira ticket with full context and linked PRs. Engineers receive a notification that explains what changed, describes the impact, and presents a proposed fix for review. End-to-end resolution now takes hours instead of days.
Schema evolution agentic workflow
Unified data access with Amazon SageMaker Unified Studio
Before the Data Accelerator, working with Customer 360 data required navigating multiple disconnected environments. Data engineers curated pipelines in one account. Data scientists who wanted to model fan behavior needed access to a separate account, and analysts operated in a third world entirely. Nobody shared tooling or context, and getting from a question to an answer took days of coordination before any analysis could begin.
The solution uses Amazon SageMaker Unified Studio as the foundation for a data mesh framework where a central governance account brokers data discovery and access across multiple producer teams. The key enabler: governance is codified as declarative configuration, not manual console operations. A single data source definition simultaneously publishes data to the catalog and provisions the access control needed for consumers to subscribe. This means agents can safely onboard new data products end-to-end, from storage to catalog to governed access, because the framework enforces security constraints by construction. No human needs to review IAM policies or AWS Lake Formation grants. The platform guarantees correctness structurally. This is what makes the “one front door” possible.
Data engineers curate and govern datasets in one place, and data scientists find those same datasets in the same environment: governed, documented, and ready to model. A data scientist building a fan segmentation model or optimizing the customer identity algorithm doesn’t need to know where the data lives, who owns the pipeline, or which S3 prefix to use. They open Unified Studio, find the curated Customer 360 datasets, and start modeling. They get shared notebooks, consistent tooling, and governed access, because declarative governance made safe self-service possible without sacrificing control. The curation and the consumption finally live side by side.
End-to-end observability with RCA and context graph
A data platform is only as trustworthy as the team’s ability to answer one question: is the data correct right now? Before the Data Accelerator, answering that question meant logging into Apache Airflow, checking Amazon S3 paths, querying Amazon Redshift control tables, and reading DBT logs. “Nobody had the full view. When a stakeholder asked, ‘why does this number look wrong?’ the answer was always, ‘give us a few hours.’ The observability dashboard changes that entirely,” adds Roberts.
The observability layer presents full data lineage from S3 Raw ingestion through Processed layers into Amazon Redshift DBT stages as a single interactive graph, color-coded for health. Users click on any node to drill down to individual sources and tables, each showing pass/fail status, last run time, and duration. If a pipeline fails, the lineage visualization shows exactly where the break occurred, and which downstream data is affected.
Root cause analysis (RCA) is an agentic tool within F1’s platform that reads system logs and identifies failure points across the data estate. On its own, RCA can tell you what failed. We augment the RCA tool by passing through business context and system topology, codified as JSON. A missing file in S3 might be the error, but with the context graph, RCA tells you that the upstream provider rescheduled their delivery window, which is why the file wasn’t there when the pipeline ran. That’s the difference between knowing what failed and understanding why.
For the first time, F1 has full lineage, causal root cause analysis, and business context definitions in one place, and the dashboard auto-refreshes every 15 minutes.
Data lineage visualization showing pipeline health across sources and stages
Observability dashboard with failure details
Customer identity resolution
The final workstream optimized the algorithms that resolve customer identity across F1’s fan touchpoints. A single fan might interact through the app, buy tickets on the website, watch on F1 TV, and engage on social media. Unifying those interactions into a single identity without false merges or missed matches is what makes effective personalization possible within the Fan Personalization Platform (FPP).
F1 already had a working identity resolution process, but it was slow and struggled to scale with the growing volume of fan interactions across channels. Rather than re-architecting the pipeline or replacing components, the team focused on optimizing the existing resolution algorithm’s computational performance. By profiling execution bottlenecks and tuning the matching logic, the engagement reduced processing time by 50%, while keeping the entire resolution pipeline and its downstream integrations fully intact. No processes were changed, no accuracy trade-offs were made: the same algorithm now runs in half the time at F1’s production scale.
With faster resolution, F1 can onboard any new data source and gather new customer data in half the existing time. Faster resolution means fresher unified profiles, which in turn means more timely and relevant personalization across every marketing channel.
“The whole point is to deliver the right message to the right fan at the right time, whether that’s through email, the F1 app, ticketing, or social. Now that we can onboard sources in hours and resolve identities faster, we can actually deliver the personalized experiences our fans expect across every marketing channel,” says Kemp.
Security and governance by design
The Data Accelerator operates on the principle that AI proposes and humans review. The agents run on Amazon Bedrock AgentCore with long-term memory, retaining context across invocations. Development used Kiro for structured spec-driven development and Amazon Bedrock (Claude Sonnet 4.6) as the foundation model. The event-driven backbone uses AWS Lambda for compute, Amazon EventBridge for routing, Amazon Managed Workflows for Apache Airflow (MWAA) for workflow orchestration, and Amazon S3 as the raw data layer. All AI model access is governed through F1’s AI Gateway for unified access control, cost management, and audit logging. But the architecture is only half the story. The security posture is what makes this production-ready.
The security posture includes:
- Least privilege: fine-grained permissions, short-lived tokens with one-hour expiry, access limited to specific repositories and resources.
- Full audit trail: every action is logged and attributed for compliance.
- Human review: every generated Pull Request goes through engineer approval.
- Automated testing: agents generate comprehensive tests for their own changes.
- Rollback capabilities: issues surfaced post-merge can be reverted immediately.
- Network isolation: the entire system runs within private subnets in Amazon Virtual Private Cloud (Amazon VPC) with no direct internet access.
- Encrypted credentials: all secrets stored at rest in AWS Systems Manager Parameter Store.
“What gave us confidence to put agentic AI in our production data pipelines was what we call ‘Human at the helm.’ The agents do the heavy lifting, but humans make the decisions. Every change goes through the same review process our engineers already use, so adoption was immediate.” says Roberts.
The impact
The Data Accelerator delivered measurable impact across F1’s MarTech operations:
- Data source onboarding: reduced from 6 to 8 weeks to approximately 40 minutes of code generation plus hours of deployment and review.
- Autonomous work: AI agents handle 95% of onboarding tasks without human intervention.
- Time-to-value: approximately 99% reduction.
- Schema evolution: end-to-end resolution in hours instead of days.
- Integration backlog: 18-month backlog cleared in weeks.
- Data engineers who previously spent their time writing boilerplate ingestion code and chasing schema breaks now focus on strategic initiatives that advance the business.
- Implementation velocity: a single developer took the agentic solution from proof of concept to production release in 4 months.
The reliability, consistency, and data integrity of the MarTech platform were improved, while the operational overhead was reduced: “The Data Accelerator didn’t just speed things up. It changed how we operate. Our data engineers went from writing boilerplate ingestion code to focusing on strategic initiatives. Issues can be identified and fixed before our end users even notice.” says Kemp.
Conclusion
The Data Accelerator’s success comes down to three principles: meeting developers where they already work, keeping them at the helm, and embedding governance like GDPR classification from day one rather than bolting it on after. These principles shaped a solution where F1 partnered with AWS to use agentic AI on Amazon Bedrock AgentCore to transform MarTech data operations. By combining automated data source onboarding, schema evolution detection, and unified data access through Amazon SageMaker Unified Studio, F1 reduced onboarding time by approximately 99% and eliminated an 18-month integration backlog in weeks.
The approach is deliberately replicable. Any organization dealing with multi-source data onboarding, schema volatility, and governance requirements can apply the same architecture to their own environment. The agents are domain-agnostic, and they know how to onboard, classify, and monitor. The domain is interchangeable.
Getting started
To learn more about the AWS services used in this solution:
Acknowledgments
This outcome is the result of years of incremental improvements to the MarTech platform, delivered through a close partnership between F1 and AWS. Many contributors across both organizations have shaped the architecture and strengthened the foundations that made the Data Accelerator possible. We are grateful to the following thought leaders and developers for their dedication and expertise: Paula Marenco Aguilar, Nadeen Nilanka, Taye Aduewa, Marton Juhasz, Deepak Gulia, Alex Goff, Nick Morgan, and Seshadri Senthamaraikannan.
About the authors
Subhro Bose
Subhro is a Senior Data & AI Architect at AWS and the creator of CausalIF, an open-source causal inference library that brings causal inference to model reasoning with consistency of results, discovering why things happen in complex systems. His work spans agentic AI, self-healing platforms, and turning causal discovery into production-grade intelligence across logistics, finance, and compliance.
Jerome Descreux
Jerome is a Senior Delivery Manager within AWS Professional Services. He leads large scale transformation programs and strategic projects for major EMEA enterprise customers, across various industries including logistics, manufacturing, financial services, aviation, and sports.
Matt Kemp
Matt leads CRM and Customer Data Operations at Formula 1, overseeing the data, insight and engagement capabilities that connect millions of fans with the sport. He has delivered large-scale digital transformation programmes and is championing the use of AI, machine learning and agentic technologies to drive innovation, operational efficiency and personalised fan experiences.
Arunraja Kumar
Arunraja is Senior Data Architect at Formula 1, responsible for shaping the data platform and architecture that powers fan engagement, insight and innovation across the sport. He led the technical transformation of F1’s Fan Personalisation Programme, evolving the platform into an AI-native, agentic ecosystem that enables scalable, real-time experiences and supports Formula 1’s ambition to deliver personalised engagement to more than one billion fans worldwide.