使用 Amazon Bedrock 和 AWS Lambda 构建智能体式应用部署器
英文标题:Building an agentic app deployer with Amazon Bedrock and AWS Lambda
PDI Technologies 构建了 PDI Brew,让非技术员工用自然语言描述需求,并在数秒内获得已完成部署、支持多租户且受 SSO 保护的 AWS Web 应用。该平台将规划与部署拆分:可插拔的规划器生成统一 JSON 部署清单,运行在 AWS Lambda 上的部署智能体则以确定性、可审计的方式创建所需 AWS 资源。平台还通过 Amazon Bedrock Guardrails、12 计数器原子预算和终止开关,为应用内 AI 提供集中治理与成本控制。该架构说明企业可在不向每个小工具分配完整研发与 DevOps 流程的前提下,实现安全、按需扩缩且受治理的内部应用交付。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 470.1 KB
 2.0 MB
 116.7 KB
 23.6 KB
 47.2 KB
中文
许多企业都有一长串始终未能落地的内部工具需求。某个团队需要一个运费计算器、一个简单的录入表单,或是一个基于电子表格的小型仪表板,但每项需求都需要开发人员、待办事项优先级和部署流水线。这些工具规模太小,难以获得优先级;数量又太多,无法忽视。
PDI Technologies 服务于便利零售和石油批发行业,通过安全连接数据与运营,帮助全球企业提升效率和盈利能力。PDI 拥有 40 年经验、约 4,000 名员工,并为 200 多个国家和地区超过 200,000 个客户地点提供服务。PDI 认识到,传统部署流水线正在阻碍非技术团队交付其所需工具。
为弥合这一差距,PDI Technologies 构建了 PDI Brew。非技术员工使用自然语言描述想要的工具,数秒内即可获得一个已完整预置的多租户 Web 应用,该应用受单点登录(SSO)保护并运行在 AWS 上。不需要 Git、终端或 DevOps 知识。需要工具的人,就是交付工具的人。由于每个应用都继承同一平台,因此都可以选择启用由 Amazon Bedrock 支持且受治理的 AI 能力(聊天、摘要、分类)。整个过程中,应用作者无需接触模型端点或 API 密钥。
本文将介绍 PDI Technologies 如何围绕一种智能体式预置模式构建 PDI Brew。规划智能体通过 AI 助手中的技能(例如 Claude、ChatGPT 或 Claude Code),或在 AWS 信任边界内调用 Amazon Bedrock 模型,将用户意图捕获为结构化清单。随后,运行在 AWS Lambda 上的预置智能体会分解该清单、对工作负载进行分类、选择工具,并在一次请求中编排创建所有下游 AWS 资源。接着,我们将展示同一平台如何将应用内 AI 作为通往 Amazon Bedrock 的受治理、最小权限网关对外提供。我们会介绍架构、安全模型、Lambda 内的长时间运行预置步骤、AI 护栏与预算设计,以及大规模运行该系统的成本特征。
前提条件
要理解此架构,建议熟悉以下 AWS 服务:AWS Lambda、Amazon API Gateway、Amazon DynamoDB、Amazon Simple Storage Service(Amazon S3)、Amazon CloudFront 和 Amazon Bedrock。认证部分若具备 Microsoft Entra ID(原 Azure AD)和 MSAL.js 的使用经验会更有帮助。如果计划在自己的环境中实施类似模式,请确认已安装并配置 AWS Command Line Interface(AWS CLI),且所用凭证拥有创建 AWS Identity and Access Management(IAM)角色与策略所需的足够权限。
传统的内部工具交付方式,将一个简单的业务需求绑定到完整的软件交付生命周期。即使只是单页计算器,也要承担代码仓库、构建流水线、认证集成、托管方案、TLS 证书、DNS、日志记录和持续维护的成本。结果是,小型工具形成了永久待办队列,始终排在创造营收的功能之后。
我们希望系统具备四项特性:
- 输入意图,输出应用。 请求者描述工具需求,由平台完成预置,无需移交给工程团队。
- 默认安全且受治理。 每个应用都继承企业 SSO、范围受限的 IAM、HTTPS 和集中式可观测性。不存在“不安全”的路径。
- 无服务器且可缩减至零。 数百个小型应用在闲置时几乎不应产生费用,无需维护共享服务器,也不必规划容量。
- AI 并非无序开放。 应用可以使用生成式 AI,但只能通过带有护栏、配额和完整审计追踪的受控路径使用。绝不允许嵌入各自的模型密钥。
解决方案概览
“智能体式”并不一定意味着“每个决策都要在请求路径中使用大语言模型”。我们将智能体定义为:接收一个目标、对其进行分解、选择工具,并朝着该目标采取行动的系统。PDI Brew 将这一定义的两部分拆分为两个具有截然不同信任配置的智能体。
规划智能体负责捕获意图。它会访谈用户、帮助用户细化需求、生成应用前端,并且至关重要的是,输出一个结构化部署清单:即对用户意图的 JSON 描述,包含应用名称、类型、数据模式和访问控制设置。规划逻辑被打包为 Vibe App Builder 技能,并运行在员工已经使用的任意 AI 助手中。在助手中运行规划器,既能让用户在已打开的工具中获得丰富的对话体验,也能让 AWS 侧的暴露面保持较小。
预置智能体则是一个 AWS Lambda 函数。它接收清单,并作为确定性、可审计、能够使用工具的编排器运行。它会验证请求、对工作负载分类,并选择预置路径。随后,它将 AWS 和 Microsoft Graph API 作为工具调用,通过异步自调用处理长时间运行步骤,并返回可访问的 URL。有意将预置逻辑放在 Lambda 中、而不是聊天会话中:预置正是这样一种工作负载,其中每个决策都必须有日志、可复现且不受幻觉影响。
可插拔规划器:自带助手
意图可以来自任何地方,因此规划器被设计为可插拔层,提供两条可互换的路径。通过一个环境变量(PLANNER_MODE)选择启用哪一条路径;两条路径均输出完全相同的部署清单,因此所有下游流程都无需改变。
路径 A —— 任意 AI 助手中的 Vibe Skill。Vibe App Builder skill(下文称 Vibe Skill)封装规划逻辑,并在员工已经使用的任意 AI 助手中运行。该助手会访谈用户、生成前端并产出清单。规划器在 AWS 之外运行,从而让用户能够在已打开的工具中获得丰富的对话体验。
路径 B —— AWS 信任边界内的 Amazon Bedrock。对于 Teams、Web 表单或 IDE 等渠道,请求会发送至 Amazon Bedrock。一次 Bedrock 模型调用(InvokeModel)充当规划器:它对工作负载分类、输出同一份清单,并且可在预置之前验证或修复数据模式。此路径完全在 AWS 内部运行,因此每项决策都会被记录在 AWS CloudTrail 中并关联至模型调用 ID,且意图数据不会离开 AWS 边界。对于具有严格数据驻留要求的团队而言,这一点十分重要。
一份契约,一个预置智能体。由于两种规划器都输出相同的清单 JSON,Lambda 上的预置智能体和完整的单应用运行时无论采用哪条路径都完全一致。增加 Bedrock 路径是一项增量改动,而非重写。并且,PLANNER_MODE 可以按组织、工作区或用户固定设置,因此一家企业可以要求使用 Bedrock 路径,另一家则可保留助手内体验。这也保留了清晰的前进路径:未来无需触及路径 A 或预置智能体,即可将 Bedrock 调用替换为功能更丰富的托管智能体运行时。
架构
下图展示端到端架构。它包括三个层次:可插拔的意图与规划层、统一的智能体式预置运行时,以及单应用运行时;并由共享的边缘、身份和可观测性服务提供支持。
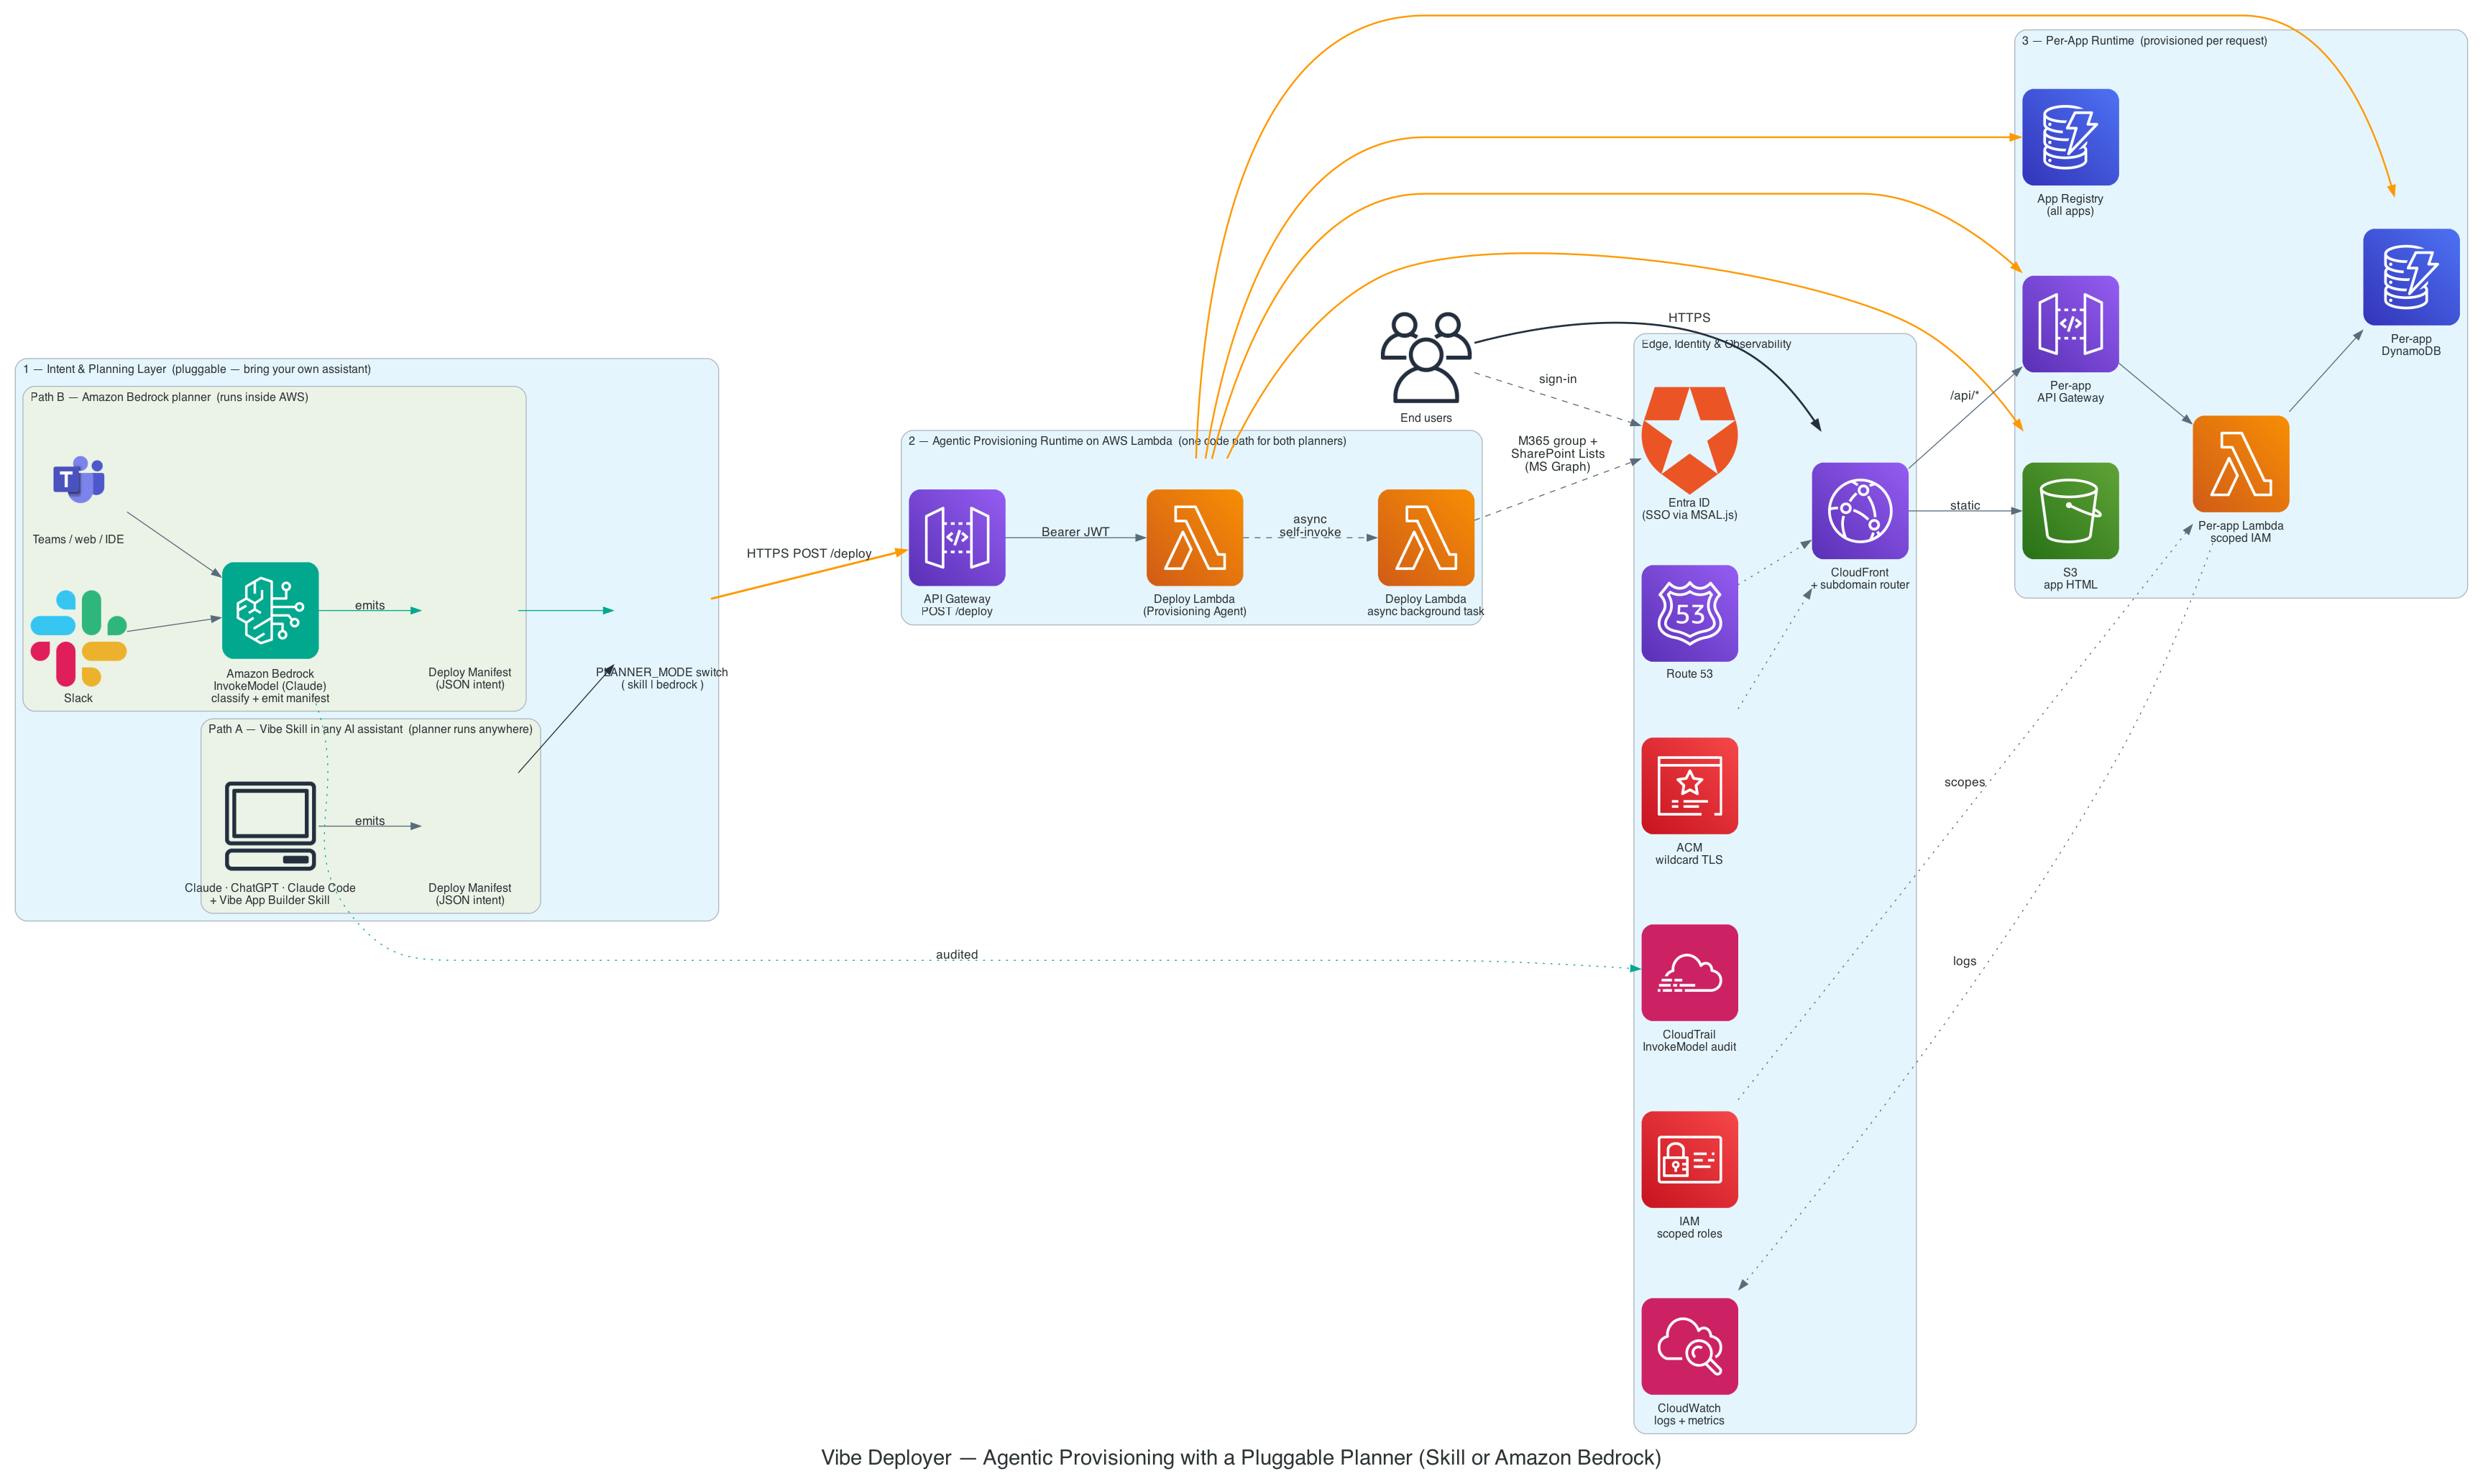
以下演练将追踪一个请求经过每个层次的过程:
- 在意图与规划层中,员工以自然语言描述工具需求。根据
PLANNER_MODE,规划器要么是运行在其助手中的 Vibe Skill(路径 A),要么是位于 Slack 或 Teams 等渠道之后的一次 Amazon Bedrock 调用(路径 B)。无论采用哪种方式,规划器都会以 JSON 格式输出相同的部署清单。 - 该清单通过 HTTPS 发送至 Amazon API Gateway 上的
POST /deploy,并使用 Entra ID bearer token(MSAL.js)进行认证。由于两条规划路径汇聚至同一端点和契约,从此处开始后续流程完全相同。 - API Gateway 调用Deploy Lambda(预置智能体)。它验证 Entra JWT(租户和有效期),强制要求存在访问控制模式,并在应用注册表中以原子方式检查 slug 所有权。
- 智能体会对工作负载分类(静态应用,例如计算器或图表;全栈应用,需要数据持久化),并选择匹配的预置路径。
- 对于静态应用,智能体会将 HTML 封装在 Entra 认证壳中,上传至 Amazon S3,使 Amazon CloudFront 缓存失效,并在 Amazon DynamoDB 中注册该应用。
- 对于全栈应用,智能体还会预置单应用 DynamoDB 表、带有范围受限 AWS IAM 角色的单应用 AWS Lambda 函数,以及单应用 API Gateway。随后,它会在封装并上传之前,将新的 API URL 注入前端。
- 长时间运行的步骤(例如创建 Microsoft 365 组)通过异步自调用处理:智能体以后台任务方式调用自己的第二个副本,使用户请求能够快速返回。
- 最终用户通过 CloudFront 上的 HTTPS 访问已上线的应用,其中 CloudFront Function 将
<slug>.domain路由到 S3 中正确的应用。每个应用均位于 Entra 单点登录之后,并可在 Amazon CloudWatch 中观测。
预置智能体的工作方式
预置智能体执行两项核心功能:对工作负载分类,以及编排长时间运行的预置步骤。
Deploy Lambda 将 AWS SDK for JavaScript v3 和 Microsoft Graph API 视为自己的工具带。它根据清单决定调用哪些工具以及调用顺序。静态应用仅涉及 S3、CloudFront 和 DynamoDB 注册表。全栈应用还会使用 DynamoDB 和 API Gateway;对于具备额外能力的应用,还会使用 Lambda 和 IAM。访问控制会延伸至 Microsoft Graph,以创建和管理应用的 M365 组。分类过程具有确定性且被完整记录:同一份清单始终生成同一计划。
Lambda 内的长时间运行工作
部分预置步骤的耗时超过用户愿意在同步请求中等待的时间,尤其是在创建 M365 组后的目录传播。智能体不会让请求保持打开状态,而是使用异步自调用:它以 Event 调用类型对自身调用 lambda:InvokeFunction,立即返回可访问 URL,并让后台副本完成缓慢任务。这相当于智能体“后台任务”模式的无服务器实现,并且完全位于 Lambda 执行边界内。
单应用运行时:双层计算模型
并非每个应用都需要独立的计算资源。大多数全栈应用只是对其专属 DynamoDB 表进行简单的创建、读取、更新和删除(CRUD)操作,因此它们运行在由平台管理、位于采用预置并发的加权别名之后的共享 CRUD Lambda 上。这提供了一条经过预热和审计的代码路径来服务多个应用,并具备自动金丝雀回滚保护。只有当应用清单声明了封闭允许列表中的某项能力时(例如发送电子邮件、调用特定外部 HTTPS 域,或从指定数据源读取),应用才会升级到拥有专用、范围受限 IAM 角色的单应用 Lambda。该升级需要管理员审批。审批以对提交代码的静态分析以及对生成 IAM 角色的漂移检测为基础。默认路径是共享且低成本的;特权路径则是单应用、最小权限且受门控的。
受治理的应用内 AI
已部署应用越来越希望具备 AI 功能:汇总一条记录、对录入表单分类,或基于应用数据回答问题。最简单直接的做法,是让每个应用嵌入模型供应商的 SDK 和 API 密钥。这会分散凭证、破坏集中治理,并使支出难以控制。PDI Brew 采取相反的方式:AI 是通过一个端点触达的平台能力,而不是每个应用各自拥有的一项集成。
每次调用都会在模型调用前后运行三项控制措施。首先,强制性的 Amazon Bedrock Guardrail 会在每次调用中处理个人身份信息(PII)脱敏、内容过滤和提示词注入防御。应用无法关闭此功能。其次,一个12 计数器原子预算负责执行支出限制。在任何 Bedrock 调用之前,单次 DynamoDB TransactWriteItems 会在四个范围(全局、应用、用户和应用-用户)内预留支出,每个范围又分为三个时间窗口(每日、每周、每月)。十二个计数器中任一计数器触及上限,都会以 429 Too Many Requests 和一个标明触发限制的结构化响应体短路该请求。这使得无论因缺陷、循环还是滥用导致的失控成本,都会成为有界且可观测的事件,而非一张意外账单。应用所有者可由管理员授予更高的应用范围预算;全局和单用户上限不能由所有者扩大。第三,一个双层终止开关允许管理员禁用始终优先于所有者
English / 原文
Many enterprises have a long tail of internal tools that never get built. A team needs a shipping-cost calculator, a straightforward intake form, a small dashboard over a spreadsheet, but each one requires a developer, a backlog slot, and a deployment pipeline. The tools are too small to prioritize and too numerous to ignore.
PDI Technologies serves the convenience retail and petroleum wholesale industries, helping businesses around the globe increase efficiency and profitability by securely connecting their data and operations. PDI has 40 years of experience, a workforce of approximately 4,000 employees, and serves over 200,000 customer locations across more than 200 countries and territories. PDI recognized that traditional deployment pipelines were blocking non-technical teams from shipping the tools they needed.
To close that gap, PDI Technologies built PDI Brew. A non-technical employee describes the tool they want in plain English, and within seconds they receive a fully provisioned, multi-tenant web application, protected by single sign-on (SSO) and running on AWS. No Git, no terminals, and no DevOps knowledge required. The person who needs the tool is the person who ships it. Because every app inherits the same platform, each one can opt into a governed AI capability (chat, summarize, classify) backed by Amazon Bedrock. This occurs without its author ever touching a model endpoint or an API key.
In this post, we show how PDI Technologies built PDI Brew around an agentic provisioning pattern. A planning agent captures user intent as a structured manifest using a skill inside an AI assistant (for example, Claude, ChatGPT, or Claude Code) or as an Amazon Bedrock model invocation inside an AWS trust boundary. A provisioning agent running on AWS Lambda then decomposes that manifest, classifying the workload, selecting tools, and orchestrating the creation of every downstream AWS resource in one request. We then show how the same platform exposes in-app AI as a governed, least-privilege gateway to Amazon Bedrock. We describe the architecture, the security model, long-running provisioning steps inside Lambda, the AI guardrail-and-budget design, and the cost profile of running this system at scale.
Prerequisites
To understand this architecture, familiarity with the following AWS services is helpful: AWS Lambda, Amazon API Gateway, Amazon DynamoDB, Amazon Simple Storage Service (Amazon S3), Amazon CloudFront, and Amazon Bedrock. Experience with Microsoft Entra ID (formerly Azure AD) and MSAL.js is useful for the authentication sections. Verify you have the AWS Command Line Interface (AWS CLI) installed and configured with credentials that have sufficient permissions to create AWS Identity and Access Management (IAM) roles and policies if you plan to implement a similar pattern in your own environment.
Traditional internal-tool delivery couples a straightforward business need to a full software delivery lifecycle. Even a single-page calculator inherits the cost of a repository, a build pipeline, an authentication integration, a hosting decision, a TLS certificate, DNS, logging, and ongoing maintenance. The result is a permanent queue of small tools that are always deprioritized behind revenue-generating features.
We wanted a system with four properties:
- Intent in, application out. The requester describes the tool. The platform provisions it. No handoff to engineering.
- Secure and governed by default. Every app inherits enterprise SSO, scoped IAM, HTTPS, and centralized observability. There is no “insecure” path.
- Serverless and scale-to-zero. Hundreds of small apps must cost almost nothing when idle, with no shared servers to patch or capacity to plan.
- AI without a free-for-all. Apps can use generative AI, but only through a controlled path with guardrails, quotas, and a full audit trail. Never by embedding their own model keys.
Solution overview
“Agentic” does not need to mean “a large language model in the request path for every decision.” We define an agent as a system that takes a goal, decomposes it, selects tools, and acts toward that goal. PDI Brew separates the two halves of that definition into two agents with very different trust profiles.
The planning agent captures intent. It interviews the user, helps them refine what they want, generates the application front end, and critically emits a structured deploy manifest: a JSON description of the user’s intent (app name, type, data schema, and access-control settings). The planning logic is packaged as the Vibe App Builder skill, which runs inside whatever AI assistant the employee already uses. Running the planner in the assistant gives users a rich conversational experience in a tool they already have open and keeps the surface area on the AWS side small.
The provisioning agent is an AWS Lambda function. It receives the manifest and acts as a deterministic, auditable, tool-using orchestrator. It validates the request, classifies the workload, and chooses a provisioning path. It then calls AWS and Microsoft Graph APIs as tools, handles long-running steps through asynchronous self-invocation, and returns a live URL. Putting the provisioning logic in Lambda rather than in a chat session is deliberate: provisioning is exactly the kind of workload where every decision must be logged, reproducible, and free of hallucination.
A pluggable planner: bring your own assistant
Intent can come from anywhere, so the planner is designed as a pluggable layer with two interchangeable paths. A single environment variable (PLANNER_MODE) selects which one is active, and both paths emit the identical deploy manifest, so everything downstream is unchanged.
Path A — the Vibe Skill in any AI assistant. The Vibe App Builder skill (hereafter, the Vibe Skill) packages the planning logic and runs inside whatever AI assistant the employee already uses. The assistant interviews the user, generates the front end, and produces the manifest. The planner runs outside AWS, which gives users a rich conversational experience in a tool they already have open.
Path B — Amazon Bedrock inside the AWS trust boundary. For channels like Teams, a web form, or an IDE, the request is sent to Amazon Bedrock. A Bedrock model invocation (InvokeModel) acts as the planner: it classifies the workload, emits the same manifest, and can validate or repair the data schema before provisioning. This path operates entirely inside AWS, so every decision is captured in AWS CloudTrail and tied to a model-invocation ID, and no intent data leaves the AWS boundary. This is important for teams with strict data-residency requirements.
One contract, one provisioning agent. Because both planners emit the same manifest JSON, the provisioning agent on Lambda and the entire per-app runtime are identical regardless of path. Adding the Bedrock path was an additive change, not a rewrite. And PLANNER_MODE can be pinned per organization, workspace, or user, so one enterprise can require the Bedrock path while another keeps the in-assistant experience. It also leaves a clean forward path: the Bedrock invocation can later be replaced with a richer managed agent runtime without touching Path A or the provisioning agent.
Architecture
The following diagram illustrates the end-to-end architecture. It has three layers: a pluggable intent and planning layer, a unified agentic provisioning runtime, and a per-app runtime, supported by shared edge, identity, and observability services.
The following walkthrough traces a request through each layer:
- In the intent and planning layer , an employee describes the tool in plain English. Depending on
PLANNER_MODE, the planner is either the Vibe Skill running in their assistant (Path A) or an Amazon Bedrock invocation behind a channel like Slack or Teams (Path B). Either way, the planner emits the same deploy manifest as JSON. - The manifest is sent over HTTPS to
POST /deployon Amazon API Gateway, authenticated with an Entra ID bearer token (MSAL.js). Because both planner paths converge on the same endpoint and contract, everything from here on is identical. - API Gateway invokes the Deploy Lambda (the provisioning agent). It validates the Entra JWT (tenant and expiry), enforces that an access-control mode is present, and atomically checks slug ownership in the app registry table.
- The agent classifies the workload (static (a calculator or chart), full-stack (needs data persistence) and selects the matching provisioning path.
- For a static app , the agent wraps the HTML in an Entra authentication shell, uploads it to Amazon S3, invalidates the Amazon CloudFront cache, and registers the app in Amazon DynamoDB.
- For a full-stack app , the agent additionally provisions a per-app DynamoDB table, a per-app AWS Lambda function with a scoped AWS IAM role, and a per-app API Gateway. It then injects the new API URL into the front end before wrapping and uploading it.
- Long-running steps (creating a Microsoft 365 group) are handled by asynchronous self-invocation : the agent invokes a second copy of itself as a background task so the user’s request returns quickly.
- End users reach the live app over HTTPS through CloudFront, where a CloudFront Function routes
<slug>.domainto the correct app in S3. Every app sits behind Entra single sign-on and is observable in Amazon CloudWatch.
How the provisioning agent works
The provisioning agent performs two core functions: classifying workloads and orchestrating long-running provisioning steps.
The Deploy Lambda treats the AWS SDK for JavaScript v3 and the Microsoft Graph API as its tool belt. Based on the manifest, it decides which tools to call and in what order. A static app touches only S3, CloudFront, and the DynamoDB registry. A full-stack app additionally drives DynamoDB and API Gateway, and, for capability-bearing apps, Lambda and IAM. Access control reaches into Microsoft Graph to create and manage the app’s M365 group. The classification is deterministic and fully logged: the same manifest always produces the same plan.
Long-running work inside Lambda
Some provisioning steps take longer than a user wants to wait on a synchronous request, notably directory propagation after creating an M365 group. Rather than hold the request open, the agent uses asynchronous self-invocation: it calls lambda:InvokeFunction on itself with an Event invocation type, returns the live URL immediately, and lets the background copy finish the slow work. This is the serverless equivalent of an agent’s “background task” pattern, kept comfortably inside the Lambda execution envelope.
Per-app runtime: a dual-tier compute model
Not every app needs its own compute. Most full-stack apps are straightforward create, read, update, and delete (CRUD) operations over their own DynamoDB table, so they run on a shared, platform-managed CRUD Lambda fronted by a weighted alias with provisioned concurrency. This provides one warm, audited code path serving many apps, with an automatic canary-rollback guard. An app graduates to its own per-app Lambda with a dedicated, scoped IAM role only when its manifest declares a capability from a closed allowlist (for example, sending email, calling a specific external HTTPS domain, or reading from a designated data source). This graduation requires an admin approval step. The approval is backed by static analysis of the submitted code and drift detection on the resulting IAM role. The default path is shared and cheap. The privileged path is per-app, least-privilege, and gated.
Governed in-app AI
Deployed apps increasingly want AI features: summarize a record, classify an intake form, answer a question over the app’s data. The naive path is for each app to embed a model vendor’s SDK and an API key. This scatters credentials, defeats central governance, and makes spend impossible to control. PDI Brew takes the opposite approach: AI is a platform capability reached through one endpoint, not an integration each app owns.
Three controls run on every call, before and after the model. First, a mandatory Amazon Bedrock Guardrail handles personally identifiable information (PII) redaction, content filtering, and prompt-injection defense on every invocation. The app cannot turn this off. Second, a 12-counter atomic budget enforces spend limits. Before any Bedrock call, a single DynamoDB TransactWriteItems reserves spend across four scopes (global, app, user, and app-user), each over three windows (daily, weekly, monthly). A breach in any of the twelve counters short-circuits the request with 429 Too Many Requests and a structured body naming the limit that fired. This makes runaway cost, whether from a bug, a loop, or abuse, a bounded, observable event rather than a surprise invoice. App owners can be granted higher app-scoped budgets by an admin. The global and per-user ceilings cannot be widened by owners. Third, a two-tier terminate switch allows an admin disable always beats an owner enable, and a single platform-wide flag can disable AI everywhere, so the platform team retains a hard stop-switch independent of any app.
Every call is audited (UPN, app, model, token counts, estimated cost, and guardrail outcome), so spend and usage are attributable to an app and a user, end to end.
Security and least privilege
Because the agent provisions infrastructure, its security model is the most important part of the design. Several principles govern it.
Defense in depth at the IAM layer. The provisioning agent holds the broad permissions it needs to create resources. But the per-app Lambda functions it creates inherit a separate, scoped role that can reach only DynamoDB tables prefixed with pdi-brew-{env}-app-. The agent never grants a deployed app more privilege than that app needs, so a bug in one tenant’s code cannot read another tenant’s data.
Identity on every path. There is no unauthenticated route to a deployed app. The deploy API validates an Entra JWT before provisioning, and every generated app is wrapped in an MSAL.js authentication shell that checks Microsoft 365 group membership through Microsoft Graph on each visit.
Note on identity provider: this architecture uses Microsoft Entra ID with MSAL.js for authentication rather than Amazon Cognito. This is a deliberate design choice driven by PDI Technologies’ existing enterprise SSO requirements. PDI’s workforce already authenticates through Microsoft Entra ID. Integrating directly with their established identity provider reduced friction for end users and aligned with existing security policies. For organizations without an existing identity provider preference,Amazon Cognito offers an alternative that integrates natively with AWS services and supports similar federated sign-in flows.
AI is least-privilege by construction. The AI Lambda role grants bedrock:InvokeModel and InvokeModelWithResponseStream scoped by resource to the allow-listed model ARNs (not *), and nothing else in the account can call Bedrock. Lambda functions have no Bedrock permission and reach AI only over HTTPS through the gateway, where guardrails and budgets apply.
Additional controls reinforce the security posture across every deployed app. Amazon S3 public access is fully blocked. Only CloudFront (through Origin Access Control) can read objects. CloudFront enforces redirect-to-HTTPS with HSTS and a strict Content-Security-Policy. API Gateway rate-limits the deploy endpoint (50 requests per second sustained, 100 burst). Amazon S3 versioning and DynamoDB point-in-time recovery protect against data loss, and prevent-destroy lifecycle rules guard the registry and bucket.
Serverless-native multi-tenancy
Every deployed app is a tenant, and the architecture gives each tenant its own subdomain (routed by a CloudFront Function), its own DynamoDB table where applicable, and a Lambda role scoped to its own data. There is no shared compute and no noisy-neighbor risk, and because every component is serverless, each tenant scales to zero independently when idle. Adding the hundredth app costs essentially nothing until someone uses it.
Observability
The provisioning agent and every per-app Lambda function write structured JSON logs to Amazon CloudWatch. Custom metrics in the PDIBrew namespace track deploys, app views, authentication failures, group and list creation, and provisioning latency. An admin panel queries Amazon CloudWatch Logs Insights for per-app activity, and a Grafana dashboard visualizes platform-wide usage. Provisioning calls appear in AWS CloudTrail, and when the Bedrock planner (Path B) is active, each planning decision is also logged as an InvokeModel call in CloudTrail, giving an end-to-end audit trail from intent to provisioned resource.
Cost
Every service in the stack is pay-per-use with no fixed cost, so the platform’s price tracks actual usage rather than the number of apps deployed.
| Service | You pay for |
|---|---|
| Amazon S3 | Storage ($0.023/GB) + requests |
| Amazon CloudFront | Data transfer + requests |
| AWS Lambda (deploy + per-app) | Invocations + duration |
| Amazon DynamoDB | On-demand read/write request units |
| Amazon API Gateway | $3.50 per million requests |
| Amazon Bedrock (Path B planner) | Per-token InvokeModel pricing, per deploy |
In practice, a team of 20 running about 10 apps costs roughly $5–$15 per month.
Results
Since its launch, PDI Brew has scaled to serve hundreds of applications across the organization, representing significant cost savings compared to traditional subscription tooling. What makes this remarkable is that deployment is no longer confined to engineering. Non-developers now independently author and deploy applications, tracked through Entra UPN tagging, demonstrating how AI-powered tooling has broadened authorship well beyond traditional development teams. In PDI Technologies’ experience, what previously took weeks (cycling through tickets, infrastructure provisioning, and build processes) dropped to minutes, as measured by deploy Lambda timestamps. The cost economics are equally striking. The platform has achieved substantial cost efficiency, with per-app costs at idle significantly lower than traditional subscription-based tools’.
Operationally, the platform has achieved true self-sufficiency. Deployers manage and roll back their own applications independently through S3 version-controlled hosting, with no dependency on other teams for ongoing maintenance. App longevity is tracked through AppViews over time, allowing PDI to distinguish durable business tools from one-off experiments and measure lasting organizational value.
The platform has also unlocked use cases that were previously impossible with subscription-based tools. Because PDI Brew runs entirely within PDI’s own cloud and identity boundary, it can serve regulated and sensitive data workloads where data cannot leave the organization’s perimeter. AI is delivered as a built-in platform capability: Amazon Nova models available in Amazon Bedrock are exposed with shared guardrails and per-app token limits, eliminating the per-project model procurement overhead that typically slows AI adoption across enterprises.
Conclusion
PDI Brew shows that an agentic provisioning pattern maps cleanly onto serverless AWS primitives. A pluggable planner (the Vibe Skill in any assistant, or Amazon Bedrock inside the AWS trust boundary for channels like Slack and Teams) turns plain-English intent into a structured manifest. A provisioning agent on AWS Lambda then turns that manifest into a fully provisioned, authenticated, multi-tenant application. The stack uses AWS Lambda, Amazon API Gateway, Amazon DynamoDB, Amazon S3, and Amazon CloudFront as the building blocks of a platform-as-a-product. The same properties that make Lambda a great API runtime (stateless, scaled-to-zero, IAM-scoped, and observable) make it a great runtime for provisioning agents, where determinism and auditability matter most.
Many organizations sitting on a backlog of internal tools can reproduce these patterns: decouple the planner from the provisioning agent behind a single manifest contract, so intent can arrive from any assistant or channel. Keep provisioning deterministic and least-privileged, and let serverless handle multi-tenancy and scale-to-zero. To get started on building agents on serverless AWS, see the AWS Prescriptive Guidance on agentic AI architectures, AWS Samples, Amazon Bedrock Developer Guide, and the AWS AI/ML Blogs.
About the authors
Ramesh Kadali
Ramesh is a Senior Director of Platform Engineering at PDI Technologies, where he leads internal developer platforms spanning cloud infrastructure, DevOps automation, and AI systems architecture. His current focus is driving PDI Platform Engineering towards — architecting multi-provider AI gateway infrastructure, building autonomous agentic pipelines for platform operations, and embedding AI-driven tooling across PDI’s internal developer ecosystem.
Mahesh Lagishetty
Mahesh is a Senior Vice President of Engineering at PDI Technologies, where he owns end-to-end technology execution across platform architecture, data ecosystems, DevOps/SRE, and AI-driven innovation. His current focus is PDI’s shift from AI-assisted to agentic engineering — building an agentic SDLC with autonomous remediation pipelines internally, and embedding human-in-the-loop AI agents into PDI’s enterprise products.
Medha Aiyah
Medha is a Solutions Architect at AWS. She graduated from the University of Texas at Dallas with an MS in Computer Science, with a focus on AI/ML. She supports ISV customers in a wide variety of industries, by empowering customers to use AWS optimally to achieve their business goals. She is especially interested in guiding customers on ways to implement AI/ML solutions and use generative AI. Outside of work, Medha enjoys hiking, traveling, and dancing.