Databricks 将 AI 编码支出降低 70%
英文标题:🔶 Databricks drove down AI coding spend 70%
Databricks 表示,Agentic Coding 已显著改善其各项研发效率指标,部分团队的产出甚至提升一个数量级,但大规模部署也带来了呈指数增长的成本压力。该公司总结了包括采用更高性价比模型、动态路由、支出可视化与预算门槛、减少 Token 开销在内的四类成本优化手段。其内部结果显示,AI Gateway Smart Router 可在大致保持最昂贵模型质量的同时,将平均任务成本降低逾 30%;通过调优 Harness 与缓存设置,生成 Token 数及相关成本接近减半。文章认为,企业不应仅依赖硬性预算限制,而应通过模型灵活性、智能路由和渐进式治理,在扩大 AI 工具使用范围的同时控制人均成本。
 31.8 KB
 52.1 KB
 75.6 KB
 37.1 KB
 185.6 KB
 19.6 KB
 914 B
 1.3 KB
 1.8 KB
 72.3 KB
中文
AI 编码工具能带来巨大价值:在 Databricks,Agentic Coding 已可量化地改善我们跟踪的每一项研发效率指标,并且在部分团队中,将产出提升了一个数量级。但几乎每一家大规模部署 AI 工具的公司都撞上了同一堵墙:成本呈指数级增长。这条曲线不可持续——若不加以控制,成本最终将超过营收。支出爆发让企业陷入矛盾:一方面,它们希望尽可能推进 AI 转型,将强大的工具交到员工手中;另一方面,又必须面对整体成本结构可能削弱、甚至逆转 AI 所带来效率收益的问题。
幸运的是,最早的一批大规模采用者已逐步形成一套解决这一难题的方法,实现“双重目标”:(a)以尽可能低的摩擦广泛提供 AI 工具访问权限;(b)将整体成本控制在大致固定的人均预算范围内。本文基于 Databricks 的经验,以及我们与 Stripe、Coinbase、Uber 和 Ramp 等多家数字原生公司的交流,概述了已被验证的成本管理技术。下表汇总了当前技术及其对应的节省幅度;这些数字具有方向性,基于对开发团队的非正式调研:
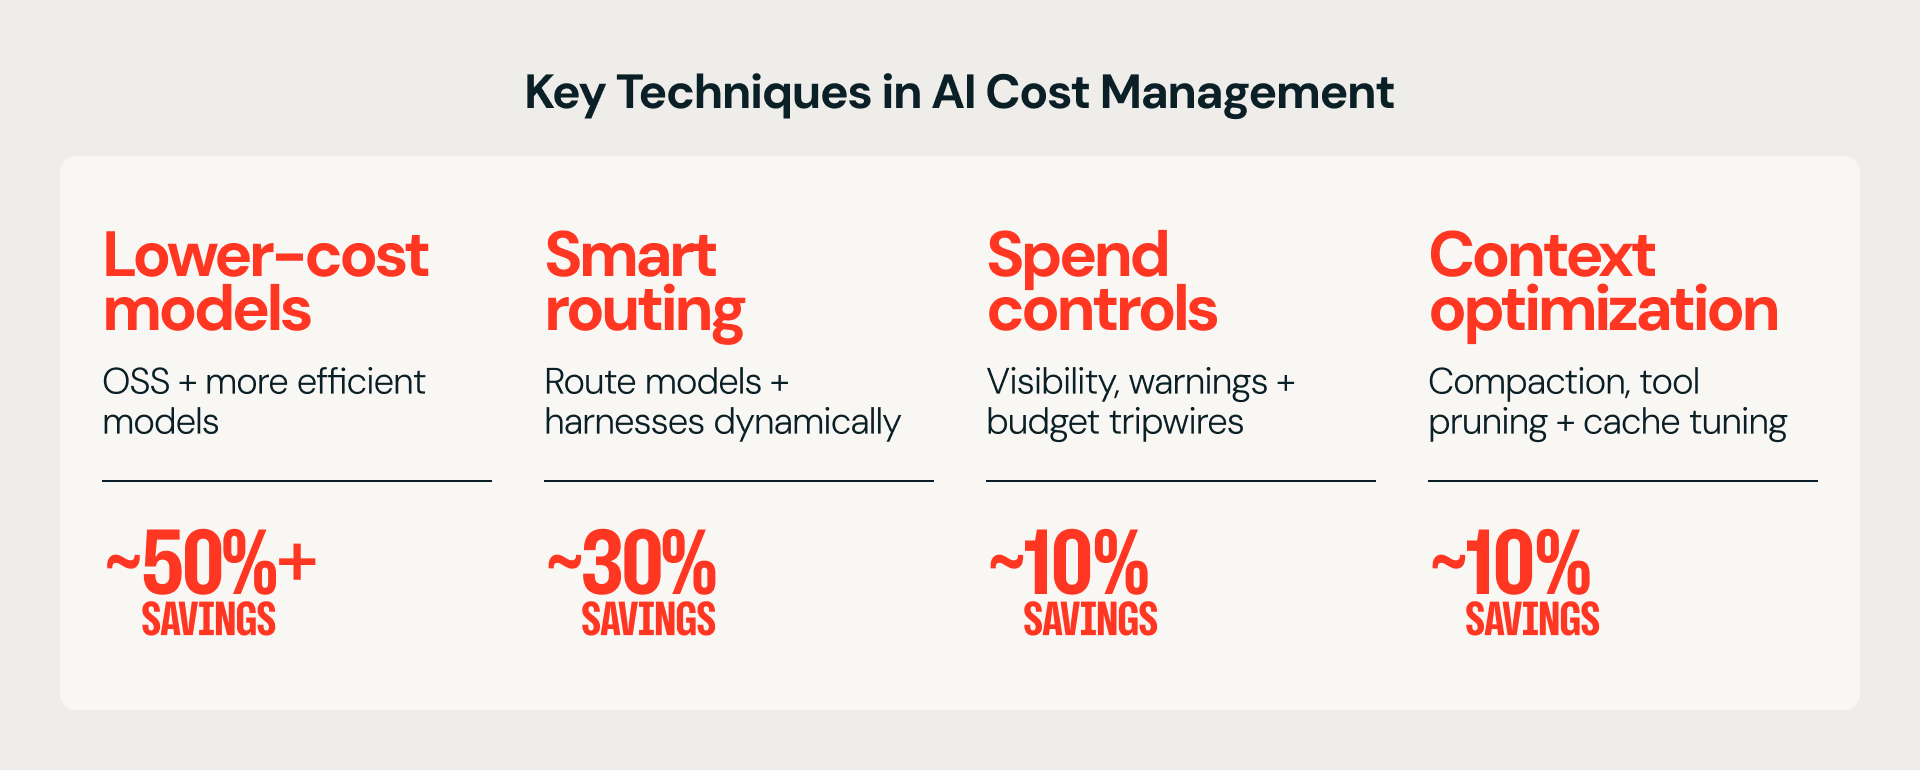
其中一些技术可以利用许多公司已经在使用的软件轻松实现。另一些则需要新的基础设施,尤其是那些会改造终端用户客户端或在不同模型之间迁移流量的技术。在 Databricks,我们已将关键基础设施开源或免费提供:终端用户元 Harness(Omnigent)以及 AI Gateway(Unity AI Gateway)。为求完整,本文也会介绍我们交流过的其他公司所使用的软件。
编码模型的“效率前沿”
在编码支出方面,最大的成本杠杆在于:随着新模型发布,将支出迁移至效率更高的模型。这一点值得展开说明,因为看似简单的“更便宜的模型”,实际上掩盖了模型成本与质量之间更微妙的关系。
通常所说的 前沿模型(frontier model),指的是“智能水平最高的模型”;而 前沿实验室(frontier labs) 主要致力于推进智能水平的上限。前沿模型如今能够解决数学或网络安全领域的新颖问题。但当 AI 被大规模部署时,另一种前沿更为重要:效率前沿(efficiency frontier)。效率前沿由在特定智能水平下拥有最佳价格点的一组模型定义。大多数日常编码工作不需要数学证明或新颖的安全洞察,因此,从整体上看,关键在于那些能够达到典型软件工程工作质量门槛的模型成本。这个“效率前沿”的进步速度远快于智能前沿:几乎每周都有新模型发布,其单位价格所提供的智能水平优于此前的模型。
成本杠杆 #1:迁移至开源及低成本模型
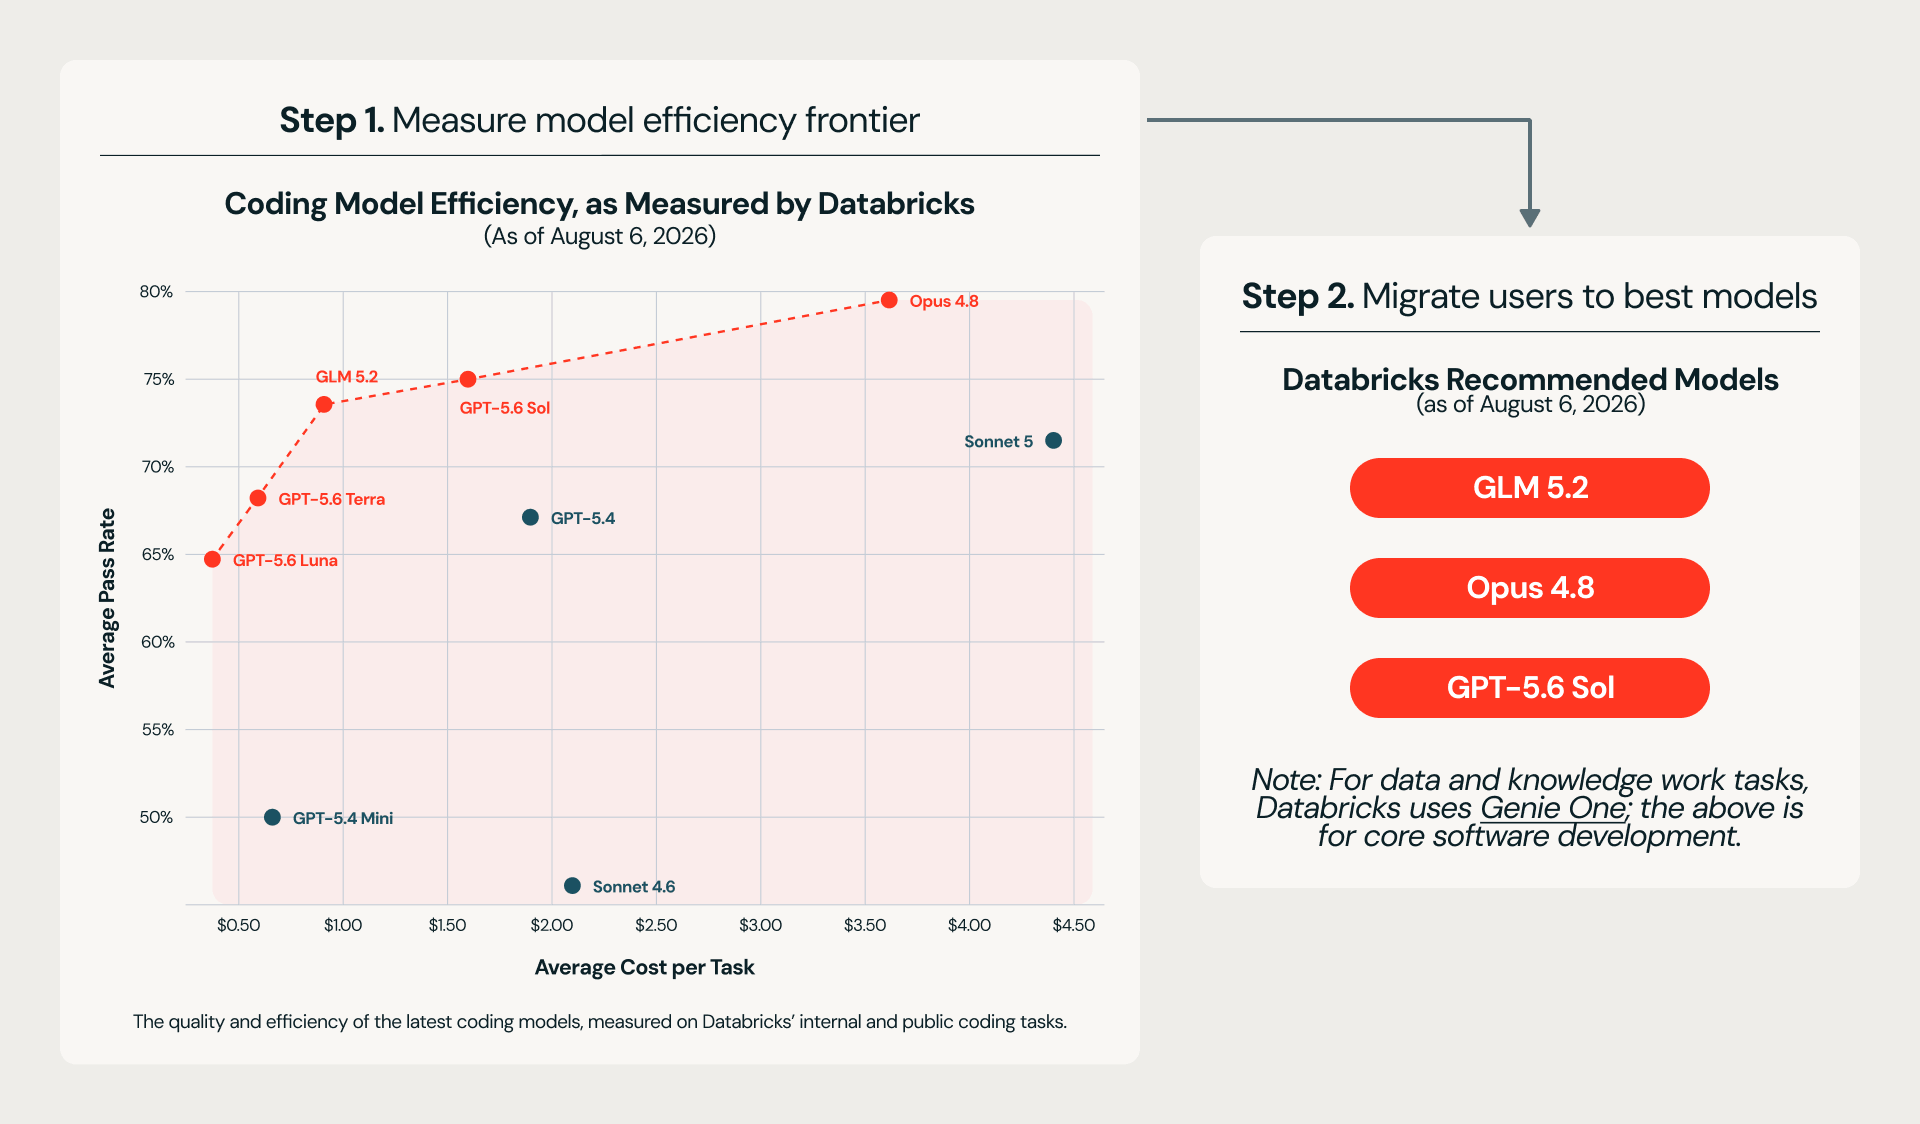
快速采用更新、更高效的模型,能够带来所有技术中最大的成本收益。但要获取这些收益,公司首先需要知道哪些模型确实优于其现有模型。这并不容易,因为公开基准测试并不能很好地反映模型在真实编码任务中的表现。为了评估新模型,许多公司建立了自动化评测体系,并认为这类体系更能代表其内部开发任务的构成。Databricks 最近发布了一个此类基准测试的示例,我们在其中观察到 GLM 模型具备极具竞争力的性价比。这项基准测试促使我们在内部向开发者推出 GLM。新模型往往并未推进效率前沿,评测也经常得出负面结论:Stripe 发现,Opus 4.7 相比 Opus 4.6 并未显著提升质量,但成本更高。因此,他们决定不在内部提供 Opus 4.7。Databricks 在比较 Opus 5.0 与 4.8 时,也观察到了类似的成本倒退。
Harness 与模型灵活性
由于最大的收益来自切换到新模型,采用允许灵活切换模型的终端用户工具,正成为控制成本的关键环节。与某个特定模型最常配套使用的工具被称为 Harness。专有前沿模型越来越多地被共同设计为与特定 Harness 良好配合,因此某些 Harness 对某些模型“表现更好”。如果一家公司希望保持模型独立性,大致有两种方法:
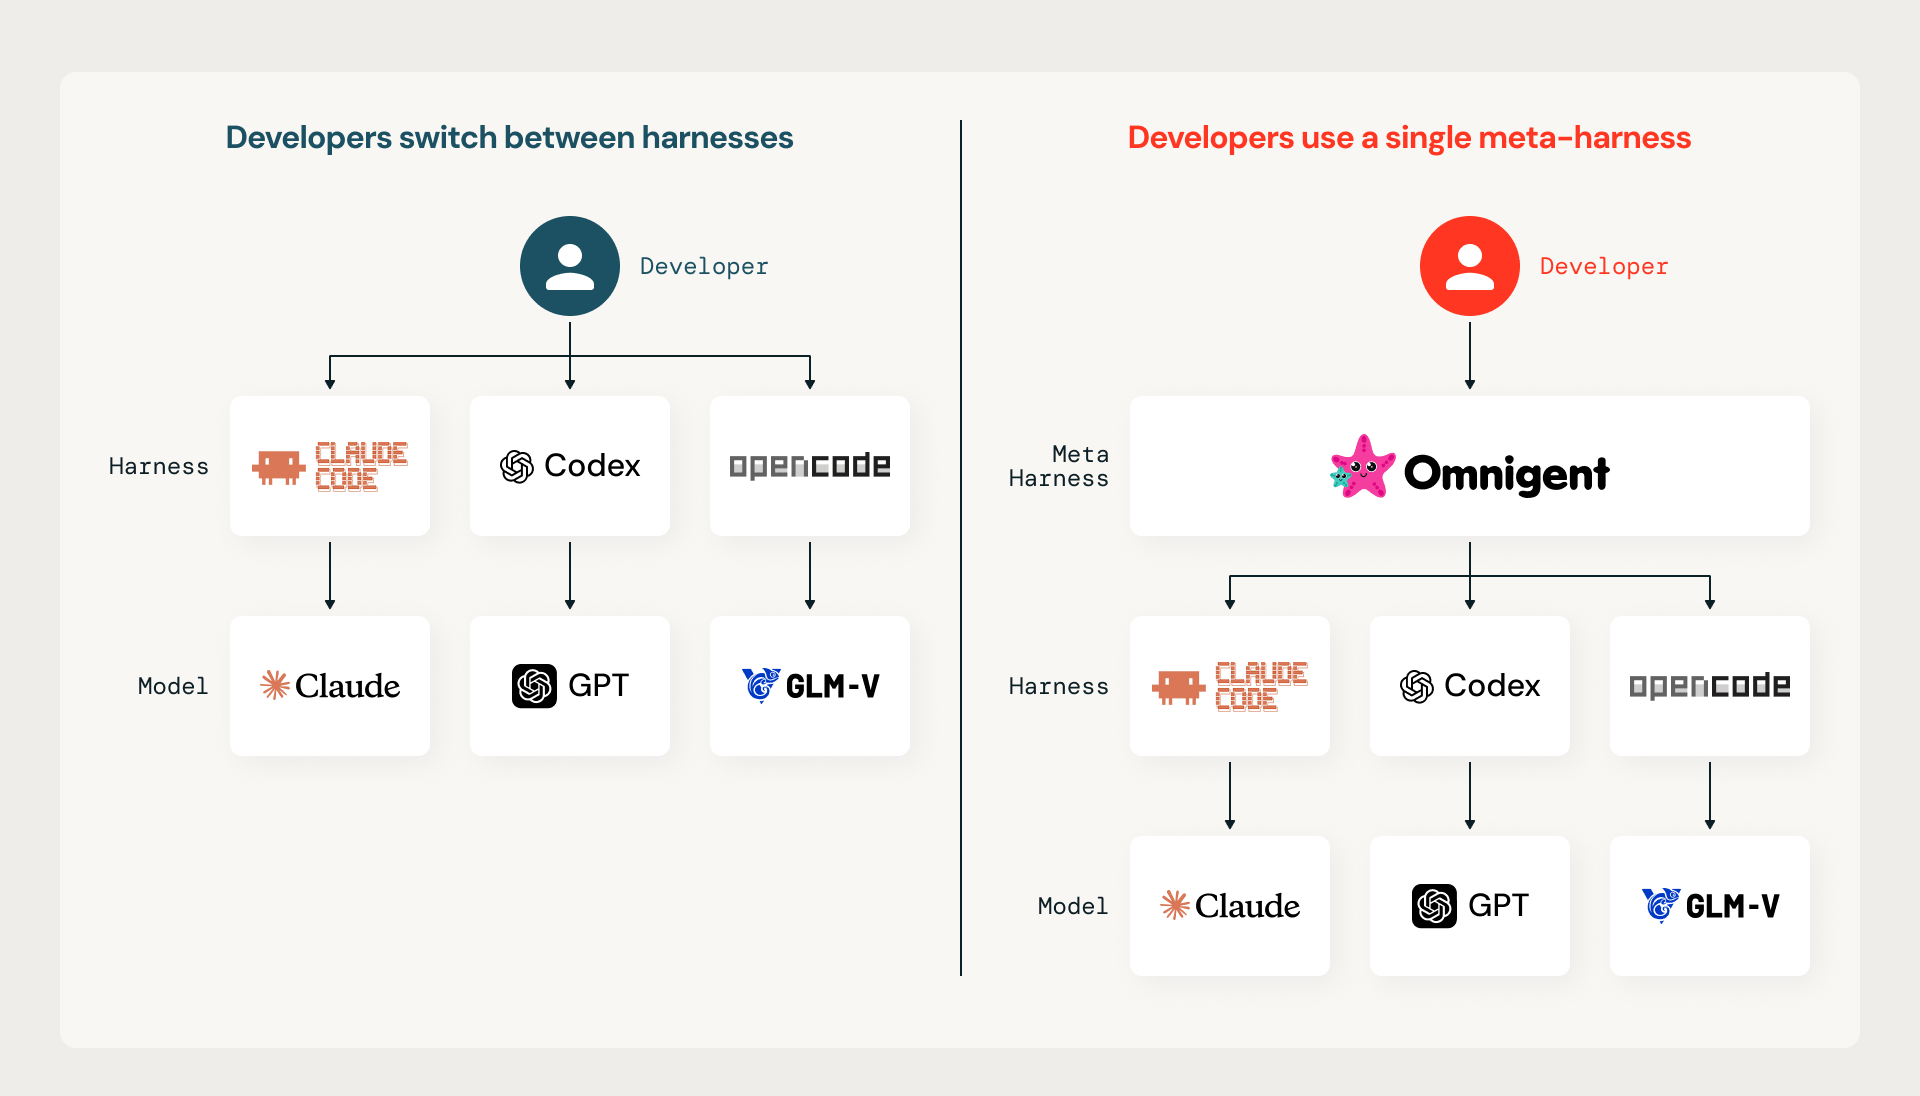
要求用户切换 Harness。 一种方法是为开发者提供一组 Harness(Claude Code、Codex 或 Cursor),随后在公司希望将支出迁移到更低成本模型时,要求他们在不同 Harness 之间切换。这让用户可以在可能的情况下使用自己偏好的 Harness,但缺点是,单个开发者的切换成本可能很高。如果切换成本过高,Harness 本身就会成为对某个模型家族的事实锁定,限制企业将支出转向更具竞争力模型的能力。
使用元 Harness。 一种新兴且日益流行的方法是使用 元 Harness(meta-harness):它向开发者提供统一的用户体验,同时将请求分派给底层 Harness,包括专有和开源 Harness。这种方法既能实现模型/Harness 独立性,也能降低开发者的切换成本。在 Databricks,这也是使用 Omnigent 的开发者的默认模式。我们交流过的一些公司则构建了与自身开发工具链集成的定制内部元 Harness。
成本杠杆 #2:动态请求与任务路由
与其要求用户自行选择适合任务的模型,越来越多的研究表明,自动选择模型和工具可以进一步提升 Agentic Coding 工作流的效率。路由方法大致可分为三类:
- 请求级路由(Request Level Routing): 在客户端(例如编码 Harness)与底层基础模型之间部署一个有状态代理。该代理尝试将每个推理请求路由至能够完成回答的最低成本模型。面向 Agentic 用例的路由还需要考虑服务端缓存,因为对于大上下文工作负载而言,缓存未命中(cold cache hit)的成本非常高。一批新产品已在路由方面展现出早期且令人鼓舞的结果。例如:Cursor Router、OpenRouter 的 AutoRouter、Ramp 的 Router 功能,以及 Databricks 在 Unity AI Gateway 中提供的 Smart Routing 功能。
- 任务级路由(元 Harness): 一个客户端进程会根据任务复杂度,将用户任务分派给不同 Harness。用户任务可能是“将这个组件从 X 重命名为 Y”(简单任务),也可能是“探索可降低延迟的设计考量”(复杂的开放式任务)。调度器通常被称为 元 Harness(Meta Harness),它会判断任务需要何种级别的底层模型,然后将整个端到端任务委派给该模型。Omnigent 就是支持这种模式的元 Harness 示例。
- 升级/委派模式(Escalation/Delegation Patterns): 单个 Harness 搭配两个模型:一个昂贵的高智能模型,以及一个低成本工作模型。在某些方法中,例如 Claude 的 Advisor Tool,低成本模型主导流程,并在判断任务需要更强能力时进行_升级(escalate)_。也存在相反模式:在 Cognition 的 Devin Fusion 中,高成本模型负责主循环,并选择性地将工作外包给更便宜的模型。
Databricks 的内部结果表明,我们的 AI Gateway Smart Router 能够将平均任务成本稳定降低 30% 以上,同时质量大致与候选模型集中最昂贵的模型相当。我们交流过的其他公司也观察到了类似结果。

成本杠杆 #3:为开发者提供可见性、预警门槛与预算
或许令人意外的是,本文并没有以“给用户设定每月预算,就这样结束”作为开头和结尾。硬预算(Hard budgets),即在达到特定支出阈值时完全切断使用权限,在我们交流过的每家公司中通常都只被作为最后手段。硬性 Token 预算对 AI 支出管理效果不佳,原因有二:第一,如果开发者达到预算上限,切断其继续使用 AI 工具的权限会严重损害生产力。公司和员工实际上都不希望看到这一结果。第二,至少有一部分“高支出”用户,实际上正是借助 AI 实现了巨大效率提升、产出极高的用户。限制这些用户无异于适得其反。
与其设置硬性的用户支出上限,大多数公司正在采用一种更细致、渐进的方法:重点是向终端用户提供可见性,并随着支出增加逐步提高使用摩擦。
- 可见性: 我们交流过的每家公司都具备某种机制,可就用户当前支出提供近乎即时的反馈;许多公司还提供具体建议或洞察,帮助用户通过使用成本更低的模型来减少支出。用户能够查看自己在所有工具上的支出非常重要,因为他们可能希望影响自己对能带来最高 ROI 的工具的选择。
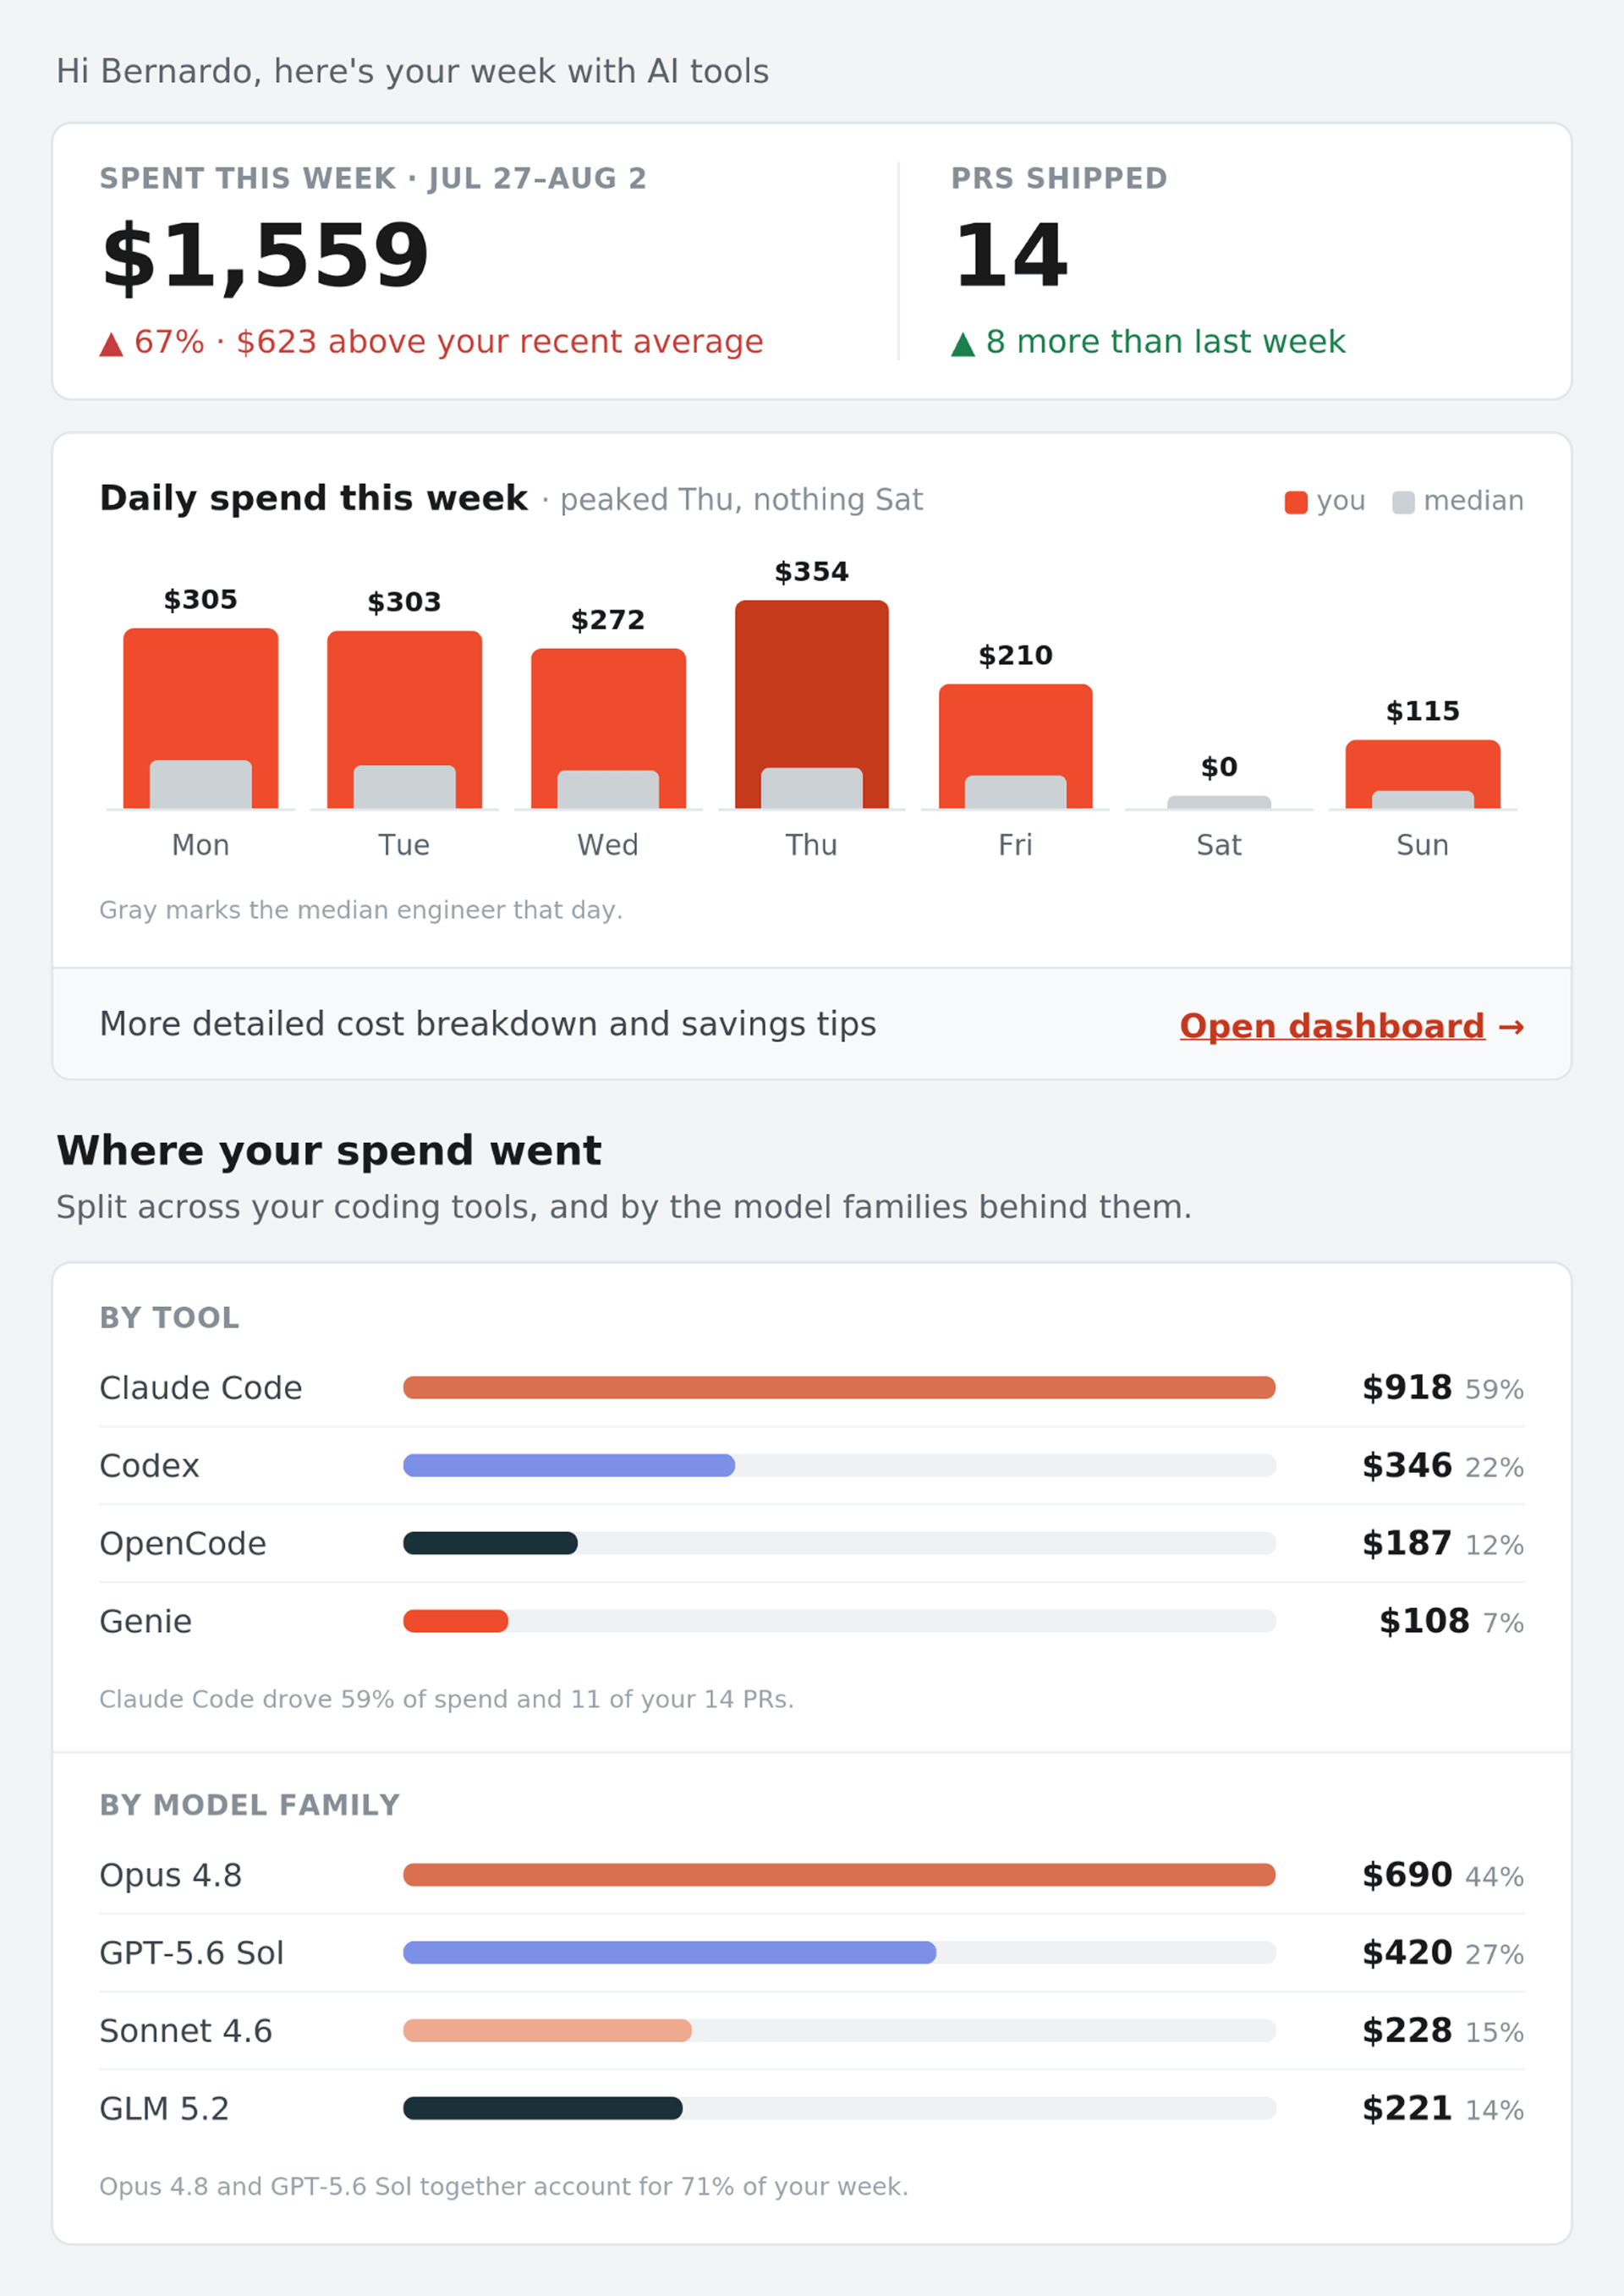
Databricks 的开发者仪表盘,展示当前活跃支出
- 支出门槛(Spend Gates): 当支出达到递增的不同水平时,可以要求开发者采取行动或寻求批准。最简单的支出门槛可由用户_自行解除(self-cleared)_,其作用是警告支出速率已超过某一阈值。在 Databricks,我们发现可自行解除的门槛是防止意外或无意支出的有效机制。还可以引入需要明确预算批准的后续门槛,通常需通过管理链路审批。
- 降档(Downshifting): 如果开发者触发支出门槛,可以将其降档至成本更低的模型,而非完全中止其 Token 访问权限。由于最低成本模型比前沿智能模型便宜得多,这项技术允许开发者继续完成工作,而不会持续产生巨额支出。
- 暂停(Suspension): 在极端情况下,大多数系统仍保留完全暂停用户所有 Token 访问权限的能力。如上所述,这通常只是临时措施,也是开启一场关于如何高效利用 AI 的对话的起点。
成本杠杆 #4:降低 Token 开销
当用户向 AI 编码 Agent 输入一个相对简单的请求时,例如“请调查并修复这个 Bug”,该 Agent 随后会收集大量相关上下文、调用大量工具、搜索代码库,并整合公司提供的技能或系统信息。到成本高昂的 LLM 推理真正发生时,用户最初的表述只占输入 AI 系统数据中微不足道的一部分,这意味着成本主要由用户未明确提供的上下文主导。减少上下文膨胀的技术仍处于早期阶段,但已有一些颇具潜力的方法正在被探索,例如:
- 强制更频繁地对活动上下文进行压缩(compaction)。
- 使用“话更少”的 Harness,即 Token 效率更高的 Harness;或者调优现有 Harness,以减少其生成的 Token 开销。
- 审计常用工具并降低其冗长度。
- 鼓励开发者将任务拆分为更小的独立工作单元,从而缩小上下文范围。
当上下文变大时,提示词**缓存(caching)**也会对整体性能产生重要影响。专有和开源 LLM 都提供了启用提示词缓存、以及调整缓存存储时长的设置。写入缓存需要成本,但读取缓存能够大幅降低单次推理成本。这一权衡取决于公司的具体工作负载,因此,手动调优默认缓存设置以提高整体缓存命中率,能够显著改善总体成本。
在 Databricks,仅通过对 Harness 和缓存设置进行相对简单的调优,就在开发者未观察到质量下降的情况下,使生成 Token 数量及相关成本降低了近 50%。我们仍在继续探索这一领域的技术,并认为仍有可能实现更多有意义的优化。
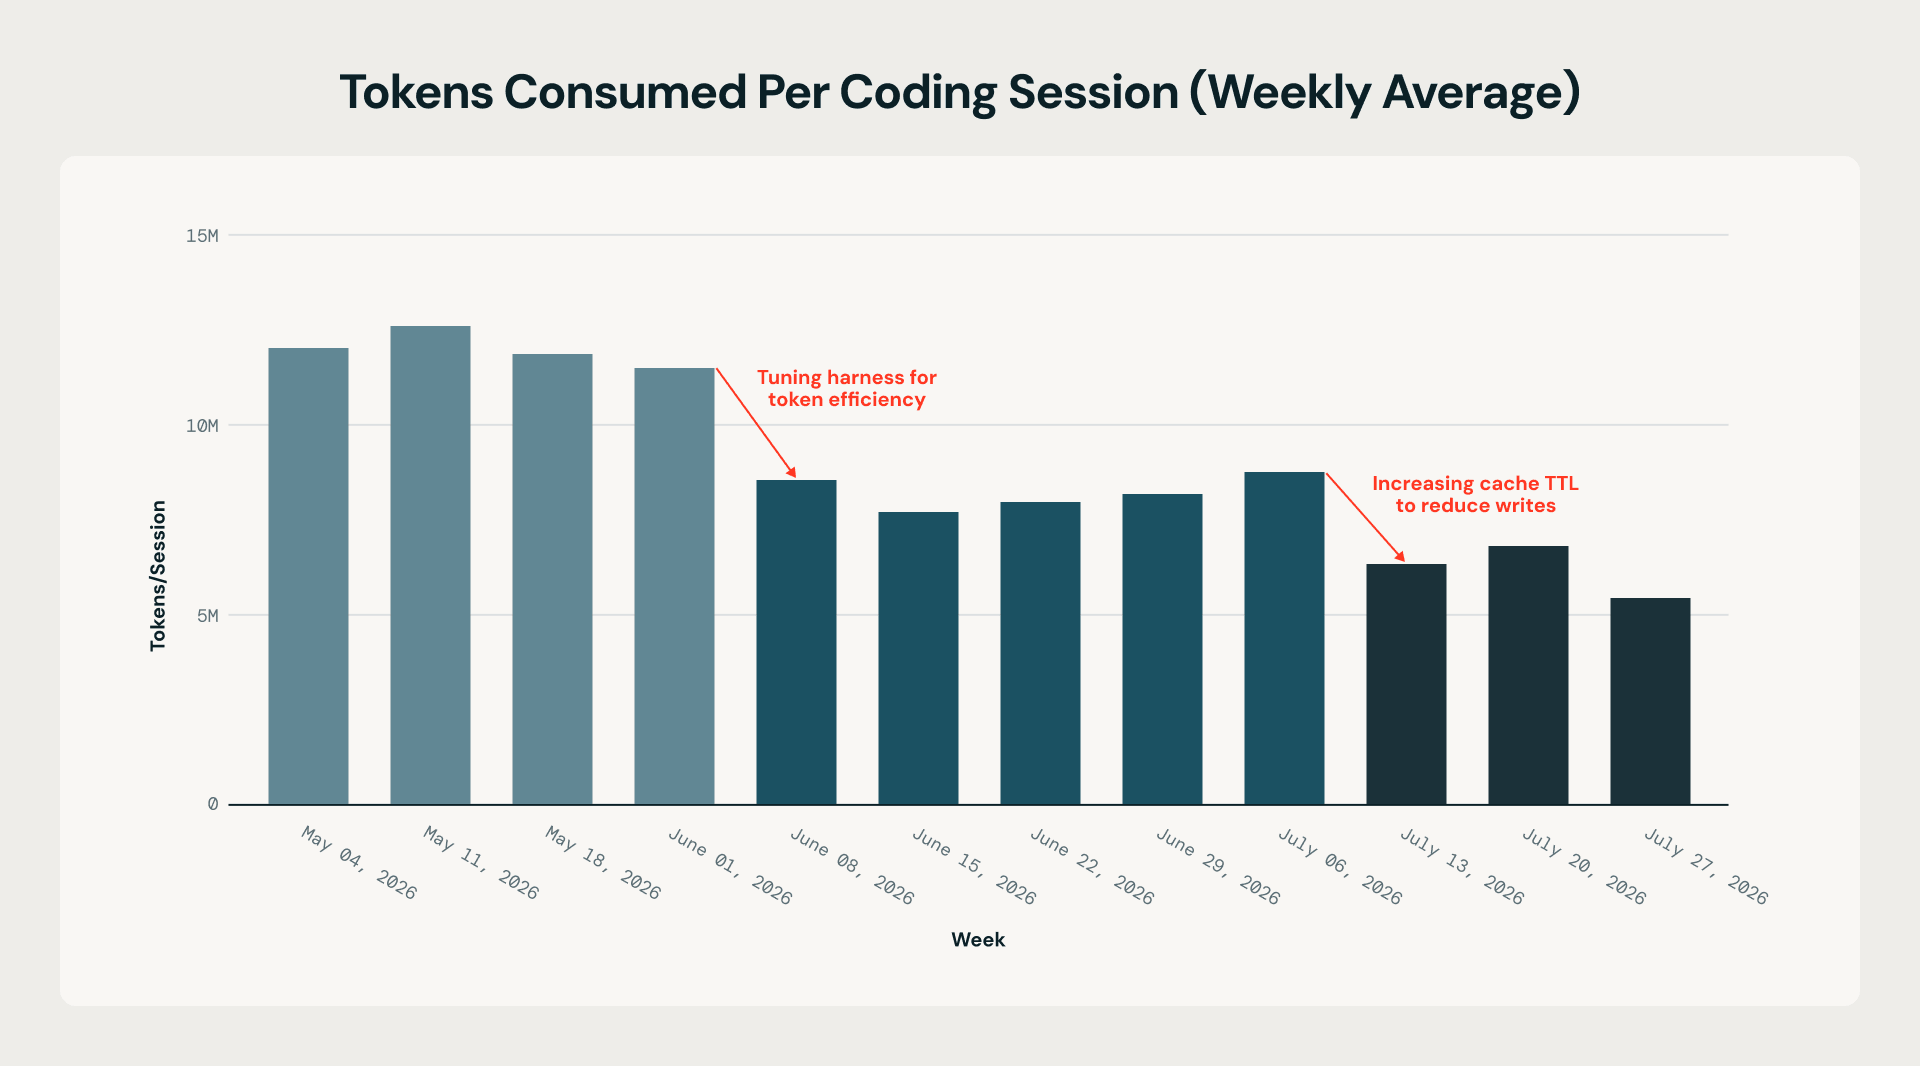
通过 e 大幅减少每次会话的 Token 数量
English / 原文
AI coding tools deliver immense value: at Databricks, agentic coding has measurably improved every velocity metric we track and, in some teams, driven an order-of-magnitude gains in output. But nearly every company deploying AI tools at scale has hit the same wall: exponentially growing costs. That curve is unsustainable - left unchecked it will eventually overtake revenue. The spend explosion has left enterprises in a paradoxical situation: on the one hand, desiring to maximally push AI transformation and put powerful tools in the hands of employees, and on the other hand, having to reconcile with an aggregate cost profile that threatens to undermine or even reverse the very efficiency gains AI provides.
Fortunately, several of the earliest large-scale adopters have converged on a set of approaches that solve this puzzle, achieving a “dual mandate”: (a) providing broad access to AI tooling, with minimal friction, and (b) keeping aggregate costs inside of a roughly fixed envelope per user. This post outlines proven cost management techniques, based on our experience at Databricks and conversations with several other digital-native companies, including Stripe, Coinbase, Uber, and Ramp. The table below summarizes current techniques and associated savings; the numbers are directional, based on an informal survey of development teams:
Some of these techniques can be easily implemented with software many companies already use. Others require new infrastructure, particularly techniques that modify end-user clients or shift traffic across models. At Databricks, we’ve open sourced or made freely available our key infrastructure components: an end user meta-harness (Omnigent) and our AI Gateway (Unity AI Gateway). For completeness, this post also covers software used by other companies we spoke with.
The “Efficiency Frontier” for Coding Models
The single greatest cost lever in moving coding spend to more efficient models as they are released. This point bears some discussion, as the simple explanation of "cheaper models” in fact hides a nuanced relationship between model cost and quality.
Colloquially, the term frontier model means “the highest intelligence model,” and frontier labs largely focus on advancing peak intelligence. Frontier models can now solve novel problems in math or cybersecurity. But when AI is deployed at scale, a different type of frontier matters more: the efficiency frontier. The efficiency frontier is defined by the set of models that have the best price point for a given level of intelligence. Most day-to-day coding doesn't require mathematical proofs or novel security insights, so what matters in aggregate is the cost of models that meet the quality bar for typical software engineering work. This "efficiency frontier” is advancing far faster than the intelligence frontier, with new models being released almost weekly that present better intelligence-per-unit-price than prior models.
Cost Lever #1: Moving to open source and lower cost models
Rapidly adopting newer, more efficient models delivers the largest cost wins of any technique. But to capture those gains, a company first needs to know which models actually beat its incumbents. This can be difficult because public benchmarks do a poor job of indicating real-world performance on coding tasks. To size up new models, many companies have built automated evaluations that they believe are more representative of their internal development mix. Databricks recently published an example of such a benchmark, in which we observed highly competitive price/performance for GLM models. That benchmark led us to roll GLM out to developers internally. Often, new models do not advance the efficiency frontier,and evaluations frequently produce negative results: Stripe found that Opus 4.7 did not meaningfully improve quality over Opus 4.6, while increasing cost. They therefore declined to make Opus 4.7 available internally. Databricks saw similar cost regressions when comparing Opus 5.0 to 4.8.
Harness and Model Flexibility
Since the biggest wins come from switching to new models, adopting end user tooling that allows for model flexibility is becoming a critical component of keeping costs down. The tool most commonly used in concern with a particular model is called harness. Proprietary frontier models are increasingly co-designed to work well with specific harnesses, meaning certain harnesses “work better” with certain models. If a company wants to preserve model independence there are roughly two approaches:
Ask users to switch harnesses. One approach is to provide developers with a set of harnesses (Claude Code, Codex, or Cursor) and then ask them to switch between harnesses when a company wants to migrate spend to lower cost models. This lets users work in their preferred harness when possible, but the downside of this approach is that switching costs for an individual developer can be high. If switching costs become too high, the harness itself becomes a de facto lock-in to a model family, limiting the ability to move spend to more competitive models.
Use a meta-harness. A new and increasingly popular approach is to use a meta-harness that surfaces a common user experience to developers while dispatching requests to underlying harnesses (both proprietary and open source). This approach allows both model/harness independence while also reducing developer switching costs. At Databricks, this is the default mode for developers who leverage Omnigent. Some companies we talked to have built custom internal meta-harnesses that integrate with their development toolchain.
Cost Lever #2: Dynamic Request and Task Routing
Instead of asking users to choose task-appropriate models themselves, a growing body of research suggests that automatic model and tool selection may further squeeze efficiency out of agentic coding workflows. Routing approaches roughly fall into three categories:
- Request Level Routing: A stateful proxy sits in between a client (such as a coding harness) and the underlying foundation models. The proxy attempts to route requests to the lowest-cost model capable of answering each inference request. Routing for agentic use cases also needs to account for server-side caching, since a cold cache hit has a very high cost for large context workloads. A new wave of products is showing early, promising results for routing. Examples are: Cursor Router, OpenRouter’s AutoRouter, Ramps Router feature and Databricks own Smart Routing feature in Unity AI Gateway.
- Task Level Routing (Meta Harness): A client-side process dispatches user tasks to different harnesses based on the complexity of the task. A user task might be “rename this component from X to Y” (a simple task) or an open-ended task like “Explore design considerations that would reduce latency” (a complex task). The dispatcher, often called a Meta Harness , examines which level of underlying model is required for a task and then delegates that entire end-to-end task to the model. Omnigent is an example of a Meta Harness that supports this pattern.
- Escalation/Delegation Patterns: A single harness pairs two models (an expensive, high-intelligence model and a cheap worker model). In some approaches, such as Claude’s Advisor Tool, the cheaper model runs the show and escalates when it thinks a task requires more horsepower. The inverse pattern also exists: In Cognition’s Devin Fusion, the higher cost model is the main loop, and it selectively outsources work to a cheaper model.
Internal results at Databricks suggest that our AI Gateway Smart Router is able to consistently reduce average task cost by more than 30%, while roughly matching the quality of the most expensive model in the working set. Other companies we spoke with have seen similar results.
Cost Lever #3: Giving developers visibility, tripwires, and budgets
It may be surprising that this entire article did not start and end with “Give users a monthly budget and be done with it.” Hard budgets , where usage is entirely cut off at a specific spend threshold, are often used only as a last resort option in every company we spoke with. There are two reasons that hard token budgets are not particularly effective for AI spend management: First, if a developer hits their budget ceiling, cutting off further access to AI tools would be debilitating to productivity. Neither the company or employee actually wants that outcome. Second, at least some of the “high spending” users are in fact those who have achieved monumental efficiency gains with AI and are producing immense output. Discouraging those users is self-defeating.
Instead of a hard user spending cap, most companies are adopting a more nuanced and progressive approach that focuses on visibility for end users and increased degrees of friction as spend increases.
- Visibility: Every company we spoke with had a mechanism to provide near-instantaneous feedback to users on their ongoing spend, with many also offering specific tips or insights on how to reduce spend by using less expensive models. It is important that users be able to see their spend across all tools, since they may want to influence their choice of tool where they get the highest ROI.
A developer dashboard at Databricks showing active spend
- Spend Gates: Developers can be asked to take actions or seek approvals at increasing levels of spend. The simplest form of spend gate is one that can be self-cleared and serves as a warning that the spend rate is increasing above some threshold. At Databricks, we’ve found self-clearing gates a useful mechanism for preventing accidental or unintentional spend. Further gates can be introduced that require explicit budget approval (often through a management chain).
- Downshifting : If a developer has hit a spend gate, they can be downshifted to a lower-cost model rather than being entirely suspended from token access. Since the lowest-cost models are drastically less expensive than frontier-intelligence models, this technique allows developers to continue getting work done without incurring massive ongoing spend.
- Suspension : In the limit case, most systems do retain the ability to fully suspend users from all token access. As stated above, this is often a temporary measure only and the starting point for a conversation about how to efficiently leverage AI.
Cost Lever #4: Reducing Token Overhead
When a user types a relatively simple request into an AI coding agent (such as “Please investigate and fix this bug.”), that agent subsequently gathers massive amounts of relevant context, invokes a large number of tools, searches through the codebase, and integrates skills or system information provided by the company. By the time costly LLM inference occurs, the user's initial statement accounts for only a negligible fraction of the data fed into the AI system, meaning costs are dominated by context the user did not explicitly include. Techniques in reducing context bloat are still new, but several promising approaches are being explored, such as:
- Coercing more frequent compaction (compression) of the active context.
- Using harnesses that are “less chatty” (more token efficient), or tuning existing harnesses to generate less token overhead.
- Auditing popular tools and decreasing their verbosity.
- Encouraging developers to break tasks into smaller individual units of work, decreasing context scope.
When contexts get large, prompt caching also plays a meaningful role in overall performance. Both proprietary and open source LLMs have settings that allow you to enable prompt caching and tune how long the cache is stored. Cache writes cost money, but cached reads can drastically reduce per-inference cost. This trade-off is dependent on a company’s specific workload, so hand-tuning of default cache settings to increase overall cache hit rate can have drastic improvements to overall cost.
At Databricks, relatively simple tuning of our harness and caching settings led to an almost 50% reduction in the number of generated tokens and associated costs, with no observed quality degradation for developers. We continue to explore techniques in this area and think meaningful additional optimization remains possible.
A drastic reduction in tokens per session by eliminating extraneous inference calls and reducing cache writes.
The AI Gateway design pattern
The techniques above had many implicit technical requirements: To rapidly take advantage of new models, companies must have a central location where the “model menu” is managed, and end-users must have a toolchain that supports model mixing. To provide budget visibility across multiple AI tools, a unified cost observability capability must exist. To manage context bloat, companies need a way to observe typical toolcall outputs and enforce compression or compaction. These needs are collectively being solved by a new class of infrastructure software, best described as an AI Gateway. An AI gateway is a central location where all of the following occur:
- Capacity management and proxying of access to underlying models (both proprietary and OSS models).
- Budget tracking and enforcement, including complex budget policies such as progressive friction levels and model downshifting.
- Configuration management for end-user tools, to enforce model allow-lists, compaction settings, and other locally mediated aspects.
- Logging of coding session traces for downstream efficiency analysis and benchmark.
At Databricks, we rely heavily on Unity AI Gateway for all of these capabilities.
Putting it all together
The exponential growth of AI coding costs is not an inevitability, it's a solvable engineering and governance problem. Companies that have tamed it share a common playbook: relentlessly chase the efficiency frontier rather than the intelligence frontier, adopt tooling that preserves model flexibility, route work intelligently to the cheapest capable model, replace hard budgets with visibility and progressive friction, and cut the token overhead that dominates real-world spend. None of these techniques requires sacrificing the productivity gains that made AI adoption worthwhile in the first place; together, they let organizations satisfy the dual mandate of broad, low-friction access within a predictable cost envelope.
A set of new infrastructure abstractions is emerging to give companies the tools to manage their costs. At Databricks, we’ve released the key components in our cost management stack as open source or free software products: Our Unity AI Gateway for central management and Omnigent for developer tooling. Thousands of companies use these components every day. We invite more companies to share findings and compare techniques as this technology landscape rapidly evolves.
Acknowledgements: Thank you to infrastructure leaders at Uber, Stripe, Coinbase, and Ramp who provided commentary and reviews of this article. Thank you to Thrive Capital for feedback on an early draft of this article.