当 Agent 式胶水融化:利用 Cloudflare Code Mode 与 Workers 的漏洞
英文标题:🔶 When Agentic Glue Melts: Exploiting Cloudflare Code Mode and Workers
Check Point Research 对 Cloudflare Code Mode 及其底层运行时 workerd 进行了安全分析,发现 workerd 原生 C++“JavaScript Glue”层中的五个内存破坏漏洞,其中两个被 Cloudflare 评为严重(Critical)。研究人员基于这些漏洞构建了两类端到端攻击:跨租户堆内存读取,以及由提示注入触发、最终实现主机原生代码执行的 Code Mode 沙箱逃逸。由于 workerd 同时支撑 Code Mode 沙箱与 Cloudflare Workers 的租户隔离,潜在影响范围覆盖数百万开发者、每秒数百万请求及 Cloudflare 网络中超过 10% 的流量。Cloudflare 已修复托管 Workers 生产环境;自行托管的 workerd 或 Code Mode 部署应升级至 v1.20260619.1。
 10.2 KB
 1.9 MB
 147.6 KB
 91.8 KB
 85.8 KB
 97.1 KB
 66.4 KB
 47.6 KB
 67.0 KB
 70.5 KB
 95.8 KB
 47.9 KB
 50.3 KB
 49.6 KB
 63.9 KB
 837 B
 617.4 KB
 163.5 KB
 133.3 KB
 472.5 KB
中文
作者:Yarden Porat,Check Point Research
核心要点
- Check Point Research 分析了 Cloudflare Code Mode。这项技术通过将工具转化为模型可编写代码调用的 TypeScript API,改变了 AI Agent 使用 MCP 的方式。
- 研究发现了 workerd 中的五个漏洞。workerd 是支撑 Code Mode 和 Cloudflare Workers 的开源运行时。其中两个漏洞被 Cloudflare 评为严重(Critical)。
- 影响范围广泛:根据 Cloudflare 自身的数据,Workers 由数百万开发者构建,[1]每秒处理数百万请求,[2]承载 Cloudflare 网络中超过 10% 的全部流量。[3]
- 由于 workerd 同时支撑 Code Mode 沙箱和 Workers 的租户隔离,这些发现带来了沙箱逃逸和跨租户暴露风险。
- Cloudflare 的托管 Workers 环境已在生产环境中完成修复。自行托管的 workerd / Code Mode 部署应升级至 v1.20260619.1。
- Check Point Research 在其 Black Hat USA 2026 演讲中发布了概念验证代码。
简要版本
我们的目标原本是攻破 Cloudflare Code Mode,结果也攻破了 Cloudflare Workers。两者都是通过攻击其共同底层的 workerd 实现的:这是一个进程内沙箱,完全依赖 V8 隔离不受信任的代码。
我们在 workerd 的原生 C++ 代码中发现了五个内存破坏漏洞(即 JavaScript 与运行时之间的“胶水”),并将其转化为两种端到端攻击:
- 跨租户堆内存窃取。
URLPattern中的越界读取允许一个 Worker 跨越共享进程堆,窃取另一租户的机密信息。 - Code Mode 沙箱逃逸。 从提示注入开始,
node:zlib中的 use-after-free 漏洞可逃出沙箱,并在主机上执行原生代码。
第一部分——理解目标
1. 起点:Code Mode
Code Mode 是 Cloudflare 对 LLM 工具调用的实现方式。与模型一次输出一个结构化工具调用不同,Code Mode 将可用工具暴露为带类型的 TypeScript API,并让模型编写代码来调用它们:包括循环、条件判断、数据重排等。
在传统的 MCP / 工具调用循环中,模型输出一次 {tool, args} 调用,Agent 运行该调用,并将结果反馈给模型。随后模型再输出下一次调用。每一步都是一次新的模型调用,通常还需要一次网络往返。Code Mode 则将这一过程合并:模型编写一个程序,自行编排大量工具调用(在本地循环、分支并组合中间结果),只有最终输出才会返回给模型。
Cloudflare 的观点是,LLM 在海量真实世界代码上训练,相比输出冗长的合成工具调用链,更擅长针对带类型的 API 编写程序。[4]
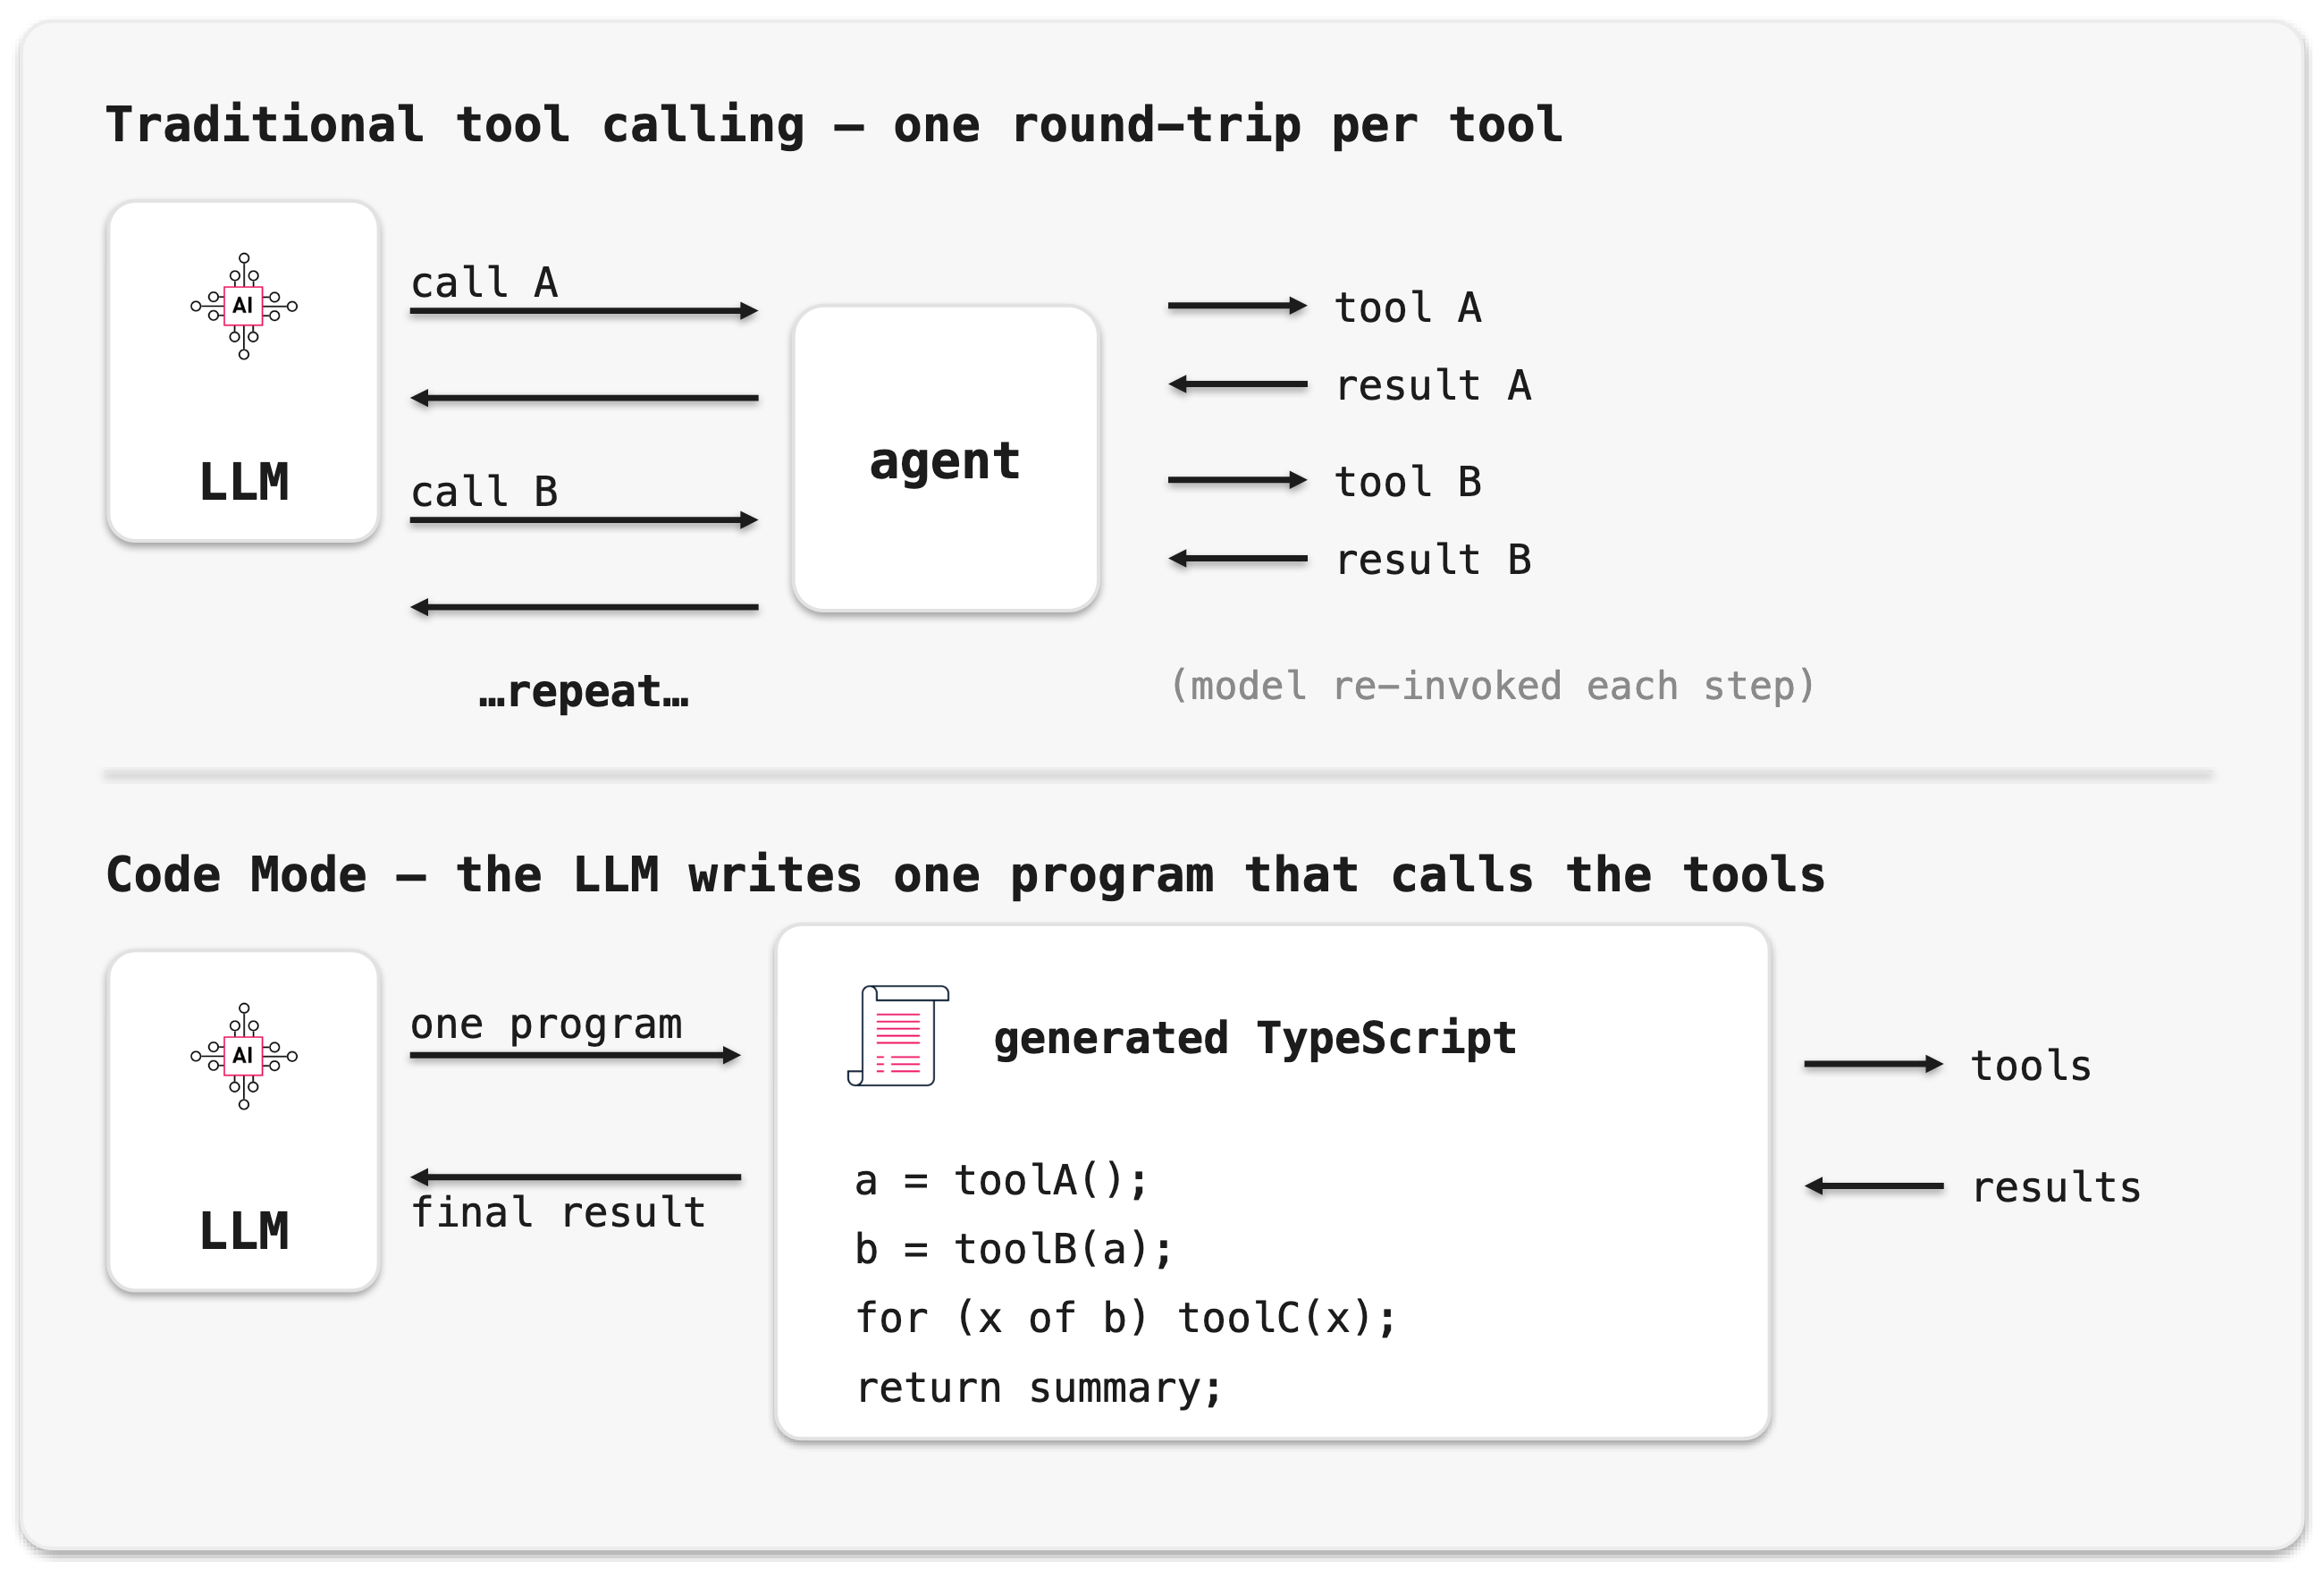
图 1——工具调用与 Code Mode 的对比
这些代码必须在某个地方运行,而这个“地方”就是 workerd,即 Cloudflare Workers 背后的运行时。
2. workerd 的起源故事
要理解 workerd,首先要从其构建所服务的产品开始:Cloudflare Workers。Workers 是 Cloudflare 的无服务器平台:你上传一段代码,Cloudflare 就会在边缘运行它——也就是在靠近用户的数据中心中,为每个请求按需运行。无需管理服务器,理想情况下也无需等待冷启动机器。
这种模式带来了棘手的隔离问题。Cloudflare 运行着大量不同客户的代码;为了控制延迟和成本,它将许多客户部署在相同机器上,而且正如我们将看到的,也部署在同一个进程中。传统答案是为每个租户分配一个容器或 VM,但这对该场景而言过于沉重:每个容器或 VM 都会增加数十到数百毫秒的冷启动时间,并带来实际的内存占用,而这正是一个处理海量短请求的边缘平台无法承受的。
Cloudflare 的解决方案是在语言运行时层面而不是操作系统层面进行隔离,使用 V8 isolate——这也是 Chrome 用于隔离浏览器标签页的同一种原语。isolate 是轻量、独立的 JavaScript 上下文。许多个 isolate 可存在于单个进程中,每个都能在个位数毫秒内启动,而 isolate 就是租户之间的安全边界。
代价在于,这一边界是同一共享地址空间中的软件边界,而非硬件或内核边界。不受信任的代码在进程内运行,整个模型都依赖于 isolate 能够维持隔离。
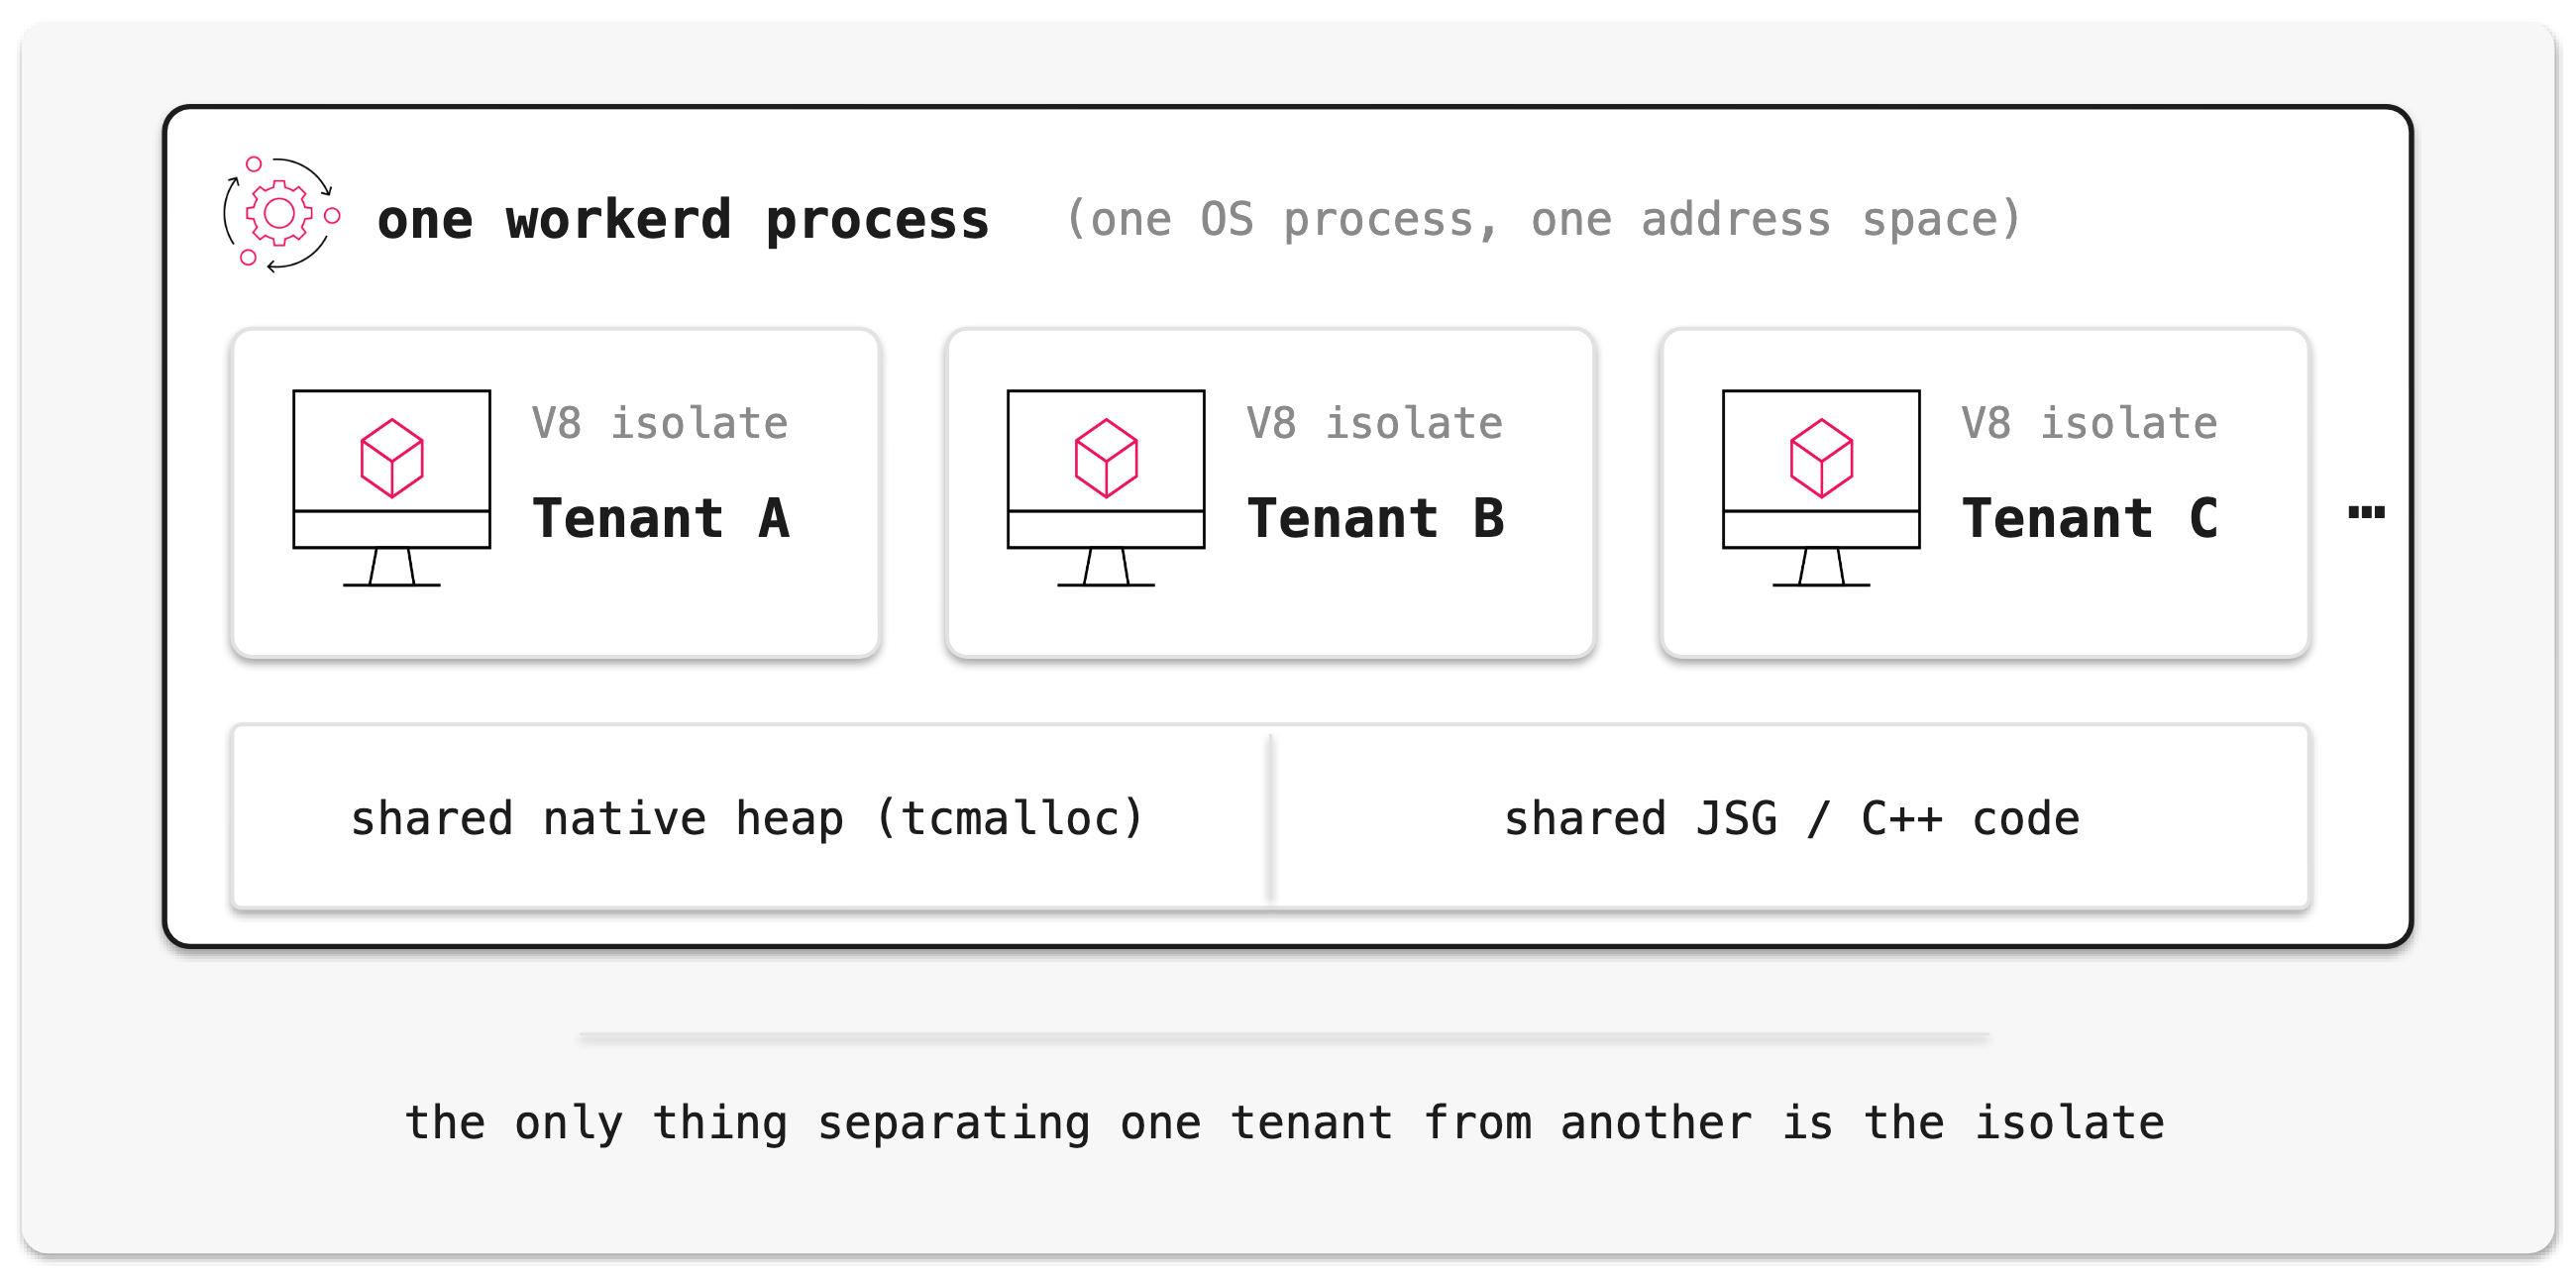
图 2——多个租户,一个进程
workerd 是实现这一切的运行时。它多年来一直是闭源的:Workers 于 2017 年推出,但 Cloudflare 直到 2022 年 9 月才将 workerd 开源。[5]它也正是 Code Mode 用于运行模型生成代码的环境。
3. 为什么 workerd 是 Code Mode 显而易见的沙箱选择
Code Mode 必须运行不受信任、由模型编写的代码,并且需要让这些代码只能访问已声明的 MCP 工具,不能访问其他任何内容。workerd 同时满足这两项要求。
在进程内运行不受信任的租户代码本就是它的日常职责,而它也让 Code Mode 可以锁定其余能力:没有文件系统、没有任意网络访问(fetch() 和 connect() 会直接抛出异常),工具仅通过 bindings 暴露。[6]Cloudflare 并未为 Code Mode 构建新的沙箱,而是复用了它已信任、用于隔离数百万 Workers 的沙箱。
4. 我们为何选择攻击 workerd
当你试图攻破 Code Mode 时,显而易见的检查位置是 Code Mode 与 workerd 之间的连接处。这里是集成层:工具如何变成 bindings、配置如何连接,以及两者如何交互。直接攻击运行时本身则是不寻常的做法。这有点像原本计划攻破一个 AI 编程助手,却转而审计 Docker 自身的源代码——即容器运行时本身,而不是其上的 Agent。
有五个原因让我们仍决定这样做:
- 进程内沙箱是一项大胆且天然高风险的选择。 在没有操作系统级边界的情况下隔离不受信任的代码,意味着没有 VM、没有容器,只有共享进程中的一个 V8 isolate。这将整个安全模型置于单一软件边界之上。这种雄心勃勃的押注正是值得进行压力测试的对象。
- workerd 几乎未受到公开审查。[7]尽管它直接位于这一安全边界上,与持续被深入剖析的 V8 形成鲜明对比的是,此前几乎没有针对 workerd 的公开漏洞研究。
- 攻击面巨大。而且不止 V8。workerd 自身实现并暴露了许多 Web/Node API,每一个都使用 C++ 编写,并可由不受信任的 JavaScript 访问。
- 影响范围延伸至 Cloudflare Workers。 workerd 不仅是 Code Mode 的运行时,也是 Cloudflare Workers 背后的引擎;后者是互联网上部署最广泛的无服务器平台之一。这里的漏洞绝不会仅局限于一个实验性的 Agent 功能。
- AI 安全也有底层的一面。 除了高层框架外,Agent 用于与现实世界交互的内部底层组件,同样值得研究。
5. 笼式沙箱、内存保护密钥与 Node
V8 是最常遭受攻击的软件组件之一,拥有悠久的内存漏洞历史,因此 Cloudflare 假定它可能被攻破,并部署多层防御,防止一个 isolate 被攻破后影响主机或其他租户。
防御措施
1. V8 沙箱(“笼”)。 笼式沙箱约束 JavaScript 可访问的对象,使被破坏的对象无法伪造指向其外部的指针。假设攻击者能在笼内实现任意读写,并阻止其访问笼外内存。
2. 内存保护密钥。 作为针对 V8 漏洞的额外防线,生产环境还会使用硬件**内存保护密钥(MPK / pkeys)**标记 isolate-group 内存。因此,即便攻击者能在一个 isolate 的 V8 内实现任意读写,仍无法读取其他租户的内存页。
3. L2 进程沙箱。 在这两层防御之下,还有一个第二层(“L2”)进程沙箱,因此即使在进程内实现原生代码执行,理论上也应受到限制。根据 Cloudflare 的说法,V8 Workers 运行在严格的第二层沙箱中(Linux namespaces 加 seccomp),可阻止所有文件系统访问和直接网络访问,[8]从而限制被攻破进程能够访问的主机资源。
攻击面
Node。 现实世界的 JavaScript 默认假设 Node.js 存在,代码也会频繁使用 node:* 模块,因此 workerd 使用 C++ 重实现了 Node API 的很大一部分。这些 API 通过其“JavaScript Glue”层 JSG 暴露给 JavaScript。Node 从未针对“_攻击者_编写 JavaScript”的威胁模型设计,因此这会在安全边界上增加大量额外的原生代码,其中大部分是 workerd 自己实现的,并且默认启用(Worker 可以直接 require('node:crypto'))。
这也意味着会在 tcmalloc 堆上分配更多原生对象,而该内存既不受笼式沙箱保护,也不受内存保护密钥保护。
6. 结论
综合以上情况,我们正是针对 workerd 的 JSG 代码展开攻击——也就是将原生 C++ 交给不受信任 JavaScript 使用的“JavaScript Glue”,无论它是 Node 重实现的一部分,还是 workerd 自身 API 实现的一部分。与 V8 相比,这部分代码受到的审查极少(§4);它分配的原生对象则位于 tcmalloc 堆上,即同时处于笼式沙箱和内存保护密钥之外的内存(§5)。因此,其中的漏洞不会像 V8 漏洞那样受到限制。这恰恰是这些缓解措施未覆盖的攻击面。
通过攻击这些代码,我们发现了五个漏洞,全部位于 workerd 自身的原生代码中,每个漏洞都将在“漏洞”章节(第二部分)中介绍。
基于这些漏洞,我们开发了两种端到端利用方式,将在“利用”章节(第三部分)中介绍。
- Code Mode 沙箱逃逸。 从单次提示注入开始,模型被引导编写攻击者控制的 TypeScript。该 TypeScript 包含一个导致原生代码执行的内存破坏漏洞,从而逃出 Code Mode,并在主机上运行,完全脱离 V8 isolate。
- 跨租户机密泄露。 从部署到 Cloudflare 共享资源池的恶意 Worker 开始,我们展示了一个租户如何读取另一租户的内存,并直接从共享进程中泄露其机密。这是生产环境场景;由于整个利用过程都在笼式沙箱和 MPK 未覆盖的 tcmalloc 堆上运行,因此该攻击在生产环境中同样成立。
但需要明确的是,我们没有亲自在 Cloudflare 生产环境上运行该利用程序。 两种利用方式均在自行托管版本的 workerd 上验证。跨租户攻击思路应当可以在生产环境中以相同方式运作,因为其完全在缓解措施未覆盖的 tcmalloc 堆上运行;但我们没有在那里进行测试。在共享主机上,可能导致进程崩溃的内存破坏利用也可能连带使其他租户中断服务,我们不愿承担这种风险。
第二部分——漏洞
7. URLPattern 越界读取
URLPattern 是一种 Web API,用于将 URL 与模式进行匹配,本质上类似于路由器的功能。你可以构建如 new URLPattern({ pathname: "/users/:id" }) 的模式,对 URL 调用 .exec(),然后读取命名捕获组({ id: "…" })。workerd 将它暴露给 Workers;在我们的场景中,模式本身由攻击者控制。
workerd 实际提供了两种 URLPattern 实现。第一种是原始的 workerd 原生实现(urlpattern_original 兼容性标志)。第二种是较新的标准实现,基于 Ada URL 解析器库。我们在两种实现中发现了相同的越界读取漏洞,且它们提供相同的利用原语。
7.1 根本原因
在底层,URLPattern 会将模式转换为正则表达式。随后,匹配 URL 会生成两个并行列表:匹配值(正则表达式中每个捕获组对应一个)以及组名称。
下面是一个正常场景的简要示例:
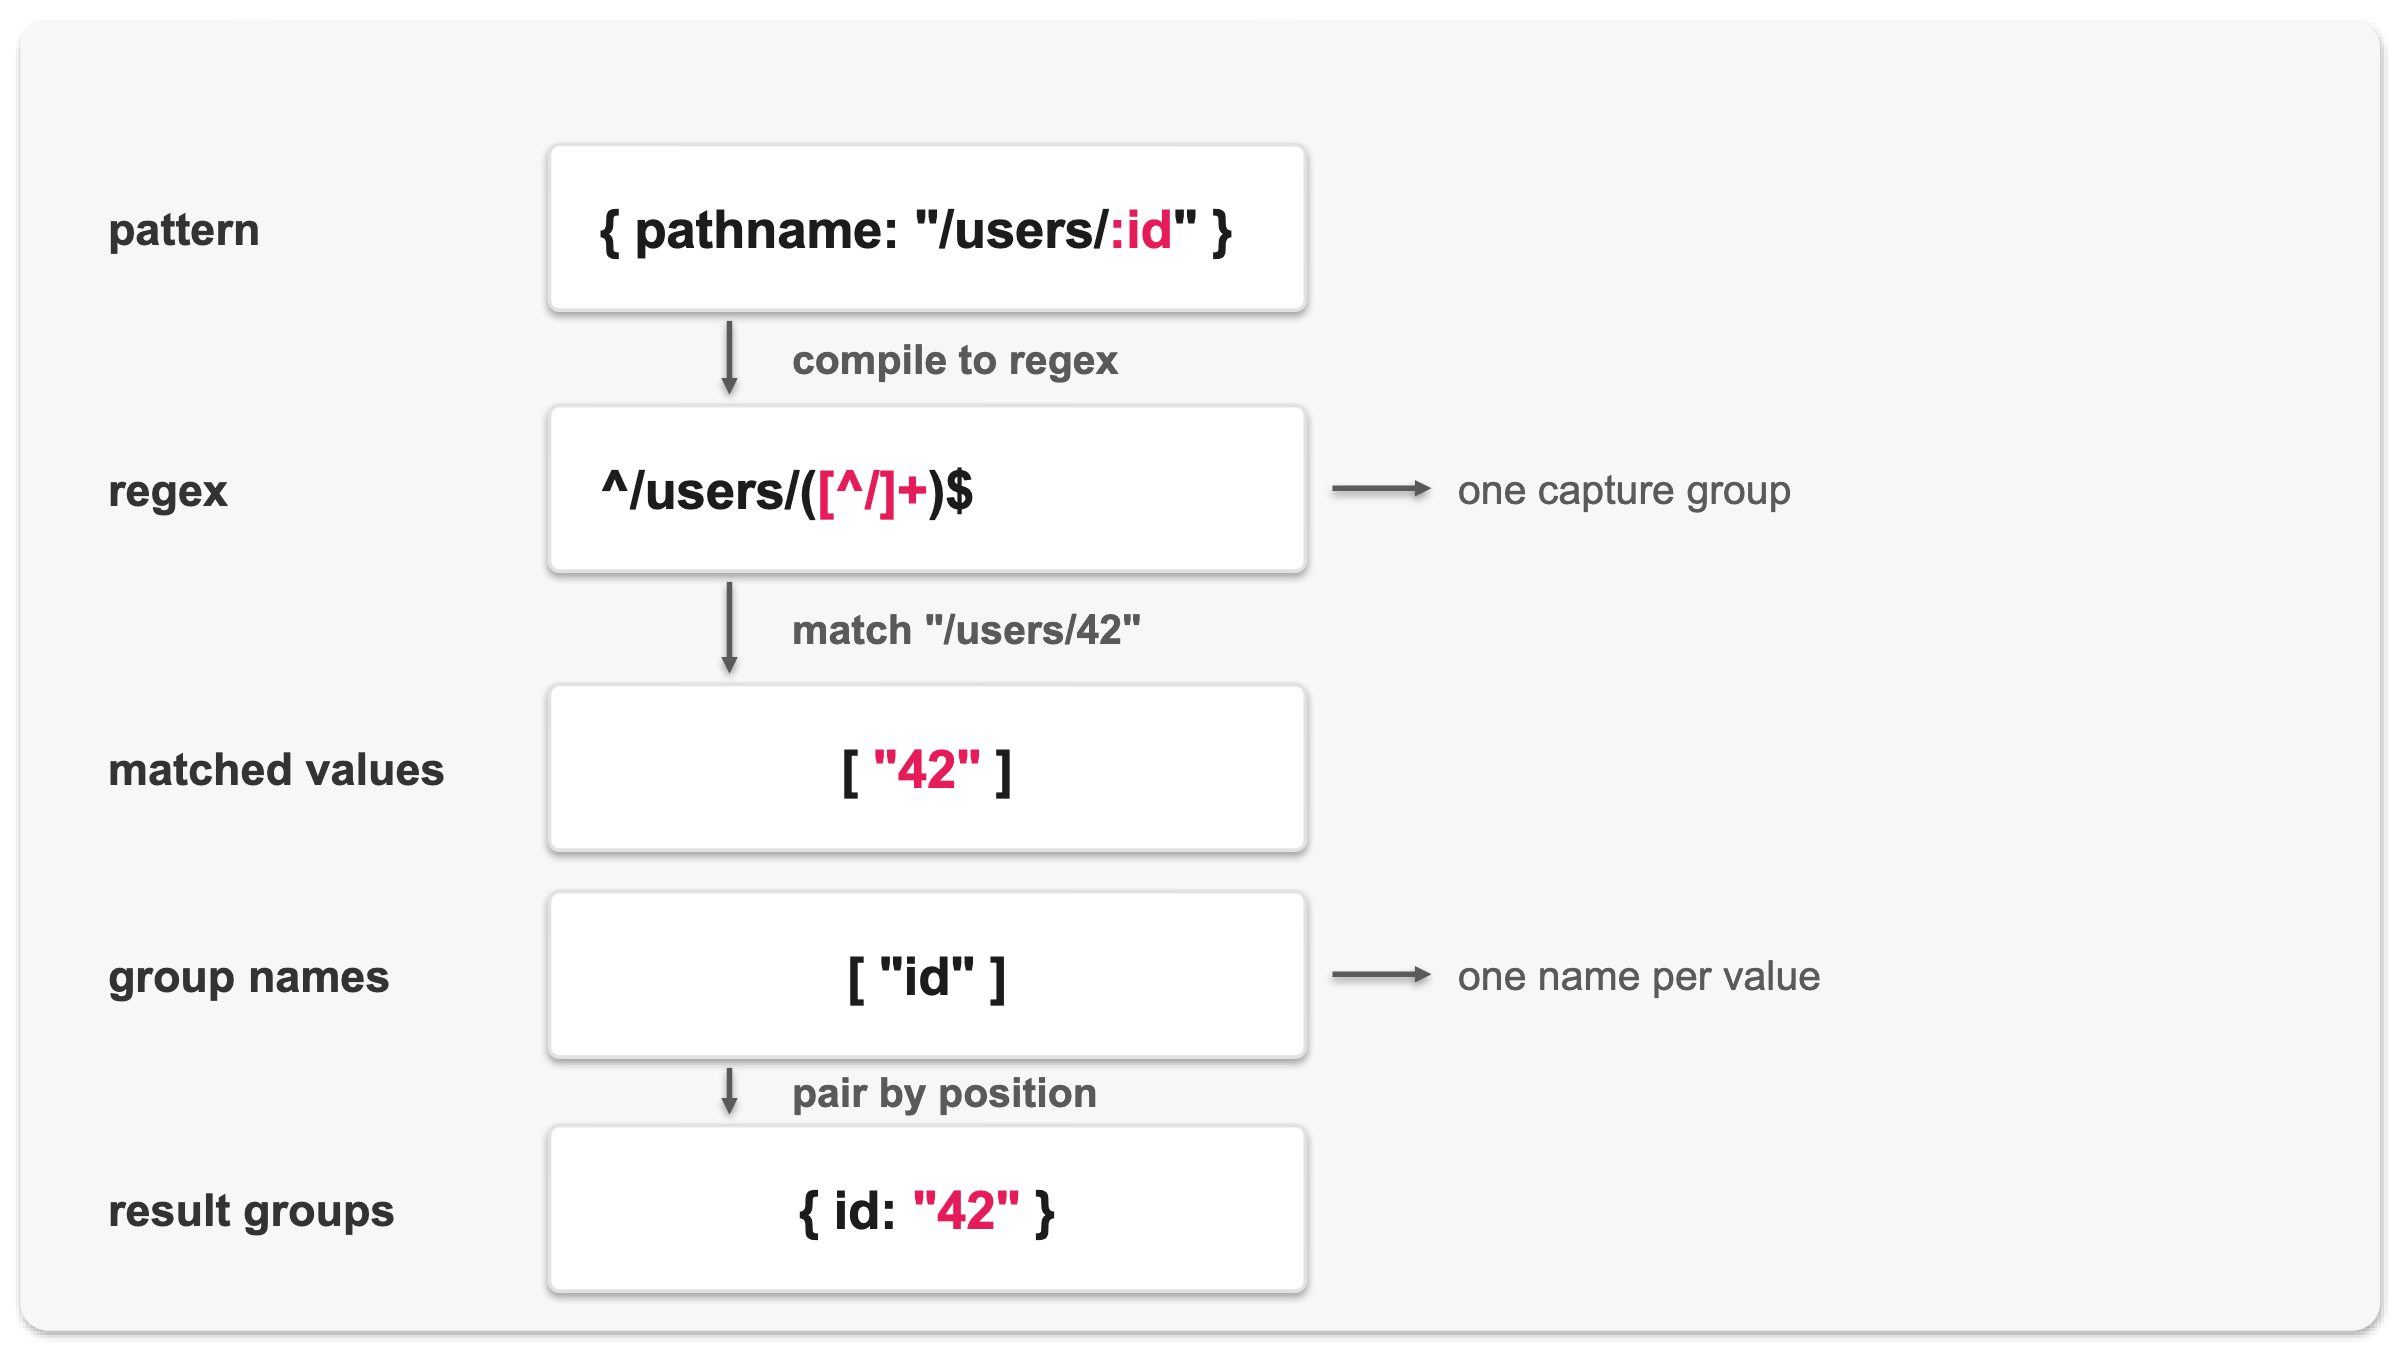
图 3——URLPattern:模式 → 结果
URLPattern 还允许你将原始正则表达式直接嵌入模式中,可使用命名或未命名组。例如,/(\d+)/(?<slug>[a-z]+) 有一个未命名组和一个命名组:
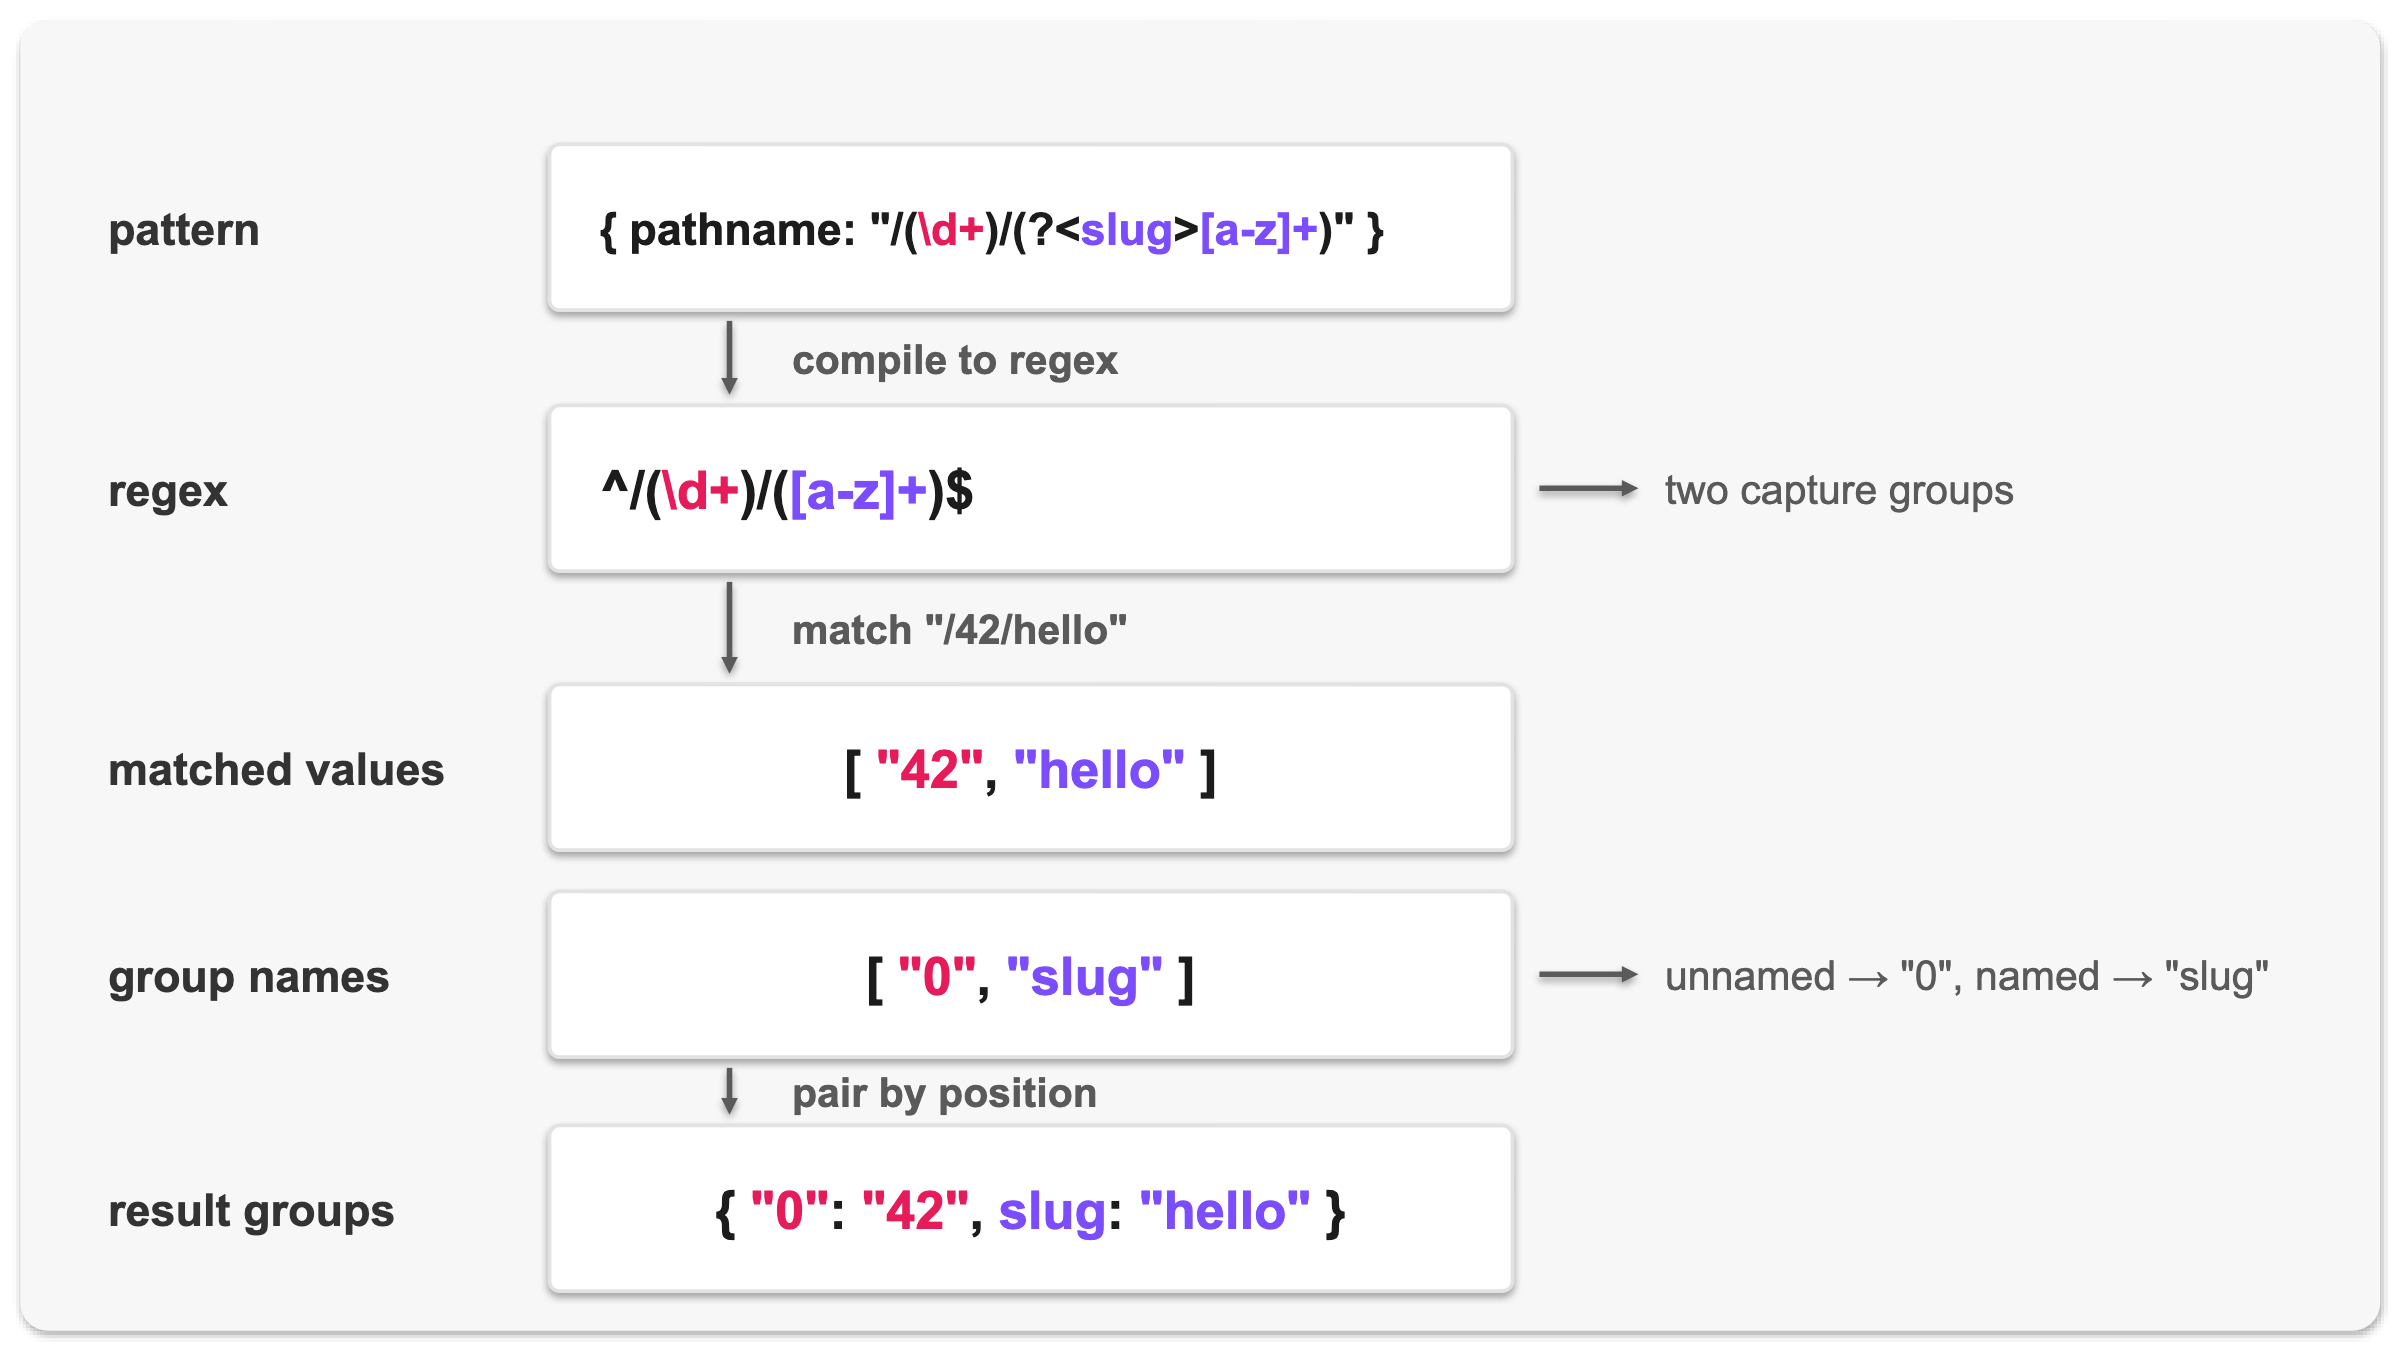
图 4——带命名组的 URLPattern
以下是实现代码。调用 .exec() 时,workerd 会针对 URL 运行编译后的正则表达式,并根据结果构建 groups 对象。原始 workerd 原生版本的实现如下:
// urlpattern.c++: building the groups object from a regex match
KJ_IF_SOME(array, regex.getHandle(js)(js, input)) {  // run regex vs URL
  uint32_t index = 1;                                // [0] is full match, skip
  uint32_t length = array.size();                    // 1 + capture count values
  kj::Vector<Groups::Field> fields(length - 1);

  while (index < length) {                           // each capture value
    auto value = array.get(js, index);
    fields.add(Groups::Field{
      .name = kj::str(nameList[index - 1]),           // name by position
      .value = value.isUndefined() ? kj::String() : kj::str(value),
    });
    index++;
  }
  // ...
}
对于每个捕获组,循环都会构建一个 { name, value } 字段。value 是正则表达式在 URL 中匹配到的内容。name 是该组的名称(例如前文中的 id),取自 nameList 向量。
这一配对的两侧来自完全不同的位置,而这正是需要记住的部分:
length来自 V8。它是 V8 在运行编译后的正则表达式后返回的匹配数组大小,即该正则表达式实际
English / 原文
By Yarden Porat, Check Point Research
Key Points
- Check Point Research analyzed Cloudflare Code Mode, a technique that changes how AI agents use MCP by turning tools into a TypeScript API the model can write code against.
- The research uncovered five vulnerabilities in workerd, the open-source runtime behind Code Mode and Cloudflare Workers. Two were rated Critical by Cloudflare.
- The blast radius is broad: by Cloudflare’s own numbers, Workers is built by millions of developers ,[1] serves millions of requests per second ,[2] and carries more than 10% of all traffic on Cloudflare’s network.[3]
- Because workerd underpins both Code Mode sandboxes and Workers tenant isolation, the findings create sandbox-escape and cross-tenant exposure risk.
- Cloudflare’s managed Workers environment has been fixed in production. Self-hosted workerd / Code Mode deployments should update to v1.20260619.1.
- Check Point Research released proof-of-concept code as part of its Black Hat USA 2026 presentation.
The short version
We set out to break Cloudflare Code Mode , and ended up breaking Cloudflare Workers too. We did both by targeting workerd , the runtime beneath both: an in-process sandbox that relies entirely on V8 to isolate untrusted code.
We found five memory-corruption bugs in workerd’s native C++ (the “glue” between JavaScript and the runtime), and turned them into two end-to-end attacks:
- Cross-tenant heap swipe. An out-of-bounds read in
URLPatternlets one Worker reach across the shared process heap and swipe another tenant’s secrets. - Code Mode sandbox escape. Starting from a prompt injection, a use-after-free in
node:zlibbreaks out of the sandbox and runs native code on the host.
Part I – Understanding the target
1. Where this started: Code Mode
Code Mode is Cloudflare’s take on LLM tool use. Instead of a model emitting structured tool calls one at a time, Code Mode exposes the available tools as a typed TypeScript API and lets the model write code that calls them: loops, conditionals, data shuffling and all.
In the traditional MCP / tool-calling loop, the model emits one {tool, args} call, the agent runs it, feeds the result back. The model then emits the next call. Every step is a fresh model invocation, and usually a network round-trip. Code Mode collapses that: the model writes one program that orchestrates many tool calls itself (looping, branching, and combining intermediate results locally) and only the final output returns to the model.
Cloudflare’s argument is that LLMs, trained on enormous amounts of real-world code, are simply better at writing a program against a typed API than at emitting long chains of synthetic tool calls. [4]
Figure 1 – Tool calling vs. Code Mode
That code has to run somewhere, and that “somewhere” is workerd , the runtime behind Cloudflare Workers.
2. The workerd origin story
To understand workerd, start with the product it was built for: Cloudflare Workers. Workers is Cloudflare’s serverless platform: you upload a piece of code and Cloudflare runs it at the edge , in data centers close to the user, on demand for every request. There’s no server to manage and, ideally, no cold machine to wait for.
That model creates a hard isolation problem. Cloudflare runs code from a huge number of different customers, and to keep latency and cost down it packs many of them onto the same machines, and, as we’ll see, into the same process. The classic answer (a container or VM per tenant) is far too heavy for this: each one adds tens to hundreds of milliseconds of cold start and a real memory footprint, which is exactly what an edge platform serving oceans of short requests cannot afford.
Cloudflare’s answer is to isolate at the language-runtime level rather than the OS level, using V8 isolates, the same primitive Chrome uses to separate browser tabs. An isolate is a lightweight, independent JavaScript context. Many can live inside a single process, each starts in single-digit milliseconds, and the isolate is the security boundary between tenants.
The trade-off is that this boundary is a software boundary inside one shared address space, not a hardware or kernel one. Untrusted code runs in-process , and the whole model rests on the isolate holding.
Figure 2 – Many tenants, one process
workerd is the runtime that implements all of this. It was closed-source for years: Workers launched in 2017, but Cloudflare only released workerd as open source in September 2022.[5] It’s exactly what Code Mode runs the model’s generated code on.
3. Why workerd was the obvious sandbox for Code Mode
Code Mode has to run untrusted, model-written code, and it needs that code to reach the declared MCP tools and nothing else. workerd answers both at once.
Running untrusted tenant code in-process is its day job, and it lets Code Mode lock the rest down: no filesystem, no arbitrary network (fetch() and connect() simply throw) with the tools exposed only through bindings.[6] Cloudflare didn’t build a new sandbox for Code Mode. It reused the one it already trusts to isolate millions of Workers.
4. Why we targeted workerd
When you set out to break Code Mode, the obvious place to look is the seam between Code Mode and workerd. This is the integration layer: how tools become bindings, how the configuration is wired, how the two interact. Going after the runtime itself is the unusual move. It’s a bit like setting out to break an AI coding assistant and then going to audit Docker’s own source code, the container runtime itself, not the agent on top of it.
Five reasons made us decide to do it anyway:
- An in-process sandbox is a bold, inherently risky bet. Isolating untrusted code without an OS-level boundary means no VM, no container, just a V8 isolate inside a shared process. That puts the entire security model on a single software boundary. That kind of ambitious bet is exactly what’s worth stress-testing.
- workerd had almost no public scrutiny.[7] Despite sitting directly on that boundary, there was barely any prior public vulnerability research on workerd, in stark contrast to V8, which is picked apart continuously.
- The attack surface is huge. And it’s not just V8. workerd has its own implementation that exposes many Web/Node APIs, each written in C++ and reachable from untrusted JavaScript.
- The blast radius reaches Cloudflare Workers. workerd isn’t only Code Mode’s runtime. It’s the engine behind Cloudflare Workers, one of the most widely deployed serverless platforms on the internet. A bug here would never have stayed contained to an experimental agent feature.
- AI security has a low-level side too. Beyond the high-level frameworks, the internal, low-level layers that agents rely on to interact with the world deserve research as well.
5. The cage, memory protection keys, and Node
V8 is one of the most heavily attacked pieces of software around, with a long history of memory bugs, so Cloudflare assumes it can break and layers defenses so a compromise of one isolate doesn’t reach the host or other tenants.
Defenses
1. The V8 sandbox (“the cage”). The cage confines JS-reachable objects so a corrupted one can’t forge pointers outside it. Assume arbitrary read/write inside the cage, and stop it reaching memory outside.
2. Memory protection keys. As a further layer against V8 vulnerabilities, production also tags isolate-group memory with hardware memory protection keys (MPK / pkeys) , so even with arbitrary read/write inside one isolate’s V8, an attacker still can’t read another tenant’s pages.
3. The L2 process sandbox. Underneath both sits a second-layer (“L2”) process sandbox , so even native code execution inside the process is meant to be contained. Per Cloudflare, the V8 Workers run in a strict layer-2 sandbox (Linux namespaces plus seccomp) that blocks all filesystem and direct network access,[8] limiting what a compromised process can reach on the host.
Attack Surface
Node. Real-world JavaScript assumes Node.js exists, and code constantly reaches for node:* modules, so workerd reimplements a large slice of the Node API in C++. This is exposed to JS through JSG , its “JavaScript Glue” layer. Node was never designed for a threat model where the attacker writes the JavaScript, so this drops a great deal of extra native code onto the boundary, much of it workerd’s own, and enabled by default (a Worker can just require('node:crypto')).
It also means more native objects allocated on the tcmalloc heap , which is secured by neither the cage nor the memory protection keys.
6. Bottom Line
Putting all of the above together, we did exactly that. We targeted workerd’s JSG code , the “JavaScript Glue” that hands native C++ to untrusted JavaScript, whether it is a Node reimplementation or one of workerd’s own API implementations. It is the code that had a fraction of V8’s scrutiny (§4), and the native objects it allocates sit on the tcmalloc heap , memory that lives outside both the cage and the memory-protection keys (§5). So a bug there is not boxed in the way a V8 bug is. It is exactly the surface those mitigations do not cover.
By going after that code we found five vulnerabilities, all of them in workerd’s own native code , each covered in the Vulnerabilities section (Part II).
Building on those bugs, we developed two end-to-end exploits , covered in the Exploits section (Part III).
- Code Mode sandbox escape. Starting from a single prompt injection, the model is steered into writing attacker-controlled TypeScript. That TypeScript contains a memory-corruption which leads to native code execution, breaking out of Code Mode and running on the host, fully outside the V8 isolate.
- Cross-tenant secret leak. Starting from a malicious Worker you deploy into Cloudflare’s shared pool, we show that one tenant can read another tenant’s memory and leak its secrets straight out of the shared process. This is the production scenario, and it holds up there because the whole exploit runs from the tcmalloc heap, the memory the cage and MPK do not cover.
But to be explicit, we did not run the exploit on Cloudflare production ourselves. Both exploits were verified on the self-hosted version of workerd. The cross-tenant idea should work the same way on production, since it runs entirely from the tcmalloc heap that the mitigations do not cover, but we did not test it there. On a shared host, a memory-corruption exploit that crashes the process could take other tenants down with it, and we were not willing to risk that.
Part II – The vulnerabilities
7. URLPattern out-of-bounds read
URLPattern is a Web API for matching a URL against a pattern, essentially what a router does. You build a pattern such as new URLPattern({ pathname: "/users/:id" }), call .exec() on a URL, and read back the named capture groups ({ id: "…" }). workerd exposes it to Workers, and in our setting the pattern itself is attacker-controlled.
workerd actually ships two URLPattern implementations. The first is the original, workerd-native one (the urlpattern_original compatibility flag). The second is the newer standard one backed by the Ada URL-parser library. We found the same out-of-bounds read in both implementations, and it gives the same primitive.
7.1 Root cause
Under the hood, URLPattern turns your pattern into a regular expression. Matching a URL then produces two parallel lists: the matched values (one per capture group in the regex) and the group names.
A quick example of the benign case:
Figure 3 – URLPattern: pattern → result
URLPattern also lets you drop raw regex straight into a pattern, with named or unnamed groups. For example, /(\d+)/(?<slug>[a-z]+) has one unnamed group and one named group:
Figure 4 – URLPattern with named group
Here is the implementation. When you call .exec(), workerd runs the compiled regex against the URL and builds the groups object from the result. The original, workerd-native version does it like this:
// urlpattern.c++: building the groups object from a regex match
KJ_IF_SOME(array, regex.getHandle(js)(js, input)) {  // run regex vs URL
  uint32_t index = 1;                                // [0] is full match, skip
  uint32_t length = array.size();                    // 1 + capture count values
  kj::Vector<Groups::Field> fields(length - 1);

  while (index < length) {                           // each capture value
    auto value = array.get(js, index);
    fields.add(Groups::Field{
      .name = kj::str(nameList[index - 1]),           // name by position
      .value = value.isUndefined() ? kj::String() : kj::str(value),
    });
    index++;
  }
  // ...
}
For each capture group, the loop builds one { name, value } field. The value is what the regex matched in the URL. The name is the group’s name (like id from earlier), taken from the nameList vector.
The two sides of that pairing come from completely different places, and that is the part to hold onto:
lengthcomes from V8. It’s the size of the match array V8 returns after running the compiled regex, i.e. how many capture groups the regex actually produced.nameListcomes from URLPattern’s own implementation. It’s the list of names workerd assembled while parsing the pattern, before the regex ever ran.
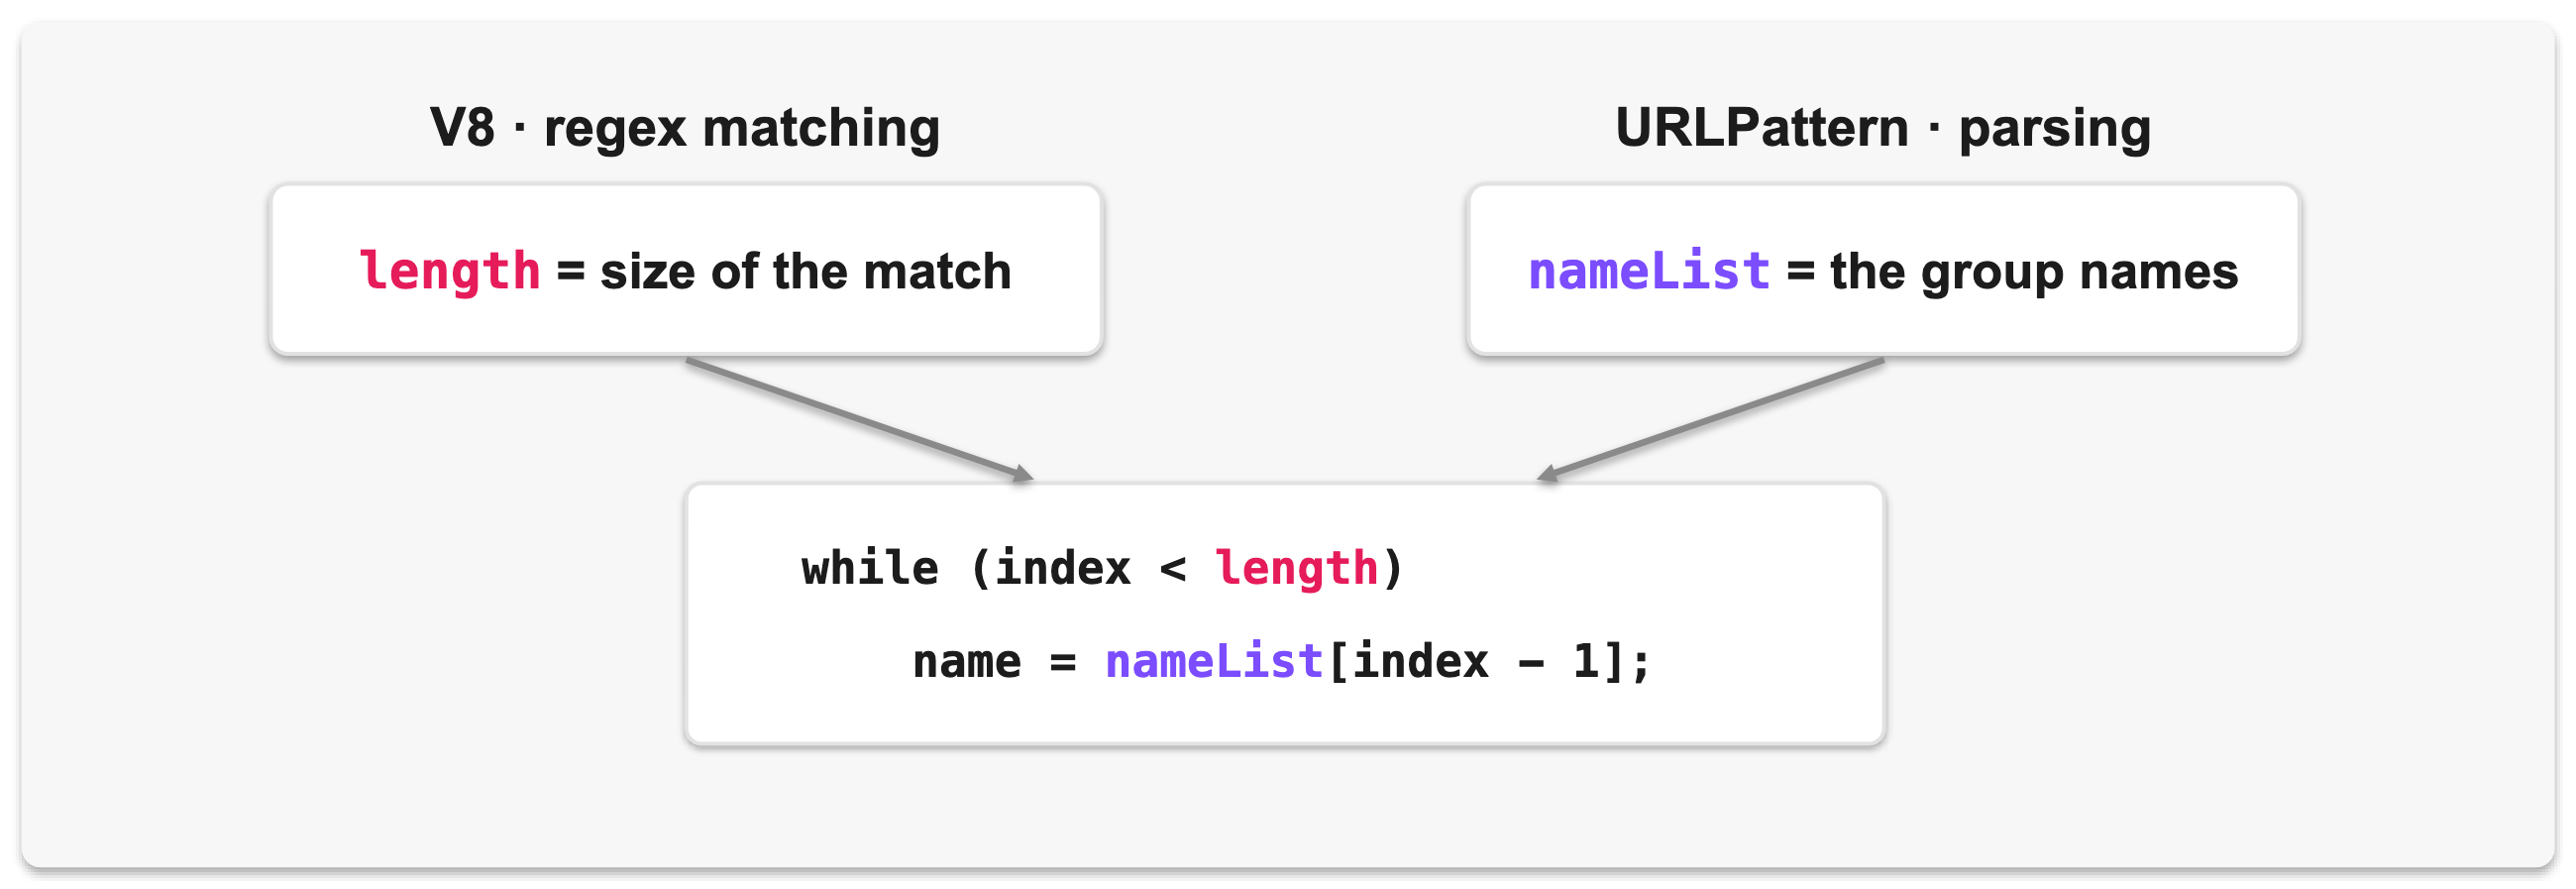
Figure 5 – The group-count mismatch
The loop lines them up position by position, on the assumption that the two counts agree.
So the whole thing rests on those two counts staying equal, and they don’t always. When URLPattern parses the pattern to build nameList, its own group counting misses a group nested inside another group. V8, compiling the real regex, counts every group, nested ones included. So a pattern with one group nested inside another, like (ab(cde)), gives V8 two capture groups where URLPattern counted only one, and length ends up larger than nameList:
const pattern = new URLPattern({ pathname: "/(ab(cde))" });
pattern.exec({ pathname: "/abcde" });   // V8: 2 groups, nameList: 1 name → OOB
Now the loop runs one step too far. For that extra value, index - 1 points past the end of nameList, and kj::str(nameList[index - 1]) reads from beyond the vector, an out-of-bounds read. That is the bug.
7.2 Why an OOB read is an arbitrary read
nameList is a kj::Vector<kj::String>. A kj::String is 24 bytes:
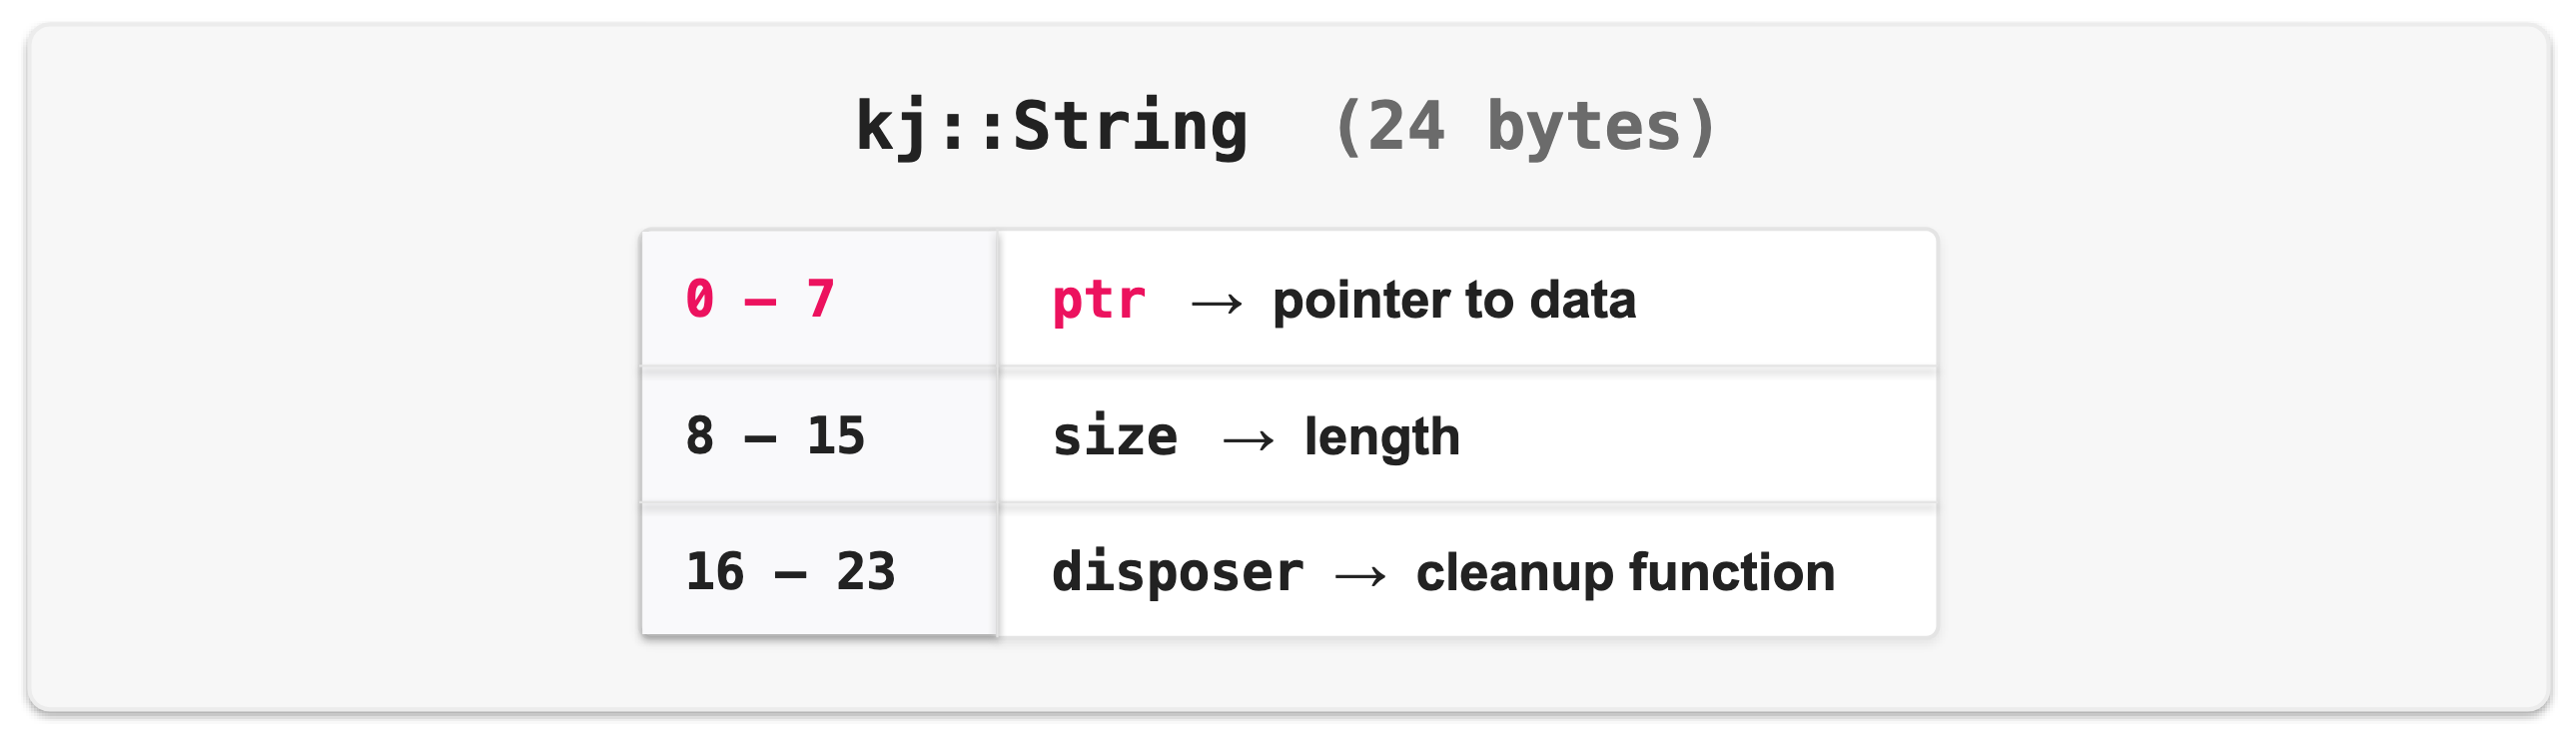
Figure 6 – kj::String memory layout
The OOB index makes kj::str() read 24 bytes of whatever follows the vector and treat it as a kj::String, then dereference ptr to copy out the “string.” So if we control the memory after nameList, we control ptr, and the returned JS string is the bytes at an address of our choosing. OOB read → arbitrary read.
7.3 Two notes
- The same bug is in both implementations, and the Ada one reaches production. The standard, Ada-backed URLPattern makes the identical counting mistake, with the same out-of-bounds read. We confirmed the Ada version triggers on Cloudflare production , and reported it to the Ada maintainers in parallel.
- Our full end-to-end exploit was on the original implementation, self-hosted. Turning the read into a working cross-tenant secret leak was demonstrated against
urlpattern_originalon self-hosted workerd. That exact path did not reproduce on production, because production has a check the open-source build lacked.
8. zlib deflateParams() UAF
zlib is the most common compression library around. Node.js ships it as the built-in node:zlib module, and to stay Node-compatible workerd reimplemented it in C++. It exposes a handful of APIs. The basic ones compress and decompress via Gzip , Deflate/Inflate , and Brotli. In workerd it comes with the nodejs_compat flag (compatibility date 2024-09-23 or later).
8.1 Dangling buffers
Let’s look at a basic use of zlib. You call write() with an input buffer and an output buffer, and zlib compresses the input into the output.
const input  = Buffer.from("hello world");
const output = Buffer.alloc(64);
handle.write(input, output);   // compress input → output
Those three lines already span three distinct layers:
- JavaScript (V8): creates the input and output buffers.
- workerd’s glue code: the translation layer between JavaScript and native C++, turning those buffers into the raw pointers and lengths the C library expects.
- zlib: the C compression library that does the actual work.
The buffer to watch is output. As it moves, its pointer is passed between all three layers, handled differently in each. So let’s take it one layer at a time, starting on the JavaScript side.
On the JavaScript side, output is reference-counted : it stays alive as long as at least one reference points at it. Follow that count through a single write():
const output = Buffer.alloc(64). The JS variable holds it: refcount 1.handle.write(input, output, …). As the buffer crosses into native code, workerd takes a reference of its own for the duration of the call: refcount 2. That extra reference is what guarantees the buffer can’t be freed while zlib is mid-compression.write()returns, and workerd drops its reference again: back to refcount 1 , held by the JS variable.- nothing holds
outputanymore (it goes out of scope, or is reassigned), so the last reference is gone: refcount 0.
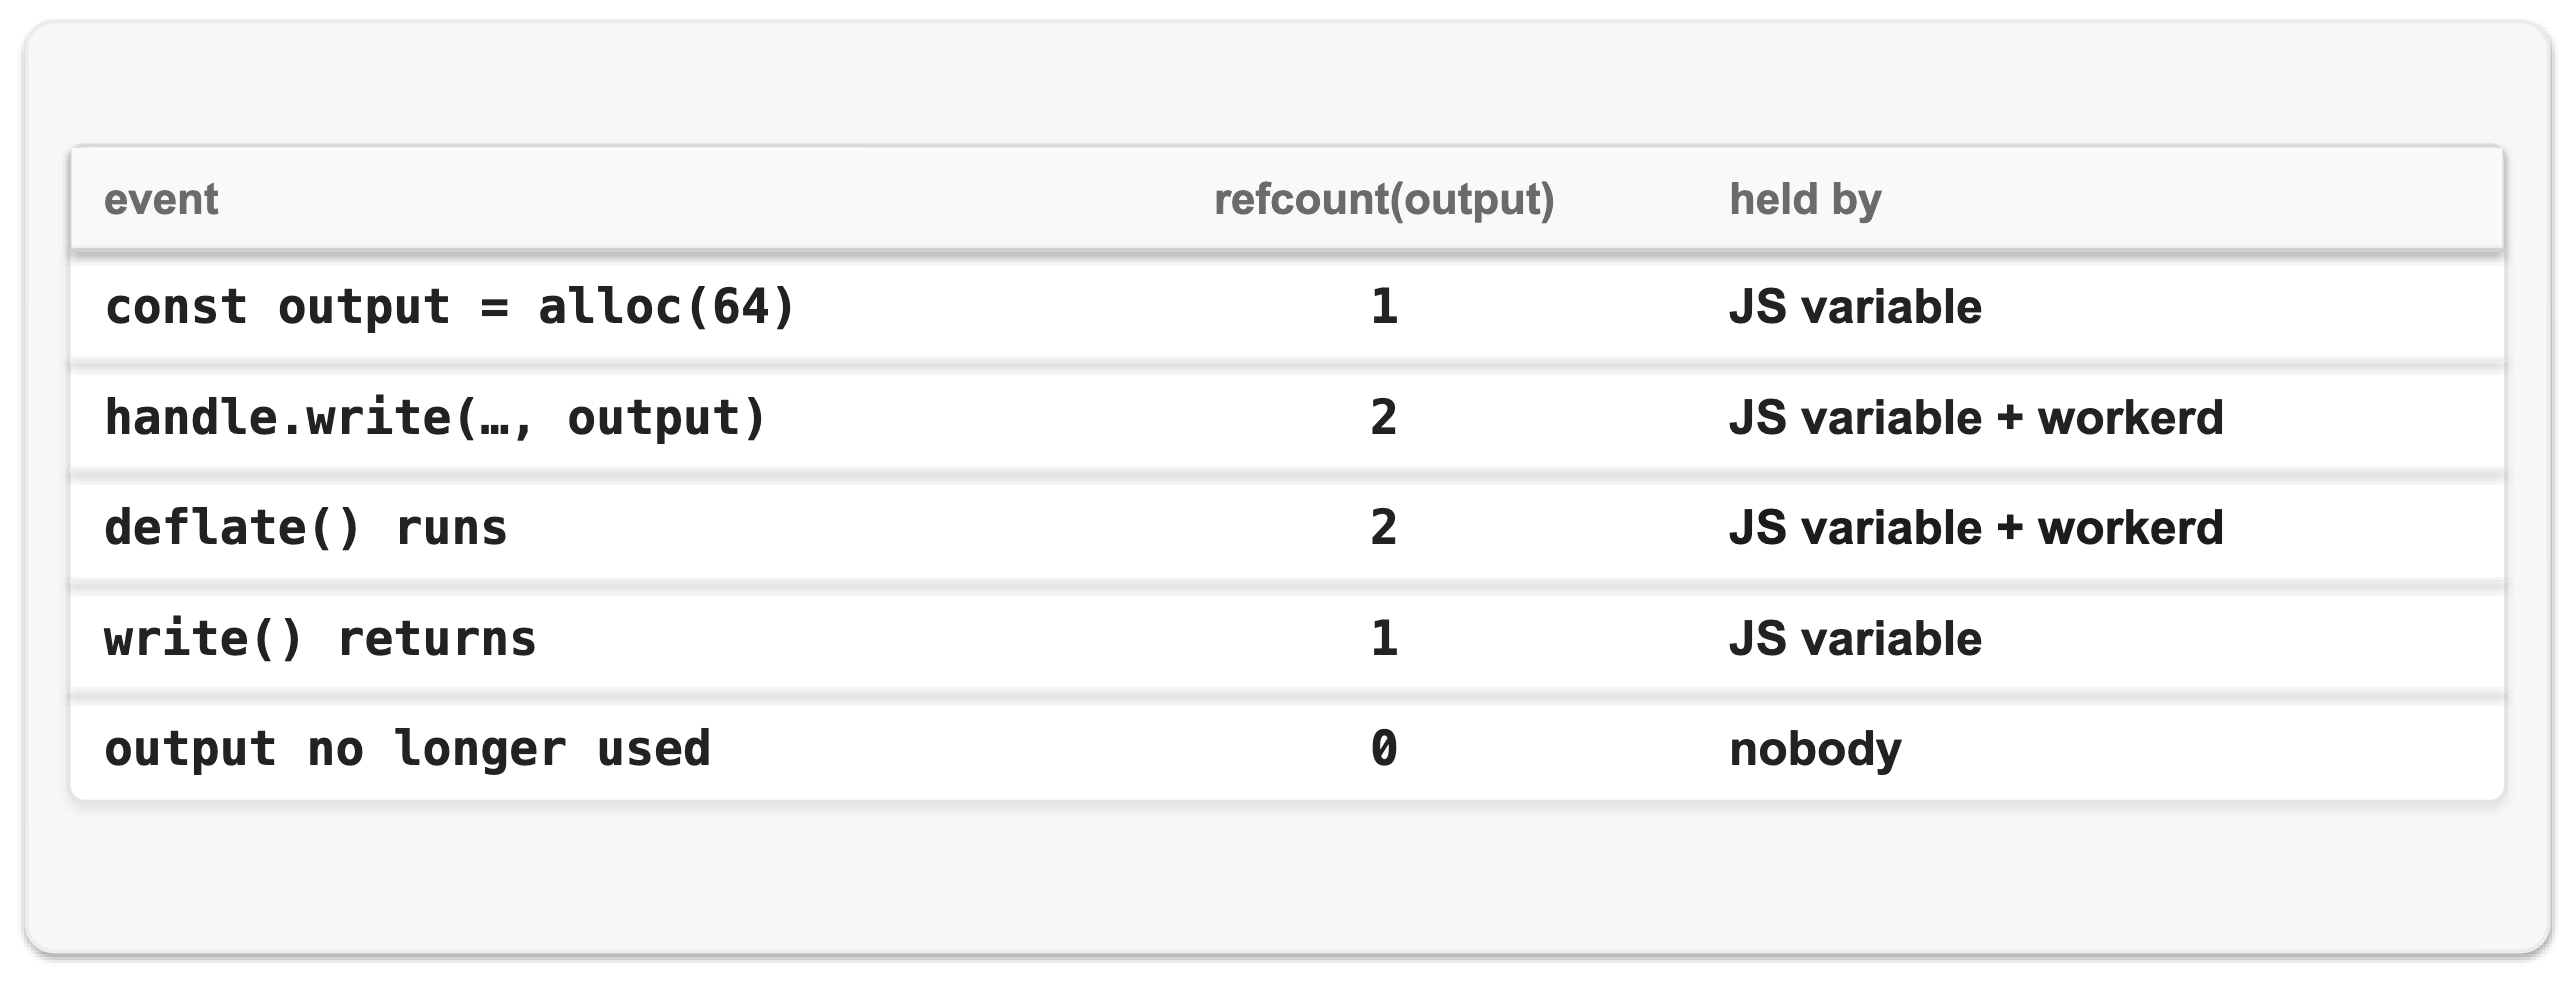
Figure 7 – output refcount lifecycle
Now follow the same buffer into the native side. To hand output to zlib, workerd fills in a z_stream(zlib’s state struct), copying the buffer’s raw address into its next_out field, the pointer zlib writes its compressed output through. That copy happens in setBuffers, on every write():
// zlib-util.c++
void ZlibContext::setBuffers(kj::ArrayPtr<kj::byte> input, kj::ArrayPtr<kj::byte> output) {
  stream.avail_in  = input.size();
  stream.next_in   = input.begin();    // raw pointer into the JS input buffer
  stream.avail_out = output.size();
  stream.next_out  = output.begin();   // raw pointer into the JS output buffer
}
And write() forgets to clear them. When it returns, it resets nothing in the z_stream. next_out still holds the raw address of output. Clearing it is workerd’s job, and the write path simply doesn’t.
The same sequence, now with stream.next_out shown alongside:
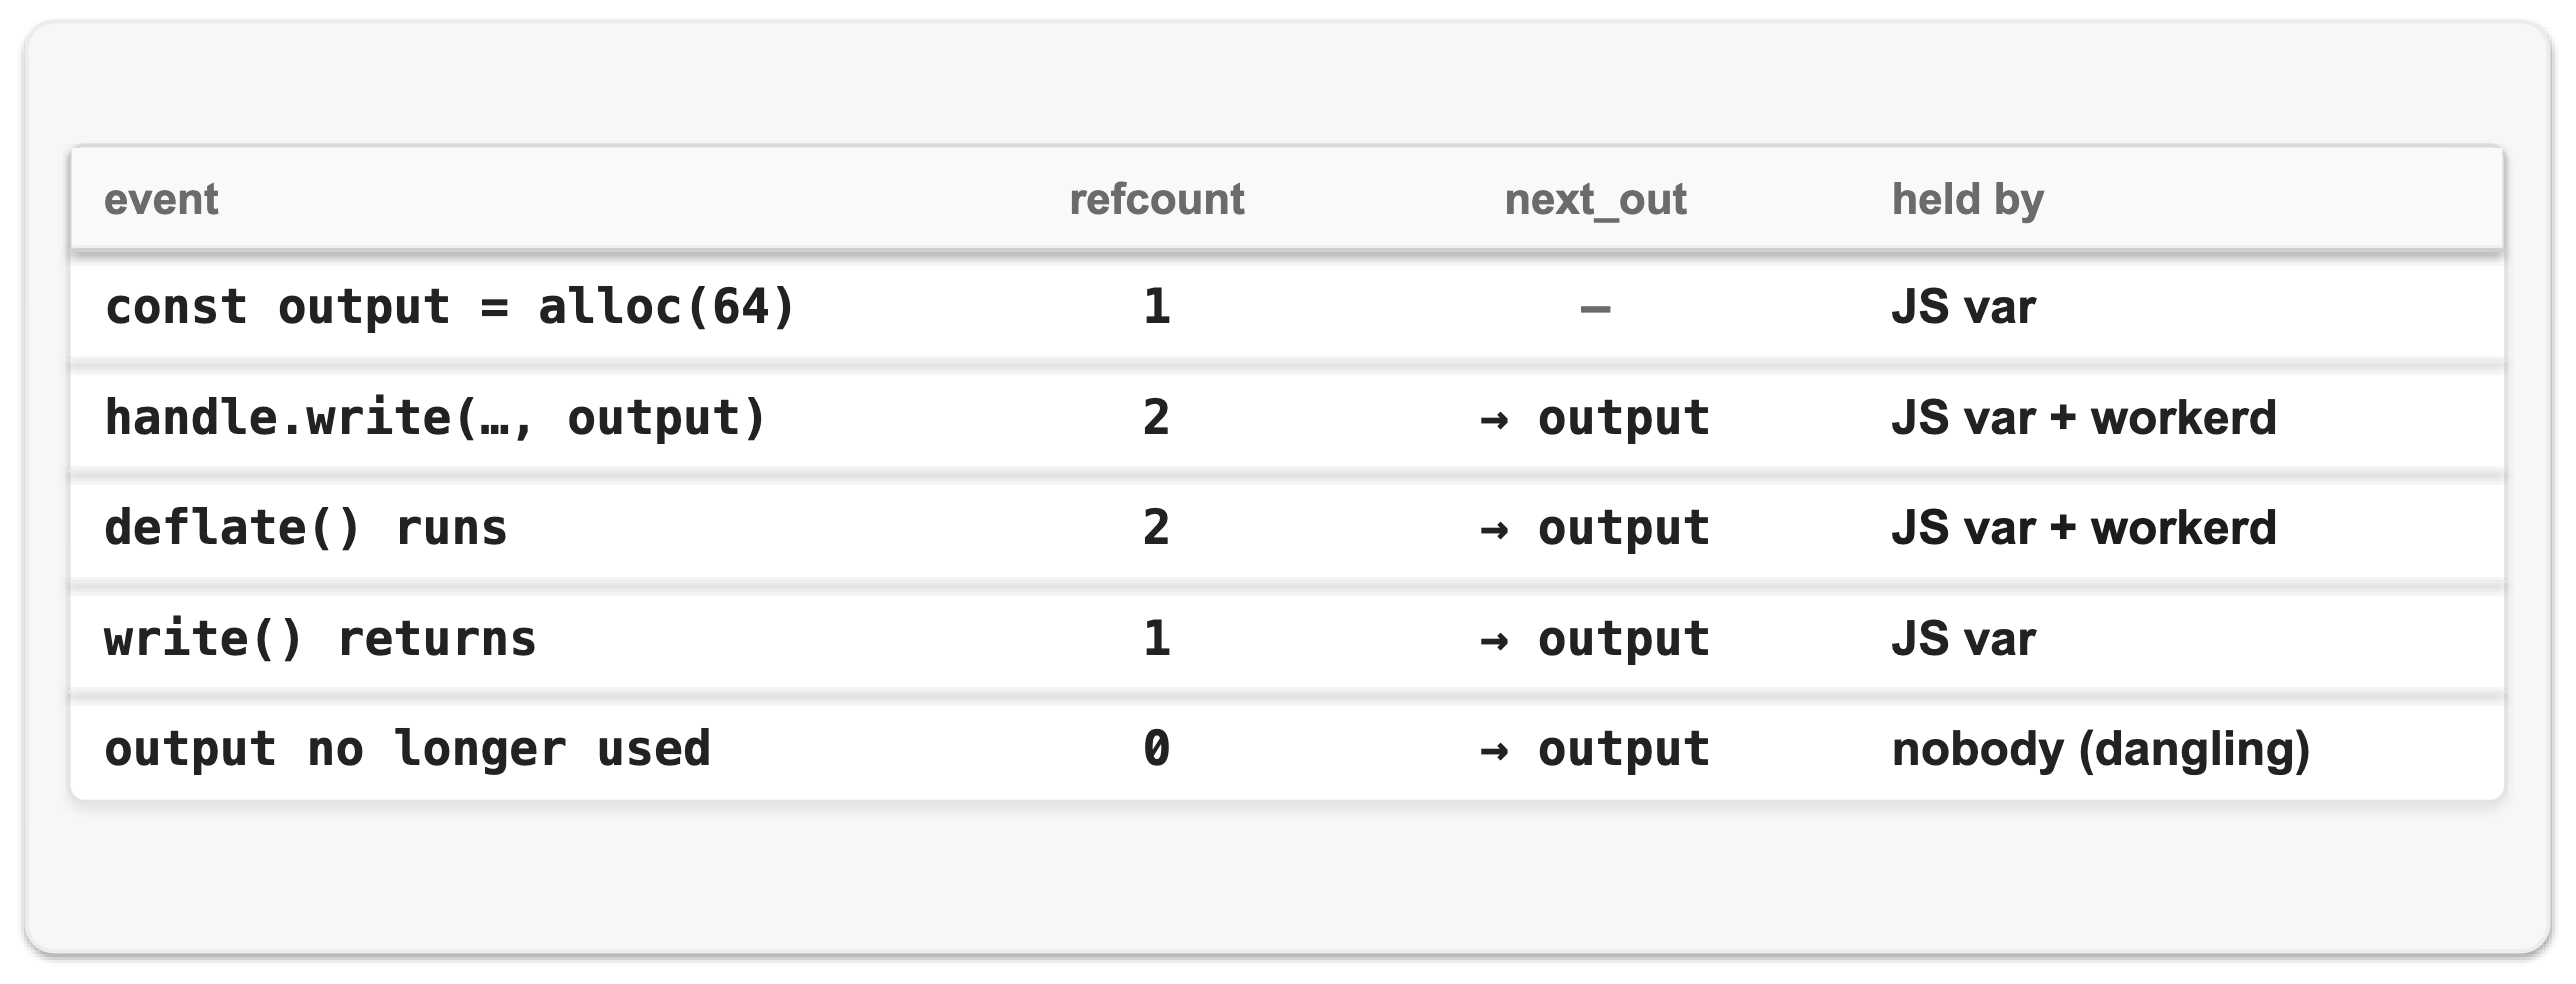
Figure 8 – next_out left dangling
Nothing ever clears next_out after setBuffers sets it. So once output’s refcount reaches 0, the buffer becomes garbage, and the next garbage-collection event reclaims its memory, leaving next_out pointing into freed memory.
8.2 The Use in Use-After-Free
We now have a dangling next_out, and the next step is to find who writes through it.
We started in workerd’s own code, but next_out is zlib’s field, and it is zlib, not workerd, that writes output through it. So the real question is where, inside the zlib library, next_out gets written.
The obvious place is an ordinary compression step: deflate() (and inflate()), the functions that push output through next_out. But in workerd that path is only ever reached through write(), and write() runs setBuffers first, resetting next_out to a fresh buffer before deflate() runs. The stale pointer is overwritten before it is ever used. No good.
What we found instead is deflateParams, reached from handle.params(), the call that adjusts the compression parameters, like the level (how hard zlib compresses). It touches the same z_stream and, crucially, does not reset next_out first:
// zlib-util.c++ — ZlibContext::setParams(), reached from handle.params()
err = deflateParams(&stream, _level, _strategy);
That hands zlib the same z_stream, still carrying the stale next_out from the last write(). And rather than clearing next_in/next_out, deflateParams flushes whatever output zlib still has buffered before it applies the new settings:
// zlib - deflate.c, deflateParams() (trimmed)
func = configuration_table[s->level].func;
if ((strategy != s->strategy || func != configuration_table[level].func)
        && /* there is data still pending */) {
    /* flush the last buffer */
    deflate(strm, Z_BLOCK);   // flush pending output through strm->next_out
}
s->level    = level;          // new config applied only after the flush
s->strategy = strategy;
If the level or strategy changes and data is still pending, zlib calls deflate() to flush it before updating the config, and that deflate() writes through strm->next_out, the dangling pointer.
But there is still a problem. When we called write(), zlib already compressed the data we handed it, so how are we supposed to have any bytes still pending for deflateParams to flush?
8.3 Z_NO_FLUSH
Each zlib write takes a flush mode controlling how eagerly output is emitted. Passing Z_NO_FLUSH tells zlib to hold compressed output in its internal buffer rather than push it all out through next_out, so the write() returns with data still pending. That pending data is exactly what deflateParams flushes.
8.4 Putting everything together
The whole use-after-free is a handful of JavaScript calls. Tracking outBuf’s refcount and next_out across the full cycle, the same way we did on the JavaScript side:
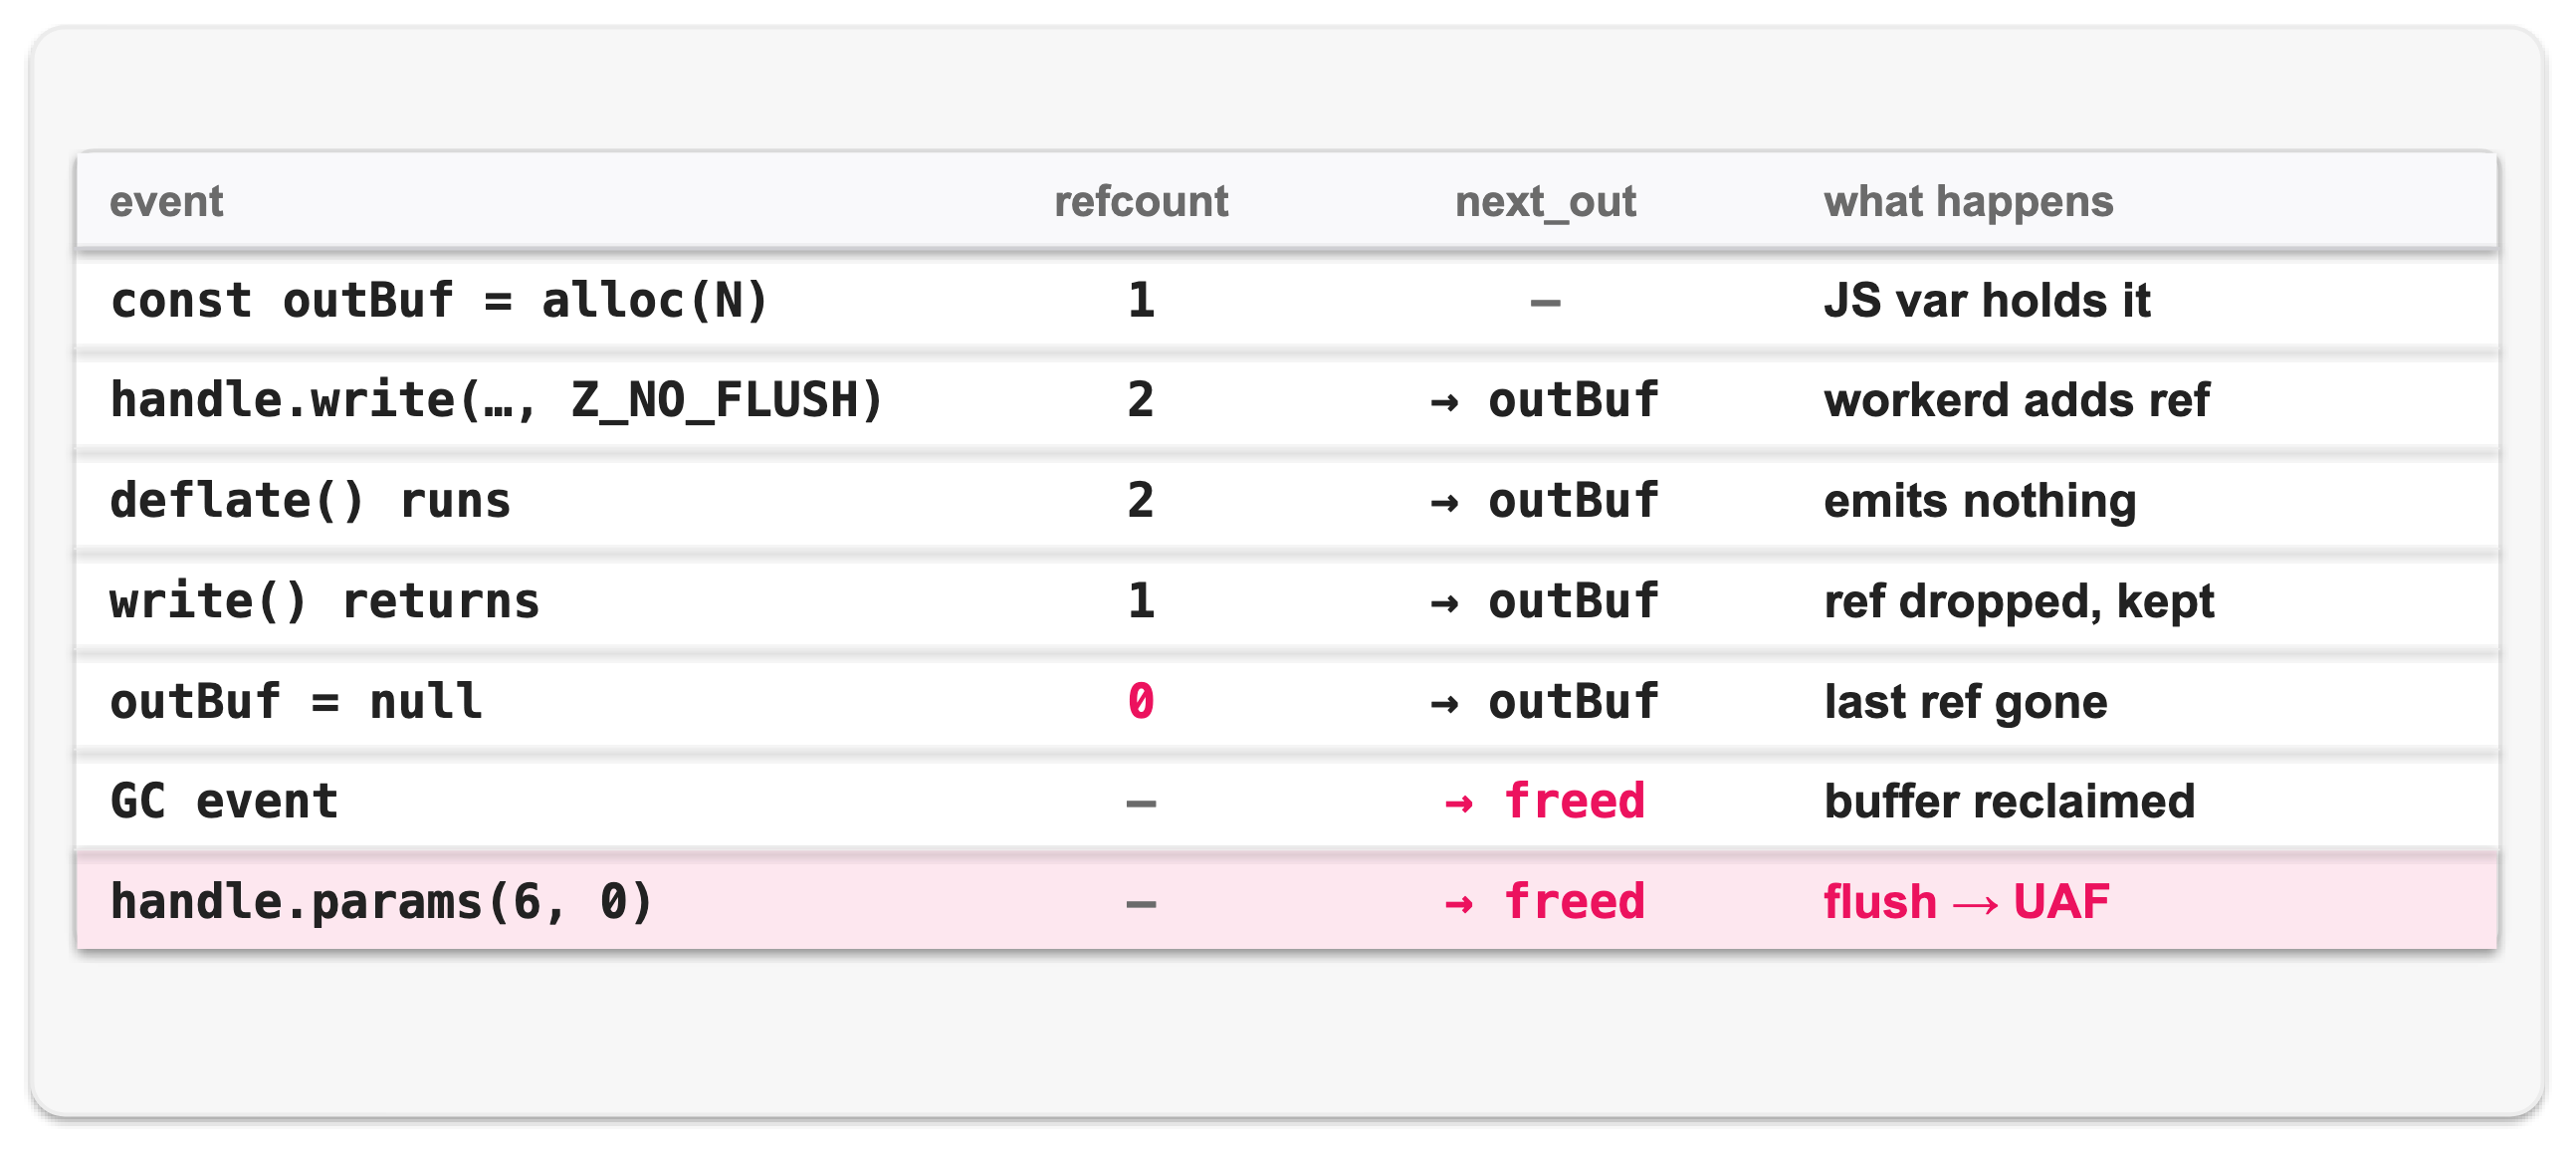
Figure 9 – The zlib use-after-free
9. HTMLRewriter AttributesIterator UAF
HTMLRewriter is a Workers API for transforming HTML as it streams through. A Worker can rewrite tags, attributes, and text on the fly without buffering the whole document. workerd exposes it on top of lol-html , Cloudflare’s Rust streaming HTML rewriter, through a layer of C++ bindings.
The bug is in those bindings, not in lol-html. When you ask an element for an attributes iterator, the C++ binding grabs a raw pointer into the element’s internal attribute array and reads through it on each next(). Adding attributes with setAttribute grows that array, and once it outgrows its capacity the array reallocates to a new location and the old one is freed , but the iterator is still pointing at the old, now-freed array. The next next() reads from that freed memory:
new HTMLRewriter().on('div', {
  element(el) {
    const iter = el.attributes[Symbol.iterator](); // pointer into backing array
    iter.next();                                   // reads backing array
    for (let i = 0; i < 10000; i++)                // grow attributes...
      el.setAttribute(`x${i}`, 'A'.repeat(100));   // ...until it reallocates

    const leaked = iter.next().value;              // iter → freed array: UAF
  }
});
10. KV SQL bypass → arbitrary deserialization
The other four bugs are memory-corruption. This one is a classic that leads to arbitrary deserialization.
10.1 Durable Objects
Workers are stateless. Each request runs in a fresh, short-lived context, and nothing held in memory survives to the next one. Durable Objects are Cloudflare’s answer to that: a Durable Object is a single, uniquely-addressable instance that stays alive and keeps its state across requests, both in memory and in private, strongly-consistent storage. It’s how you hold persistent, coordinated state on the edge: a chat room, a live document, a counter.
That storage has a newer SQLite backend, and a Worker can reach the same database in two ways:
- the key/value API (
storage.get/put), which stores each value serialized with the structured-clone algorithm, and - the SQL API (
storage.sql.exec), which runs raw SQL against the same database.
The key/value data lives in a reserved SQLite table, _cf_KV, and reading a value back deserializes its bytes with V8’s structured-clone deserializer, including workerd’s handlers for internal types.
10.2 The authorizer bypass
A SQL authorizer guards those internal tables. It rejects any query that touches a _cf_-prefixed table: CREATE, SELECT, INSERT, UPDATE, DROP, all of it. But we found one operation it forgot to check.
The authorizer validates the tables a query references , but not the destination name of a rename. So while every direct query against _cf_KV is rejected, nothing stops you from creating an ordinary table under an allowed name and then renaming it with ALTER TABLE … RENAME TO _cf_KV. You build the table under a name the authorizer permits, fill it with crafted bytes, and rename it into place:
CREATE TABLE kv_tmp (key TEXT, value BLOB);          -- allowed
INSERT INTO kv_tmp VALUES ('k', <attacker bytes>);   -- crafted payload
ALTER TABLE kv_tmp RENAME TO _cf_KV;                 -- not checked → now KV
A later key/value read (storage.get('k')) then feeds those attacker-controlled bytes straight into workerd’s internal deserializers, exactly the untrusted input they were never meant to handle.
We didn’t continue from here. The point is the attack surface. A malicious Worker can control the bytes fed to V8’s deserializer , which will deserialize any object it supports, including workerd’s own internal types. And while we stopped there, the surface is worth stressing: that deserializer was built for trusted, in-process data, and unlike V8’s parser and JIT, it isn’t fuzzed for hostile input. That makes it a very strong attack surface, and a well-worn path to type confusion and memory corruption.
Part III – The full chain and its impact
11. Cross-tenant secret theft (Workers)
Cloudflare Workers run the same workerd and the same many-tenants-one-process model from §2. Different customers’ Workers run as separate V8 isolates inside one OS process, sharing one address space and one native (tcmalloc) heap. The isolate is the only wall between them, and that wall is in V8, not on the native heap.
Figure 10 – Cross-tenant OOB read
So the URLPattern read from §7 isn’t just a crash, it’s a way for a Worker you deploy to read another tenant’s memory out of that shared heap. Here is how that out-of-bounds read becomes a private key read from a different Worker. Everything below operates on the tcmalloc heap , outside the cage and the memory-protection keys (§5).
11.1 The strategy
Recall the primitive from §7. The read goes one entry past the end of nameList, treats those 24 bytes as a kj::String { ptr, size, disposer }, and returns the bytes at ptr. So if we control whatever sits right after nameList, we control that fake kj::String, and reading one attacker-chosen kj::String is reading any address we point it at:
Figure 11 – Fake kj::String read primitive
That is the basic primitive. What we actually want is to sweep another tenant’s memory for secrets, to read anywhere in the process, and to do it with as little heap spraying as possible. To get there we need three things:
- Break ASLR. Leak a real heap address, so we know where to read.
- Control the
ptrof the fakekj::String. So we can read the bytes at any address we choose. - Make it repeatable. Read one address after another without re-shaping the heap each time.
11.2 Sizing nameList
One lever first, because it makes the rest easier. nameList’s size is ours to choose. Its length is just the number of capture groups the pattern declares, so padding the pattern with extra groups grows the kj::Vector<kj::String> to whatever size we want. tcmalloc places allocations by size class, so choosing nameList’s size chooses the neighborhood it lands in, and picking the size class is what makes landing our own allocations right next to it reliable.
11.3 Defeating ASLR
A read is only useful once we know where to aim it, and ASLR hides that. To beat it we just need to leak any one real heap address. The out-of-bounds read already returns whatever the fake kj::String’s ptr points at, so if we arrange for ptr to point at a location that itself holds a heap pointer, the read hands that pointer’s bytes back to us as a string:
Figure 12 – Leaking a heap pointer
So we need an object right after nameList with two things:
ptr(first 8 bytes) , points at a heap pointer, so dereferencing it leaks a heap address.size(next 8 bytes) , a small, valid length: not zero, not a pointer, just short enough that the read returns a sane string.
We didn’t find a real object whose layout already satisfies both, so as a last resort we turned to the tcmalloc free list , and it has two properties that fit perfectly:
- The first 8 bytes of a freed chunk are the
nextpointer (to the next free chunk), which is requirement #1. - The rest of the chunk, including bytes 8–15, is left untouched by the free, so a
sizewe wrote there earlier stays put. That is requirement #2.
So what we can do is allocate a chunk right after nameList, write size = 8 into its bytes 8–15, and free it. The free turns its first 8 bytes into a next pointer to the next free chunk, while our size = 8 survives:
Figure 13 – Freelist next-pointer overwrite
The read hands back that heap pointer as bytes. Since tcmalloc aligns its heap to a 1 GB boundary, one leaked pointer gives us the heap base.
11.4 A repeatable read with VFS files
ASLR gives us an address. Now we want to read many, to sweep the heap. The problem is doing that without re-shaping every time. If reading a new address meant a fresh allocation, we’d have to land it next to nameList again on each read. What we need instead is an allocation we can keep in place and change in-place , so we just rewrite the target pointer and read again.
The best fit we found is a workerd API called VFS , a virtual (memory-only) filesystem. A VFS file’s contents are a native kj::heapArray on the tcmalloc heap, and crucially we can overwrite those contents at will without reallocating. It also lets us pick the file’s size, so we match nameList’s size class and a sprayed file lands right after it.
The idea is to shape the heap once so a VFS file lands right after nameList, then read any address by rewriting that file’s bytes in place and calling exec() again, with no re-shaping per read:
Figure 14 – Repeatable read via VFS
(This works because nameList is allocated when the URLPattern is constructed , but the out-of-bounds read only fires later on exec(), so the shaped layout persists across reads.)
11.5 Reading another Worker’s secret
From here it’s just a sweep. We walk the heap with the repeatable read and look for bytes that look like a secret, in the PoC, Bearer sk…-style API tokens, until we find one belonging to a co-located Worker.
12. Sandbox escape: from the zlib UAF to host RCE
The second demo stays inside Code Mode and goes all the way to native code on the host, starting from the zlib use-after-free of §8.
12.1 Improving the primitive
Recall what §8 gives us, broken into the pieces we’ll build on:
- A use-after-free write. When
params()flushes, zlib writes through the stalenext_outinto the output buffer, after that buffer has been freed and its slot can be reused. - A controllable allocation size. We choose the size of the output buffer, which decides which freed slot the write targets and what we can spray into it.
Our primitive, then:
Figure 15 – Reusing the freed buffer
And the write isn’t clean. The first 5 bytes of every flush are compression metadata.
Two improvements make it precise:
1. The offset of the write. workerd’s write() lets us choose where in the output buffer zlib starts writing. Alongside the buffer it takes an output offset , and zlib sets next_out = buffer + offset, so the write lands at freed + offset, a precise spot inside the reused object instead of always at its start.
2. The size of the write. We also keep the flush small, down to a single 8-byte field, so the write overwrites exactly the field we’re aiming at, rather than splattering the whole object around it.
Together that turns a blunt write at the top of the buffer into a small write landing exactly on a field we pick:
Figure 16 – Flush at chosen offset
12.2 From use-after-free to repeatable read/write
You might still be wondering how an imprecise write is exploitable at all. We control where it lands, but not the bytes. The trick with this kind of primitive is to stop caring about the bytes. Instead of writing a value, you find a “strong” object and overwrite its size / length field. You don’t need the exact bytes, you just need to make that length bigger. A bloated length turns the object’s own bounded read/write into an out-of-bounds read/write, and that you can build on.
The strong object we use is, again, a VFS file , but this time we corrupt the file’s metadata (the FileImpl object that tracks where the file’s data lives and how long it is), not the file’s contents:
Figure 17 – FileImpl metadata layout
With a FileImpl in the freed slot, we aim the UAF write at offset 0x20 so it lands on data.size and inflates the length.
Why does a bigger data.size matter? The file’s data lives at data.ptr, and data.size is the length workerd treats as its bounds, any read or write through the file API is allowed as long as it stays within [0, data.size) of data.ptr. Normally data.size matches the real buffer, so the file stays in bounds. After we inflate it, that bound now covers the real buffer and whatever heap follows it, so a file read or write past the real buffer still passes workerd’s bounds check and is carried out normally, even though it now reaches into adjacent memory:
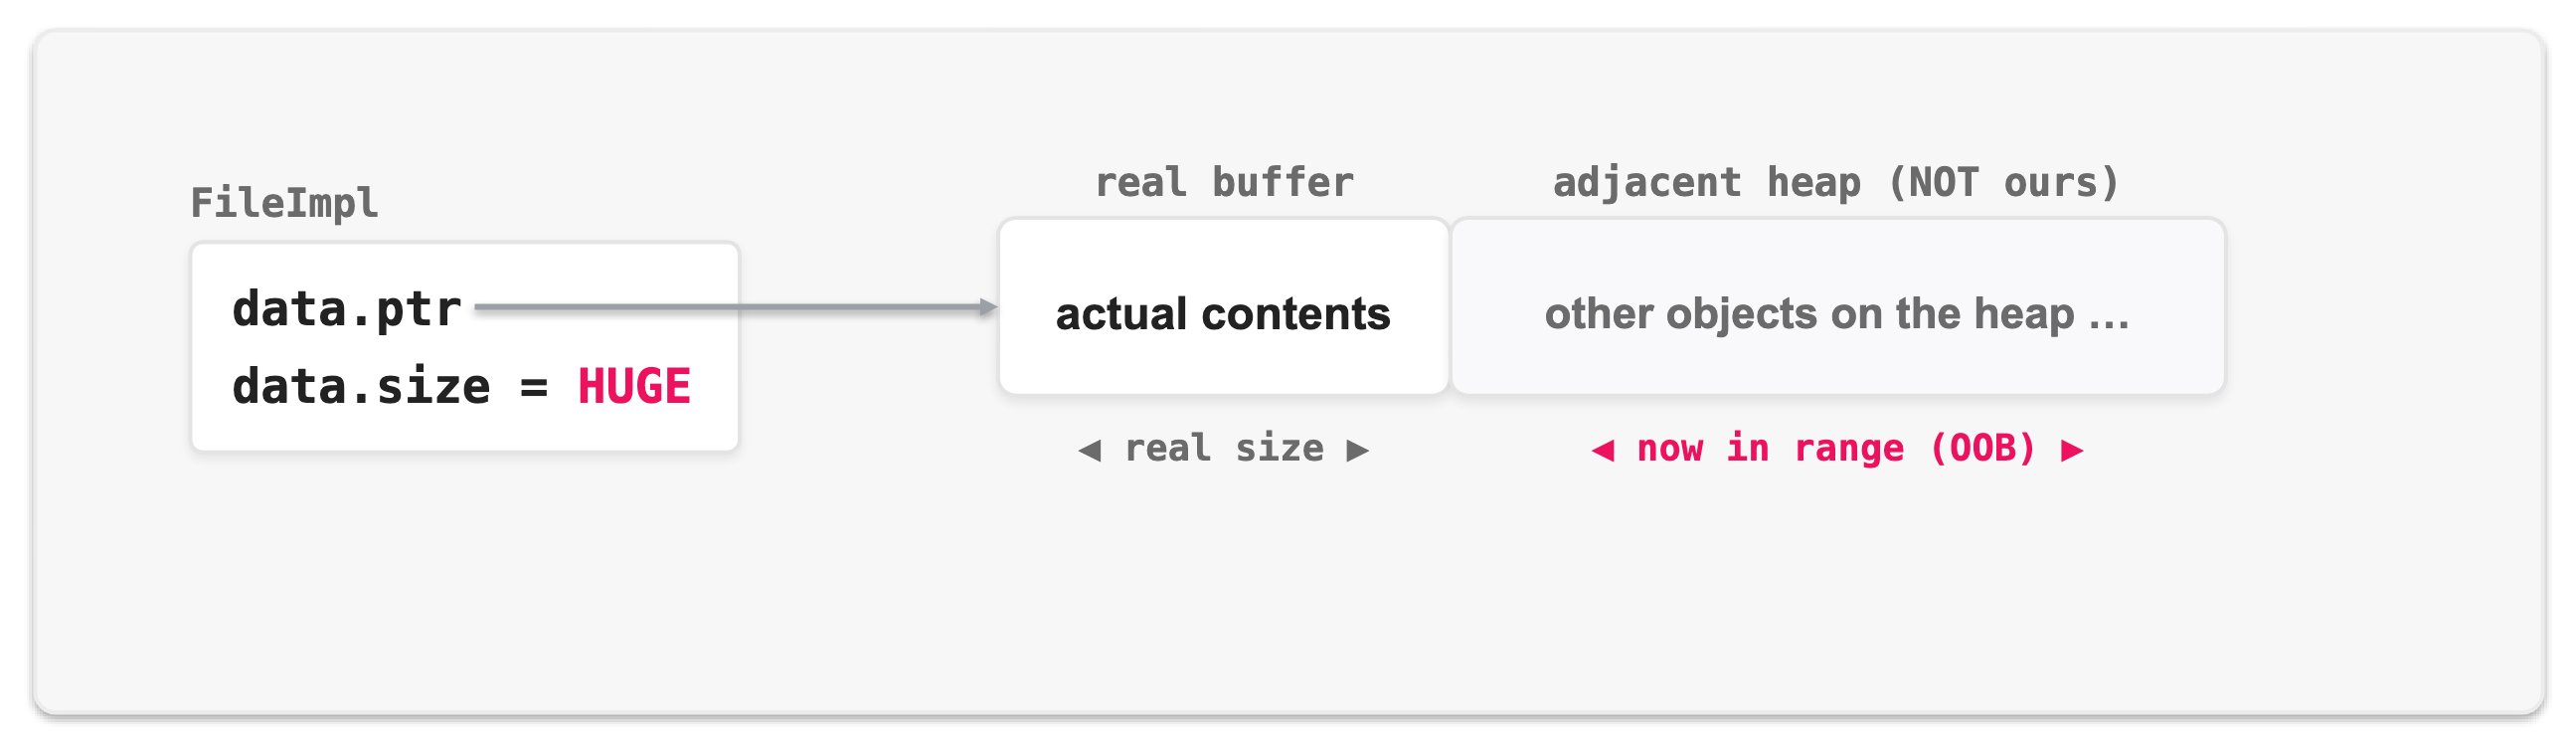
Figure 18 – Inflating data.size out-of-bounds
And the file API makes that precise. Node’s fs read/write take a position argument (the file offset to read or write at, passed straight to the call, no separate seek), plus a length, so we can land exactly on any spot at data.ptr + position. To read 8 bytes from an out-of-bounds offset:
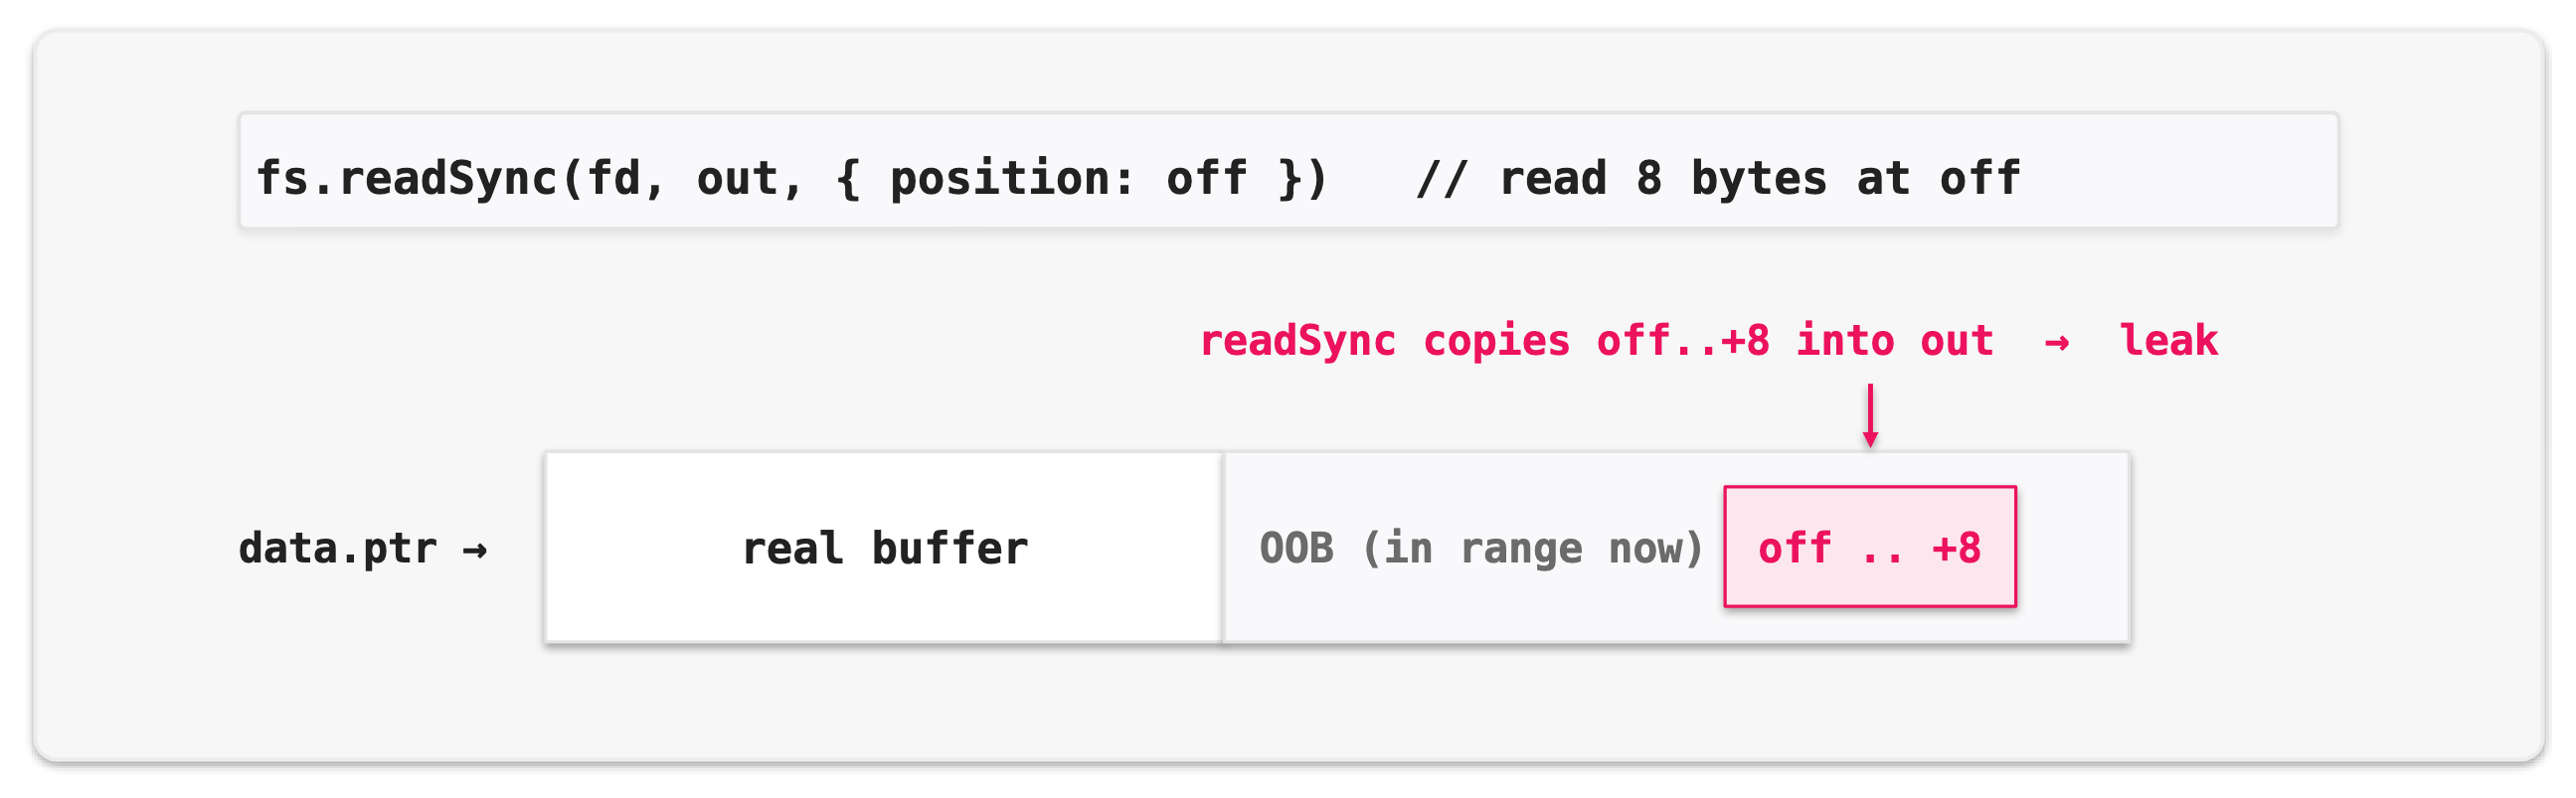
Figure 19 – OOB read via readSync
And to write 8 bytes at an out-of-bounds offset. Here the bytes are ours, it’s an ordinary file write:
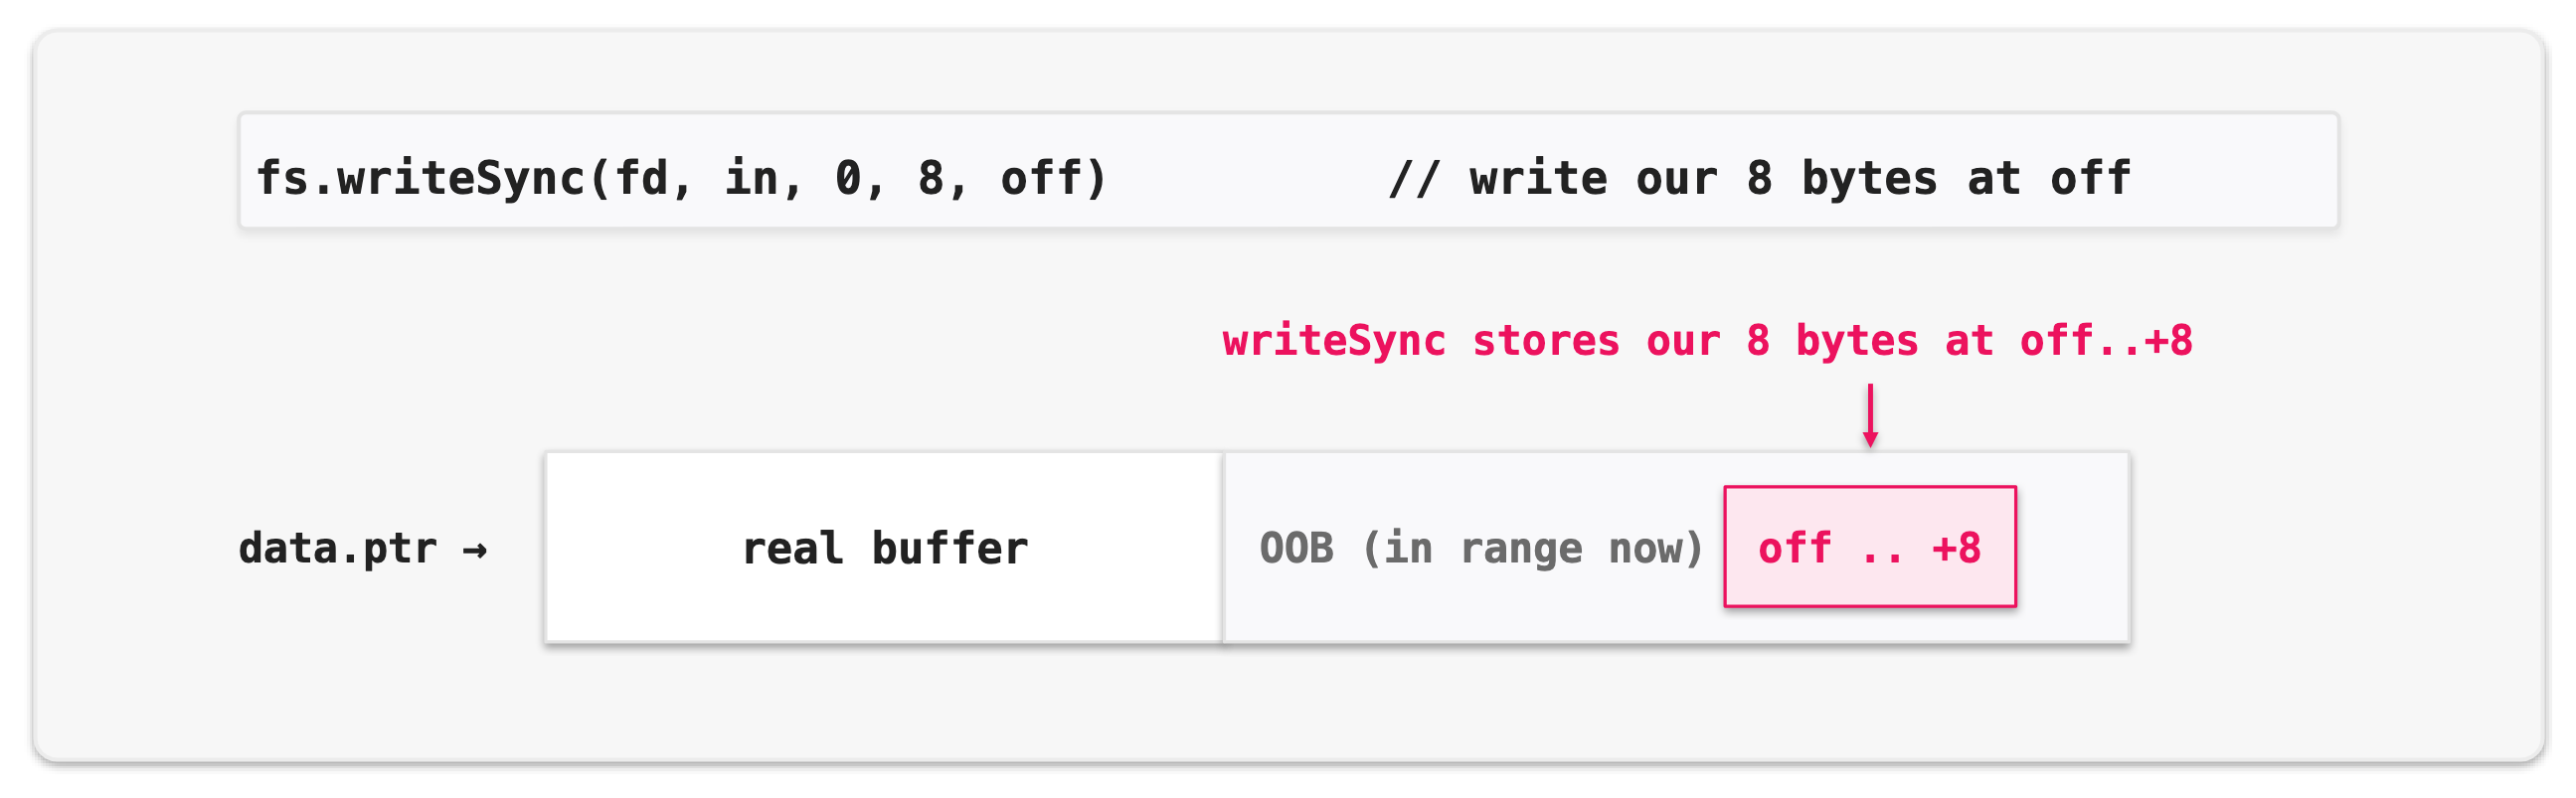
Figure 20 – OOB write via writeSync
So one inflated length turns the VFS file into an out-of-bounds read and write at any offset across the heap.
12.3 Arbitrary read/write
OOB across adjacent heap is strong, but it only reaches forward from one buffer and the exact distances depend on the layout. We upgrade it to a clean, anywhere-in-the-process read/write with a second FileImpl.
The idea is to use the OOB write from the inflated file to reach a second FileImpl sitting further along the heap, and overwrite its data.ptr with any address we want. That second file’s metadata now says “your contents live at <address>”, so an ordinary read or write of the second file reads or writes that address :
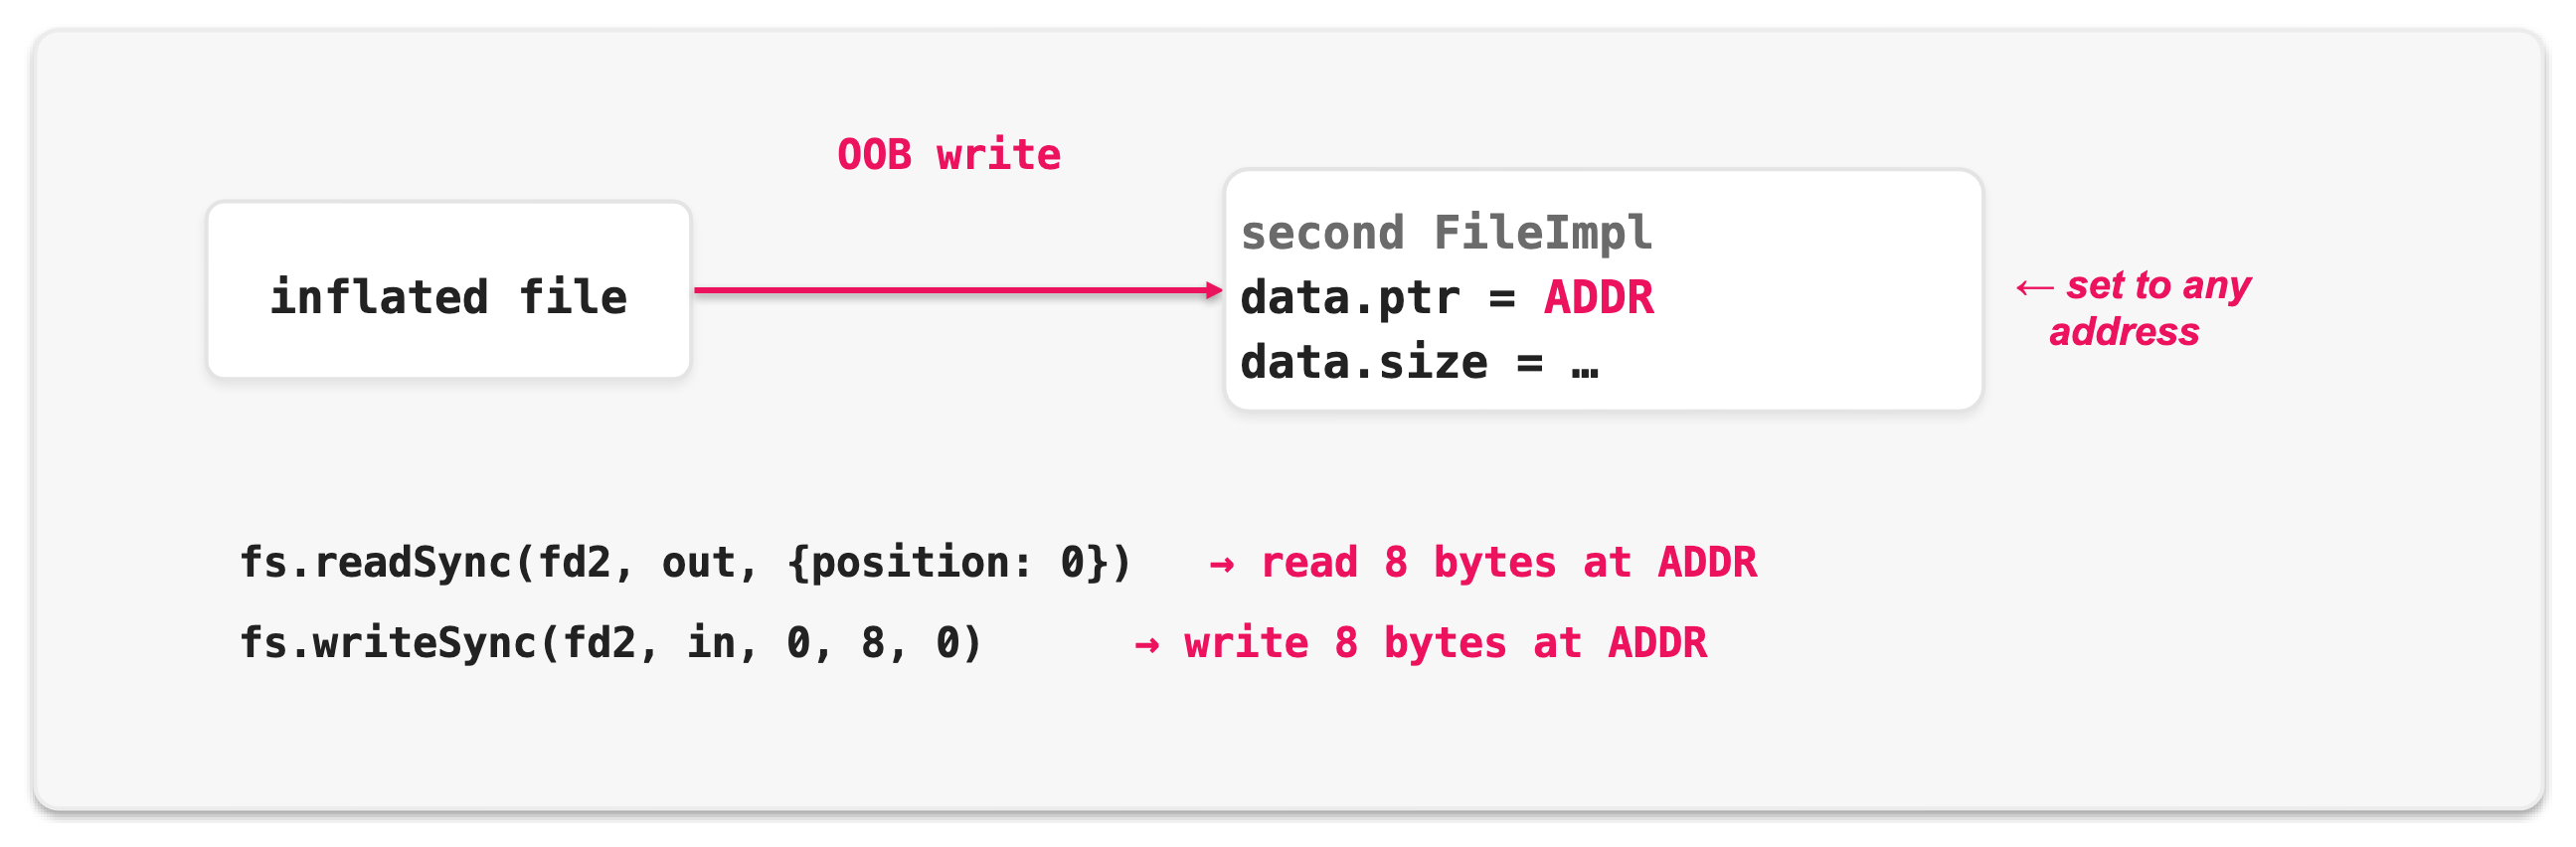
Figure 21 – Arbitrary read/write primitive
And it’s repeatable. To hit a new address we just rewrite the second file’s data.ptr through the first file again and read/write once more, with no re-triggering the bug. That gives us a stable arbitrary 64-bit read and write across the whole process, the same shape of primitive we built for the cross-tenant read in §11.
12.4 To native code
On the self-hosted build the V8 sandbox is off , which makes the finish almost trivial. Normally turning a memory read/write into code execution means defeating W^X with a ROP chain and chasing per-version gadget offsets. Here we don’t have to. With the sandbox off, workerd reserves V8’s code region as a 256 MB read-write-execute (RWX) mapping at a fixed address, 0xaaaaf0000000, present from process startup, no leak required. So we skip ROP entirely.
The finish is simple. Use the arbitrary write to drop ARM64 shellcode (a reverse shell) into that RWX region, then redirect a function pointer to it. The pointer we hijack belongs to the zlib stream itself, the native write callback that handle.write() invokes (reached through the z_stream, which we locate via its avail_in field). We overwrite that callback’s target with our shellcode address and then call handle.write() once more. Instead of running zlib’s write path, control jumps to the shellcode, native code in the host process, out of the V8 isolate entirely.
Cage-off caveat. This chain was built against a self-hosted workerd compiled with the V8 sandbox off , which lets ArrayBuffer backing stores and native C++ objects share one heap, exactly what the FileImpl overlap relies on (and how Code Mode runs, §5). The underlying UAF is independent of the cage, but with the cage on this specific FileImpl technique would not work as-is. Reaching RCE there would need a different post-UAF path.
Part IV – Takeaways and disclosure
13. Defensive takeaways
- The engine is not the whole boundary. Hardening V8 and shipping the cage is necessary, not sufficient. Every native API reachable from untrusted JS is part of the boundary.
- Glue layers deserve first-class security review. JSG marshals lifetimes and pointers across the JS/native seam. That’s exactly where UAFs and missing bounds checks live. It had a fraction of V8’s scrutiny.
- Native allocations need their own threat model. tcmalloc free-list behavior, VFS buffers, and
kjcontainers live outside the cage. If the cage is your isolation story, the things it doesn’t cover are your attack surface. - Agent-generated code is normal code. In Code Mode the model writing exploit-shaped TypeScript isn’t an exceptional event, it’s the intended mode of operation. Prompt injection is a code-execution entry point, and should be modeled as one.
Disclosure timeline
All five vulnerabilities were reported to Cloudflare through HackerOne under coordinated disclosure.
| Date | Event |
|---|---|
| February 1, 2026 | 4 of the 5 vulnerabilities reported via HackerOne (zlib UAF, HTMLRewriter UAF, both URLPattern OOB reads) |
| March 11, 2026 | Cloudflare rated two of them Critical (zlib UAF, HTMLRewriter UAF) |
| March 12, 2026 | The 5th, the KV SQL-bypass → deserialization, reported |
| Aug 5–6, 2026 | Public reveal at Black Hat USA 2026 (Mandalay Bay) |
Cloudflare’s responses and confirmations:
- Two rated Critical. Cloudflare rated the zlib use-after-free and the HTMLRewriter use-after-free as Critical.
- Production reach. Cloudflare confirmed that the bugs reproduce on Cloudflare production , with one exception. The original URLPattern out-of-bounds read (
urlpattern_original) does not trigger there (the Ada-backed standard URLPattern does). - The cage doesn’t cover the heap we used. Cloudflare confirmed our central claim, that the tcmalloc native heap is outside both the V8 sandbox (cage) and the memory-protection keys. Exactly the memory every primitive in this post operates on.
- Fix. Cloudflare’s managed Workers were fixed in production, and workerd v1.20260619.1 closes all of these bugs for self-hosted deployments. As of now, Cloudflare has not assigned CVEs.
Links
- Cloudflare Q1 2026 earnings call (May 7, 2026), “Developers on Cloudflare’s platform increased to more than 5.5 million…”: https://www.theglobeandmail.com/investing/markets/stocks/NET/pressreleases/1904486/cloudflare-q1-earnings-call-highlights/
- “go from no traffic at all to millions of requests per second instantly”: https://blog.cloudflare.com/workerd-open-source-workers-runtime/
- “More than 10% of all requests flowing through our network today use Cloudflare Workers”: https://blog.cloudflare.com/cloudflare-workers-serverless-week/
- “LLMs are better at writing code to call MCP, than at calling MCP directly” : https://blog.cloudflare.com/code-mode/
- “workerd is Open Source under the Apache License version 2.0” (post dated 2022-09-27) : https://blog.cloudflare.com/workerd-open-source-workers-runtime/
- “we prohibit the sandboxed worker from talking to the Internet. The global fetch() and connect() functions throw errors” : https://blog.cloudflare.com/code-mode/
- only two published security advisories, both Moderate : https://github.com/cloudflare/workerd/security/advisories
- “The ‘layer 2’ sandbox uses Linux namespaces and seccomp to prohibit all access to the filesystem and network” : https://blog.cloudflare.com/mitigating-spectre-and-other-security-threats-the-cloudflare-workers-security-model/
- no public link, Cloudflare coordinated-disclosure correspondence. Cloudflare confirmed there are no MPK protection keys on the tcmalloc allocations.