NVIDIA Nemotron 3.5 Lightning 现已登陆 Amazon SageMaker JumpStart
英文标题:NVIDIA Nemotron 3.5 Lightning now available in Amazon SageMaker JumpStart
NVIDIA 面向高调用量 Agent 工作负载打造的开放模型 Nemotron 3.5 Lightning,现已可通过 Amazon SageMaker JumpStart 部署。该模型采用混合 Mixture-of-Experts(MoE)架构,总参数量为 300 亿、每次推理仅激活 30 亿参数,支持最长 100 万 token 上下文,可在单张受支持 GPU 上运行。NVIDIA 称,该模型在高调用量 Agent 工作负载中可实现最高 4 倍吞吐量,并将任务完成速度提升最高 30%。开发者可在 SageMaker Studio、Hugging Face 或 SageMaker Python SDK 中部署 NVFP4 和 BF16 版本,并可通过 NVIDIA NeMo 针对垂直领域工具、流程和策略进行后训练。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 229.3 KB
 265.1 KB
 269.9 KB
 223.1 KB
 232.0 KB
 508.2 KB
 6.7 KB
 77.8 KB
 153.9 KB
 69.7 KB
 64.6 KB
中文
NVIDIA Nemotron 3.5 Lightning 专为高调用量 Agent 工作负载所需的快速、专用模型执行而设计。借助 Amazon SageMaker JumpStart 上的 NVIDIA Nemotron 3.5 Lightning,您可以使用一款专为高调用量 Agent 工作负载打造的开放模型。
通过此次发布,您无需自行配置推理服务基础设施,即可从 Amazon SageMaker JumpStart 部署 Nemotron 3.5 Lightning。NVIDIA 将 Lightning 描述为同类模型中为始终在线 Agent 提供支持的最快开放模型。它在高调用量 Agent 工作负载中可实现最高 4 倍的吞吐量,以及最高 30% 更快的任务完成速度。该模型总参数量为 300 亿,但仅激活 30 亿参数,可在一张受支持的 GPU 上运行。因此,Agent 工作流中重复性、专用性的步骤无需依赖前沿规模的基础设施即可运行。本文将介绍如何从 SageMaker JumpStart 部署 Nemotron 3.5 Lightning。
NVIDIA Nemotron 3.5 Lightning 概述
Nemotron 3.5 Lightning 是一款公开可用的基础模型,由 NVIDIA 的前沿模型 Nemotron 3 Ultra 蒸馏而来,并与 Nemotron Coalition 共同开发。它采用混合 Mixture-of-Experts(MoE)架构,专门针对主流 Agent 框架中的 Agent 工具调用进行了训练。该模型使用开放数据集训练,并以开放模型形式发布,因此您可以对其进行定制、拥有最终生成的权重,并将其部署到 Agent 运行的任何环境中。
下表汇总了 NVIDIA Nemotron 3.5 Lightning 的主要规格和性能特征。
| 规格 | 详情 |
|---|---|
| 架构 | 混合 Mixture-of-Experts(MoE) |
| 参数量 | 总计 300 亿 / 激活 30 亿 |
| 上下文长度 | 最长 100 万 token |
| 输入 / 输出 | 文本输入,文本输出 |
| 推测解码 | DFlash |
| 吞吐量 | 针对高调用量 Agent 工作负载最高提升 4 倍 |
| 任务完成 | 最高提速 30% |
| 蒸馏来源 | NVIDIA Nemotron 3 Ultra |
并非每个 Agent 步骤都需要前沿模型
始终在线的 Agent 会持续工作:收集上下文、观察环境、基于已知信息进行推理并采取行动。这些步骤中有许多可能涉及模型调用,但并非都需要同等水平的能力。规划多阶段工作流或编排子 Agent,可能需要前沿级别的推理能力;而对告警进行分类、从表单提取字段,或依据策略核查记录,通常可由更小型的专用模型处理。这类任务可能占据调用量中的很大比例。
在很多情况下,使用单一大型模型处理所有由模型支持的步骤,可能会为本可由更小型专用模型完成的工作增加前沿模型的成本和延迟。采用模型系统(system-of-models)方法,则可以将每个步骤路由到适合该任务的模型。
Nemotron 3.5 Lightning 专为这一模型系统中高调用量的一端而构建。其 MoE 架构在每次前向传播时激活 300 亿参数中的 30 亿,有助于在长时间、多轮会话中维持高吞吐量。DFlash 推测解码可进一步降低每个 token 的延迟。100 万 token 的上下文窗口可让 Agent 在长时间运行的会话中保留累积状态,无需反复重新建立上下文基础。
如果您的技术栈包含 NVIDIA NeMo Switchyard,它可以在您选定的模型池中路由单个工作流步骤。对于速度和领域专用准确性均适配的高调用量专用步骤,可以选择 Lightning。
推理与 Agent 基准测试中的准确性
根据已发布的评测结果,NVFP4 在许多任务上的表现仍接近 BF16,如下表所示。NVIDIA 表示,用于产出这些结果的评测配方和命令已发布在 NeMo Gym 中。准确性结果由 NVIDIA 在一致的测试框架下测得,可能与其他供应商自行报告的数据不同。
下表比较了 Nemotron 3.5 Lightning 的 BF16 和 NVFP4 版本在关键推理和 Agent 基准测试中的表现。
| 基准测试 | BF16 | NVFP4 |
|---|---|---|
| MMLU Pro | 81.94 | 81.62 |
| GPQA Diamond | 75.44 | 75.57 |
| SWE-bench Verified | 51.56 | 52.80 |
| PinchBench | 85.37 | 83.43 |
| IFBench | 71.88 | 72.88 |
| AA-LCR | 52.00 | 49.19 |
针对领域准确性进行定制
企业可以使用 NVIDIA NeMo 对模型进行后训练,以适配领域专用工具、工作流和策略,然后将生成的模型部署到其选择的环境中。本次发布的 SageMaker JumpStart 模型卡不提供 JumpStart 定制功能。
企业应用场景
Lightning 专为 Agent 工作流中的专用、高频工作而构建:
- 个人 Agent:处理电子邮件、日历、项目和预订事务的长时间运行助手,并可选择在本地运行以处理上下文数据。
- 金融服务:从文档中提取数据、检查策略规则、监控风险信号,以及生成结构化摘要。
- 网络安全运营:扩充告警信息、分类事件、查询日志、验证控制措施、关联指标,并为分析师准备调查结果。
- 电信:分流网络告警、优化网络配置,以及回答账单相关问题。
- 零售:扩充商品目录、处理库存和履约异常、协助商品发现,以及处理订单、退货和会员忠诚度相关问题。
SageMaker JumpStart 快速入门
您可以通过 Amazon SageMaker JumpStart 部署 Nemotron 3.5 Lightning,无需手动配置推理服务框架。
前提条件
开始前,请确保您具备:
- 一个 AWS 账户。
- 针对 SageMaker JumpStart 正确配置范围的权限。
- 足够的 GPU 实例服务配额,例如
ml.g6e.12xlarge、ml.p4d.24xlarge或ml.p5.48xlarge。
**重要提示:**部署该模型会创建一个处于运行状态时持续计费的 SageMaker AI 终端节点。有关详细信息,请参阅 Amazon SageMaker AI 定价。完成后请删除终端节点,以避免持续产生费用。
使用 SageMaker Studio 部署
- 打开 Amazon SageMaker Studio。
- 在导航窗格中,选择 SageMaker JumpStart。
- 搜索 Nemotron 3.5 Lightning。
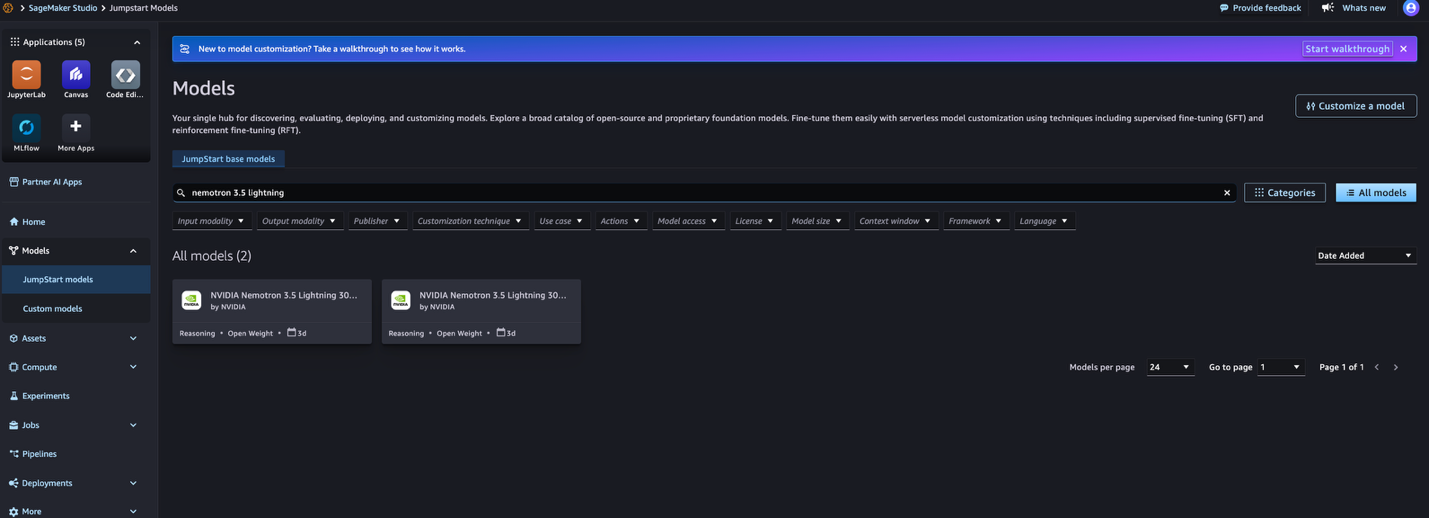
图 1:在 SageMaker JumpStart 中搜索 Nemotron 3.5 Lightning
- 选择模型卡。NVFP4 模型 ID 为
huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4。如需 BF16,请使用huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16。
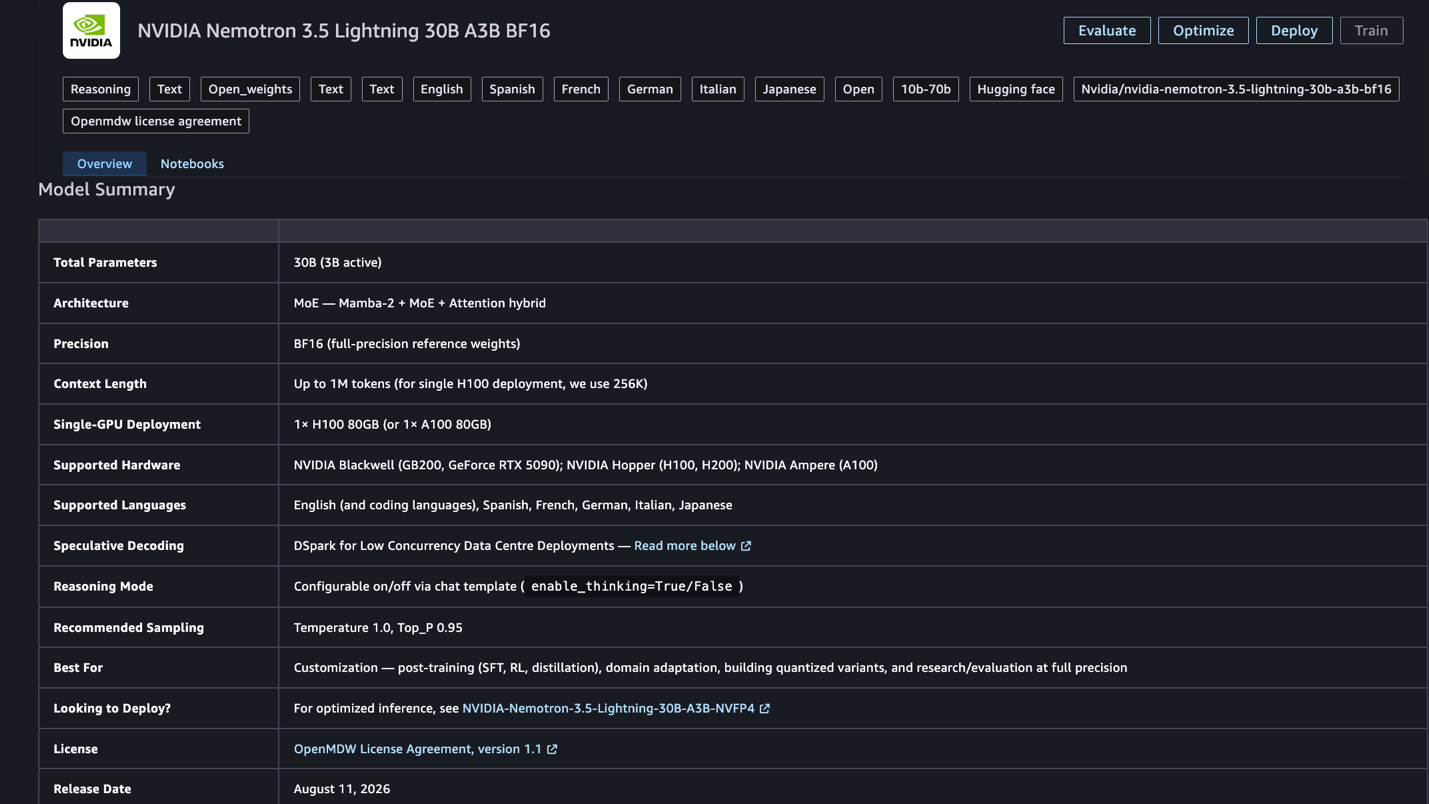
图 2:SageMaker JumpStart 中的 Nemotron 3.5 Lightning 模型卡
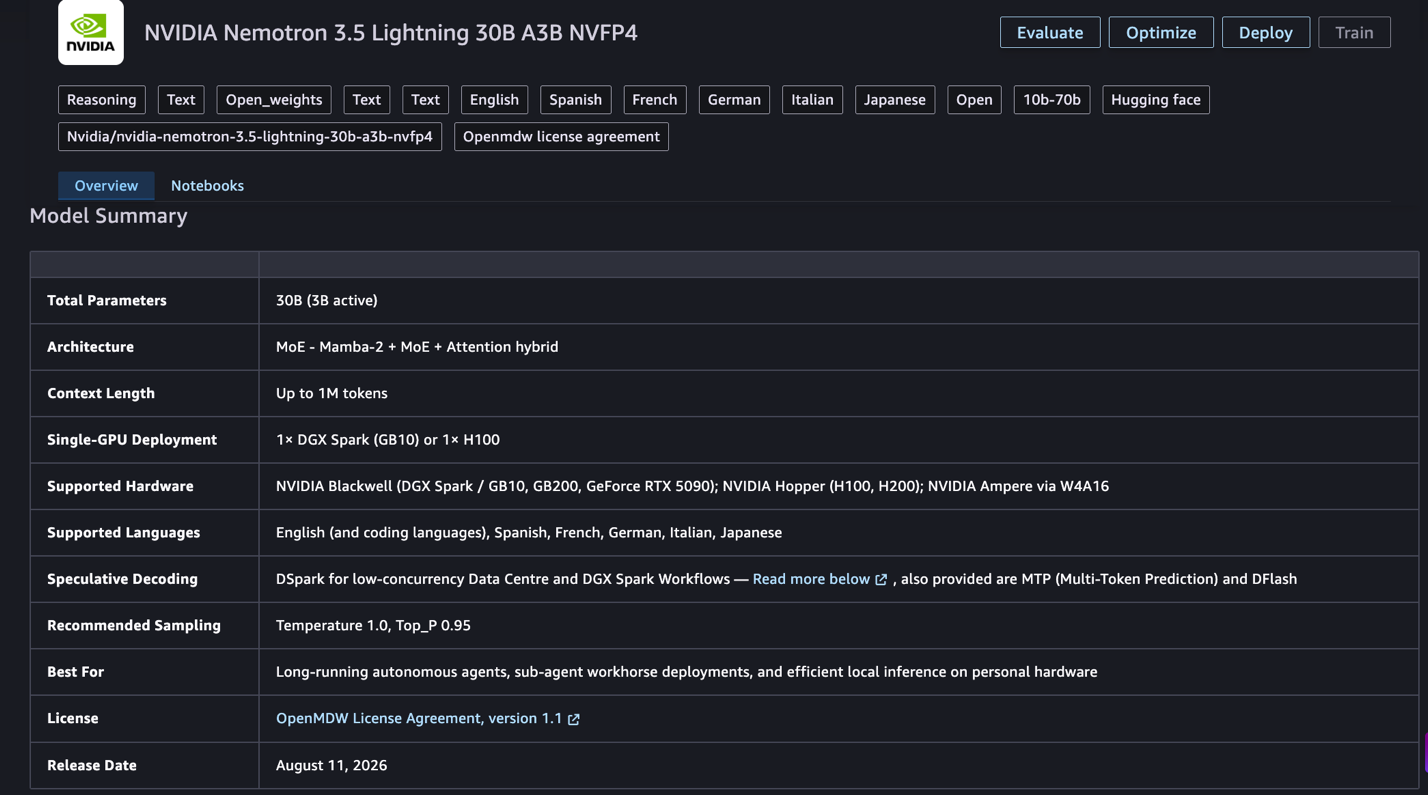
图 3:Nemotron 3.5 Lightning 的模型卡详情
- 选择 Deploy。
- 选择实例类型,例如
ml.g6e.24xlarge。
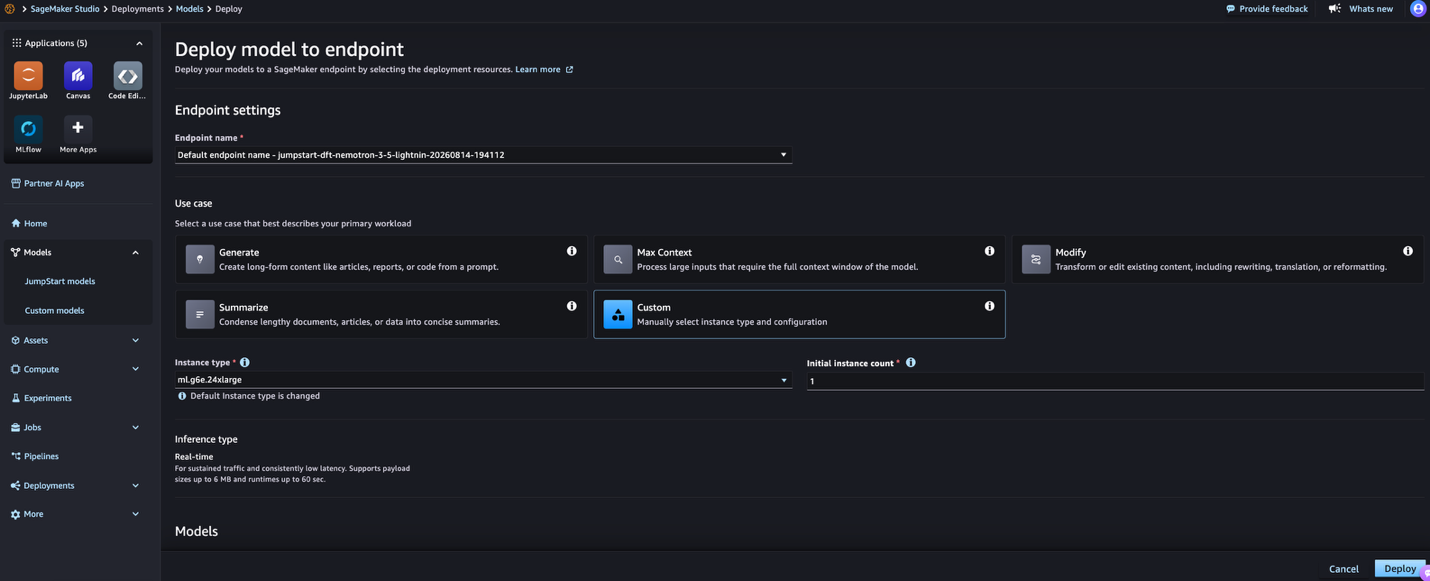
图 4:选择用于部署的实例类型
- 检查部署设置。默认设置足以满足大多数使用场景。
- 选择 Deploy 创建终端节点。
- 在运行推理之前,等待终端节点状态显示为 InService。
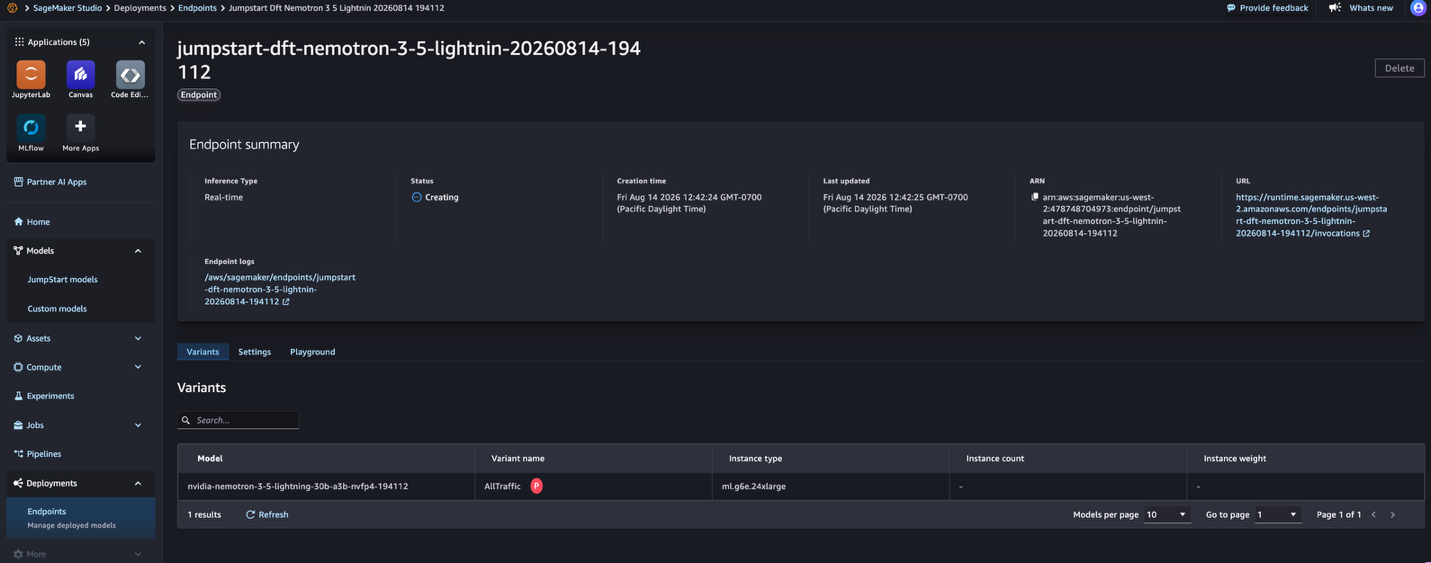
图 5:显示 InService 的终端节点状态
从 Hugging Face 部署
您也可以通过 NVIDIA Nemotron 3.5 Lightning 的 Hugging Face 模型页面,将其部署到 Amazon SageMaker AI。在 Hugging Face 模型页面中,选择 Deploy,选择 Amazon SageMaker AI,然后选择 Deploy on SageMaker AI。这将打开 SageMaker AI 部署工作流,您可在其中配置并部署模型。
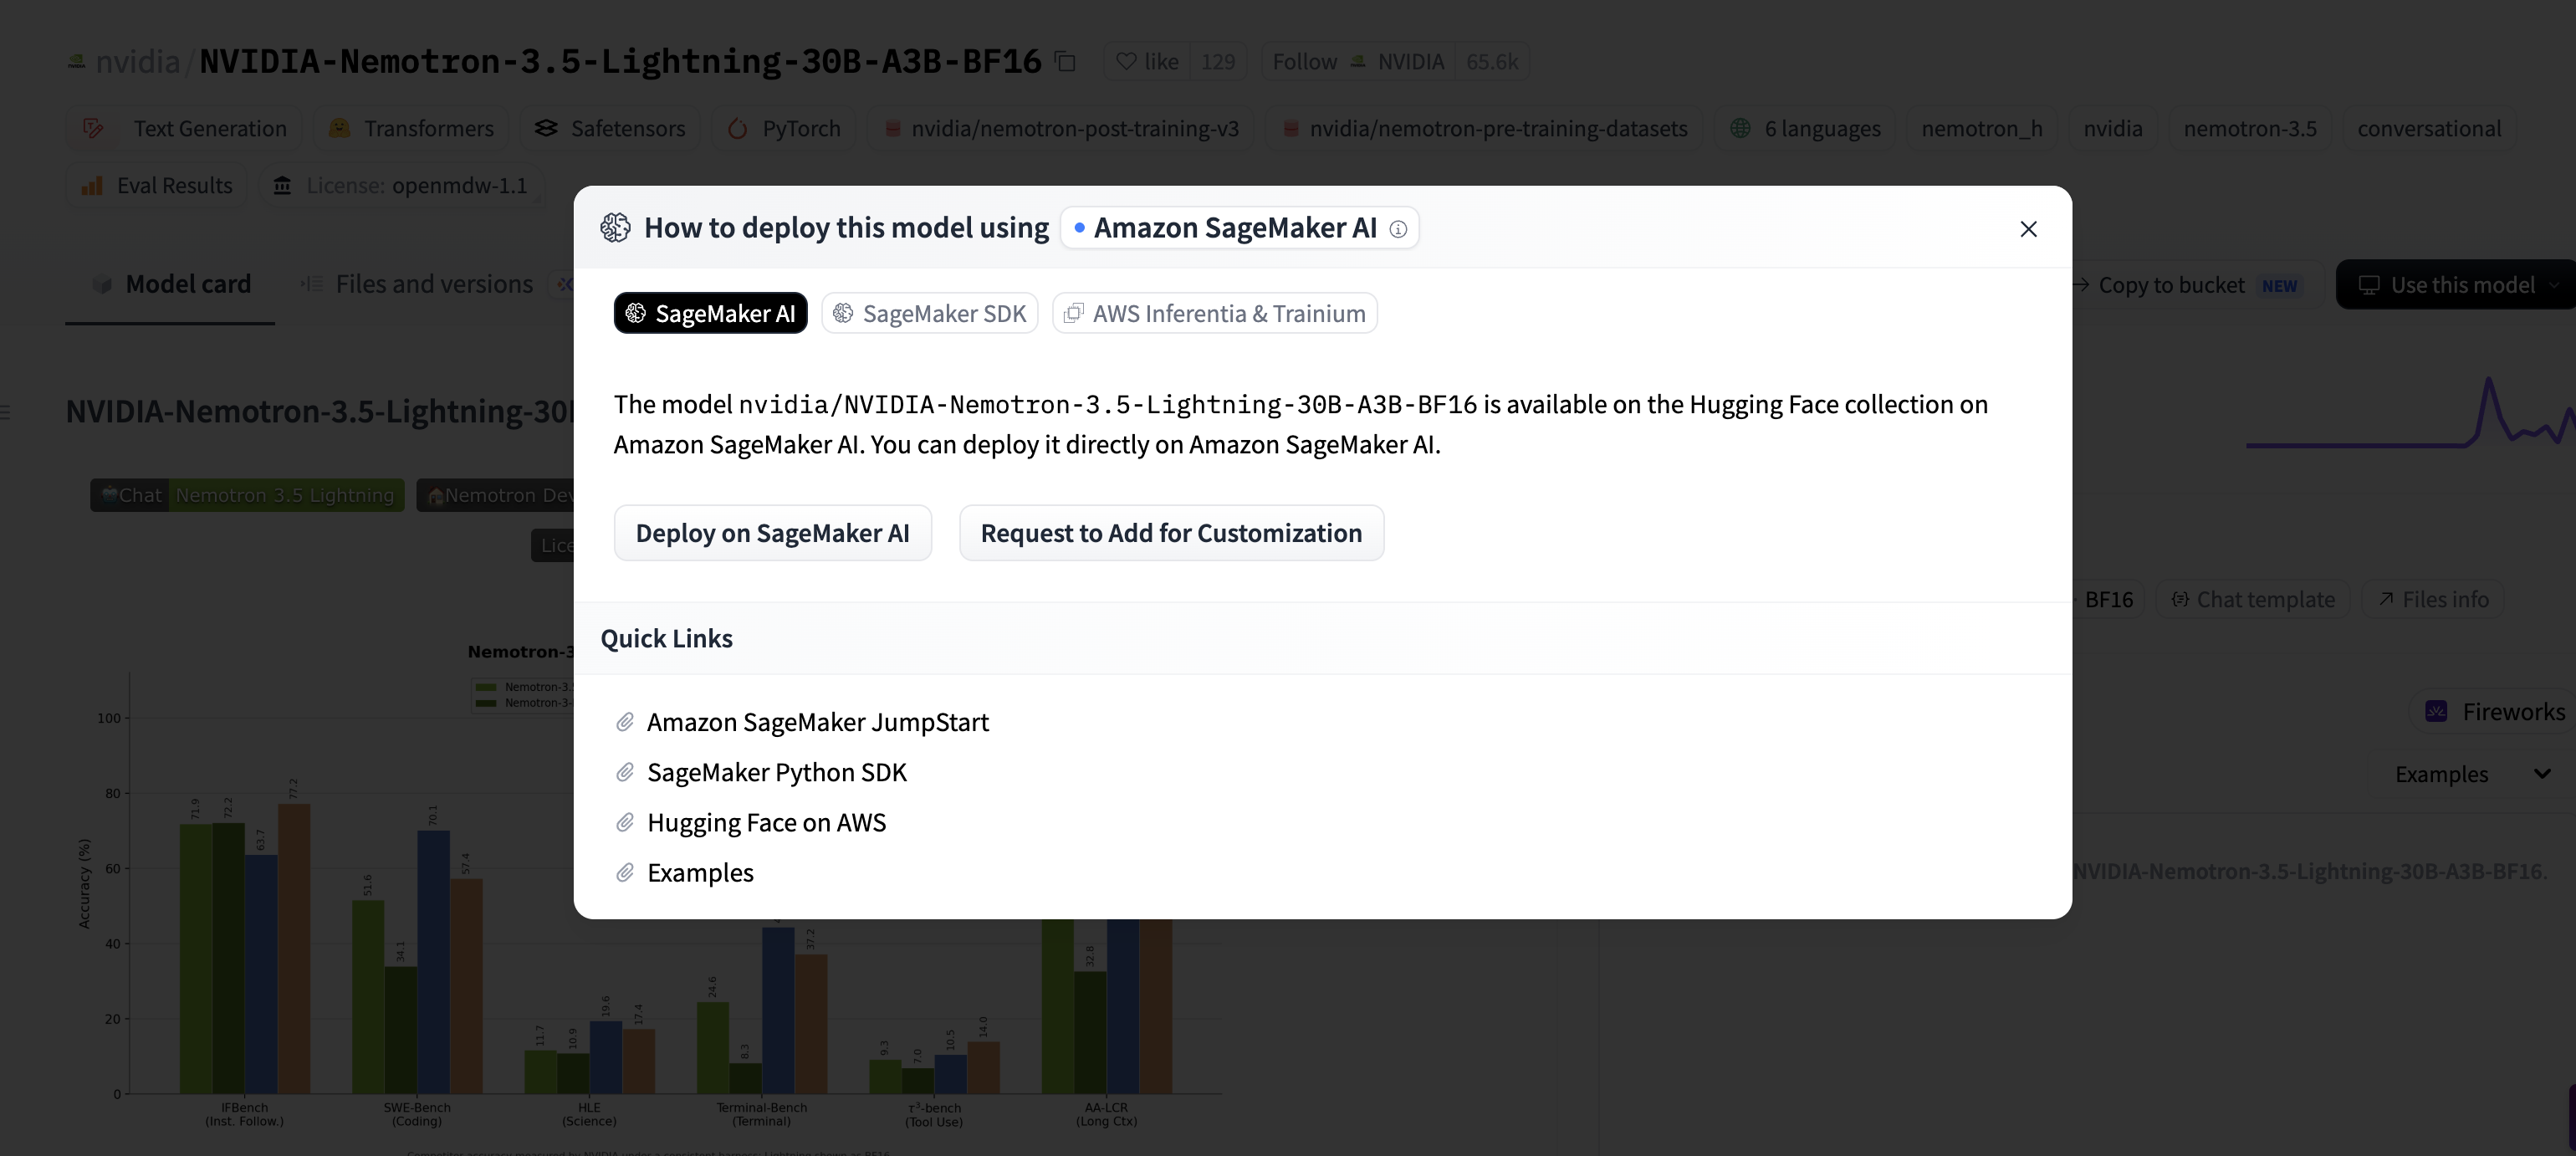
图 6:从 Hugging Face 模型页面部署
使用 SageMaker Python SDK 部署
通过 SageMaker JumpStart,您可以使用 NVFP4 和 BF16 版本。以下示例使用 NVFP4 模型 ID huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4。如需 BF16,请使用 huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16。
from sagemaker.jumpstart.model import JumpStartModel

model_id = "huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4"
model_version = "*"

model = JumpStartModel(model_id=model_id, model_version=model_version)
predictor = model.deploy()
清理资源
为避免不必要的费用,请在完成后删除 SageMaker AI 终端节点:
predictor.delete_endpoint()
结论
NVIDIA Nemotron 3.5 Lightning 将快速、专用的 Agent 执行能力带到了 Amazon SageMaker JumpStart。NVIDIA 表示,该模型可针对高调用量的专用工作实现最高 4 倍吞吐量和最高 30% 的任务完成速度提升。其混合 MoE 架构、30 亿激活参数、DFlash 推测解码和 100 万 token 上下文,均针对高调用量 Agent 工作流而设计。由于该模型是开放模型且支持定制,您可以针对自己的工具和策略进行后训练,并保持对最终模型的控制权。
Nemotron 3.5 Lightning 可支持个人助手、金融服务、安全运营、电信和零售等领域的专用 Agent 工作负载。您今天即可从 SageMaker JumpStart 部署该模型。
要开始使用,请在 Amazon SageMaker JumpStart 中搜索 Nemotron 3.5 Lightning。有关部署指南,请参阅 Amazon SageMaker AI Developer Guide 中的 JumpStart foundation model usage。
作者简介
Venu Kanamatareddy
Venu 是 Amazon Web Services 的 AI 专项解决方案架构师,负责帮助高速成长的 AI 原生初创公司设计、扩展和运营生产级 AI 系统。
Evan Kravitz
Evan 是 Amazon Web Services 的软件工程师,负责 SageMaker JumpStart。他关注机器学习与云计算的交汇领域。Evan 获得了康奈尔大学学士学位和加州大学伯克利分校硕士学位。2021 年,他在 ICLR 会议上发表了一篇关于对抗性神经网络的论文。闲暇时,Evan 喜欢烹饪、旅行以及在纽约市跑步。
Vivek Gangasani
Vivek 是 Amazon Web Services 的高级机器学习解决方案架构师。他与机器学习初创公司合作,在 AWS 上构建和部署 AI/ML 应用。他目前专注于提供 MLOps、ML 推理和低代码机器学习解决方案。他曾参与多个领域的项目,包括自然语言处理和计算机视觉。
Naidile Murali
Naidile 是 AWS 的产品经理,常驻华盛顿州贝尔维尤。她专注于提升 Amazon SageMaker AI 上的 AI/ML 开发者体验,包括入门流程、IDE 连接和 GPU 容量管理。在加入 AWS 之前,她曾在汇丰银行担任软件工程师。Naidile 拥有乔治城大学 MBA 学位。
English / 原文
NVIDIA Nemotron 3.5 Lightning is designed for the fast, specialized model execution required by high-volume agentic workloads. With NVIDIA Nemotron 3.5 Lightning on Amazon SageMaker JumpStart, you can access an open model designed for high-volume agentic workloads.
With this launch, you can deploy Nemotron 3.5 Lightning from Amazon SageMaker JumpStart without configuring the serving infrastructure yourself. NVIDIA describes Lightning as the fastest open model in its class for powering always-on agents. It delivers up to 4x higher throughput and up to 30% faster task completion on high-volume agentic workloads. At 30B total parameters with only 3B active, it can run on a single supported GPU. Repetitive, specialized steps in agent workflows can therefore run without frontier-scale infrastructure. In this post, we show you how to deploy Nemotron 3.5 Lightning from SageMaker JumpStart.
Overview of NVIDIA Nemotron 3.5 Lightning
Nemotron 3.5 Lightning is a publicly available foundation model distilled from NVIDIA’s frontier Nemotron 3 Ultra and developed with the Nemotron Coalition. It uses a hybrid Mixture-of-Experts (MoE) architecture and is trained specifically for agentic tool use across popular agent harnesses. It is trained on open datasets and released as an open model, so you can customize it, own the resulting weights, and deploy it wherever your agents run.
The following table summarizes the key specifications and performance characteristics of NVIDIA Nemotron 3.5 Lightning.
| Specification | Details |
|---|---|
| Architecture | Hybrid Mixture-of-Experts (MoE) |
| Parameters | 30B total / 3B active |
| Context length | Up to 1M tokens |
| Input / Output | Text in, text out |
| Speculative decoding | DFlash |
| Throughput | Up to 4x higher for high-volume agentic workloads |
| Task completion | Up to 30% faster |
| Distilled from | NVIDIA Nemotron 3 Ultra |
Not every agent step needs a frontier model
Always-on agents work continuously: they gather context, observe their environment, reason over what they know, and act. Many of these steps can involve model calls, but they do not all require the same level of capability. Planning a multi-stage workflow or orchestrating sub-agents can demand frontier-level reasoning. Classifying an alert, extracting fields from a form, or checking a record against a policy can often be handled by a smaller, specialized model. These tasks can account for a large share of call volume.
In many cases, running all model-backed steps through a single large model can add frontier-model cost and latency to work that a smaller, specialized model can handle. A system-of-models approach can instead route each step to a model suited to the task.
Nemotron 3.5 Lightning is built for the high-volume end of that system. Its MoE architecture activates 3B of 30B parameters per forward pass, helping maintain high throughput across long, multi-turn sessions. DFlash speculative decoding can further reduce per-token latency. The 1M-token context window allows an agent to carry accumulated state across a long-running session without repeated re-grounding.
If NVIDIA NeMo Switchyard is part of your stack, it can route individual workflow steps across your chosen model pool. Lightning can be selected for high-volume specialized steps where its speed and domain-specific accuracy are a good fit.
Accuracy across reasoning and agentic benchmarks
Across the published evaluations, NVFP4 remains close to BF16 on many tasks, as summarized in the following table. NVIDIA reports that the evaluation recipes and commands used to produce these results are published in NeMo Gym. Accuracy results were measured by NVIDIA under a consistent harness and may differ from vendors’ self-reported numbers.
The following table compares the BF16 and NVFP4 variants of Nemotron 3.5 Lightning across key reasoning and agentic benchmarks.
| Benchmark | BF16 | NVFP4 |
|---|---|---|
| MMLU Pro | 81.94 | 81.62 |
| GPQA Diamond | 75.44 | 75.57 |
| SWE-bench Verified | 51.56 | 52.80 |
| PinchBench | 85.37 | 83.43 |
| IFBench | 71.88 | 72.88 |
| AA-LCR | 52.00 | 49.19 |
Customizing for domain accuracy
Organizations can post-train the model with NVIDIA NeMo for domain-specific tools, workflows, and policies, then deploy the resulting model in their chosen environment. The SageMaker JumpStart model card for this launch does not expose JumpStart customization.
Enterprise use cases
Lightning is built for the specialized, high-frequency work inside agent workflows:
- Personal agents : Long-running assistants handling email, calendar, projects, and bookings, with the option to run locally for contextual data.
- Financial services : Extracting data from documents, checking policy rules, monitoring risk signals, and preparing structured summaries.
- Cyber security operations : Enriching alerts, classifying incidents, querying logs, validating controls, correlating indicators, and preparing findings for analysts.
- Telecom : Triaging network alarms, optimizing network configurations, and answering billing questions.
- Retail : Enriching product catalogs, resolving inventory and fulfillment exceptions, assisting product discovery, and handling order, return, and loyalty questions.
Getting started with SageMaker JumpStart
You can deploy Nemotron 3.5 Lightning through Amazon SageMaker JumpStart without manually configuring the serving framework.
Prerequisites
Before you begin, make sure you have:
- An AWS account.
- Appropriately scoped permissions for SageMaker JumpStart.
- Sufficient service quota for GPU instances (for example,
ml.g6e.12xlarge,ml.p4d.24xlarge, orml.p5.48xlarge).
Important: Deploying this model creates a SageMaker AI endpoint that incurs charges while running. For details, see Amazon SageMaker AI pricing. Delete your endpoint when finished to avoid ongoing charges.
Deploy using SageMaker Studio
- Open Amazon SageMaker Studio.
- In the navigation pane, choose SageMaker JumpStart.
- Search for Nemotron 3.5 Lightning.
Figure 1: Searching for Nemotron 3.5 Lightning in SageMaker JumpStart
- Select the model card. The NVFP4 model ID is
huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4. For BF16, usehuggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16.
Figure 2: The Nemotron 3.5 Lightning model card in SageMaker JumpStart
Figure 3: Model card details for Nemotron 3.5 Lightning
- Choose Deploy.
- Select your instance type (for example,
ml.g6e.24xlarge).
Figure 4: Selecting an instance type for deployment
- Review the deployment settings. The defaults are sufficient for most use cases.
- Choose Deploy to create the endpoint.
- Wait for the endpoint status to show InService before running inference.
Figure 5: Endpoint status showing InService
Deploy from Hugging Face
You can also deploy NVIDIA Nemotron 3.5 Lightning to Amazon SageMaker AI from its Hugging Face model page. On the Hugging Face model page, choose Deploy , select Amazon SageMaker AI , and then choose Deploy on SageMaker AI. This opens the SageMaker AI deployment workflow, where you can configure and deploy the model.
Figure 6: Deploying from the Hugging Face model page
Deploy using the SageMaker Python SDK
With SageMaker JumpStart, you can access the NVFP4 and BF16 variants. The following example uses the NVFP4 model ID huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4. For BF16, use huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-bf16.
from sagemaker.jumpstart.model import JumpStartModel

model_id = "huggingface-reasoning-nemotron-3-5-lightning-30b-a3b-nvfp4"
model_version = "*"

model = JumpStartModel(model_id=model_id, model_version=model_version)
predictor = model.deploy()
Clean up
To avoid unnecessary charges, delete the SageMaker AI endpoint when you are done:
predictor.delete_endpoint()
Conclusion
NVIDIA Nemotron 3.5 Lightning brings fast, specialized agent execution to Amazon SageMaker JumpStart. NVIDIA reports up to 4x higher throughput and up to 30% faster task completion for high-volume specialized work. Its hybrid MoE architecture, 3B active parameters, DFlash speculative decoding, and 1M-token context are designed for high-volume agent workflows. Because the model is open and designed for customization, you can post-train it for your own tools and policies and retain control of the resulting model.
Nemotron 3.5 Lightning can support specialized agent workloads across personal assistants, financial services, security operations, telecom, and retail. You can deploy it today from SageMaker JumpStart.
Get started by searching for Nemotron 3.5 Lightning in Amazon SageMaker JumpStart. For deployment guidance, see JumpStart foundation model usage in the Amazon SageMaker AI Developer Guide.
About the authors
Venu Kanamatareddy
Venu is an AI Specialist Solutions Architect at Amazon Web Services, where he works with high-growth, AI-native startups to design, scale, and operationalize production-grade AI systems.
Evan Kravitz
Evan is a software engineer at Amazon Web Services, working on SageMaker JumpStart. He is interested in the confluence of machine learning with cloud computing. Evan received his undergraduate degree from Cornell University and master’s degree from the University of California, Berkeley. In 2021, he presented a paper on adversarial neural networks at the ICLR conference. In his free time, Evan enjoys cooking, traveling, and going on runs in New York City.
Vivek Gangasani
Vivek is a Senior Machine Learning Solutions Architect at Amazon Web Services. He works with Machine Learning startups to build and deploy AI/ML applications on AWS. He is currently focused on delivering solutions for MLOps, ML Inference and low-code ML. He has worked on projects in different domains, including Natural Language Processing and Computer Vision.
Naidile Murali
Naidile is a Product Manager at AWS based in Bellevue, WA. She focuses on enhancing the AI/ML developer experience on Amazon SageMaker AI, including onboarding, IDE connectivity, and GPU capacity management. Prior to AWS, she worked as a software engineer at HSBC. Naidile holds an MBA from Georgetown University.