KnowledgeForge:从 ITSM 工单“坟场”中挖掘知识金矿
英文标题:KnowledgeForge: mining gold from the ITSM ticket graveyard
KnowledgeForge 将已解决的 ITSM 事件工单聚类并生成新的知识库文章和根因分析文档,同时持续治理既有知识库中的重复、过时和低质量内容。该方案使用 Amazon Bedrock 生成和改写内容,使用 Amazon S3 Vectors 进行每客户隔离的向量检索与重复检测,并通过 AWS Step Functions 编排大规模治理工作流。系统采用“生成—治理—人工审核—向量回灌”的闭环,使后续生成可参考已审核的既有知识,减少重复和虚构内容。对开发者而言,该架构提供了可复用的多租户文档处理、RAG、批处理编排与容错模式。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 115.8 KB
 79.0 KB
 9.2 KB
 7.5 KB
 8.6 KB
 7.2 KB
 50.5 KB
中文
KnowledgeForge 旨在从 IT 服务管理(ITSM)工单“坟场”中挖掘知识金矿:那些已经解决、却从未沉淀为知识库文章的事件工单。企业 IT 支持团队每月会解决数千张工单,而每张工单都包含有价值的信息:症状、根本原因,以及工程师采取的修复措施。这些知识被锁在工单历史中,下一位遇到相同问题的工程师无法找到它。
知识库本身则面临相反的问题。它会不断增长,但也会变得混乱:重复文章不断累积,内容逐渐过时,质量则取决于每篇文章由谁、在何时编写。寻找答案的支持工程师需要在大量几乎相同的草稿中艰难筛选,其中有些准确,有些却已经落后当前产品版本三个版本。
我们构建 KnowledgeForge,正是为了同时弥合这两端的缺口。它从已解决的事件工单中挖掘新的文章;与此同时,它还会治理现有知识库,按类型整理文章、删除重复项、评估质量,并重写薄弱内容。知识经理会审核并批准结果,因此最终上线的内容仍由人工负责。
本文介绍 KnowledgeForge 背后的 AWS 构建模块:Amazon Bedrock 用于生成和改进内容;作为 Amazon Simple Storage Service(Amazon S3)能力的 Amazon S3 Vectors 用于重复检测;AWS Step Functions 用于编排。对于每项服务,我们都会说明选择原因并链接至相关文档。如果你正在基于生成式 AI构建大规模文档处理管道,可以复用这些模式。
前提条件
要部署并跟随本方案操作,你需要:
- 一个可访问 Amazon Bedrock 的 AWS 账户,并已启用 Anthropic Claude Sonnet 4.5 和 Amazon Titan Text Embeddings V2 模型的访问权限。
- 具备创建本方案所用资源的权限:Amazon S3 存储桶和 Amazon S3 Vectors 索引、AWS Step Functions 状态机、AWS Lambda 函数、运行在 AWS Fargate 上的 Amazon Elastic Container Service(Amazon ECS) 服务、Amazon DynamoDB 表、Amazon Simple Queue Service(Amazon SQS) 队列、Amazon Bedrock Guardrails,以及 AWS Key Management Service(AWS KMS)密钥。
- 已安装 AWS Cloud Development Kit(AWS CDK),并熟悉 Amazon Bedrock、AWS Step Functions、Amazon ECS 和向量嵌入。
- 来自 aws-samples/sample-knowledgeforge 仓库的代码。
闭环式知识库生命周期
KnowledgeForge 由两个相互供给的子系统构成。生成子系统将聚类后的事件工单转化为新的文章草稿。当一组相关工单描述同一个问题时,系统会根据该聚类撰写一篇知识库文章和一份根因分析文档。治理子系统随后会将每篇文章——无论是新生成的还是已有的——依次经过四个步骤:按类型分类、检查重复项、评估质量,以及改进薄弱内容。完成的文章会被发送至 ServiceNow,供知识经理审核。
这个循环之所以闭合,是因为治理流程会为每篇文章存储一个向量,而生成流程会在编写任何新内容之前读取这些向量。下图展示了两个子系统如何连接。
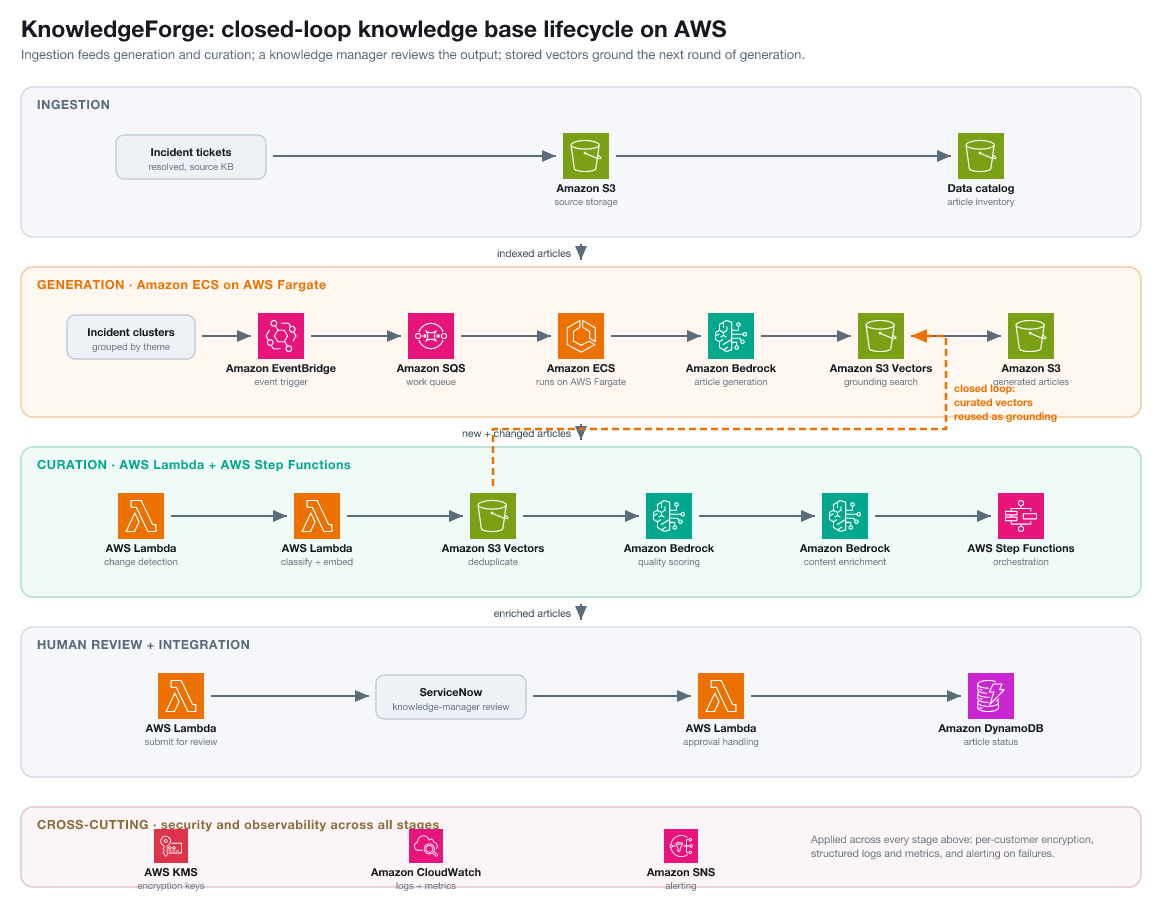
图 1:闭环式知识库生命周期。摄取流程为生成和治理提供输入,知识经理审核输出结果,治理流程则为每篇文章生成嵌入,以便生成流程在下一次运行时将这些向量作为依据复用。
从高层次看,一篇文章会经历五个阶段:
- 摄取 —— 已解决工单和现有文章进入 Amazon S3,并由数据目录跟踪。
- 生成 —— 聚类后的工单在运行 AWS Fargate 的 Amazon ECS 上转化为新的文章草稿。
- 治理 —— 每篇文章通过运行于 AWS Lambda 上的 AWS Step Functions 工作流完成分类、去重、质量评分和改进。
- 人工审核 —— 富化后的文章被发送至 ServiceNow,由知识经理批准;审核决定会回写至 Amazon DynamoDB。
- 闭环 —— 治理流程将每篇文章嵌入 Amazon S3 Vectors 索引,生成流程在下一次运行时复用这些向量。
这两个子系统运行在不同的计算环境中,原因将在后续章节中随着文章在系统中的流转而说明。
根据事件聚类生成文章
生成流程从共享同一主题的一组工单开始。上游流程会按工单所描述的问题对已解决事件进行分组,并将结果作为 JSON 文件写入 Amazon S3 存储桶,且限定在单个客户范围内。每个主题包含关键词、文章范围,以及工单描述和工作备注的示例。
存储桶中的新文件会向 Amazon SQS 队列发送事件。运行在 AWS Fargate 上的 Amazon ECS 容器会轮询该队列,读取文件,并一次为一个客户处理最多五个主题。
在编写之前,系统会基于现有内容进行约束。对于每个主题,它会从该客户的 Amazon S3 Vectors 索引中检索五篇最相似的现有文章,并将其作为参考上下文传递给模型。这种检索增强生成(RAG)方式能够保持术语一致,并减少虚构的操作步骤。当尚不存在参考文章时,系统仅根据工单数据进行生成,并对其中的操作流程标记为待审核。
生成使用 Amazon Bedrock 中的 Anthropic Claude Sonnet 4.5。对于每个主题,模型会按照固定结构生成两份文档:
- 知识库文章:标题和摘要、症状、根本原因、解决步骤、预防措施和相关主题。
- 根因分析文档:执行摘要、问题描述、客户影响、五个为什么分析、临时解决方案和最终解决方案、纠正与预防措施、关键事件时间线和原因代码。
我们使用 Amazon Bedrock 的响应流式传输,使容器能够在 Token 到达时组装每份文档,而不是等待完整响应返回。
为什么使用容器而不是函数
我们在运行 AWS Fargate 的 Amazon ECS 上执行生成任务,因为这项工作的形态决定了它更适合容器。为一个主题生成两份完整文档可能需要数分钟,而一个繁忙的文件会包含许多主题,因此单个工作单元的运行时间可能很长。该工作负载也以突发形式到达:一段时间较为安静,随后会一次性出现大批任务。一个可根据队列深度扩缩任务数量、并在队列清空后缩容的长时间运行容器服务,非常适合这种模式。
AWS Fargate 符合这一需求。它以无服务器方式运行我们的容器,在主题到达时按需扩展,使团队能够专注于生成逻辑,而不是管理计算容量。每份文档都会以 JSON 形式写入 Amazon S3,为后续治理做好准备。
使用 Amazon S3 Vectors 查找重复文章
治理流程的第一个挑战,是检测某篇文章是否已经存在。重复内容有多种形式:两篇文章使用不同措辞描述相同修复方案;一篇较新的文章取代一篇旧文章;或者工程师复制一篇文章,只修改两行后将其另存为新文章。
我们选择 Amazon S3 Vectors 来解决这一问题。它将嵌入向量直接存储在 Amazon S3 中,因此无需独立的向量数据库。它会在每个向量旁保存元数据,支持按客户过滤,并按查询次数和 GB 容量计费,而不是按持续运行的节点计费。这使得为知识库中的每篇文章保留一个向量在成本上可行。如果你的内容已经存储在 Amazon S3 中,无需新增基础设施即可添加向量搜索。详情请参阅 Amazon S3 用户指南。
关键词匹配无法识别这些重复形式,因此该管道按语义进行匹配。每篇文章都会获得一个由 Amazon Titan Text Embeddings V2 生成的 1,024 维嵌入,并存储在按客户划分的 Amazon S3 Vectors 索引中。向量存储通常用于检索;在这里,同一个索引还兼任重复检测器。系统会为新文章生成嵌入,查询索引以获得最近的现有向量,落在严格余弦距离阈值内的结果即被视为重复。我们从余弦距离 0.05(即相似度不低于 0.95)和 top-K 为 5 开始。我们通过抽样检查被标记的文章对来调优距离阈值,并不断收紧阈值,直到近乎相同的文章能够匹配,同时不会误判仅有关联的文章。更宽松的阈值会产生误判重复项,更严格的阈值则会漏掉改写后的副本。查询只需一次调用,并按当前客户和活跃文章过滤:
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=VECTOR_INDEX,
    queryVector={"float32": embedding},
    topK=TOP_K + 1,  # +1 because the article can match itself
    returnMetadata=True,
    returnDistance=True,
    filter={"$and": [
        {"tenant_id": {"$eq": TENANT_ID}},  # per-customer isolation
        {"status": {"$in": ["UNIQUE", "PENDING"]}},  # ignore retired articles
    ]},
)
matches = [v for v in response.get("vectors", []) if v["key"] != article_id]
当系统发现一对重复文章时,它会保留较新的文章并淘汰过时文章,而不是默认丢弃新文章。最新且准确的版本获胜,这正是支持工程师所期望的行为。
以这种方式复用索引,也有助于处理重试。生成嵌入需要一次模型调用成本。重新运行时,系统会读取已存储的向量,而不是重新计算,从而在批处理重新执行时同时节省时间和 Amazon Bedrock 支出。
使用 AWS Step Functions 大规模编排治理流程
治理流程面向成批文章运行,需要通过编排将任务分配给工作器并从故障中恢复。AWS Step Functions 通过两阶段 Distributed Map 提供这种能力。它管理工作流状态,应用定义中声明的重试和错误处理机制,并将工作分发至各个工作器,无需编写自定义协调代码。关于 Distributed Map 的工作原理,请参阅 AWS Step Functions 开发人员指南。
有两项配置选择值得特别说明。第一,我们将项目处理器设为 STANDARD,而不是 EXPRESS。每篇文章都会发起耗时较长的 Amazon Bedrock 调用,超过 EXPRESS 的 5 分钟限制;而 STANDARD 会保留完整的执行历史,便于调试。第二,我们将 ItemReader 指向 Amazon S3 中的清单文件,而不是以内联方式传递项目,从而保持较小的工作流状态。
Amazon EventBridge 上的每日计划任务会启动运行。一个 AWS Lambda 函数查找存在新增或变更文章的客户,将变更分组为批次,并将每个批次放入 Amazon SQS 先进先出(FIFO)队列。FIFO 队列使用客户 ID 作为消息组键,在多次运行之间按客户为批次排序,因此不同客户仍可并行运行。跨运行排序只是问题的一部分。在单次执行中,第二阶段最多可并发处理 40 个批次,因此 FIFO 本身无法阻止不同批次中的两个重复项发生竞争。真正保护去重的机制是:在每个工作器内,每个批次中的去重操作按顺序执行,而质量评分和内容改进则并行运行。批次内顺序去重、质量评分和改进并行执行,以及 FIFO 提供的跨运行排序,共同确保重复检测的一致性。
调度函数每次拉取一个批次并启动一次 Step Functions 执行。状态机分两个阶段运行,每个阶段都是 Distributed Map,因此批次中的文章可并发处理:
- 分类和嵌入 —— 每篇文章按类型分类,并生成向量嵌入。
- 去重、评分和改进 —— 管道查找重复内容、评估质量,并改进低于阈值的内容。
下图展示了触发链路、两个阶段以及保护运行的容错机制。
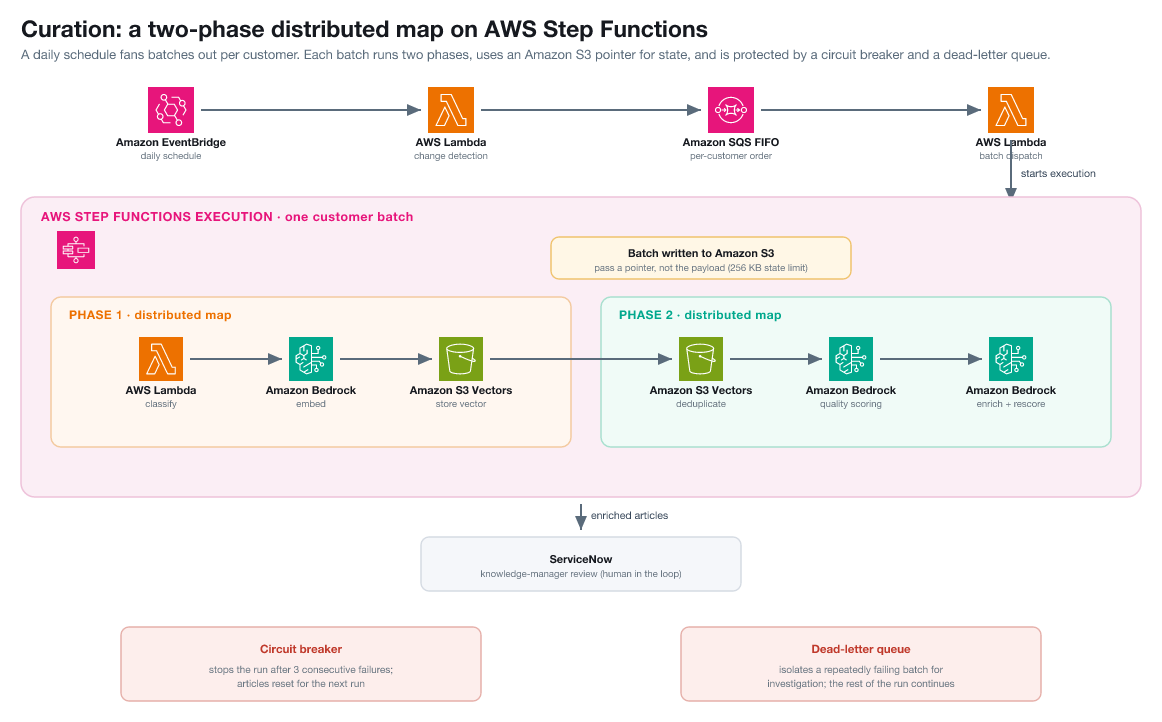
图 2:治理流程作为两阶段 Distributed Map 运行。批次通过 Amazon SQS FIFO 队列按客户排序,文章内容以 Amazon S3 指针而非内联状态传递,熔断器和死信队列可防止问题批次阻塞整个运行。
传递指针,而不是负载
一次 Step Functions 执行会在各状态之间传递状态数据,其上限为 256 KB。带有完整 HTML 正文的知识库文章很容易超过该限制。我们不会通过状态机传递文章内容,而是将批次写入 Amazon S3,只在工作流中传递其位置。每个 Map 工作器都会直接从 Amazon S3 读取所需内容,因此无论文章有多大,状态负载始终保持较小。
Distributed Map 从 Amazon S3 中的清单读取工作项目,而不是从内联状态读取。可容忍失败百分比使运行能够吸收少量有问题的文章,而不会中止整个批次:
"Phase1_ClassifyEmbed": {
    "Type": "Map",
    "ItemProcessor": {
        "ProcessorConfig": { "Mode": "DISTRIBUTED", "ExecutionType": "STANDARD" }
    },
    "ItemReader": {
        "Resource": "arn:aws:states:::s3:getObject",
        "ReaderConfig": { "InputType": "JSON" },
        "Parameters": { "Bu
English / 原文
KnowledgeForge is about mining gold from the IT Service Management (ITSM) ticket graveyard: the resolved incident tickets whose knowledge never reaches a knowledge base article. Enterprise IT support teams resolve thousands of tickets every month, and each one holds something useful: a symptom, a root cause, and the fix an engineer applied. That knowledge stays locked in ticket history, where the next engineer to hit the same problem won’t find it.
The knowledge base itself has the opposite problem. It grows, but it grows messy: duplicate articles pile up, content goes stale, and quality varies depending on who wrote each article and when. A support engineer searching for an answer wades through near-identical drafts, some accurate and some three product versions out of date.
We built KnowledgeForge to work both sides of that gap. It mines resolved incident tickets for new articles. At the same time, it curates the existing knowledge base by sorting articles by type, removing duplicates, scoring their quality, and rewriting weak content. A knowledge manager reviews and approves the result, so a person still owns what goes live.
This post covers the AWS building blocks behind KnowledgeForge: Amazon Bedrock for generation and content improvement, Amazon S3 Vectors, a capability of Amazon Simple Storage Service (Amazon S3), for duplicate detection, and AWS Step Functions for orchestration. For each one, we explain why we chose it and link to the documentation. If you’re building a large-scale document-processing pipeline on generative AI, you can reuse these patterns.
Prerequisites
To deploy and follow along with this solution, you need:
- An AWS account with access to Amazon Bedrock, and access enabled for Anthropic Claude Sonnet 4.5 and Amazon Titan Text Embeddings V2 models.
- Permissions to create the resources this solution uses: Amazon S3 buckets and Amazon S3 Vectors indexes, AWS Step Functions state machines, AWS Lambda functions, Amazon Elastic Container Service (Amazon ECS) services on AWS Fargate, Amazon DynamoDB tables, Amazon Simple Queue Service (Amazon SQS) queues, Amazon Bedrock guardrails, and AWS Key Management Service (AWS KMS) keys.
- The AWS Cloud Development Kit (AWS CDK) installed, and working familiarity with Amazon Bedrock, AWS Step Functions, Amazon ECS, and vector embeddings.
- The code from the aws-samples/sample-knowledgeforge repository.
A closed-loop knowledge base lifecycle
KnowledgeForge is two subsystems that feed each other. Generation turns clustered incident tickets into new draft articles. When a group of related tickets describes the same problem, the system writes a knowledge base article and a root cause analysis document from that cluster. Curation then takes every article, both newly generated and existing, through four steps: classify it by type, check for duplicates, score its quality, and improve weak content. Finished articles go to ServiceNow for knowledge-manager review.
The loop closes because curation stores a vector for every article, and generation reads those vectors back before writing anything new. The following diagram shows how the two subsystems connect.
Figure 1: The closed-loop knowledge base lifecycle. Ingestion feeds generation and curation, a knowledge manager reviews the output, and curation embeds every article so generation can reuse those vectors as grounding on the next run.
At a high level, an article moves through five stages:
- Ingestion – Resolved tickets and existing articles land in Amazon S3, tracked by a data catalog.
- Generation – Clustered tickets become new draft articles on Amazon ECS with AWS Fargate.
- Curation – Each article is classified, deduplicated, quality-scored, and improved through an AWS Step Functions workflow on AWS Lambda.
- Human review – Enriched articles go to ServiceNow for knowledge-manager approval, and the decision is written back to Amazon DynamoDB.
- Closed loop – Curation embeds every article into the Amazon S3 Vectors index, and generation reuses those vectors on the next run.
The two subsystems run on different compute, for reasons the next sections explain as they follow an article through the system.
Generating articles from incident clusters
Generation starts with a cluster of tickets that share a theme. An upstream process groups resolved incidents by the problem they describe and drops the result into an Amazon S3 bucket as a JSON file, scoped to one customer. Each theme carries keywords, an article scope, and a sample of ticket descriptions and work notes.
A new file in the bucket sends an event to an Amazon SQS queue. A container on Amazon ECS with AWS Fargate polls the queue, reads the file, and processes up to five themes at once for a customer.
Before writing, the system grounds itself in what exists. For each theme, it retrieves the five most similar existing articles from that customer’s Amazon S3 Vectors index and passes them to the model as reference context. This Retrieval Augmented Generation (RAG) keeps terminology consistent and reduces invented procedures. When no reference articles exist yet, the system generates from the ticket data alone and flags the procedures for review.
Generation runs on Anthropic Claude Sonnet 4.5 in Amazon Bedrock. For each theme, the model produces two documents with a fixed structure:
- Knowledge base article : Title and summary, symptoms, root cause, resolution steps, prevention, and related topics.
- Root cause analysis document : Executive summary, problem description, customer impact, five-why analysis, workaround and resolution, corrective and preventive actions, timeline of key events, and cause code.
We use response streaming from Amazon Bedrock so the container assembles each document as tokens arrive rather than waiting for the full response.
Why containers instead of functions
We run generation on Amazon ECS with AWS Fargate because of the shape of the work. Generating two full documents for a theme can take several minutes, and a busy file holds many themes, so a single unit of work can run for a long time. The workload also arrives in bursts, quiet for stretches and then a large batch at once. A long-running container service that scales its task count on queue depth, and scales back when the queue drains, fits this pattern well.
AWS Fargate matches this profile. It runs our containers serverlessly, scales on demand as themes arrive, and lets the team focus on the generation logic rather than on managing compute capacity. Each document lands in Amazon S3 as JSON, ready for curation.
Finding duplicate articles with Amazon S3 Vectors
The first curation challenge is detecting whether an article already exists. Duplicates come in several forms. Two articles describe the same fix in different words, a newer article supersedes an older one, or an engineer copies an article, changes two lines, and saves it as new.
We chose Amazon S3 Vectors to solve this. It stores embedding vectors directly in Amazon S3, which avoids a standalone vector database. It keeps metadata alongside each vector for per-customer filtering and bills per query and per gigabyte rather than per running node. That makes it affordable to keep a vector for every article in the library. If you already store content in Amazon S3, you can add vector search without new infrastructure. For details, see the Amazon S3 User Guide.
Keyword matching misses these duplicate forms, so the pipeline matches on meaning. Every article gets a 1,024-dimension embedding from Amazon Titan Text Embeddings V2, stored in a per-customer Amazon S3 Vectors index. A vector store usually powers retrieval. Here the same index doubles as a duplicate detector. A new article is embedded, the index is queried for the nearest existing vectors, and anything inside a tight cosine-distance threshold counts as a duplicate. We start with a cosine distance of 0.05 (a similarity of 0.95 or higher) and a top-K of 5. We tuned the distance by sampling flagged pairs and tightening it until near-identical articles matched without catching merely related ones. A looser threshold produced false duplicates, and a tighter one missed reworded copies. The query is one call, filtered to the current customer and to active articles:
response = s3vectors.query_vectors(
    vectorBucketName=VECTOR_BUCKET,
    indexName=VECTOR_INDEX,
    queryVector={"float32": embedding},
    topK=TOP_K + 1,  # +1 because the article can match itself
    returnMetadata=True,
    returnDistance=True,
    filter={"$and": [
        {"tenant_id": {"$eq": TENANT_ID}},  # per-customer isolation
        {"status": {"$in": ["UNIQUE", "PENDING"]}},  # ignore retired articles
    ]},
)
matches = [v for v in response.get("vectors", []) if v["key"] != article_id]
When the system finds a duplicate pair, it keeps the fresher article and retires the stale one instead of dropping the newcomer by default. The newest accurate version wins, which is the behavior a support engineer wants.
Reusing the index this way helps on retries too. Embeddings cost a model call to produce. A re-run reads the stored vector back instead of recomputing it, saving both time and Amazon Bedrock spend when a batch reruns.
Orchestrating curation at scale with AWS Step Functions
Curation runs over batches of articles that need orchestration to spread work across workers and recover from failures. AWS Step Functions provides that with a two-phase distributed map. It manages workflow state, applies the retries and error handling declared in the definition, and fans work across workers without custom coordination code. For how the distributed map works, see the AWS Step Functions Developer Guide.
Two configuration choices are worth calling out. First, we set the item processor to STANDARD rather than EXPRESS. Each article makes long-running Amazon Bedrock calls that exceed the 5-minute EXPRESS limit, and STANDARD keeps a full execution history for debugging. Second, we point the ItemReader at a manifest file in Amazon S3 rather than passing items inline, which keeps the workflow state small.
A daily schedule on Amazon EventBridge starts the run. An AWS Lambda function finds customers with new or changed articles, groups the changes into batches, and places each batch on an Amazon SQS first-in-first-out (FIFO) queue. The FIFO queue orders batches per customer across runs, using the customer ID as the message group key, so different customers still run in parallel. Ordering across runs is only part of the story. Within a single execution, Phase 2 can process up to 40 batches concurrently, so FIFO alone doesn’t stop two duplicates in different batches from racing. What actually protects deduplication is that it runs sequentially within each batch inside the worker, while quality scoring and improvement run in parallel. Sequential dedup per batch, parallel quality and improvement, and FIFO for cross-run ordering together keep duplicate detection consistent.
A dispatcher function pulls one batch at a time and starts a Step Functions execution. The state machine runs in two phases, each a distributed map so the articles in a batch process concurrently:
- Classify and embed – Each article is classified by type and given a vector embedding.
- Deduplicate, score, and improve – The pipeline finds duplicates, scores quality, and improves content that falls below the threshold.
The following diagram shows the trigger chain, the two phases, and the fault-tolerance mechanisms that protect a run.
Figure 2: Curation runs as a two-phase distributed map. Batches are ordered per customer through an Amazon SQS FIFO queue, article content is passed as an Amazon S3 pointer rather than inline state, and a circuit breaker and dead-letter queue keep a bad batch from stalling the run.
Passing pointers, not payloads
A Step Functions execution carries state between states, capped at 256 KB. Knowledge base articles, with full HTML bodies, pass that limit quickly. Rather than thread article content through the state machine, we write the batch to Amazon S3 and pass only the location through the workflow. Each map worker reads what it needs directly from Amazon S3, so the state payload stays small no matter how large the articles are.
The distributed map reads its work items from a manifest in Amazon S3 rather than from inline state. A tolerated-failure percentage lets the run absorb a few bad articles without aborting the whole batch:
"Phase1_ClassifyEmbed": {
    "Type": "Map",
    "ItemProcessor": {
        "ProcessorConfig": { "Mode": "DISTRIBUTED", "ExecutionType": "STANDARD" }
    },
    "ItemReader": {
        "Resource": "arn:aws:states:::s3:getObject",
        "ReaderConfig": { "InputType": "JSON" },
        "Parameters": { "Bucket.$": "$.bucket", "Key.$": "$.manifest_key" }
    },
    "MaxConcurrency": 40,
    "ToleratedFailurePercentage": 10
}
Recovering from failures
Two mechanisms keep a bad batch from taking down a run:
- Dead-letter queue – A batch that fails repeatedly is set aside for investigation instead of blocking the queue behind it.
- Circuit breaker (best effort) – After three consecutive failures, the dispatcher stops starting new batches and resets the affected articles to their starting state. The failure counter lives in the memory of a warm Lambda function, so it isn’t shared across concurrent dispatcher containers and resets when a new job starts. Under interleaved multi-tenant load the breaker might not trip, so we treat it as a best-effort backstop rather than a guarantee. Nothing is lost either way: the next scheduled run picks up reset articles, and a tripped breaker signals that a service dependency needs attention first.
Making Amazon Bedrock reliable at scale, and improving article quality
The engineering effort goes into running tens of thousands of model calls concurrently against shared service quotas. The pipeline reaches Anthropic Claude Sonnet for generation and improvement, and Amazon Titan Text Embeddings V2 for deduplication vectors, all through Amazon Bedrock model inference. For model availability by AWS Region, see Supported models by AWS Region.
Keeping model calls inside their limits
Three controls keep generation predictable under load:
- A hard wall-clock timeout on each execution, so a slow response cannot hold a worker open indefinitely.
- Automatic retry with backoff – The Amazon Bedrock client runs in adaptive mode, retrying on its own when it meets throttling, with exponential backoff on longer content-improvement calls.
- A guardrail fallback – We run an Amazon Bedrock guardrail on model output to filter unintended content. The guardrail is a production control, and the following fallback is a resilience measure that keeps it in force under normal conditions rather than a signal that it is optional.
The guardrail API has its own rate limit. If it throttles, the pipeline processes the article without the guardrail and logs a warning instead of failing, which keeps things moving during a spike. In code, the fallback is a short piece of the model-call wrapper:
try:
    return converse_with_timeout(kwargs, BEDROCK_CALL_TIMEOUT)
except ClientError as e:
    if "ThrottlingException" in str(e) and guardrail_config:
        log.warn("Guardrail throttled, retrying without guardrail")
        del kwargs["guardrailConfig"]
        return converse_with_timeout(kwargs, BEDROCK_CALL_TIMEOUT)
    raise
A fourth control handles truncated output. Content-improvement responses have a token budget, and a long article can hit it, leaving the JSON response cut off. The system detects the “stopped at token limit” signal and retries with double the budget, up to the model’s ceiling. Short articles never trigger this path, so the common case pays nothing for the safety net.
Scoring quality before and after improvement
Not every article needs improvement, and improvement does not always help. A quality score decides. Each article is scored across ten weighted dimensions, from the highest weight to the lowest:
- Completeness
- Actionability
- Structure
- Coherence
- Readability
- Self-service value
- Freshness
- Automation readiness
- Grammar
- Security
The weighted total produces one score, and a threshold decides whether the article meets the bar as-is or goes forward for improvement. The threshold is configurable, so a customer can hold generated content to a higher bar than imported content.
Articles below the threshold go through content improvement, also on Amazon Bedrock. This step has a practical challenge: a model asked to improve prose will often change image tags and hyperlinks too, and break them. Placeholders solve it. Before improvement, the system swaps every image and link for a numbered token, improves the prose around those tokens, and swaps the real media back afterward. The model never sees the raw markup, so headings and structure survive.
In code, this is a pair of functions that bracket the improvement call. The first replaces every media tag and link with a numbered token and records what it removed. The second puts the originals back after the model returns:
# Before improvement: swap media/links for [IMG_N] / [LINK_N] tokens
html_with_placeholders, placeholder_map = extract_placeholders(article_html)

enriched = improve_with_bedrock(html_with_placeholders)  # model never sees raw markup

# After improvement: restore the exact original tags in place
restored_html, missing = restore_placeholders(enriched, placeholder_map)
Because the model only ever sees [IMG_1] or [LINK_3], it cannot corrupt a URL or an image reference. The restore step keeps the published article’s media exactly as it started.
After improvement, the article is scored again. The new version is kept only when its score beats the original. Otherwise the original stands. That before-and-after check lets the pipeline improve content automatically without quietly making the library worse.
Serving many customers safely
The system runs many customers on shared infrastructure, and a knowledge base is exactly the data customers expect kept separate. Isolation is designed in from the start: each customer gets its own copy of everything that touches its content:
- A configuration profile
- An Amazon S3 Vectors index
- A set of model prompts
- An Amazon Bedrock guardrail
- An AWS KMS encryption key
Because those resources are per-customer, each customer’s data stays within its own boundary. A duplicate check runs against that customer’s index alone, content improvement uses that customer’s prompts, and data is encrypted under that customer’s key. No shared pool exists where one customer’s articles could surface in another’s results.
Onboarding a customer doesn’t mean editing a central list. The system discovers customers from the data catalog at run time, so adding one only means provisioning its resources, with no change to the pipeline code.
Results and lessons learned
The behavior here comes from our internal testing, not a guaranteed service level. Because each customer flows through its own Amazon SQS FIFO message group, adding a customer adds a parallel stream of work rather than slowing the others. Your own throughput will depend on article size, model latency, and your Amazon Bedrock quotas.
A representative run showed the pattern you can expect. Most articles came through fully processed on the first pass, a small share were held for improvement, and a smaller share were removed as duplicates. The run completed with no dead-letter-queue messages and no timeouts. A handful of articles hit the content-improvement token limit, were reset automatically, and were retried with a higher budget on the next run rather than failing. That last case matters, because it shows the resilience controls turning what would otherwise be hard failures into automatic retries.
Four lessons stand out. Reusing the vector index as a duplicate detector turned a hard problem into a nearest-neighbor query. Passing an Amazon S3 pointer through Step Functions instead of the article body removed a class of state-size failures. Scoring quality on both sides of improvement made it safe to run automatically. Treating a guardrail throttle as a warning kept the pipeline healthy through load spikes. The larger point is the closed loop itself: generated content feeds curation, and curation grounds the next round of generation, so the knowledge base improves as the system runs.
Clean up resources
The resources in this solution are billable, so remove them when you finish to avoid ongoing charges. Deleting the two AWS CDK stacks, one for knowledge base generation and one for knowledge base curation, removes most of them. That includes the AWS Lambda functions, the AWS Step Functions state machine, the Amazon ECS service on AWS Fargate, the Amazon SQS queues, and the Amazon DynamoDB tables.
A few resources need manual attention because they hold data or are created per customer:
- Amazon S3 Vectors indexes and vector buckets – Delete each per-customer index, then the vector bucket.
- Amazon S3 buckets – Empty and delete the source, output, and pipeline buckets.
- Amazon Bedrock guardrails – Delete the per-customer guardrails if the stack leaves them in place.
- AWS KMS keys – Schedule deletion of the per-customer keys.
- Amazon DynamoDB tables – Confirm the metrics and article-status tables are removed if you disabled point-in-time recovery retention.
See the repository README for the exact deletion commands.
Conclusion
The ITSM ticket graveyard is a knowledge problem that looks like a data problem. The resolutions already exist, trapped where nobody can reuse them, next to a knowledge base that decays faster than any team can hand-curate it. KnowledgeForge closes that gap with generative AI on AWS. It mines tickets into articles with Amazon Bedrock, catches duplicates with Amazon S3 Vectors, and orchestrates the flow with AWS Step Functions. A knowledge manager stays in control of what goes live.
To get started building a similar pipeline:
- Create a vector index using the Amazon S3 Vectors documentation.
- Embed a sample of your own articles and load the vectors.
- Run the nearest-neighbor query shown earlier to flag duplicates.
- Add the AWS Step Functions distributed map to batch-process articles.
- Layer on the score-improve-rescore quality gate.
The complete code is available in the aws-samples/sample-knowledgeforge repository on GitHub. The code samples throughout show the load-bearing parts of each pattern, ready to adapt to your own knowledge base.
To learn more, see the Amazon Bedrock User Guide, the AWS Step Functions Developer Guide, and the Amazon S3 User Guide.
About the authors
Anmol Dhankhar
Anmol is an AI/ML Consultant at AWS with more than 11 years of industry experience. He specializes in artificial intelligence, machine learning, data analytics, and generative AI, helping enterprise customers design and implement scalable, production-ready AI solutions.
Subhayan Saha
Subhayan is a Data Scientist at AWS ProServe with more than 15 years of experience leading technical teams and designing end-to-end solutions. He focuses on back-end technologies, cloud architecture on AWS, and AI/ML innovation. Outside of work, he values time with family and enjoys spiritual travel.
Raju Joshi
Raju is a Delivery Consultant (Data Science) at AWS ProServe with more than 8 years of experience specializing in generative AI. He advises customers on cloud transformation and AI strategy. A machine learning enthusiast, he balances work with family time, road trips, and movies.
Harshal Golecha
Harshal is a Senior Engagement Manager at AWS ProServe, specializing in the delivery of enterprise-scale generative and agentic AI solutions on AWS. He leads cross-functional teams delivering production-grade AI platforms – including agentic IT service desks and large-scale telecom monitoring solutions – partnering with enterprise customers on cloud transformation and AI-driven delivery outcomes.