Amazon Bedrock 推出 OpenAI GPT-5.6 模型跨 Region 推理
英文标题:Introducing cross-Region inference for OpenAI GPT-5.6 models on Amazon Bedrock
Amazon Bedrock 现已在超过 25 个 AWS Region 提供支持跨 Region 推理的 OpenAI GPT-5.6 模型,包括 Sol、Terra 和 Luna 三个变体。开发者可使用美国地理推理配置文件,将数据处理限定在美国地理范围内;也可使用全球配置文件,根据实时容量将请求路由至全球支持的商业 AWS Region。三款模型均支持文本和图像输入、100 万 token 上下文窗口、推理模式、服务端工具调用和提示词缓存,并兼容 OpenAI Responses API、Chat Completions API 与 Bedrock Converse API。该能力通过扩大可用计算资源池来提升吞吐量和负载下的性能稳定性,同时要求开发者根据数据驻留和合规要求选择合适的推理配置文件。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 517.1 KB
 2.7 KB
 8.2 KB
 39.2 KB
 575.2 KB
 32.3 KB
 189.3 KB
中文
本文由 OpenAI 的 Chris Dickens 与我们共同撰写。
Amazon Bedrock 现已在超过 25 个 AWS Region 中提供支持跨 Region 推理的 Amazon Bedrock OpenAI GPT-5.6 模型。GPT-5.6 有三个支持跨 Region 推理的变体:Sol、Terra 和 Luna;每个变体针对不同的能力与成本平衡进行了优化。
Amazon Bedrock 中的跨 Region 推理(Cross-Region inference,CRIS)通过推理配置文件实现。推理配置文件定义了模型以及 Amazon Bedrock 可将请求路由至的 AWS Region。您从源 Region 调用该配置文件,Amazon Bedrock 则使用目标 Region 中的计算资源将请求路由至相应 Region。CRIS 的主要作用是容量机制。它允许请求使用更广泛的计算资源池,而非受限于单个 Region 的可用容量,因此可提升吞吐量,并帮助在负载下维持稳定的性能。地理推理配置文件会在单一地理区域内路由请求,因此您可在确保数据仍在该地理区域内处理的同时进行扩展。对于 GPT-5.6,此次发布引入了美国地理推理(美国跨 Region 推理)和全球 CRIS。全球推理配置文件会根据实时容量,在模型已部署的所有受支持 AWS 商业 Region 之间路由请求,从而提供对 Amazon Bedrock 容量的广泛访问。
本文将概述 Amazon Bedrock 上的 GPT-5.6 模型、这些模型的地理和全球跨 Region 推理工作方式,以及如何通过 Amazon Bedrock 控制台,并在代码中使用 OpenAI Responses API、OpenAI Chat Completions API 和 Amazon Bedrock Converse API 调用它们。
Amazon Bedrock 上的 GPT-5.6
Amazon Bedrock 上的 GPT-5.6 系列包括通用型和专用网络安全变体。本文介绍支持跨 Region 推理的三个通用变体:Sol、Terra 和 Luna。三者均接受文本和图像输入并返回文本,拥有 100 万 token 的上下文窗口,支持推理模式、服务端工具调用和提示词缓存。您可以通过 OpenAI Responses API、OpenAI Chat Completions API 和 Amazon Bedrock Converse API 调用它们。Responses API 和 Chat Completions API 通过 stream=True 支持流式输出,ConverseStream 同样支持流式输出。
Amazon Bedrock 推理配置文件是逻辑标识符,您传入它们而不是原始模型 ID。
- 地理推理配置文件(以地理代码作为前缀,例如
us.,如us.openai.gpt-5.6-terra)会将推理处理限制在其预定义地理区域的 Region 内。请求通过您的源 Region 进入,并且只能被路由到该地理区域内的目标 Region,因此具有数据驻留要求的工作负载可在保持区域边界的前提下跨 Region 扩展。 - 全球推理配置文件(以
global.为前缀,例如global.openai.gpt-5.6-terra)可根据实时容量,将请求路由至模型已部署的任意受支持 AWS 商业 Region。它提供最广泛的容量池,适用于没有地理处理要求的工作负载。
无论由哪个后端 Region 处理请求,计费和配额消耗都会在您的账户下进行追踪,因此您仍可获得统一的支出和吞吐量视图。通过全球 CRIS 处理的数据可能跨越该模型符合条件的 Region 集合。如果您的工作负载存在数据驻留要求,限制只能在特定地理区域内处理数据,请使用该地理区域的地理配置文件(例如 us.openai.gpt-5.6-terra),或直接调用单个 Region,而不要使用全球配置文件。Amazon Bedrock 跨 Region 推理文档列出了参与每个模型全球和地理配置文件集合的 Region。
下表列出了您可以调用 GPT-5.6 推理配置文件的源 Region,以及请求可被处理的目标 Region。相同的路由规则适用于全部三个变体:Sol、Terra 和 Luna。
美国跨 Region 推理配置文件(us.openai.gpt-5.6-sol / -terra / -luna)
| 源 Region | 目标 Region |
|---|---|
美国东部(弗吉尼亚北部)us-east-1 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2 |
美国西部(俄勒冈)us-west-2 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2 |
美国东部(俄亥俄)us-east-2 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2 |
美国西部(加利福尼亚北部)us-west-1 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2、美国西部(加利福尼亚北部)us-west-1 |
加拿大(中部)ca-central-1 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2、加拿大(中部)ca-central-1 |
加拿大西部(卡尔加里)ca-west-1 |
美国东部(弗吉尼亚北部)us-east-1、美国西部(俄勒冈)us-west-2、美国东部(俄亥俄)us-east-2、加拿大西部(卡尔加里)ca-west-1 |
全球跨 Region 推理配置文件(global.openai.gpt-5.6-sol / -terra / -luna)
| 源 Region | 目标 Region |
|---|---|
**美国:**美国东部(弗吉尼亚北部)us-east-1、美国东部(俄亥俄)us-east-2、美国西部(俄勒冈)us-west-2、美国西部(加利福尼亚北部)us-west-1 **加拿大:**加拿大(中部)ca-central-1 **欧洲:**欧洲(斯德哥尔摩)eu-north-1、欧洲(巴黎)eu-west-3、欧洲(爱尔兰)eu-west-1、欧洲(法兰克福)eu-central-1、欧洲(西班牙)eu-south-2、欧洲(米兰)eu-south-1、欧洲(伦敦)eu-west-2、欧洲(苏黎世)eu-central-2 **亚太地区:**亚太地区(墨尔本)ap-southeast-4、亚太地区(悉尼)ap-southeast-2、亚太地区(东京)ap-northeast-1、亚太地区(大阪)ap-northeast-3、亚太地区(首尔)ap-northeast-2、亚太地区(孟买)ap-south-1、亚太地区(海得拉巴)ap-south-2、亚太地区(新加坡)ap-southeast-1、亚太地区(雅加达)ap-southeast-3、亚太地区(泰国)ap-southeast-7、亚太地区(马来西亚)ap-southeast-5、亚太地区(台北)ap-east-2 **中东:**中东(阿联酋)me-central-1、以色列(特拉维夫)il-central-1 **南美洲:**南美洲(圣保罗)sa-east-1 |
路由至全球受支持的 AWS 商业 Region |
在 Amazon Bedrock 控制台中试用 GPT-5.6
试用 GPT-5.6 的最快方法是 Amazon Bedrock 控制台中的文本 Playground,无需编写代码或配置 SDK。您可以发送提示词、调整推理参数,并在不同变体之间切换,以便在集成 API 前了解各模型的特性。模型选择器同时列出了地理和全球跨 Region 推理配置文件,因此您可在编写代码前测试这两种跨 Region 推理选项。在前述截图中,源 Region 是美国东部(弗吉尼亚北部)。模型选择器中的 US 条目是地理推理配置文件,Global 条目则是全球推理配置文件。
- 在模型可用的 Region 中打开 Amazon Bedrock 控制台,例如美国东部(弗吉尼亚北部)。
- 在导航窗格的 Test 下,选择 Playground。
- 在页面中间选择 Select model。
- 搜索 OpenAI GPT-5.6 Sol,选择 US OpenAI GPT-5.6 Sol 或 Global OpenAI GPT-5.6 Sol,然后选择 Apply。
- 输入提示词并选择 Run 以生成响应。
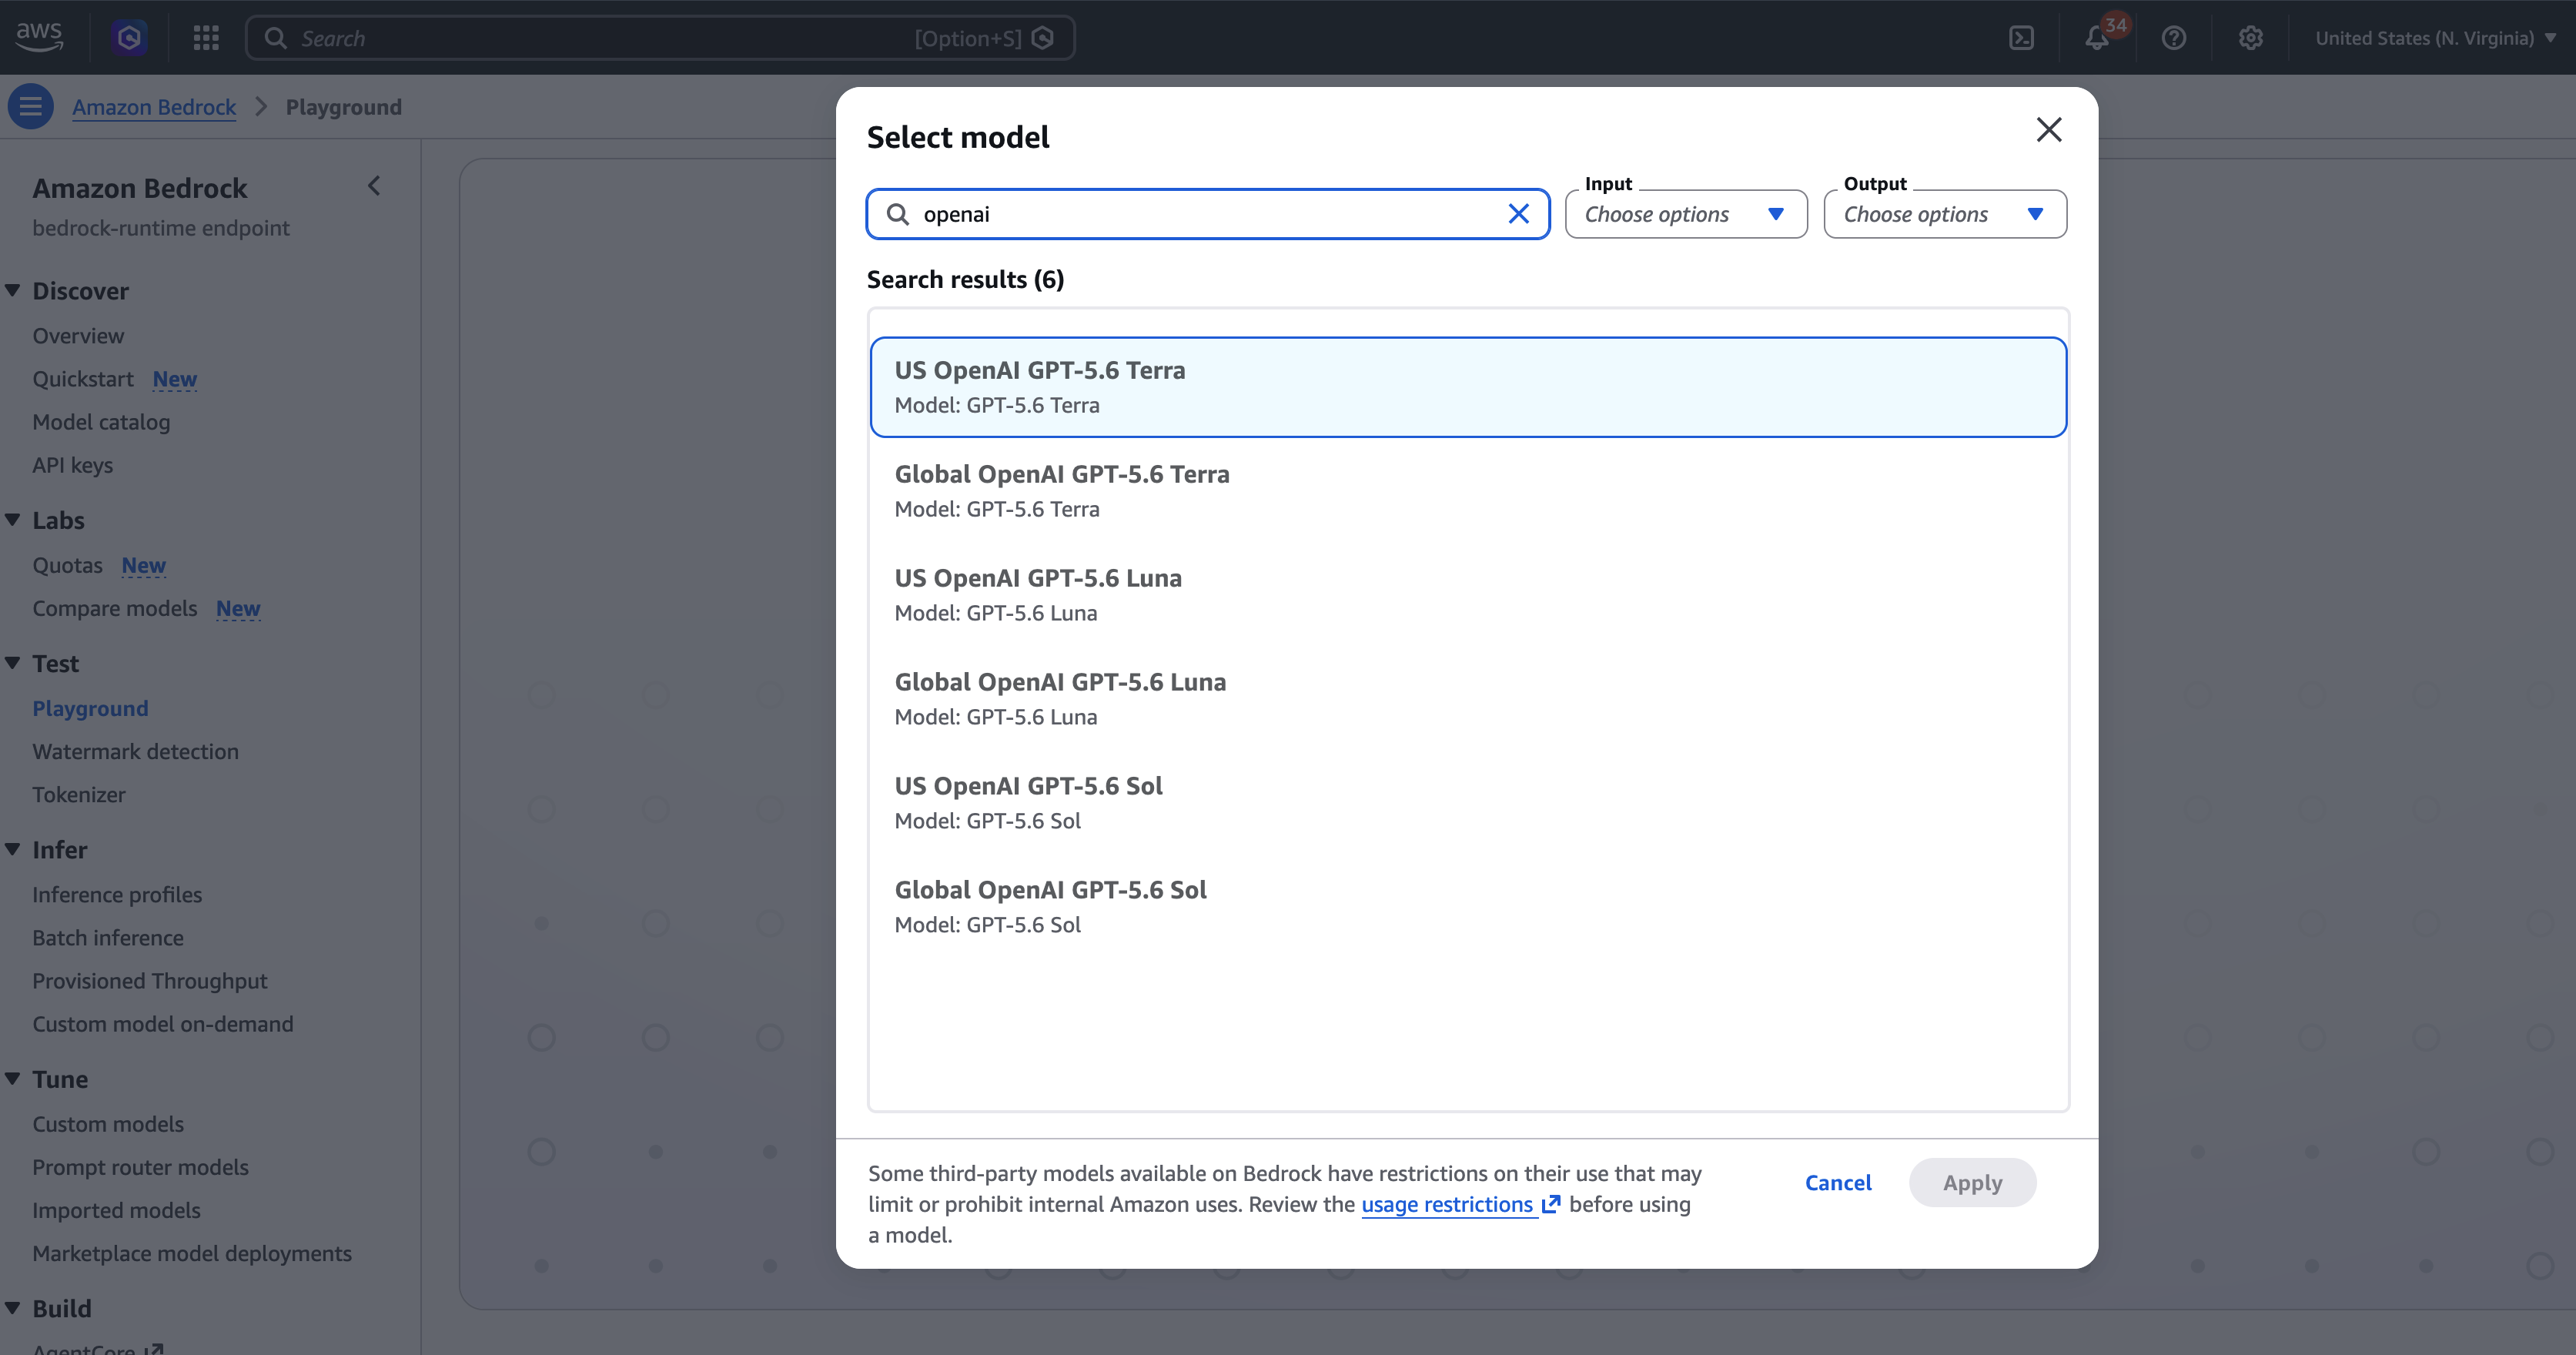
图 1:在 Amazon Bedrock 控制台模型选择器中选择美国或全球 GPT-5.6 推理配置文件
API 入门
GPT-5.6 在 Amazon Bedrock 上原生支持 OpenAI Responses API 格式。如果您的应用已经调用 OpenAI 模型,可以将现有 OpenAI SDK 客户端指向 Amazon Bedrock 的 OpenAI 兼容端点。然后,将推理配置文件 ID(全球或地理)替换为模型参数。对于身份验证,Amazon Bedrock 同时接受标准 AWS 凭证和 Amazon Bedrock API 密钥。API 密钥方式最适合 OpenAI SDK,因为 SDK 会将其作为 bearer token 传递。对于生产环境,请使用 aws-bedrock-token-generator 软件包以编程方式生成短期 API 密钥;该软件包会基于现有 AWS 凭证生成 bearer token(长期密钥仅建议用于探索)。
from aws_bedrock_token_generator import provide_token
from openai import OpenAI
region = "us-east-1"
# Point the OpenAI SDK at Amazon Bedrock's OpenAI-compatible endpoint for your Region. provide_token() generates a short-term Amazon Bedrock API key from your current AWS credentials (valid up to 12 hours), so no static key needs to be stored.
client = OpenAI(
    base_url= f"https://bedrock-runtime.{region}.amazonaws.com/openai/v1",
    api_key=provide_token(region=region),
)

# Use the global inference profile ID for GPT-5.6 Terra.
model_id = "global.openai.gpt-5.6-terra"
response = client.responses.create(
    model=model_id,
    input="Summarize the difference between horizontal and vertical scaling in two sentences.",
     max_output_tokens=512,
)

print(response.output_text)
如需支持参数的完整列表,请参阅 Amazon Bedrock 用户指南中的 OpenAI GPT 模型参数页面。同一个客户端也可用于 Chat Completions API;如果您的应用已使用这一格式,该 API 会十分有用。
response = client.chat.completions.create(
     # For US Geo CRIS, use "us.openai.gpt-5.6-terra".
     # Other variants: gpt-5.6-sol, gpt-5.6-luna
     model="global.openai.gpt-5.6-terra",
     messages=[
         {
             "role": "user",
             "content": "In one sentence, what is cross-Region inference in Amazon Bedrock?",
         }
     ],
     max_completion_tokens=2000,
     reasoning_effort="low",
 )

print(response.choices[0].message.content)
如果您是直接调用 Amazon Bedrock 而非通过 OpenAI SDK 调用,请使用 Amazon Bedrock Converse API。它提供与您调用 Bedrock 其他模型时相同的请求结构:
import boto3

client = boto3.client("bedrock-runtime", region_name="us-east-1")

model_id = "global.openai.gpt-5.6-terra"
 response = client.converse(
     modelId=model_id,
     messages=[{"role": "user", "content": [{"text": "List three common uses for a message queue."}]}],
     inferenceConfig={"maxTokens": 512},
 )
 print(response["output"]["message"]["content"][0]["text"])
对于流式响应,请使用相同参数调用 converse_stream,并迭代事件流:
stream_response = client.converse_stream(
     modelId=model_id,
     messages=[{"role": "user", "content": [{"text": "List three common uses for a message queue."}]}],
     inferenceConfig={"maxTokens": 512},
 )

for event in stream_response["stream"]:
     if "contentBlockDelta" in event:
         print(event["contentBlockDelta"]["delta"]["text"], end="")
安全与合规
跨 Region 推理采用与直接在 Region 内调用相同的 Amazon Bedrock 安全模型。请求使用您的 AWS Identity and Access Management(IAM)凭证进行身份验证,IAM 策略控制某个角色能够调用哪些推理配置文件。Amazon Bedrock 使用由芯片层面强制执行的零运营人员访问(zero-operator access,ZOA)安全模型,因此 AWS 运营人员无法访问您的提示词或补全内容。每次模型调用均在您的 IAM 策略下运行,可通过 VPC 端点从您的虚拟私有云(VPC)私密访问,并记录在 AWS CloudTrail 中。数据边界策略有助于防止数据跨账户和网络边界外泄。
对于包括 GPT-5.6 在内的某些模型,被 Amazon Bedrock 自动滥用检测分类器标记的内容会被保留最多 30 天,以用于离线滥用检测。有关适用的模型及其工作方式,请参阅 Amazon Bedrock 用户指南中的滥用检测。如需进一步了解 Bedrock 上的数据保留配置,请参阅 Amazon Bedrock 数据保留文档。有关每个配置文件路由集合中 Region 的权威列表,请参阅 Amazon Bedrock 跨 Region 推理支持页面。
跨 Region 推理请求会显示在源 Region 的 AWS CloudTrail 中,additionalEventData.inferenceRegion 字段会记录处理每个请求的 Region。如果您启用模型调用日志记录,请求和响应负载将被传输至同一账户和 Region 中的 Amazon Simple Storage Service(Amazon S3)或 Amazon CloudWatch Logs。
为跨 Region 推理配置 IAM 权限
要允许某个角色通过推理配置文件调用 GPT-5.6,请授予其对推理配置文件以及该配置文件可路由到的每个 Region 中基础模型的访问权限。您可以使用托管策略 AmazonBedrockLimitedAccess,也可以自行创建策略。
对于地理推理配置文件,该策略包含三条语句。第一条授予对源 Region 中地理推理配置文件及默认项目的访问权限。第二条授予对源 Region 以及该配置文件可路由到的每个目标 Region 中基础模型的访问权限。
English / 原文
This post is co-written with Chris Dickens from OpenAI.
Amazon Bedrock now offers OpenAI GPT-5.6 models on Amazon Bedrock in more than 25 AWS Regions, with cross-Region inference. Three GPT-5.6 variants support cross-Region inference, Sol, Terra, and Luna, each tuned for a different balance of capability and cost.
Cross-Region inference (CRIS) in Amazon Bedrock works through inference profiles, which define a model and the AWS Regions to which Amazon Bedrock can route a request. You call the profile from a source Region, and Amazon Bedrock routes the request to a destination Region using compute in that Region. CRIS is primarily a capacity mechanism. By allowing requests to draw on a broader pool of compute rather than being bound to one Region’s available capacity, it improves throughput and helps maintain consistent performance under load. A geographic inference profile routes requests within a single geography, so you can scale while keeping data processed within that geography. For GPT-5.6, this launch introduces US geographic (US cross-Region inference) and global CRIS. A global inference profile routes across all supported AWS commercial Regions where the model is deployed, based on real-time capacity, giving you broad access to Amazon Bedrock capacity.
In this post, we walk through an overview of GPT-5.6 models on Amazon Bedrock, how geographic and global cross-Region inference work for these models, and how to call them from the Amazon Bedrock console and in code with the OpenAI Responses API, the OpenAI Chat Completions API, and the Amazon Bedrock Converse API.
GPT-5.6 on Amazon Bedrock
The GPT-5.6 family on Amazon Bedrock includes general-purpose and specialized cyber security variants. This post covers the three general-purpose variants that support cross-Region inference, Sol, Terra, and Luna. All three accept text and image inputs and return text, have a 1 million token context window, and support reasoning mode, server-side tool calling, and prompt caching. You can call them with the OpenAI Responses API, the OpenAI Chat Completions API, and the Amazon Bedrock Converse API. Streaming is supported through the Responses and Chat Completions API (stream=True), and ConverseStream.
Amazon Bedrock inference profiles are logical identifiers you pass instead of a raw model ID.
- A geographic inference profile (prefixed with a geography code such as
us., for example us.openai.gpt-5.6-terra) keeps inference processing within the Regions of its predefined geography. Requests enter through your source Region and can only be routed to destination Regions inside that geography, so workloads with data residency requirements can scale across Regions while staying within the boundary. - A Global inference profile (prefixed
global.such as global.openai.gpt-5.6-terra) can route a request to any supported commercial AWS Region where the model is deployed, based on real-time capacity. It offers the widest capacity pool and is the right choice when your workload has no geographic processing requirements.
Billing and quota consumption are tracked against your account regardless of which backend Region handled the request, so a single spending and throughput picture still applies. Data processed through global CRIS may cross the Regions in that model’s eligible set. If your workload has data residency requirements that restrict processing to specific geographies, use the geographic profile for that geography (such as us.openai.gpt-5.6-terra) or a direct call to one Region instead of the global profile. The Amazon Bedrock cross-Region inference documentation lists which Regions participate in each model’s global and geographic profile sets.
The following tables list the source Regions where you can invoke the GPT-5.6 inference profiles and the destination Regions where your requests can be processed. The same routing applies to all three variants: Sol, Terra, and Luna.
US cross-Region inference profile (us.openai.gpt-5.6-sol / -terra / -luna)
| Source Region | Destination Regions |
|---|---|
| US East (N. Virginia) us-east-1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2 |
| US West (Oregon) us-west-2 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2 |
| US East (Ohio) us-east-2 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2 |
| US West (N. California) us-west-1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, US West (N. California) us-west-1 |
| Canada (Central) ca-central-1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, Canada (Central) ca-central-1 |
| Canada West (Calgary) ca-west-1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2, US East (Ohio) us-east-2, Canada West (Calgary) ca-west-1 |
Global cross-Region inference profile (global.openai.gpt-5.6-sol / -terra / -luna)
| Source Regions | Destination Regions |
|---|---|
| United States: US East (N. Virginia) us-east-1, US East (Ohio) us-east-2, US West (Oregon) us-west-2, US West (N. California) us-west-1 Canada : Canada (Central) ca-central-1 Europe : Europe (Stockholm) eu-north-1, Europe (Paris) eu-west-3, Europe (Ireland) eu-west-1, Europe (Frankfurt) eu-central-1, Europe (Spain) eu-south-2, Europe (Milan) eu-south-1, Europe (London) eu-west-2, Europe (Zurich) eu-central-2 Asia Pacific: Asia Pacific (Melbourne) ap-southeast-4, Asia Pacific (Sydney) ap-southeast-2, Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Osaka) ap-northeast-3, Asia Pacific (Seoul) ap-northeast-2, Asia Pacific (Mumbai) ap-south-1, Asia Pacific (Hyderabad) ap-south-2, Asia Pacific (Singapore) ap-southeast-1, Asia Pacific (Jakarta) ap-southeast-3, Asia Pacific (Thailand) ap-southeast-7, Asia Pacific (Malaysia) ap-southeast-5, Asia Pacific (Taipei) ap-east-2 Middle East : Middle East (UAE) me-central-1, Israel (Tel Aviv) il-central-1 South America : South America (São Paulo) sa-east-1 | Routes to supported AWS commercial Regions globally |
Try GPT-5.6 in the Amazon Bedrock console
The quickest way to try GPT-5.6 is the text playground in the Amazon Bedrock console, which requires no coding or SDK setup. You can send prompts, adjust inference parameters, and switch between variants to get a feel for each model before you integrate the API. The model selector lists both the geographic and global cross-Region inference profiles, so you can test either cross-Region inference option before writing code. In the preceding screenshot, the source Region is US East (N. Virginia). The US entry in the model selector is the geographic inference profile, and the Global entry is the global inference profile.
- Open the Amazon Bedrock console in a Region where the models are available, such as US East (N. Virginia).
- In the navigation pane, under Test , choose Playground.
- Choose Select model in the middle of the page.
- Search for OpenAI GPT-5.6 Sol , select either US OpenAI GPT-5.6 Sol or Global OpenAI GPT-5.6 Sol , and choose Apply.
- Enter a prompt and choose Run to generate a response.
Figure 1: Selecting a US or Global GPT-5.6 inference profile in the Amazon Bedrock console model selector
Getting started with the API
GPT-5.6 speaks the OpenAI Responses API formats natively on Amazon Bedrock. If your application already calls OpenAI models, you can point your existing OpenAI SDK client at the Amazon Bedrock OpenAI-compatible endpoint. Then swap in the inference profile ID (global or geographic) as the model parameter. For authentication, Amazon Bedrock accepts either standard AWS credentials or an Amazon Bedrock API key. The API key path is the most direct fit for the OpenAI SDK, which passes it as the bearer token. For production, generate short-term API keys programmatically using the aws-bedrock-token-generator package, which derives a bearer token from your existing AWS credentials (long-term keys are recommended only for exploration).
from aws_bedrock_token_generator import provide_token
from openai import OpenAI
region = "us-east-1"
# Point the OpenAI SDK at Amazon Bedrock's OpenAI-compatible endpoint for your Region. provide_token() generates a short-term Amazon Bedrock API key from your current AWS credentials (valid up to 12 hours), so no static key needs to be stored.
client = OpenAI(
    base_url= f"https://bedrock-runtime.{region}.amazonaws.com/openai/v1",
    api_key=provide_token(region=region),
)

# Use the global inference profile ID for GPT-5.6 Terra.
model_id = "global.openai.gpt-5.6-terra"
response = client.responses.create(
    model=model_id,
    input="Summarize the difference between horizontal and vertical scaling in two sentences.",
     max_output_tokens=512,
)

print(response.output_text)
For the full list of supported parameters, see the OpenAI GPT model parameters page in the Amazon Bedrock User Guide. The same client also works with the Chat Completions API, useful if your application already uses this format.
response = client.chat.completions.create(
     # For US Geo CRIS, use "us.openai.gpt-5.6-terra".
     # Other variants: gpt-5.6-sol, gpt-5.6-luna
     model="global.openai.gpt-5.6-terra",
     messages=[
         {
             "role": "user",
             "content": "In one sentence, what is cross-Region inference in Amazon Bedrock?",
         }
     ],
     max_completion_tokens=2000,
     reasoning_effort="low",
 )

print(response.choices[0].message.content)
If you’re calling Amazon Bedrock directly rather than through the OpenAI SDK, use the Amazon Bedrock Converse API, which gives you the same request shape you already use for other models on Bedrock:
import boto3

client = boto3.client("bedrock-runtime", region_name="us-east-1")

model_id = "global.openai.gpt-5.6-terra"
 response = client.converse(
     modelId=model_id,
     messages=[{"role": "user", "content": [{"text": "List three common uses for a message queue."}]}],
     inferenceConfig={"maxTokens": 512},
 )
 print(response["output"]["message"]["content"][0]["text"])
For streaming responses, call converse_stream with the same arguments and iterate over the event stream:
stream_response = client.converse_stream(
     modelId=model_id,
     messages=[{"role": "user", "content": [{"text": "List three common uses for a message queue."}]}],
     inferenceConfig={"maxTokens": 512},
 )

for event in stream_response["stream"]:
     if "contentBlockDelta" in event:
         print(event["contentBlockDelta"]["delta"]["text"], end="")
Security and compliance
Cross-Region inference uses the same Amazon Bedrock security model as direct in-Region calls. Requests are authenticated with your AWS Identity and Access Management (IAM) credentials, and IAM policies control which inference profiles a role can invoke. Amazon Bedrock uses a zero-operator access (ZOA) security model enforced at the chip, so no AWS operators can access your prompts or completions. Every model call runs under your IAM policies, can be reached privately from your virtual private cloud (VPC) through a VPC endpoint, and is logged on AWS CloudTrail. Data perimeter policies help prevent exfiltration across account and network boundaries.
For certain models, including GPT-5.6, content flagged by the Amazon Bedrock automated abuse-detection classifiers is retained for up to 30 days for offline abuse detection. To see which models this applies to and how it works, see Abuse detection in the Amazon Bedrock User Guide. To understand more about data retention configuration on Bedrock, see the Amazon Bedrock data retention documentation. For the authoritative list of Regions in each profile’s routing set, see the Amazon Bedrock cross-Region inference support page.
Cross-Region inference requests appear on AWS CloudTrail in your source Region, and the additionalEventData.inferenceRegion field records which Region processed each request. If you enable model invocation logging, the request and response payloads are delivered to Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch Logs in the same account and Region.
Setting up IAM permissions for cross-Region inference
To let a role invoke GPT-5.6 through an inference profile, grant it access to the inference profile and to the foundation model in every Region the profile can route to. You can use this managed policy AmazonBedrockLimitedAccess or create your own.
For a geographic inference profile , the policy has three statements. The first grants access to the geographic inference profile and the default project in your source Region. The second grants access to the foundation model in your source Region and in every destination Region in the geography, with a condition that limits this access to requests made through that profile. The third grants the bearer-token authentication the OpenAI-compatible APIs use.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "GrantGeoCrisProfileAndProjectAccess",
      "Effect": "Allow",
      "Action": ["bedrock:InvokeModel"],
      "Resource": [
        "arn:aws:bedrock:<SOURCE REGION>:<ACCOUNT>:inference-profile/us.openai.gpt-5.6-terra",
        "arn:aws:bedrock:<SOURCE REGION>:<ACCOUNT>:project/default"
      ]
    },
    {
      "Sid": "GrantGeoCrisDestinationModelAccess",
      "Effect": "Allow",
      "Action": ["bedrock:InvokeModel"],
      "Resource": [
        "arn:aws:bedrock:us-east-1::foundation-model/openai.gpt-5.6-terra",
        "arn:aws:bedrock:us-east-2::foundation-model/openai.gpt-5.6-terra",
        "arn:aws:bedrock:us-west-2::foundation-model/openai.gpt-5.6-terra"
      ],
      "Condition": {
        "StringLike": {
          "bedrock:InferenceProfileArn": "arn:aws:bedrock:<SOURCE REGION>:<ACCOUNT>:inference-profile/us.openai.gpt-5.6-terra"
        }
      }
    },
    {
      "Sid": "AllowBearerTokenAuth",
      "Effect": "Allow",
      "Action": ["bedrock:CallWithBearerToken"],
      "Resource": "*"
    }
  ]
}
A global inference profile uses a four-part policy. The first grants access to the global inference profile and the default project in your source Region. The second grants access to the foundation model in your source Region. The third grants access to the foundation model through the Region-agnostic global ARN, which is what enables cross-Region routing. The fourth grants the bearer-token authentication used by the OpenAI-compatible APIs.
{
 "Version": "2012-10-17",
 "Statement": [
   {
     "Sid": "GrantGlobalCrisProfileAndProjectAccess",
     "Effect": "Allow",
     "Action": ["bedrock:InvokeModel"],
     "Resource": [
       "arn:aws:bedrock:<REQUESTING REGION>:<ACCOUNT>:inference-profile/global.openai.gpt-5.6-terra",
       "arn:aws:bedrock:<REQUESTING REGION>:<ACCOUNT>:project/default"
     ],
     "Condition": {
       "StringEquals": { "aws:RequestedRegion": "<REQUESTING REGION>" }
     }
   },
   {
     "Sid": "GrantGlobalCrisInRegionModelAccess",
     "Effect": "Allow",
     "Action": ["bedrock:InvokeModel"],
     "Resource": ["arn:aws:bedrock:<REQUESTING REGION>::foundation-model/openai.gpt-5.6-terra"],
     "Condition": {
       "StringEquals": {
         "aws:RequestedRegion": "<REQUESTING REGION>",
         "bedrock:InferenceProfileArn": "arn:aws:bedrock:<REQUESTING REGION>:<ACCOUNT>:inference-profile/global.openai.gpt-5.6-terra"
       }
     }
   },
   {
     "Sid": "GrantGlobalCrisGlobalModelAccess",
     "Effect": "Allow",
     "Action": ["bedrock:InvokeModel"],
     "Resource": ["arn:aws:bedrock:::foundation-model/openai.gpt-5.6-terra"],
     "Condition": {
       "StringEquals": {
         "aws:RequestedRegion": "unspecified",
         "bedrock:InferenceProfileArn": "arn:aws:bedrock:<REQUESTING REGION>:<ACCOUNT>:inference-profile/global.openai.gpt-5.6-terra"
       }
     }
   },
   {
     "Sid": "AllowBearerTokenAuth",
     "Effect": "Allow",
     "Action": ["bedrock:CallWithBearerToken"],
     "Resource": "*"
   }
 ]
}
These policies grant bedrock:CallWithBearerToken and bedrock:InvokeModel on the project/default resource, which the OpenAI Responses and Chat Completions APIs use to authenticate with an Amazon Bedrock API key and run inference. If you use the streaming Converse API (ConverseStream), add bedrock:InvokeModelWithResponseStream to the inference-profile and foundation-model statements.
The statements work together, so removing one denies that profile’s cross-Region access for the role, which also gives you a clean way to turn either capability off for specific roles. Alternatively, you can attach an explicit deny that targets global. or us. inference profiles.
Service control policy consideration for global cross-Region inference
If your organization uses Region-restrictive service control policies (SCPs), Global CRIS requests set aws:RequestedRegion to unspecified rather than a specific Region name. Geographic CRIS requests are evaluated against every destination Region in the profile. The recommended approach is to exempt cross-Region inference with the bedrock:InferenceProfileArn condition rather than widening your Region allowlist. Amazon Bedrock sets that condition key when it authorizes the foundation model, so you can allow CRIS routing while keeping your allowlist tight for every other service. Your source Region still has to be in the allowlist. If you prefer not to use the condition, you can instead add the destination Regions and unspecified to your allowlist, but that opens those Regions to every service, not only Amazon Bedrock. For a ready-to-use SCP and step-by-step guidance, see the Bedrock CRIS Region-control SCP sample.
The following SCP denies Amazon Bedrock inference outside your approved Regions (Sydney and N. Virginia are shown) and exempts the us. and global. inference profiles that GPT-5.6 uses. The first statement keeps the Region allowlist enforced for every other service, so include the global services your organization uses in its NotAction list.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyOutsideApprovedRegionsExceptBedrockInvoke",
      "Effect": "Deny",
      "NotAction": [
        "iam:*", "sts:*", "organizations:*", "account:*",
        "route53:*", "cloudfront:*", "waf:*", "wafv2:*", "shield:*",
        "support:*", "trustedadvisor:*", "health:*",
        "budgets:*", "ce:*", "cur:*", "tax:*", "billing:*",
        "bedrock:Invoke*"
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEquals": { "aws:RequestedRegion": ["ap-southeast-2", "us-east-1"] }
      }
    },
    {
      "Sid": "DenyBedrockInferenceOutsideApprovedRegionsUnlessCris",
      "Effect": "Deny",
      "Action": [
        "bedrock:Invoke*"
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEquals": { "aws:RequestedRegion": ["ap-southeast-2", "us-east-1"] },
        "ArnNotLike": {
          "bedrock:InferenceProfileArn": [
            "arn:aws:bedrock:*:*:inference-profile/us.*",
            "arn:aws:bedrock:*:*:inference-profile/global.*"
          ]
        }
      }
    }
  ]
}
Model access must be enabled for the account and Region for both profile types. For the full checklist, see Prerequisites for inference profiles.
Working with prompt caching
All three GPT-5.6 variants support prompt caching on the bedrock-runtime endpoint. When your requests share a long prompt prefix, such as a system prompt or a set of few-shot examples, Amazon Bedrock caches that prefix. Later requests reuse the cached prefix instead of reprocessing it. This lowers input cost and latency for the cached portion.
GPT-5.6 supports two caching modes on Amazon Bedrock. Implicit caching is the default: the service places a cache breakpoint at the latest user or tool message, which suits conversations that grow by appending messages. If your requests share a stable prefix followed by content that changes on every request, you can mark the end of the stable content with an explicit cache breakpoint instead. In both modes, pass the optional prompt_cache_key parameter so requests with the same prefix are routed to the same cache. Both modes work with geographic and global inference profiles. Each cache breakpoint needs a prompt prefix of at least 1,024 tokens. For more information, see Prompt caching for faster model inference.
Prompt caching also affects quota usage. Cache read tokens are not counted toward your TPM quota, so requests that reuse a cached prefix consume less of it. The next section describes how quotas are calculated. The following example uses explicit prompt caching with the client and model_id from the Getting started section:
# support_policy_manual is a long, stable prefix shared across requests.
# The breakpoint marks the end of the stable content; the user question
# after it changes on every request without invalidating the cached prefix.
completion = client.chat.completions.create(
     model=model_id,
     messages=[
         {
             "role": "system",
             "content": [
                 {
                     "type": "text",
                     "text": support_policy_manual,
                     "prompt_cache_breakpoint": {"mode": "explicit"},
                 }
             ],
         },
         {"role": "user", "content": "A customer wants a refund for a damaged laptop. What must I verify first?"},
     ],
     max_completion_tokens=300,
     prompt_cache_key="support-policy-v1",
 )
To confirm that caching is working, check the usage object of each response.
details = completion.usage.prompt_tokens_details
print("Cached tokens:", details.cached_tokens)
print("Written tokens:", details.cache_write_tokens)
Quota management
On-demand quotas for GPT-5.6 are managed as tokens per minute (TPM), and they attach to the inference profile you call: a geographic profile and a global profile for the same model carry separate quota allocations, so switching between them changes the pool you draw from. To view your current allocations or request an increase, search for the GPT-5.6 model inference quotas in the AWS Service Quotas console from the Region your application calls Amazon Bedrock in.
When you size a quota increase request, account for the burndown rate: the rate at which input and output tokens convert into token quota usage for the throttling system. Input tokens count against your quota at 1:1, while output tokens can consume quota at a higher multiple. For GPT-5.6 models, the burndown rate is 10x for output tokens, meaning one output token consumes 10 tokens from your TPM quota, so output-heavy workloads use up quota considerably faster than raw token counts suggest. The per-request calculation is:
Input token count + Cache write input tokens + (Output token count x Burndown rate)
For example, a request with 2,000 input tokens and 1,000 output tokens depletes 12,000 tokens from your quota. Cache read tokens are not part of this calculation, which is what makes prompt caching (previous section) effective for quota management and cost. For the current burndown rates by model, see the Amazon Bedrock quotas page. Three practices help you avoid surprises:
- Request increases before deployment. If you anticipate high usage, request the increase through the Service Quotas console ahead of your launch rather than reacting to throttling in production.
- Monitor utilization. Amazon CloudWatch publishes quota utilization metrics in real time per inference profile, so you can set alerts when usage approaches thresholds and track historical patterns to plan future increases.
- Load test with realistic traffic (including peak patterns and production-size prompts) before you commit a workload to production, and validate against the profile type you will actually use, since geographic and global quotas are separate.
Monitoring and logging
Because GPT-5.6 requests run through the Bedrock Runtime API, requests made through a geographic or global inference profile appear in Amazon Bedrock model invocation logging the same way on-demand requests do, with the inference profile ARN recorded alongside the request and response payloads (subject to your logging configuration). You can deliver invocation logs to Amazon S3 or Amazon CloudWatch Logs. Whichever profile type you use, invocation logs and metrics are recorded in your source Region, so your observability stays in one place even when the request is processed elsewhere.
Amazon CloudWatch metrics covering invocation counts, token counts, latency, throttles, and errors are published per inference profile. Because geographic and global profiles are distinct resources, their metrics are reported separately. Per-request latency will vary somewhat with the destination Region a request lands in, so if your dashboards break metrics down by Region today, consider adding a view that aggregates by inference profile ID instead, since that is the ID your application code and quota consumption are tied to. Usage is also itemized on AWS Cost Explorer and the AWS Cost and Usage Report, so you can attribute GPT-5.6 spend by model and by profile the same way you do for the rest of your Bedrock workloads.
Conclusion
GPT-5.6 brings three OpenAI model variants to Amazon Bedrock. With this launch you can call each of them through two kinds of cross-Region inference profiles. You can use a geographic profile when inference processing needs to stay within a geography (scaling across the Regions inside it), and a global profile when you want the widest capacity pool across supported commercial AWS Regions. Either way, your application talks to one endpoint with one profile ID, logs, quotas and billing stay in your source Region. The models speak the OpenAI Chat Completions API and Responses API, including streaming, and the Amazon Bedrock Converse API.
To get started, open the Amazon Bedrock console and send a test prompt to GPT-5.6 Sol, Terra, or Luna through an inference profile, or call the models programmatically through the Responses API. Review the Amazon Bedrock pricing page for current GPT-5.6 rates before sizing a production workload. If your application needs long-context (1 million token) processing, check the Amazon Bedrock model support by Region page for Region availability.
About the authors
Melanie Li
Melanie Li, PhD, is a Senior Generative AI Specialist Solutions Architect at AWS based in Sydney, Australia, where her focus is on working with customers to build solutions using state-of-the-art AI/ML tools. She has been actively involved in multiple generative AI initiatives across APJ, harnessing the power of LLMs. Prior to joining AWS, Dr. Li held data science roles in the financial and retail industries.
Zohreh Norouzi
Zohreh is a Senior Security Solutions Architect at Amazon Web Services (AWS). She helps customers make good security choices and accelerate their journey to the AWS Cloud. She has been actively involved in AI security initiatives, using her expertise to help customers build secure AI solutions at scale.
Saurabh Trikande
Saurabh is a Senior Product Manager for Amazon Bedrock and Amazon SageMaker Inference. He is passionate about working with customers and partners, motivated by the goal of democratizing AI. He focuses on core challenges related to deploying complex AI applications, inference with multi-tenant models, cost optimizations, and making the deployment of generative AI models more accessible. In his spare time, Saurabh enjoys hiking, learning about innovative technologies, following TechCrunch, and spending time with his family.
Chase Kernan
Chase is a Principal Engineer at AWS.
Chris Dickens
Chris is a Member of Product Staff at OpenAI focused on the OpenAI APIs. His work includes collaboration with AWS on Amazon Bedrock to make OpenAI’s frontier models widely accessible to developers.