Agentic Data Operations Platform(ADOP):将数据工程工作压缩至数小时
英文标题:Agentic Data Operations Platform (ADOP): Data engineering into hours
AWS 推出的 Agentic Data Operations Platform(ADOP)是一套基于 Amazon Bedrock 的参考架构,通过专用 AI Agent 自动化从 Bronze、Silver 到 Gold 的数据管道全生命周期。该架构将 Agent 用于开发阶段的代码与策略生成,而生产环境部署经 CI/CD 审核后的确定性 PySpark、SQL、Airflow DAG 和 IAM/Cedar 策略,从而兼顾效率、成本可预测性与可审计性。ADOP 旨在将新数据源接入从通常需要数周的工作压缩至数小时,并把合规控制前移至接入阶段。对开发者和数据平台团队而言,它为 Claude Code、Kiro、Cursor、Codex 等多种 AI 编程工具提供统一的架构约束、治理规则和接入流程。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 147.2 KB
 182.7 KB
 172.8 KB
 116.6 KB
 124.4 KB
 108.4 KB
 111.9 KB
 339.5 KB
 135.7 KB
中文
数据工程团队通常需要花费数周时间才能接入一个新的数据源:编写 ETL、手工编写质量检查、更新语义模型,以及验证合规性。AWS 上的 Agentic Data Operations Platform(ADOP)旨在显著缩短这一周期。它是一套构建于 Amazon Bedrock 以及您所选择的 AI 编程工具之上的参考架构。专用 AI Agent 可自动完成从 Bronze 到 Silver 再到 Gold 的完整生命周期,同时提供可配置的控制措施,以支持您的数据治理和监管合规工作。
对于数据工程负责人而言,有三项变化。工程师不再将大部分时间耗费在管道基础设施工作上,而是开始交付数据产品。合规不再是下游关卡,而成为数据接入时即应用的内联控制。并且,决定 Claude Code、Kiro、Cursor、Codex 等每种 AI 编程工具如何与数据系统交互的,是您的架构而非模型。
本文面向工程副总裁、首席数据官和数据平台总监;文章后半部分还将为平台工程师提供实施细节。
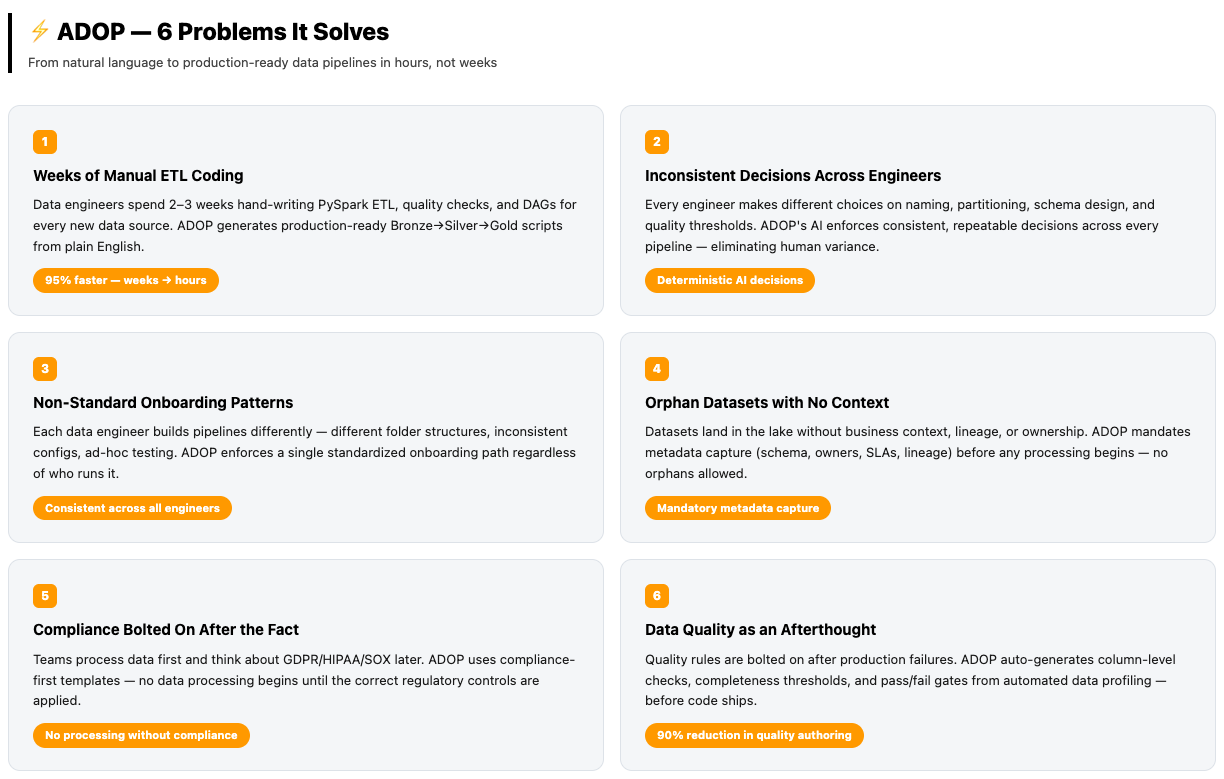
图 1:ADOP 应对的六项数据工程挑战
Agent 在开发环境,产物在生产环境
这是使 ADOP 区别于典型 Agent 平台宣传的设计选择。
ADOP 是一种构建阶段加速器,而不是运行时依赖。Agent 在开发环境中运行,负责推理、提出建议和生成:ETL 代码、质量检查、语义层定义、监管控制措施。工程师对输出进行审查。持续集成和持续交付(CI/CD)将生成的产物——确定性的 PySpark、SQL、Airflow DAG、IAM 与 Cedar 策略——提升至预发布和生产环境。在 ADOP 的默认模式中,生产环境运行确定性产物,无需调用模型。对于要求在运行时进行模型在环推理的组织,可以利用 Amazon Bedrock 端点扩展该架构,但生成的管道代码本身仍保持静态且可审计。
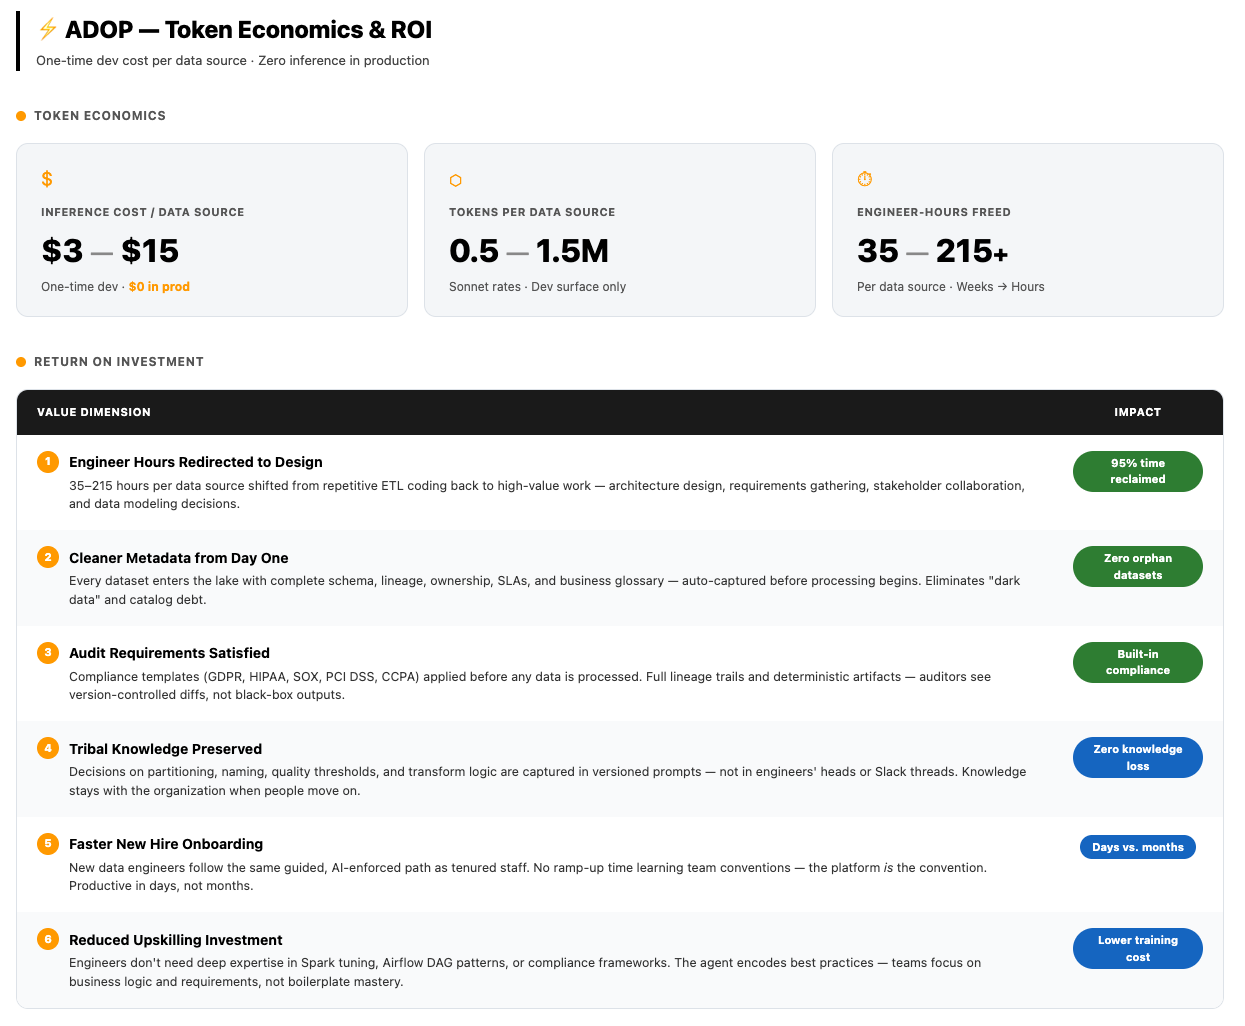
图 2:ADOP 的 Token 经济性与投资回报
**ADOP 与通用编程助手的差异:**后者是通用编程助手:能力出色,但开放无边界。将它们用于数据平台时,每位工程师可能每天都会得到不同的架构。ADOP 有意采用带有明确倾向的方法。它将同样的模型封装在以下约束中:
- 收窄的赛道——数据工程技能和提示词,而不是“任何你能输入的内容”。
- 内置公司理念——您的标准存在于设计中,而非某个人的记忆里。
- 不允许大语言模型(LLM)擅自设计架构——模型填充蓝图,而不是绘制蓝图。
- 策略与监管护栏——在构建阶段应用支持合规工作的控制措施,而非仅在审查阶段应用。
- 覆盖整个企业的统一接入流程——每个数据源每次都以相同方式接入。
通用工具让一名开发者更快。ADOP 则让每一名开发者保持一致。
**ADOP 与 Amazon Bedrock AgentCore 的关系:**Amazon Bedrock AgentCore 是一个可使用任意框架或模型来大规模构建、连接和优化 Agent 的平台。ADOP 在开发环境中运行 Agent,并向生产环境交付确定性产物。两者都是符合 AWS 生态的有效模式。ADOP 针对受监管数据工作负载的成本可预测性和审计能力进行了优化。
使用场景
只要数据工程速度受到手动接入和合规开销的限制,ADOP 就适用。常见模式包括:
- 大规模企业数据接入——使用自然语言描述一个新数据源。Agent 处理模式推断、ETL、质量检查和语义层更新。
- 医疗保健和金融服务领域的受监管管道——通过专门的治理提示词,针对每个数据集应用可配置的控制措施,以帮助您应对所在行业的监管要求。客户应自行负责确定自身合规性。
- 面向 AI 的 Gold 层——自动填充和维护,用于商业智能与机器学习(ML)功能。
- 多工具 AI 开发治理——Claude Code、Kiro、Cursor 和 Codex 均基于同一架构契约运行。
架构
ADOP 是一个 AI 驱动的编程框架,可在 AWS 和多云环境中构建端到端数据管道。它通过 Amazon Bedrock 在 Claude Code 中启动数据接入 Agent,并使用 Claude Code 的 Dynamic Workflow 功能,为管道构建的每个阶段创建专用子 Agent。
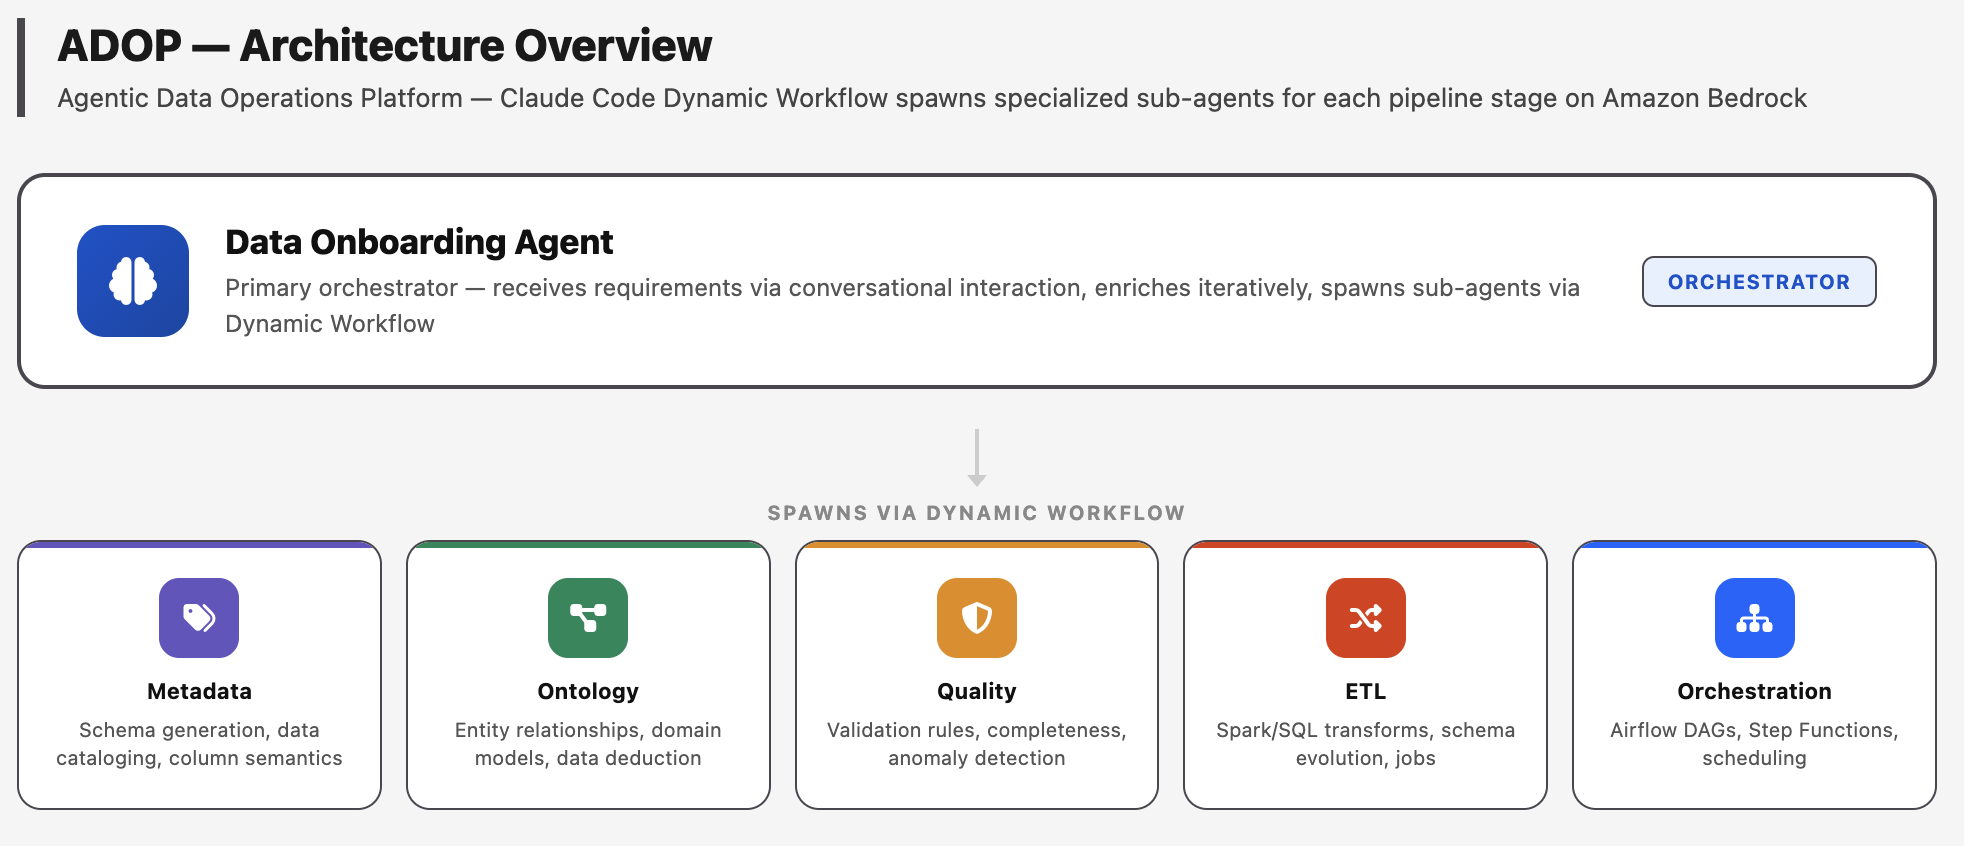
图 3:ADOP 架构概览,数据接入 Agent 在 Amazon Bedrock 上创建专用子 Agent
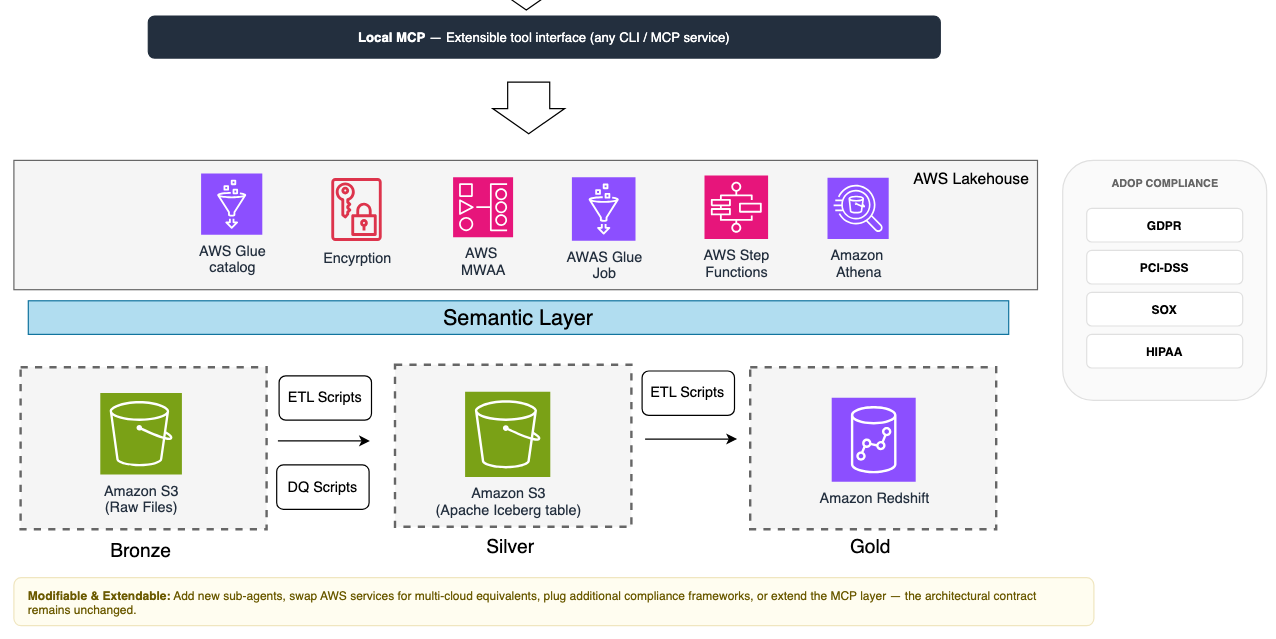
图 4:ADOP 从 Bronze 到 Silver 再到 Gold 的湖仓分层,以及内置合规控制措施
子 Agent——子 Agent 负责元数据生成、数据本体推导、数据质量检查、ETL 转换和编排(Airflow 或 AWS Step Functions)。系统通过与用户角色的对话交互,迭代丰富需求;每项产物都在部署至 AWS 前于本地完成验证,并经由人工在环审批。
决策引擎(AI 克隆)——决策引擎相当于企业架构师的 AI 编码版本,将组织的指南、技术标准和设计理念直接嵌入构建流程。这有助于推动不同构建者之间的一致性,缓解团队在缺乏共享护栏的情况下使用通用编程工具所造成的碎片化问题。
护栏——子 Agent 受到架构契约的约束:工具路由规则、Cedar 授权策略、不变量和内联合规提示词。尽管参考实现面向 AWS,该框架也可扩展至具有 CLI 或 Model Context Protocol(MCP)接口的其他服务,支持混合云和多云环境。
数据合规——三项能力完善了该架构。ADOP 可帮助您应用与合规相关的控制措施:每个治理框架对应一个监管提示词,可在接入阶段应用,因此法务团队审核的是提示词文件,而非应用程序代码。您仍需负责验证这些控制措施是否满足您的监管义务。
Agent 可观测性——每项 Agent 决策都会通过 AgentTrace 进行追踪,包括意图、所选工具、结果和成本,并可发布至 Amazon CloudWatch 或 OpenTelemetry 接收端以供审计。默认情况下,整个技术栈均在本地开发环境中运行。当规模需求出现时,可提升至 AgentCore runtime——Amazon Bedrock AgentCore 的一项能力——且无需改变架构契约。
负责任的 AI 与数据处理——Agent 在开发期间可能处理受监管数据或个人身份信息。客户应审查其数据处理实践,应用适当的访问控制,并在将产物提升至生产环境前,验证 Agent 行为是否符合组织的负责任 AI 政策。
通过两步开始使用
-
首先克隆代码库。
git clone https://github.com/aws-samples/sample-Agentic-Ai-Data-Operations.git -
将数据集上传至 Amazon Simple Storage Service(Amazon S3)或本地存储,然后运行修改后的提示词。
**注意:**以下示例仅使用虚构数据、存储桶名称和字段引用来说明。未涉及任何真实个人身份信息(PII)。该示例不构成监管合规指导或法律建议。
/onboard-workflow

Onboard attendance data from s3://amzn-s3-demo-source-bucket/demo_landing/attendance.csv into Silver with dedup on (employee_id, check_in)
and not-null policy on employee_id and check_in,and into a flat denormalized Gold Iceberg table aggregated daily-per-employee with derived
measures(hours_worked_clean, attendance_rate, late_arrival_flag, overtime_hours, absence_category).

Run daily at 03:00 UTC.

Apply data governance controls: hash/pseudonymize PII fields in Silver, suppress or mask sensitive fields in Gold, enforce retention policies,
and log processing metadata. Apply guidelines (This example is illustrative only and does not constitute compliance guidance.)

Please profile the data first, then propose your recommended quality thresholds and transforms before generating any code.
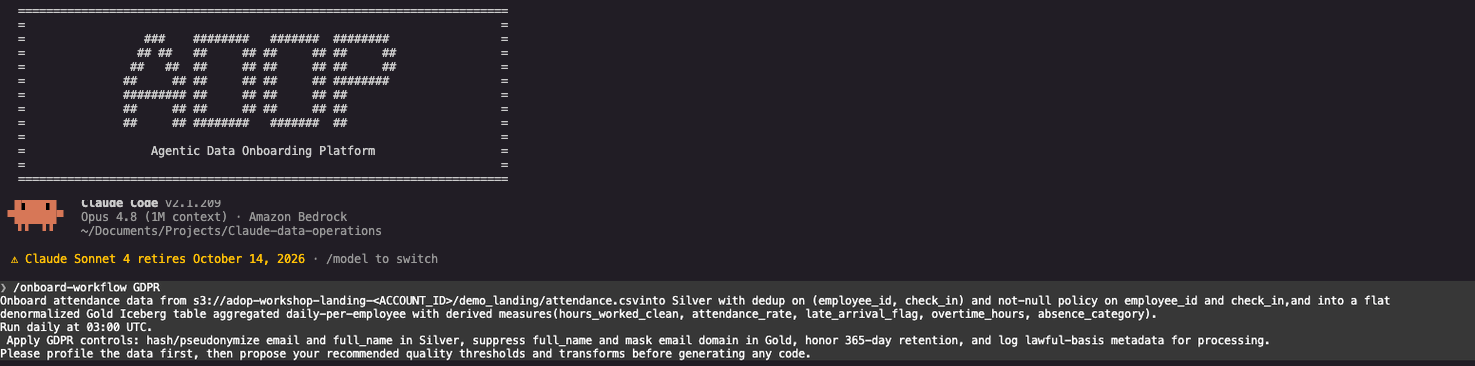
图 5:在 Amazon Bedrock 上的 Claude Code 中运行 ADOP 接入工作流
ADOP:从概念验证到生产环境
在早期几周,架构相关工作占比较高,因为对标准进行编码(而非构建管道)是一次性投入。契约建立后,每个新数据源只是一条提示词,而非一个项目。从趋势上看,采用这一模式的团队在后续数据源上的接入周期显著缩短;随着技能追踪记忆不断积累,该曲线还会进一步趋于平缓。
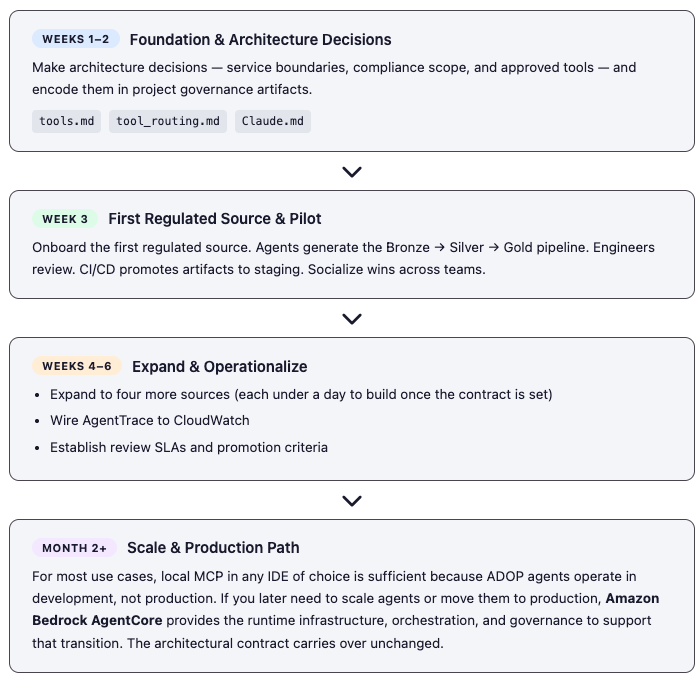
图 6:ADOP 从基础建设到生产环境的分阶段采用时间线
变革管理
转向 Agent 驱动的数据工程需要审慎的组织变革。以下计划旨在推动工程团队平稳采用,同时保留问责机制和质量标准。
利益相关方沟通——确定三个沟通层级:高管赞助人(CDO、工程副总裁)每月接收进度仪表板;平台和数据工程负责人每周获得 Sprint 摘要;个人贡献者则通过团队频道接收实时更新。信息传达应聚焦 ADOP 保留的内容(工程判断、架构标准),而不是它自动化的内容。在第一次赋能培训前,发布一页式 FAQ,解答关于 Agent 生成代码质量和岗位影响的常见疑问。
培训计划——第 1 周:由 AWS 主导的 ADOP 研讨会,涵盖架构契约设置、决策引擎配置和平台最佳实践。第 2 周:提示词编写实操实验室。每个团队在 AWS 指导下端到端接入一个低风险数据源。第 3 周:产物审查和护栏配置会议。工程师将 Agent 输出与自己的代码进行验证。第 4 至第 6 周:每周两次办公答疑,用于排障;从第 7 周开始降为每周一次。录制所有课程,以便未来团队成员异步入职学习。
分阶段推广策略——阶段 1(第 1 至第 3 周):选择两到三名工程骨干和一个非关键数据源开展试点。骨干成员验证输出质量,并提供反馈以完善架构契约。阶段 2(第 4 至第 6 周):扩展至完整的平台团队。接入 3 至 5 个复杂度递增的数据源。阶段 3(第 7 至第 12 周):全组织推广。新数据源接入均通过 ADOP 进行;现有管道则在计划维护窗口中择机迁移。
成功指标——跟踪四项关键指标:(1)数据源接入周期时间,目标是在阶段 3 实现显著缩短;(2)首次产物验收率,目标应根据组织自身质量标准确定;(3)工程满意度评分,在第 3、6 和 12 周通过匿名脉冲调查收集;(4)护栏合规率,衡量生成的管道在无需人工干预的情况下通过自动化策略检查的一致程度。
升级路径——第 1 级:工程骨干在其小组内解决提示词编写问题和小型产物调整。第 2 级:平台团队在一个 Sprint 内解决架构契约缺口、护栏配置错误或反复出现的产物拒绝问题。第 3 级:对于无法在平台层面解决的跨团队采用障碍、资源冲突或策略争议,由工程副总裁或 CDO 介入。将所有升级事项记录在共享日志中,以识别系统性问题,并将改进反馈至架构契约。
安全与数据隐私
Agent 驱动开发的一个常见担忧是,构建过程如何处理密钥、凭据和敏感数据。ADOP 通过多项设计选择解决这一问题。
密钥管理——密钥不会进入 Agent 上下文。数据库凭据、API 密钥和服务令牌会在部署时通过 AWS Secrets Manager 或您现有的密钥库解决方案进行解析。Agent 引用密钥 ARN 或占位符变量,不会在生成管道期间查看或处理实际凭据值。
数据隔离——敏感数据留在原处。Agent 使用模式元数据、样本行数和列统计信息,而不是原始生产数据。当需要进行数据剖析以生成质量规则时,它 r
English / 原文
Data engineering teams routinely spend weeks standing up a single new data source: writing ETL, hand-writing quality checks, updating semantic models, and validating compliance. The Agentic Data Operations Platform (ADOP) on AWS is designed to significantly accelerate that timeline. It’s a reference architecture built on Amazon Bedrock and your AI coding tool of choice. Specialized AI agents automate the full Bronze to Silver to Gold lifecycle, with configurable controls designed to support your data governance and regulatory compliance efforts.
For Heads of Data Engineering, three things change. Engineers stop spending the majority of their time on pipeline plumbing and start shipping data products. Compliance moves from a downstream gate to an inline control applied at onboarding time. And your architecture, not the model, governs how every AI coding tool (Claude Code, Kiro, Cursor, Codex) interacts with your data systems.
This blog post is for VPs of Engineering, Chief Data Officers, and Data Platform Directors, with implementation detail for platform engineers later in the post.
Figure 1: Six data engineering challenges that ADOP addresses
The agents in dev, artifacts in prod
This is the design choice that separates ADOP from a typical agentic platform pitch.
ADOP is a build-time accelerator , not a runtime dependency. Agents run in development environments where they reason, propose, and generate: ETL code, quality checks, semantic layer definitions, regulation controls. Engineers review the output. Continuous integration and continuous delivery (CI/CD) promotes the generated artifacts (deterministic PySpark, SQL, Airflow DAGs, IAM and Cedar policies) into staging and production. In ADOP’s default pattern, production runs deterministic artifacts without calling a model. Organizations that require model-in-the-loop inference at runtime can extend this architecture using Amazon Bedrock endpoints, but the generated pipeline code itself remains static and auditable.
Figure 2: ADOP token economics and return on investment
How ADOP differs from general-purpose coding assistants: Those are general-purpose coding assistants: brilliant, but open-ended. Point them at a data platform and every engineer gets a different architecture on a different day. ADOP is opinionated on purpose. It wraps those same models in:
- A narrowed lane – data-engineering skills and prompts, not “anything you can type.”
- Company philosophy baked in – your standards live in the design, not in someone’s memory.
- No large language model (LLM) freelancing on architecture – the model fills in the blueprint. It doesn’t draw it.
- Policy and regulation guardrails – apply controls that support your compliance efforts at build time, not only at review.
- One onboarding flow for the whole enterprise – every source lands the same way, every time.
General tools make a developer faster. ADOP makes every developer consistent.
How ADOP relates to Amazon Bedrock AgentCore: Amazon Bedrock AgentCore is a platform to build, connect, and optimize agents at scale, with any framework or model. ADOP runs agents in development and ships deterministic artifacts to production. Both are valid AWS aligned patterns. ADOP optimizes for cost predictability and audit posture on regulated data workloads.
Use cases
ADOP applies wherever data engineering velocity is throttled by manual onboarding and compliance overhead. Common patterns include:
- Enterprise data onboarding at scale – describe a new source in natural language. Agents handle schema inference, ETL, quality checks, and semantic layer updates.
- Regulated pipelines in healthcare and financial services – configurable controls designed to help you address regulatory requirements in your industry, applied per dataset through dedicated governance prompts. Customers are responsible for determining their own compliance.
- AI-ready Gold layers populated and maintained automatically for business intelligence and machine learning (ML) features.
- Multi-tool AI development governance – Claude Code, Kiro, Cursor, and Codex all operate from the same architectural contract.
Architecture
ADOP is an AI-powered coding framework that builds end-to-end data pipelines on AWS and multi-cloud environments. It launches a Data Onboarding Agent on Claude Code through Amazon Bedrock, using Claude Code’s Dynamic Workflow feature to spawn specialized sub-agents for each stage of pipeline construction.
Figure 3: ADOP architecture overview, with the Data Onboarding Agent spawning specialized sub-agents on Amazon Bedrock
Figure 4: ADOP lakehouse layers from Bronze to Silver to Gold, with built-in compliance controls
Sub-agents – Sub-agents handle metadata generation, data ontology deduction, data quality checks, ETL transformations, and orchestration (Airflow or AWS Step Functions). Requirements are enriched iteratively through conversational interaction with user persona, and every artifact is validated locally before deployment to AWS with human-in-the-loop approval.
Decision engine (AI clone) – The Decision Engine acts as an AI-encoded version of your enterprise architect, embedding your organization’s guidelines, technology standards, and design philosophy directly into the build process. This helps promote consistency across builders, alleviating the fragmentation that occurs when teams use general-purpose coding tools without shared guardrails.
Guardrails – Sub-agents are constrained by the architectural contract: tool routing rules, Cedar authorization policies, invariants, and inline compliance prompts. While the reference implementation targets AWS, the framework extends to other services with a CLI or Model Context Protocol (MCP) interface, supporting hybrid and multi-cloud environments.
Data compliance – Three capabilities round out the architecture. ADOP helps you apply compliance-related controls: one regulation prompt per governance framework can be applied at onboarding, so legal reviews a prompt file, not application code. You remain responsible for validating that controls meet your regulatory obligations.
Agent observability – Every agent decision is traced through AgentTrace (intent, tool selected, outcome, cost) and publishable to Amazon CloudWatch or an OpenTelemetry sink for audit. And the entire stack runs locally in dev by default. When scale demands it, promote to AgentCore runtime, a capability of Amazon Bedrock AgentCore, with no change to the architectural contract.
Responsible AI and data handling – Agents might process regulated or personally identifiable data during development. Customers should review their data-handling practices, apply appropriate access controls, and validate that agent behaviors align with their organization’s responsible-AI policies before promoting artifacts to production.
How to get started in two steps
-
Start by cloning the repository.
git clone https://github.com/aws-samples/sample-Agentic-Ai-Data-Operations.git -
Upload a dataset to Amazon Simple Storage Service (Amazon S3) or local storage, then run a modified prompt.
Note: The following example uses fictitious data, bucket names, and field references for illustration purposes only. No real personally identifiable information (PII) is represented. This example doesn’t constitute regulatory compliance guidance or legal advice.
/onboard-workflow

Onboard attendance data from s3://amzn-s3-demo-source-bucket/demo_landing/attendance.csv into Silver with dedup on (employee_id, check_in)
and not-null policy on employee_id and check_in,and into a flat denormalized Gold Iceberg table aggregated daily-per-employee with derived
measures(hours_worked_clean, attendance_rate, late_arrival_flag, overtime_hours, absence_category).

Run daily at 03:00 UTC.

Apply data governance controls: hash/pseudonymize PII fields in Silver, suppress or mask sensitive fields in Gold, enforce retention policies,
and log processing metadata. Apply guidelines (This example is illustrative only and does not constitute compliance guidance.)

Please profile the data first, then propose your recommended quality thresholds and transforms before generating any code.
Figure 5: Running the ADOP onboarding workflow in Claude Code on Amazon Bedrock
ADOP: proof of concept to production
The early weeks are architecture-heavy because encoding your standards (not building pipelines) is the one-time investment. After the contract exists, each new source is a prompt, not a project. Directionally, teams running this pattern have seen source onboarding timelines compress significantly on subsequent sources, with the curve flattening further as the skill-trace memory accumulates.
Figure 6: A phased ADOP adoption timeline from foundation to production
Change management
Transitioning to agent-driven data engineering requires deliberate organizational change. The following plan facilitates smooth adoption across engineering teams while preserving accountability and quality standards.
Stakeholder communication – Identify three communication tiers: executive sponsors (CDO, VP Engineering) receive monthly progress dashboards. Platform and data engineering leads get weekly sprint summaries. Individual contributors receive real-time updates through team channels. Frame messaging around what ADOP preserves (engineering judgment, architectural standards) rather than what it automates. Publish a one-page FAQ addressing common concerns about agent-generated code quality and job impact before the first enablement session.
Training schedule – Week 1: AWS-led ADOP workshop covering architecture contract setup, decision engine configuration, and platform best practices. Week 2: Hands-on prompt authoring lab. Each team onboards one low-risk source end-to-end with AWS guidance. Week 3: Artifact review and guardrail configuration session. Engineers validate agent output against their own code. Weeks 4–6: Office hours twice weekly for troubleshooting. Reduce to weekly from Week 7 onward. Record all sessions for asynchronous onboarding of future team members.
Phased rollout strategy – Phase 1 (Weeks 1–3): Pilot with two to three engineering champions and one non-critical data source. Champions validate output quality and provide feedback to refine the architectural contract. Phase 2 (Weeks 4–6): Expand to the full platform team. Onboard 3–5 additional sources of increasing complexity. Phase 3 (Weeks 7–12): Organization-wide rollout. New source onboarding flows through ADOP. Existing pipelines migrate opportunistically during scheduled maintenance windows.
Success metrics — Track four key indicators: (1) Source onboarding cycle time, targeting significant reduction by Phase 3. (2) First-pass artifact acceptance rate, with targets defined based on your organization’s quality standards. (3) Engineering satisfaction score through anonymous pulse surveys at Weeks 3, 6, and 12. (4) Guardrail compliance rate, measuring how consistently generated pipelines pass automated policy checks without manual intervention.
Escalation paths — Level 1: Engineering champions resolve prompt-authoring questions and minor artifact adjustments within their squad. Level 2: Platform team addresses architectural contract gaps, guardrail misconfigurations, or recurring artifact rejections within one sprint. Level 3: VP of Engineering or CDO intervenes for cross-team adoption blockers, resource conflicts, or policy disputes that cannot be resolved at the platform level. Document all escalations in a shared log to identify systemic issues and feed improvements back into the architectural contract.
Security and data privacy
A common concern with agent-driven development is how the build process handles secrets, credentials, and sensitive data. ADOP addresses this through several design choices.
Secrets management – Secrets don’t enter the agent context. Database credentials, API keys, and service tokens are resolved at deploy time through AWS Secrets Manager or your existing vault solution. Agents reference secret ARNs or placeholder variables. They don’t see or process actual credential values during pipeline generation.
Data isolation – Sensitive data stays in place. Agents work with schema metadata, sample row counts, and column statistics rather than raw production data. When data profiling is required for quality rule generation, it runs in an isolated sandbox against a scoped subset, and results are summarized before being returned to the agent context.
Data privacy – Model interactions are ephemeral. Conversations with Claude through Amazon Bedrock aren’t retained for model training (see Amazon Bedrock Data Privacy and Security FAQ. Prompts and responses exist only for the duration of the session, and inference stays within your AWS account boundary.
Network isolation – Network boundaries are respected. The local-first development model means agents run on developer machines or within your virtual private cloud (VPC). No data leaves your network unless you explicitly configure an external integration. When promoted to AgentCore runtime, the same network isolation policies apply at the service level.
Responsible AI considerations
ADOP agents generate pipeline code, data quality rules, and compliance controls based on schema metadata and natural-language prompts. Because these outputs are AI-generated, the following practices apply:
- Mandatory human review – Generated artifacts, especially compliance and regulation controls, must be reviewed by qualified engineers before promotion to production. Agent output is a draft, not a certified implementation.
- Hallucination risk – LLMs can produce plausible but incorrect logic. Generated masking rules, retention policies, or access controls might be incomplete or subtly wrong. Treat every generated control as unverified until validated by your legal or compliance team.
- Legal and compliance validation – AI-generated regulatory controls don’t constitute legal advice or a certified compliance implementation. Your legal, privacy, and compliance teams must validate that generated artifacts meet your specific regulatory obligations before deployment.
- Scope of trust – Agents work from schema metadata and configuration prompts, not from legal interpretation. They can’t assess regulatory applicability, jurisdictional nuance, or organizational risk tolerance.
Production AI controls with Amazon Bedrock Guardrails
ADOP treats Amazon Bedrock Guardrails as mandatory production controls in the architecture, not optional add-ons. Three capabilities apply to ADOP agents at the API layer:
Content filtering – Amazon Bedrock Guardrails enforce topic and content boundaries on every agent interaction, blocking outputs outside data-engineering scope. Filters are configured per agent role and enforced before responses reach artifact generation.
Grounding validation – Contextual grounding checks verify that agent outputs are anchored in schema metadata and the architectural contract. Responses failing grounding thresholds are rejected, helping prevent hallucinated logic from entering generated pipelines.
Sensitive information filters – PII detection and regex-based filters help prevent credentials or regulated data from surfacing in agent responses or generated code, complementing the secrets-management controls in the Security section.
These controls run inline with every agent invocation, forming a validation layer between the LLM and artifact output. They are configured once in the architecture contract and enforced uniformly across sub-agents.
Conclusion
ADOP encodes your enterprise architecture standards once, then lets agents apply them consistently across every new data source. The result: faster onboarding, uniform pipelines, and compliance controls applied from the start. Whether you run agents locally in your IDE or scale to Amazon Bedrock AgentCore, the architectural contract stays the same.
Resources
- AWS Show and tell video podcast
- It’s Safe to Close Your Laptop Now – Hosting Coding Agents on Amazon Bedrock AgentCore. When your ADOP agents outgrow local development, this guide covers promoting them to managed hosting on AgentCore for persistent, scalable execution.
- Spark on AWS Lambda – An Apache Spark Runtime for AWS Lambda. If your ADOP-generated pipelines need to compile PySpark code, the SoAL (Spark on AWS Lambda) architecture can significantly reduce token count by executing Spark jobs serverlessly without full cluster overhead.
About the authors
John Cherian
John is a Senior Solutions Architect (SA) at Amazon Web Services who helps customers with Data/AI strategy and architecture for building solutions on AWS.
Nuwan Bandara
Nuwan is a passionate technologist, excited about helping people and businesses realize value from technology. As a senior leader at Amazon Web Services, he works with fintech and capital markets customers to architect the future of financial infrastructure, specializing in AI/ML implementation, data strategy, and blockchain innovation.