驱动科学发现:BYOKG 与 GraphRAG 赋能智能药物研究
英文标题:Powering scientific discovery: BYOKG and GraphRAG for intelligent pharmaceutical research
在药物早期研发中,数据散落导致成功率仅5%、周期超过6个月,且机构知识易流失。本文介绍的 GraphRAG 与自带知识图谱(BYOKG)方法,通过 Amazon Neptune Analytics 的图处理与 Amazon Bedrock 的生成式 AI,将化合物、基因、疾病等实体连接为统一知识网络。研究者可用自然语言提出复杂问题,系统借助图遍历返回附有引用路径的证据化答案,大幅提升研究透明度和可重复性。文章详述了方案架构、实施步骤和成本,为开发者构建类似系统提供了蓝图。
 55.0 KB
 29.5 KB
 241.1 KB
 38.1 KB
 152.0 KB
 21.0 KB
 32.7 KB
 23.2 KB
 79.2 KB
 59.4 KB
中文
在药物研究中,科学家面临一项根本挑战:获取并连接分散在不同系统中的海量科学知识。从公开发表的文献、内部实验室笔记到基因组学数据库,关键洞察仍被困在孤岛中,使研究人员难以建立全面的联系并生成有前景的假设。这种碎片化拖慢了药物发现过程,还导致宝贵的机构知识因研究人员离职而流失,最终影响整个行业高效研发的能力。对能够智能弥合这些知识鸿沟、同时保持科学完整性的解决方案的需求变得日益迫切。
挑战:数据散落于碎片化系统
在领先的制药公司,研究人员在早期药物发现阶段面临严峻挑战:传统方法的成功率仅为 5%,初始筛选耗时超过六个月。科学家们竭力连接散落在不同系统中的洞察,包括 PubMed、内部实验室笔记和基因组学数据库,同时还要与竞争对手和时间赛跑。数据的分散导致重复劳动和错失机会,也使追踪监管审批所需的证据链变得困难。当研究人员离职时,往往会带走宝贵的隐性知识,进一步削弱突破性发现所需的机构记忆。
早期药物发现的挑战:
- 成功率和时间效率低下——每次筛选命中率仅5%,耗时超过6个月。
- 知识系统碎片化——关键洞察散落于 PubMed、实验室笔记和数据库,导致联系缺失。
- 机构记忆流失——研究人员离职时,有价值的知识随之消失,破坏研究的连续性。
这些挑战共同构成了药物发现管线中的重大瓶颈,导致效率低下、错失机会,并可能延误挽救生命的疗法。我们的方案通过超越传统方法来解决这些瓶颈:图驱动的 AI 通过构建互联的知识环境来支持药物研究。使用 Amazon Neptune Analytics,研究人员现在可以用自然语言提出复杂问题,并从统一的知识图谱中即刻获得有证据支持的洞察,该图谱连接了化合物相互作用、基因表达和临床研究等方方面面。这种方法不仅提供答案,还通过展示详细的引用路径和图遍历步骤,揭示每个结果背后的完整推理过程。通过暴露系统如何遍历相互关联的研究论文和数据点,它使科学发现更加透明和可重复。
通过结合图与生成式 AI,科研人员不仅能检索信息,还能放大推理能力、保留机构记忆,并浮现原本会被埋没的洞察。这也有助于他们生成更好的假设、更快行动,并信任输出结果,因为每条洞察都附有背景和证据。在一个延误成本以金钱和生命衡量的领域,这种转变不仅仅是锦上添花,而是改变了研究的开展方式。
在本文中,我们将探索基于图的检索增强生成(GraphRAG)如何通过将图数据库与生成式 AI 相结合,来变革科学研究。借助这种方法,可以在不损害科学完整性的前提下加快发现进程。
通过将用于高性能图处理的 Amazon Neptune Analytics 与 Amazon Bedrock 集成,研究人员可以构建既理解复杂科学关系,又提供直观自然语言界面的复杂系统。GraphRAG 架构通过智能遍历知识图谱来识别相关信息路径,从而提高 AI 生成响应的质量,确保响应牢牢锚定在已验证的科学数据之上。
该方案对科学研究的强大之处在于,它能够理解并连接从植物、化合物到蛋白质、基因及其相关健康影响等实体间的复杂关系。有了这种全面的理解,研究人员可以更高效地发现洞察,并更有信心地做出数据驱动决策。
解决方案概述
该方案通过自带知识图谱(Bring Your Own Knowledge Graph, BYOKG)方法并增强 GraphRAG 能力,重新构想了研究流程。知识图谱是一种信息的结构化表示,以互连节点和边的网络形式展示不同实体间的关系。在 Amazon Neptune 的支持下,它将多样化的科学实体(植物、化合物、基因、蛋白质和健康影响)整合进一个统一的知识网络中,连接了 PubMed、基因本体等公共来源和专有数据集。自动化摄取管道和图算法持续丰富图谱,帮助研究人员发现在原本脱节的数据孤岛中隐藏的复杂生物关系和洞察。
使用 Neptune Analytics 和 Amazon Bedrock,该方案将图算法与自然语言查询相结合,使科学探索既具分析性又直观易用。研究人员可以用简单的英语提出复杂问题,并获得源自图遍历的、有证据支持的答案,这些答案附有完整的源引用和可视化路径。交互式可视化工具进一步提高了透明度和理解力,允许用户探索关系、追溯假设到结论,并用清晰、可验证的证据验证结果。这加速了发现过程,并增强了跨领域的科学严谨性。
解决方案架构
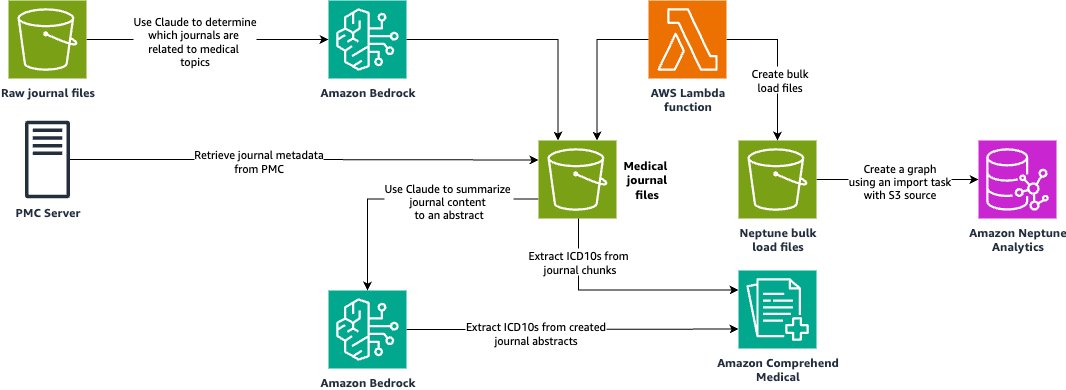
我们的方案可帮助研究人员快速发现跨疾病和主题的相关医学期刊文章。数据集包含由 PMC 开放获取子集(CC BY 和 CC0 许可证)提供的 HCLS 期刊文章、通过 Bio.Entrez 包由美国国家生物技术信息中心(NCBI)提供的期刊元数据、疾病本体层次结构,以及使用 Amazon Comprehend Medical 中的 ICD-10-CM 链接 API 提取的 ICD10 代码。尽管最终数据集会提供给您,以下架构描述了创建该数据集所使用的流程。
下图展示了使用 Amazon Bedrock 和 Amazon Comprehend 等服务将数据加载到 Amazon Neptune Analytics 中的流程。
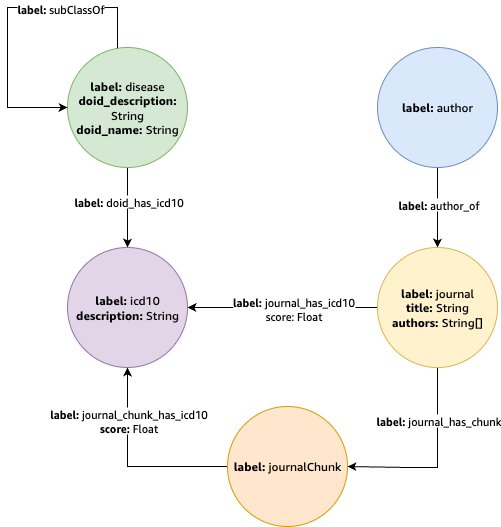
以下图像展示了最终图谱,其中包含以下节点类型:
- disease:表示疾病本体中的一种疾病。疾病本体提供映射,帮助我们理解哪些疾病是其他疾病的子类。
- author:表示某期刊的作者。
- journal:表示一种期刊。
- journalChunk:表示某期刊的一个分块。分块使用 Amazon Bedrock 知识库提供的默认分块策略确定。
- icd10:表示一个 ICD-10 代码,这是一种标准化的医疗问题分类。
icd10节点与journal和journalChunk节点之间的边是通过 Amazon Comprehend Medical ICD-10-CM 链接创建的。
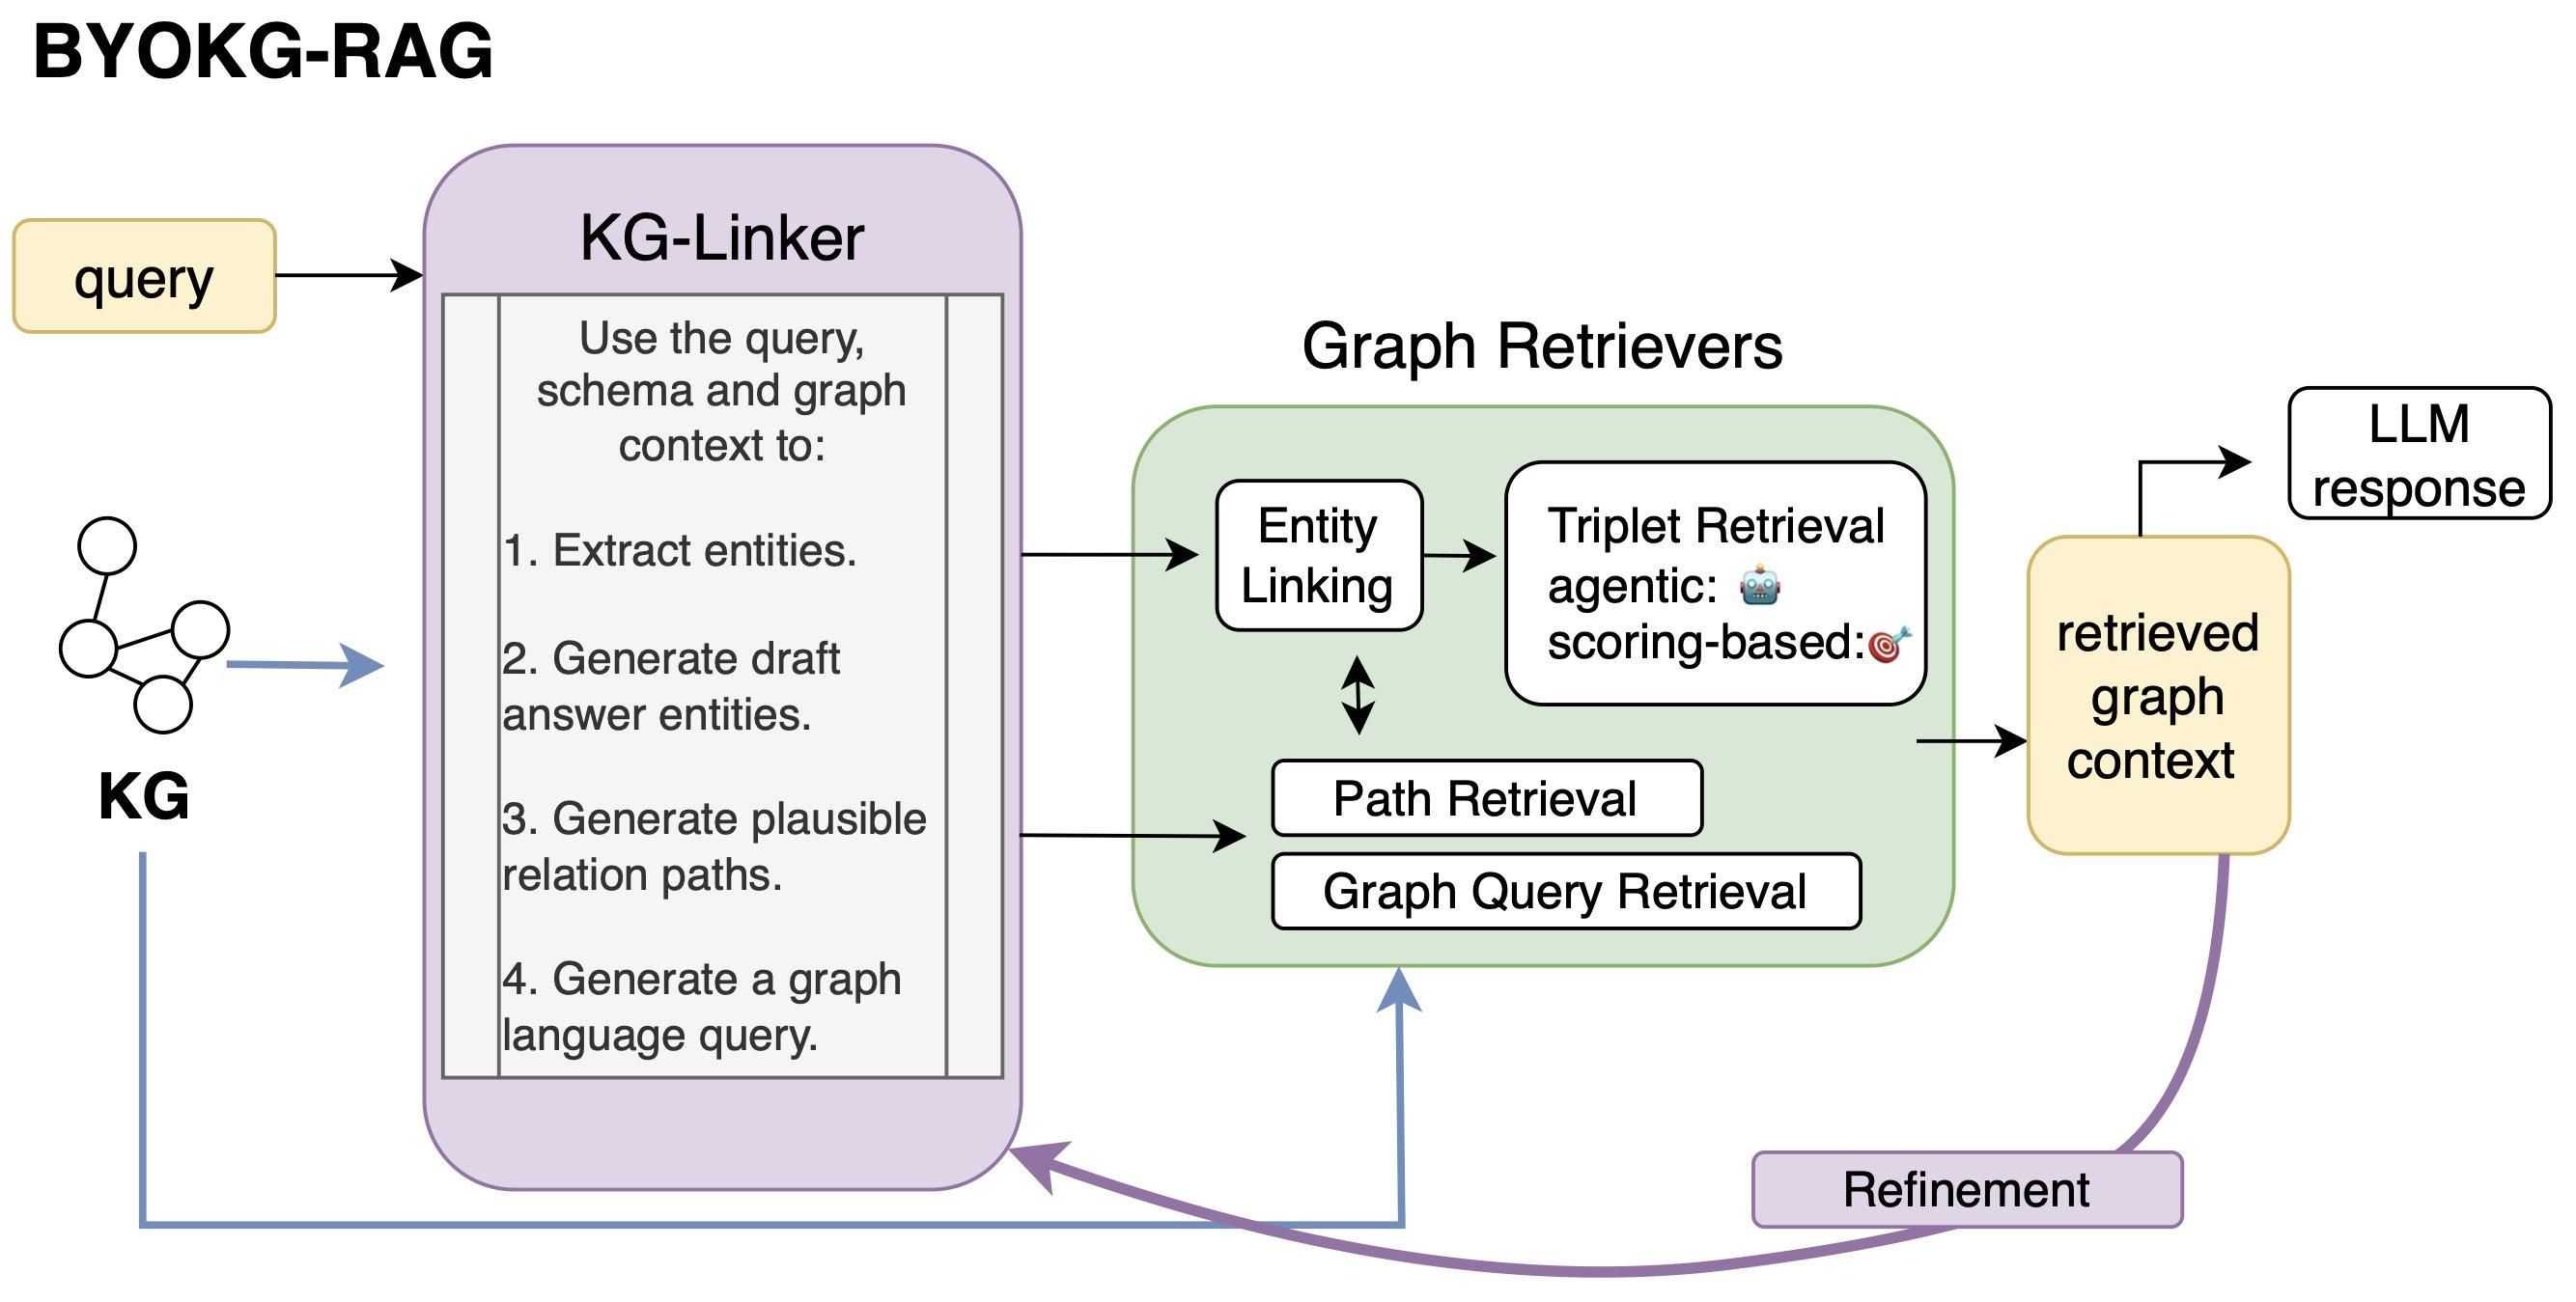
由于我们使用自己的图数据模型,我们采用了 BYOKG-RAG 工具包来实现对图谱的自然语言查询。下图展示了 BYOKG 的组成部分。
先决条件
在开始之前,请确保具备以下先决条件:
- AWS 命令行界面(AWS CLI)2.11.0 或更高版本已安装并配置(安装指南)
- 访问以下 AWS 服务:
- Amazon Neptune Analytics
- Amazon Bedrock(Claude 4.5 Sonnet 模型)
- Amazon SageMaker
- Amazon Simple Storage Service (Amazon S3)
- Amazon Comprehend Medical
- 具有以下权限的 IAM 角色:
- NeptuneAnalyticsFullAccess
- AWSServiceRoleForAmazonNeptuneAnalytics
- AmazonS3ReadOnlyAccess
- AmazonBedrockFullAccess
- ComprehendMedicalFullAccess
- Python 3.9 或更高版本
- graphrag_toolkit 1.0.0 或更高版本
- Jupyter Notebook 环境
方案成本概览
运行此演示的成本估算(每小时):
- Neptune Analytics 图,16 mNCU,无备用,公共连接 – 0.48 美元/小时。
- SageMaker Jupyter 笔记本,t3.medium 配备 5 GB EBS 卷 – 计算 0.05 美元/小时加存储 0.70 美元/小时。
- S3 标准存储,161 MB – 0.161 GB × 0.023 美元 = 每月 0.0037 美元。
- Amazon Bedrock – Amazon Bedrock 的费用取决于模型使用情况和令牌消耗。最新信息请参阅定价页面。
设置 Neptune Analytics
下面开始实施您的 GraphRAG 解决方案,首先设置 Neptune Analytics。以下步骤将引导您完成数据导入、图创建和笔记本配置,以构建知识图谱基础:
-
创建一个 S3 存储桶:
aws s3 mb s3://amzn-s3-bucket-name。 -
使用 AWS CLI 将数据集复制到您自己的存储桶中:
aws s3 sync s3://aws-neptune-customer-samples-us-east-1/sample-notebooks/vector-graph-hybrid-search/graph-data/ s3://amzn-s3-bucket-name/<您的 PREFIX> -
使用
CreateGraphUsingImportTaskAPI 创建 Neptune Analytics 图,从您在上一步中复制到的 Amazon S3 位置导入。有关操作方法,请参见 Neptune Analytics 用户指南。将最小和最大预置内存设置为 16。 -
在图创建过程中,创建一个与该图关联的 Neptune Notebook。笔记本可让您轻松查询和与图交互,以及设置和运行 GraphRAG 工具包。有关创建 Neptune Notebook 的详细信息,请参见 Neptune Analytics 用户指南。
-
下载示例笔记本,并将其上传到您的 Jupyter 环境。
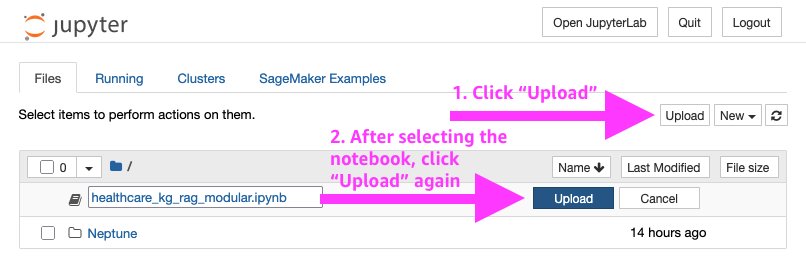
在此笔记本中,我们展示了在医疗知识图谱之上构建检索增强生成(RAG)系统的模块化方法,使用了 graphrag-toolkit Python 包和 Amazon Bedrock Anthropic Claude 4.5 Sonnet 模型。该解决方案支持对知识图谱进行自然语言查询和实体链接,将先进的语言模型生成与结构化图谱数据检索相结合。
关键组件
- 语言模型初始化
我们首先初始化基于 Amazon Bedrock 的语言模型生成器,为自然语言响应提供动力。
from graphrag_toolkit.byokg_rag.llm import BedrockGenerator

def init_llm_generator(model_name='us.anthropic.claude-3-5-sonnet-20240620-v1:0', region_name='us-west-2'):
    return BedrockGenerator(
        model_name=model_name,
        region_name=region_name
    )

llm_generator = init_llm_generator()
- 知识图谱链接器设置
KGLinker通过传递图存储和语言模型生成器进行初始化。它充当查询图谱和生成答案的核心接口。
from graphrag_toolkit.byokg_rag.graph_connectors import KGLinker

def init_kg_linker(graph_store, llm_generator):
    return KGLinker(graph_store=graph_store, llm_generator=llm_generator)

kg_linker = init_kg_linker(graph_store, llm_generator)
- 从查询生成响应
使用
kg_linker,我们可以提出自然语言问题,并获取受知识图谱上下文增强的生成响应。
def generate_kg_response(kg_linker, question, schema, graph_context="Not provided. Use the above schema to un
English / 原文
In pharmaceutical research, scientists face a fundamental challenge: accessing and connecting the vast amount of scientific knowledge scattered across disparate systems. From published literature and internal lab notes to genomics databases, critical insights remain trapped in silos, making it difficult for researchers to form comprehensive connections and generate promising hypotheses. This fragmentation slows down the drug discovery process. It also risks valuable institutional knowledge being lost as researchers transition, ultimately affecting the industry’s ability to research and develop efficiently. The need for a solution that can intelligently bridge these knowledge gaps while maintaining scientific integrity has become increasingly important.
The challenge: Scattered data across fragmented systems
At leading pharmaceutical companies, researchers face a critical challenge in early-stage drug discovery, where traditional methods yield only a 5 percent success rate and initial screening takes over six months. Scientists struggle to connect insights buried across fragmented systems such as PubMed, internal lab notes, and genomics databases, all while racing against competitors and time constraints. The scattered nature of data leads to redundant work and missed opportunities. It also makes it difficult to trace the evidence trail needed for regulatory approval. When researchers depart, they often take valuable tacit knowledge with them, further compromising the institutional memory needed for breakthrough discoveries.
Challenges in early-stage drug discovery:
- Poor success rate and time efficiency – Only 5 percent hit rate with over 6 months of screening time per attempt.
- Fragmented knowledge systems – Critical insights scattered across PubMed, lab notes, and databases, leading to missed connections.
- Loss of institutional memory – Valuable knowledge disappears when researchers leave, breaking continuity in research efforts.
These challenges collectively create a significant bottleneck in the drug discovery pipeline, leading to inefficiencies, missed opportunities, and potential delays in developing life-saving treatments. Our solution addresses these bottlenecks by moving beyond traditional methods: graph-powered AI supports pharmaceutical research by creating an interconnected knowledge environment. Using Amazon Neptune Analytics, researchers can now ask complex questions in natural language and receive instant, evidence-backed insights drawn from a unified knowledge graph that connects everything from compound interactions to gene expressions and clinical studies. This approach doesn’t only provide answers. It reveals the complete reasoning behind each result by showing detailed citation paths and graph traversal steps. By exposing how the system navigates through interconnected research papers and data points, it makes scientific discovery more transparent and reproducible.
By combining graph and generative AI, research scientists don’t only retrieve information. They can amplify reasoning, preserve institutional memory, and surface insights that would otherwise stay buried. It also helps them generate better hypotheses, move faster, and trust the outputs, because every insight comes with context and proof. In a field where the cost of delay is measured in both dollars and lives, this shift is more than helpful. It changes how research gets done.
In this post, we explore how Graph-based Retrieval Augmented Generation (GraphRAG) is transforming scientific research by combining graph databases with generative AI. With this approach, you can accelerate discovery processes without compromising scientific integrity.
By integrating Amazon Neptune Analytics for high-performance graph processing with Amazon Bedrock, researchers can build sophisticated systems that not only understand complex scientific relationships but also provide intuitive natural language interfaces. The GraphRAG architecture helps enhance the quality of AI-generated responses by intelligently traversing knowledge graphs to identify relevant information paths. This makes sure that the responses are firmly anchored in verified scientific data.
What makes this solution powerful for scientific research is its ability to understand and connect intricate relationships between entities, from plants and compounds to proteins, genes, and their associated health effects. With this comprehensive understanding, researchers can uncover insights more efficiently and make data-driven decisions with greater confidence.
Solution overview
The solution reimagines the research process through a Bring Your Own Knowledge Graph (BYOKG) approach enhanced with GraphRAG capabilities. A knowledge graph is a structured representation of information that shows relationships between different entities as a network of interconnected nodes and edges. Powered by Amazon Neptune, it integrates diverse scientific entities (plants, compounds, genes, proteins, and health effects) into a unified knowledge network that bridges data from public sources like PubMed and Gene Ontology with proprietary datasets. Automated ingestion pipelines and graph algorithms continuously enrich the graph, helping researchers uncover complex biological relationships and insights that were previously hidden across disconnected data silos.
Using Neptune Analytics and Amazon Bedrock, the solution combines graph algorithms with natural language querying to make scientific exploration both analytical and intuitive. Researchers can ask complex questions in plain English and receive evidence-based answers derived from graph traversal, complete with source citations and visual pathways. Interactive visualization tools further help enhance transparency and understanding, allowing users to explore relationships, trace hypotheses to conclusions, and validate results with clear, verifiable evidence. This accelerates discovery and strengthens scientific rigor across domains.
Solution architecture
Our solution helps researchers quickly discover relevant medical journal articles across conditions and topics. The dataset includes the HCLS journal articles provided by the PMC Open Access Subset licensed with CC BY and CC0 licenses, journal metadata provided by the National Center for Biotechnology Information (NCBI) via the Bio.Entrez package, Disease Ontology hierarchies, and ICD10 codes that have been extracted using the ICD-10-CM linking API within Amazon Comprehend Medical. Although the final dataset is provided to you, the following architecture depicts the flow used to create the dataset.
The following diagram illustrates the loading of the data to Amazon Neptune Analytics using services like Amazon Bedrock and Amazon Comprehend to extract data from medical journals.
The following image represents the final graph, which contains these node types:
- disease : Represents a disease within the Disease Ontology. The Disease Ontology provides a mapping to help us understand which diseases are subclasses of other diseases.
- author : Represents an author of a particular journal.
- journal : Represents a journal.
- journalChunk : Represents a chunk of a given journal. Chunks were determined using the default chunking strategy provided through Amazon Bedrock Knowledge Bases.
- icd10 : Represents an ICD-10 code, which is a standardized classification of medical issues. Edges between
icd10nodes andjournalandjournalChunknodes were created using the Amazon Comprehend Medical ICD-10-CM linking.
Because we’re using our own graph data model, we use the BYOKG-RAG toolkit to implement natural language querying over the graph. The following diagram illustrates the components of BYOKG.
Prerequisites
Before getting started, make sure you have the following prerequisites:
- AWS Command Line Interface (AWS CLI) version 2.11.0 or later installed and configured (installation guide)
- Access to the following AWS services:
- Amazon Neptune Analytics
- Amazon Bedrock (Claude 4.5 Sonnet model)
- Amazon SageMaker
- Amazon Simple Storage Service (Amazon S3)
- Amazon Comprehend Medical
- IAM role with the following permissions:
- NeptuneAnalyticsFullAccess
- AWSServiceRoleForAmazonNeptuneAnalytics
- AmazonS3ReadOnlyAccess
- AmazonBedrockFullAccess
- ComprehendMedicalFullAccess
- Python 3.9 or later
- graphrag_toolkit version 1.0.0 or later
- Jupyter Notebook environment
Solution cost overview
Cost approximation (per hour) for running this demo:
- Neptune Analytics graph, 16 mNCU, no standby, public connectivity – $0.48/hour.
- SageMaker Jupyter notebook, t3.medium with 5 GB of EBS volume – $0.05/hour for compute plus $0.70/hour for storage.
- S3 storage, standard, 161 MB – 0.161 GB × $0.023 = $0.0037 per month.
- Amazon Bedrock – The cost for Amazon Bedrock depends on model usage and token consumption. For the most up-to-date information, see the pricing page.
Setting up Neptune Analytics
Let’s begin implementing your GraphRAG solution by setting up Neptune Analytics. The following steps will guide you through data import, graph creation, and notebook configuration to build your knowledge graph foundation:
-
Create an S3 bucket:
aws s3 mb s3://amzn-s3-bucket-name. -
Copy the dataset into your own buckets using the AWS CLI:
aws s3 sync s3://aws-neptune-customer-samples-us-east-1/sample-notebooks/vector-graph-hybrid-search/graph-data/ s3://amzn-s3-bucket-name/<YOUR PREFIX> -
Create a Neptune Analytics graph using the
CreateGraphUsingImportTaskAPI to import from the Amazon S3 location you copied to in the first step. For details on how to do this, see the Neptune Analytics User Guide. Set the minimum and maximum provisioned memory to 16. -
While the graph is creating, create a Neptune Notebook associated with the graph. The notebook makes it straightforward to query and interact with the graph, as well as set up and run the GraphRAG Toolkit. For details on how to create a Neptune Notebook, see the Neptune Analytics User Guide.
-
Download the sample notebook, and upload it to your Jupyter environment.
In this notebook, we demonstrate a modular approach to building a Retrieval Augmented Generation (RAG) system over a healthcare knowledge graph, using the graphrag-toolkit Python package and the Amazon Bedrock Anthropic Claude 4.5 Sonnet model. This solution supports natural language querying and entity linking within a knowledge graph, combining advanced language model generation with structured graph data retrieval.
Key components
- Language model initialization
We begin by initializing the Amazon Bedrock-based language model generator that powers our natural language responses.
from graphrag_toolkit.byokg_rag.llm import BedrockGenerator

def init_llm_generator(model_name='us.anthropic.claude-3-5-sonnet-20240620-v1:0', region_name='us-west-2'):
    return BedrockGenerator(
        model_name=model_name,
        region_name=region_name
    )

llm_generator = init_llm_generator()
- Knowledge graph linker setup The
KGLinkeris initialized by passing the graph store and the language model generator. It acts as the core interface to query the graph and generate answers.
from graphrag_toolkit.byokg_rag.graph_connectors import KGLinker

def init_kg_linker(graph_store, llm_generator):
    return KGLinker(graph_store=graph_store, llm_generator=llm_generator)

kg_linker = init_kg_linker(graph_store, llm_generator)
- Generating responses from queries
With thekg_linker, we can pose natural language questions and obtain generated responses augmented by the knowledge graph context.
def generate_kg_response(kg_linker, question, schema, graph_context="Not provided. Use the above schema to understand the graph."):
    return kg_linker.generate_response(
        question=question,
        schema=schema,
        graph_context=graph_context
    )

# Example usage
response = generate_kg_response(kg_linker, question, schema)
print(response)
- Entity linking for enhanced retrieval
To improve information extraction and link natural language text to graph entities, we use a fuzzy string index combined with theEntityLinker.
from graphrag_toolkit.byokg_rag.indexing import FuzzyStringIndex
from graphrag_toolkit.byokg_rag.graph_retrievers import EntityLinker

def init_and_link_entities(graph_store, artifacts):
    string_index = FuzzyStringIndex()
    string_index.add(graph_store.nodes())
    retriever = string_index.as_entity_matcher()
    entity_linker = EntityLinker(retriever=retriever)

    linked_entities = entity_linker.link(artifacts["entity-extraction"], return_dict=False)
    linked_answers = entity_linker.link(artifacts["draft-answer-generation"], return_dict=False)

    return entity_linker, linked_entities, linked_answers

entity_linker, linked_entities, linked_answers = init_and_link_entities(graph_store, artifacts)
Summary
This modular structure cleanly separates the following components:
- Large language model (LLM) initialization (using Amazon Bedrock).
- Knowledge graph interfacing (
KGLinker). - NLP (natural language querying).
- Entity linking on graph nodes.
The modular structure allows flexible experimentation and straightforward extension for different domains or datasets.
The integration of a fuzzy string matcher facilitates robust entity recognition, which is important in noisy or complex healthcare data contexts.
By combining the Amazon Bedrock advanced language models with structured graph querying and linking, this solution forms a powerful foundation for context-aware question answering and information retrieval over knowledge graphs.
Solution benefits and performance metrics
The following key performance indicators from our implementation of the solution demonstrate how this GraphRAG solution can create measurable value and competitive advantage for pharmaceutical research organizations:
- Research timeline acceleration – GraphRAG reduces research cycles from six months to three weeks, delivering an 87 percent efficiency boost. This supports rapid hypothesis testing and faster scientific breakthroughs.
- Success rate optimization – GraphRAG reduced research cycles in our implementation from six months to three weeks. The solution is powered by advanced graph algorithms. Cross-domain analysis facilitates more effective research directions and optimal resource deployment.
- Workflow efficiency gains – Key metrics show measurable improvements in our tests: 70 percent reduction in review time, 85 percent faster data access, and 90 percent enhanced knowledge use. Teams can focus on strategic research priorities.
- Data-driven validation – Advanced tracking and visualization facilitate full research transparency. Clear data pathways strengthen regulatory compliance and improve scientific communication.
- Intelligent knowledge integration – The system efficiently scales and integrates new data sources with minimal resource impact. Enhanced collaboration preserves vital institutional knowledge.
- Industry leadership enablement – Accelerated innovation cycles maintain scientific rigor while speeding industry entry. This helps create sustainable competitive advantages and industry leadership positions.
Clean up
To avoid incurring additional charges, clean up the resources created in this post.
- Delete the Neptune Analytics graph by following these steps or by running the following CLI command.
Note: Replace g-sample with the graph created.
aws neptune-graph delete-graph --graph-id g-sample - Delete the graph notebook created in the AWS Management Console by selecting the instance, choosing the Actions menu, and selecting the Delete option.
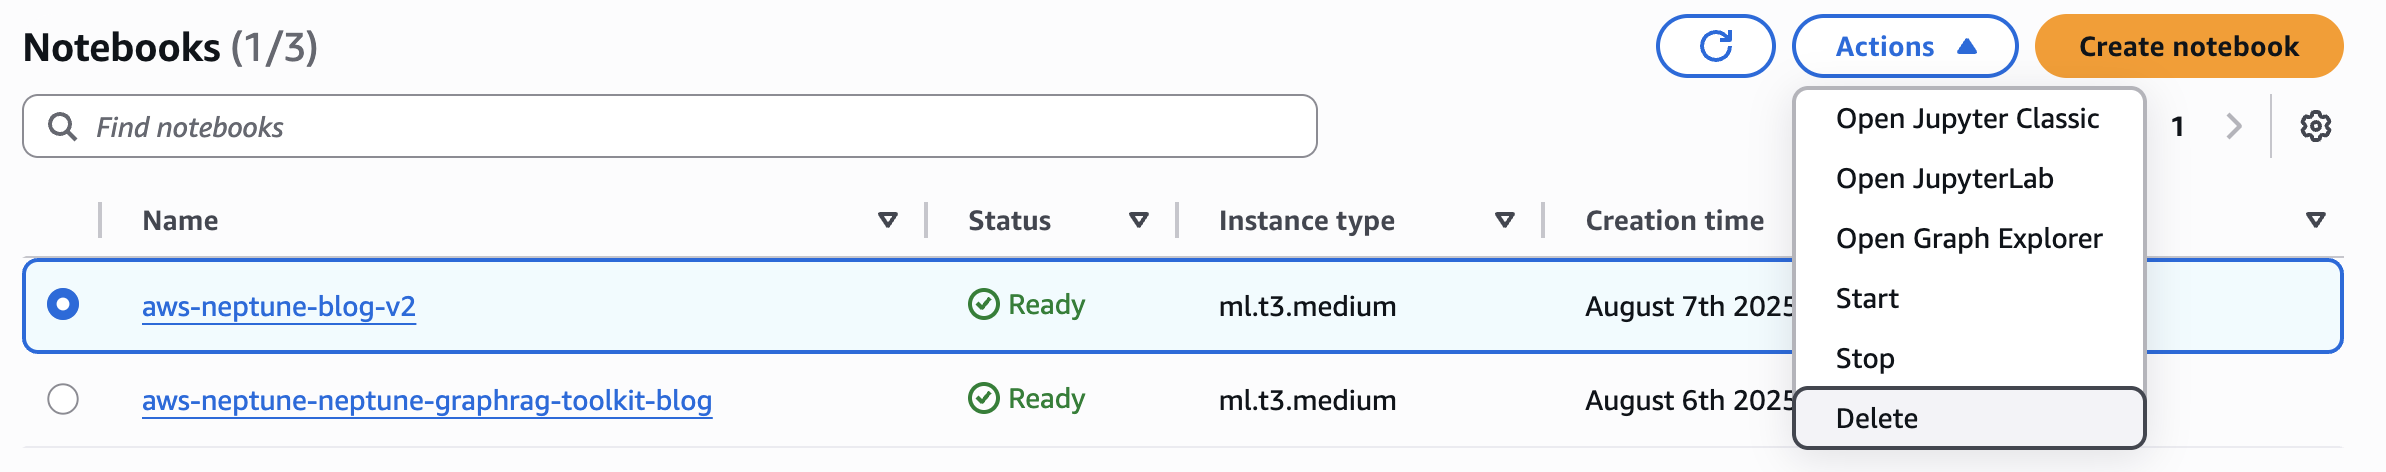
- Delete the S3 bucket created by following these steps or by running the CLI command.
Note: Replace amzn-s3-bucket-name with the name of the bucket created.
aws s3 rb s3://amzn-s3-bucket-name --force
Conclusion
The integration of GraphRAG technology with Amazon Neptune Analytics and Amazon Bedrock represents a significant advancement in scientific research methodology. Researchers can now connect previously siloed data sources, interact with complex datasets using natural language queries, and visualize intricate relationships. This solution can deliver immediate, measurable impact for research organizations by reducing research cycle times by up to 87 percent and increasing discovery hit rates five-fold. It not only accelerates the pace of discovery but also helps enhance the quality and credibility of scientific findings. This solution supports rapid scientific advancements, potentially leading to outcomes that were unattainable within traditional research timeframes. Organizations that adopt generative AI solutions are not only improving their research processes. They are positioning themselves at the forefront of scientific innovation, ready to tackle the most complex challenges of our time with greater speed and accuracy.
About the authors
Jasmine Rasheed Syed
Jasmine is a Sr. Customer Solutions Manager at AWS, focused on accelerating time to value for customers on their cloud and AI journey by adopting best practices, mechanisms, and AI-powered solutions to transform their business at scale. He partners with customers to identify high-impact AI/ML use cases and helps them move from experimentation to production faster. Jasmine is a seasoned, results-oriented leader with 22+ years of experience in Insurance, Retail & CPG, and Media & Entertainment. He brings a unique ability to bridge the gap between cutting-edge AI capabilities and real-world business outcomes, enabling organizations to harness the full potential of generative AI, machine learning, and data-driven decision-making.
Jagadish Maripi
Jagadish is a Solutions Architect at AWS with over 20 years of experience architecting enterprise applications and implementing DevOps practices. He is passionate about helping customers build secure, scalable architectures and accelerating delivery through automation and modern cloud-native patterns. He enjoys sharing knowledge and exploring emerging technologies with the broader community.
Ramprasath S
Ramprasath is a Senior Applied AI Architect at AWS, specializing in enterprise-scale Generative AI and agentic workflows. He turns complex ML and cloud challenges into production-ready solutions, with deep expertise in Amazon Bedrock, SageMaker, and multi-agent orchestration. He is passionate about AI safety, model evaluation, and sharing best practices with the AWS community.
Oscar Hernandez
Oscar is a Senior Account Executive at AWS, focused on driving AI workload adoption and cloud strategy for global enterprises. He works with executive leaders to identify high-impact AI opportunities and build long-term technology roadmaps that deliver sustained business value. With over 15 years of experience in cloud and enterprise technology, Oscar specializes in helping customers navigate rapid technological change and accelerate production AI deployments at scale.