Qwen3.8-Flash-Next
英文标题:Qwen3.8-Flash-Next
Qwen 发布了另一款开放权重模型 Qwen3.8-Flash-Next,这是一款多模态 MoE 模型,也是 Qwen4 所用架构的早期预览。该模型规模为 125B token,但仅激活 6B,因此可获得显著的性能提升。作者正在 DGX Spark 上通过 Unsloth 提供的量化模型进行测试,并已尝试 UD-IQ1_S 与 UD-Q2_K_XL 两个版本。
 201.4 KB
中文
2026 年 8 月 26 日
Qwen3.8-Flash-Next(经由)Qwen 推出的另一款开放权重模型。这是一款“多模态 MoE 模型,同时也是 Qwen4 所采用架构的早期预览”。
它的规模相当大:125B token,但其中只有 6B 处于激活状态,这意味着它能获得显著的性能提升。
我一直在 DGX Spark 上使用这些由 Unsloth 提供的量化模型测试它。我仍在探索这款模型——目前为止,我尝试了 72.5GB 的 UD-IQ1_S 版本(生成了这些鹈鹕),以及 78.9GB 的 UD-Q2_K_XL 版本(生成了这些内容)。
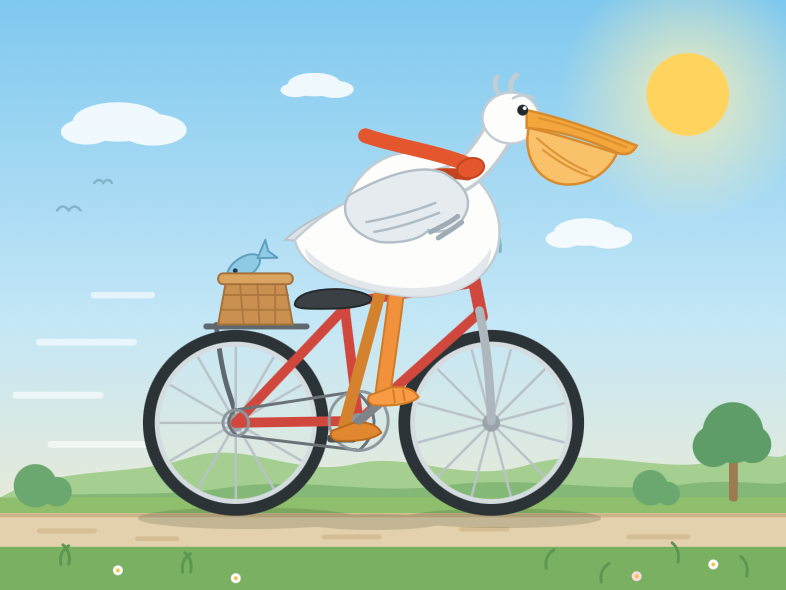
到目前为止,我最喜欢的是由 UD-Q2_K_XL 以 xhigh 推理力度生成的这一张:
English / 原文
26th August 2026 - Link Blog
Qwen3.8-Flash-Next (via) Another open weights model from Qwen. This one is "a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4".
It's pretty big: 125B tokens, but only 6B active which means it gets a significant performance boost.
I've been trying it out on a DGX Spark using these Unsloth quantized models. I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans) and the 78.9GB UD-Q2_K_XL (producing these).
My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL: