GPT-6 Astra、循环 Transformer 与隐藏推理
英文标题:GPT-6 Astra, Looped Transformers, and Hidden Reasoning
OpenAI 发布的 GPT-6 Astra 被作者评价为目前使用过的最佳模型之一,尤其在 3D 渲染、动画、图形界面操作和计算机使用任务上表现突出。独立基准显示,Astra 在数学、编程及智能体编程任务中位居前沿,并在 ARC-AGI-3 上达到 99.9%,显著高于 GPT-5.6 Sol 的 7.8%。文章还讨论了有关 Astra 使用“循环 Transformer”或“递归深度”架构、以及是否隐藏思维链的传闻。对开发者而言,模型能力提升意味着应重新审视 AGENTS.md、SKILL.md 等旧有提示与工作流说明,同时为日益成熟的 GUI 自动化和计算机使用智能体做好准备。
 4.5 KB
 5.1 KB
 1.4 KB
 120.5 KB
 128.0 KB
 145.8 KB
 133.0 KB
 268.9 KB
 360.6 KB
 115.0 KB
中文
过去几周发生了很多事。我相信,OpenAI 的 GPT-6 Astra 现在一定是所有人最关注的话题。尤其是对于它性能的看法、循环 Transformer/递归深度方面的特性,以及关于 Astra 正在“隐藏”其推理轨迹(即思维链)的传闻。
因此,本文将先分享一些关于 Astra 的简要印象,以及对这一趋势未来走向的一些思考。随后,我会详细讨论什么是“循环 Transformer”,以及这与隐藏思维链究竟如何相关(或者说,是否相关)。
最后,在介绍循环 Transformer 的基础知识后,我还想重点介绍近期相关研究论文带来的一些新见解。
首先,在深入讨论架构传闻及相关研究文献之前,让我先简要总结一下关于 GPT-6 Astra 的一些观察和信息。
上周,OpenAI 高调发布了新的 GPT-6 Astra。我在过去几天里使用了它;它是一款异常出色的模型,在写作本文时,很可能是我用过的最好的模型。但它究竟提升了什么,又是如何提升的?
Astra 是我目前使用过的最佳模型,而且相较于其他模型,它在 3D 渲染和动画任务上的表现尤其突出。我的意思是,尽管它几乎在所有类别中都超越了前代 GPT-5.6——包括写作、数学、编程等——但它在图形演示方面的领先尤为明显。
我们也可以从基准测试中看到这一点。例如,如下所示,GPT-6 Astra 的数学和编程能力确实很强。
其中一个亮点(图中未展示)是,Astra 在衡量逻辑谜题求解与泛化能力的 ARC-AGI-3 基准中也达到了 99.9%(GPT-5.6 Sol 仅为 7.8%)。不过,数学、编程和计算机使用基准更值得关注,因为它们更接近真实世界的应用。
回到 Artificial Analysis Coding Agent Index v1.4(前一张图的右下角),该指标融合了多项智能体式编程任务。GPT-6 Astra 显然处于前沿,但其领先幅度并非遥遥领先。这一点也可以从下面的通用 Artificial Analysis Intelligence Index 中看出,该指数混合了不同类型的任务,而不只是编程任务。
图 2:Artificial Analysis Intelligence Index,来源:https://artificialanalysis.ai/#intelligence
如今,Artificial Analysis 基准的一大优势在于它们是独立的,因此可能比模型开发商自行评估的基准更值得信赖一些。
评测 harness 的设置取决于具体基准。例如,GDPval-AA 和 AA-Briefcase 在所比较的不同 LLM 中,使用其开源、极简的 Stirrup harness。上图所示的 Intelligence Index v4.2 中,Terminal-Bench v2.1 使用 Terminus 2,而 τ³-Banking 使用 τ-Bench harness。独立的 Coding Agent Index 同样比较不同的编程智能体 harness。
对于使用共享 harness 的评测,这会使比较更接近于苹果对苹果的公平比较。与此同时,在模型训练阶段,模型通常会围绕一个主要 harness 开发,并较少针对其他 harness 做微调。而且,主要 harness 往往会被设计成适合并放大某个模型的优势。
因此,一些智能体评测可能低估了 Astra 在其主要 harness 中的实际表现。这会在多大程度上影响其 Intelligence Index 分数,需要通过让 Astra 在相同任务上跨不同 harness 进行比较来验证。
顺带一提,正如一位同事最近向我建议的那样(Claude Code 负责人也有类似建议),删除(/archive)部分现有的 AGENTS.md 内容和 SKILL.md 文件或许并不是坏主意,因为较新的 LLM 已经更高效地理解提示并解决当前问题。过多的手把手指导可能会不必要地限制新模型,并导致更差的解决方案。
当然,我并不是建议以后永远不再使用 SKILL.md 文件。对于某些工作流而言,它们可以在复用时提升效率,因为模型不需要重新发现这些内容。但我想表达的是,某些工作流并不需要被描述;而“旧的”描述可能已不再理想,LLM 或许能够提出更好的解决方案。因此,现在或许该更新或重新生成这些指令文件了。
GPT-6 Astra 在图像与渲染任务上似乎异常强大。当这些任务涉及与图形用户界面交互时,它们也体现了计算机使用能力,也就是说,模型会通过 Codex/ChatGPT 应用操作你本地电脑上的软件。
与其他模型相比,计算机使用正是该模型真正出彩的领域;任何与图形相关的内容,也很容易在社交媒体平台上形成有趣且直观的演示。网上已有大量令人印象深刻的案例,从在 blender 中渲染纽约市,到虚拟开放日看房导览。
举一个例子:下面是一项对比,我让 GPT-6 Astra Medium 和 High 使用我电脑上的鼠标,在 浏览器版 MS Paint 中重绘我的一张照片(没有使用 Extra High 和 Max,因为我不想耗尽所有 token :))。
这不仅突出了模型的艺术能力,更重要的是,也体现了它使用用户电脑工具的能力(本例中是 Paint;你可以通过鼠标光标看到模型在操作界面)。
这并非首个能够在 harness 内实现通用计算机使用的模型。例如,从今年早些时候开始,我就已经成功地使用 GPT 模型完成一些 UI 任务(例如 Excel 中与报销相关的任务)等等。不过,计算机使用是一项相对较新的、由 harness 赋能的能力,通常还没有那么成熟。这很合理。LLM 是文本模型,因此更容易实现的能力自然是写作、编程,以及使用 API 和 CLI。
与此同时,许多工具和软件尚未提供 CLI(至少目前没有)。与其等待有人设计出这样的接口,为什么不提升模型使用图形用户界面的能力呢?(而且,如前所述,这本来也能带来漂亮、令人印象深刻的演示。)这与新兴的人形机器人发展在某种程度上类似。当然,人形机器人并非效率最高的机器人——例如,在已有专用机器的装配线上就是如此——但它们具备通用性。
因此,我预计接下来的数月(甚至数年)也将成为在 LLM 层和智能体 harness 层持续完善计算机使用能力的时代。也就是说,除了现有能力以及不断扩展数学和编程能力之外,模型将越来越多地围绕计算机使用进行训练。这也将使 LLM 对科技行业之外的日常电脑任务更加易用(“嘿,ChatGPT,请帮我报税”:))。
计算机使用的趋势也与近期报道相一致:据称 OpenAI 购买了数万台 Mac Mini 和 Mac Studio 用于强化学习。因此,这些 Mac 并非被用于直接训练模型(使用 GPU 更适合这一任务),而是在模型训练期间提供 macOS 环境,让模型学习使用该操作系统及其中的工具。
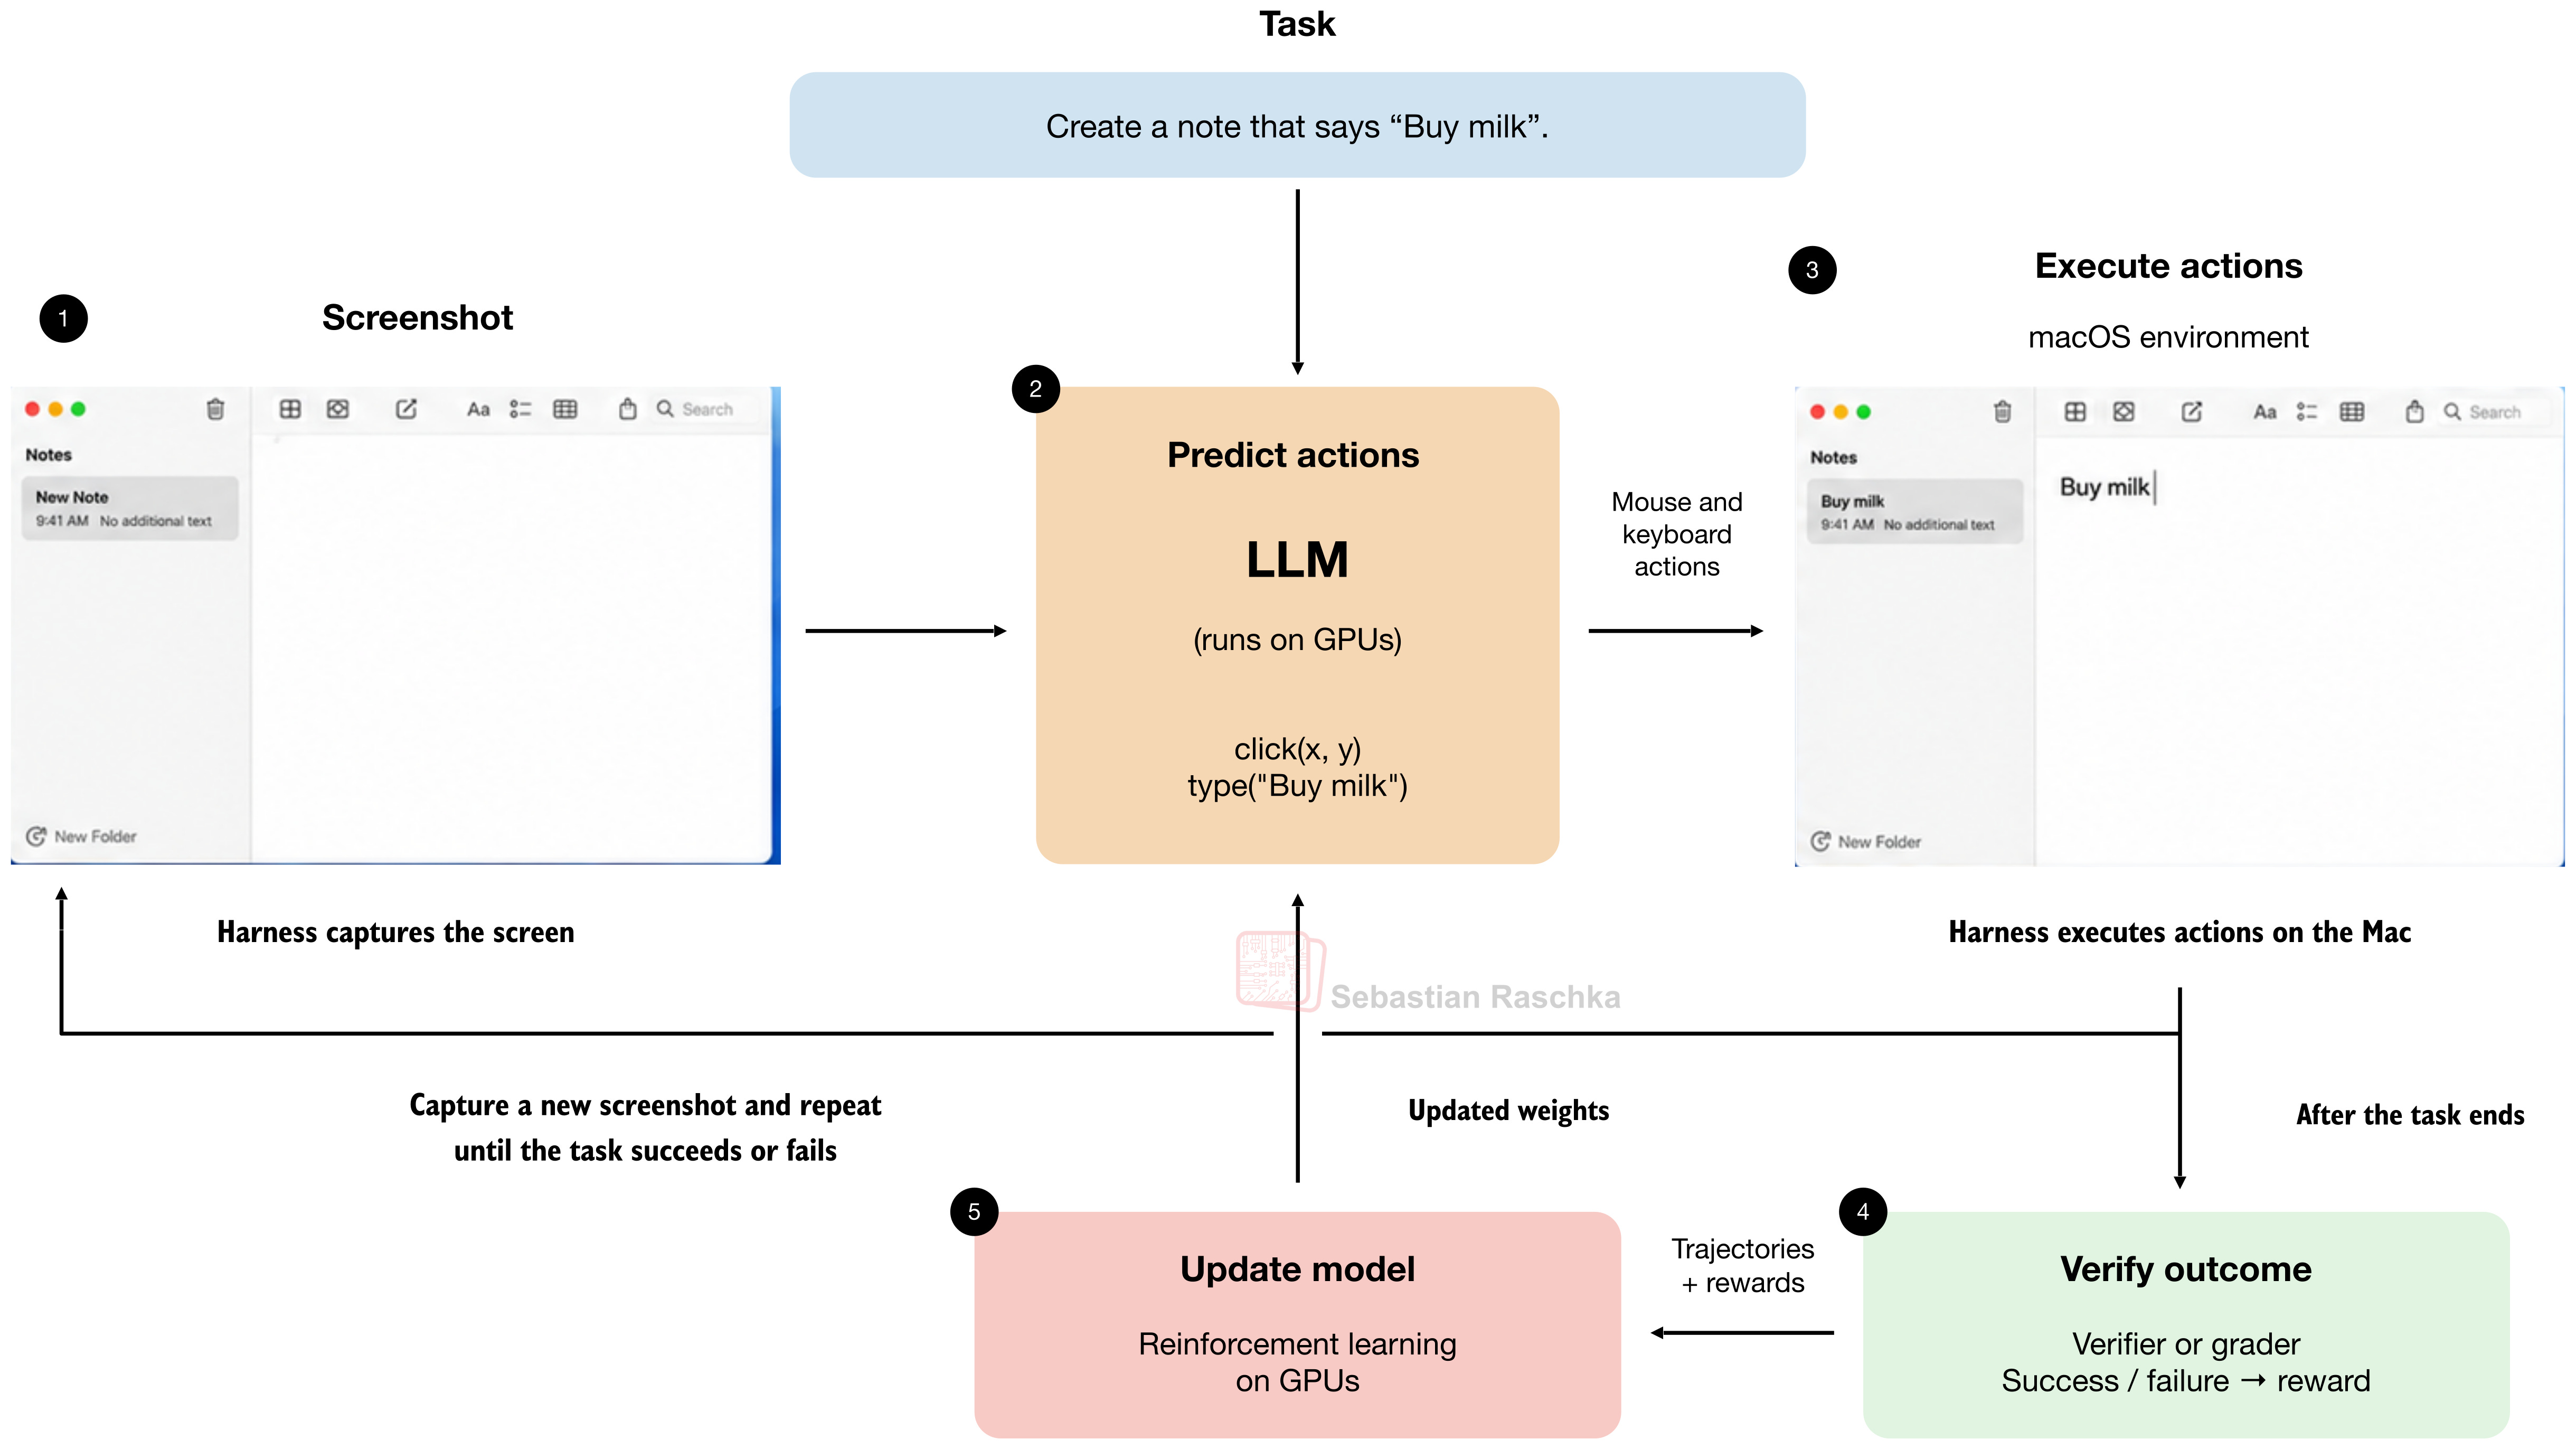
那么,在这些 Mac 上进行计算机使用训练是如何运作的?简言之,这些 Mac(或者更准确地说,是它们的 macOS 操作系统)充当模型在训练期间可交互的环境。
基本工作流程如下:
-
向模型发出提示并交给它一项任务,例如“打开 xyz 应用并完成 abc”。
-
向模型提供 macOS 界面的截图(这通常由 harness 完成)。
-
LLM 随后预测鼠标/键盘操作(点击、按键、滚动等)。
-
在 Mac 上执行这些操作(同样由 harness 完成)。
-
在执行前一步操作后,向模型输入更新后环境的新截图。
-
重复步骤 2 至 5,直至任务成功或失败。
-
使用成功/失败信号和验证器(或评分器)作为训练反馈,其中包括后训练阶段的强化学习;这与常规的具备可验证奖励的强化学习(RLVR)类似。
再次强调,Mac 在这里主要是环境,而不是在训练期间运行或更新模型的机器。模型很可能运行在 NVIDIA GPU 上,并通过 API 向这些 Mac 提供服务。顺便说一句,NVIDIA CEO 提到,GPT-6 Astra 使用了约 10 万张 Grace Blackwell GPU 进行训练。
上一节讨论的对计算机使用训练的关注,并不是训练流水线的根本范式转变。GPT-6 Astra(以及在可预见未来可能出现的任何 LLM)仍然是一种推理模型。这意味着,LLM 通过具备可验证奖励的强化学习(RLVR)进行训练,并产生中间推理轨迹(思维链)。
但我会在本文稍后进一步讨论 GPT-6 Astra 的推理模型特征,尤其是与隐藏思维链有关的部分。
话虽如此,在官方模型发布大约两天前,新闻杂志 The Information 发表了一篇文章,报道称根据一些内部信息,Astra 使用了一种名为“递归深度”(recurrent depth)或“循环 Transformer”(looped transformers)的概念。
由于 LLM 架构属于我的专业领域,也是我的热情所在,我制作了一段简短的讲解视频,说明循环 Transformer 的一般机制,并回应有关隐藏推理链的说法,详见下方。
在接下来的小节中,我会先解释什么是循环 Transformer,并将在本文稍后重新讨论隐藏思维链的说法。
(循环 Transformer 的解释可能看起来有点长,但我确实认为,它有助于建立对这项技术的基础性理解,从而能够据此判断其是否会模糊推理轨迹或思维链。)
那么,什么是循环 Transformer?
循环 Transformer 本质上是一项架构调整,其核心思路是让中间表征多次通过同一组 Transformer block(而不是只通过一次)。与单纯增加更多 block 相比,这里的“诀窍”在于:这些多次传递之间的权重保持不变。
定义与术语
在本文中,我将使用以下术语:
-
Transformer block 是包含注意力机制、前馈模块、归一化和快捷连接的一个单元。在论文中,这些 block 通常被称为“Transformer layer”。
-
stack 是由一系列 Transformer block 构成的序列。
-
block application 指让输入单次通过一个 Transformer block 的过程。
循环 Transformer 并不是什么新概念,其基本思想早已出现在 2018 年的 Universal Transformers 论文中。但在讨论 Universal Transformer 之前,让我们先从一个更简单的例子开始:Nanbeige4.2-3B。这是一个近期发布的开放权重 LLM,于 7 月推出;我在今年夏初的 Substack Notes 和我的 LLM Architecture Gallery 中都介绍过它。
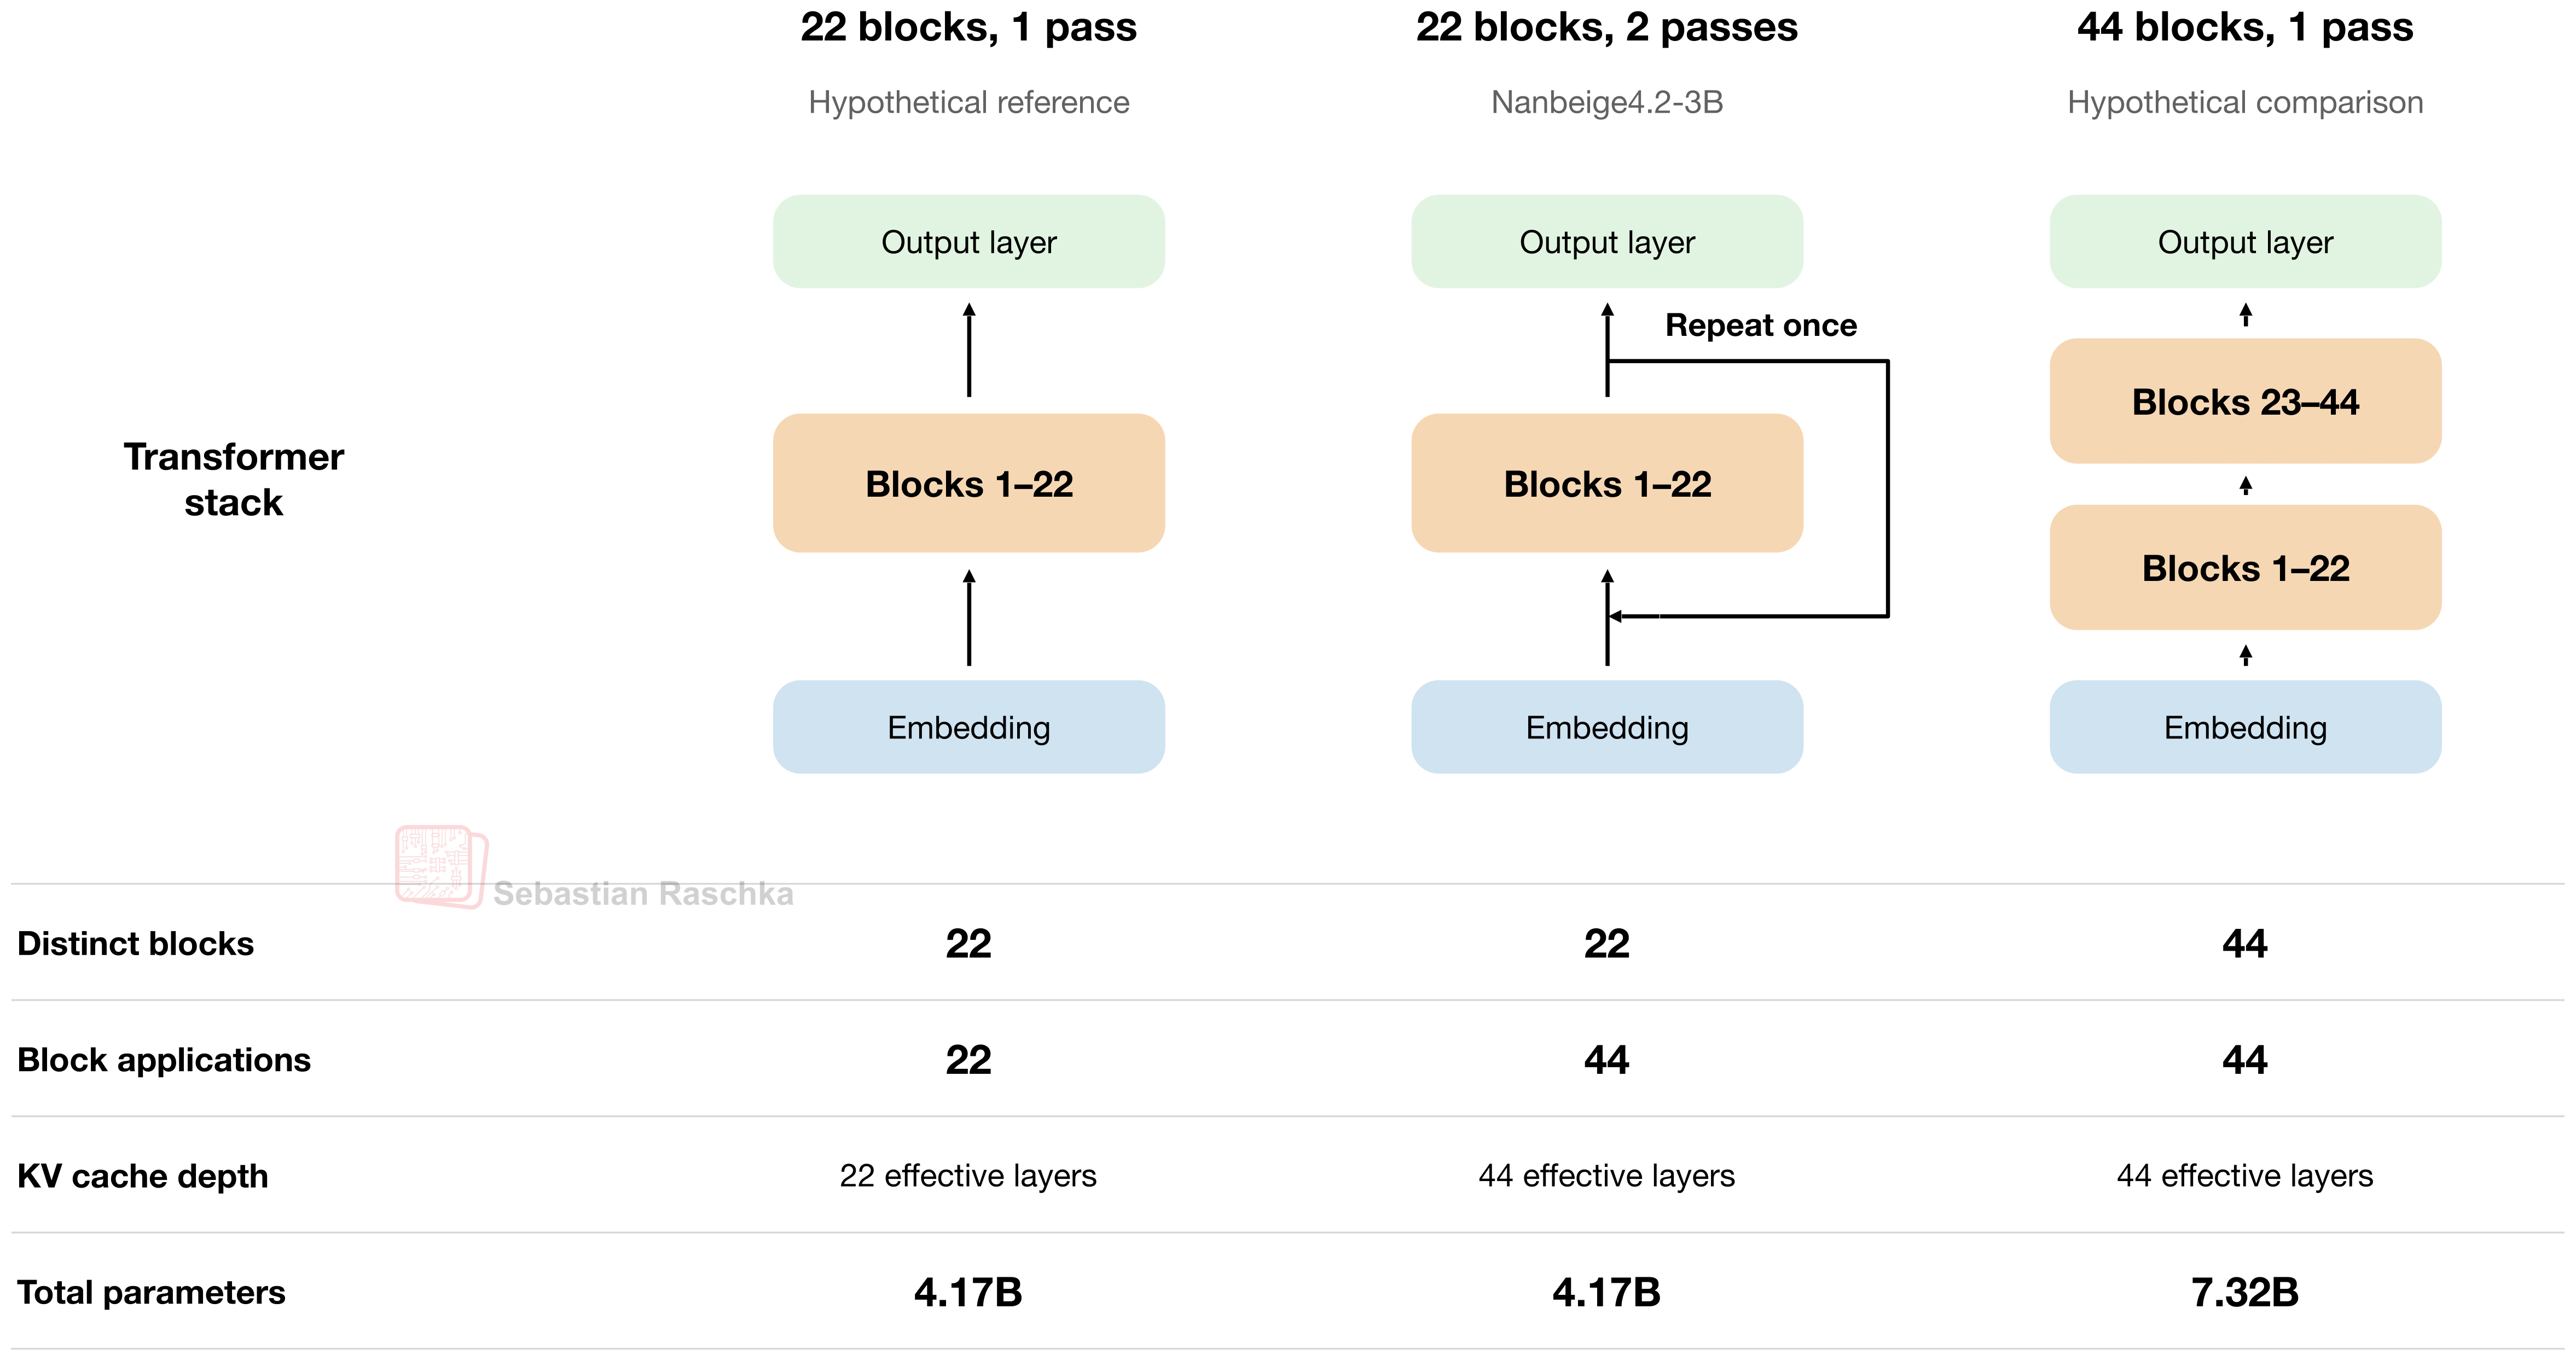
如下图所示,Nanbeige 架构本质上看起来像一个常规 Transformer。不过,请注意它有一条额外的橙色箭头,循环指向 Transformer stack 的起点。
图 5:Nanbeige4.2-3B 将相同的一组 22 个 Transformer block 应用两次。橙色箭头显示中间表征被传回 stack 的位置。
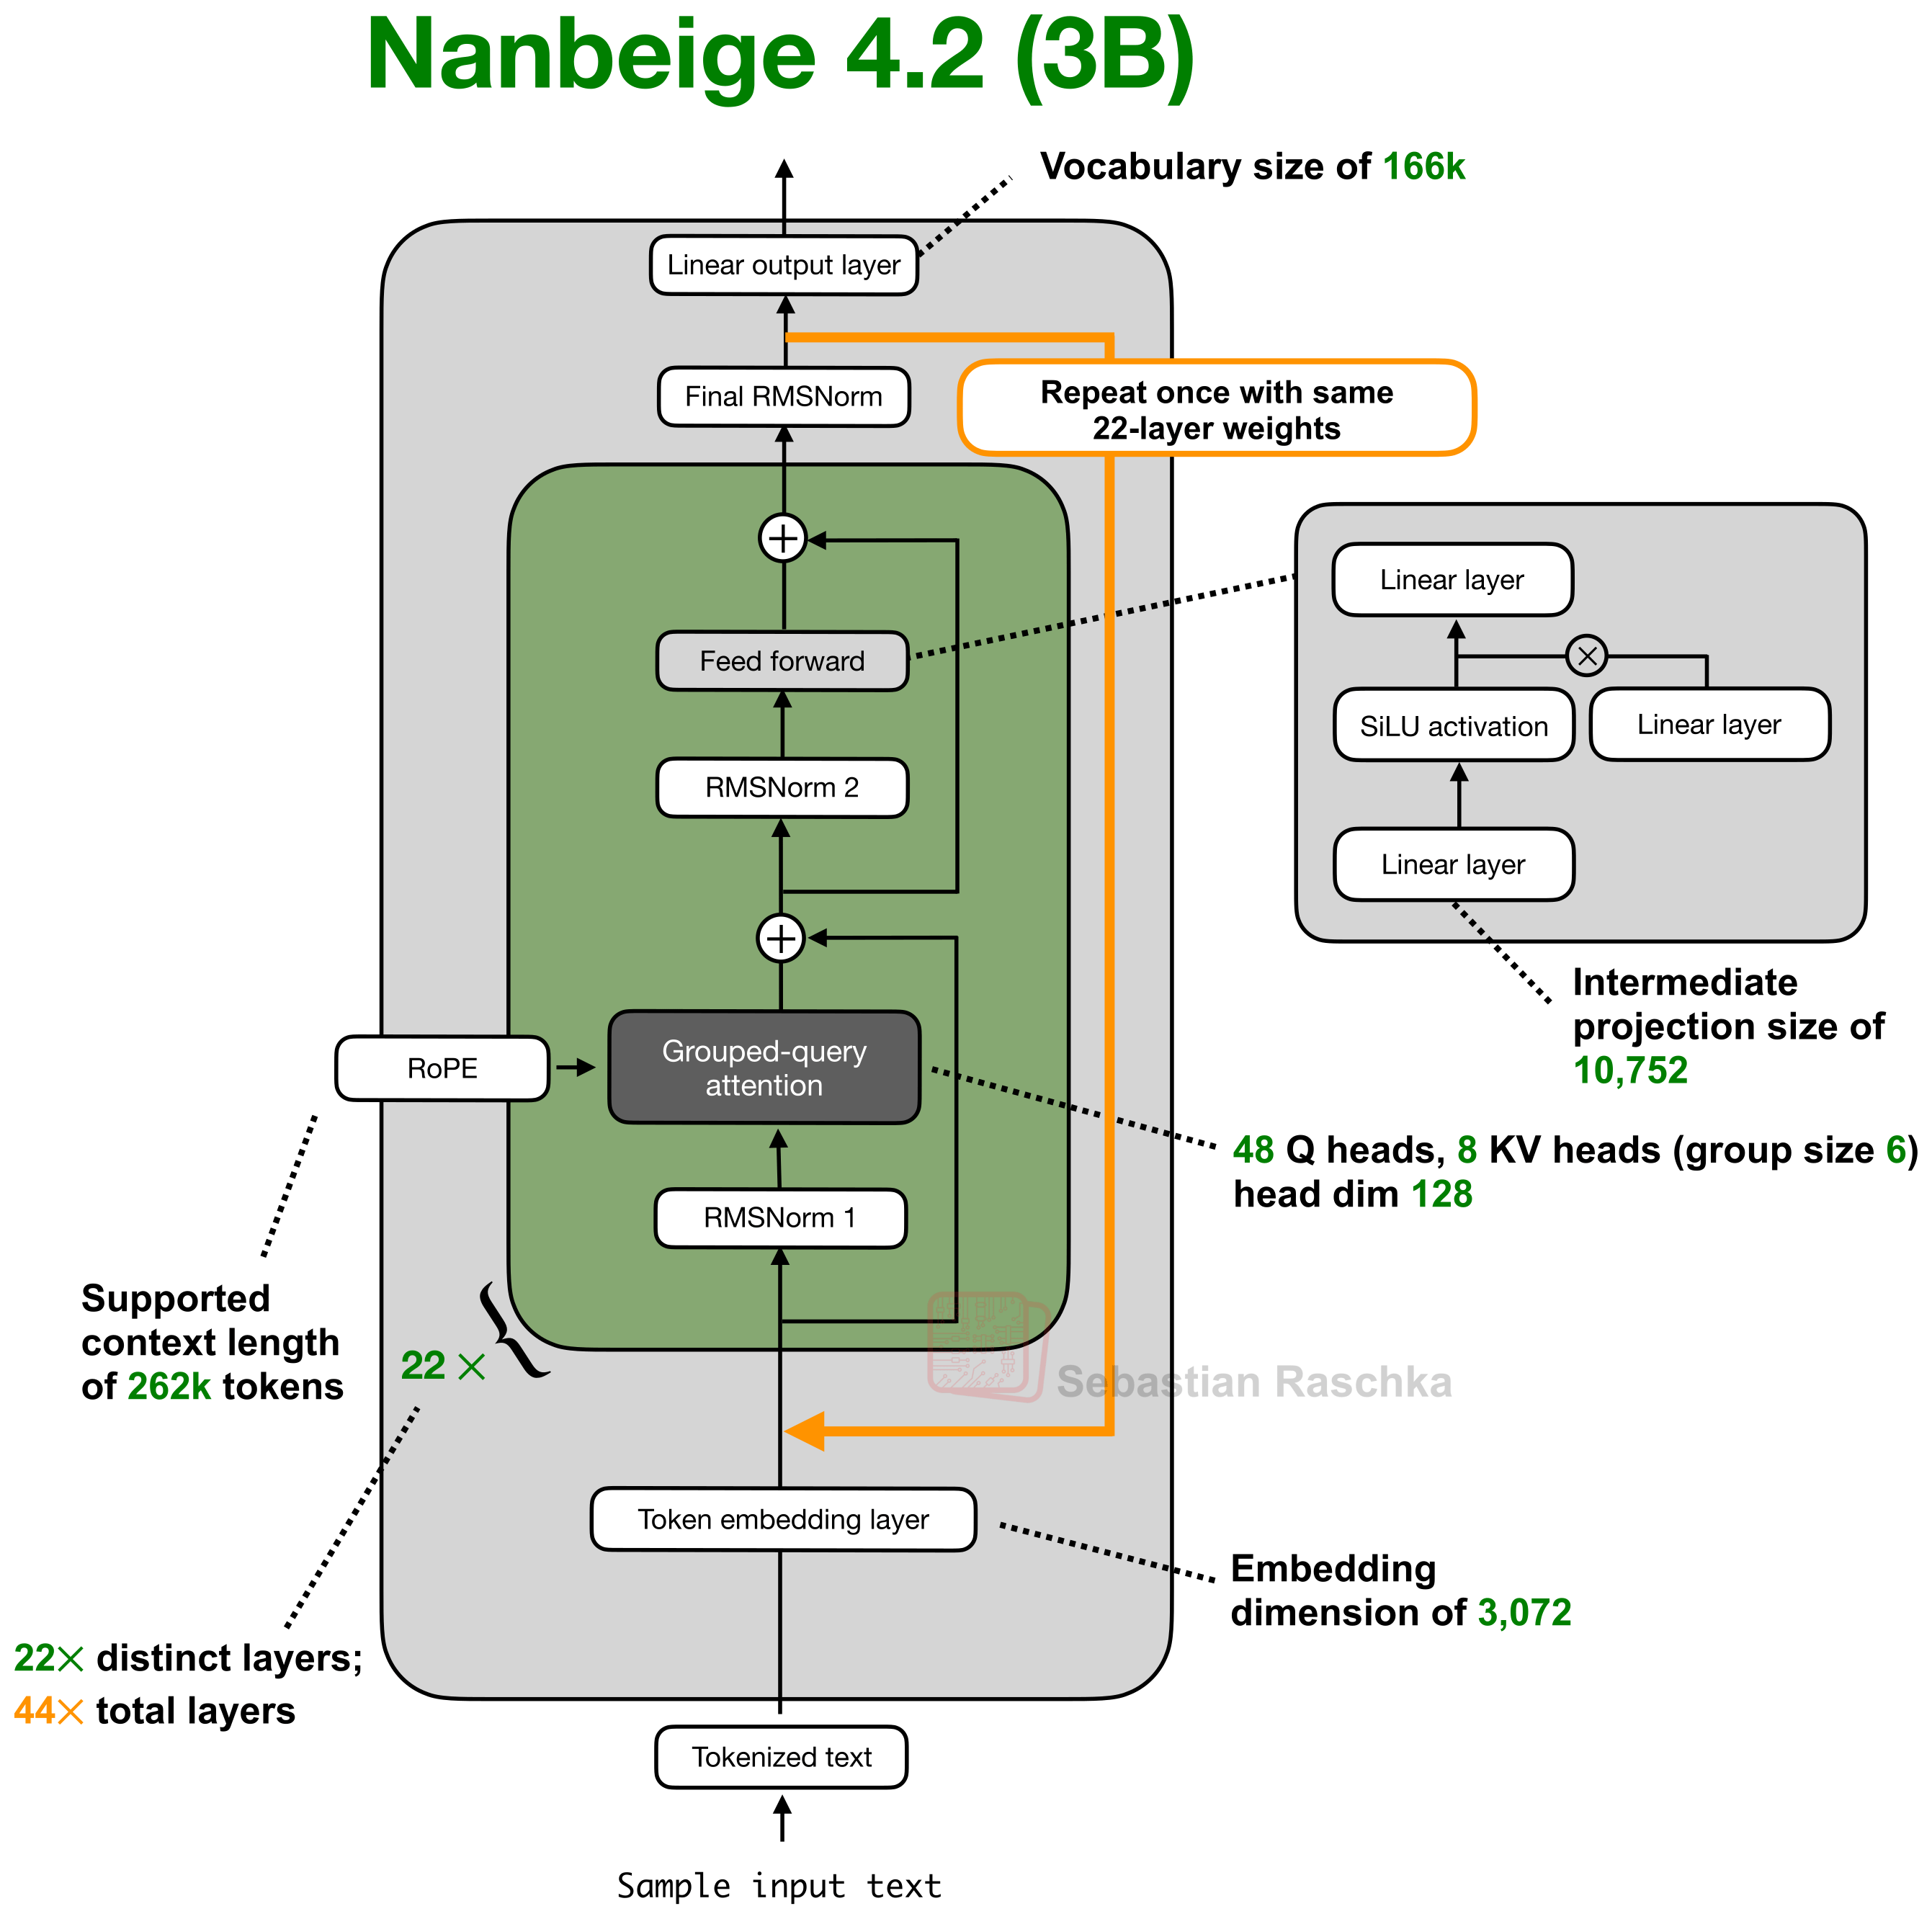
让我们从下往上看。首先,与其他基于 Transformer 的 LLM 一样,输入文本会被分词并转换为嵌入向量。这些向量随后通过 22 个 Transformer block,且这 22 个 block 分别拥有各自的权重。
但这里的循环 Transformer 特性在于:第一次传递后,隐藏状态会被再次输入相同的 22 个 block。因此,先再次应用 block 1,然后是 block 2,依此类推,直至 block 22。
如果将这一计算展开,我们会得到 44 次 Transformer block application。不过,与具有 44 个不同 block 的传统 Transformer 相比,第二组 22 次 block application 会复用第一组 stack 的权重。例如,第 23 次 block application 使用 block 1 的权重,第 24 次 block application 使用 block 2 的权重,依此类推。
English / 原文
A lot has happened in the last few weeks. I am sure that OpenAI’s GPT-6 Astra is top of mind for everyone right now. In particular, thoughts on its performance, the looped transformer/recurrent depth aspects, and rumors that Astra is “hiding” its reasoning trace (i.e., chain of thought).
So, in this article, I want to start with some brief impressions of Astra and some thoughts on where all this is headed. Then, I will discuss, in detail, what “looped transformers” are, and how (or rather, if) this relates to hiding chains of thought.
Lastly, after covering the basics of the looped transformer, I wanted to highlight some new insights from recent research papers on the topic.
First things first. Before getting into the architecture rumors and related research literature, let me briefly summarize some GPT-6 Astra observations and tidbits.
Last week, OpenAI’s new GPT-6 Astra was released with a big fanfare. I used it over the past couple of days, and it’s an exceptionally good model, likely the best I’ve used as of this writing. But what, exactly, has it improved, and how?
Astra is the best model I’ve used so far, and it’s disproportionately good at 3D rendering and animation tasks (relative to other models). With that, I mean that while it leapfrogs its GPT-5.6 predecessor in practically all categories (writing, math, coding, and more), it especially does so when it comes to graphical demos.
We can see this also reflected in the benchmarks. For instance, GPT-6 Astra is really good at math and coding, as shown below.
One of the highlights (not shown in the figure) is that Astra also achieves 99.9% on the ARC-AGI-3 benchmark (GPT-5.6 Sol only 7.8%), which measures a mix of solving logic puzzles and generalization. However, the math, coding, and computer use benchmarks are more interesting because they are closer to real-world use.
Coming back to the Artificial Analysis Coding Agent Index v1.4 (lower right in the previous figure), which blends several agentic coding tasks, GPT-6 Astra is clearly at the frontier, but it doesn’t pull ahead by leaps and bounds. This can also be seen in the general Artificial Analysis Intelligence Index shown below, which blends different types of tasks, not just coding tasks.
Figure 2: Artificial Analysis Intelligence Index via https://artificialanalysis.ai/#intelligence
Now, the big advantage of Artificial Analysis benchmarks is that they are independent and thus may be a bit more trustworthy than self-evaluated benchmarks by model developers.
The harness setup depends on the benchmark. For example, GDPval-AA and AA-Briefcase use their open-source, minimal Stirrup harness across the different LLMs they compare. In the Intelligence Index v4.2 shown above, Terminal-Bench v2.1 uses Terminus 2, and τ³-Banking uses the τ-Bench harness. The separate Coding Agent Index also compares different coding-agent harnesses.
For evaluations that use a shared harness, this makes it more of an apples-to-apples comparison. At the same time, during model training, models are typically developed with one primary harness in mind (and fine-tuned less on other harnesses). Plus, the primary harness is often developed to suit and amplify a model’s strengths.
So, some of the agentic evaluations might underestimate how well Astra performs in its primary harness. How much this affects its Intelligence Index score would need to be tested by comparing Astra across harnesses on the same tasks.
As a side note, as a colleague recently suggested to me (as also recommended by the Claude Code lead), it’s maybe not a bad idea to delete (/archive) some of your existing AGENTS.md contents and SKILL.md files, as newer LLMs have become more efficient at understanding the prompt and solving the problem at hand. The extra hand-holding could unnecessarily constrain newer models and lead to worse solutions.
Of course, I am not suggesting never using SKILL.md files again, but for some workflows, because they can improve efficiency upon reuse, since the model doesn’t have to rediscover them. But what I am suggesting is that some workflows don’t need describing, and “old” descriptions may no longer be ideal, and the LLM may be able to come up with better solutions. So, it’s perhaps time to update or regenerate said instruction files.
GPT-6 Astra seems to be exceptionally strong in image and rendering tasks. When these tasks involve interacting with graphical user interfaces, they also demonstrate computer-use capabilities, meaning the model operates software on your local computer through the Codex/ChatGPT app.
Computer use is where the model really shines compared to others, and anything graphic-related also makes for interesting and intuitive demos on social media platforms. There are tons of examples of impressive demos out there, from modeling rendering New York City in blender to virtual open house tours.
To pick one example, below is a comparison where I had GPT-6 Astra Medium and High redraw a picture of me in a browser version of MS Paint using the mouse on my computer (not Extra High and Max, because I didn’t want to waste all my tokens :)).
This highlights not only the model’s artistic capabilities but, more importantly, its ability to use tools on one’s computer (in this case, Paint; you can see the model using the interface via the mouse cursor).
This is not the first model that, inside a harness, is capable of general computer use. For example, I successfully used GPT models for some UI tasks (e.g., expense-related tasks in Excel) and so on since earlier this year. However, computer use is a relatively new capability, enabled by the harness, and usually feels not quite as mature yet. This makes sense. LLMs are text models, so naturally the lower-hanging fruit is writing and coding and using APIs and CLIs.
At the same time, there are many tools and software that don’t expose CLIs (yet), and instead of waiting until someone designs that interface, why not improve models to use graphical user interfaces (and, as mentioned before, this makes for pretty and impressive demos, anyway)? This is somewhat analogous to the emerging humanoid robot developments. Sure, humanoid robots are not the most efficient robots, for example, at the assembly line, where special-purpose machines exist. But they are versatile.
So, I expect the upcoming months (or years) also to be an era of computer use refinement on both the LLM and the agent harness layer. I.e., in addition to the current capabilities, and expanding their math and coding capabilities, models will be trained with an increasing amount of computer use in mind. And this will also make LLMs more accessible for everyday computer tasks outside the tech world (”Hey ChatGPT, please do my tax return” :))
The computer usage trend is also consistent with the recent reporting that OpenAI purchased tens of thousands of Mac Minis and Mac Studios for Reinforcement Learning. So, here the Macs are not used to literally train the models (it’s better to use GPUs for that) but rather to expose macOS during the model training for the model to learn to use said operating system and the tools therein.
So, how does computer-use training on said Macs work? In short, the Macs (or their macOS operating system, to be precise) serve as an environment that the model can interact with during training.
The basic workflow looks like this:
-
Prompt the model by giving it a task, such as “open an app xyz and do abc”.
-
Provide it with screenshots of the macOS interface (this is usually done by the harness).
-
The LLM then predicts mouse/keyboard actions (click, key presses, scrolling, and so on).
-
Execute those actions on the Mac (again, this is done by the harness).
-
Feed new screenshots of the updated environment after performing the actions in the previous step.
-
Repeat steps 2-5 until the task succeeds or fails.
-
Use success/failure signals and verifiers (or graders) as training feedback, including reinforcement learning during post-training; this is analogous to regular Reinforcement Learning with Verifiable Rewards (RLVR).
Figure 3: Overview of a computer-use training workflow.
Again, the Mac is mostly the environment here and not the machine for running or updating the model during training. The model likely sits on NVIDIA GPUs and is fed via API to said Mac. By the way, NVIDIA’s CEO mentioned that GPT-6 Astra was being trained on ~100,000 Grace Blackwell GPUs.
The focus on computer-use training discussed in the previous section is not a fundamental paradigm shift in the training pipeline. GPT-6 Astra (and likely any LLM in the foreseeable future) is still a reasoning model. This means the LLM is trained with reinforcement learning with verifiable rewards (RLVR) and produces intermediate reasoning traces (chains of thought)
But I will discuss the reasoning model aspects of GPT-6 Astra (especially regarding hiding chains of thought) a bit later in this article.
That being said, about two days before the official model, the news magazine The Information published an articlereporting that, according to some inside information, Astra is using a concept called “recurrent depth” or “looped transformers.”
Since LLM architectures are within my area of expertise and my passion, I created a short lecture video explaining the general looped transformer mechanism and addressing the comment about hidden reasoning chains, which you can find below.
In the following subsections, I’ll first explain what looped transformers are, and I’ll revisit the comment about the hidden chains of thought later in this article.
(The looped transformer explanation may seem a bit long, but I really think that it helps with establishing a foundational understanding of the technique, which is then useful to judging the claim that it obscures the reasoning traces or chains of thought.)
So, what’s a looped transformer?
A Looped Transformer is essentially an architectural tweak, with the main idea being to pass the intermediate representations through the same transformer blocks multiple times (instead of just once). Compared to just adding more blocks, the “trick” here is that the weights stay the same across these passes.
Definitions & Jargon
Throughout this article, I’ll use the following terms:
-
A transformer block is a unit containing attention, a feedforward module, normalization, and shortcut connections. These blocks are often called “transformer layers” in papers.
-
A stack is a sequence of transformer blocks.
-
A block application means running an input through a transformer block once.
The looped transformer is nothing new, and the basic idea already appeared in the Universal Transformers paper from 2018. But before discussing Universal Transformer, let’s start with a simpler example, Nanbeige4.2-3B, a recent open-weight LLM that came out in July and that I covered on Substack Notes and in my LLM Architecture Gallery earlier this summer.
The Nanbeige architecture, shown below, essentially looks like a regular transformer. However, notice that it has an extra (orange) arrow looping back to the beginning of the transformer stack.
Figure 5. Nanbeige4.2-3B applies the same stack of 22 transformer blocks twice. The orange arrow shows where the intermediate representations are passed back into the stack.
Let’s walk through this from the bottom up. First, as in any other transformer-based LLM, the input text is tokenized and converted into embedding vectors. These vectors then pass through 22 transformer blocks, and each of these 22 blocks has its own weights.
However, the looping transformer aspect here is that after the first pass, the hidden states are fed back through the same 22 blocks. So, block 1 is applied again, followed by block 2, and so on up to block 22.
If we were to unroll this computation, we would have 44 transformer block applications. However, compared to a conventional transformer with 44 distinct blocks, the second stack of 22 block applications reuses the weights from the first stack. For example, block application 23 uses the weights of block 1, block application 24 uses the weights of block 2, and so on.
Figure 6. Nanbeige4.2-3B unrolled into two passes through the same 22 transformer blocks, giving 44 block applications.
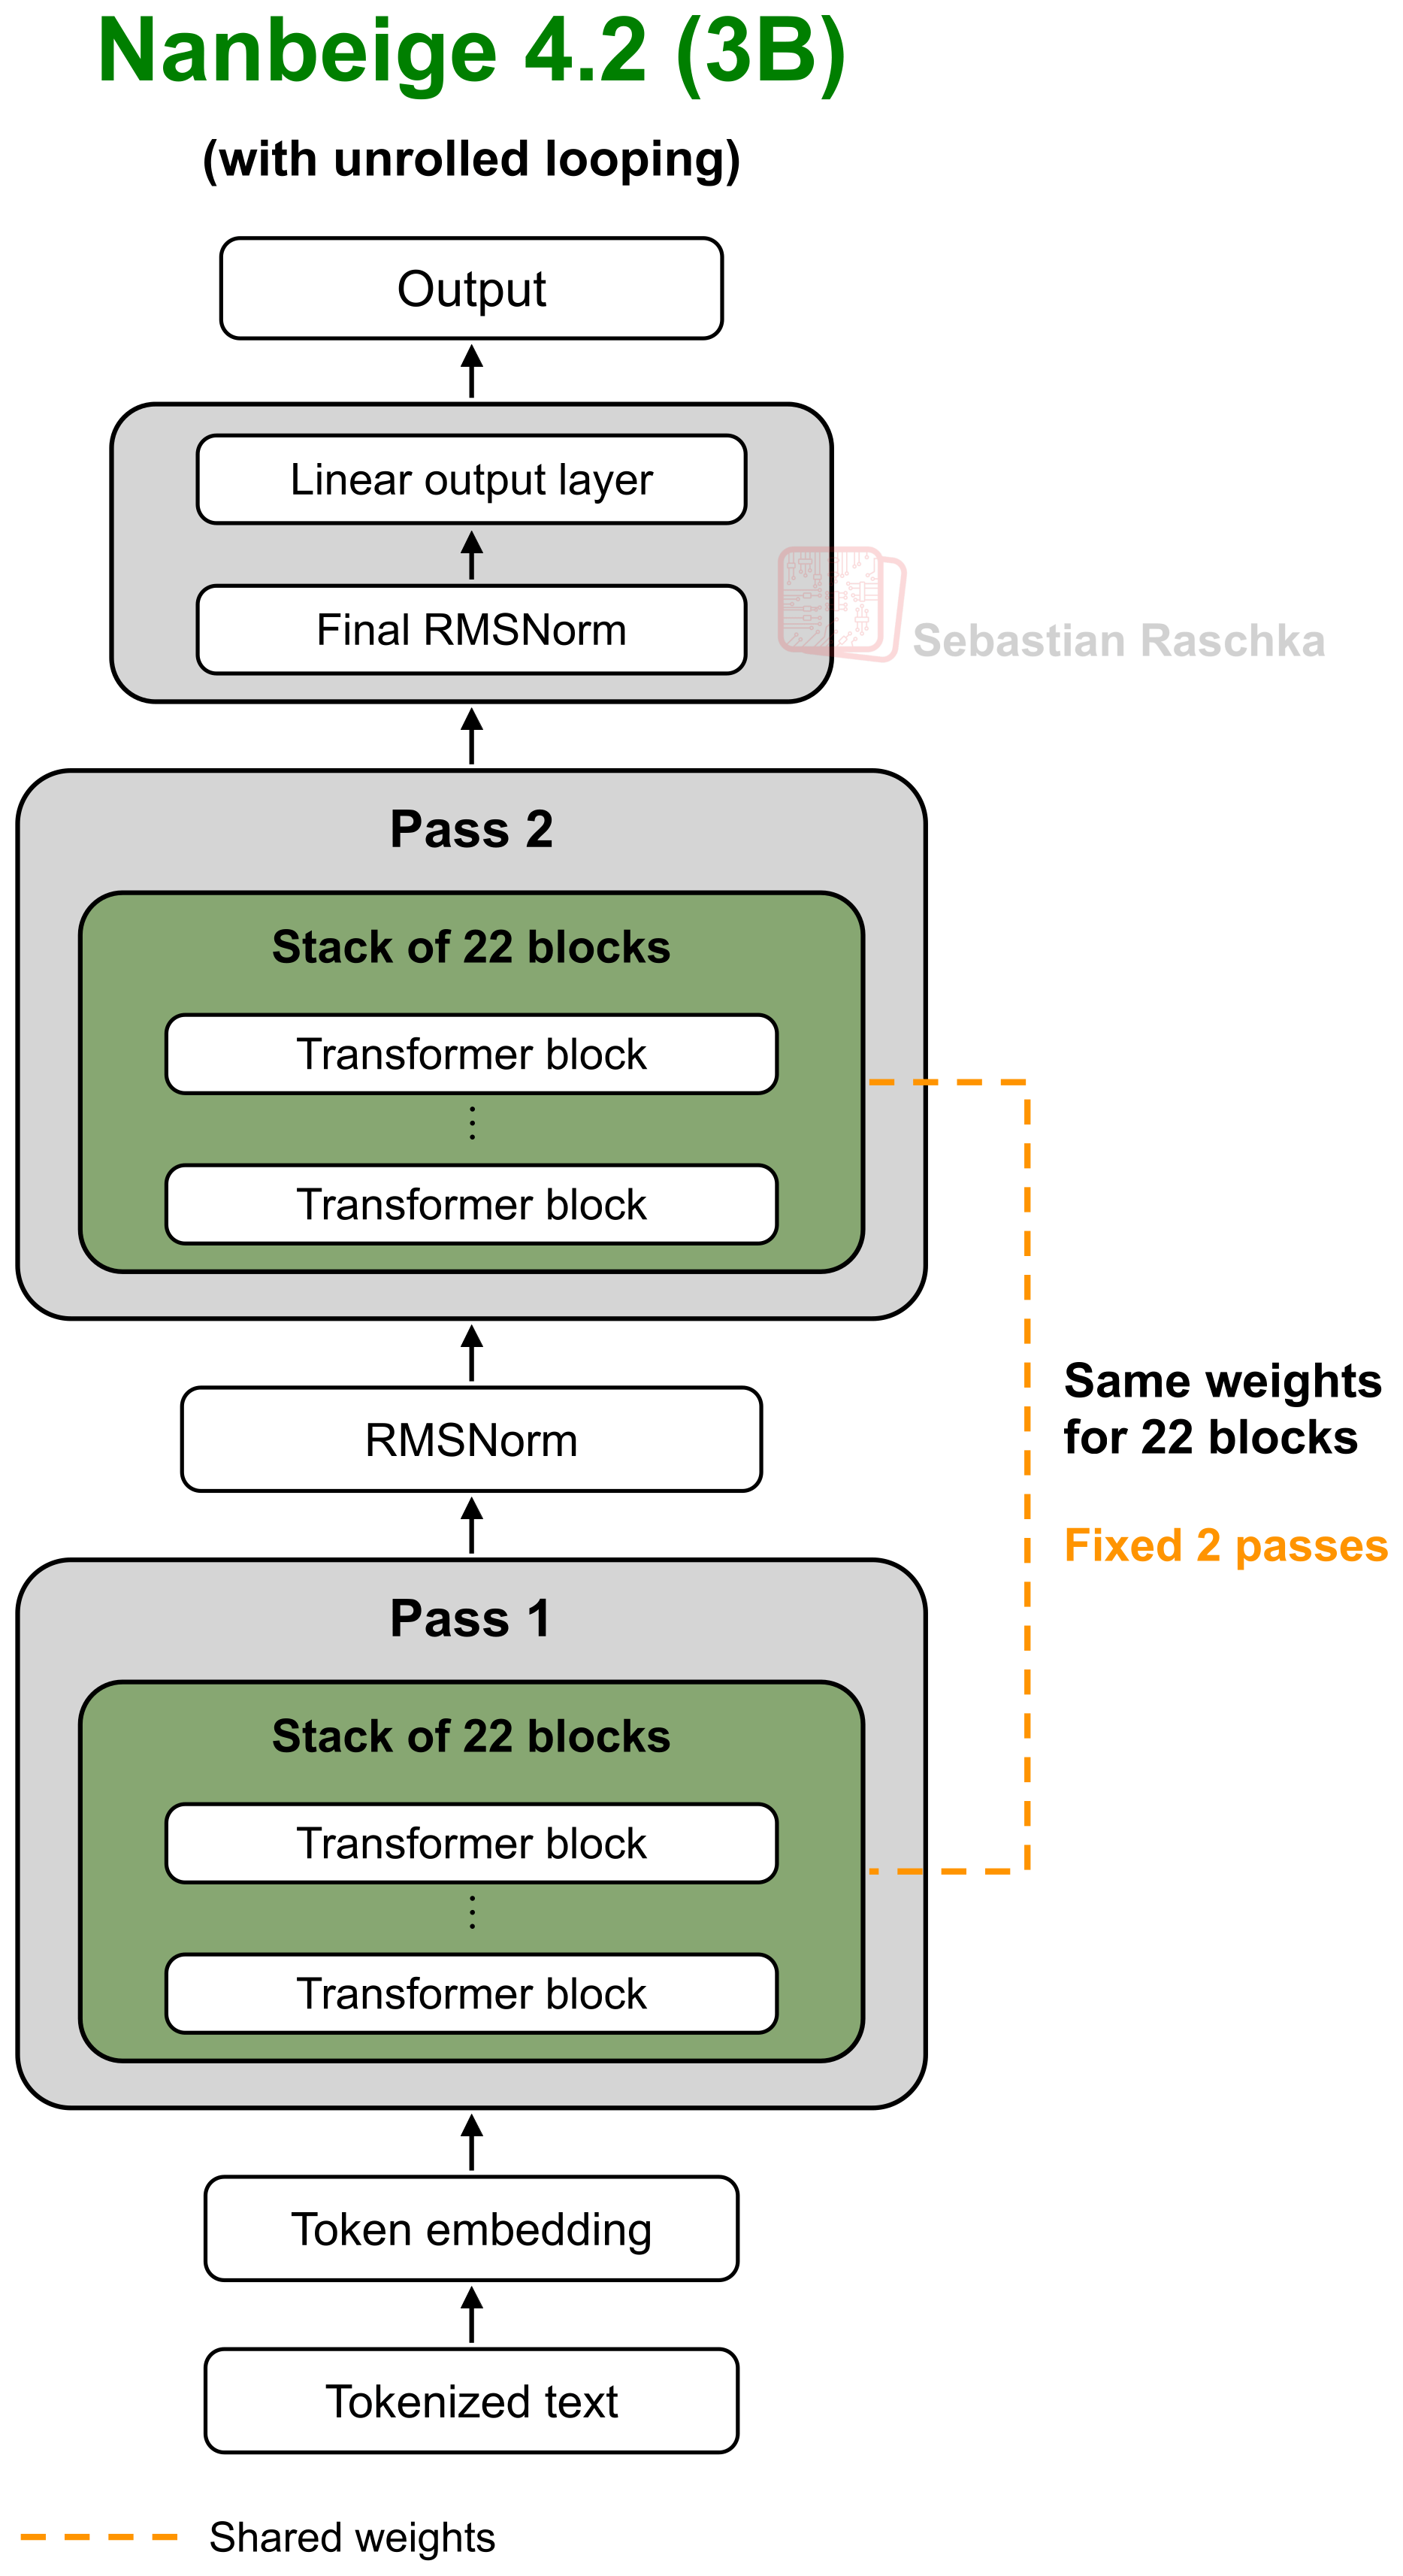
So, the whole idea here is that we increase the effective depth from 22 to 44 block applications without adding another set of transformer weights.
By the way, why 2 rounds, not 3, 4, or more? There are not many details in the Nanbeige paper, but they say that this was essentially the most efficient setup. Increasing the loops from 2 to 3 can increase modeling performance, but the extra computational cost wasn’t worth it.
So, why would we do this looping in general? This is essentially an alternative to just making the model bigger by adding more transformer blocks.
So, for instance, a model that uses 22 transformer blocks twice has roughly half as many (transformer-block) parameters compared to a model with 44 conventional blocks.
This then reduces the memory needed to store the weights. As a side note, note that the embedding and output layers, which are usually large and make up a substantial portion of the total, are separate from this comparison. (In the case of Nanbeige 4.2 3B, the embedding and output layers make up ~25% of the total 3B parameters; with weight sharing between those two, we could reduce that to 12.5%.)
Figure 7: Side-by-side comparison showing how many parameters would be required in traditional versus looping scenarios.
Of course, reusing the same blocks in a loop still requires computation. More precisely, we pass the intermediate inputs through 44 block applications during the forward pass. And, during training, gradients flow backward through both repetitions of the shared stack. So, compared to using the 22 blocks only once, this adds substantial work. Actually, it’s similarly expensive as having 44 distinct blocks (except the optimizer has fewer distinct parameters to update; backprop still runs through all 44 block applications).
There is also the KV cache, which stores the attention keys and values of previous tokens for reuse in conventional and looped transformers in each next-token generation step. By the way, I have a standalone article on KV caching here if useful:
Understanding and Coding the KV Cache in LLMs from Scratch
KV caches are one of the most critical techniques for efficient inference in LLMs in production. KV caches are an important component for compute-efficient LLM inference in production. This article explains how they work conceptually and in code with a from-scratch, human-readable implementation.
But back to the topic. Even though there is weight-sharing in looped transformers, the intermediate states that enter a block are different on the second pass. Consequently, in KV caching, the resulting keys and values are also different between these two transformer stacks (just like in the no-looping case). So, there are no KV cache-related savings either.
To make this more concrete, for example, consider block applications 1 and 23, which both use block 1 in the looped transformer setup. But each application still needs its own KV cache entries. So, since we have to keep separate caches for both passes, the repeated stack of 22 blocks has the same KV cache requirements as a conventional transformer with 44 distinct blocks.
Interestingly, the Nanbeige researchers reported in the paper that they tried sharing the KV cache between passes. This, of course, halved the KV cache size, but the model performed worse than the version with separate caches (which is the version they released).
Just to complete the Nanbeige discussion before moving on and looking at some other looped transformer designs, their technical report also discusses two other choices or trade-offs.
-
Training the looped architecture from scratch worked better than converting an already pre-trained transformer through upcycling.
-
And two passes gave their preferred trade-off, as mentioned in the previous section. More passes brought only small additional gains while slowing training and making optimization less stable.
So, the number of passes is another architectural choice we have to make. As mentioned before, in Nanbeige, this is fixed at two. But we can also make it depend on the token, as we will see next.
Now, let’s come back to Universal Transformers. In Nanbeige, we apply a stack of 22 transformer blocks twice. In the Universal Transformer paper from 2018, we repeatedly apply the same transformer block instead of repeating a stack of transformer blocks. The main idea is similar, though.
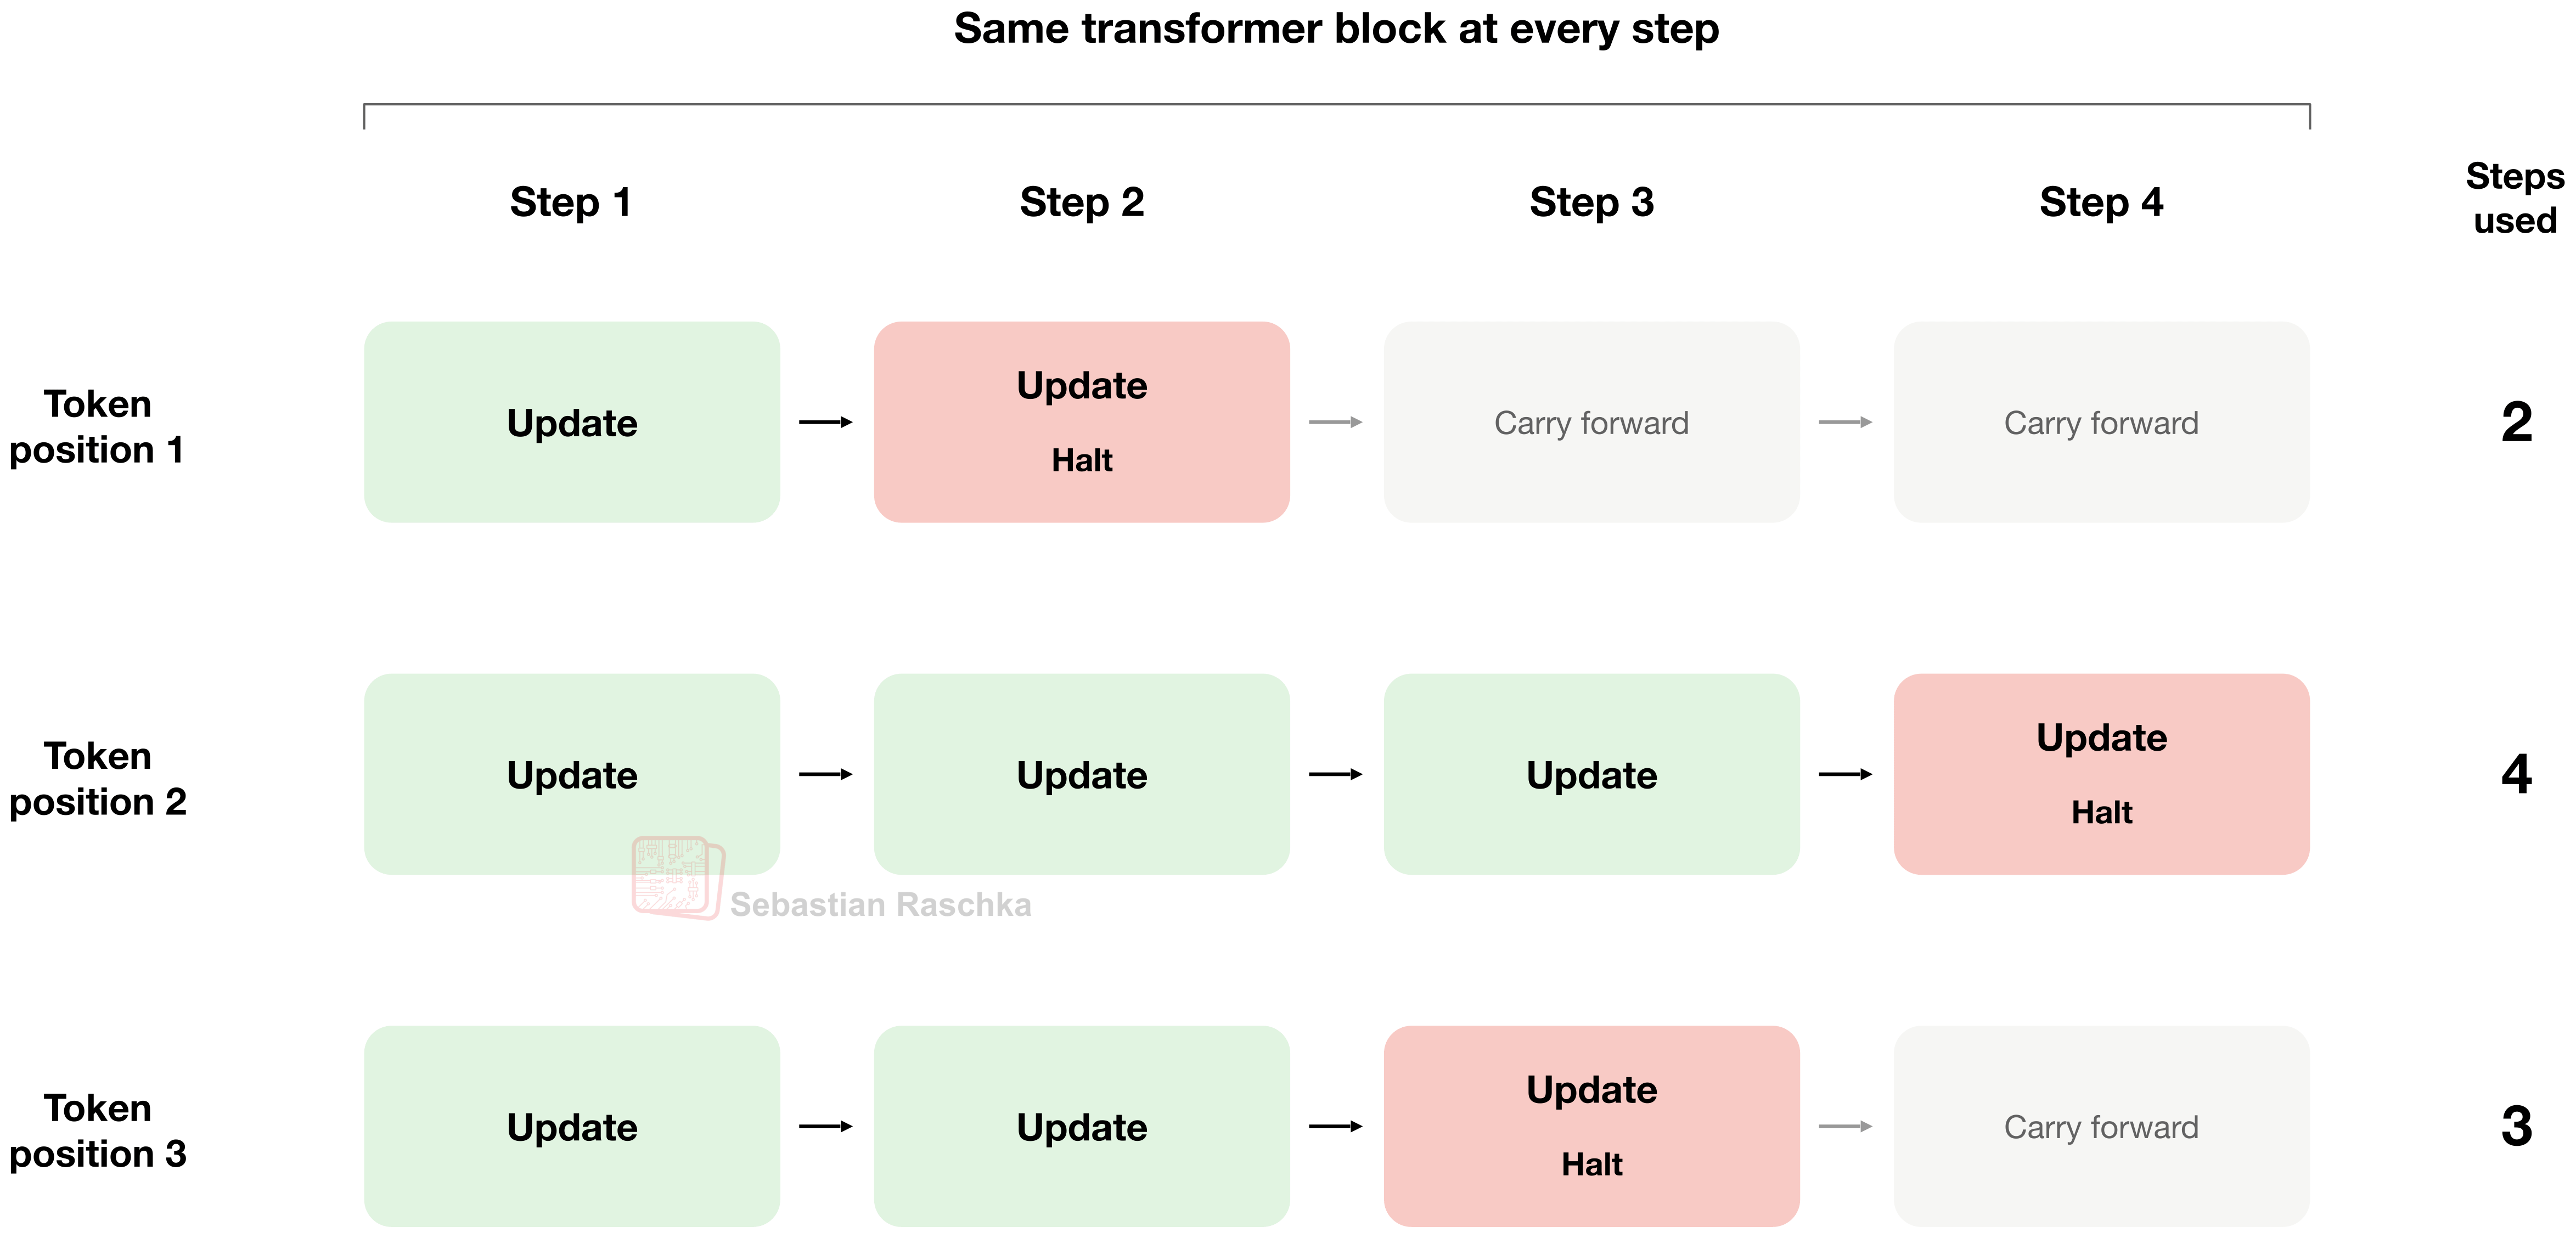
Also, the number of steps can be fixed, but the paper also explores adaptive halting. For example, a token at a particular position may only go through one or two loops. Another may go through three or four loops, and so on. This gives the model flexibility to allocate the compute to those tokens that benefit from extra computation.
How is the looping number decided? Here, the model uses a small, trained function that outputs a so-called halting probability for each position at each step. It adds up these probabilities over these successive loops and then stops looping at a given position once the sum exceeds a threshold value. In addition, a maximum loop count also limits the computation just in case.
Figure 8: Adaptive halting in a Universal Transformer.
Another example of a looped transformer is ByteDance’s Ouro, which I also covered in my LLM Architecture Gallery. For instance, Ouro-Thinking 2.6B applies the same stack of 48 transformer blocks four times. That’s 192 block applications while storing weights for 48 distinct blocks. Basically, that’s a more extreme case than Nanbeige. Additionally, a learned exit gate assigns probabilities to the different exits, and a threshold on the cumulative probability determines which pass supplies the output. So, it’s also borrowing the adaptive halting idea from Universal Transformer, which Nanbeige didn’t use. (However, there is a practical caveat here. The released Hugging Face implementation computes all configured passes before selecting an output, so it seems like the number of loops is effectively hard-coded to 4).
Another approach is Mixture-of-Recursions, a paper from 2025 that is essentially a more sophisticated version of the Universal Transformer discussed earlier. Similar to the Universal Transformer, individual tokens pass the transformer blocks one or more times as illustrated in the figure below. However, the innovation is how this looping number is determined on a per-token basis.
In the following figure from the paper, the looped (repeated) stack is called a recursion block here. This contains several transformer blocks, and it sits between separate first and last transformer blocks (labeled Layer 0 and Layer L-1).
Figure 9. Mixture-of-Recursions applies a shared stack a different number of times at different token positions. The highlighted text shows an example with 1, 2, or 3 passes. Figure adapted from the Mixture-of-Recursions paper.
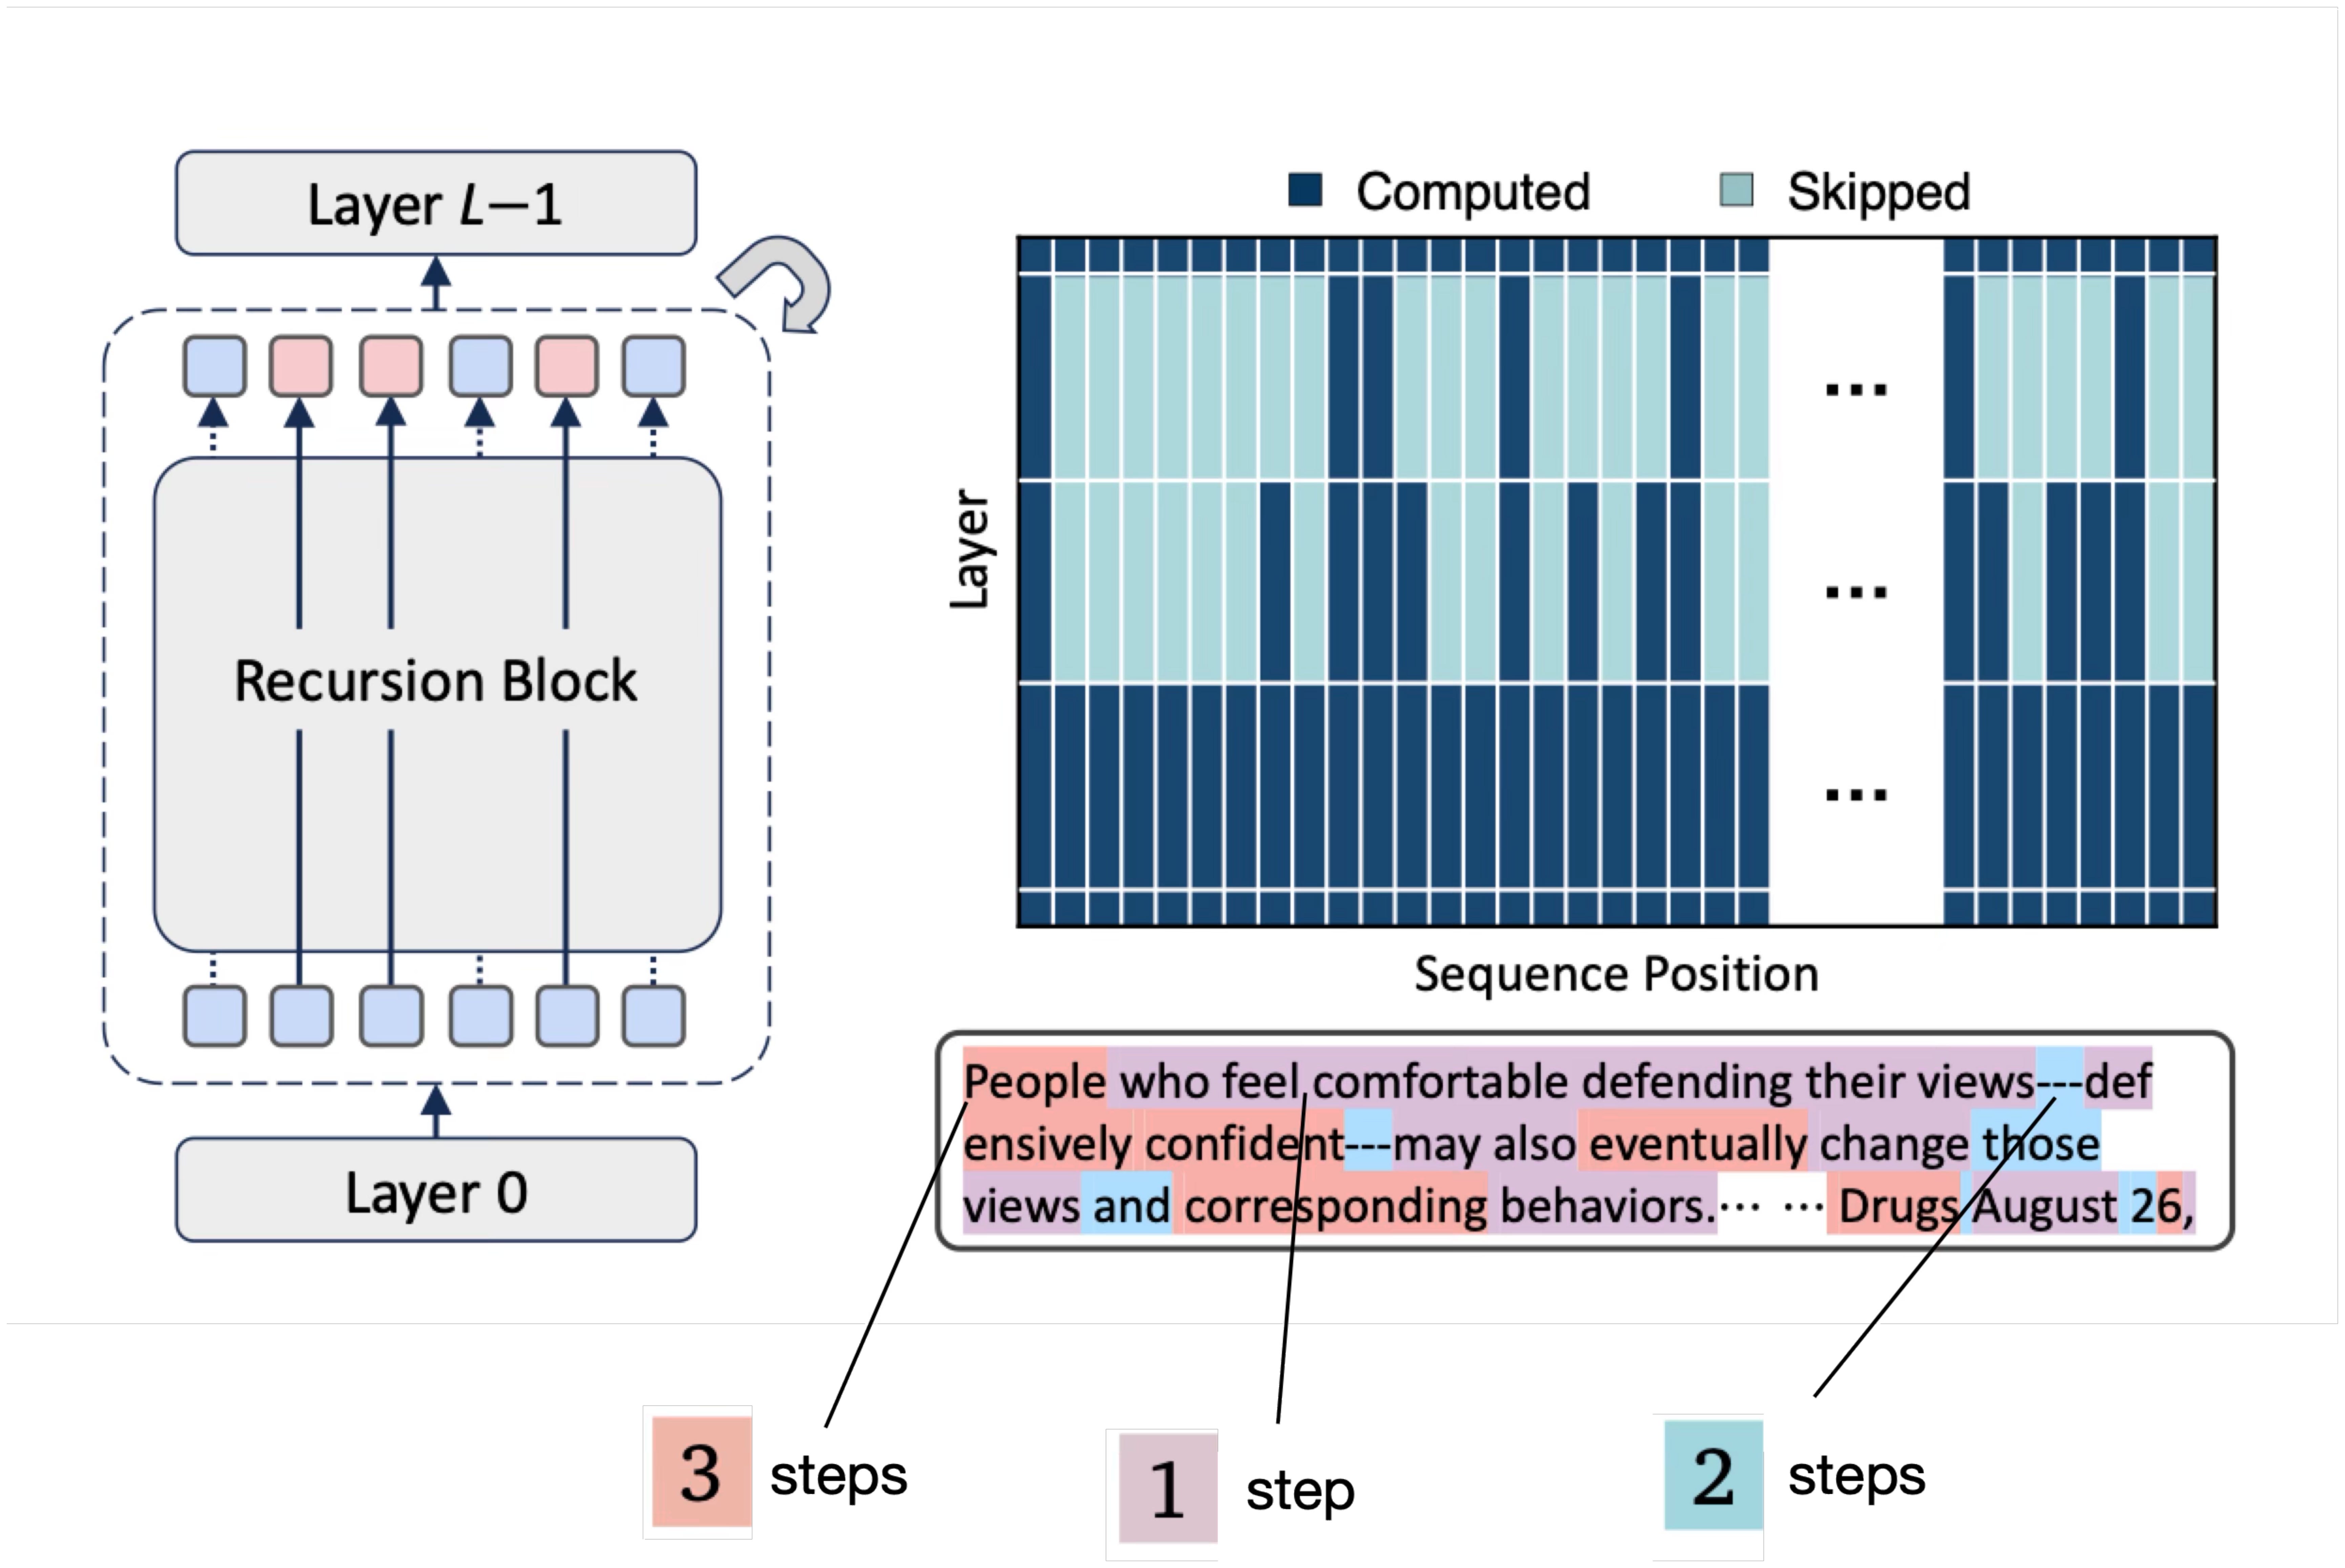
How does the model decide how many times a token should go through the recursion block? In the previously discussed Universal Transformer, it’s based on a learned halting probability at each step. This Mixture-of-Recursion approach here uses a small, learned router. This is similar to the routing idea in a mixture-of-experts model, except that here the routing decision determines how many times to apply the shared stack.
The router operates on a token’s hidden representation, which also contains information about its context. So, we shouldn’t think of this as assigning every occurrence of a particular token the same number of passes (i.e., the word “People” in the figure above doesn’t always go through a loop of 3). The decision can change depending on where that word appears and what came before it.
Now, how does the routing work exactly? The paper explores two ways to make this routing decision, as illustrated below.
Figure 10. Two ways to choose the recursion depth. On the left, routers select which tokens continue at each step. On the right, a single router assigns the number of passes at the beginning. Figure from the Mixture-of-Recursions paper.
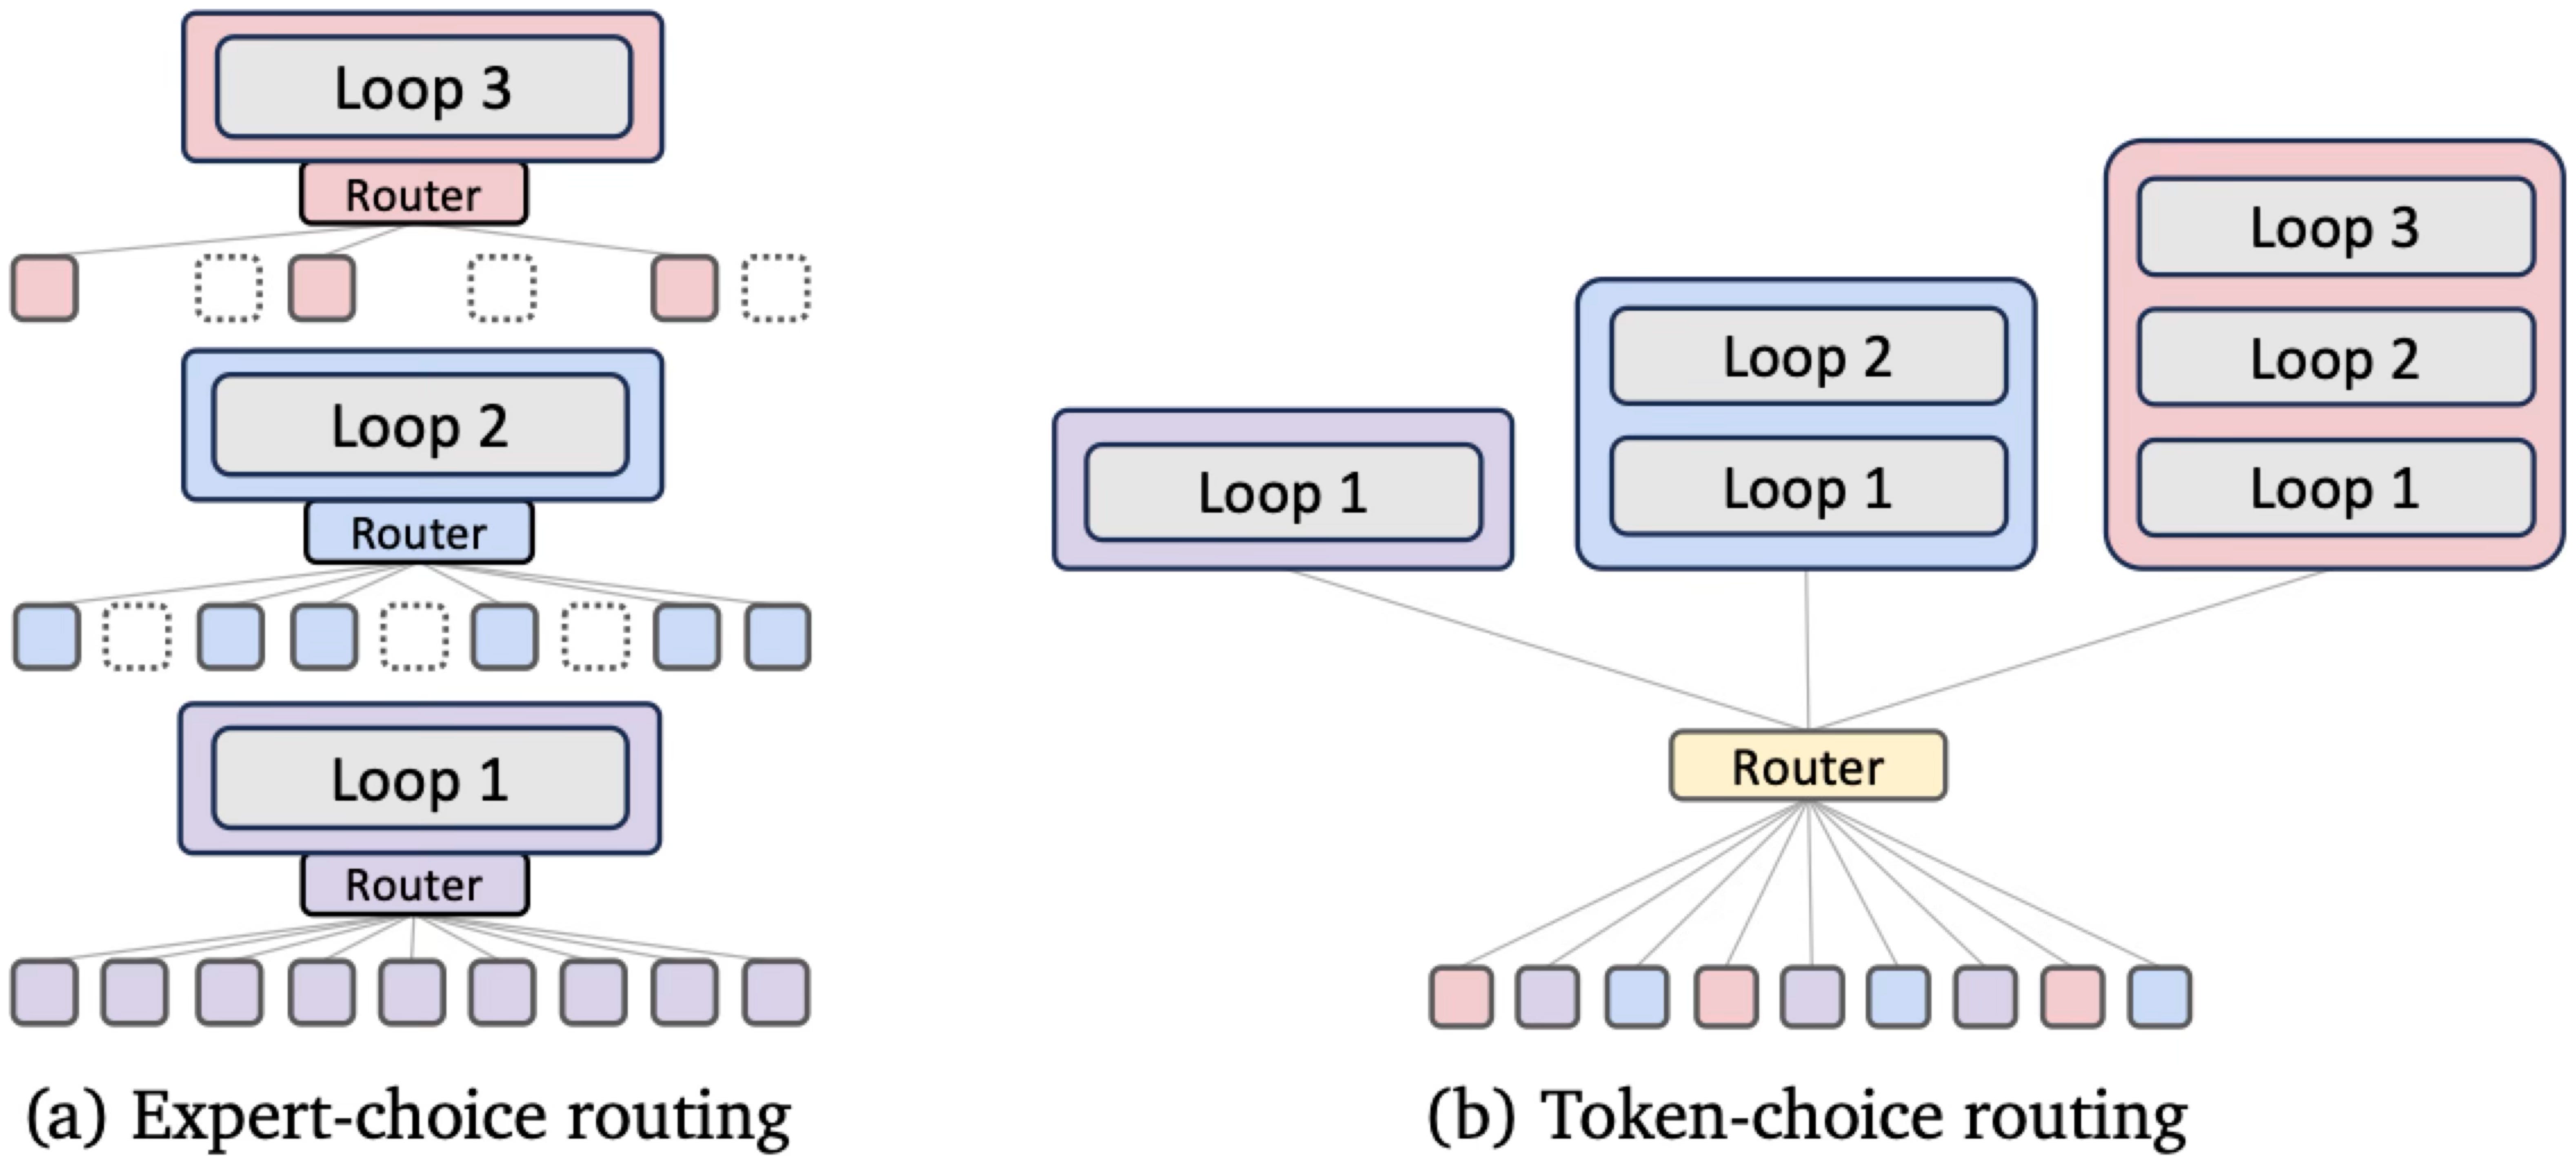
In expert-choice routing , which is shown in the left subpanel in the figure above, each recursion step selects which tokens it will process. Tokens that exit are excluded from later steps. In token-choice routing , shown on the right, the router makes one decision at the beginning, assigning each token to a path with one, two, or three passes.
In both cases, the transformer weights are reused across passes, similar to Nanbeige, etc. But the additional flexibility comes from choosing how much computation each token receives. The model and its routers are trained together, so the model learns to work with these different paths during training.
The plot from the Mixture-of-Recursions paper below compares a regular transformer (Vanilla), a transformer with fixed recursion (Recursive), and Mixture-of-Recursions (MoR) for different model sizes and compute budgets (x-axis).
At the smallest model scale, the regular transformer performs best. For the larger models, Mixture-of-Recursions catches up and often performs better, especially at the smaller training budgets. At the largest budget, several of the curves are very close. So, the advantage depends on the model size and how much compute we spend on training.
Another detail here is that equal training compute doesn’t necessarily mean an equal number of training tokens. By skipping some computation, Mixture-of-Recursions can process more tokens within the same budget.
I think this is an interesting example because it shows that there are several choices within the looped-transformer idea, that is, how many loops there are at each position and how that’s decided.
So, in short, we can say that using looped transformers can improve model quality at a fixed compute budget if the model is large enough. (It also illustrates the importance of running some experiments at scale; e.g., just looking at the smaller 135M parameter model, we would have drawn the opposite conclusion.)
By the way, if you have a background in deep learning (or even artificial neural networks in the 1990s), the looping or “recurrent depth” idea should be somewhat familiar. Remember recurrent neural networks (RNNs)? The whole idea in RNNs is to reuse the layers (weights) from a previous iteration.
Figure 12: Illustration of an RNN (from my 2022 “Machine Learning with PyTorch and Scikit-Learn book”, https://amzn.to/3YzRnPR)
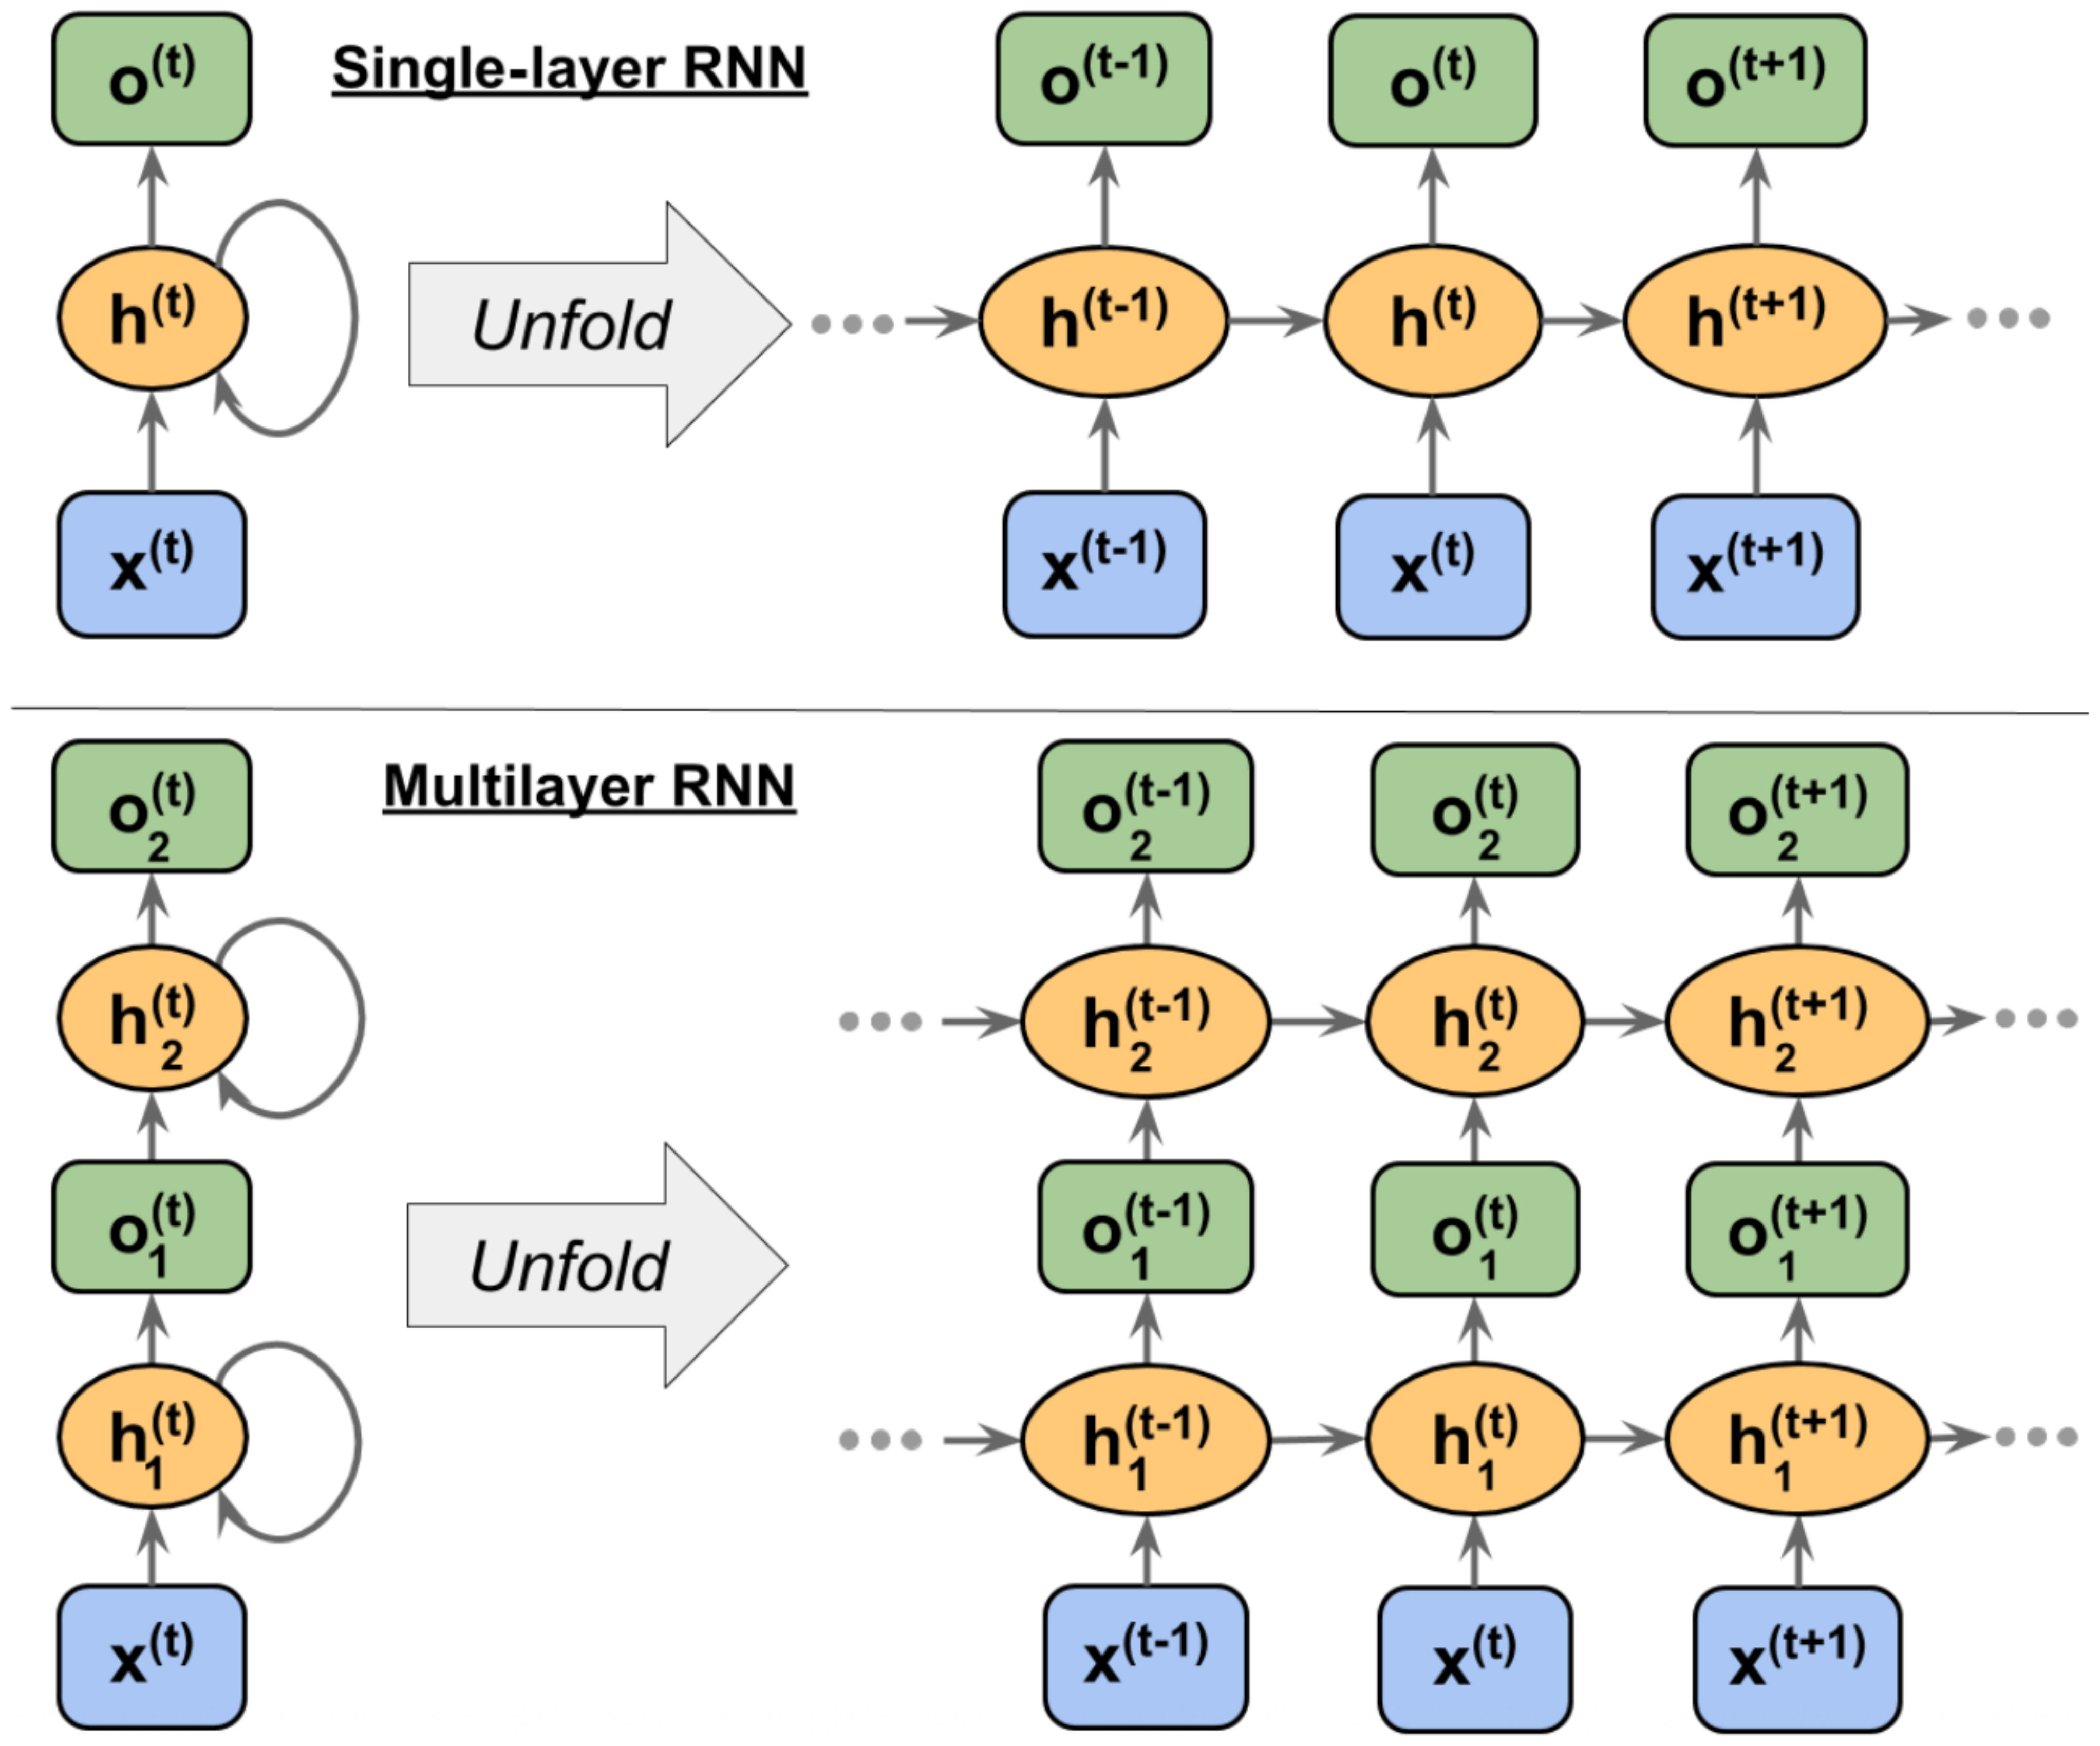
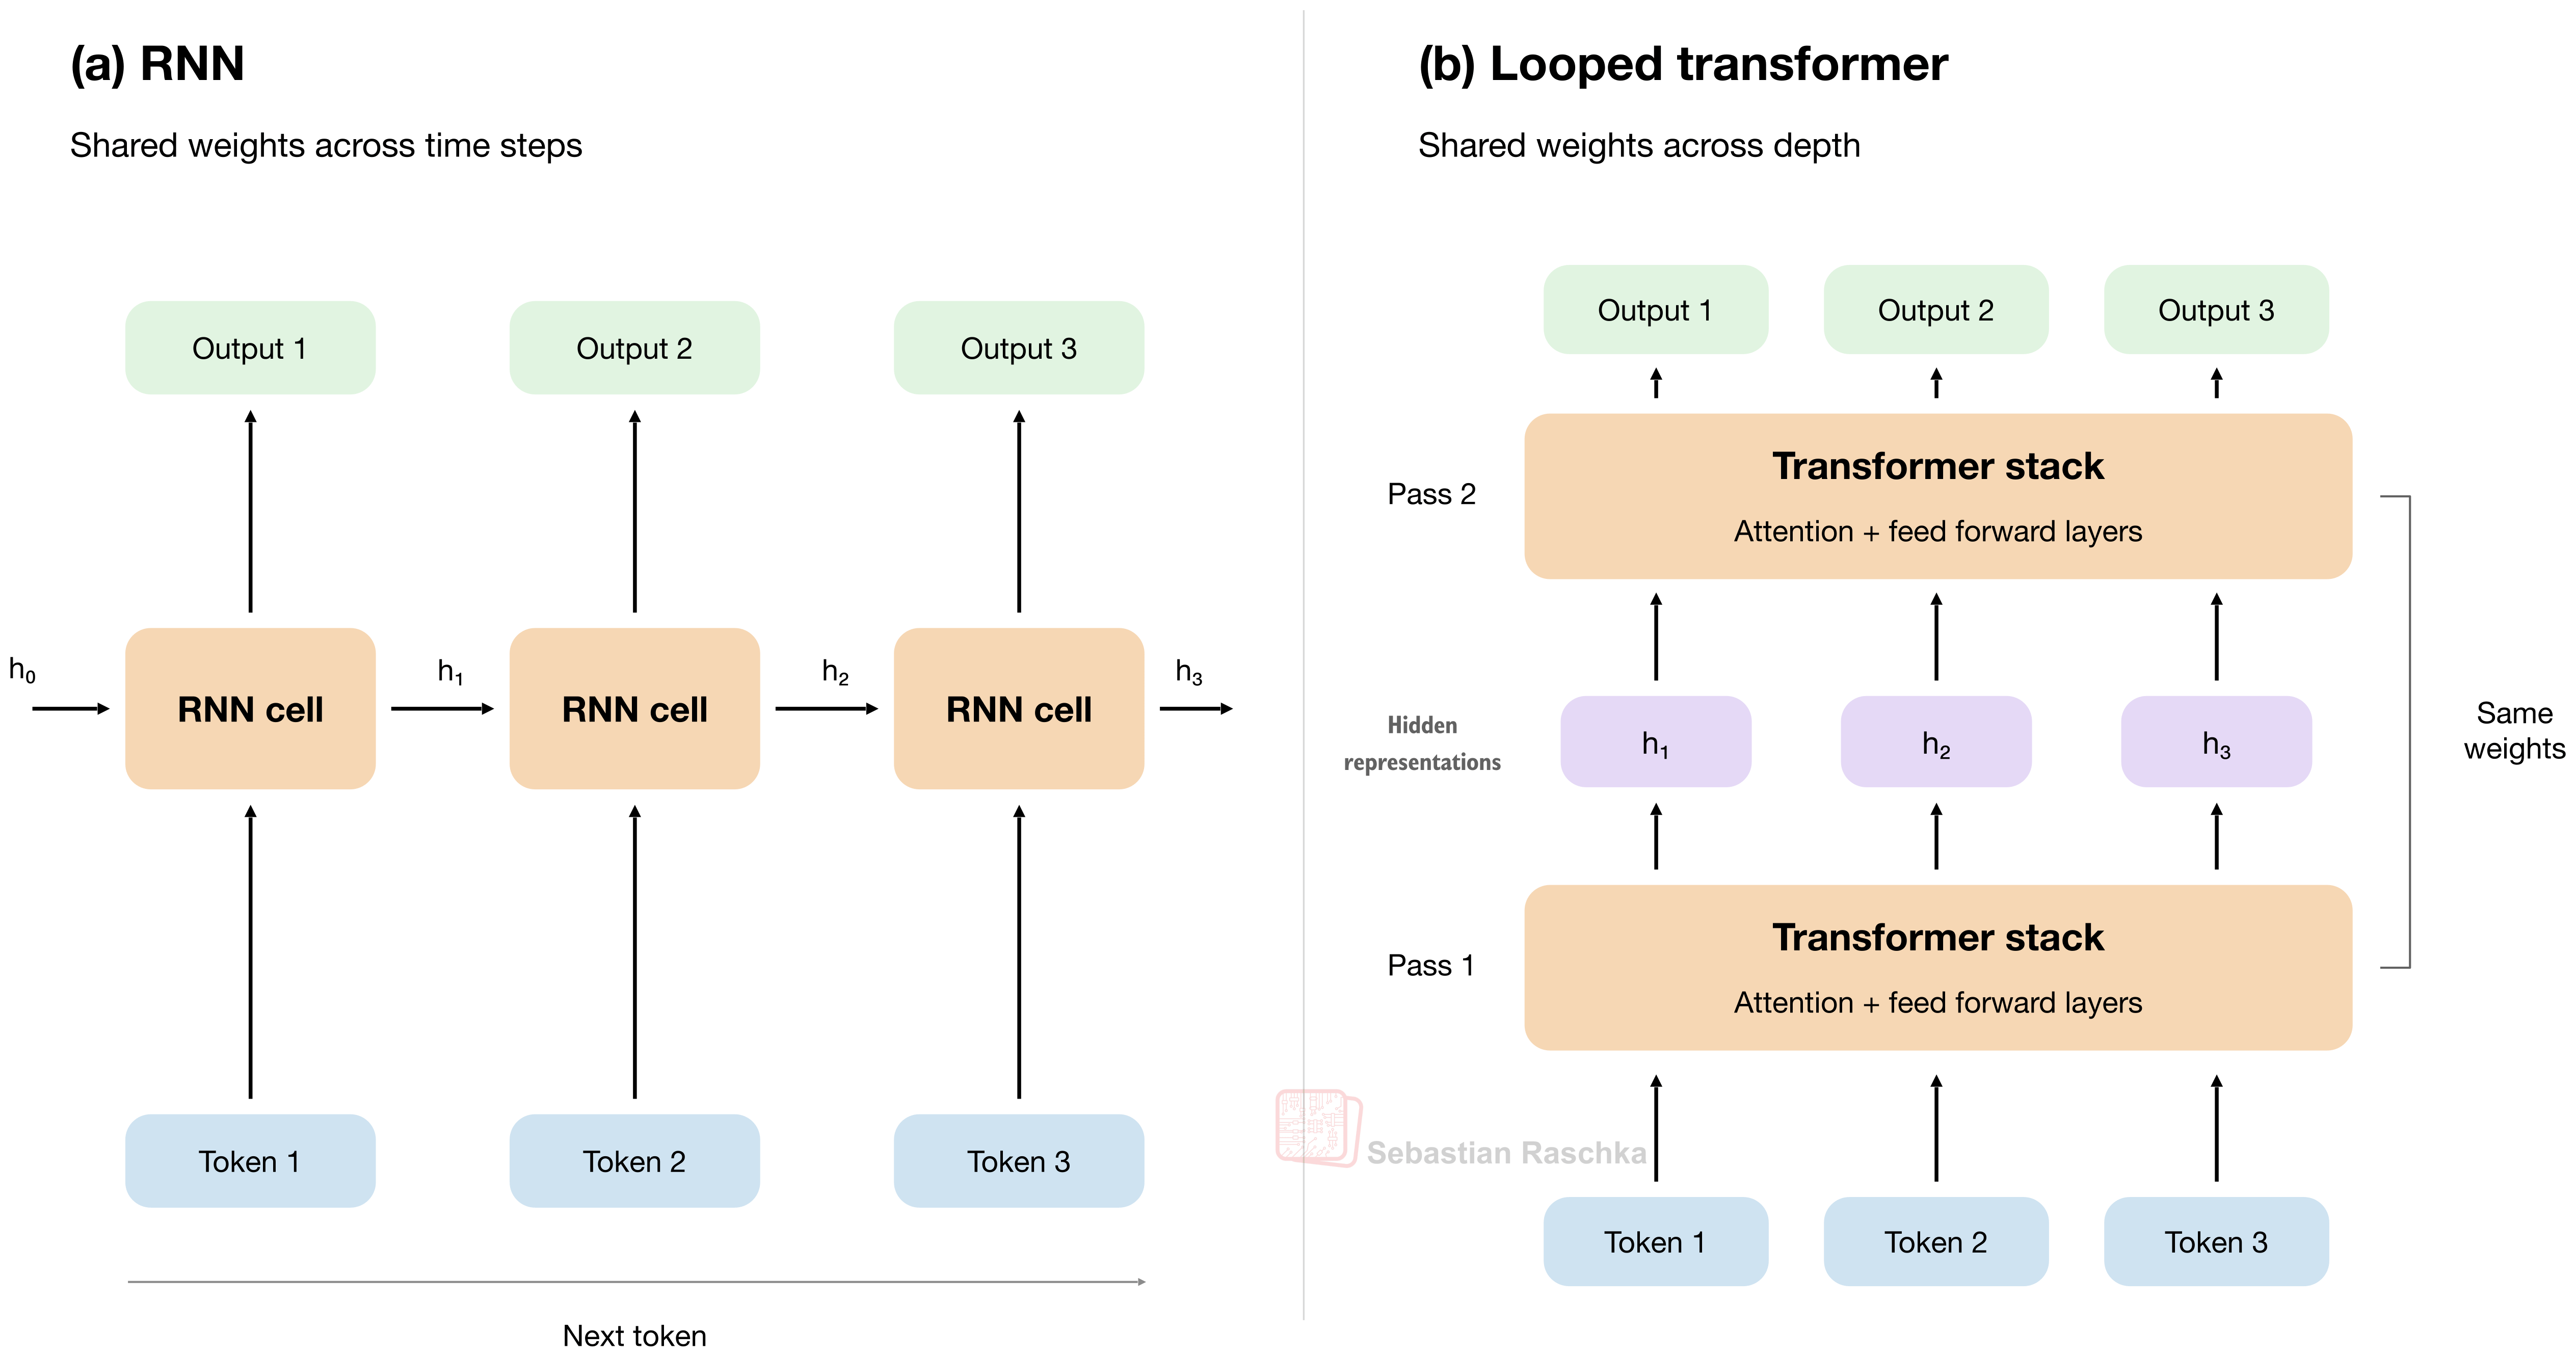
The main distinction is that RNNs reuse their weights across time steps. That is, the hidden state is carried forward from one token to the next. In the looped transformer, the looping of a token is across the architecture depth.
Or, in other words, in a conventional RNN, each step takes the next element in the input sequence and the hidden state from the previous step. So, when the RNN is processing a chunk of text, it reads one word or token at a time and carries information from the earlier words forward in its hidden state.
In a looped transformer, the intermediate representation of a given token goes through the transformer stack multiple times. The model still uses attention to pass information between tokens.
If this analogy is a bit too confusing, don’t worry about it too much. A perhaps simpler way to think about looped transformers is to think of them as reusing transformer blocks, similar to making the model bigger but with weight sharing.
Figure 13: Side-by-side comparison of the “recurrence” in an RNN and a looped transformer.
Before we discuss whether the looped transformer mechanism obscured reasoning traces, as rumored in The Information quote from earlier, does GPT-6 Astra even use the looped transformer concepts?
We have to keep in mind that this is still just a rumor or scoop, with no official confirmation. If the model were open-weight, we could double-check this ourselves, of course, but in this case we have to rely on unverified reporting.
However, I think it’s highly likely that GPT-6 Astra uses looped transformer aspects. First, there is the reporting mentioned above. Second, it’s a technique that has shown promise in past studies (as discussed earlier), so why not? Third, OpenAI’s chief scientist said the following.
[...] The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4. [...]
However, this doesn’t confirm the looped transformer architecture explicitly, and it could also just mean they use twice as many regular transformer blocks.
In my opinion, the success (i.e., good modeling performance) behind Astra is likely primarily due to other reasons, namely improved training recipes and training data.
The looped transformer tweak might help a bit, but I think that The Information is overestimating its contribution.
Next, let’s finally address the elephant in the room: does looped transformer obscure the reasoning traces?
First, OpenAI has been hiding (most of) the reasoning traces from users from the very beginning, since OpenAI o1, anyway. So, for the end-user, there shouldn’t be a big difference.
So, the interpretation-concern is mostly with respect to the model developers.
Either way, I don’t think that looped transformers are significant contributors towards hiding or obscuring chains of thought. To explain my own reasoning (no pun intended), let’s take a step back and explain how reasoning models work.
Reasoning models typically generate intermediate steps before producing a final answer. These steps use regular text token (that are optionally hidden from the user in some user interfaces) and called a reasoning trace or chain of thought.
For example, say we ask for two numbers whose sum is 10 and whose product is 21. In the figure below, the model tries 5 and 5 at first. While the sum is correct, the product is 25, not 21. Next, it then tries 3 and 7 and checks both conditions again.
Figure 15. An illustrative LLM response annotated to show intermediate steps, backtracking, and the final answer.
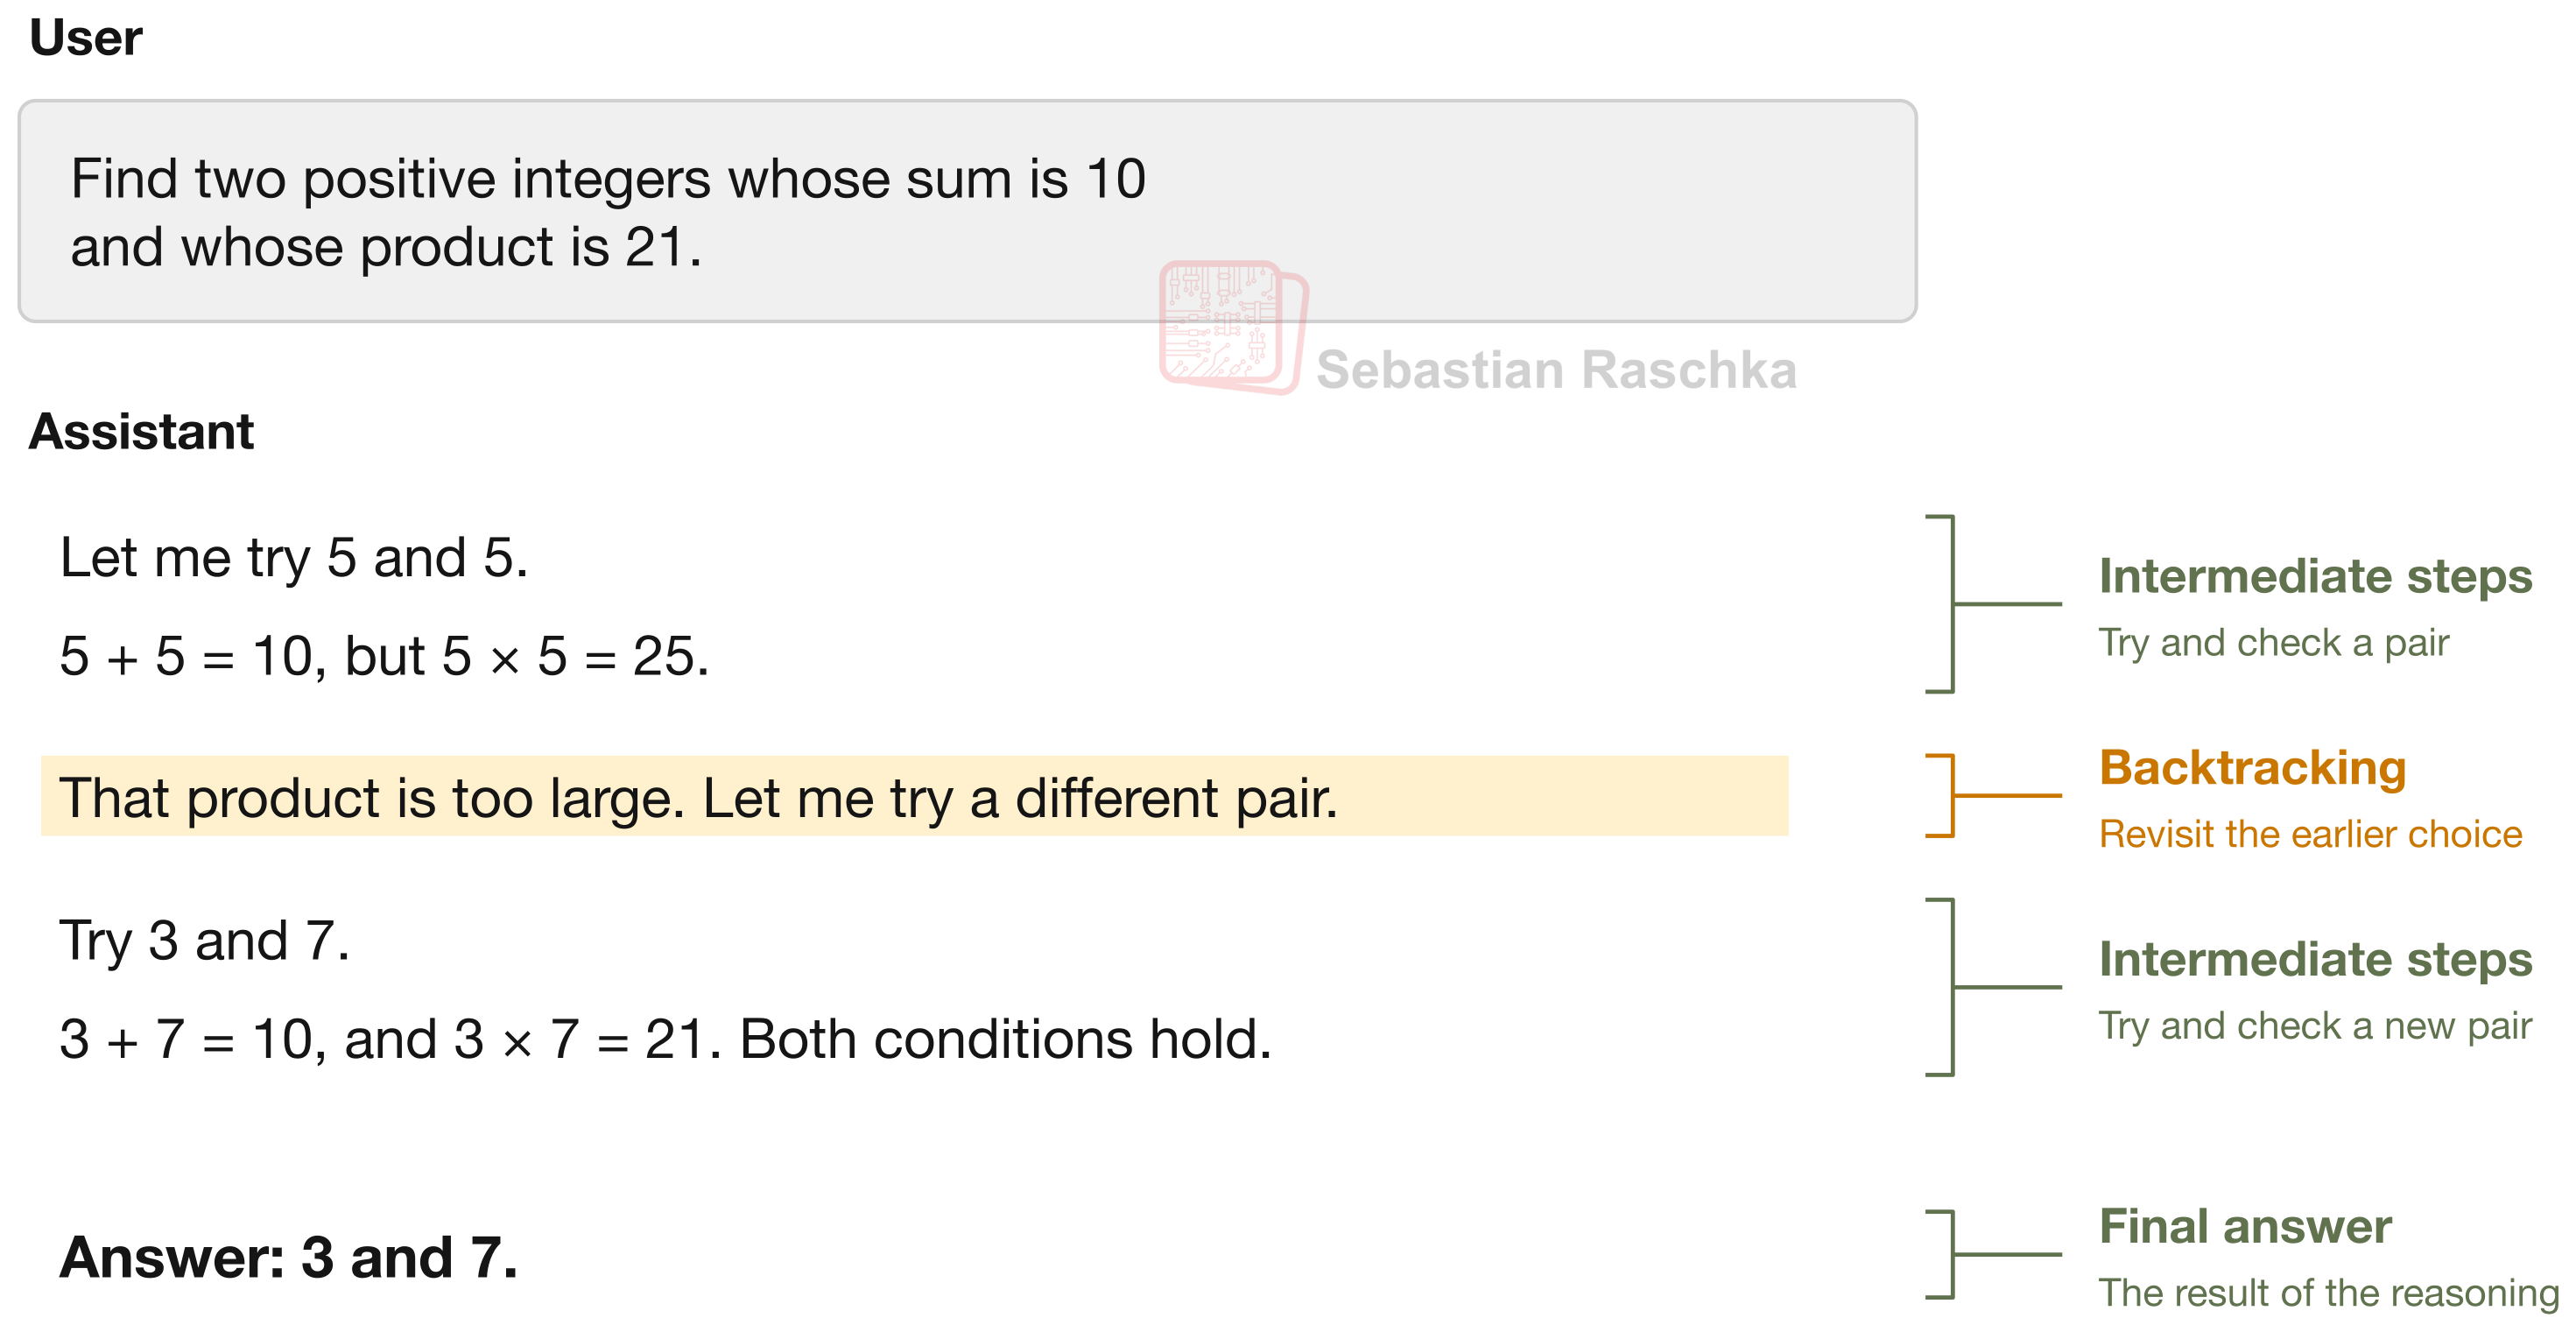
The figure illustrates how a reasoning model “reasons,” including backtracking. That is, the model notices a mistake, then revisits an earlier choice, and then continues with a different approach.
Note that the model still generates one token at a time, using the prompt and previous tokens as context. So, these intermediate steps work as a scratch pad and add computation before the final answer.
The final answer can then be much shorter than the reasoning trace that preceded it, as shown in the example above. (OpenAI tends to hide most of the reasoning traces from the users.)
For more details on understanding and developing reasoning models, I recommend my book Build a Reasoning Model From Scratch.
Now, extra tokens in the reasoning trace add more computation. Looped transformers add more computation, because the tokens go through more transformer blocks. One might argue that a model with looping uses more computation internally, it doesn’t need as many external thinking tokens.
Below is a selection of the GPT-6 benchmarks with the output token number on the x-axis.
We can see that GPT-6 Astra doesn’t necessarily use fewer tokens than its GPT 5.6 Sol predecessor across effort levels overall. However, at a fixed accuray, it is true that GPT-6 Astra uses fewer tokens than GPT 5.6 Sol.
Is this a concern for interpretability? Not necessarily. Using fewer tokens could just mean that the model is more capable and makes fewer mistakes, uses less backtracking, and so on. I.e., it might just get more things right on the first try. To me, that doesn’t raise an immediate concern regarding interpretability.
I mean, the same is true for previous models. I don’t think that anyone has strong concerns that GPT 5.6 Sol is so much less interpretable than the smaller GPT 5.6 Luna model, which uses many more tokens for the same task performance, as shown below.
In fact, as we can see that Luna uses 80% more tokens than Sol at similar modeling performance. Does that make Sol that much less interpretable?
Rather, the more plausible answer here is that more capable (bigger, well-trained models that use more compute) can solve problems more efficiently, where “efficient” here means fewer tokens.
It’s also worth keeping in mind that a reasoning trace is not guaranteed to faithfully describe everything that happens inside the model. In my view, the only valid concern is that looped transformers purposefully mislead users by presenting “fake” reasoning traces more often than conventional transformers. But I don’t think we have any strong evidence that this is happening.
Now, Astra’s system card does state that there is also evidence of reduced monitorability of their reasoning traces, and there is a bit of regression relative to Sol. It’s mostly associated with shorter, less informative traces. But again, this doesn’t establish looping as the root cause. It could just be due to the shorter length in general, similar to the Luna vs Sol example above.
A few hours after I shared my thoughts about looped transformers with respect to hiding reasoning chains, Jakub Pachocki (OpenAI’s Chief Scientist) also shared the following clarification:
I want to prevent a race into unmonitorability kicked off by confused reporting. The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4. OpenAI has worked to preserve and utilize chain-of-thought monitoring since our very first reasoning models. We deeply care about this technique, as it can give us a view into how model alignment generalizes from its training distribution. I do think it is fragile and unfortunately trending in a negative direction, for reasons not contingent on architecture changes that I will write about soon. But there are things we can do to strengthen it, and it’s a core goal of our current research program.
The “confused reporting” likely refers to The Information’s aforementioned paragraph here, implying that the looping aspect does not have anything to do with chain-of-thought changes.
Lastly, I want to share some interesting papers related to looped transformer architectures beyond the ones we already discussed.
Related to the Universal Transformer, the 2025 Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach paper studies how a model can use additional loops at inference time. For this, they trained a relatively modest but also not super tiny 3.5B-parameter model on 800B tokens.
Instead of reusing the same block over and over again as in the Universal Transformer, it repeats a stack like in Nanbeige; however, in contrast to Nanbeige, it sandwiches this shared stack of four blocks between 2 initial and 2 final blocks.
Also, what’s different from Nanbeige is that the shared stack receives the output of the initial blocks at the start of every loop, in addition to the previous loop’s hidden state. These are concatenated and passed through a learned linear projection before entering the four shared blocks. You can think of this as giving the stack access to the same initial input representation on every pass. This whole layout is summarized in the figure below.
So, in short, this is an additional and interesting looped transformer variant.
Figure 19. Conceptual summary of the latent reasoning model in Geiping et al..
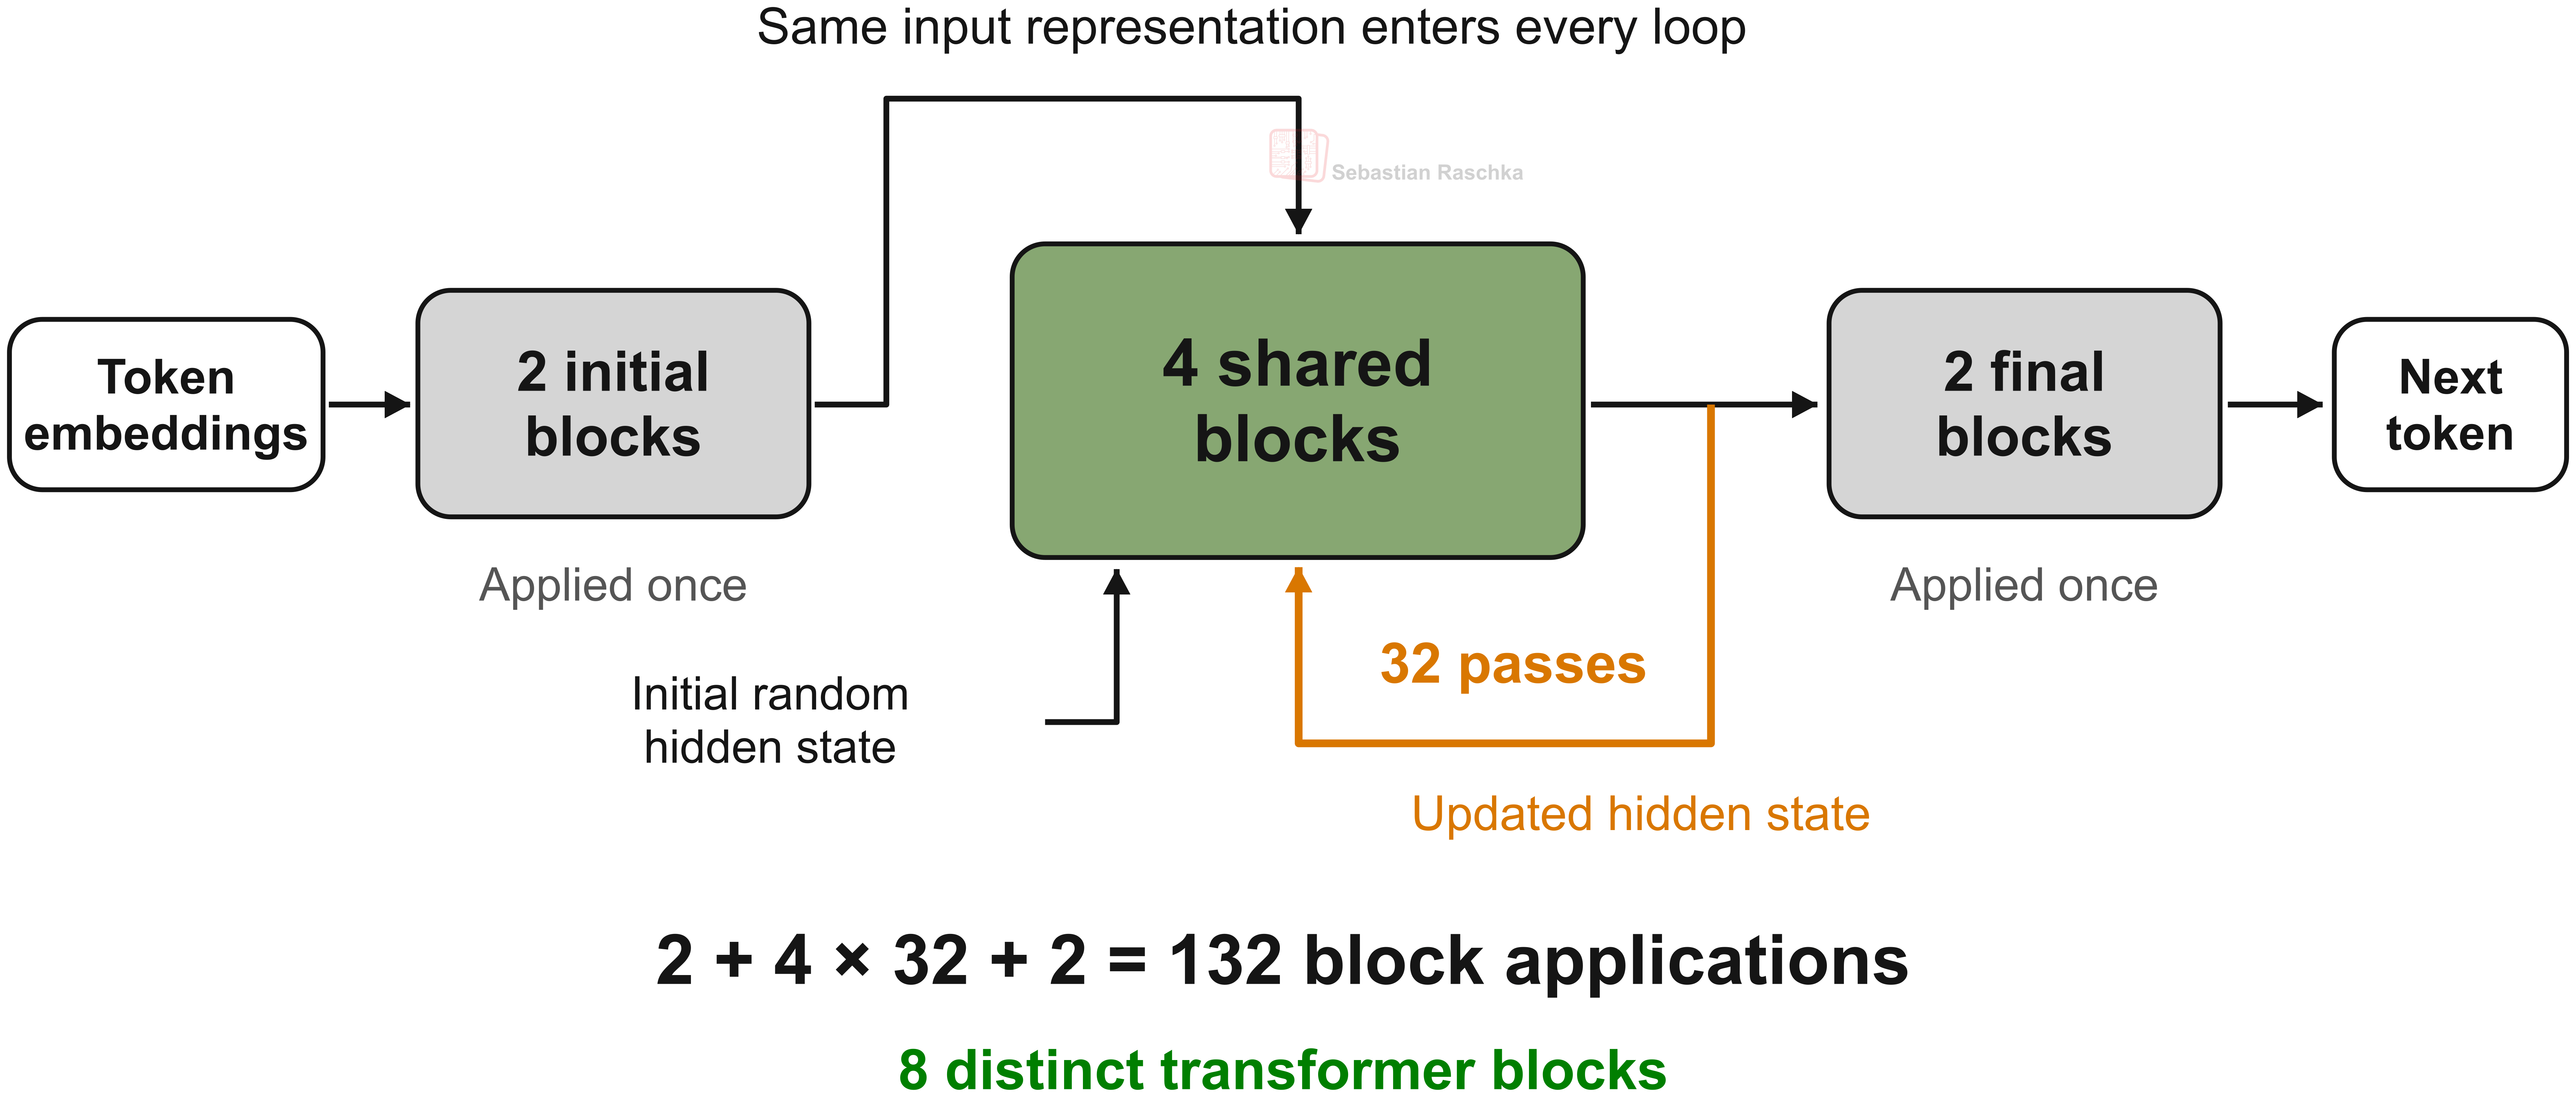
An interesting detail is that the researchers vary the number of loops during training. This prepares the model to work with different amounts of computation at inference time.
Here, during training, the loop count is randomly sampled. At inference, a fixed budget is chosen by whoever runs the model, such as 8, 32, or 64 loops. Additionally, they have an adaptive stopping mechanism for each token based on the next-token probability distribution. If the KL-divergence between 2 successive rounds is below a certain threshold, i.e., if the distributions are too similar, the looping is halted.
The overall benefit depends on the task. In their evaluations, HellaSwag performance largely levels off after about eight loops, while GSM8K and HumanEval benefit from more.
However, while the title of the paper mentions “latent reasoning”, the model can still generate a textual chain of thought. Looping just gives it additional computation before each output token.
There’s a useful distinction between storing information and using it to solve a problem. For instance, the Beyond Parameters: Exploring Virtual Logic Depth for Scaling Laws paper from June 2025 investigates this by measuring memorization and reasoning in an LLM separately.
First, in the memorization experiments, looping leaves the amount of stored information nearly unchanged when the parameter count stays fixed. Increasing the number of distinct parameters does increase this capacity. From this, we can conclude that looping doesn’t add or let’s the model retrieve more knowledge. This makes sense. Information retrieval is a relatively simple task once the information is stored. Also, looping in itself is computing not “storing” mechanism.
Second, in separate reasoning experiments, reusing the blocks improves performance on multi-step math problems without adding parameters. This is interesting. Here, we can conclude that extra computation can help a model solve problems even when it doesn’t have more space to store information. But again, bigger models can also improve reasoning (although they add parameters as well).
Figure 20. In this memorization test, capacity grows with parameter count but changes little with additional block applications. Annotated figure from Zhu et al.
The just-released SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers paper from September 2026 comes back to the cost comparison from section 2.2. What happens if we compare looped and conventional transformers with approximately the same compute per token, total non-embedding parameters, and KV cache requirements?
The researchers use a mixture-of-experts architecture and apply the middle half of the transformer blocks twice, kind of similar to Nanbeige except with the sandwiching in Latent Reasoning.
However, they narrow the hidden dimension to compensate for the compute needed for the extra block applications. And then, because that makes the parameter count smaller, they then add experts to recover the total parameter count. They also adjust the attention head configuration to keep the KV cache comparable.
The experiments scale up to 54B non-embedding parameters and so on. Then, from fitted scaling curves, the researchers estimate that SMELT requires about 6.8-18% less training compute to reach the same validation loss within the studied compute range.
So, this answers the question of whether looped transformers are worth it computationally: Yes! They give us a slightly better model when using the same compute budget.
Finally, the also very recent Full-bandwidth transformer paper from August 2026 studies recurrence across token positions. At each decoding step, it combines the previous token’s final hidden state with the newly sampled token’s embedding through a learned gate. This becomes the input for the next forward pass.
So, the next token’s computation has access to the previous token’s final representation from the bottom of the stack, which is somewhat similar to Latent Reasoning.
When using a 1B base model, they found that their latent feedback approach outputs shorter reasoning traces on MATH500 while maintaining or improving accuracy. However, the shortening effect disappears after instruction tuning.
Figure 22. Latent feedback shortens reasoning traces in the base model, but this effect disappears after instruction tuning. Adapted from Wang et al., Figure 6, CC BY 4.0. Definitions and caveats added.
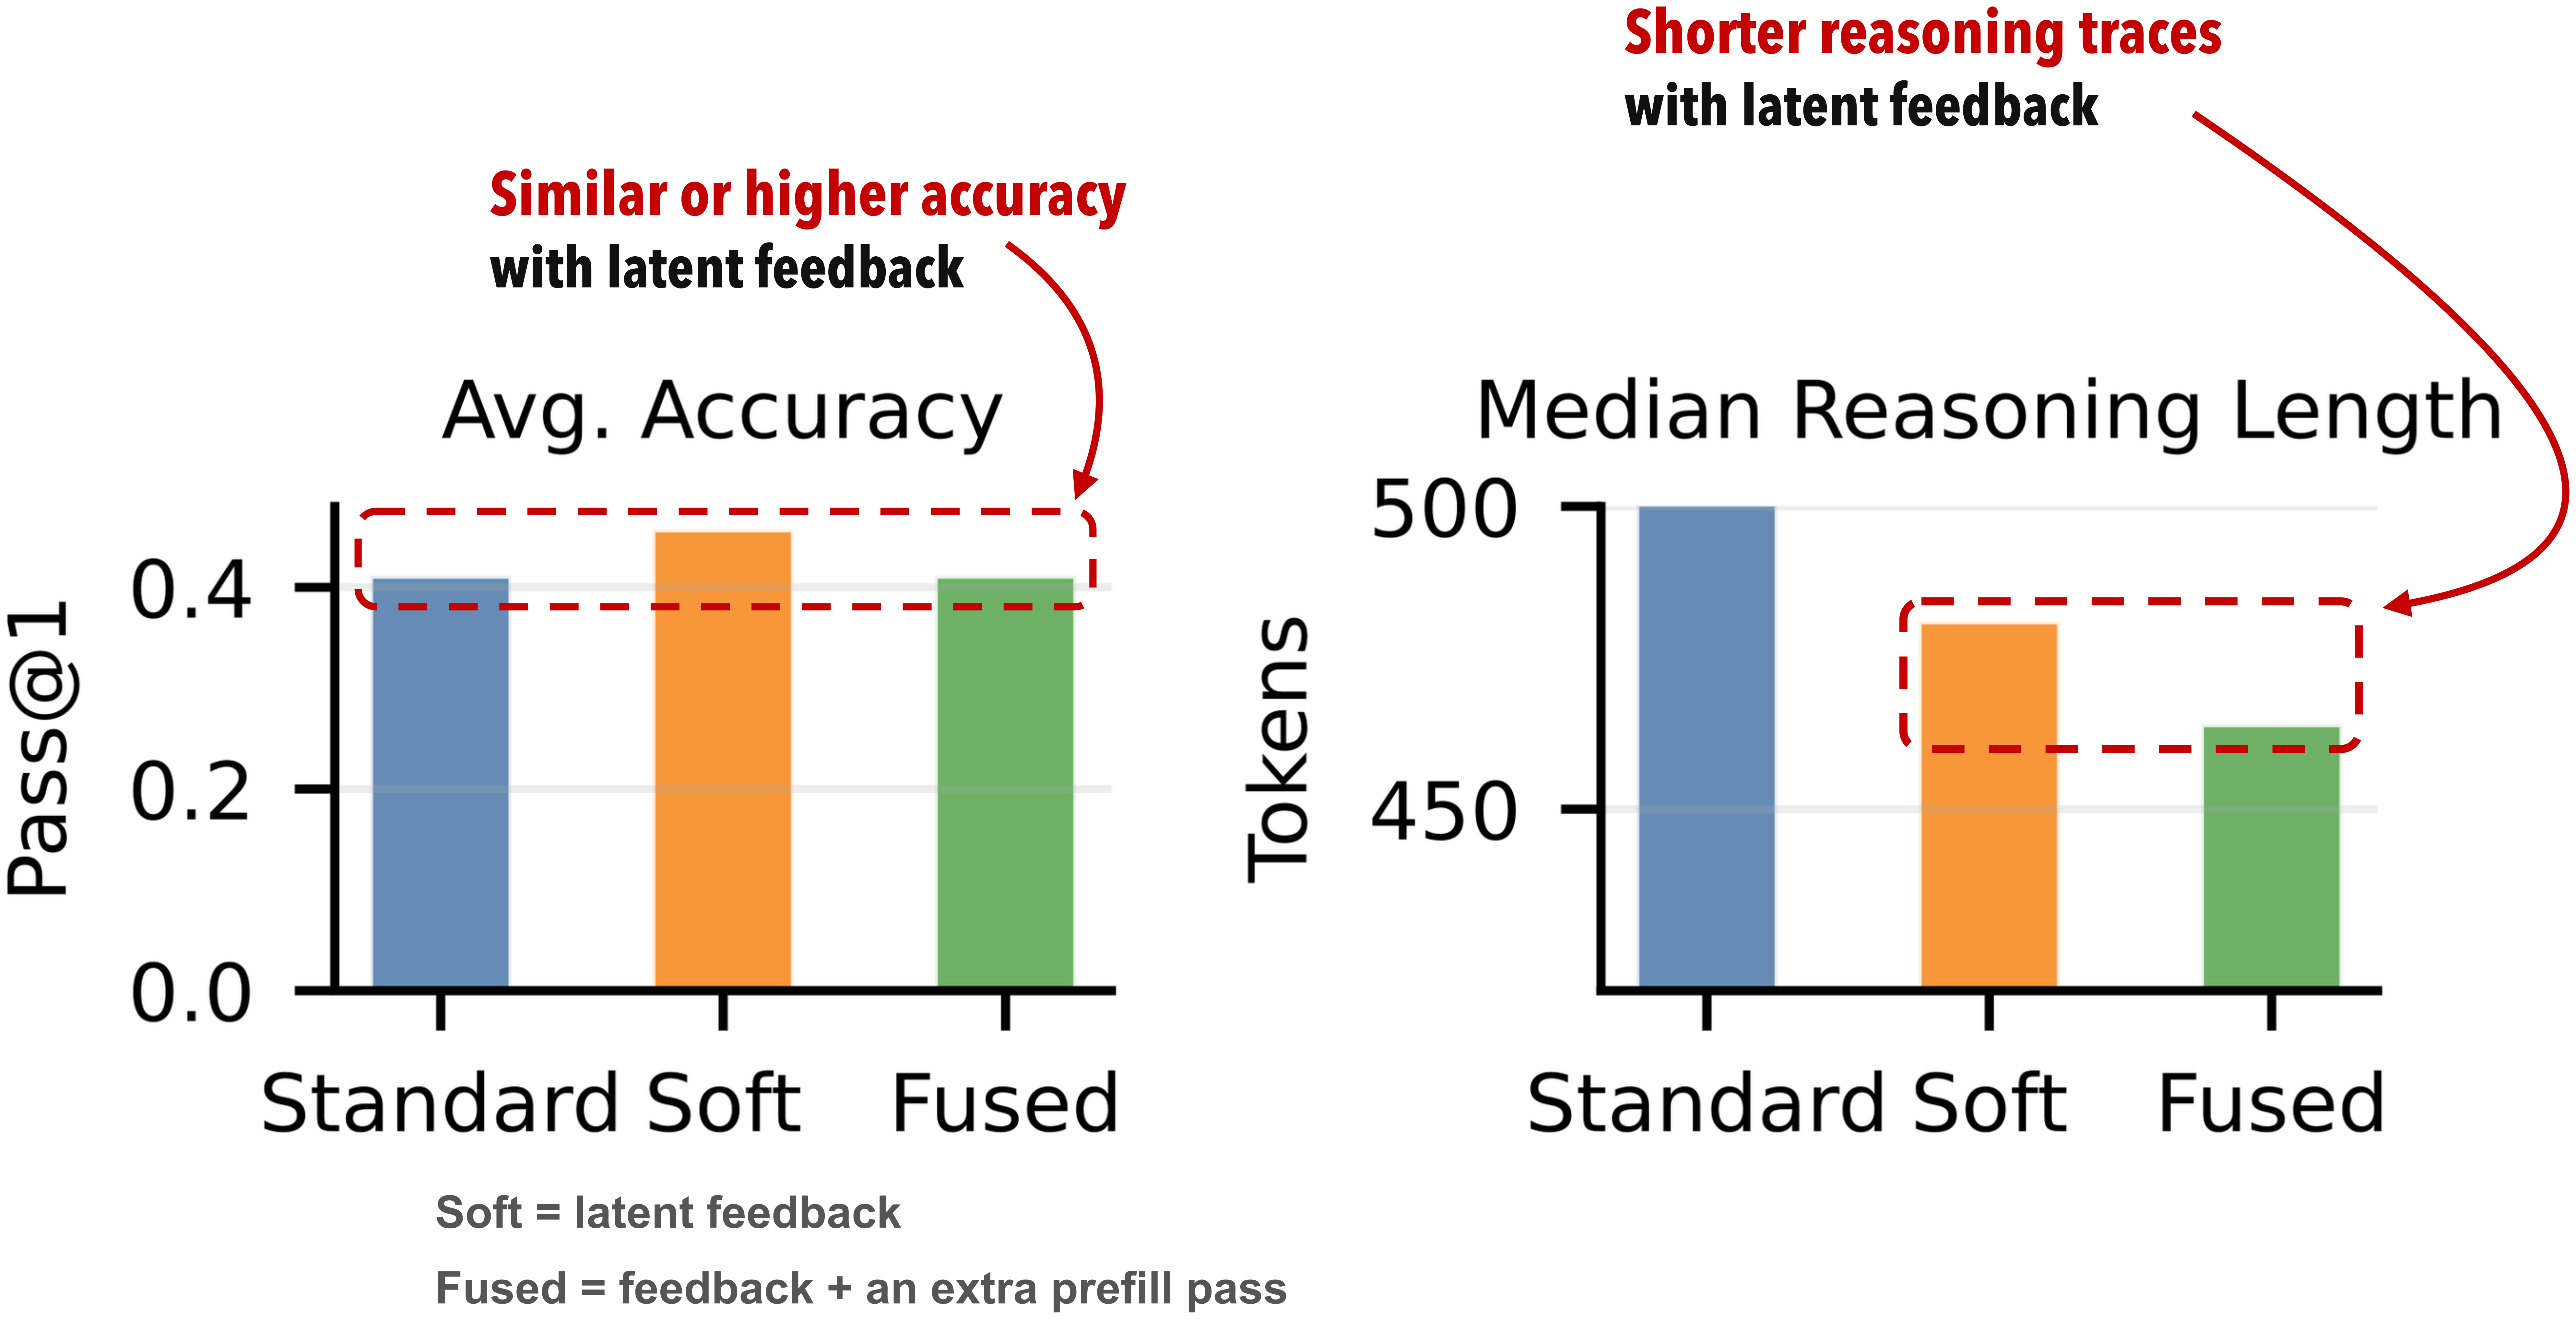
Anyway, this is interesting because this connects directly to the earlier discussion about whether looping results in shorter reasoning traces. The result depends on both the feedback mechanism and how the model is trained, of course. Also, the experiment doesn’t establish whether those shorter traces are less faithful.
Also, the big caveat of the study is that they didn’t test whether increasing the size of the model in conventional ways (adding more transformer blocks instead of looping) has a similar effect on the reasoning trace lengths.
To wrap it all up, we can say that yes, OpenAI GPT-6 Astra is a very strong model. And it’s making a particularly large leap in computer use. I believe computer use will be the next big focus area for open-source and proprietary harnesses in the upcoming months. I find open-source especially important when it comes to computer use, as “with great power come great responsibilities”, and it’s nice to be able to audit the harness before giving it access to my main computer.
Besides, GPT-6 Astra is likely to use a variant of the looped transformer. Looped transformers simply give better modeling performance at a fixed compute budget.
Also, better modeling performance may decrease in shorter reasoning chains. But this is not a new trend. We have always seen that within a model family with models of different sizes (e.g., GPT 5.6 Luna versus Sol).
In my opinion, shorter reasoning traces are a side effect of more “intelligent” or capable models that make fewer mistakes and can access more compute internally inside their architecture versus using a reasoning trace as a scratchpad. In a sense, the same is true for humans. During an in-person college math exam, a smart and well-prepared student likely requires less use of the notepaper and needs to backtrack less often, and so on.
Thanks for reading and supporting my work!
If you’d like to learn how to build reasoning models yourself, check out my book Build a Reasoning Model (From Scratch). We start with a pre-trained LLM and add reasoning capabilities step by step, with code you can run and experiment with. It’s both fun and rewarding, and a good investment in future-self to build the fundamentals to keep up with the AI field.
Also, if you’ve read one of my books, I’d appreciate a short, honest review on Amazon. Reviews help other readers decide whether a book is right for them and are a simple way to support authors.