面向多轮对话的 Agent 评估指标
英文标题:Agent Evaluation Metric for multi-turn conversations
多轮 Agent 的早期错误会在后续回合中级联传播,而仅评估最终结果或单轮回复,往往无法识别真正的根因。本文提出 Agent Evaluation Metric(AEM),以可分解、逐回合的方式衡量 Agent 质量,并首先将“正确性”拆分为真实性与完整性两个子指标。AEM 可区分根因回合与仅继承此前错误的级联失败回合,并通过失败分类明确定位工具、动作、参数或回复的问题。对开发者而言,这种方法有助于将笼统的任务成功率转化为可诊断、可优化、可扩展至安全性和指令保持等维度的评估体系。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 240.9 KB
 138.1 KB
 232.4 KB
 258.1 KB
 16.3 KB
 18.7 KB
 25.2 KB
 47.6 KB
中文
多轮 Agent 会以单轮评估无法捕捉的方式失败:一个早期错误会悄然污染之后的每一轮。本文介绍 Agent Evaluation Metric(AEM):一种可分解、逐回合衡量 Agent 质量的方法。我们将其应用于第一个维度——正确性。我们展示 AEM 如何定位导致失败的那一个回合,并将其与那些仅继承问题的后续回合区分开来。
多轮 Agent 对话中的正确性挑战
在多轮对话中评估 Agent 的正确性很困难,因为这一属性本身十分脆弱,而整体评分会掩盖错误发生的位置。本节说明级联错误为何会击败基于结果的评估,并阐释为何需要一种可分解的逐回合指标。
为什么正确性至关重要
一次错误的工具调用会跨回合级联为后续失败。设想一个包含五个回合、使用企业助手的对话:用户先要求创建销售报告,然后对其进行细化。在第 2 回合中,Agent 选择了正确的动作,但传入的是“利润”而非“收入”。这一个错误随后会在每一个后续回合中悄然传播。
下图追踪了这一失败过程。它展示了第 2 回合的一个早期错误如何级联至第 3—5 回合,以及逐回合评估如何将唯一的根因与其下游影响隔离开来。
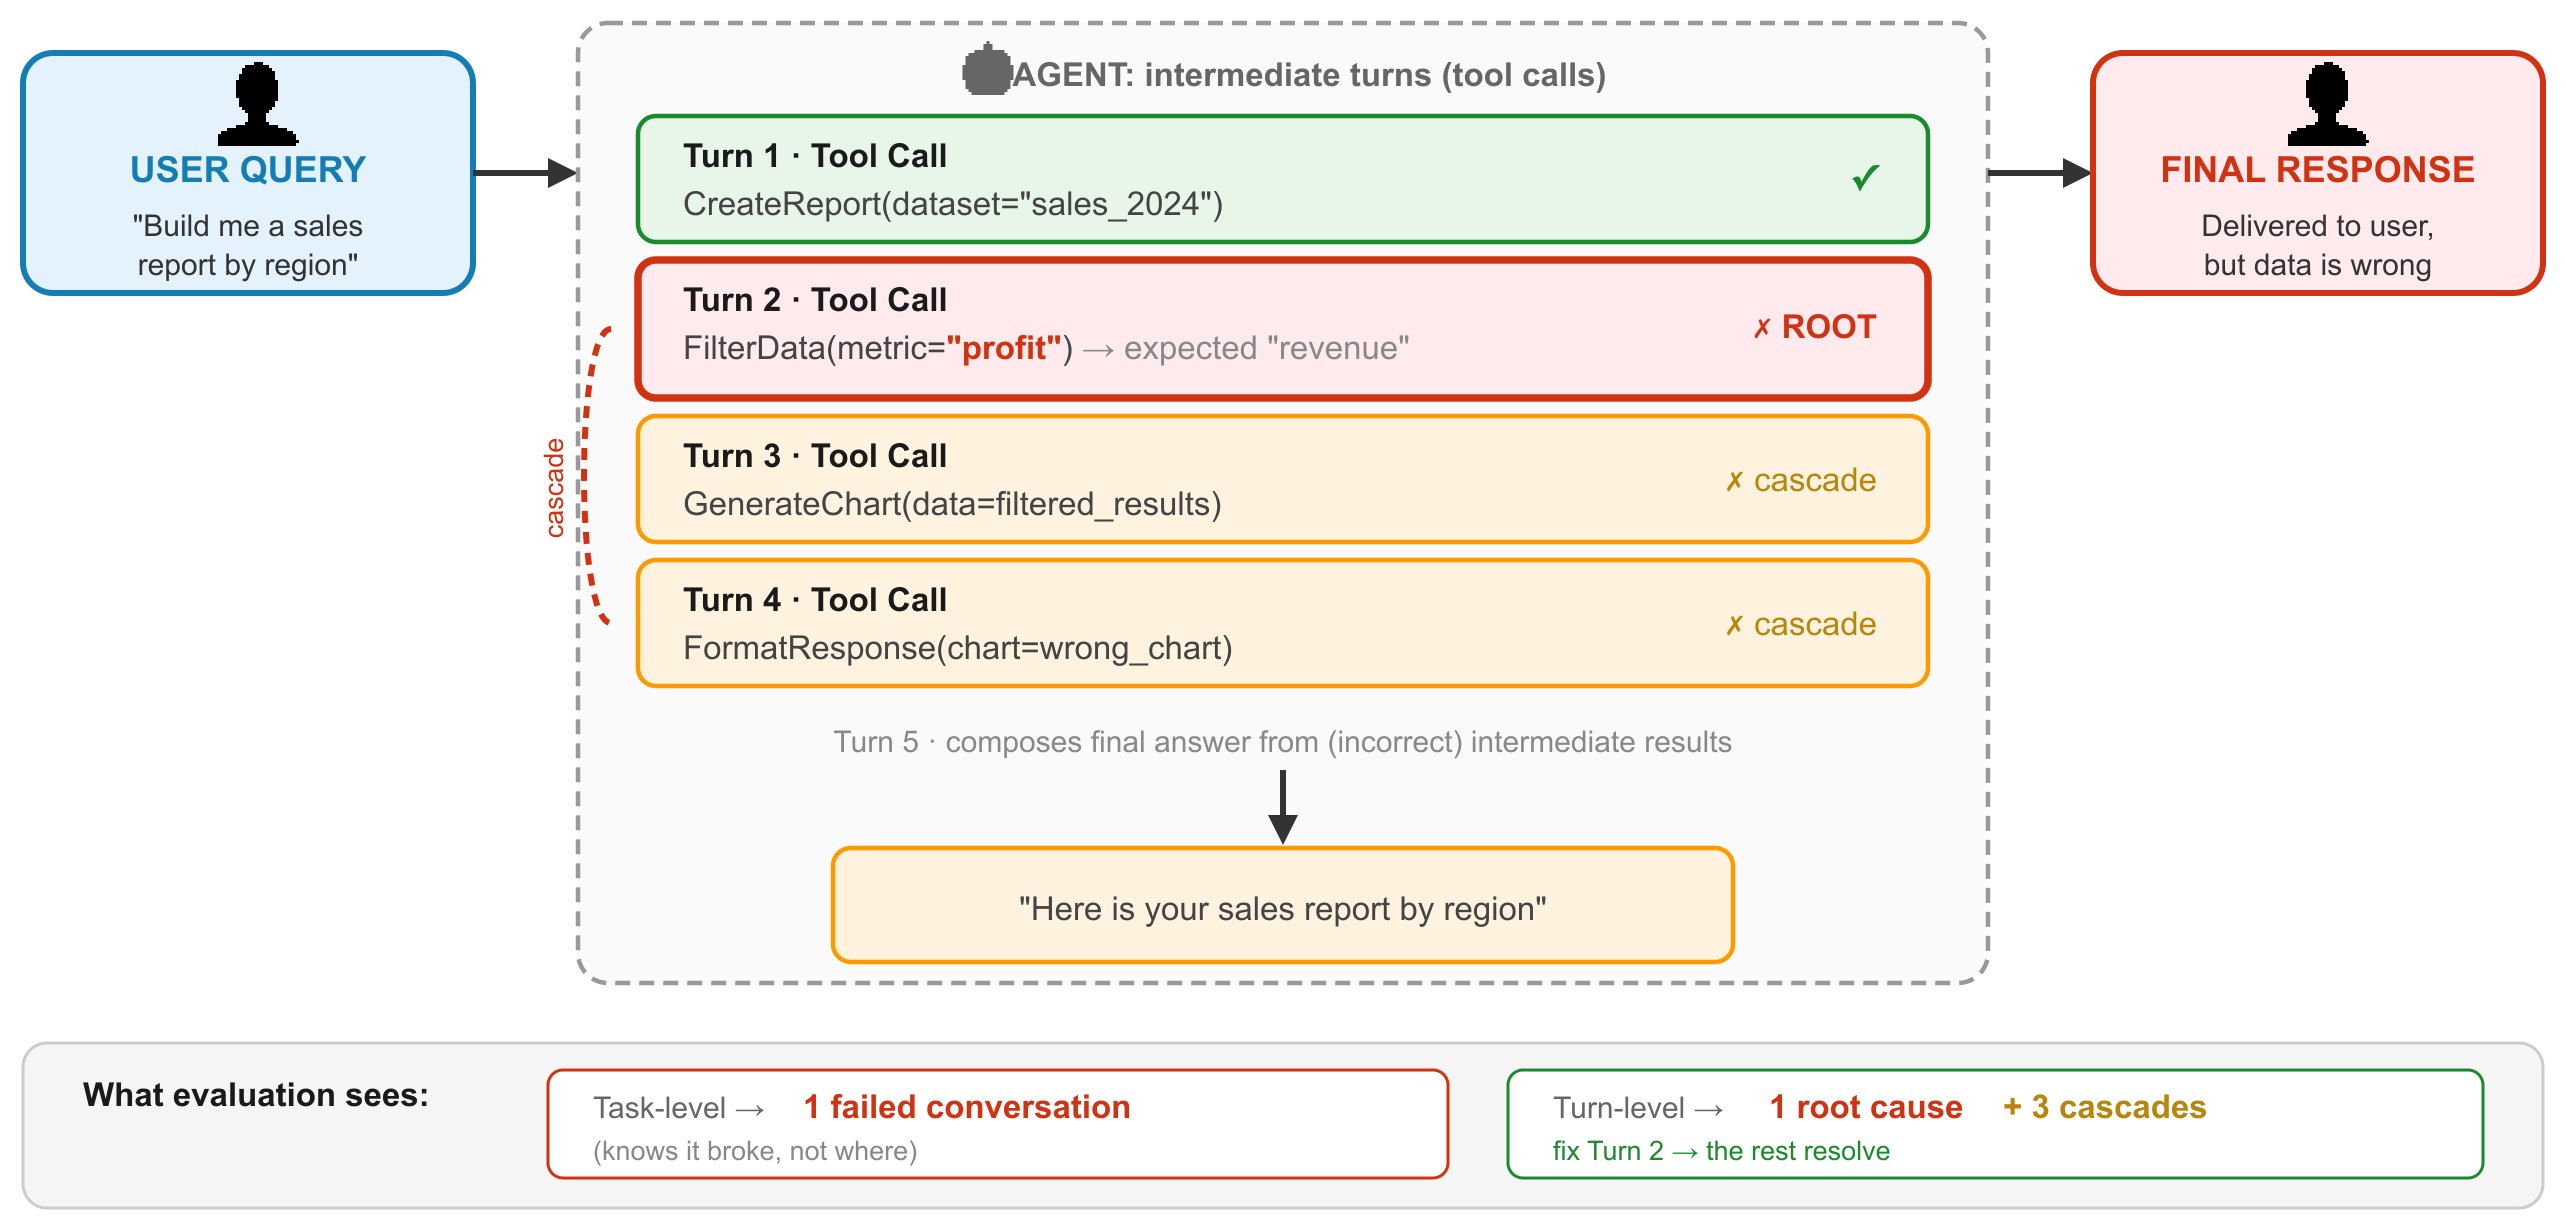
图 1:一个早期错误会级联到后续回合,逐回合评估则可隔离根因
任务级评估只检查最终结果。它会将整段交互标记为失败,却不会揭示其实只有一个回合需要修复。这正是核心问题:在多轮 Agent 对话中,错误会级联,而基于结果的评估无法区分根因与其下游影响。
现有指标的局限性
大多数 Agent 评估工具从整体层面、任务层面或回复层面对质量打分。当前一代工具提供目标完成度评分和大语言模型(LLM)充当评审的质量评估。一些工具还增加了轨迹级根因分析。这些能力都很有价值,但它们共享同一种框架:Agent 质量被视为一个单一信号,而不是被拆分为可以独立追踪的组成部分。
它们所没有提供的,是一种可将质量分解为具名、可单独衡量、并能逐回合追踪的子指标的方法。知道某个 Agent“目标完成度得分为 70%”,并不能说明失败究竟来自事实错误、信息缺失,还是错误的工具选择。单一分数也难以随着需求增长而平滑扩展到新维度。由此产生三个缺口:
- 任务级指标(目标成功率)告诉你 Agent 是否完成任务,但不会告诉你是哪一个质量维度失效。
- 单轮指标(有用性、忠实性)孤立地评估回复,不考虑错误如何跨回合传播。
- 整体评分无法区分事实错误与必填字段缺失;若要增加新的维度(安全性、指令保持),也没有无需重构评估架构的清晰路径。
一种可分解、逐回合的评估模式能够弥合这些缺口。它将质量拆分为具名子指标,在完整轨迹中评估每个回合,并将它们组合为一个单一指标。同一方法还能在不改变机制的前提下扩展到新的维度。
作为复合指标的正确性
我们将 Agent 质量定义为一个由 AEM 计算的单一复合指标,它由具名且可独立衡量的子指标构成。在这篇首篇文章中,AEM 通过两个子指标衡量正确性:
- 真实性:Agent 生成的值在事实层面是否与预期结果一致?这既适用于工具调用中的参数值,也适用于自然语言回复中的陈述。
- 完整性:所有必需元素是否都已存在?即没有遗漏参数,也没有遗漏所请求信息的不完整回复。
下图展示了这种分解。它说明顶层分数如何拆分为可独立衡量、再重新组合的具名子指标,以及同一模式如何扩展到未来维度。
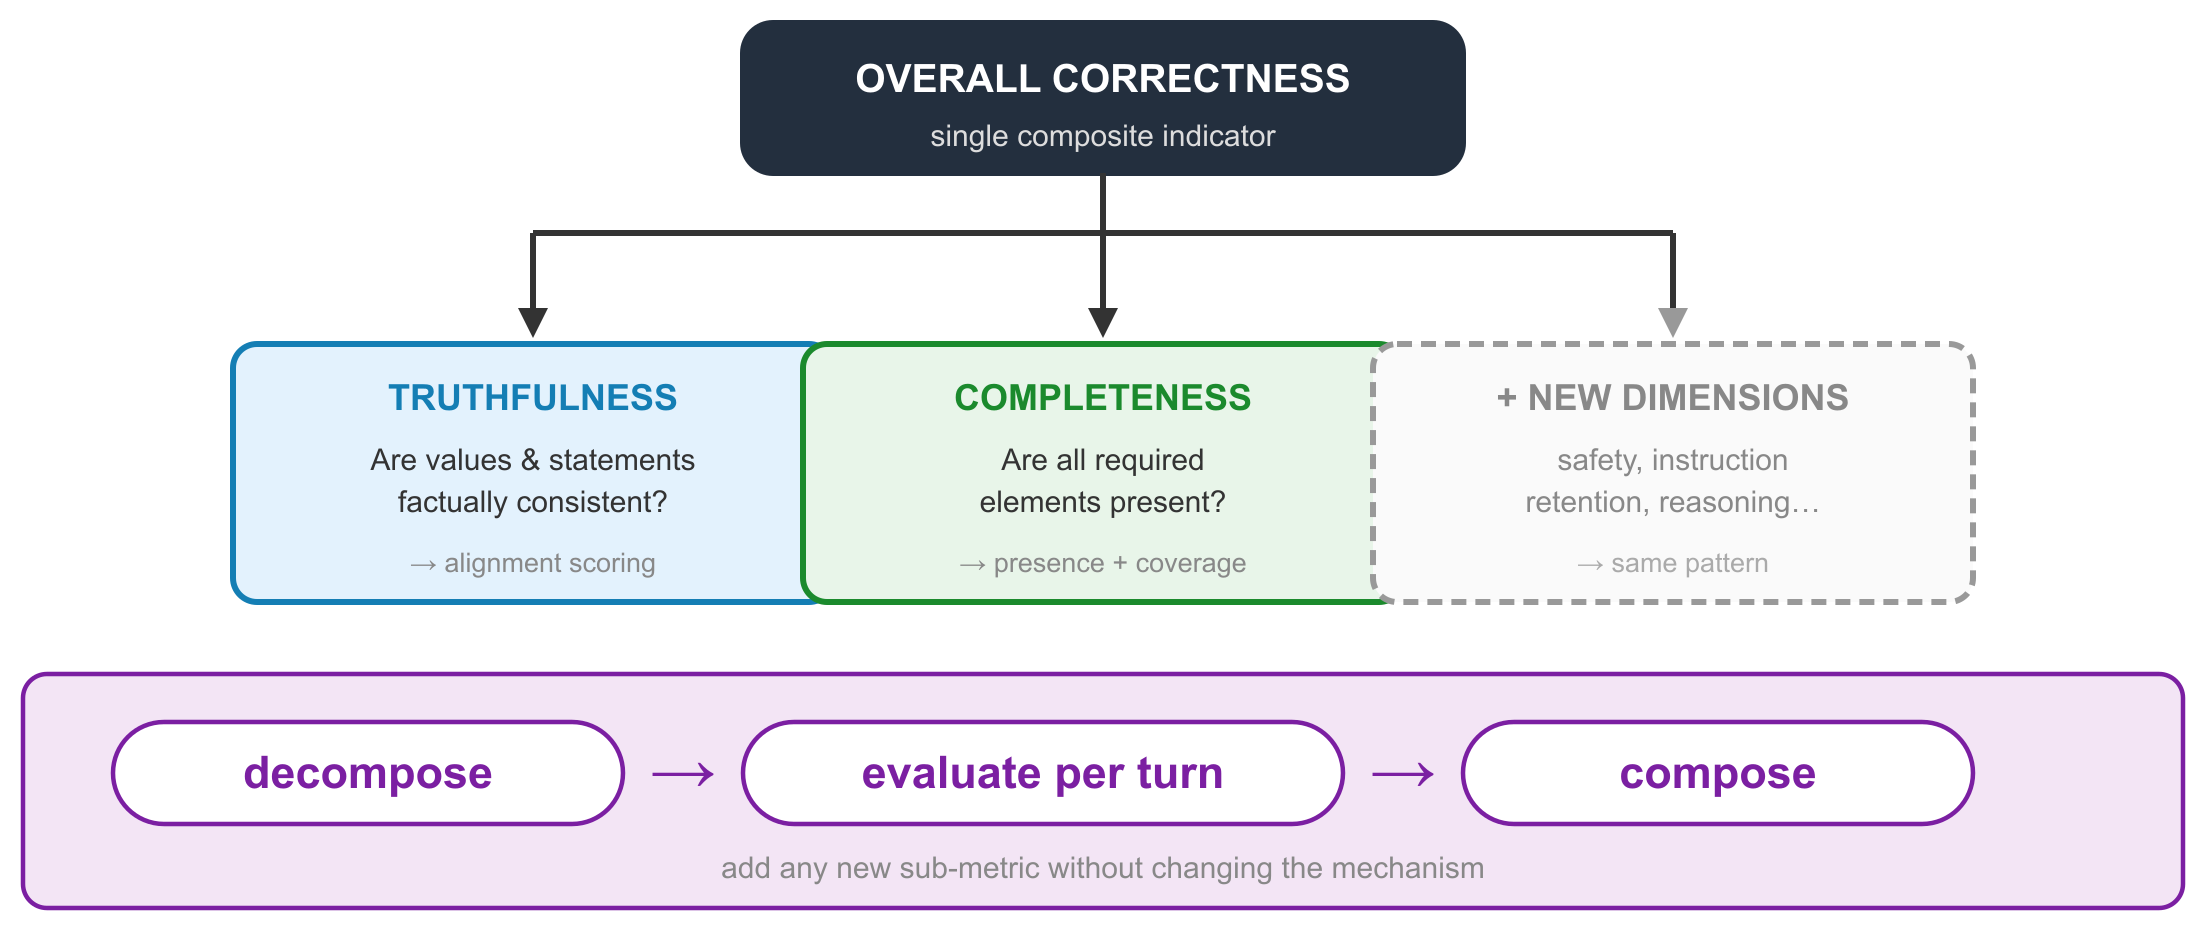
图 2:正确性可分解为具名子指标,并可扩展至新的维度
最主要的贡献在于这种分解本身。AEM 并非一个不透明的单一分数,而是由多个子指标构成的复合体;每个子指标都可按回合衡量,并可跨轨迹组合。工具与动作选择构成其下层的结构基础。同样的“分解—评估—组合”模式可扩展至安全性、指令保持和推理深度等新维度。正确性是我们首先实现的维度。
Agent Evaluation Metric 框架
AEM 将分解理念转化为具体的逐回合指标。本节定义逐回合层级、两个子指标及其组合方式,以及使评分可执行的失败分类法。
逐回合层级
正确性按回合计算。一个回合要么是回复回合,即 Agent 回答用户;要么是动作回合,即 Agent 调用工具。我们先从回复回合开始,因为这是用户最终看到的内容;同一指标也适用于动作回合。两者都属于同一层级。
下图展示了这一共享层级。图中一侧是对工具调用的评估——参数键和值;另一侧是对自然语言回复的评估——覆盖度和事实依据,二者均使用相同的两个子指标。

图 3:相同的两个子指标可评估工具调用和自然语言回复
对于回复回合,两个子指标应用于自由文本。完整性关注回复是否覆盖完整问题,真实性关注回复在事实层面是否一致。同样的复合指标也适用于动作回合。在动作回合中,完整性检查参数键,确认所有必需参数均已存在;真实性检查参数值,确认其在语义上正确。二者都建立在一项结构性检查之上:是否选择了正确的工具和动作。
在本文中,一个回合的正确性被视为二元结果:通过或失败,并附有说明子指标及字段的具体失败原因。同一分解也支持更细粒度的评分,例如在连续量表上为单个主张或字段打分。
在整个对话中组合后,AEM 分数是通过回合所占的比例。由于它按子指标进行了分解,分数下降时可以显示是哪个维度——真实性还是完整性——导致了变化,而不仅是显示正确性下降。
AEM 的分解与形式化
两个子指标都依赖语义比较,而非精确匹配。对于回复和参数值,精确字符串匹配过于脆弱。“New York City”与“NYC”在语义上等价,“Q3 2024 revenue”与“third quarter revenue figures for 2024”传递的是相同信息。
语义相似度评分决定两个值在语义上是否等价。从概念上说,检查方式如下:
def evaluate_truthfulness(gold_value, predicted_value, scorer, threshold=0.5):
    """Score semantic equivalence of a predicted value against gold."""
    if gold_value == predicted_value:
        return True, 1.0  # Exact match (fast path)

    score = scorer.score(gold_value, predicted_value)
    return score >= threshold, score
评分器可以是基于嵌入的相似度检查(快速、低成本),也可以是一次 LLM-as-judge 调用(更细致)。嵌入检查是透明的“编码器加相似度函数”机制;评审模型则是更不透明的、基于解码器的模型,其评分过程无法被直接检查。阈值控制严格程度:更高的阈值能够捕获真实错误,但也可能将语义等价的表达误判为错误;更低的阈值则更加宽松。这里的 0.5 是一个用于起步的中性默认值,并非经调优的值。正确取值取决于你的领域对假阳性与假阴性的容忍度(参见“经验教训”)。
相似度分数是连续值。对于本文而言,阈值会将其压缩为二元的回合判定;更细粒度的设置则可以保留逐主张分数。
完整性在回复回合中通过语义方式检查(回复是否回答了完整问题),在动作回合中通过结构方式检查(所有必需参数键是否存在):
def evaluate_completeness(gold_args, predicted_args):
    """Check all required parameters are present, with no unexpected extras."""
    missing = set(gold_args.keys()) - set(predicted_args.keys())
    extra = set(predicted_args.keys()) - set(gold_args.keys())
    return len(missing) == 0 and len(extra) == 0, missing, extra
返回的 missing 与 extra 集合会直接输入失败分类法。非空的 missing 集合会产生 missing_parameters 失败,非空的 extra 集合会产生 extra_parameters 失败,从而准确指出哪些参数出错。
组合分数。 分解会生成逐子指标、逐回合的判定结果;组合则将它们转化为一个数字。与框架的可组合原则一致,组合规则本身也是一种选择。本文的默认规则是对通过回合计算未加权平均值。
其他规则同样有效。加权平均可为错误成本更高的回合赋予更大权重。门控规则允许单次关键回合失败封顶整体分数。逐子指标阈值则为每个维度设置单独门槛。该框架将此组合函数视为可插拔组件。
失败分类法与动作链
当一个回合失败时,具体的失败原因会准确记录发生了什么。该分类法覆盖两种回合类型:回复回合失败与动作回合失败处于相同层级;结构性检查(工具和动作选择)仅适用于调用工具的回合。
| 失败原因 | 适用对象 | 子指标 | 含义 |
|---|---|---|---|
inconsistent_response |
回复回合 | 真实性 | 回复与参考答案在事实层面不一致 |
incomplete_response |
回复回合 | 完整性 | 回复遗漏部分请求的信息 |
tool_mismatch |
动作回合 | 结构性 | 选择了错误的工具 |
action_mismatch |
动作回合 | 结构性 | 工具正确,但操作错误 |
missing_parameters |
动作回合 | 完整性 | 未提供必需参数 |
extra_parameters |
动作回合 | 完整性 | 添加了意外参数 |
inconsistent_parameter_values |
动作回合 | 真实性 | 参数值存在,但语义错误 |
prior_action_failed |
任一回合 | 级联 | 并非根因。此前的回合导致了这一失败 |
真实性和完整性这两个子指标,是两类回合之间保持不变的部分。只有结构性检查是工具特有的。prior_action_failed 标签使该指标能够在多轮场景中切实发挥作用。它将根因与级联影响区分开来,并且既可以附加到回复回合,也可以附加到动作回合。评估器根据依赖关系分配该标签:当一个回合的失败源于该回合自身时,它是根因;当一个回合仅仅因为消费了此前已失败回合的输出而失败时,它会获得 prior_action_failed 标签。在开篇示例中,只有第 2 回合是根因,第 3—5 回合继承这一标签。该指标还会跟踪动作链长度(单次调用、两步调用和复杂的三步及以上序列),因为较长的链路集中了大部分性能退化。
面向 Agent 工作流的评估流水线
前文描述的指标运行在一条可重复执行的流水线中。带标注的对话被输入,输出为一个按回合归因、经过分解的单一 AEM 分数,并在 Agent 生命周期的各个阶段使用。
下图展示了这一端到端流程:从带标注的对话开始,经过逐回合评分和归因,形成一个可在开发和生产环境中使用的单一分数。
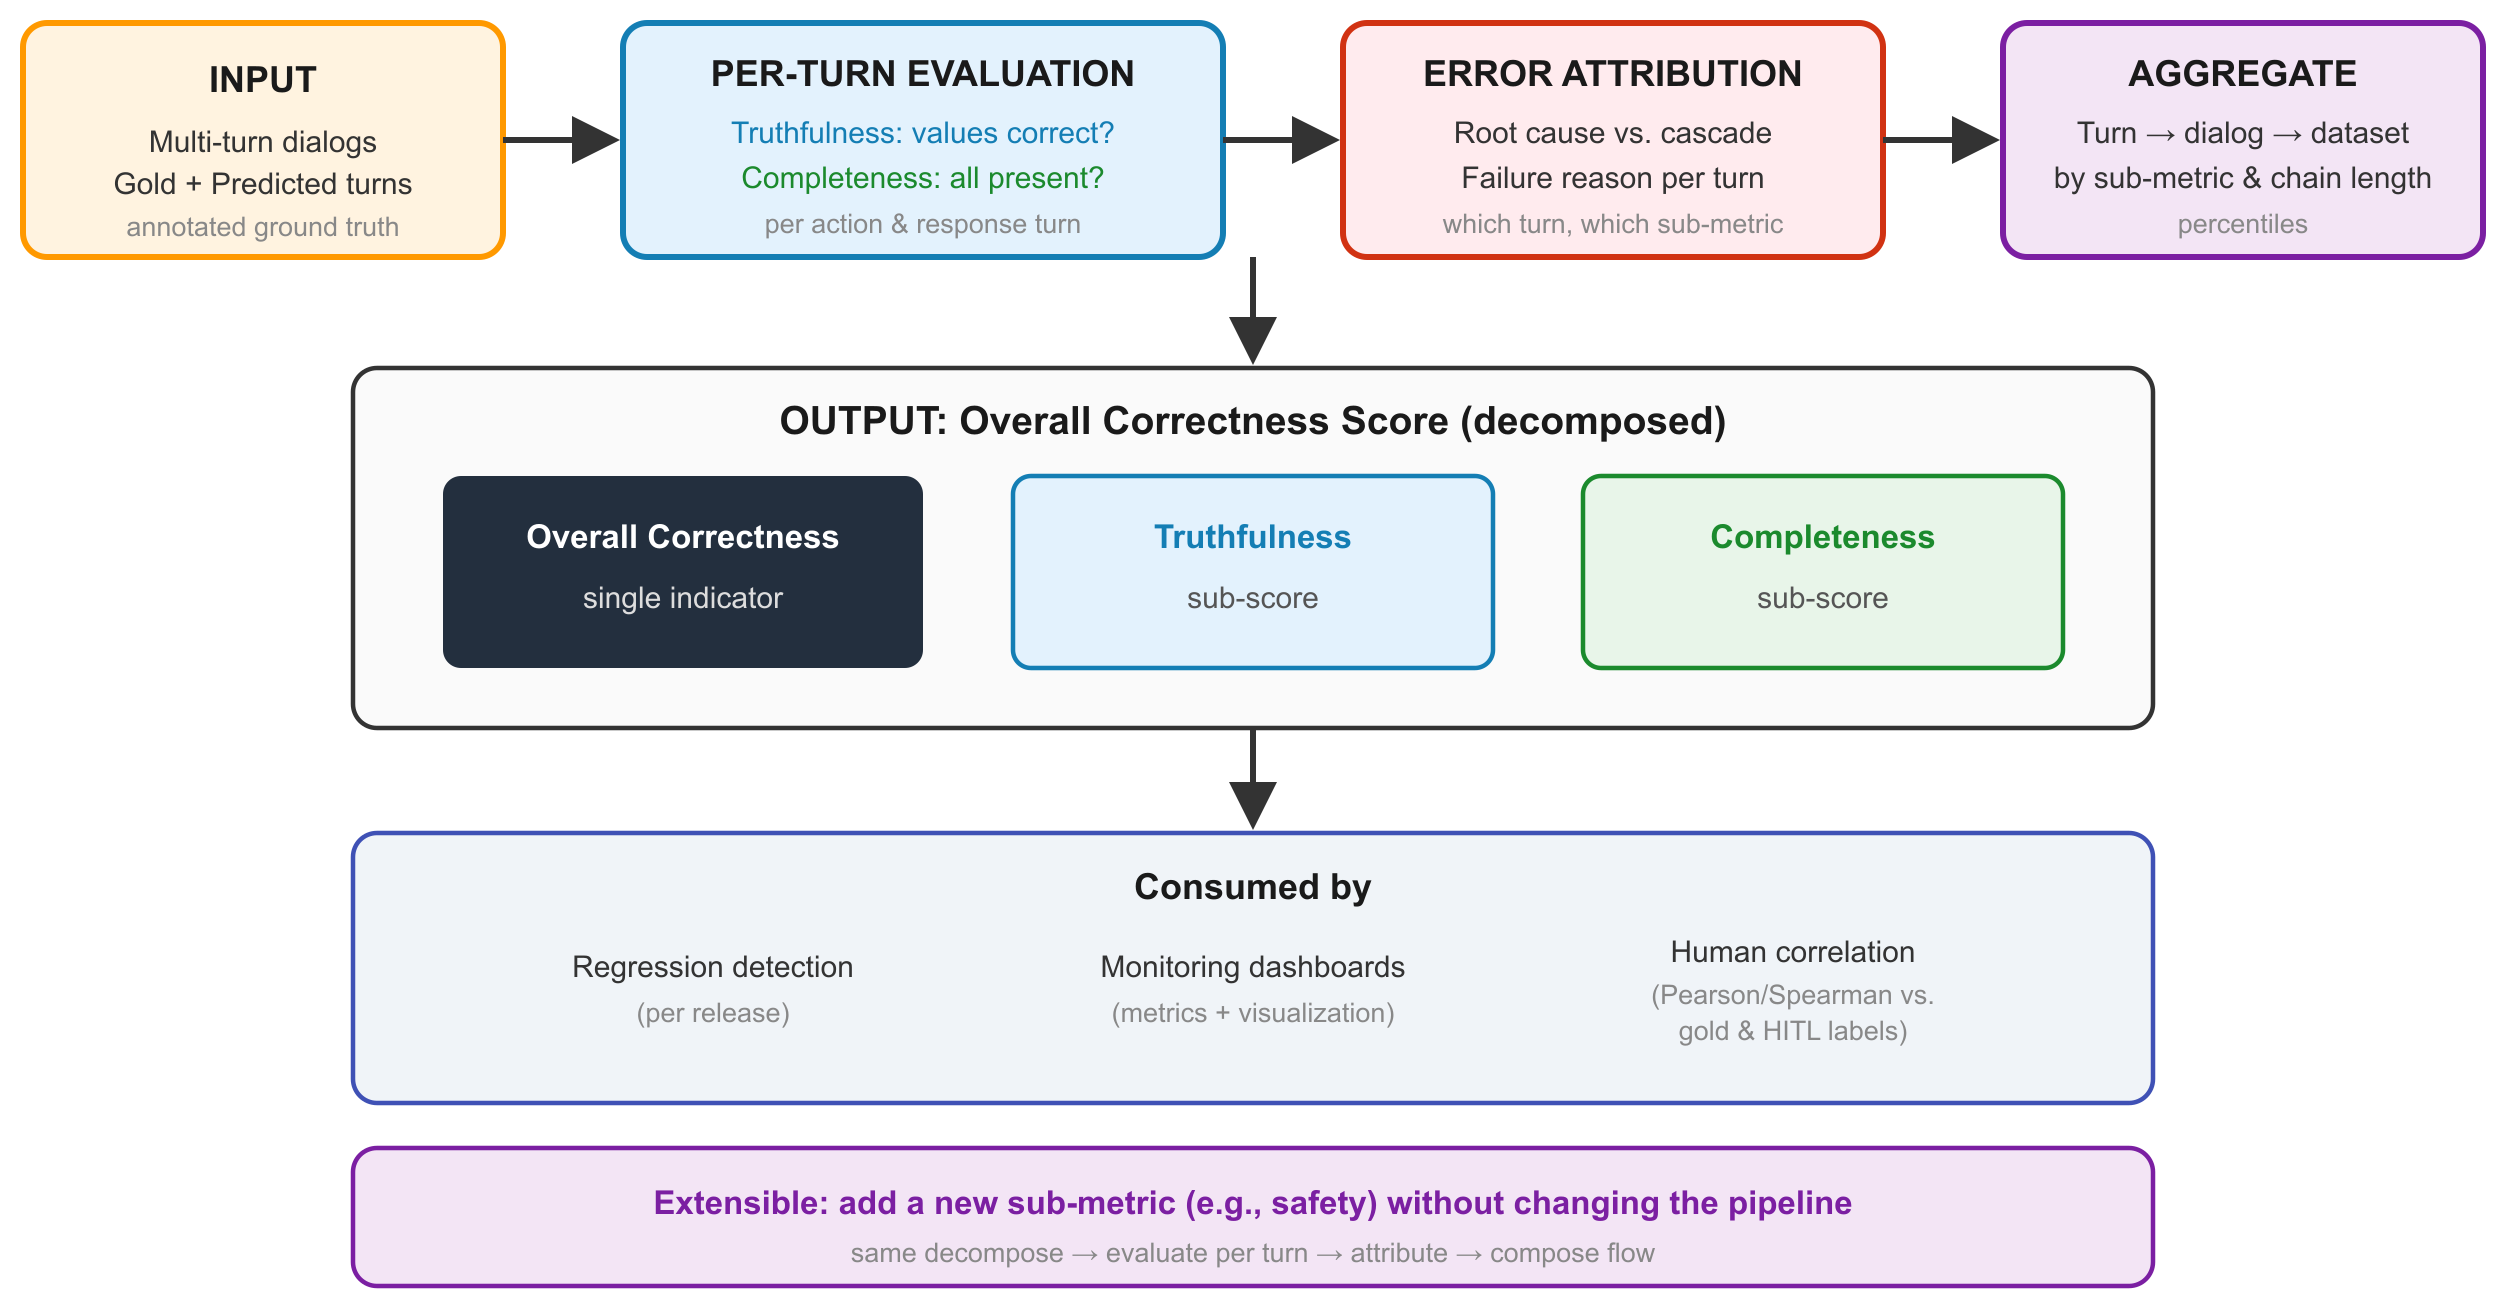
图 4:从带标注的对话到经过分解、逐回合计算的正确性分数
对于五回合销售报告示例,该流水线会返回一个紧凑的分解结果(示例):
{"success_rate": 0.2, "test_pass": false,
 "first_failure_turn": 2, "root_cause": "inconsistent_parameter_values",
 "root_cause_count": 1, "cascading_count": 3}
黄金数据集设计
评估始于真实标注:对话中正确的回复和正确的工具调用都需要被标注。这类黄金参考通常由人工标注(或在经人工审核的情况下通过自举方式生成
English / 原文
Multi-turn agents fail in ways that single-turn evaluation misses: one early mistake quietly corrupts every later turn. This post introduces the Agent Evaluation Metric (AEM), a decomposable, turn-level way to measure agent quality. We apply it to its first dimension, correctness. We show how AEM pinpoints the one turn that caused a failure and separates it from the turns that merely inherited the problem.
The correctness challenge in multi-turn agentic conversations
Evaluating agent correctness in a multi-turn conversation is hard because the property itself is fragile, and holistic scores hide where it breaks. This section shows why cascading errors defeat outcome-level evaluation and motivates a decomposable, turn-level metric.
Why correctness matters
A single wrong tool call cascades into downstream failures across turns. Consider a five-turn conversation with an enterprise assistant. The user asks to create a sales report, then refine it. In turn 2, the agent selects the right action but passes “profit” instead of “revenue.” That single error then silently propagates through every subsequent turn.
The following diagram traces that failure. It shows one early error in turn 2 cascading through turns 3–5, and how turn-level evaluation isolates the single root cause from its downstream effects.
Figure 1: One early error cascades through later turns, and turn-level evaluation isolates the root cause
A task-level evaluation checks only the final outcome. It marks the entire interaction as failed without revealing that only one turn needs fixing. This is the core problem: in multi-turn agentic conversations, errors cascade, and outcome-level evaluation can’t tell root causes from their downstream effects.
Limitations of existing metrics
Most agent evaluation tools score quality holistically, at the task or response level. The current generation provides goal-completion scoring and large language model (LLM)-as-judge quality assessment. Some also add trace-level root cause analysis. These are valuable, but they share a common framing: agent quality is treated as a single signal, not broken down into parts that can be tracked independently.
What they don’t provide is a way to decompose quality into named, separately measurable sub-metrics tracked turn by turn. Knowing an agent “scored 70 percent on goal completion” doesn’t tell you whether the failures were factual errors, missing information, or wrong tool choices. A single score also can’t extend cleanly to new dimensions as requirements grow. Three gaps follow:
- Task-level metrics (goal success rate) tell you whether the agent completed the task but not which quality dimension broke down.
- Single-turn metrics (helpfulness, faithfulness) evaluate responses in isolation without considering how errors propagate across turns.
- Holistic scores cannot distinguish a factual error from a missing required field, and they offer no clear path to add new dimensions (safety, instruction retention) without re-architecting the evaluation.
A decomposable, turn-level evaluation pattern closes these gaps. It breaks quality into named sub-metrics, evaluates each turn within the full trajectory, and composes them into a single indicator. The same approach extends to new dimensions without changing the mechanism.
Correctness as a composite metric
We define agent quality as a single composite indicator built from named, separately measurable sub-metrics, computed by AEM. In this first post, AEM measures correctness through two sub-metrics:
- Truthfulness : Are the values produced by the agent factually consistent with what was expected? This applies to both parameter values in tool calls and statements in natural language responses.
- Completeness : Are all required elements present? No missing parameters, and no partial responses that omit requested information.
The following diagram shows this decomposition. It illustrates how a top-level score breaks into named sub-metrics that are measured independently and then recombined, and how the same pattern extends to future dimensions.
Figure 2: Correctness decomposes into named sub-metrics, extensible to new dimensions
The headline contribution is the decomposition itself. AEM isn’t a single opaque score but a composite of sub-metrics, each measurable per turn and composable across the trajectory. Tool and action selection form the structural foundation beneath them. The same decompose-evaluate-compose pattern extends to new dimensions such as safety, instruction retention, and reasoning depth. Correctness is the first dimension we instantiate.
The Agent Evaluation Metric framework
AEM turns the decomposition idea into a concrete, per-turn metric. This section defines the turn-level hierarchy, the two sub-metrics and how they compose, and the failure taxonomy that makes a score actionable.
The turn-level hierarchy
Correctness is computed per turn. A turn is either a response turn , where the agent replies to the user, or an action turn , where the agent invokes a tool. We lead with the response turn, since that is what the user ultimately sees, and the same metric applies to action turns too. Both fall under one hierarchy.
The following diagram shows that shared hierarchy. It shows the same two sub-metrics evaluating a tool call (parameter keys and values) on one side and a natural-language response (coverage and grounding) on the other.
Figure 3: The same two sub-metrics evaluate a tool call and a natural-language response
For a response turn, the two sub-metrics apply to free text. Completeness asks whether the reply covers the full query, and truthfulness asks whether it’s factually consistent. The same composite applies to an action turn. There, completeness checks the parameter keys , confirming that all required parameters are present. Truthfulness checks the parameter values , confirming they are semantically correct. Both sit on top of a structural check that the right tool and action were selected.
For this post, a turn’s correctness is treated as binary: pass or fail, with a specific failure reason naming the sub-metric and the field. The same decomposition also supports finer-grained grading, scoring individual claims or fields on a continuous scale.
Composed across a dialog, the AEM score is the proportion of turns that pass. Because it’s decomposed by sub-metric, a decline shows which dimension , truthfulness or completeness, drove the change, not just that correctness dropped.
Decomposing and formalizing AEM
Both sub-metrics rely on semantic comparison rather than exact matching. For responses and parameter values, exact string matching is too brittle. “New York City” and “NYC” are semantically equivalent, and “Q3 2024 revenue” and “third quarter revenue figures for 2024” convey the same information.
Semantic similarity scoring determines whether two values are semantically equivalent. Conceptually, the check looks like this:
def evaluate_truthfulness(gold_value, predicted_value, scorer, threshold=0.5):
    """Score semantic equivalence of a predicted value against gold."""
    if gold_value == predicted_value:
        return True, 1.0  # Exact match (fast path)

    score = scorer.score(gold_value, predicted_value)
    return score >= threshold, score
The scorer can be an embedding-based similarity check (fast, cheap) or an LLM-as-judge call (more nuanced). The embedding check is a transparent encoder-plus-similarity-function, and the judge is a more opaque decoder-based model whose scoring isn’t directly inspectable. The threshold controls strictness: a higher threshold catches real errors but risks flagging semantic equivalents, while a lower one is more permissive. The 0.5 here is a neutral default to start from, not a tuned value. The right value depends on your domain’s tolerance for false positives versus false negatives (see Lessons learned).
The similarity score is continuous. The threshold is what collapses it to a binary turn verdict for this post, and a finer-grained setup can retain the per-claim scores instead.
Completeness is checked semantically for response turns (does the response address the full question?) and structurally for action turns (are all required parameter keys present?):
def evaluate_completeness(gold_args, predicted_args):
    """Check all required parameters are present, with no unexpected extras."""
    missing = set(gold_args.keys()) - set(predicted_args.keys())
    extra = set(predicted_args.keys()) - set(gold_args.keys())
    return len(missing) == 0 and len(extra) == 0, missing, extra
The returned missing and extra sets feed directly into the failure taxonomy. A non-empty missing set produces a missing_parameters failure, and a non-empty extra set produces an extra_parameters failure, pinpointing exactly which parameters were wrong.
Composing the score. Decomposition produces per-sub-metric, per-turn verdicts. Composition turns them into one number. The composition rule is itself a choice, in keeping with the framework’s composable principle. The default in this post is an unweighted mean of passing turns.
Other rules are equally valid. Weighted means give more weight to turns that carry higher cost when wrong. Gating rules let a single critical-turn failure cap the score. Per-sub-metric thresholds set a separate bar for each dimension. The framework treats this composition function as pluggable.
Failure taxonomy and action chains
When a turn fails, a specific failure reason captures exactly what went wrong. The taxonomy spans both turn types: response-turn failures sit at the same level as action-turn failures, and the structural checks (tool and action selection) apply only where a turn invokes a tool.
| Failure reason | Applies to | Sub-metric | What it means |
|---|---|---|---|
inconsistent_response |
Response turn | Truthfulness | Response not factually consistent with reference |
incomplete_response |
Response turn | Completeness | Response omits part of the requested information |
tool_mismatch |
Action turn | Structural | Wrong tool selected |
action_mismatch |
Action turn | Structural | Right tool, wrong operation |
missing_parameters |
Action turn | Completeness | Required parameter not provided |
extra_parameters |
Action turn | Completeness | Unexpected parameter added |
inconsistent_parameter_values |
Action turn | Truthfulness | Value present but semantically wrong |
prior_action_failed |
Either turn | Cascade | Not a root cause. A prior turn caused this |
The two sub-metrics, truthfulness and completeness, are the constant across both turn types. Only the structural checks are tool-specific. The prior_action_failed label is what makes the metric actionable in a multi-turn setting. It separates root causes from cascading effects, and it can attach to a response turn as readily as to an action turn. The evaluator assigns the label by dependency. A turn is a root cause when its failure originates in that turn. It gets prior_action_failed when it fails only because it consumed an already-failed turn’s output. In the opening example, only turn 2 is a root cause, and turns 3–5 inherit the label. The metric also tracks action chain length (single call, two-step, and complex three-step-plus sequences), since longer chains concentrate most degradation.
Evaluation pipeline for agentic workflows
The metric described earlier runs inside a repeatable pipeline. Annotated dialogs go in, and a single decomposed AEM score comes out, attributed per turn and consumed across the agent lifecycle.
The following diagram shows that end-to-end flow, from annotated dialogs through per-turn scoring and attribution to a single score consumed in development and production.
Figure 4: From annotated dialogs to a decomposed, per-turn correctness score
For the five-turn sales-report example, the pipeline returns a compact, decomposed result (illustrative):
{"success_rate": 0.2, "test_pass": false,
 "first_failure_turn": 2, "root_cause": "inconsistent_parameter_values",
 "root_cause_count": 1, "cascading_count": 3}
Golden dataset design
Evaluation begins with ground truth: conversations where both the correct responses and the correct tool calls are annotated. This gold reference is typically human-annotated (or human-reviewed when bootstrapped from a stronger model), since it defines what correct means for each turn. Each dialog is a sequence of turns, and each turn pairs the gold (expected) output with the predicted (actual) output. A turn carries a turn role identifying who produced it. A response turn and an action turn look like this:
[
  {
    "turn_no": 1,
    "turn": "Agent",
    "gold_turn":    {"response": "Which region should the report cover?"},
    "predict_turn": {"response": "Sure, which region would you like the report for?"}
  },
  {
    "turn_no": 2,
    "turn": "Tool",
    "gold_turn":    {"tool_id": "reports", "action": "FilterData",
                     "args": {"metric": "revenue", "region": "EU"}},
    "predict_turn": {"tool_id": "reports", "action": "FilterData",
                     "args": {"metric": "profit",  "region": "EU"}},
    "tags": ["OrderInvariant_filter"]
  }
]
Comparing gold and predicted yields the per-turn correctness verdict. The response turn passes: the wording differs from gold but is semantically equivalent, which is exactly what semantic similarity scoring is for. The action turn fails: a truthfulness error surfaces on the metric value (profit where revenue was expected). The tags field supports order-invariant evaluation. When multiple tool calls are valid in any order, such as checking a calendar and searching flights, the evaluator checks against valid orderings. It does not penalize correct but differently sequenced behavior.
Error attribution
After every turn is evaluated, error attribution separates root causes from cascading effects. It operates on turn verdicts regardless of whether a turn was a response or an action:
def attribute_errors(turn_results):
    """Separate root cause failures from cascading failures."""
    root_causes = []
    cascading = []

    for result in turn_results:
        if not result.success:
            if result.failure_reason == "prior_action_failed":
                cascading.append(result)
            else:
                root_causes.append(result)

    return {
        "first_failure_turn": root_causes[0].turn_no if root_causes else None,
        "root_cause": root_causes[0].failure_reason if root_causes else None,
        "total_failures": len(root_causes) + len(cascading),
        "root_cause_count": len(root_causes),
        "cascading_count": len(cascading),
    }

# Example output:
# first_failure_turn: 2, root_cause: "inconsistent_parameter_values"
# root_cause_count: 1, cascading_count: 3
# Fix the parameter in turn 2; turns 3-5 likely resolve automatically.
This changes how teams prioritize fixes. Instead of investigating every failure independently, they focus on root causes, since cascading failures often resolve after the root is fixed. A single root cause in a multi-step chain can otherwise appear as several distinct failures.
Production monitoring
In production, the overall correctness score is tracked continuously:
- Overall correctness by release (regression detection): Did the latest model update degrade turn-level success rate?
- Correctness by chain length : Do complex multi-step chains degrade over time?
- Failure reason distribution (root cause trends): Is
tool_mismatchincreasing after a model swap? - Latency correlation : Do conversations with higher accumulated latency show lower correctness?
The framework outputs structured JSON that feeds into monitoring dashboards. Some errors are costly, such as a financial calculation or a compliance-related response. For those, the decomposed sub-metric scores can also be correlated against human or gold labels. A per-sub-metric correlation (for example, Pearson or Spearman) shows whether the automated score tracks human judgment and where to bring a reviewer into the loop.
Integrating with the Strands Agents evaluation SDK
The methodology is framework-agnostic, but many teams run evaluations through an existing harness. The turn-level correctness signal integrates with the Strands Agents evaluation SDK as a custom evaluator. From there it plugs into the same pipeline teams already use for goal-completion and LLM-as-judge scoring. Those built-in evaluators report quality as a holistic, per-trajectory signal. AEM is complementary, contributing a decomposed, per-turn correctness score that attributes a failure to a specific sub-metric and turn. The wrapper reuses the per-turn checks built earlier in this post (evaluate_truthfulness, evaluate_completeness, and the attribution logic):
from strands_evals.evaluators import Evaluator
from strands_evals.types import EvaluationData, EvaluationOutput


class CorrectnessCustomEvaluator(Evaluator):
    """Wraps the turn-level correctness checks as a Strands Agents custom evaluator."""

    def __init__(self, threshold: float = 0.5, name: str = "correctness"):
        super().__init__(name=name)
        self._threshold = threshold

    def evaluate(self, evaluation_case: EvaluationData) -> list[EvaluationOutput]:
        # Run the per-turn truthfulness + completeness checks over the dialog
        turn_results = evaluate_dialog(evaluation_case, threshold=self._threshold)

        success_rate = sum(r.success for r in turn_results) / len(turn_results)
        failures = [r.failure_reason for r in turn_results if not r.success]
        return [
            EvaluationOutput(
                score=success_rate,
                test_pass=all(r.success for r in turn_results),
                reason=f"failing turns: {failures}" if failures else "all turns pass",
                label="correctness",
            )
        ]
Here evaluate_dialog applies the same per-turn truthfulness and completeness checks shown earlier and returns a result per turn. This pattern keeps the evaluation logic (the decomposition, the failure taxonomy, the turn-level composition) as portable custom code, while Strands Agents provides the runner, trace collection, and reporting. Concretely, each run yields per-turn traces (spans for tool calls and model invocations) and a structured report. You can display or export that report as JSON to your own dashboards and alerting. AEM adds the per-turn correctness score. The wrapper runs the correctness signal alongside other evaluators in a single run, including the safety evaluator we introduce in the next post.
Applying the framework to Amazon Quick Suite
Amazon Quick Suite is an enterprise assistant that runs the kind of multi-turn, multi-tool conversations this metric targets. Rather than report internal production numbers, this section walks through how a team reads AEM output, using the sales-report conversation from the opening example.
Reading an AEM score
What the user ultimately judges is the response they receive at each turn, so that response is the unit we evaluate, turn by turn across the dialog. Behind a single response, the agent often chains several tool calls under interactive latency constraints, and AEM scores the correctness that results.
Running the evaluation pipeline across a dialog produces the single AEM score for the conversation and its decomposition. The success_rate is the leading indicator, alongside the per-sub-metric breakdown and the test_pass flag, which is true only when every turn passes. That same call returns the per-turn failure reasons that drive error attribution.
A worked attribution example
Return to the five-turn sales-report conversation. Turn 2 passes profit where revenue was expected, so it fails on truthfulness with inconsistent_parameter_values. Turns 3–5 build on that result and fail too, but as cascades: each carries prior_action_failed. A raw failure count reports four broken turns. Attribution reports one root cause at turn 2 and three downstream effects, which is the number that matters.
The practical rule is to attribute first, then investigate. The following recurring patterns make this concrete, and the table summarizes where to look in each case.
| What you observe | What to inspect first | Typical root cause |
|---|---|---|
| Many failures clustered in a long chain | The first failing turn, not the count | One early inconsistent_parameter_values cascading downstream |
| Failures appear mid-conversation | The turn that breaks, via prior_action_failed labels |
An upstream missing_parameters or action_mismatch |
| The response looks wrong but every tool call succeeded | The response turn’s truthfulness and completeness | inconsistent_response or incomplete_response |
The takeaway is that longer chains push a larger share of failures back to earlier turns rather than to independent errors. Fixing a small number of root causes can resolve many of the observed failures, so attribution turns a noisy failure list into a short, ordered fix list.
Lessons learned
A few lessons emerged from applying AEM in practice. First, attribute before you investigate: the prior_action_failed label separates root causes from cascades, so one early error in a chain does not read as many independent failures.
Second, tune the similarity threshold to your domain. Set it by your tolerance for false positives versus false negatives. Too strict a threshold flags semantic equivalents such as “NYC” versus “New York City,” while too lenient a threshold misses real errors.
Third, tag order-invariant steps. When several tool calls are valid in any order, marking them lets the evaluator credit valid alternate orderings instead of failing correct behavior.
Two broader lessons concern trust and growth. For costly errors, validate against human labels by correlating the decomposed sub-metrics with human or gold judgments. Bring a reviewer into the loop where an undetected error carries real consequences. And extend with new sub-metrics rather than new pipelines: define per-turn criteria and a failure taxonomy, then compose with the same score. Planning quality, instruction retention, and safety all follow this approach.
Conclusion and next steps
This post presented the Agent Evaluation Metric (AEM) as a single composite indicator for multi-turn agentic conversations, applied to its first dimension, correctness. AEM decomposes correctness into named sub-metrics (truthfulness and completeness) and evaluates them at the turn level with precise error attribution. It goes beyond detecting failures: it identifies which dimension broke down, which turn caused it, and whether later failures are root causes or cascading effects.
The methodology fits into an evaluation workflow a team already runs. Ground truth comes first, then AEM scores each turn through truthfulness and completeness. Error attribution then separates root causes from cascading failures, so the count reflects independent problems rather than downstream noise. Tracking the score across model versions turns the metric into a regression signal, run inside an existing Strands Agents pipeline through the custom-evaluator wrapper. A decline points to the sub-metric responsible, and the failure taxonomy identifies the precise turn to investigate.
Correctness is the first dimension AEM instantiates through a deliberately extensible approach: decompose a quality concept into named sub-metrics, evaluate each turn within the full trajectory, attribute failures, and compose the results into a single indicator. The next post in this series applies the same method to safety, and later posts extend it to multilingual and multimodal evaluation.
To get started, explore the working examples in the Strands Agents samples repository and the Strands Agents evaluation documentation, then adapt the custom evaluator shown earlier to your own dialogs. To learn more about the enterprise assistant used here, see Amazon Quick Suite. Teams adopting correctness today can add safety and other dimensions as their requirements grow.
About the authors
Surafel Lakew
Surafel is an Applied Scientist at AWS AI whose research spans the safety, security, and evaluation of LLMs and agentic systems. He currently works on Amazon Quick, following earlier contributions to Amazon Translate working on customized translation and automatic dubbing. He earned his PhD in multilingual NLP, with a focus on neural translation, few shot and self-supervised learning.
Sina Torfi
Sina is an Applied Scientist at AWS whose research focuses on agentic AI evaluation, reasoning, and alignment. His work explores how to understand and improve the behavior of AI agents and build more capable, reliable, and trustworthy AI systems.
Sailik Sengupta
Sailik is a Scientist on the Agentic AI team at AWS, focusing on large-scale retrieval, LLM alignment, and decoding. He earned his PhD from Arizona State University as an IBM PhD Fellow, with research spanning game theory, automated planning, and cybersecurity, published at venues including ACL, ICLR, NeurIPS, and AAAI. When he’s not shipping models, you’ll find him on a trail or buried in a book.