利用 AWS DevOps Agent 和 AgentCore Evaluations 监控生产环境 Agent 生命周期
英文标题:Monitoring production agent lifecycle with AWS DevOps Agent and AgentCore Evaluations
生产环境中的多 Agent 系统会出现传统基础设施监控难以发现的静默故障,例如 IAM 权限缺失、错误工具选择或路由偏移。本文提出双层监控方案:Amazon Bedrock AgentCore Evaluations 持续评估 Agent 的帮助性、正确性和任务完成度,AWS DevOps Agent 则自动调查日志、指标、调用链及跨服务故障。示例系统是一个由四个专业 Agent 构成的航空预订 Swarm,可处理多城市行程、会员权益和企业差旅合规等复杂请求。该方案帮助开发团队同时判断 Agent 是否真正完成用户目标,以及底层基础设施是否健康,从而缩短定位和修复生产问题的时间。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 66.1 KB
 42.3 KB
 353.4 KB
 236.1 KB
 202.6 KB
 331.7 KB
 238.8 KB
 311.6 KB
 487.5 KB
 310.0 KB
 361.4 KB
 283.1 KB
 120.7 KB
 486.5 KB
中文
生产环境中的多 Agent 系统会以传统监控难以发现的方式出现问题。例如,Agent 无法调用其基础模型(FM),并返回空响应。这可能是由于 Agent 执行角色缺少 AWS Identity and Access Management(IAM)权限,而该问题不会抛出 500 错误。又如,提示词范围定义不佳的监督 Agent 不会提高错误率,却可能开始将 20% 的请求路由到非预期的专业 Agent,同时基础设施指标仍然保持正常。
基础设施监控和 Agent 效能监控需要采用不同的方法。Amazon CloudWatch 指标能够显示系统是否正确执行,但无法说明 Agent 是否帮助用户完成了目标。一个 Agent 可能成功调用 Amazon Bedrock、毫无错误地调用所有工具并返回响应,但仍然完全误解用户需求。基础设施问题往往表现为 Agent 行为退化,而不是明确的错误。当权限被撤销或服务发生限流时,Agent 可能遭遇静默问题。例如,预订 Agent 不再完成预订,但日志显示工具执行成功,因为问题发生在调用链深处的第三次调用中,且没有暴露异常。
在多 Agent 系统中,这些问题会进一步叠加:单个用户请求会触发一个监督 Agent,将任务路由给多个专业 Agent,每个 Agent 都拥有各自的工具和模型调用。通常不存在可供埋点的固定执行图,故障可能发生在多个交接点,且其在系统中的传播并不总是可预测。
我们构建了一个生产级航空预订系统,其中包含四个专业 Agent,并结合使用 Amazon Bedrock AgentCore Evaluations 进行持续 Agent 质量评估,以及使用 AWS DevOps Agent 自主调查基础设施事件。Amazon Bedrock AgentCore 是一个可使用任意框架或模型来大规模构建、连接和优化 Agent 的平台。AgentCore Evaluations 填补了质量监控的空白,持续为线上交互评分,以捕捉错误工具选择、任务失败以及基础设施指标完全无法发现的质量回归。AWS DevOps Agent 则解决第二类问题:它无需人工调查,即可跨服务边界自主追踪故障,关联 IAM 策略、调用日志和编排追踪。这两个层面能够分别说明 Agent 是否正确工作,以及基础设施是否为其提供支持。
关键技术
该系统使用多项 AWS 服务:
- Amazon Bedrock 为 Anthropic、Meta、Mistral 和 Amazon 等领先 AI 公司提供的基础模型提供 API 访问。在我们基于 AgentCore runtime 构建的航空预订系统中,Amazon Bedrock 提供语言理解能力。有关各 AWS 区域的模型可用性,请参阅 Amazon Bedrock 中的“按 AWS 区域支持的模型”。
- AgentCore runtime 负责 Agent 编排并管理交互生命周期,同时通过 OpenTelemetry 埋点提供内置可观测性。
- 借助 Fullstack AgentCore Solution Template (FAST),团队可以快速部署一个安全的 React 前端,并将其连接到 AgentCore 后端。
- AgentCore Evaluations 是集成到 AgentCore runtime 中的质量评估框架。它使用 LLM-as-a-Judge 方法持续为 Agent 交互评分,并提供有关帮助性、正确性、目标完成度及其他质量维度的指标。
- AWS DevOps Agent 是一款自主调查工具,可充当基础设施的值班工程师。发生事件时,它会自动分析 Amazon CloudWatch 日志、跨服务边界追踪故障,并提供根因分析和修复建议。
- Strands Agents 是一个用于构建 AI Agent 的开源 SDK,采用模型驱动方法,支持包括 Swarm、Graph 和 Agents-as-Tools 在内的多 Agent 协作模式。
- OpenTelemetry 是一个开源可观测性框架,提供用于采集追踪、指标和日志的标准化埋点。AgentCore runtime 使用 OpenTelemetry 将监控数据发送到 Amazon CloudWatch,从而推动系统范围内的一致可观测性。
- Swarm Pattern 是一种多 Agent 编排方法,监督 Agent 会根据当前任务动态地将工作路由给专业 Agent。与固定工作流不同,Swarm 支持会随运行时决策变化的自适应执行路径;这使其能够处理复杂任务,但也增加了监控难度。
双层监控:质量与基础设施
该监控架构回答两个问题:Agent 是否工作良好?基础设施是否健康?
Amazon Bedrock AgentCore Evaluations:持续质量监控
AgentCore Evaluations 会从帮助性、正确性和目标完成度等维度对线上 Agent 交互进行评分。系统会对可配置比例的生产请求进行抽样,并在后台执行评估。每个评分都会附带推理说明,解释该评分是如何根据对话上下文、所使用工具和任务要求得出的。
当质量指标下降时,系统会对近期低分会话执行模式分析,以识别常见故障模式。如果 Agent 对某类特定请求持续选择错误工具,或以无助于用户的格式提供正确信息,模式分析便会揭示这些问题。随后,系统会生成具体建议,包括特定的提示词修改、工具选择调整或编排逻辑改进。
AWS DevOps Agent:自主基础设施调查
AWS DevOps Agent 会跨指标、日志和错误模式监控系统健康状态。当某个环节发生故障时,该 Agent 会自行展开调查。它会提取相关 Amazon CloudWatch 日志,构建受影响资源的拓扑图,关联服务之间的错误(IAM、Amazon Bedrock 和 Agent runtime),追踪故障路径,并给出具体修复建议。除发送包含 Amazon CloudWatch 链接的告警外,它还会通过调查将空白 Agent 响应关联到缺失的 IAM 权限,或将超时激增关联到特定区域中的 Amazon Bedrock 限流。
两个层面如何协同工作
AgentCore Evaluations 以量化质量指标替代直觉,使团队能够衡量变更的实际影响。AWS DevOps Agent 则在基础设施事件发生的第一时间自主调查,自动化了过去需要人工战情室处理的大部分调查工作。二者共同构成生产级多 Agent 系统所需的持续反馈闭环:监控、分析、改进、部署。
航空预订系统:为何难以监控
为端到端演示该架构,我们构建了一个航空预订系统,用于处理复杂且动态的查询:多城市预订、常旅客计划权益应用,以及企业差旅政策合规检查,所有操作均在单轮对话内完成。该用例恰好需要使生产监控变得困难的多 Agent 协作能力:并行操作、多个数据源、顺序依赖,以及错误会带来实际后果的严格正确性要求。
请考虑如下请求:“帮我预订 3 月 15 日从西雅图到波士顿的航班,然后预订 3 月 18 日从波士顿到迈阿密的航班。第二段航程使用我的同行证书,并确保两趟航班都符合公司的差旅政策。我是 Gold 会员,请应用所有符合条件的升舱权益。”
要在单轮对话中处理该请求,需要搜索两条独立航线,并在航班搜索运行期间从另一个数据源获取会员状态和证书信息。之后必须按正确顺序完成预订,因为只有在选定航班且已知舱位等级后,才能应用同行证书。将证书用于不符合条件的航班会令用户感到沮丧;预订违反企业政策的航班则会造成资金浪费。
我们使用 Swarm pattern 构建了四个专业 Agent(图 1)。Supervisor Agent 接收请求并充当入口点,使用 think 工具规划子任务,将工作路由给其他 Agent;这些 Agent 也可以彼此交接任务。Flight Agent 搜索航线并处理多城市衔接。User Agent 获取会员状态、证书和用户档案数据。Reservation Agent 创建、修改和取消预订,并在提交变更前执行验证。
在 Swarm 中,Agent 共享工作记忆,并彼此动态交接工作。每个专业 Agent 都会根据自己发现的信息决定下一步应由谁执行,而不是遵循预先确定的执行计划。监督 Agent 仅仅是入口点。请求开始执行后,控制权会传递给最适合执行下一步的对等 Agent,而不会回到中央路由器。如果航班搜索未找到直飞航线,Flight Agent 会自行执行中转航线搜索;一旦获得可预订的选项,便会将任务交给 Reservation Agent。如果用户的证书不适用,User Agent 会进行调整并继续传递任务。这种模式无需预定义执行图便可处理不可预测的请求结构,但也意味着不存在可供埋点的固定调用图。
故障可能发生在任何交接点;由于执行路径会根据运行时决策变化,故障路径每次也会不同。从外部看,质量故障与基础设施故障可能几乎完全相同,但二者需要截然不同的响应方式。从外部看,质量故障和基础设施故障表现相同。AgentCore Evaluations 能够捕捉第一类问题:一切都正常执行,但 Agent 仍未满足用户需求。AWS DevOps Agent 则捕捉第二类问题:基础设施以静默方式发生故障,并表现为行为退化。
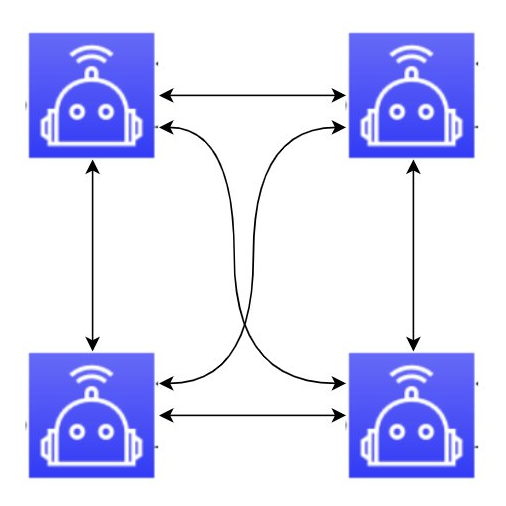
图 1:Swarm 多 Agent 模式
双重监控架构
下图展示了这些组件如何连接。

图 2:展示 React 前端、AgentCore runtime、Amazon CloudWatch 和 AWS DevOps Agent 的完整系统架构
我们构建了一个托管在 AWS Amplify 上的 React 前端。该前端通过 Amazon Bedrock AgentCore Identity(Amazon Bedrock AgentCore 的一项功能)连接到 Amazon Bedrock AgentCore runtime,四 Agent Swarm 在此处理用户请求。AWS Amplify 托管对话界面,Amazon Simple Storage Service (Amazon S3) 负责会话存储,Amazon Bedrock AgentCore Identity 管理前端与 runtime 之间的身份验证。
监控数据来自单一来源:承载四 Agent Swarm 的 Amazon Bedrock AgentCore runtime。Amazon Bedrock AgentCore Observability(Amazon Bedrock AgentCore 的一项功能)直接为 runtime 进行埋点,以 OpenTelemetry 格式捕获追踪和指标,并将其转发到 Amazon CloudWatch。Amazon Bedrock AgentCore Evaluations 从这些相同的 runtime 追踪中获取数据,为线上交互评分;评估结果也会流入 Amazon CloudWatch。这意味着运行指标、分布式追踪和质量评分都汇聚在同一位置。
第二层监控连接到同一后端。当事件发生时,团队成员会通过已签名的 webhook 将其提交给 AWS DevOps Agent。该 Agent 会提取 Amazon CloudWatch 日志和指标,自主调查,并返回发现结果和修复步骤,而无需任何人在多个工具之间切换。
快速开始
开源:我们基于 FAST 构建了该系统。该系统的完整源代码,包括 CDK 基础设施、评估仪表板和 AWS DevOps Agent 集成,均可在 GitHub repository 中获取。我们以 fullstack-solution-template-for-agentcore(FAST)中的 AgentCore Evaluations Guide 为参考。
要使用 Amazon Bedrock AgentCore Evaluations,你需要:
第 1 层:Amazon Bedrock AgentCore Evaluations,Agent 是否工作良好?
生产环境 Agent 中的静默质量问题会影响团队效率、用户信任和业务成果。AgentCore Evaluations 通过持续针对结构化质量维度为线上交互评分,可在这些故障刚开始出现时便将其捕捉。
_视频 1:提取会话、追踪和 span 的评估指标;在仪表板上查看指标以了解 Agent 性能;每
English / 原文
Multi-agent systems in production experience issues in ways that traditional monitoring misses. For example, the agent can’t invoke its foundation model (FM) and returns an empty response. This could be because of a missing AWS Identity and Access Management (IAM) permission on an agent’s execution role that doesn’t throw a 500 error. A supervisor agent with a poorly scoped prompt doesn’t increase error rates but instead starts routing 20 percent of requests to the unintended specialist while the infrastructure metrics stay green.
Infrastructure monitoring and agent effectiveness monitoring require different approaches. Amazon CloudWatch metrics show whether systems executed correctly, but not whether agents helped users accomplish their goals. An agent can successfully invoke Amazon Bedrock, call every tool without errors, and return a response while completely misunderstanding what the user needs. Infrastructure issues often manifest as reduced agent behavior rather than clear errors. When permissions are revoked or services throttle, agents might experience silent issues. For example, the booking agent stops completing reservations, but the logs show successful tool executions because the issue occurred three calls deep in a chain that didn’t surface an exception.
These problems compound in multi-agent systems where a single user request triggers a supervisor agent that routes work to multiple specialists, each with their own tools and model invocations. There’s typically no fixed execution graph to instrument, failures can occur at multiple handoff points, and their propagation through the system is not always predictable.
We built a production airline reservation system with four specialized agents that combine Amazon Bedrock AgentCore Evaluations for continuous agent quality assessment and AWS DevOps Agent for autonomous infrastructure incident investigation. Amazon Bedrock AgentCore is a platform to build, connect, and optimize agents at scale, with any framework or model. AgentCore Evaluations addresses the quality monitoring gap, continuously scoring live interactions to catch wrong tool selections, task failures, and quality regressions that infrastructure metrics miss entirely. AWS DevOps Agent addresses the second, autonomously tracing failures across service boundaries, correlating IAM policies, invocation logs, and orchestration traces without manual investigation. These two layers show whether the agent works correctly and whether the infrastructure supports it.
Key technologies
The system uses several AWS services:
- Amazon Bedrock provides API access to foundation models from leading AI companies including Anthropic, Meta, Mistral, and Amazon. In our airline reservation system built on AgentCore runtime, Amazon Bedrock powers the language understanding. For model availability by AWS Region, refer to Supported models by AWS Region in Amazon Bedrock.
- AgentCore runtime handles agent orchestration and manages interaction lifecycles, with built-in observability through OpenTelemetry instrumentation.
- With the Fullstack AgentCore Solution Template (FAST), teams can quickly deploy a secured React frontend connected to an AgentCore backend.
- AgentCore Evaluations is a quality assessment framework integrated into AgentCore runtime. It continuously scores agent interactions using LLM-as-a-Judge methodology, providing metrics on helpfulness, correctness, goal completion, and other quality dimensions.
- AWS DevOps Agent is an autonomous investigation tool that acts as an on-call engineer for your infrastructure. When incidents occur, it automatically analyzes Amazon CloudWatch logs, traces failures across service boundaries, and provides root cause analysis with remediation recommendations.
- Strands Agents is an open source SDK for building AI agents with a model-driven approach, supporting multi-agent collaboration patterns including Swarm, Graph, and Agents-as-Tools.
- OpenTelemetry is an open source observability framework that provides standardized instrumentation for collecting traces, metrics, and logs. AgentCore runtime uses OpenTelemetry to emit monitoring data to Amazon CloudWatch, facilitating consistent observability across the system.
- The Swarm Pattern is a multi-agent orchestration approach where a supervisor agent dynamically routes work to specialized agents based on the task at hand. Unlike fixed workflows, Swarm supports adaptive execution paths that change based on runtime decisions, making it powerful for complex tasks but challenging to monitor.
Dual-layer monitoring: quality and infrastructure
The monitoring architecture answers two questions: Is the agent working well? Is the infrastructure healthy?
Amazon Bedrock AgentCore Evaluations: Continuous quality monitoring
AgentCore Evaluations scores live agent interactions on helpfulness, correctness, and goal completion. The system samples a configurable percentage of production requests and evaluates them in the background. Every score comes with reasoning that explains why that score was assigned based on the conversation context, tools used, and task requirements.
When quality metrics drop, it runs pattern analysis across recent low-scoring sessions to identify common failure modes. If the agent consistently chooses the wrong tool for a specific request type, or provides correct information in an unhelpful format, the pattern analysis surfaces that. It then generates concrete recommendations: specific prompt changes, tool selection adjustments, or orchestration logic improvements.
AWS DevOps Agent: Autonomous infrastructure investigation
AWS DevOps Agent monitors system health across metrics, logs, and error patterns. When something breaks, the agent investigates on its own. It pulls relevant Amazon CloudWatch logs, builds a topology graph of affected resources, correlates errors across services (IAM, Amazon Bedrock, your agent runtime), traces the failure path, and delivers specific fix recommendations. In addition to sending an alert with a link to Amazon CloudWatch, it also does the investigation by connecting a blank agent response to a missing IAM permission or linking a spike in timeouts to Amazon Bedrock throttling in a specific Region.
How the layers work together
AgentCore Evaluations replaces intuition with quantitative quality metrics, so teams can measure the actual impact of changes. AWS DevOps Agent automates much of the investigation that previously required manual war rooms by autonomously investigating infrastructure incidents the moment they occur. Together they create the continuous feedback loop, monitor, analyze, improve, deploy, that production multi-agent systems require.
The airline reservation system: why it’s hard to monitor
To demonstrate this architecture end to end, we built an airline reservation system that handles complex, dynamic queries: multi-city bookings, loyalty program benefit application, and company travel policy compliance, all within a single conversational turn. This use case demands exactly the kind of multi-agent coordination that makes production monitoring hard: parallel operations, multiple data sources, sequential dependencies, and strict correctness requirements where errors have real consequences.
Consider a request like this one: “Book me from Seattle to Boston on March 15th, then Boston to Miami on March 18th. Use my companion certificate for the second leg and make sure both flights comply with my company’s travel policy. I’m Gold status so apply any eligible upgrades.”
Handling this in a single conversational turn requires searching two separate routes and retrieving loyalty status and certificates from a different data source while the flight search runs. The bookings must then be sequenced in the right order, because the companion certificate can’t be applied until the flight is selected and the fare class is known. Applying a certificate to an ineligible flight frustrates users. Booking a flight that violates corporate policy wastes money.
We built this with four specialized agents using the Swarm pattern (Figure 1). The Supervisor Agent receives requests and acts as an entry point, uses a think tool to plan subtasks, routes work to other agents which can hand off tasks to each other. The Flight Agent searches routes and handles multi-city connections. The User Agent fetches loyalty status, certificates, and profile data. The Reservation Agent creates, modifies, and cancels bookings, validating before committing changes.
In a Swarm, agents share working memory and hand off work to one another dynamically. Each specialist decides who should act next based on what it finds, rather than following a predetermined execution plan. The supervisor is only the entry point. After a request is in flight, control passes to whichever peer is best suited to the next step, not back through a central router. If flight search finds no direct route, the Flight Agent runs the connection search itself, then hands off to the Reservation Agent once it has options to book. If a user’s certificate doesn’t apply, the User Agent adjusts and passes the task along. This handles unpredictable request structures without a predefined execution graph, but it also means there is no fixed call graph to instrument.
Failures can occur at any handoff point, and because execution paths change based on runtime decisions, the failure path changes each time too. A quality failure and an infrastructure failure can look nearly identical from the outside, but they require completely different responses. From the outside, a quality failure and an infrastructure failure look the same. AgentCore Evaluations catches the first kind: everything executes but the agent still fails the user. AWS DevOps Agent catches the second: infrastructure breaks silently and surfaces as degraded behavior.
Figure 1: Swarm multi-agent pattern
Dual monitoring architecture
The following diagram shows how these components connect.
Figure 2: Full system architecture showing the React frontend, AgentCore runtime, Amazon CloudWatch, and AWS DevOps Agent
We built a React frontend hosted on AWS Amplify that connects through Amazon Bedrock AgentCore Identity, a capability of Amazon Bedrock AgentCore, to Amazon Bedrock AgentCore runtime, where the four-agent swarm handles user requests. AWS Amplify hosts the conversational interface, Amazon Simple Storage Service (Amazon S3) handles session storage, and Amazon Bedrock AgentCore Identity manages authentication between the frontend and the runtime.
Monitoring data originates from a single source: the Amazon Bedrock AgentCore runtime hosting the four-agent swarm. Amazon Bedrock AgentCore Observability, a capability of Amazon Bedrock AgentCore, instruments the runtime directly, capturing traces and metrics in OpenTelemetry format and forwarding them to Amazon CloudWatch. Amazon Bedrock AgentCore Evaluations draws from those same runtime traces to score live interactions, with evaluation results also flowing into Amazon CloudWatch. This means operational metrics, distributed traces, and quality scores land in one place.
The second monitoring layer connects to this same backend. When an incident occurs, a team member submits it to AWS DevOps Agent through a signed webhook. The agent pulls Amazon CloudWatch logs and metrics, investigates autonomously, and returns findings and remediation steps without requiring anyone to navigate between tools.
Getting started
Open source : We built this system on FAST and the complete source code for this system including CDK infrastructure, evaluation dashboard, and AWS DevOps Agent integration is available in the GitHub repository. We used the AgentCore Evaluations Guide in the fullstack-solution-template-for-agentcore (FAST) as reference.
To use Amazon Bedrock AgentCore Evaluations, you need:
Layer 1: Amazon Bedrock AgentCore Evaluations, is the agent working well?
Silent quality issues in production agents impact team efficiency, user trust, and business outcomes. AgentCore Evaluations catches these failures the moment they begin by continuously scoring live interactions against structured quality dimensions.
Video 1: Extracting evaluation metrics for sessions, traces, and spans; viewing metrics on the dashboard to understand agent performance; performing on-demand evaluation by exploring session traces and spans; running the AI engine to identify patterns across low-scoring sessions; and uploading prompts to receive AI-generated improvement recommendations
Amazon Bedrock AgentCore provides 16 built-in evaluators organized by what they measure and when they run. There are 13 LLM-as-a-Judge evaluators to score interactions with detailed explanations, so teams can verify judgments and understand exactly why an interaction received a particular rating, and three deterministic trajectory matchers.
| Evaluator | Definition | Evaluation Level |
|---|---|---|
| Goal Success Rate | Assesses whether the AI assistant successfully completed the user goals within a conversation session by analyzing the entire conversation end-to-end. | Session |
| Coherence | Assesses the logical consistency and cohesion of a response, checking for self-contradictions, logic gaps, and soundness of reasoning without evaluating factual accuracy. | Trace |
| Conciseness | Measures how efficiently the assistant communicates, assessing whether responses provide necessary information using minimal words without unnecessary elaboration. | Trace |
| Correctness | Assesses the factual accuracy of a response to a given task, focusing on whether the content and solution are accurate regardless of style or presentation. | Trace |
| Faithfulness | Assesses whether a response remains consistent with the conversation history, identifying conflicts between the current response and previous interactions within the same conversation. | Trace |
| Harmfulness | Detects potentially harmful content in a response, including insults, hate speech, violence, inappropriate sexual content, and stereotyping. | Trace |
| Helpfulness | Assesses how effectively a response helps users progress toward their goals, evaluated purely from the user’s perspective on whether the response moves them closer to their objectives. | Trace |
| Instruction Following | Assesses whether a response adheres to the explicit instructions provided in the user’s input, focusing on compliance with specific directives regardless of overall response quality. | Trace |
| Refusal | Detects when the assistant declines to address or fulfill a user’s request, identifying both direct declines and indirect avoidance of the requested task. | Trace |
| Response Relevance | Assesses how well a response addresses the specific question or request, measuring the focus and relevance of the response to the given input. | Trace |
| Stereotyping | Detects bias and stereotypical content in a response, identifying prejudicial assumptions or generalizations about specific groups of people. | Trace |
| Tool Parameter Accuracy | Assesses whether the assistant correctly uses contextual information when making tool calls, verifying that tool parameters are accurately derived from the conversation context. | Tool |
| Tool Selection Accuracy | Assesses whether the assistant chooses the appropriate tool for a given situation, determining if the selected action is justified and optimal at a specific point in the conversation. | Tool |
| Trajectory Any Order Match | Validates that expected tools are present regardless of order. | Session |
| Trajectory Exact Order Match | Validates that actual tools match expected tools in exact order with no extras. | Session |
| Trajectory In Order Match | Validates that expected tools appear in order within actual trajectory, extras allowed between. | Session |
Table 1: Built-in evaluator metrics supported by AgentCore Evaluations
Online evaluation: continuous production monitoring
Online evaluation monitors live agent interactions by continuously sampling a configurable percentage of traces (from 0.01–100 percent) and scoring them asynchronously against your chosen evaluators. This asynchronous, event-driven design means evaluation runs alongside production traffic without adding to user-facing response latency.
Amazon Bedrock AgentCore emits evaluation metrics in real time to Amazon CloudWatch through OpenTelemetry. If you’re already collecting traces for observability, online evaluation adds quality scores alongside your existing operational metrics without requiring code changes or redeployments. You can set Amazon CloudWatch alarms that trigger the moment a quality metric drops below your defined threshold catching silent quality failures before they reach a broad set of users.
For our airline reservation system online evaluation, we selected three built-in Amazon Bedrock AgentCore evaluators that provide comprehensive coverage of agent quality: Helpfulness, Correctness, and Goal Success Rate. We chose these metrics because they represent the three fundamental dimensions of agent performance that matter most to end users. Together, these three metrics create a balanced scorecard that captures both the quality of individual responses and the effectiveness of the overall interaction. This gives teams actionable insights into where their agents excel and where they need improvement.
| Metric | Why it matters | Example scenarios |
|---|---|---|
| Helpfulness | Captures user satisfaction beyond correctness. Identifies responses that are technically accurate but not useful. Helps optimize for user experience, not only accuracy. Detects when agents provide too much or too little information. | ✅ High helpfulness: Agent provides a clear, actionable answer with context. ❌ Low helpfulness: Agent gives a correct but overly technical response to a simple question. |
| Correctness | Facilitates reliability and trustworthiness. Catches hallucinations and factual errors. Critical for domains requiring accuracy (finance, healthcare, legal). Builds user confidence in the agent. | ✅ High correctness: Agent provides accurate data and valid reasoning. ❌ Low correctness: Agent makes up facts or provides incorrect calculations. |
| Goal Success Rate | Measures actual business value delivered. Captures multi-turn conversation effectiveness. Identifies when agents get stuck or fail to complete tasks. Aligns with user intent and business objectives. | ✅ High goal success: User wanted to book a flight, and the agent completed the booking. ❌ Low goal success: User wanted to book a flight, but the agent only provided flight options. |
Workflow to set up the online evaluation configuration:
Online evaluation runs in production without interruption in the background, automatically sampling sessions at your configured rate and writing results to Amazon CloudWatch Logs without impacting production latency.
 Workflow diagram for setting up the online evaluation configuration
Why not more metrics?
- Avoid metric overload : Too many metrics make it hard to identify what matters.
- Reduce evaluation costs : Each evaluator adds latency and cost per invocation.
- Focus on actionable insights : These three cover the dimensions that matter most to users.
- Enable quick iteration : Teams can quickly understand and act on these metrics.
- Additional evaluators (Faithfulness, Instruction Following, Tool Use Quality) are available but not enabled by default. Teams can add them based on their specific needs.
 Evaluation dashboard showing agent quality score summaries

Figure 3: Evaluation dashboard displaying average scores across sessions with distribution breakdown by score range (0.0–1.0)
The evaluation dashboard transforms raw Amazon CloudWatch logs and OpenTelemetry traces into an actionable view of how your agent is actually performing (Figure 3). Instead of sifting through thousands of JSON log entries across multiple log groups to piece together what happened in a single session, the dashboard surfaces session timelines, span hierarchies, and evaluation scores in a visual interface. You can filter sessions by date range and drill into individual traces to see exactly where an agent spent time or encountered errors. You can also run on-demand evaluations against specific sessions with built-in or custom evaluators.
Responsible AI safeguards
Evaluators like Correctness and Faithfulness catch hallucinated or inaccurate outputs after the fact, but because online evaluation runs asynchronously on a sample of sessions, a problematic response can still reach the user before it’s scored. For production agent systems, Amazon Bedrock Guardrails provides a complementary inline layer that operates on every response before it’s returned. Key capabilities include content filtering to block harmful or inappropriate content, denied topic detection to help prevent agents from responding to out-of-scope queries (for example, medical or legal advice in an airline context), contextual grounding checks that flag responses not grounded in retrieved source material, and sensitive information redaction to mask PII such as credit card numbers or passport details that may surface in tool outputs.
For a system like the airline reservation agent, these controls address real-time risks that asynchronous evaluation cannot: a model fabricating flight pricing that sounds plausible but wasn’t returned by any tool, an agent offering legal commitments about refund policies it has no authority to make, or PII from one customer’s profile leaking into another session. Where AgentCore Evaluations scores quality after the fact on a sample of sessions, Guardrails acts synchronously on every response, providing the real-time safety net that sampled evaluation alone cannot. Together they form a complete quality and safety posture: Guardrails help prevent harmful outputs from reaching users in the first place, while Evaluations identifies subtler quality regressions that accumulate over time.
On-demand evaluation: development and CI/CD integration
While online evaluation provides continuous monitoring, on-demand evaluation helps you investigate specific sessions: a user complaint, an edge case, or a session flagged by your monitoring. Production metrics operate on a sampling rate (typically 10 percent), so not every session gets scored. On-demand evaluation fills that gap, so you can evaluate a specific session against a selected evaluator at any time. Beyond the three default metrics (Helpfulness, Correctness, Goal Success Rate), Amazon Bedrock AgentCore provides a full catalog of built-in evaluators you can run on-demand as shown in Table 1.
You can also create custom evaluators with your own scoring rubrics and instructions tailored to your domain. The dashboard surfaces these through the evaluators API, so you can browse what’s available and run combinations against individual sessions or in batch across multiple sessions (Figure 4). This makes on-demand evaluation the go-to tool for root cause analysis: when a production metric dips, you pick the problematic sessions and run targeted evaluators to understand exactly what went wrong.

Figure 4: Viewing trace and span data and performing on-demand evaluation against a session’s trace, spans, and tool calls
Workflow for on-demand evaluation:
On-demand evaluation follows a synchronous workflow where you request evaluation of a specific session and receive immediate results with scores and explanations.
 Workflow diagram for on-demand evaluation
The AI analysis engine: from scores to improvements
After retrieving evaluation metrics, build an analysis layer that detects patterns in low-performing sessions, runs statistical analysis to separate systemic issues from isolated incidents, and generates concrete prompt improvements. This layer should apply:
- Unsupervised pattern detection to surface recurring failure modes across evaluation dimensions.
- Statistical analysis (frequency, correlation) to identify which failure patterns are systemic versus isolated.
- LLM-based reasoning to generate concrete prompt optimization recommendations grounded in production evidence.
The AI Engine identifies common failure patterns: poor tool selection, missing context, or specific criteria that score low. Configure it to return structured findings with frequency counts, affected session IDs, and concrete evidence from the traces. For example, your engine might identify that 23 percent of low-scoring sessions involve the agent selecting the wrong tool when users ask about flight changes, with the pattern appearing most frequently in multi-turn conversations (Figure 5).
Prompt improvement layer : Build on the pattern analysis by implementing a prompt improvement feature that generates revised versions of your original prompt. This feature should directly address the identified patterns with clear explanations of what changed, why, and the expected impact (Figure 6). This closes the evaluation loop: metrics surface problems, analysis identifies root causes, and prompt improvements provide actionable fixes that can be validated in the next continuous integration and continuous delivery (CI/CD) run and monitored through the next production cycle.

Figure 5: AI pattern analysis based on the low-scoring sessions

Figure 6: Prompt improvement recommendations and the improved prompt
Layer 2: AWS DevOps Agent, is the system healthy?
AgentCore Evaluations monitors agent quality, but infrastructure issues like permissions and tool errors need a different approach. The AWS DevOps Agent acts as an autonomous on-call engineer, investigating infrastructure issues automatically. When anomalies occur, it analyzes system logs, infrastructure metrics, and error patterns, then provides specific remediation steps.
The following demo video (Video 2) showcases how the AWS DevOps Agent can be triggered through a signed webhook for the Travel Agent:
Video 2: How the AWS DevOps Agent performs an investigation, looking into relevant Amazon CloudWatch logs and AWS service gaps to identify the root cause and provide remediation steps
As shown in the video, after an incident is submitted through a signed webhook, the AWS DevOps Agent first identifies relevant logs from Amazon CloudWatch, then analyzes it to check for common errors such as IAM permission issues, tool failures or other hidden errors, and finally applies large language model (LLM)-based reasoning to identify a root cause and targeted recommendations to help prevent the issue in the future.
Without the AWS DevOps Agent, you would see that the airline swarm agent suddenly stopped responding to flight booking requests, returning either a generic error message or a completely blank output instead of helping the user.
At this point, you would:
- Check application logs for error patterns.
- Review recent deployments for potential causes.
- Examine IAM policies and permissions manually.
- Correlate Amazon CloudWatch metrics across multiple services.
- Trace the execution flow through multiple agent interactions.
This process could take 30–60 minutes, assuming there is a deep knowledge of the system architecture.
After we submitted the incident directly to our AWS DevOps Agent Space through a signed webhook connected to the AWS DevOps Agent Space, an investigation was kicked off, resulting in a topology graph of the affected AWS resources as well as a comprehensive analysis of the Amazon CloudWatch logs from the AgentCore runtime.

Figure 7: The AWS DevOps Agent UI showing the topology graph construction and Amazon CloudWatch log analysis beginning simultaneously
Then, by examining the errors that occurred across the invocation chain, the AWS DevOps Agent identified the root cause.

Figure 8: The AWS DevOps Agent UI showing the identified root cause, a missing bedrock:InvokeModel permission, with the complete failure path traced from the user request through AgentCore runtime to the Amazon Bedrock API denial
It identified a missing bedrock:InvokeModel permission on the execution role. Every agent invocation was calling Amazon Bedrock to run its language model, and every call was being denied at the IAM layer. The Supervisor Agent couldn’t invoke its model to process the initial request, so it returned a blank output (not a 403 error or an exception) because there was no model response available to synthesize into anything more informative.
Critically, the AWS DevOps Agent did not only identify an IAM error. It traced the complete failure path starting from the user request:
User request → AgentCore runtime → Amazon Bedrock API call → Access denied → Agent failure
Lastly, the investigation provided specific remediation steps in the prevention tab.

Figure 9: The AWS DevOps Agent UI showing the prevention tab with specific, actionable remediation steps and a high confidence rating
At a high level, recommended actions were to add the required Amazon Bedrock permissions to the particular execution role, and scope permissions to the specific foundation model resource in use. These provide the user with things to think about for future development to help prevent failures in this paradigm.
The AWS DevOps Agent improves developer efficiency by automating failure diagnosis across the multi-agent system. For example, it maps blank agent outputs to a missing Amazon Bedrock permission at the IAM layer. The AWS DevOps Agent coordinates between Amazon Bedrock AgentCore runtime, Amazon Bedrock, AWS IAM execution roles, and Amazon CloudWatch Logs to correlate automatically with a failure. Its ability to pattern-match across the entire multi-agent call flow catches errors that would otherwise go unnoticed.
Beyond IAM permission issues, the AWS DevOps Agent is designed to handle the full range of complex failure modes common in multi-agent systems. Such examples include:
- Model throttling under load : When subagents scale up and hit Amazon Bedrock token-per-minute limits, individual subagents begin failing intermittently. The AWS DevOps Agent correlates throttling metrics with agent invocation timelines to identify which model, Region, and traffic spike caused the issue.
- Tool call failures masked by retry logic : If a subagent’s tool integration begins returning errors and the Supervisor Agent silently reroutes, the AWS DevOps Agent surfaces downstream tool errors from logs and connects them to degraded user experience.
- Memory and context issues : If an agent loses access to its memory resource mid-session, responses become incoherent rather than failing outright. The AWS DevOps Agent detects anomalies in response quality patterns and correlates them with configuration changes.
- Cross-agent communication breakdowns : When handoffs between agents fail because of network issues or authentication problems, the AWS DevOps Agent tracks the complete handoff chain and identifies exactly where communication broke down.
Note: Before adopting this architecture, keep the following in mind:
- LLM-as-judge reliability : AgentCore Evaluations uses LLM-based scoring, which lacks ground truth. Treat scores as signals, not absolute measures. Calibrate evaluators with subject matter experts to align automated judgments with human expectations in your domain.
- Service maturity : AWS DevOps Agent is actively evolving. Currently, webhook credential generation is done through the console, but Agent Space creation and management can be automated with the AWS CDK and the AWS SDK.
- Latency trade-offs : Online evaluation adds processing overhead. Lower sampling rates reduce this overhead but may miss edge cases. Tune your sampling rate based on your traffic volume and how comprehensively you need to cover the interaction space.
- Security : Careful IAM policy configuration is required. The AWS DevOps Agent needs broad read access to logs and metrics, scope permissions appropriately while making sure it has access to everything needed to trace cross-service failures.
- Responsible AI controls : For production deployments, complement evaluation with Amazon Bedrock Guardrails to enforce content filtering, denied topics, grounding checks, and PII redaction inline on every response. Evaluations catch quality drift over time. Guardrails help prevent harmful outputs in real time.
Conclusion
Deploying agents to production is only the start. This dual-monitoring approach, quality and infrastructure, gives teams the feedback loop they need to improve continuously. AgentCore Evaluations monitors quality. AWS DevOps Agent investigates infrastructure. Together, they turn production data into specific improvements.
Our airline reservation system, built on the Swarm pattern with a Strands agent and deployed to AgentCore, demonstrates that this dual-monitoring approach is practical, scalable, and effective. The result is faster incident resolution, higher policy compliance, and an iterative improvement cycle grounded in real production behavior.
Whether you’re building your first multi-agent system or scaling an existing deployment, the same principles apply: measure quality continuously, investigate failures autonomously, and let production data drive your next iteration.
Ready to get started?
- Check out our Open Sourced Code to demo our dual-layer monitoring architecture for multi-agent systems.
- Explore AgentCore for agent deployment and evaluation.
- Learn more about Strands Agents for building multi-agent systems.
- Review the τ-Bench benchmark for evaluating agent architectures. tau-Bench includes a tau-airline domain that benchmarks exactly the kind of tool-calling and policy-following behaviors our system requires, making it a natural fit for validating quality improvements driven by AgentCore Evaluations.
About the authors
Meghana Ashok
Meghana is a Senior Machine Learning Engineer at the AWS Generative AI Innovation Center (GenAIIC), where she operates at the intersection of engineering, research, and GenAI solutions. She specializes in designing and building scalable AI architectures that bridge the gap between cutting-edge generative AI research and production-ready systems. With a passion for turning complex GenAI concepts into robust, deployable solutions, Meghana drives innovation by combining deep technical engineering expertise with a forward-thinking approach to AI-powered automation and intelligent systems.
Suren Gunturu
Suren is a Data Scientist II working in the AWS Generative AI Innovation Center, where he works with various AWS customers to solve high-value business problems. He specializes in building AI/ML pipelines using agentic frameworks, primarily through Amazon Bedrock AgentCore and other AI/ML cloud services.
Samaneh Aminikhanghahi
Samaneh is an Applied Scientist at the AWS Generative AI Innovation Center, where she works with customers across different verticals to accelerate their adoption of generative AI. She specializes in agentic AI frameworks, building robust evaluation systems, and implementing responsible AI practices that drive sustainable business outcomes.
Vidya Sagar Ravipati
Vidya Sagar is a Science Manager at the AWS Generative AI Innovation Center, where he uses his vast experience in large-scale distributed systems and his passion for machine learning to help AWS customers across different industry verticals accelerate their AI and cloud adoption.