Abnormal AI:使用 Amazon Bedrock AgentCore 实现大规模 Agent 式邮件安全
英文标题:Abnormal AI: Amazon Bedrock AgentCore for agentic email security at scale
Abnormal AI 将 Amazon Bedrock AgentCore Code Interpreter 部署于实时邮件威胁检测系统,为 Agent 提供临时、隔离的计算沙盒,在数十亿封邮件规模下执行动态代码并拦截威胁。其三级检测架构由启发式规则、机器学习模型和内联 Agent 依次处理从简单到复杂的邮件,其中最难案例由结合 Code Interpreter 的 Agent 处理,每日规模达数万封。该公司还运行批处理分析 Agent,从误判数据中发现模式、生成候选规则并改进模型,每周约运行 100 个批处理任务。实践表明,对于需要数据处理、验证和长任务恢复能力的生产级 Agent,零信任沙盒、程序化验证器与基于文件系统的检查点是关键设计模式。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 183.4 KB
 129.3 KB
 113.5 KB
 23.7 KB
 297.3 KB
 19.5 KB
 209.0 KB
中文
如今,AI Agent 已在生产环境中每天运行数十亿次操作,并且一个反复出现的架构模式逐渐浮现:Agent 需要一个计算草稿空间。这不仅适用于编程任务,也适用于数据汇总、分析、验证,以及任何仅靠语义推理不足以完成的工作流。
Abnormal AI 是一家行为安全服务商,为超过 25% 的《财富》500 强企业提供保护。该公司已部署 Amazon Bedrock AgentCore 的一项能力 Amazon Bedrock AgentCore Code Interpreter,并将其用于支持实时内联邮件威胁检测的 Agent。这些系统现已投入生产,每天处理数十亿封邮件,并以同等规模执行由 Agent 驱动的代码,在威胁到达收件箱之前进行内联检测和拦截。
这项工作也是 Abnormal AI 构建软件的方式之一。目前,该公司 80% 的代码变更以某种方式借助 Agent 构建,40% 的代码变更则由后台 Agent 端到端完成(完全由 AI 构建,而非 AI 辅助)。其将 AgentCore Code Interpreter 用于威胁检测,反映了同样的 AI 原生方法已被应用于生产运行时。
本文将介绍 Abnormal AI 如何设计这些系统、其沙盒方案背后的设计决策,以及面向大规模部署 Code Interpreter 的开发者的实用经验。
什么是 Amazon Bedrock AgentCore Code Interpreter?
Amazon Bedrock AgentCore Code Interpreter 为 Agent 动态执行代码提供了完全托管、无服务器的运行时。其主要特性包括:
- 临时 MicroVM 会话:可配置的存活时间从 15 分钟(默认)到 8 小时,适合长时间运行的任务。
- 安全性:会话在安全沙盒中运行,并在宿主操作系统层面实现完全隔离,旨在帮助防止会话间意外的数据泄露。
- 灵活的网络配置:可配置为沙盒虚拟私有云(VPC)模式,或允许访问公共互联网。
- 文件处理:可通过 API 直接处理最大 100 MB 的文件,也可连接 Amazon Simple Storage Service(Amazon S3)处理更大的数据集。
- 预加载运行时:提供 Python 和
Node.js环境,并预装常用的可视化、统计和数据处理库。 - 内置可观测性:日志会发送至 Amazon CloudWatch 和 AWS CloudTrail,以便进行监控。
关键在于,Code Interpreter 以 API 形式提供。这意味着它不会规定 Agent 的工作流;相反,它提供了一个容器,Agent 可以在其中运行命令、上传文件并获取结果。对于已有 Agent 基础设施的团队而言,这种即插即用的设计使集成变得直接。
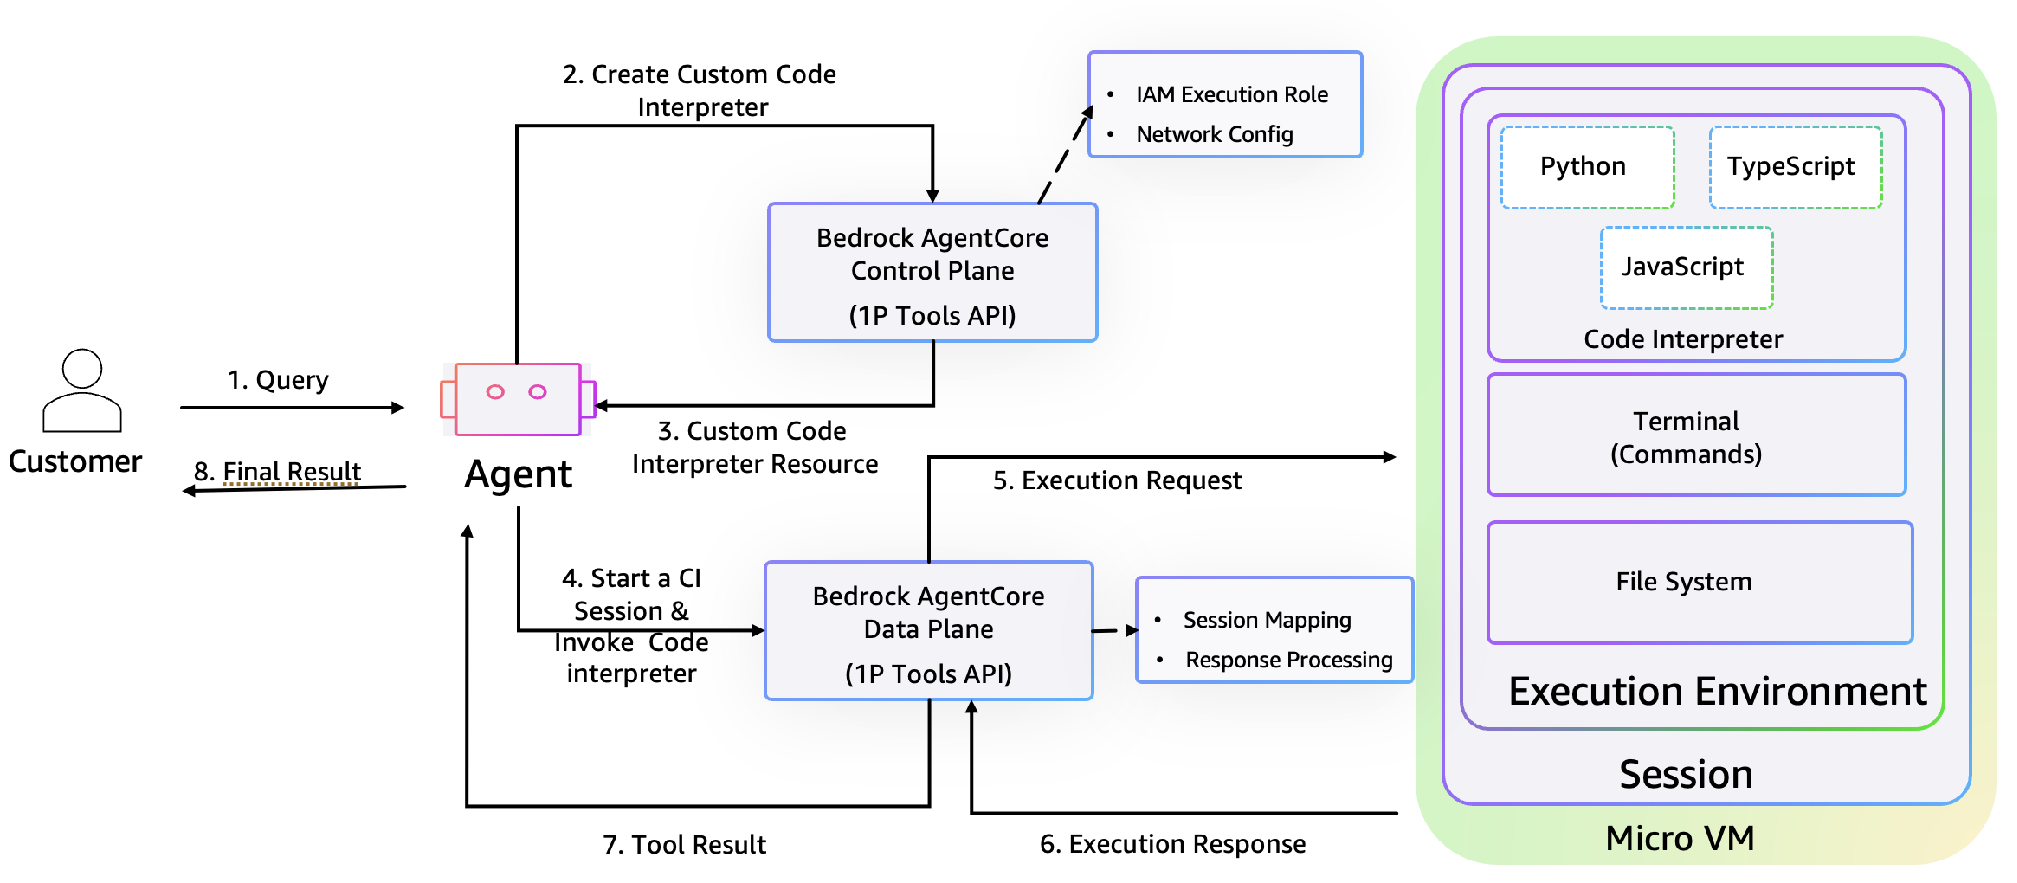
图 1:Amazon Bedrock AgentCore Code Interpreter 架构。Agent 调用 Code Interpreter API,预置一个临时 MicroVM 沙盒会话,用于代码执行、文件输入和输出以及结果检索。
为什么 Agent 需要计算草稿空间
大语言模型(LLM)擅长推理和语义连贯性,但许多现实操作并不适合映射为语义推理:
- 基础数学和计数:“过去一小时我们检测到多少封钓鱼邮件?”需要的是计算,而不是语言生成。
- 数据处理和可视化:将原始数据转换为图表、PDF 或结构化报告。
- 代码验证:运行单元测试、代码检查(linting)和集成测试,以验证 Agent 生成的输出。
通过将大语言模型与 Code Interpreter 配对,可以将 Agent 的能力扩展到单凭推理无法实现的范围。
“几乎所有 Agent,无论是否用于写代码,都需要一个代码解释器沙盒,让它能够真正处理数据并得出答案。”
— Abnormal AI AI 战略副总裁 Shrivu Shankar
Abnormal AI 的架构:数十亿邮件规模的三级检测
如图 2 所示,Abnormal AI 通过三级检测架构处理数十亿封电子邮件。
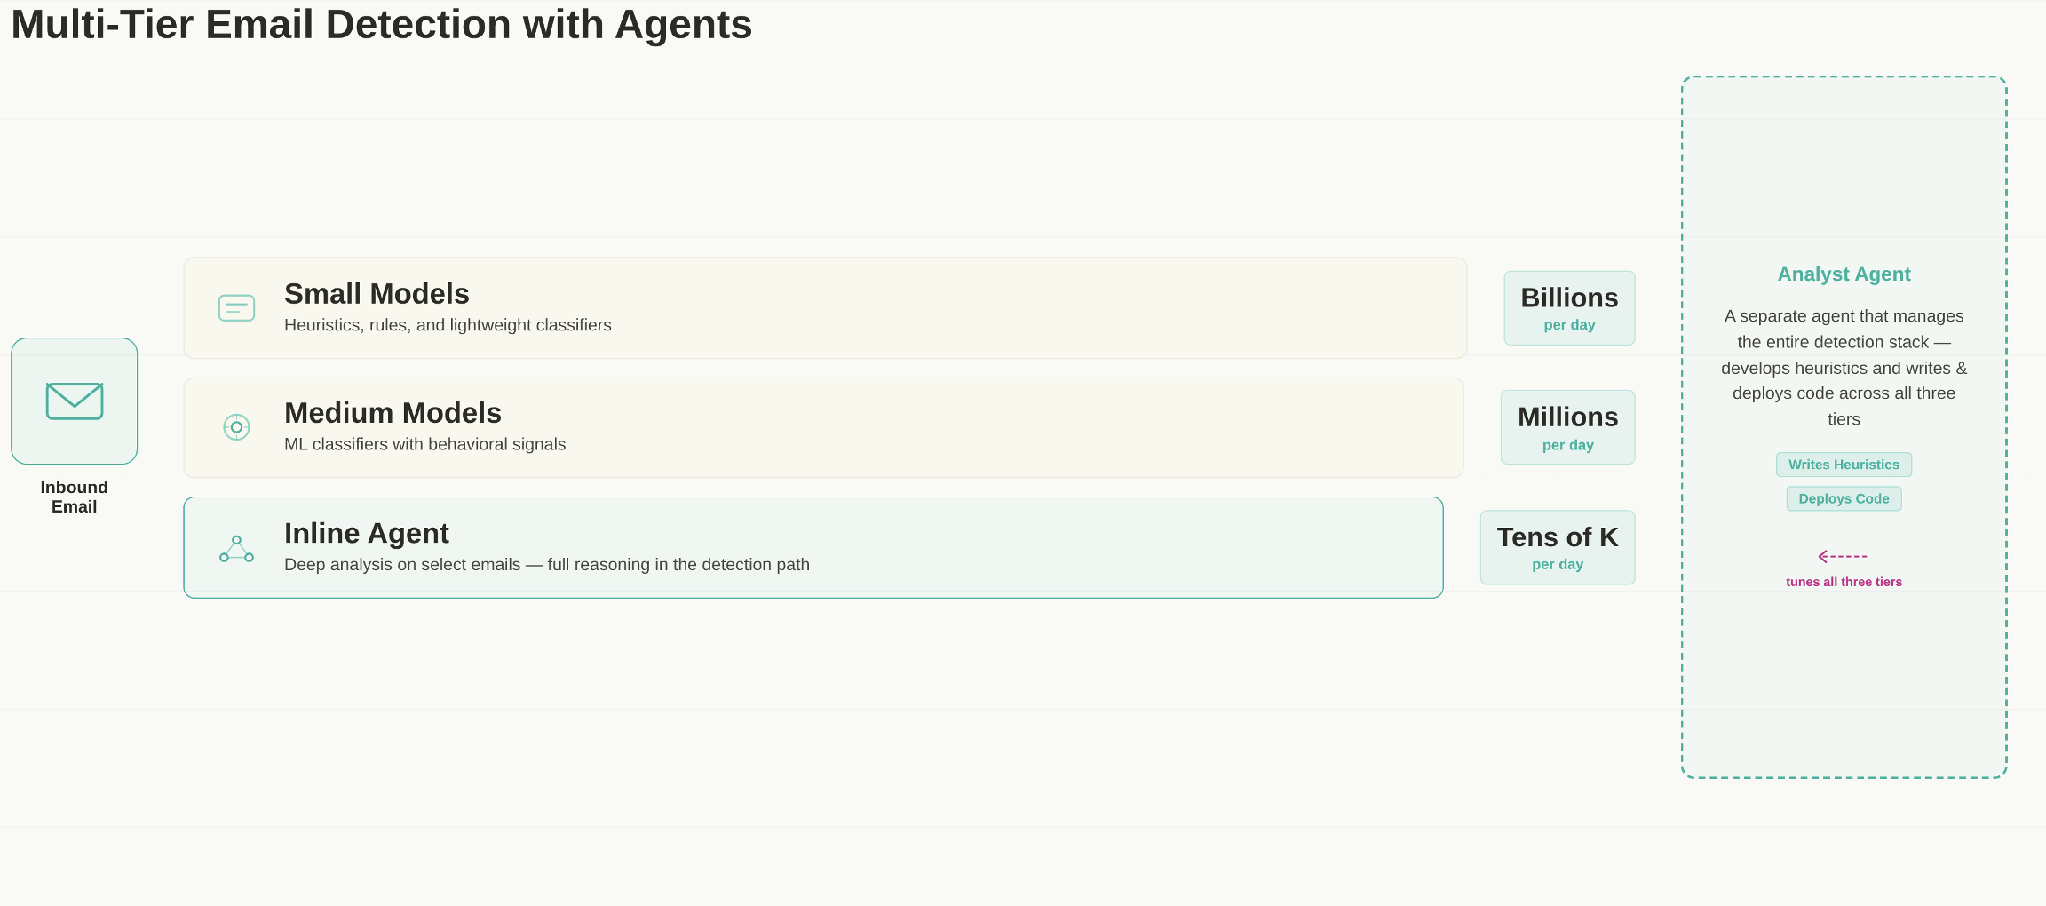
图 2:Abnormal AI 的三级邮件检测流水线,包括第 1 层(启发式规则,每天数十亿封)、第 2 层(机器学习模型,每天数百万封)和第 3 层(配备 Code Interpreter 的内联 Agent,每天数万封)。每一层处理前一层无法确定、难度逐步升高的案例。
第 1 层 —— 高吞吐量轻量级分类(每天数十亿封)
小型模型、启发式规则和轻量级分类器(逻辑回归)处理最大规模的流量。在这一规模下,运行更大的模型既成本高昂,也没有必要。大多数邮件无需深度分析即可完成分类。
第 2 层 —— 用于不确定案例的中等规模模型(每天数百万封)
第 1 层无法确定的邮件会流入深度学习和机器学习(ML)模型,这些模型执行更多行为信号分析。
第 3 层 —— 配备 Code Interpreter 的内联 Agent(每天数万封)
通常需要人工分析师评估的最困难案例,由内联 Agent 处理。这些 Agent 接收威胁情报数据,并使用沙盒对其进行分析,动态编写脚本。随后,它们评估这些数据如何契合整体行为模型,并作出判定。误分类由独立系统处理,该系统会持续学习并改进整个系统。多种监控系统会验证线上系统的运行情况。
分析师 Agent —— 批量情报分析
除图 2 所示的实时分类流水线外,Abnormal 还部署了一个以批处理模式运行的 分析师 Agent(图 3):
- 摄取检测流水线中的误分类结果和调优信号。
- 识别大规模邮件集合中的模式和趋势。
- 基于 Abnormal AI 自有检测流水线的特征和信号,自主编写第 1 层候选启发式规则草案。
- 改进第 2 层模型。
- 每周运行规模约为 100 个批处理作业。
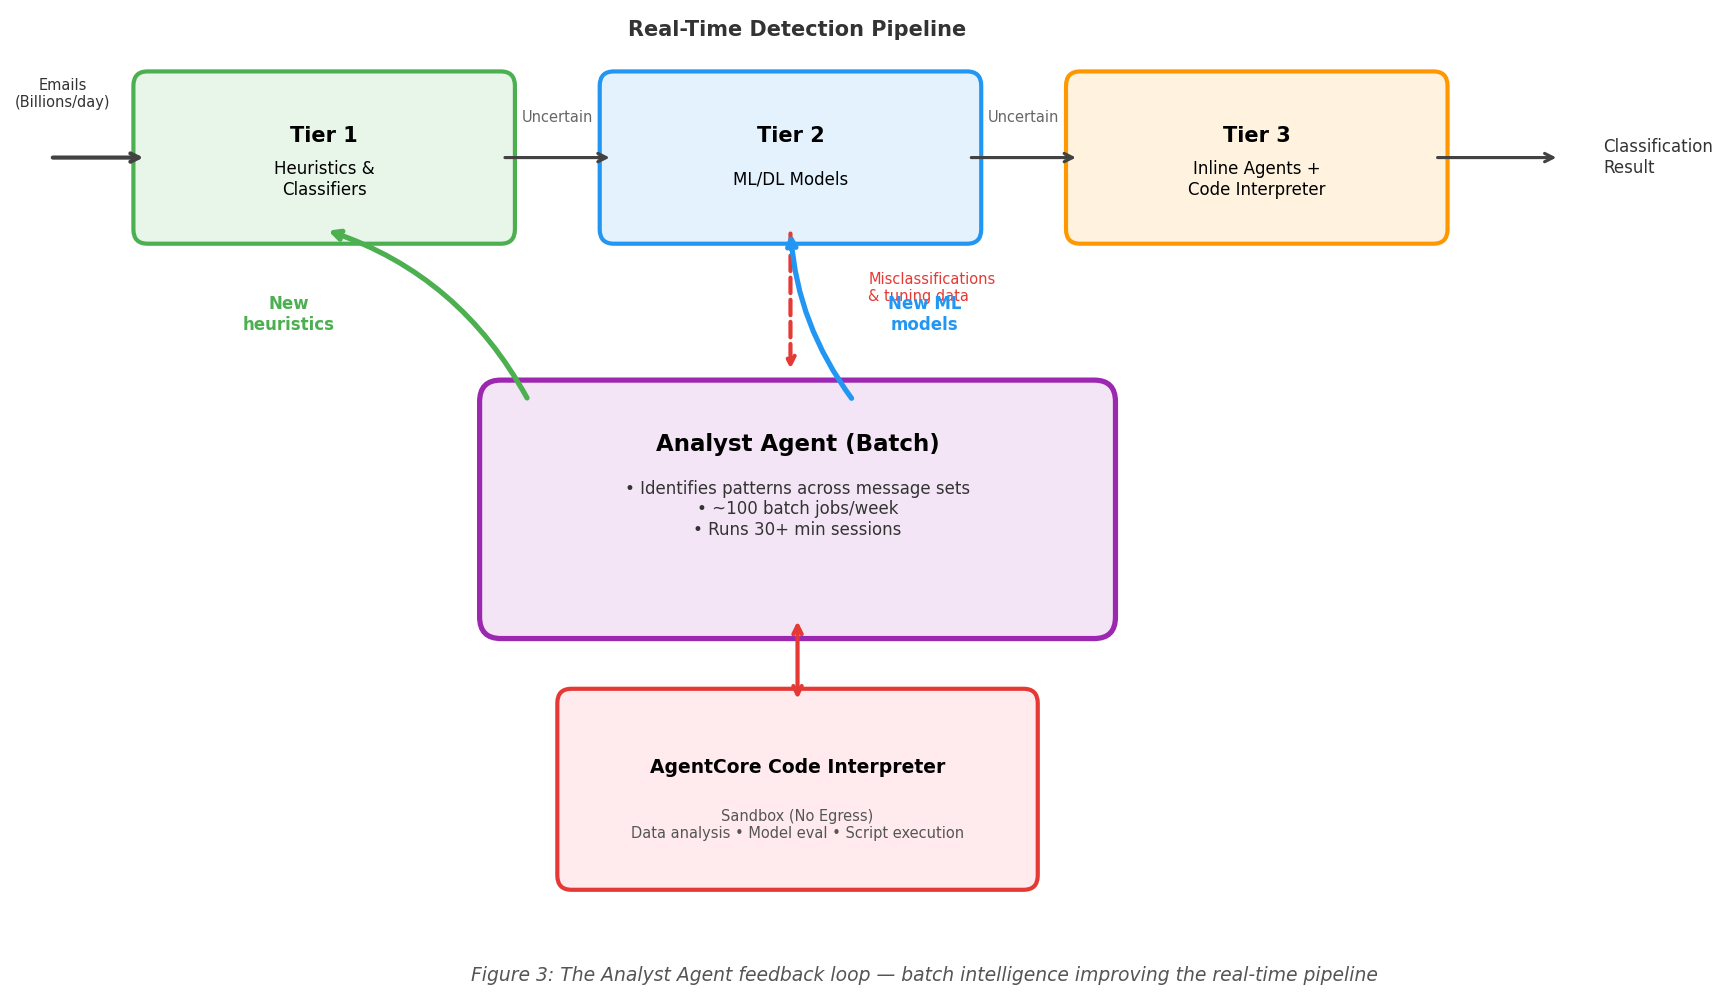
图 3:分析师 Agent 的反馈闭环。批处理 Agent 从实时流水线中摄取误分类数据,使用 Code Interpreter 会话分析模式,并将改进后的启发式规则和模型回馈至第 1 层和第 2 层。
这些批处理作业可以运行超过 30 分钟,并在整个过程中维持 Code Interpreter 会话。它们也可以跨越全天的操作,Agent 在此期间间歇性地使用 Code Interpreter。例如,Agent 先运行一个会话,在外部训练模型,然后再次调用 Code Interpreter 处理结果。
安全性:零信任沙盒设计
Abnormal 选择了 Code Interpreter 的沙盒(无出站访问)配置,主要由两项考量驱动:
- 可复现性——由于沙盒没有外部网络访问能力,在该会话期间,Abnormal AI 控制范围之外的任何事物都无法影响 Agent 的行为。该环境旨在实现完全确定性。
- 防止数据外泄——威胁情报数据会进入沙盒进行分析。即使 Agent 因提示词注入或随机性行为而变得恶意,该设计也旨在防止这些数据被外泄到互联网。
其他安全实践包括:
- 受控数据摄取:审慎确定进入 Code Interpreter 的数据类型,以及允许执行哪些写入操作。
- 子处理方一致性:Code Interpreter 在现有 AWS 子处理方关系下运行,从而降低合规负担。
- 网络隔离分层:在既有网络隔离运行框架的基础上增加沙盒隔离,提供纵深防御。
经验总结与最佳实践
Abnormal AI 在生产环境中运行 Code Interpreter 的过程中形成了多项实践。
1. 给 Agent 它想要的能力
与严格的分步工作流相比,Agent 在轻量、通用的运行框架中表现更好。应提供解决问题的高层原则,让 Agent 运用自身智能决定具体方法。
2. 每个 Agent 都需要一个草稿空间
Code Interpreter 不仅适用于编程 Agent。分析邮件的安全 Agent 同样可从用于数据汇总、模式分析和验证的计算草稿空间中受益。
3. 使用程序化验证器作为护栏
当 Agent 拥有程序化验证工具时,能够交付更高质量的输出。单元测试、集成测试和代码检查让 Agent 能够在交付最终结果前,在沙盒内进行自测。
4. 将文件系统用作长任务的恢复点
对于超过 Code Interpreter 会话时长的操作(例如模型训练),可使用文件系统作为检查点。使用 Code Interpreter 进行计算,将状态持久化到文件,在外部执行长时间运行的操作,然后再次调用 Code Interpreter 处理结果。分析师 Agent(图 3)在全天候模型训练操作中使用了这一模式。
结论
Abnormal AI 的实施展示了生产级 Agent 系统的一项关键洞见:Code Interpreter 不仅仅是编程工具,更是 Agent 用于进行计算推理的基础设施。通过将 AgentCore Code Interpreter 的托管安全沙盒与其自有轻量级 Agent 运行框架相结合,Abnormal 实现了:
- 通过沙盒隔离形成零信任安全态势,帮助防止数据外泄。
- 仅将 Agent 计算资源保留给最困难的案例,从而实现数十亿邮件规模的处理能力(图 2)。
无论是在构建安全 Agent,还是构建一个需要 Agent 处理数据并验证自身输出的系统,这一模式都很清晰:为 Agent 提供一个草稿空间,并且更应相信它们的评估,而非它们的断言。
后续步骤
- 开始使用 Amazon Bedrock AgentCore Code Interpreter。
- 探索 AgentCore 的功能和其他工具(Gateway、Memory、Runtime、Identity)。
- 前往 abnormalsecurity.com 了解更多关于 Abnormal AI 的信息。
Abnormal AI 是 AWS 客户。本文表达的观点和意见属于该客户,不一定反映 Amazon Web Services 的观点。
关于作者
Aswin Vasudevan
Aswin 是 AWS 安全与 ISV 领域的高级解决方案架构师。他非常喜爱生成式 AI 和无服务器架构,并乐于与客户协作,构建能够创造业务价值的解决方案。
Felipe Lopez
Felipe 是 AWS 的首席 AI/ML 专项解决方案架构师。在加入 AWS 之前,Felipe 曾就职于 GE Digital 和 SLB,专注于工业应用中的建模和优化产品。
Shrivu Shankar
Shrivu 是 Abnormal AI 的 AI 战略副总裁,负责领导 AI 转型,并推动 Agent 系统在网络安全和软件开发中的实用应用。作为一名机器学习工程师,他专长于构建 AI 原生工作流和多 Agent 系统。
English / 原文
AI agents now run in production at a scale of billions of operations a day, and a recurring architectural pattern has surfaced: agents need a compute scratch pad. Not only for coding tasks, but for data aggregation, analysis, verification, and any workflow where semantic reasoning alone isn’t enough.
Abnormal AI, a behavioral security service that protects more than 25 percent of the Fortune 500, has deployed Amazon Bedrock AgentCore Code Interpreter, a capability of Amazon Bedrock AgentCore. Abnormal AI uses it for the agents that support its real-time inline email threat detection. These systems run in production today, processing billions of messages and executing agent-driven code at that same scale to detect and block threats inline, before they reach the inbox.
This work is part of how Abnormal AI builds software. Today, 80 percent of their code changes are built using an agent in some way, and 40 percent are built end-to-end by a background agent (fully AI built, not AI assisted). Their use of AgentCore Code Interpreter for threat detection reflects the same AI-native approach applied to their production runtime.
In this post, we share how Abnormal AI architected these systems, the design decisions behind their sandbox approach, and practical lessons for builders deploying Code Interpreter at scale.
What is Amazon Bedrock AgentCore Code Interpreter?
Amazon Bedrock AgentCore Code Interpreter provides a fully managed, serverless runtime for agents to execute code dynamically. Key characteristics include:
- Ephemeral MicroVM sessions: configurable time-to-live from 15 minutes (default) up to 8 hours for long-running tasks.
- Security: sessions run in secure sandboxes with full separation at the host operating system level, designed to help prevent inadvertent disclosure between sessions.
- Flexible networking: configurable for sandbox virtual private cloud (VPC) mode, or public internet access.
- File handling: up to 100 MB through the API directly, or connect to Amazon Simple Storage Service (Amazon S3) for larger datasets.
- Preloaded runtimes: Python and
Node.jsenvironments with common visualization, statistics, and data processing libraries. - Built-in observability: logs sent to Amazon CloudWatch and AWS CloudTrail for monitoring.
Critically, Code Interpreter is exposed as an API. This means it doesn’t dictate the agent’s workflow. Instead, it provides a box where the agent can run commands, upload files, and retrieve results. For teams with existing agent infrastructure, this plug-and-play design makes the integration straightforward.
Figure 1: Amazon Bedrock AgentCore Code Interpreter architecture, where the agent invokes the Code Interpreter API to provision an ephemeral MicroVM sandbox session for code execution, file input and output, and result retrieval
Why agents need a compute scratch pad
Large language models (LLMs) excel at reasoning and semantic coherence, but many real-world operations don’t map to semantic reasoning:
- Basic math and counting: “How many phishing email did we detect in the past hour?” requires computation, not language generation.
- Data processing and visualization: transforming raw data into charts, PDFs, or structured reports.
- Code verification: running unit tests, linting, and integration tests to validate agent-generated outputs.
By pairing a large language model with Code Interpreter, you enhance the agent’s capabilities beyond what reasoning alone can achieve.
“Pretty much any agent, whether it’s writing code or not, needs a code interpreter sandbox that allows it to actually crunch data and come to answers.”
— Shrivu Shankar, VP of AI Strategy, Abnormal AI
Abnormal AI’s architecture: Three-tiered detection at billion-message scale
Abnormal AI processes billions of email messages through a three-tiered detection architecture, as shown in Figure 2.
Figure 2: Abnormal AI’s three-tiered email detection pipeline, with Tier 1 (heuristics, billions/day), Tier 2 (machine learning models, millions/day), and Tier 3 (inline agents with Code Interpreter, tens of thousands/day), where each tier handles progressively harder cases that the previous tier was unconfident about
Tier 1 — high-volume lightweight classification (billions/day)
Small models, heuristic rules, and lightweight classifiers (logistic regressions) handle the largest volume of traffic. At this scale, it’s both cost-prohibitive to run larger models and unnecessary. Most messages can be classified without deep analysis.
Tier 2 — medium models for uncertain cases (millions/day)
Messages that Tier 1 is unconfident about flow into deep learning and machine learning (ML) models that perform more behavioral signal analysis.
Tier 3 — inline agents with Code Interpreter (tens of thousands/day)
The hardest cases, which would typically require a human analyst to evaluate, are processed by inline agents. These agents receive the threat intelligence data and use a sandbox to analyze it, writing scripts dynamically. They then evaluate how it fits into the overall behavioral model and make a determination. Misclassifications are handled by a separate system that learns and improves the system. A variety of monitoring systems verify the live system.
The analyst agent — batch intelligence
Beyond the real-time classification pipeline shown in Figure 2, Abnormal deploys an analyst agent that operates in batch mode (Figure 3):
- Ingests misclassifications and tuning signals from its detection pipeline.
- Identifies patterns and trends across large message sets.
- Autonomously writes draft candidate heuristics for Tier 1, operating on Abnormal AI’s own detection-pipeline features and signals.
- Improved models for Tier 2.
- Runs on the scale of approximately 100 batch jobs per week.
Figure 3: The analyst agent feedback loop, where the batch agent ingests misclassifications from the real-time pipeline, analyzes patterns using Code Interpreter sessions, and feeds improved heuristics and models back into Tier 1 and Tier 2
These batch jobs can run for more than 30 minutes with Code Interpreter sessions maintained throughout. They can also span day-long operations where the agent uses Code Interpreter intermittently. For example, it runs a session, trains a model externally, then re-invokes Code Interpreter to process the result.
Security: Zero-trust sandbox design
Abnormal chose the sandbox (no egress) configuration for Code Interpreter driven by two considerations:
- Reproducibility – Because the sandbox has no external network access, nothing outside Abnormal AI’s control can influence the agent’s behavior during that session. The environment is designed to be fully deterministic.
- Data exfiltration prevention – threat intelligence data enters the sandbox for analysis. Even if the agent becomes malicious through prompt injection or stochastic behavior, it is designed to prevent the exfiltration of that data to the internet.
Additional security practices:
- Controlled data ingestion: intentional about what types of data enter Code Interpreter and what write actions are permitted.
- Subprocessor alignment: Code Interpreter operates under the existing AWS subprocessor relationship and reduces compliance overhead.
- Network isolation layering: sandbox isolation on top of their existing network-isolated harness provides defense in depth.
Lessons learned and best practices
Several practices emerged from running Code Interpreter in production at Abnormal AI.
1. Give the agent what it wants
Agents perform better with a lightweight, general harness rather than rigid step-by-step workflows. Provide high-level principles for solving a problem and let the agent use its intelligence to determine the approach.
2. Every agent needs a scratch pad
Code Interpreter isn’t only for coding agents. Security agents analyzing email benefit from compute scratch pads for data aggregation, pattern analysis, and verification.
3. Use programmatic verifiers as guardrails
Agents deliver higher quality outputs when they have programmatic verification tools. Unit tests, integration tests, and linting allow the agent to self-test within the sandbox before delivering final results.
4. Use file systems as recovery points for long-running tasks
For operations exceeding the Code Interpreter session time (for example, model training), use the file system as a checkpoint. Run Code Interpreter for computation, persist state to files, perform long-running operations externally, then re-invoke Code Interpreter to process results. The analyst agent (Figure 3) uses this pattern for day-long model training operations.
Conclusion
Abnormal AI’s implementation demonstrates a key insight for production agent systems: Code Interpreter is not merely a coding tool. It’s fundamental infrastructure that agents use to reason computationally. By combining the managed, secure sandbox of AgentCore Code Interpreter with their own lightweight agent harness, Abnormal achieves:
- Zero-trust security posture through sandbox isolation helping prevent data exfiltration.
- Billion-message scale by reserving agent compute for the hardest cases (Figure 2).
Whether you’re building security agents or a system where agents need to crunch data and verify their own outputs, the pattern is clear. Give your agents a scratch pad and trust their evaluations more than you trust their assertions.
Next steps
- Get started with Amazon Bedrock AgentCore Code Interpreter.
- Explore AgentCore capabilities and other tools (Gateway, Memory, Runtime, Identity).
- Learn more about Abnormal AI at abnormalsecurity.com.
Abnormal AI is an AWS customer. The views and opinions expressed in this post are those of the customer and don’t necessarily reflect the views of Amazon Web Services.
About the authors
Aswin Vasudevan
Aswin is a Senior Solutions Architect for Security, ISV at AWS. He is a big fan of generative AI and serverless architecture and enjoys collaborating and working with customers to build solutions that drive business value.
Felipe Lopez
Felipe is a Principal AI/ML Specialist Solutions Architect at AWS. Prior to joining AWS, Felipe worked with GE Digital and SLB, where he focused on modeling and optimization products for industrial applications.
Shrivu Shankar
Shrivu is VP of AI Strategy at Abnormal AI, where he leads AI transformation and advances practical applications of agentic systems in cybersecurity and software development. A machine-learning engineer by background, he specializes in building AI-native workflows and multi-agent systems.