🔶 在 Databricks 数百万行代码库上评测编程 Agent
英文标题:🔶 Benchmarking coding agents on Databricks' multi-million line codebase
Databricks 基于内部工程师的真实 PR 任务构建了编程基准,评估了 OpenAI、Anthropic 和开源模型在数十种语言构成的数百万行代码库上的表现。结果显示,帕累托前沿需要混合不同模型才能获得最佳性价比;开源模型 GLM 5.2 已进入顶级能力梯队,且单任务成本低于 Opus 4.8;按 Token 价格预估总成本并不可靠,不同 harness(如 Claude Code 与 Pi)可导致两倍以上成本差异。这些发现帮助团队避免模型锁定,并启发了基于 Unity AI Gateway 和 Omnigent 的智能路由优化,使开发者能更高效地使用编程 Agent。
 89.3 KB
 84.6 KB
 49.2 KB
 11.2 KB
 13.1 KB
 62.5 KB
 30.9 KB
 59.6 KB
 39.0 KB
 914 B
 1.3 KB
 1.8 KB
 66.2 KB
中文
在 Databricks,随着我们大力采用 AI 进行工程开发,我们构建软件的方式正在迅速变化。过去一年中,用于代码编写的模型和配套工具 (harness) 的生态急剧扩展,为开发者提供了比以往更多的选择。随着选项增多,了解哪些编程 Agent 在实际编码任务中表现最佳,以及任务表现如何随价格变化,变得愈发重要。
本文分享我们在 Databricks 内部构建的编程基准测试的结果和方法,该基准基于工程师在 Databricks 代码库上执行的实际编码任务对工具进行评估。这些任务涉及对包含数百万行代码的代码库进行编辑,覆盖多种流行语言(Python、Go、TypeScript、Scala 等),并且任务和解决方案都经过仔细审查以确保准确性。这并非为了面面俱到,但这项实践带来的洞察已经让我们工程团队在使用编程 Agent 时效率显著提升。以下图表展示了模型和 harness 在整体基准测试中的得分:
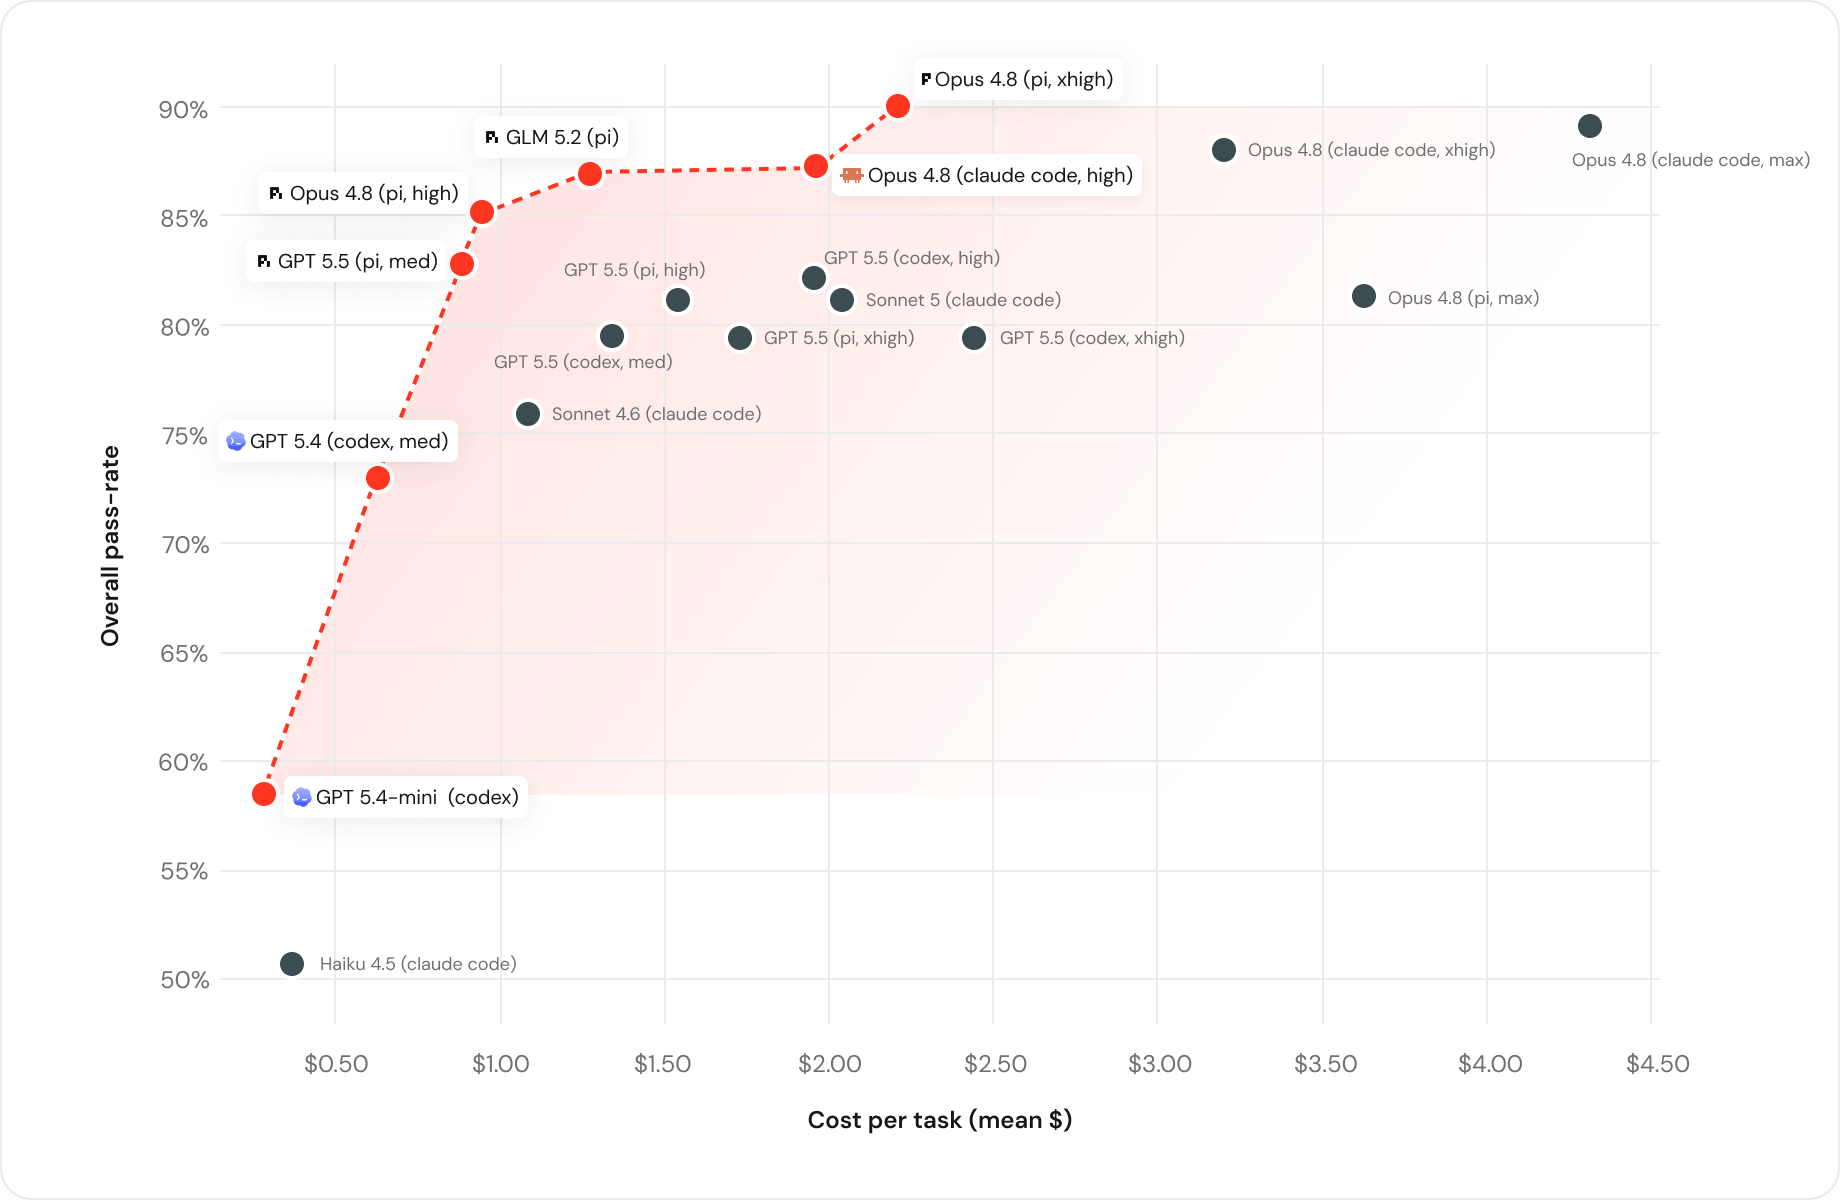
图1:基准测试中的成本与性能对比
我们分析的主要结论如下:
- 编程任务的帕累托前沿(即给定成本下的最佳质量)包含了来自 OpenAI、Anthropic 以及 开源的模型。这意味着,今天只有混合使用多种工具才能获得前沿性能。
- 开源模型,尤其是 GLM 5.2,现已能够处理最高难度的任务。
- 模型的 Token 定价并不能很好地预示端到端任务的实际成本。较大的模型可能 Token 效率高得多,总成本更低。
- 调用模型的 harness 对成本和质量有巨大影响。许多情况下,像 Pi 这样的简洁 harness 在我们的工作负载上表现最佳。
让我们逐一深入探讨。
模型可大致分为“能力梯队”
某些具体结果差几个百分点往往会在实际任务中相互抵消。我们更关注能帮助我们在不同任务中选择模型的主题模式。实际上,结果清晰地显示出模型和 harness 聚类为三个能力梯队。

图2:整体结果中出现了三个明显的能力梯队,每个梯队中哪些模型更有效存在细微差异
在性能的高端,我们看到最智能的模型在解决各类问题时非常高效,但它们也极其昂贵。中等和较低智能的模型在常见任务中依然高度有效,并且在许多情况下,它们也便宜得多。
日常工作中,工程师会做很多复杂度差异很大的事:像切换开关或更新配置这类常见操作性任务不需要非常智能的模型,但深层的设计探索则需要。然而,过去我们的默认模型总是最昂贵的那些。根据这一分析,我们决定应该将更多工作推给 Haiku 和 GPT 5.4 Mini 这类级别的模型。
开源模型已具备编程能力
围绕 GLM 5.2 有很多兴奋的声音,我们的结果也表明,GLM 可以成为众多开发者日常主力模型。它进入了最高能力梯队,在质量上与 Opus 4.8 统计持平,但每个任务成本仅 1.28 美元,而 Opus 为 1.94 美元。
GLM 的质量得分与我们从内部试用 GLM 进行日常开发的开发者那里获得的定性反馈一致。由于其出色的日常编码任务表现,我们一直在致力于以最佳性能提供服务给 GLM,而证据表明,现在是时候开始将这些模型作为日常编程的主力部署了。
单任务价格 vs. 单 Token 价格
开发者常通过 Token 成本来大致判断模型完成编码任务时的昂贵程度。然而我们发现,Token 成本往往并不能很好地预示总体任务成本,原因在于模型间的推理效率存在差异。这凸显了进行任务级基准测试的必要性,因为任务的形态和复杂度在不同上下文中可能不同。
例如,Sonnet 5 的每 Token 价格约为 Opus 4.8 的 1.7 分之一,但在我们的任务中,Sonnet 单个任务成本为 2.09 美元,而 Opus 为 1.94 美元,任务完成得分却低了 6 个百分点(81% vs 87%)。这主要是因为 Sonnet 5 花费更长时间、读取更多内容才达到目标,消耗的 Token 数量是 Opus 的 1.9 倍。
Harness 对效率有重大影响
当我们用相同的模型和相同的思考投入量分别通过两个不同的 harness(Claude Code/Codex 与 Pi)运行时,我们观察到每个任务的成本差异很大(某些情况下超过 2 倍),但质量保持不变。主要差异在于每个回合每个 harness 喂给模型的上下文量。

Pi 每次发送的上下文大约只有前者的三分之一。它更好地管理了上下文,保持了更紧凑的工作集,并以更少的运行次数完成任务。

这里得到的经验并非某个 harness 总是更便宜,也不是原生 harness 更差。相反,模型选择只是拼图的一块。正是为了建立这种灵活性,我们投资了 Omnigent,以实现模型和 harness 的无缝切换。
为什么要构建自己的基准?
像 SWE-Bench 和 TerminalBench 这样的公开基准很有用,但它们无法回答我们提出的问题。原因有几个:
- 任务是公开的,因此解决方案会随时间泄漏到训练数据中。
- 我们发现这些结果对我们的代码库不具代表性,我们的代码库涵盖 10 多种语言,以及许多用 Scala、Go、Rust、Java 和 Python、Bazel、Protobuf 等编写的服务。
通过在我们自己的 PR 上构建基准,我们可以更有信心地做出这些决策,确保推行优化时不会阻碍开发者。
我们如何构建基准
我们使用 Unity AI Gateway 捕获所有编码交互的日志,这使我们能够分析工程师使用编程 Agent 处理的任务的复杂度。任务复杂度存在显著多样性,约四分之一被标记为低复杂度工作,约 60% 为中等复杂度。

然而,工程师默认使用昂贵的模型,因此显然存在提升效率的巨大机会。
任务构建
我们的工程师每天合并数千项代码变更,因此我们已经拥有一个很好的构建基础数据集。一个好的拉取请求 (PR) 是丰富的产物,它包含了展示开发者迭代的提交记录、人工审查以及用于验证代码变更是否忠实于意图的测试。然而,我们需要多个质量检查和过滤器,才能从中构建出高质量的基准:
- 时效性: 我们从近期历史中提取,以便任务反映当前的构建方式,包括当前使用的框架、模式和约定。
- 人工编写: 过滤掉了机器人提交、服务账号、完全由 AI 生成的变更以及自动生成的变更。
- 关联高质量测试套件: 我们筛选了包含高质量测试以验证代码变更的 PR。
- 自包含性: 变更局限于少量模块内。
- 代表典型任务: 我们选择了覆盖全栈任务分布的 PR:Scala 后端服务、Rust 系统代码、React 和 TypeScript 前端、protobuf 与 gRPC 契约以及 Bazel 配置。

一旦有了候选 PR,我们便专注于构建规格明确的任务,方法如下:
- 提炼意图并总结为提示词。 我们阅读 PR 以理解其实际目的,然后描述我们期望的结果。这通常意味着重写 PR 描述,陈述问题或目标,列出任何约束条件,并移除对解决方案的描述。重要的是,要移除例如“为什么某个 bug 修复是正确的”这类解释,因为这会使任务过于简单。
- 分离相关测试。 非测试文件是模型必须自行重现的变更内容,因此我们将测试文件放在一边,并确保这些文件可以编译。我们的构建系统已能确定哪些测试依赖于原始 PR 中所触及的文件,因此我们完整地运行这些测试目标。
经过这些操作,就生成了基准中的单个任务。以下是一个简化的示例:
尽管我们使用脚本和 AI 生成候选任务,但我们手工评估了每个样本。在某些情况下,我们发现原始 PR 中的测试需要重写,以允许替代实现或使其更严格,这些我们均手动完成(未借助 AI)。同样,我们也发现了一些需要改进任务描述以使其规格明确的情况。

图3:测试套件的前后对比:之前的测试锚定于验证精确字符串匹配,导致模型尝试解决任务时出现一些失败。对于非确定性输出,这不是一个好的测试方法,因此被重写以评估行为。
我们使用标准的开箱即用设置来实例化编程 Agent harness 和模型,并配备 Databricks 工程师可用的所有常见工具。

当 Agent 明确表示已完成任务时,我们对该代码设置了检查点,打上被保留的测试补丁,并评估测试以确定该任务对该模型 + harness 组合是否为“通过”。我们没有使用 LLM 评判正确性,因为我们发现这奖励的是听起来正确,而非实际正确。
额外的防护措施

在早期实验中,部分模型的得分看起来好得令人难以置信,因此我们人工检查了跟踪轨迹,以了解这些 Agent 轨迹中发生了什么。我们看到,由于我们最初的设置,“正确”的实现仍然可以在工作树的 Git 历史中找回!每个任务都源自一个合并提交,因此没有什么能阻止一个带有 shell 的 Agent 在 Git 历史中向前查找以找到它。为了解决这个问题,我们封闭了 Git 历史:在每次运行的持续时间内,我们将工作副本与仓库完全断开。
下一步?
我们从一个简单的问题出发:能否更高效地使用编程 Agent?答案是肯定的,而且因为我们可以数据驱动,我们可以开始构建能力,自动选择合适的模型并追踪效率。
任何公司都可以做到同样的事。任何拥有合并 PR 积压的团队,其实都坐拥一个现成的基准,没有任何模型在此基准上训练过,并由团队自己编写的测试来打分。我们正在积极增加更多任务(尤其是更难的任务),并计划让每个新的 Agent/harness 都通过它,从而对我们的选择更有信心。
在 Databricks,我们一直警惕被锁定,不仅是对供应商,也警惕那些随时间推移使团队灵活性降低的假设。这种直觉塑造了我们对开放格式和标准的早期投入,也塑造了我们如今对 AI 的处理方式:衡量在我们交付的代码上实际有效的方法,为工程师提供在模型间切换和harness 间切换的空间,并配合一致的防护措施,并实施优化以更有效地使用 AI。
在后续博客中,我们将进一步介绍如何利用 Unity AI Gateway 和 Omnigent 中的智能路由功能,帮助我们的开发者使用最智能的 Agent,同时保持高效。
English / 原文
At Databricks, the way we build software is changing quickly as we aggressively adopt AI for engineering. The landscape of models and harnesses for code authoring has rapidly expanded in the last year, giving developers more choices than ever. With more options, it has become increasingly important to understand which coding agents offer the best performance on real-world coding tasks as well as understanding how task-performance varies with price.
This article shares the results and methodology of the internal coding benchmark we built at Databricks, which evaluates tools on actual coding tasks our engineers performed on the Databricks codebase. Tasks featured edits against a multi-million line codebase covering many popular languages (Python, Go, Typescript, Scala, etc.) and both tasks and solutions were carefully reviewed to ensure accuracy. This isn't meant to be comprehensive, but the exercise surfaced insights that have already made our engineering team meaningfully more efficient with coding agents. Below, you can see how models and harnesses scored on the overall benchmark:
Figure 1: Cost vs. Performance on our benchmark
The main conclusions from our analysis were:
- The Pareto frontier for coding tasks (i.e. best quality for a given cost) includes models from OpenAI, Anthropic, and open source. This means today, only a mix of tools can provide frontier performance.
- Open models, and GLM 5.2 in particular, are now able to handle even the highest level of task difficulty.
- The token price of a model is a poor indicator of actual costs incurred on end-to-end tasks. Larger models can be far more token efficient and have lower overall costs.
- The harness a model is called from dramatically impacts cost and quality. In many cases, simple harnesses like Pi performed best on our workloads.
Let’s dive a bit deeper on each one.
Models cluster into rough “capability tiers”
Specific results being a couple points off can often even out in real world tasks. We focused more on the thematic patterns that help us reason about which models to use for various tasks. In fact, the results showed clear clustering of the models and harnesses into 3 capability tiers.
Figure 2: Three distinct capability tiers emerged in our overall results, with nuance in which models were effective in each group
At the upper end of performance, we see that the most intelligent models are very effective at solving all kinds of problems, but they’re very expensive. Medium and lower intelligence models are still highly effective at the common tasks, and in many cases, they’re also significantly cheaper.
Day to day, engineers do a lot of different things that vary significantly in complexity: common operational tasks like flipping a flag or updating configs don’t require extremely intelligent models, but deeper design explorations do. However, in the past, our default models were always the most expensive ones. Based on this analysis we determined we should push more work to the Haiku and GPT 5.4 Mini class of models.
Open models are here for coding
There’s been a lot of excitement about GLM 5.2, and our results showed evidence that GLM can be a daily driver model for a lot of our developers. It landed in the top capability tier, statistically tied with Opus 4.8 on quality, but costing $1.28/task against Opus’s $1.94.
The GLM quality scores are consistent with qualitative feedback we’ve gotten from internal developers who have been piloting GLM for daily development. Because of its great performance for everyday coding tasks, we’ve been focused on serving GLM with the best performance, and the evidence shows it’s time to start deploying these as daily drivers for coding.
Price-per-task vs price-per-token
Developers often eyeball token costs to determine how expensive a model will be when completing coding tasks. We found, however, that token costs are often a poor indicator of overall task costs, due to variance in reasoning efficiency amongst models. This underscores the need for task-level benchmarking, since task shape and complexity may be different in different contexts.
As an example, Sonnet 5 is ~1.7x cheaper per token than Opus 4.8, but, on our tasks, we found that Sonnet cost $2.09/task vs Opus’s $1.94, while scoring six points lower on task completion (81% vs 87%). This was mostly because Sonnet 5 worked longer and read more to get there, consuming 1.9x more tokens.
Harnesses have a major impact on efficiency
When we ran the same model with the same thinking effort through two different harnesses (Claude Code/Codex vs Pi), we observed that the cost per task differed significantly (more than 2x in some cases), while quality remained the same. The main difference came down to how much context each harness fed the model on each turn.
Pi sent about 3x less context per turn. It managed context better, keeping a tighter working set and finishing the tasks in fewer runs.
The lesson here isn’t that one harness is always cheaper or that native harnesses are worse. Instead, model choice is only one piece of the puzzle. Establishing this flexibility is why we invested in Omnigent to make mode-and-harness swaps seamless.
Why build your own benchmark?
Public benchmarks like SWE-Bench and TerminalBench are useful, but they can’t answer the questions we had. There are a few reasons for this:
- The tasks are public, so the solutions leak into training data over time.
- We found the results weren’t representative for our codebase, which spans 10+ languages and many services written in Scala, Go, Rust, Java and Python, Bazel, Protobuf, and more.
By building a benchmark on our own PRs, we can make these decisions with higher confidence that we won’t hamper our developers by rolling out optimizations.
How we built the benchmark
We used Unity AI Gateway to capture logs of all our coding interactions, which enabled us to analyze the complexity of the tasks engineers tackle using coding agents. There was a significant diversity in the task complexity, and about a quarter were tagged as low-complexity work and ~60% as medium complexity.
However, expensive models are the default models engineers use, so there was clearly a huge opportunity for improving efficiency.
Task Construction
Our engineers merge thousands of code changes a day, so we already have a great dataset to build off. A good pull request is a rich artifact, with commits that show iteration from the developer, review by humans, and tests that help verify a code change is faithful to its intent. However, we needed several quality checks and filters to construct a high-quality benchmark out of them:
- Recency: We pull from recent history so the tasks reflect how we build today, including the frameworks, patterns, and conventions currently in use.
- Human written: Bot commits, service accounts, fully AI generated changes, and auto-generated changes were filtered.
- Associated high quality test suite: We filtered for PRs that included high-quality tests for validating the code changes.
- Self-contained: The changes were confined to a few modules.
- Representative of typical tasks: We selected PRs from a distribution of tasks across the full stack: Scala backend services, Rust systems code, the React and TypeScript frontend, protobuf and gRPC contracts, and Bazel configs.
Once we had candidate PRs, we focused on constructing well-specified tasks by:
- Gleaning the intent and summarizing it as a prompt. We read the PR to understand what it was actually for and then describe the outcome we want. Usually, that meant rewriting the PR description by stating the problem or goal, naming any constraints, and removing the description of the solution. It’s important to remove, for example, explanations of why a bug fix is the right one, since that makes the task too easy.
- Splitting out the relevant tests. The non-test files were the change the model has to reproduce on its own, so we set the test files aside and ensured we could compile that. Our build system can already determine which tests depend on the files that were touched in the original PR, so we ran all those test targets in full.
What came out of this exercise was a single task in the benchmark. Here’s a simplified example:
While we used scripting and AI to generate candidate tasks, we evaluated each sample by hand. In some cases, we found that tests in the original PR needed to be rewritten to allow for an alternative implementation or to be more rigorous, which we did manually (without AI). Similarly, we also found cases that required improving the task description to make them well-specified.
Figure 3: A before-and-after from our test suite: the previous test anchored on verifying exact string match which resulted in some failures when the model tried to solve the task. This wasn’t a great way to test non-deterministic output so it was rewritten to grade behavior instead.
We instantiated the coding agent harnesses and models using their standard, out of the box setups, with all common tools that Databricks engineers would have available to them.
When the agent explicitly said that it had completed the task, we checkpointed that code, patched the tests that were held out, and evaluated the tests to determine whether that task is a “pass” for that model + harness combination. We did not use an LLM judge to evaluate correctness, since we’ve found that this rewards sounding right over being right.
Additional Guardrails
In our early experiments, a few model scores looked too good to be true, so we manually inspected the traces to understand what happened in these agent trajectories. What we saw was that due to our original setup, the “correct” implementation was still recoverable in the Git history of the worktree! Every task had originated from a merged commit, so nothing stopped an agent with a shell from walking forward through git history to find it. To fix this issue, we sealed git history: for the length of each run, we cut the working copy off from the repository entirely.
What’s next?
We started with a simple question: can we use coding agents more efficiently? The answer is a definitive yes, and because we can be data driven, we can start building capabilities to select the right models automatically and track efficiency.
Any company can do the same. Any team with a backlog of merged PRs is sitting on a benchmark already that no model has trained on, graded by the tests your team wrote. We’re actively adding more tasks (especially harder ones), and we plan to run every new agent/harness through it and feel more confident about our choices.
At Databricks, we’ve always been wary of lock-in, not just to vendors, but to assumptions that make teams less flexible over time. That same instinct shaped our early bets on open formats and standards, and it shapes how we’re approaching AI now: measure what actually works on the code we ship, give engineers room to move across models and harnesses with consistent guardrails, and do optimizations to use AI effectively.
In a follow-up blog, we’ll talk more about how we’re using intelligent routing features in Unity AI Gateway and in Omnigent to help our developers use the most intelligent agents while being efficient.