全新 GPT-5.6 系列:Luna、Terra、Sol
英文标题:The new GPT-5.6 family: Luna, Terra, Sol
OpenAI 今日正式发布旗舰模型 GPT-5.6,包含 Luna、Terra、Sol 三种尺寸,定价分别为每百万输入/输出令牌 1/6 美元、2.5/15 美元、5/30 美元。在 Agent 长期工作流基准测试中,三款模型均超越 Claude Fable 5,Sol 取得 53.6 分并指出 SWE-Bench Pro 存在约 30% 任务缺陷。本次更新还引入了程序化工具调用、多智能体、提示缓存断点等新 API 特性,显著提升了模型的可控性与成本效率。
 167.8 KB
 95.4 KB
中文
全新 GPT-5.6 系列:Luna、Terra、Sol
2026年7月9日
OpenAI 的最新旗舰模型已于今晨全面上线,提供三种尺寸:Luna、Terra 和 Sol(从小到大)。
新模型每百万输入/输出令牌的定价分别为 Luna $1/$6、Terra $2.50/$15、Sol $5/$30。作为对比,Claude Opus 系列为 $5/$25,Claude Fable 5 为 $10/$50,但每百万令牌的价格如今已不能完全说明问题,因为同一任务不同模型消耗的推理令牌数量可能相去甚远。
三款模型的知识截止日期均为 2026 年 2 月 16 日,拥有百万令牌上下文窗口,最大输出 128,000 枚令牌。
OpenAI 最重磅的基准测试声明集中在长时间运行的 Agent 性能上,其中一项基准显示三款模型均优于 Claude Fable 5:
我们训练 GPT-5.6 从每一枚令牌中获取更多有效工作。在覆盖 55 个领域的长时间专业工作流评测 Agents’ Last Exam 中,GPT-5.6 Sol 创下 53.6 的新纪录,比 Claude Fable 5(自适应推理)高出 13.1 分。即便使用中等推理强度,它仍以大约四分之一的预估成本领先 Fable 5 达 11.4 分。这种效率同样延伸至更小的模型,而小模型对于让智能更加充裕和普惠至关重要:GPT-5.6 Terra 和 GPT-5.6 Luna 以约十六分之一的成本超越 Fable 5。
有趣的是,OpenAI 自我报告的另一项基准 SWE-Bench Pro 中,Fable 5 以 80% 大幅领先 GPT-5.6 Sol 的 64.6%。这或许可以解释为何 OpenAI 选择在昨天发布这篇文章,专门指出他们在审核该基准时发现的 SWE-Bench Pro 问题:
鉴于这些结果,我们估计约 30% 的 SWE-Bench Pro 任务存在问题,并建议模型开发者仔细核查结果。
我曾提前体验过 GPT-5.6 Sol——它无疑非常强大,但在我一直用 Anthropic 模型处理的那类复杂编码任务中,尚未觉得它比 Fable 更出色。
一如往常,GPT-5.6 的模型使用指南包含了最有趣的细节。其中有一系列新 API 特性值得深入探索(或许我也会为 LLM 添加支持),包括:
- 程序化工具调用 允许模型“组合并运行编排工具调用的 JavaScript”——这听起来或许能弥合 MCP 与可以灵活组合 CLI 工具的完整终端会话之间的鸿沟。这也让人联想到 Anthropic 为其网页搜索工具添加的动态过滤机制,该机制允许在单次模型回合中对网页结果执行代码。
- 多智能体 使模型能够“启动子代理以并行、专注地工作”——子代理模式现已内置到核心 API 中。
- 提示缓存断点 将 Claude 风格的提示缓存引入 OpenAI,允许你显式指定缓存断点位置,而不是依赖 API 自动检测。我个人更偏好自动检测(OpenAI 仍然支持),但对于愿意投入工程精力的团队来说,这里无疑存在优化成本的空间。
- 现在你可以为图像请求设置
detail: original,在处理之前不再对图像进行任何缩放。
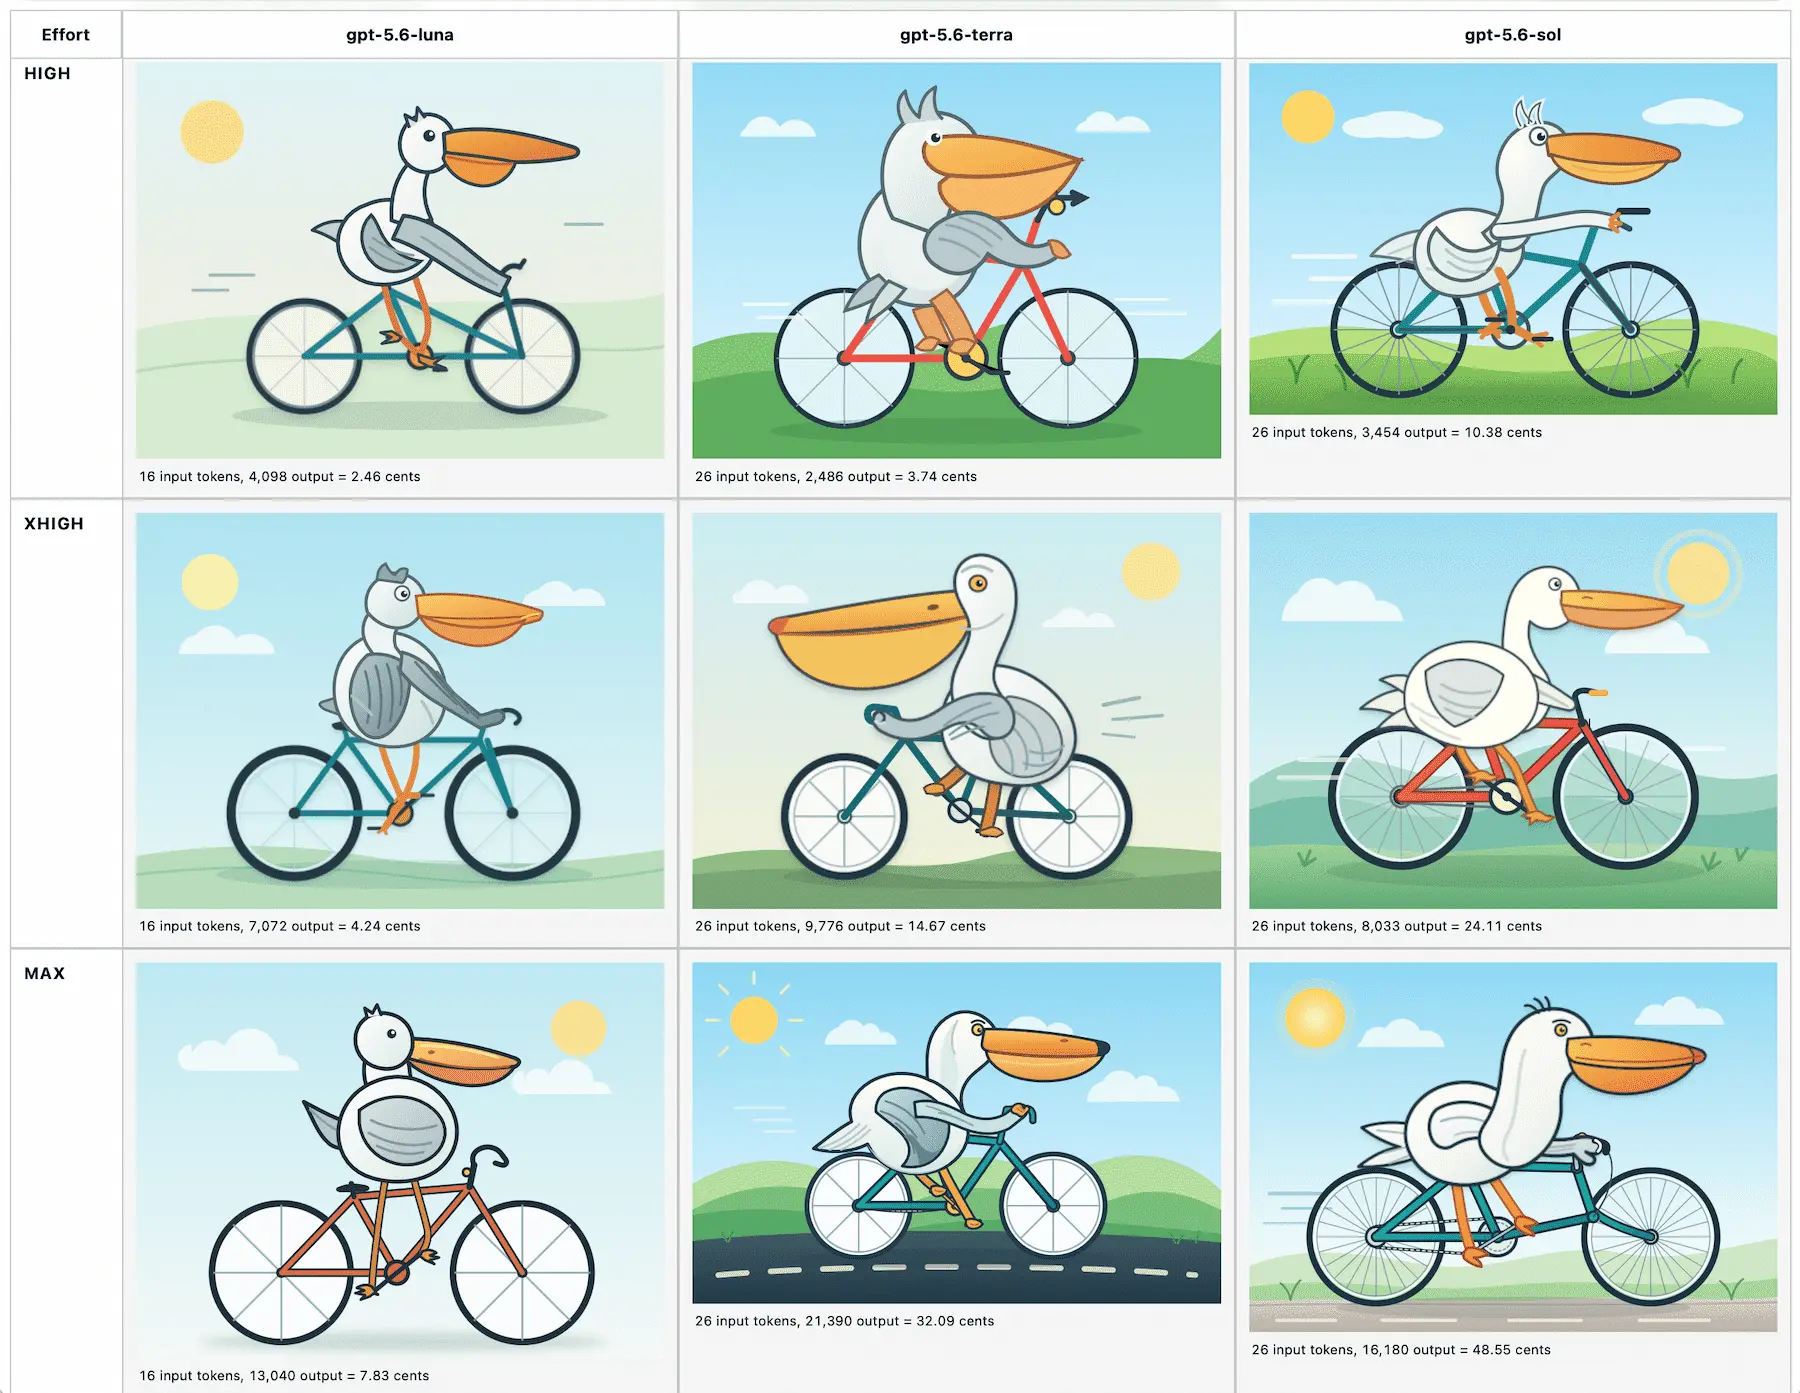
这里有一个包含 18 种不同鹈鹕的完整页面——展示了三款模型在无推理、低、中、高、超高、最高推理努力下的表现。页面还列出了令牌量和计算后的成本——最便宜的是 gpt-5.6-luna 零推理强度,仅 0.71 美分,最昂贵的则是最高推理级别下的 gpt-5.6-sol,花费 48.55 美分。
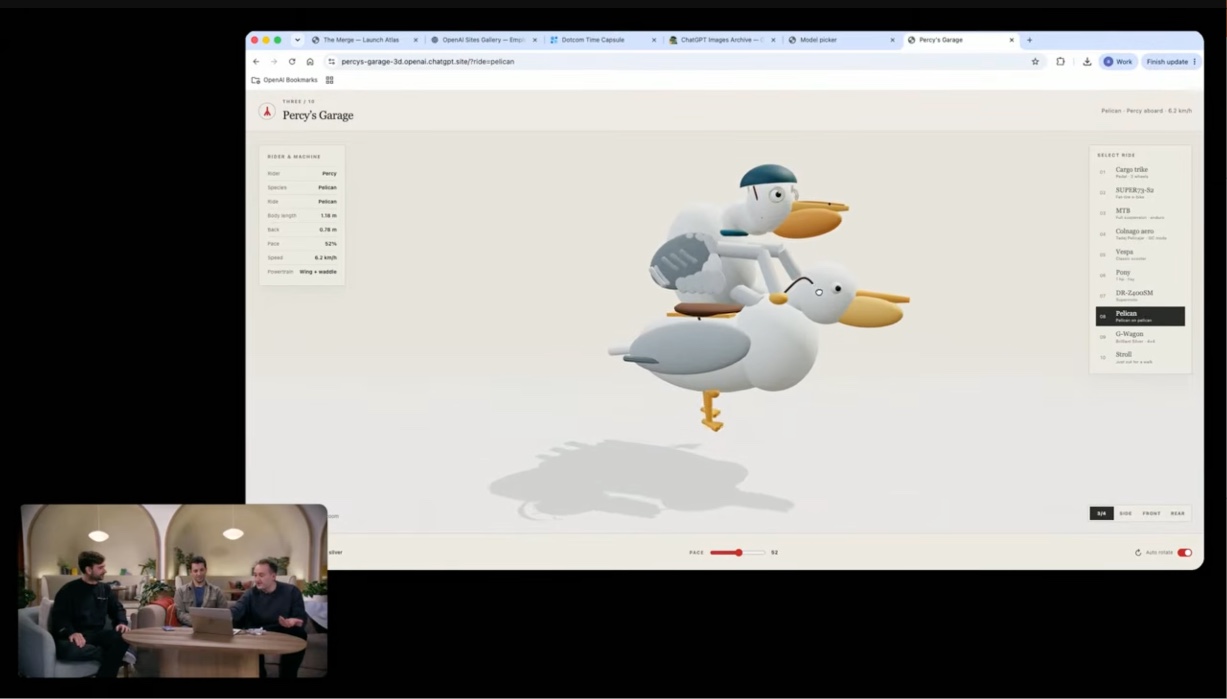
还有更多关于鹈鹕的趣闻:如果你跳转到今早直播的 17 分 50 秒处,就能看到 OpenAI 自家的演示——3D 鹈鹕骑着三轮车、自行车、小马,甚至骑着另一只鹈鹕!
English / 原文
The new GPT-5.6 family: Luna, Terra, Sol
9th July 2026
OpenAI’s latest flagship model hit general availability this morning, and comes in three sizes: Luna, Terra, and Sol (from smallest to largest).
The new models are priced per 1M input/output tokens as Luna $1/$6, Terra $2.50/$15, Sol $5/$30. For comparison, the Claude Opus series are $5/$25 and the Claude Fable 5 is $10/$50, but price-per-million tokens doesn’t tell us much now that the number of reasoning tokens can differ so much between models for the same task.
All three models have a February 16th 2026 knowledge cutoff, a million token context window, and 128,000 maximum output tokens.
OpenAI’s biggest benchmark claim concerns long-running agentic performance, with one benchmark showing all three models outperforming Claude Fable 5:
We trained GPT-5.6 to get more useful work from every token. On Agents’ Last Exam, an evaluation of long-running professional workflows across 55 fields, GPT-5.6 Sol sets a new high of 53.6, eclipsing Claude Fable 5 (adaptive reasoning) by 13.1 points. Even at medium reasoning, it beats Fable 5 by 11.4 points at roughly one-quarter the estimated cost. That efficiency extends to smaller models, which are essential to making intelligence more abundant and affordable: GPT-5.6 Terra and GPT-5.6 Luna outperform Fable 5 at around one-sixteenth the cost.
Amusingly, one self-reported benchmark that Fable 5 crushed the GPT-5.6 family on was SWE-Bench Pro, where Fable 5 got 80% compared to GUT-5.6 Sol getting 64.6%. This may help explain why OpenAI chose to publish this article yesterday specifically calling out SWE-Bench Pro for problems they found while auditing that benchmark:
In light of these results, we estimate that ~30% of SWE-bench Pro tasks are broken, and advise that model developers carefully examine results
I’ve had some early access to GPT-5.6 Sol—it’s definitely very competent, though so far it hasn’t struck me as better than Fable at the kind of complex coding tasks I’ve been using with Anthropic’s model.
As usual, the model guidance for using GPT-5.6 has the most interesting details. There are a bunch of new API features that I need to explore (and probably add support for in LLM), including:
- Programmatic Tool Calling allows the models to “compose and run JavaScript that orchestrates tool calls”—which sounds to me like it could help bridge the gap between MCPs and full terminal sessions that can compose CLI utilities in useful ways. Also reminiscent of the dynamic filtering mechanism Anthropic added to their web search tool, which allows code execution against web results as part of a single model turn.
- Multi-agent lets the model “spin up subagents for parallel, focused work”—the sub-agent pattern now baked into the core API.
- Prompt cache breakpoints brings the Claude model of prompt caching to OpenAI, letting you be explicit about where the cache breakpoints are rather than relying on the API to detect them automatically. Personally I much prefer automatic detection (still supported by OpenAI), but presumably there are optimization cost savings to be had here if you put the work in.
- You can now set detail: original on image requests to avoid resizing the image at all before it is processed.
Here’s a full page with 18 different pelicans—for reasoning efforts none, low, medium, high, xhigh, and max across the three different models. It also lists their token and calculated costs—the least expensive was gpt-5.6-luna at effort none for 0.71 cents, the most expensive was gpt-5.6-sol at max reasoning level for 48.55 cents.
In further pelican news, if you jump to 17:50 in their livestream from this morning you’ll see OpenAI’s own demo of 3D pelicans riding a tricycle, a bicycle, a pony, and another pelican!