Gemini Live 音频
英文标题:Gemini Live audio
Google 发布了 Gemini 3.8 Live 和 Gemini 3.8 Live Extended Thinking 两款语音到语音模型,其产品形态与 OpenAI 的 GPT-Live 系列相近。作者让 GPT-6 Astra Extra High 根据文档构建了一个浏览器端 Web UI,可选择模型和语音预设、设置系统提示词,并进行可随时打断模型的实时语音对话。该实现不依赖第三方库,直接通过 WebSocket 连接 Gemini API,并使用 Web Audio API 完成音频采集和播放,为开发者提供了一个简洁的 Live API 接入示例。
 79.7 KB
中文
Google 今天发布了 Gemini 3.8 Live 和 Gemini 3.8 Live Extended Thinking——两款语音到语音模型,其产品形态与 OpenAI 的 GPT-Live 系列相似。
我让 GPT-6 Astra Extra High 参考相关文档,为我构建了这个 Web UI,用于试用这些新模型。你可以选择模型和语音预设,输入可选的系统提示词,然后通过浏览器开始语音对话;它还支持在模型说话时打断其回复。
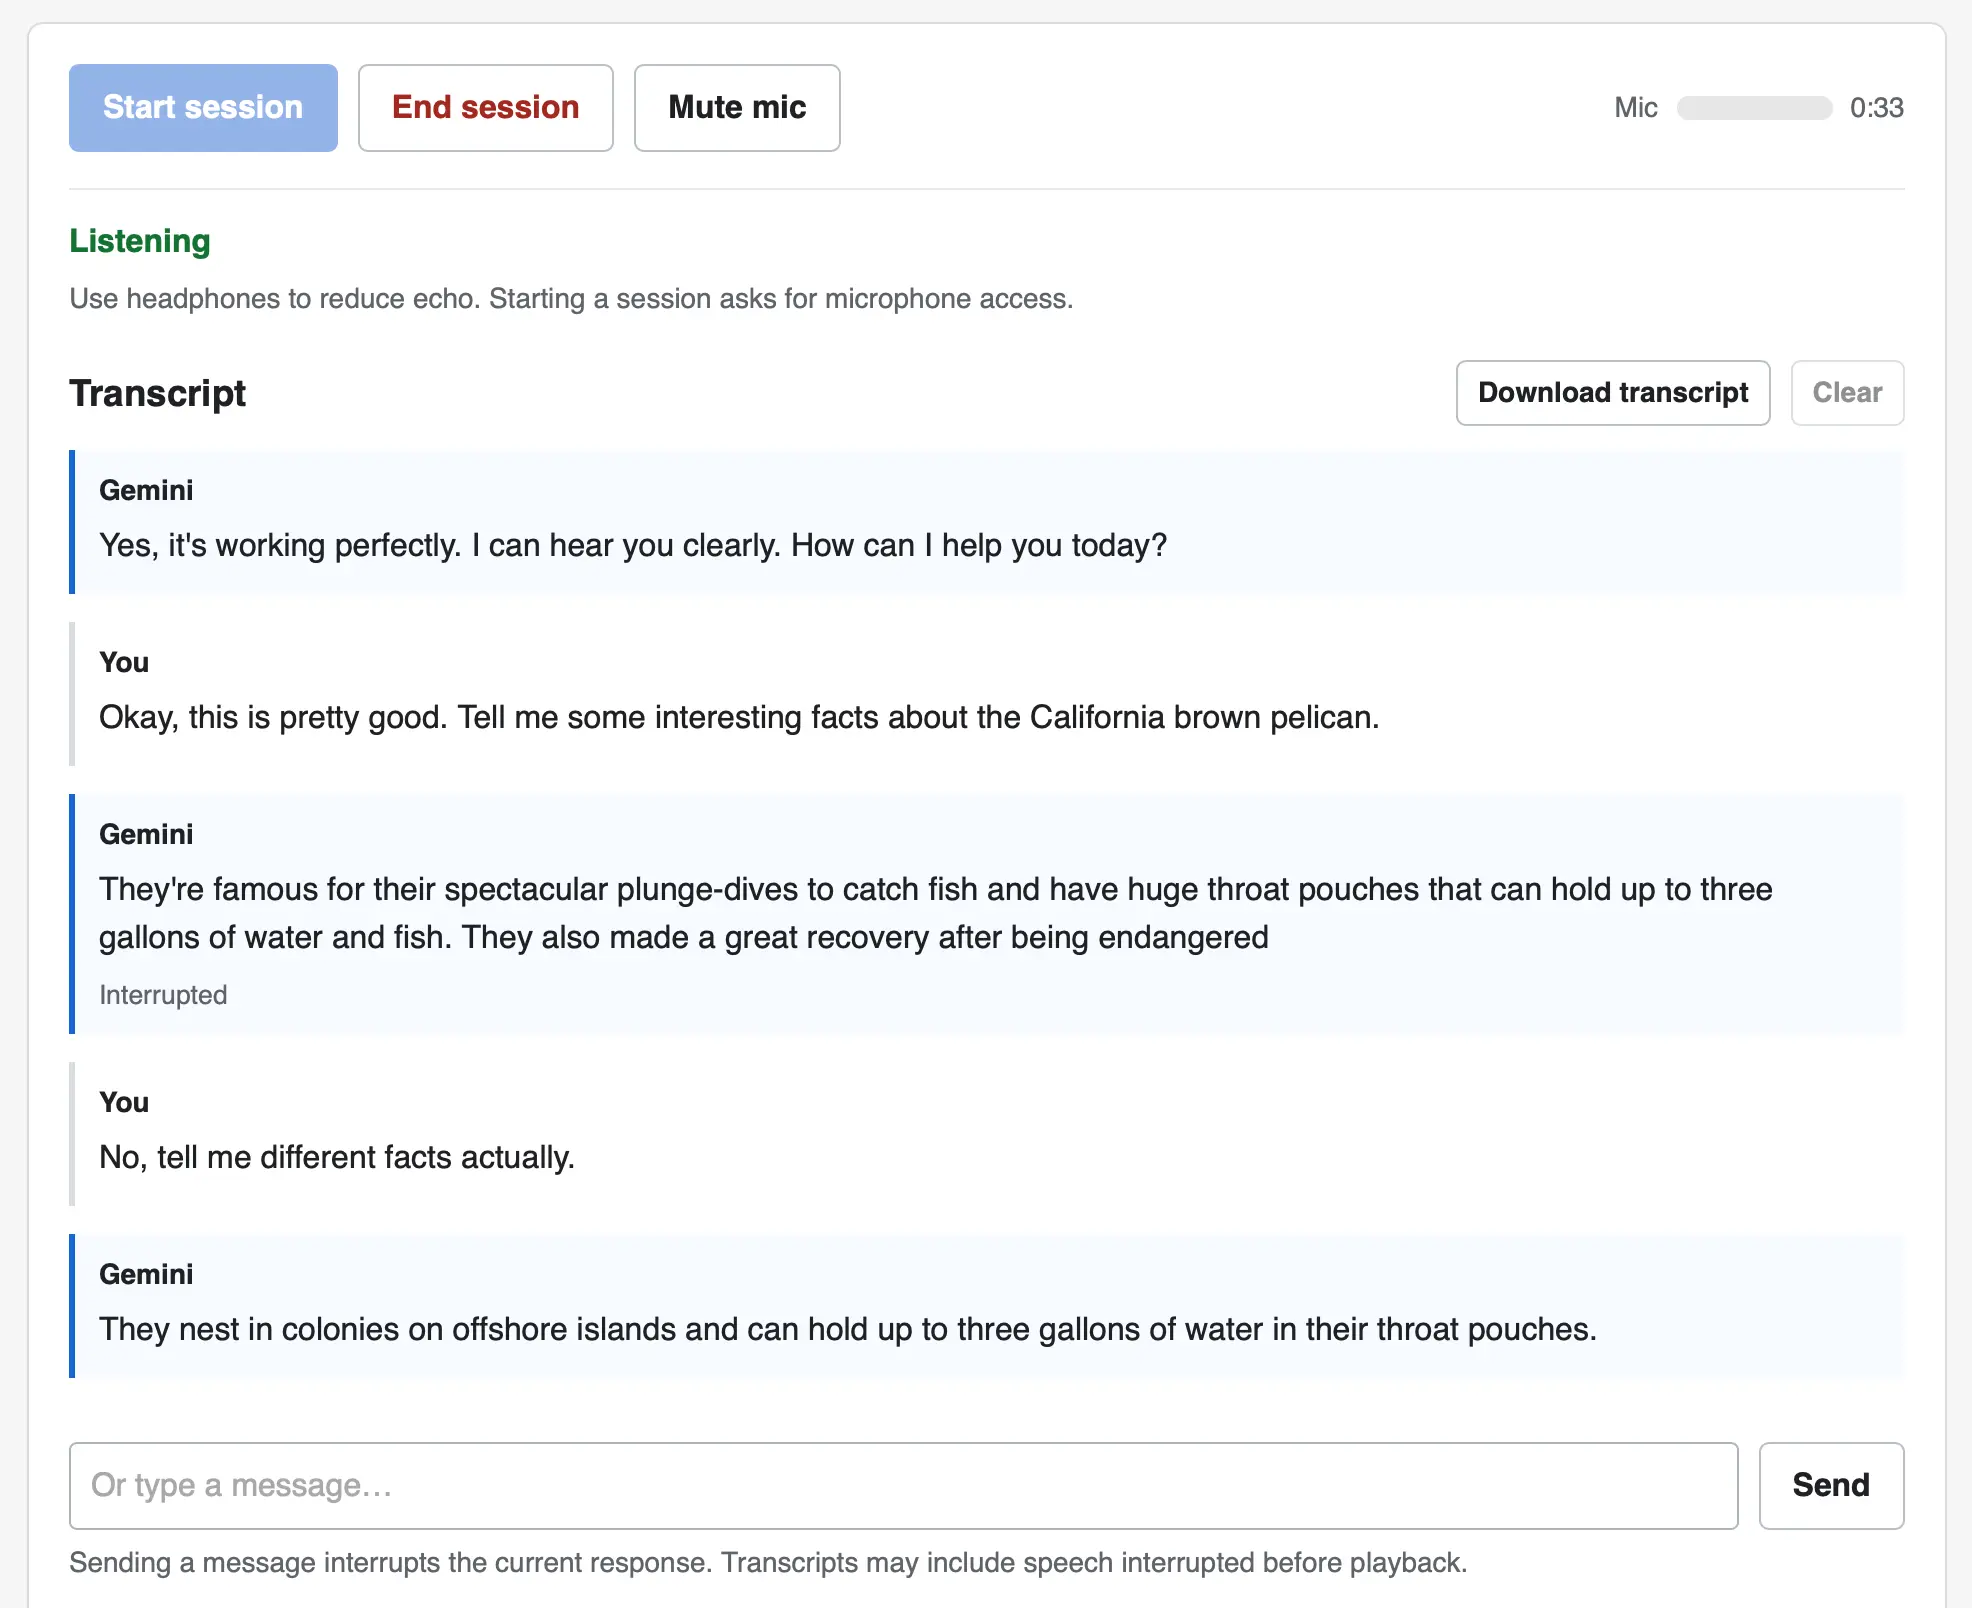
这一实现没有使用任何库。它连接到 wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=... WebSocket 端点,并使用 Web Audio API 的 AudioContext 同时进行音频采集和播放。
以下是用于开始使用该 WebSockets API 的 Gemini Live 教程。
English / 原文
Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family.
I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying out the new models. You can select a model and voice preset, enter an optional system prompt and then start a voice conversation through your browser, including the ability to interrupt the model while it is talking.
The implementation uses no libraries. It connects to the wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=... WebSocket endpoint and uses a Web Audio API AudioContext for both capture and playback.
Here's the Gemini Live tutorial for getting started with that WebSockets API.