为 Amazon Bedrock Knowledge Bases 选择向量存储
英文标题:Selecting a vector store for Amazon Bedrock Knowledge Bases
为 Amazon Bedrock Knowledge Bases 构建 RAG 应用时,向量存储的选择会直接影响检索性能与成本。本文聚焦客户自管模式,对比 Amazon OpenSearch Service、Amazon Aurora PostgreSQL with pgvector 和 Amazon S3 Vectors 三种受支持的后端,并以不同 RAG 用例说明适配场景。针对电商商品目录搜索,文章认为 Amazon OpenSearch Serverless 凭借混合搜索、低毫秒级延迟、复杂过滤与聚合能力更为适合。文中还使用包含 121.6 万余件商品和 9.7 万余条标注查询的 ESCI 数据集,评估不同嵌入维度、数据类型及磁盘优化配置对 NDCG、延迟和索引大小的影响。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 54.2 KB
 96.7 KB
 29.7 KB
 16.5 KB
 19.9 KB
 108.2 KB
中文
使用 Amazon Bedrock Knowledge Bases 构建检索增强生成(Retrieval Augmented Generation,RAG)解决方案时,选择合适的向量存储会影响性能和成本。Amazon Bedrock Knowledge Bases 同时提供完全托管选项,以及由客户自行选择向量存储的客户自管选项。本文聚焦客户自管路径,对三种受支持的后端进行比较: Amazon OpenSearch Service、采用 pgvector 的 Amazon Aurora PostgreSQL 以及 Amazon S3 Vectors。后者是 Amazon Simple Storage Service(Amazon S3)的一项功能。本文将在不同的 RAG 用例中对它们进行比较。
如需了解涵盖全部 AWS 向量解决方案的更广泛指导,请参阅 AWS vector solutions: Build agentic AI where your data lives。如需了解向量数据存储在生成式 AI 应用中的作用,请参阅 The role of vector datastores in generative AI applications。如需获取针对 RAG 向量数据库的规范性指导,请参阅 Choosing an AWS vector database for RAG use cases。
向量数据库如何融入 RAG 解决方案
RAG 架构结合了大语言模型(LLM)与信息检索系统的能力,以生成更准确、更及时且更符合上下文的回答。它基于数学中的向量概念:文本会被转换为能够对应文本语义的向量。对向量执行搜索能够找到与问题语义相近的结果,因此相比关键词匹配,能更有效地捕捉语义相似性。
当用户提交查询时,系统会使用嵌入模型将其转换为向量嵌入。向量数据库中预先处理、分块并以向量嵌入形式存储了文档内容;该数据库会执行相似度搜索,找出其嵌入与查询最相似的文本块。通常,系统会检索排名前 n 的文本块(例如最相似的前五个)来丰富原始查询。这些检索到的文本块会作为额外上下文提供给 LLM,使其能够生成信息更充分、准确度更高的回答。
向量数据库是原始信息与上下文理解之间的关键桥梁。它将非结构化数据转换为可搜索、具有语义意义的知识空间,帮助大语言模型给出更精确、更相关的回答。向量数据库通过将嵌入向量存储在称为向量索引的高效数据结构中实现这一目标;该结构支持快速的高维语义搜索,以及近乎即时地检索语义相似的信息。
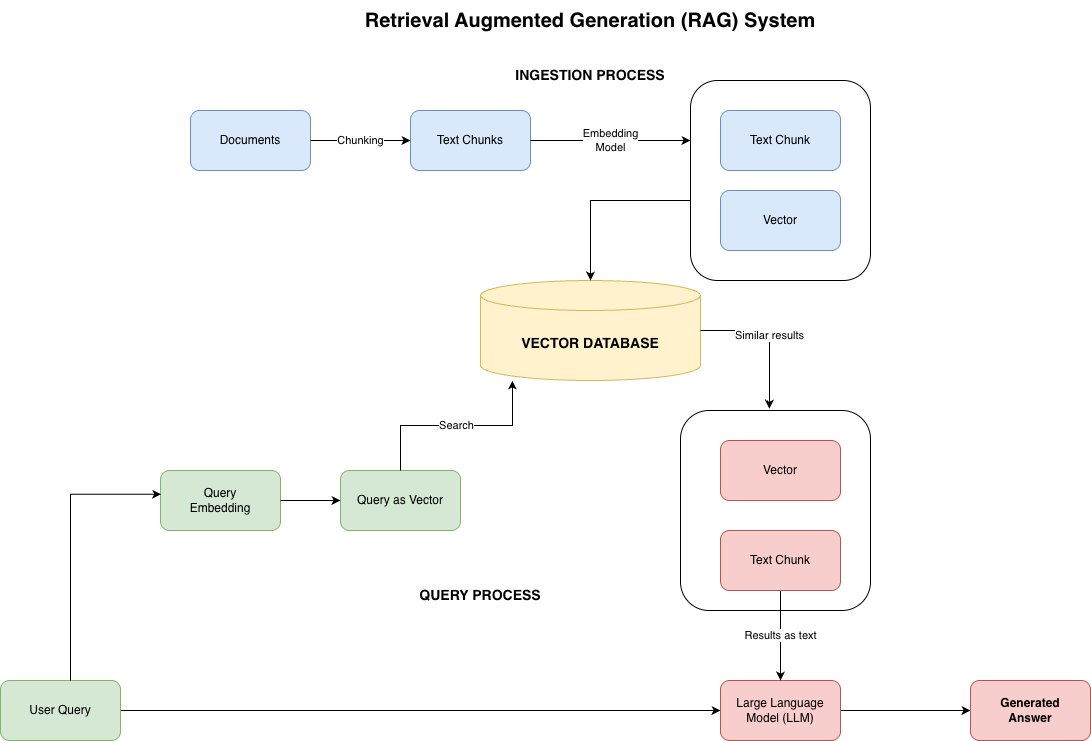
图 1:检索增强生成(RAG)架构。摄取阶段会将文档分块、嵌入并存储到向量数据库中;查询阶段会对查询进行嵌入、检索相似文本块,并将其作为上下文传递给 LLM 以生成回答。
Amazon Bedrock Knowledge Bases 的向量存储后端
采用客户自管(非托管)配置的 Amazon Bedrock Knowledge Bases 支持三种向量存储后端。如需了解覆盖六项服务的完整 AWS 向量产品组合,请参阅 AWS vector solutions: Build agentic AI where your data lives。
Amazon OpenSearch Service 可从内存中的数据获得高速结果。它支持高维向量嵌入,提供托管集群和无服务器部署选项,并具备 k-NN 搜索、结合词法与向量方法的混合搜索等功能。Amazon Bedrock Knowledge Bases 同时支持 Amazon OpenSearch 托管集群和 Amazon OpenSearch Serverless 作为向量存储后端。
采用 pgvector 的 Amazon Aurora PostgreSQL 结合了 Amazon Aurora 高性能关系型数据库能力与 pgvector 的向量相似度搜索功能。它支持多种索引方法(IVFFlat 和 HNSW)、多种距离度量方式(L2、余弦、内积),并且能够处理单精度下最高 2,000 维的向量。
Amazon S3 Vectors 是具备原生向量支持的 AWS 云对象存储服务,旨在以经济高效的方式大规模存储和查询向量嵌入。它可为相似度搜索提供亚秒级查询性能,并且与传统向量数据库相比,最多可将向量存储成本降低 90%。
为了解这些选项在实践中的表现,接下来将考察三种不同的 RAG 用例。每种用例对延迟、成本和搜索有不同要求,我们将据此了解最适合的向量数据库。
用例 1:商品目录搜索
电商平台面临的挑战是:在数千种商品中帮助客户准确找到所需商品。高效的商品搜索工具必须理解自然语言查询,并能够在购物高峰期扩展以处理数千个并发查询,同时保持低延迟。
为什么 Amazon OpenSearch 最适合此用例
Amazon OpenSearch Serverless 非常适合商品目录搜索,因为它能够通过混合搜索功能,将语义理解与传统关键词匹配相结合。处理大型商品目录时,性能至关重要。Amazon OpenSearch Serverless 可在低毫秒级延迟范围内完成向量搜索。
对于电商而言,其特别有价值之处在于内置支持复杂过滤和聚合,可为分面导航提供支撑,例如按价格、品牌或颜色过滤。您还可以从余弦相似度或欧氏距离等多种距离度量中进行选择,根据具体需求微调商品相似度的计算方式。
Amazon OpenSearch Serverless Classic 集合提供多种优化选项,可用于平衡成本与搜索质量,详情见下一节。
**注意:**Amazon Bedrock Knowledge Bases 同时支持 Amazon OpenSearch Serverless 和托管集群。以下基准测试在 Serverless Classic 集合上运行。Amazon OpenSearch Serverless NextGen 集合(于 2026 年 5 月正式发布)尚不兼容 Amazon Bedrock Knowledge Bases Retrieve API。NextGen 通过从索引映射中移除引擎和模式参数来简化索引创建,默认采用 32× 压缩和 GPU 加速索引构建,并支持缩容至零。本篇文章的基准测试使用 Classic 集合,其中会显式配置引擎、模式和 HNSW 参数。托管集群提供额外的调优选项(自动优化、GPU 加速索引和可配置实例规格),可能产生不同结果。
Amazon OpenSearch Serverless 向量搜索的性能分析与优化
Amazon OpenSearch 具有高度可配置性,并提供多项配置选项。选择这些选项时应谨慎,因为它们可能显著影响向量索引性能。本文将考察其中一些针对成本和数据库大小优化的选项,并以量化方式展示其对向量索引性能的影响。
一些常见的优化选项包括:
- 向量嵌入的大小:更大的向量通常可以包含更多有关嵌入文本的语义信息。但它也会带来更高的内存消耗,从而增大向量索引规模和成本。Amazon Titan Text Embedding v2 等现代嵌入模型支持以不同大小的向量嵌入文本(Amazon Titan 支持 1024、512 或 256 维)。对不同大小的嵌入进行性能基准测试很有帮助,可定量衡量其对特定用例性能和成本的影响。有关不同 AWS 区域的模型可用性,请参阅 Supported models by AWS Region in Amazon Bedrock。
- 嵌入的数据类型:我们还可以通过以较低精度的数据类型(例如二进制嵌入)存储嵌入,减小向量索引大小(从而降低成本)。这可以显著减小向量索引的规模。
- 面向磁盘优化的存储:Amazon OpenSearch Serverless Classic 集合提供基于磁盘的向量搜索(
on_disk模式),该模式会在内部应用 32× 二进制量化,并依据从磁盘读取的全精度向量重新评分。这可在降低内存占用的同时保持质量,但代价是更高的延迟。请注意,on_disk要求使用 float 数据类型,且不能与二进制嵌入结合使用。
根据所使用的索引算法,用户还可以配置 HNSW 参数(ef_construction、m),以调整索引构建时间、内存使用量和搜索准确性之间的权衡(实用指导请参阅 A practical guide to selecting HNSW hyperparameters)。此外,Classic 集合支持 Faiss 16 位标量量化,可用于减少内存使用量。选择嵌入维度和数据类型时,需要依据自身的相关性数据进行评估,因为这些选择会改变嵌入空间本身。完成选择后,auto-optimize 功能可通过根据召回率和延迟阈值评估索引配置,在一小时内消除剩余的 HNSW 和量化调优工作(适用于使用 Faiss 引擎的 Amazon OpenSearch Serverless 和托管集群)。
数据集
我们使用 Amazon 提供的大型高难度搜索查询数据集“Shopping Queries Data Set”(ESCI)。该数据集包含 1,215,851 件独特的美国商品(标题、描述、要点和品牌;字符数中位数约为 1,140),以及 97,345 条经过标注的查询。对于每条查询,数据集提供分级相关性标签:完全匹配(Exact,3)、替代品(Substitute,2)、补充品(Complement,1)和不相关(Irrelevant,0)。以下示例展示了一条查询,以及一个相关商品和一个不相关商品。
查询:
self-seal envelopes without window
相关商品标题:
BAZIC Security Self Seal Envelope 4 1/8\" x 9 1/2\" #10, No Window Tint Pattern Mailing Envelopes, Peel & Seal, Office Checks Invoices (30/Pack), 1-Pack
不相关商品标题:
ValBox 200 Count #8 Double Window Envelopes 3 5/8\" x 8 11/16\" Flip and Seal Double Window Security Check Envelopes- Security Tint Pattern Designed for Home Office Secure Mailing
我们抽样 5,000 条查询(每条查询约有 19 件经过标注的商品,其中约 17 件相关),并为全部 1,215,851 条商品描述建立索引以进行基准测试。我们衡量检索质量(NDCG@10)、延迟(并发度为 1 和 10 时的 p50/p95/p99)以及索引大小(ANN 内存占用)。
向量索引构建
我们测试嵌入维度(1024、512、256)与数据类型(float、binary)的所有组合,共六种配置;此外,还测试默认 compression_level: 32x 下的 on_disk 模式 1024-float 配置,并将其与 1024-float 内存模式基线进行比较(总计七种配置)。所有索引均使用带 HNSW 的 FAISS(ef_construction=128、m=24);float 嵌入使用 l2 距离,binary 嵌入使用 hamming 距离。请注意,on_disk 模式要求 data_type: float,并会在内部自行应用 32× 二进制量化,再基于从磁盘读取的全精度向量重新评分。因此,“1024 维 binary on_disk”并不是有效的索引配置。每个索引均单独创建于集合中,摄取全部 122 万份文档,预热至延迟稳定后进行测量,随后删除;在运行下一种配置前等待 15 分钟冷却。
| 配置 | 嵌入大小 | 嵌入类型 |
|---|---|---|
| 内存模式 | 1024 | float(基线) |
| 内存模式 | 512 | float |
| 内存模式 | 256 | float |
| 内存模式 | 1024 | binary |
| 内存模式 | 512 | binary |
| 内存模式 | 256 | binary |
| 磁盘模式(32×) | 1024 | float |
评估方法
对于每种配置,我们都会在 Amazon OpenSearch Serverless(Classic 集合)中创建一个向量索引,摄取全部 1,215,851 件商品,等待合并操作稳定,然后执行自适应预热,直至延迟稳定后再进行测量。我们在并发度为 1 和并发度为 10 的条件下,分别测量 1,000 条查询 × 3 次重复实验。配置执行顺序采用交错方式,以消除数据类型和维度与时间之间的相关性。主要基准测试(表 1)使用语义搜索(仅 k-NN)。我们在表 2 中另行评估混合搜索(语义搜索 + 使用 BM25 的关键词搜索)。我们评估以下指标:
- 检索延迟:延迟定义为 Amazon OpenSearch 结果所报告的、从向量索引中检索相关匹配结果所需的时间。这不包括将文本转换为嵌入所需的时间。
- 检索性能:我们使用 Normalized Discounted Cumulative Gain (NDCG) 指标为每条查询的检索结果评分。该指标通过同时考虑检索文档的相关性及其在排名中的位置,衡量排序检索结果的质量。排名更高的相关文档比排名靠后的文档对总分贡献更大。该分数会相对于理想可能排名进行归一化,范围为 0–1;这在商品搜索中尤其重要,其中
English / 原文
When building a Retrieval Augmented Generation (RAG) solution with Amazon Bedrock Knowledge Bases, selecting the right vector store impacts performance and cost. Amazon Bedrock Knowledge Bases offers a fully managed option and a customer-managed option where you choose your own vector store. This post focuses on the customer-managed path, comparing the three supported backends: Amazon OpenSearch Service, Amazon Aurora PostgreSQL with pgvector, and Amazon S3 Vectors, a capability of Amazon Simple Storage Service (Amazon S3), across distinct RAG use cases.
For broader guidance across all AWS vector solutions, see AWS vector solutions: Build agentic AI where your data lives. For the role of vector datastores in generative AI applications, see The role of vector datastores in generative AI applications. For prescriptive guidance on vector databases for RAG, see Choosing an AWS vector database for RAG use cases.
How vector databases fit into RAG solutions
A RAG architecture combines the capabilities of large language models (LLMs) with information retrieval systems to generate more accurate, up-to-date, and contextually relevant responses. It is based on the mathematical concept of a vector , where the text is translated into vectors that align to the meaning of the text. A search performed on vectors will find results that have similar meaning to the question, which is more effective at capturing semantic similarity than keyword matching.
When a user submits a query, it is converted into a vector embedding using an embedding model. The vector database, where document content has been pre-processed, chunked, and stored as vector embeddings, performs a similarity search to find the chunks whose embeddings are most similar to the query. Typically, the system retrieves the top n chunks (for example, the top five most similar) to enrich the original query. These retrieved chunks are provided to the LLM as additional context so it can generate a more informed, accurate response.
The vector database serves as the key bridge between raw information and contextual understanding. It transforms unstructured data into a searchable, semantically meaningful knowledge space that helps large language models deliver more precise and relevant responses. Vector databases achieve this by storing embedding vectors in an efficient data structure called a vector index, which supports rapid, high-dimensional semantic searches and near-instantaneous retrieval of semantically similar information.
Figure 1: Retrieval Augmented Generation (RAG) architecture, where documents are chunked, embedded, and stored in a vector database during ingestion, and at query time the query is embedded, similar chunks are retrieved, and passed to the LLM as context for response generation
Vector store backends for Amazon Bedrock Knowledge Bases
Amazon Bedrock Knowledge Bases with a customer-managed (unmanaged) configuration supports three vector store backends. For the full AWS vector portfolio covering six services, see AWS vector solutions: Build agentic AI where your data lives.
Amazon OpenSearch Service provides high-speed results from data held in memory. It supports high-dimensional vector embeddings with both managed cluster and serverless deployment options, and features including k-NN search and hybrid search combining lexical and vector approaches. Amazon Bedrock Knowledge Bases supports both Amazon OpenSearch Managed Clusters and Amazon OpenSearch Serverless as vector store backends.
Amazon Aurora PostgreSQL with pgvector combines the high-performance relational database capabilities of Amazon Aurora with pgvector’s vector similarity search functionality. It supports multiple indexing methods (IVFFlat and HNSW), various distance metrics (L2, cosine, inner product), and can handle vectors up to 2,000 dimensions in single precision.
Amazon S3 Vectors is the AWS cloud object storage service with native vector support, designed for cost-effective storage and querying of vector embeddings at scale. It provides sub-second query performance for similarity searches while reducing vector storage costs by up to 90 percent compared to traditional vector databases.
To understand how these options perform in practice, let’s examine three distinct RAG use cases, each with different latency, cost, and search requirements, and see which vector database is the best fit for each.
Use case 1: Product catalog search
Ecommerce platforms face the challenge of helping customers find exactly what they’re looking for among thousands of products. An effective product search tool must understand natural language queries and scale to handle thousands of concurrent queries during peak shopping periods while maintaining low latency.
Why Amazon OpenSearch is the best fit for this use case
Amazon OpenSearch Serverless is well suited for product catalog search because it supports combining semantic understanding with traditional keyword matching through hybrid search capabilities. When dealing with large product catalogs, performance matters. Amazon OpenSearch Serverless handles vector search with query latency in the low milliseconds range.
What makes it particularly valuable for ecommerce is the built-in support for complex filtering and aggregations that power faceted navigation (think filtering by price, brand, or color). You can also choose from multiple distance metrics like cosine similarity or Euclidean distance to fine-tune how product similarity is calculated based on your specific needs.
Amazon OpenSearch Serverless Classic collections offer several optimization options to balance cost and search quality, as detailed in the following section.
Note: Amazon Bedrock Knowledge Bases supports both Amazon OpenSearch Serverless and Managed Clusters. The following benchmarks were run on Serverless Classic collections. Amazon OpenSearch Serverless NextGen collections (generally available May 2026) aren’t yet compatible with the Amazon Bedrock Knowledge Bases Retrieve API. NextGen simplifies index creation by removing the engine and mode parameters from index mappings, defaults to 32× compression with GPU-accelerated index builds, and supports scale-to-zero. The benchmarks in this post use Classic collections, where engine, mode, and HNSW parameters are configured explicitly. Managed Clusters offer additional tuning options (auto-optimize, GPU-accelerated indexing, configurable instance sizing) that may yield different results.
Performance analysis and optimizations for Amazon OpenSearch serverless vector search
Amazon OpenSearch is highly configurable and provides several configuration options. Be careful when selecting these options because they can significantly affect the performance of the vector index. We consider some of these options targeted at optimizing cost and database size and quantitatively demonstrate their impact on vector index performance.
Some of the common optimization options are:
- Size of vector embeddings : A larger vector can generally contain more semantic information about the embedded text. However, it also leads to higher memory consumption, which increases vector index size and cost. Modern embedding models like Amazon Titan Text Embedding v2 offer the ability to embed text in vectors of different sizes (1024, 512, or 256 for Amazon Titan). It is useful to benchmark performance of embeddings of different size to quantitatively measure impact of performance and cost on a particular use case. For model availability by AWS Region, refer to Supported models by AWS Region in Amazon Bedrock.
- Data type of embeddings : We can also reduce vector index size (and thus cost) by storing embeddings in lower precision data types, such as binary embeddings. This can significantly reduce the size of the vector index.
- Disk optimized storage : Amazon OpenSearch Serverless Classic collections offer disk-based vector search (on_disk mode) that applies 32× binary quantization internally while rescoring against full-precision vectors from disk. This preserves quality while reducing in-memory footprint, at the cost of higher latency. Note that on_disk requires float data type and can’t be combined with binary embeddings.
Depending on the indexing algorithm used, users may also configure HNSW parameters (ef_construction, m) to tune the trade-off between index build time, memory usage, and search accuracy (for practical guidance, see A practical guide to selecting HNSW hyperparameters). Additionally, Faiss 16-bit scalar quantization is available on Classic collections to reduce memory usage. Choosing embedding dimension and data type requires evaluating against your own relevance data, as these change the embedding space itself. After selected, the auto-optimize feature can remove the remaining HNSW and quantization tuning in under an hour, by evaluating index configurations against recall and latency thresholds (available for both Amazon OpenSearch Serverless and Managed Clusters with Faiss engine).
Dataset
We use the “Shopping Queries Data Set” (ESCI), a large dataset of difficult search queries provided by Amazon. The dataset contains 1,215,851 unique US products (title, description, bullets, and brand; approximately 1,140 characters median) and 97,345 judged queries. For each query, the dataset provides graded relevance labels: Exact (3), Substitute (2), Complement (1), and Irrelevant (0). An example query and a relevant and irrelevant product are shown in the following examples.
Query:
self-seal envelopes without window
Relevant product title:
BAZIC Security Self Seal Envelope 4 1/8" x 9 1/2" #10, No Window Tint Pattern Mailing Envelopes, Peel & Seal, Office Checks Invoices (30/Pack), 1-Pack
Irrelevant product title:
ValBox 200 Count #8 Double Window Envelopes 3 5/8" x 8 11/16" Flip and Seal Double Window Security Check Envelopes- Security Tint Pattern Designed for Home Office Secure Mailing
We sample 5,000 queries (approximately 19 judged products per query, approximately 17 relevant) and index all 1,215,851 product descriptions for benchmarking. We measure retrieval quality (NDCG@10), latency (p50/p95/p99 at concurrency 1 and 10), and index size (ANN in-memory footprint).
Vector index construction
We test all combinations of embedding dimension (1024, 512, 256) and data type (float, binary), totaling six configurations, plus 1024-float in on_disk mode at the default compression_level: 32x, compared against the 1024-float in-memory baseline (seven configurations total). All indexes use FAISS with HNSW (ef_construction=128, m=24), l2 distance for float embeddings and hamming for binary. Note that on_disk mode requires data_type: float and applies its own binary quantization internally at 32×, rescoring against full-precision vectors read from disk. So “1024-dim binary on_disk” is not a valid index configuration. Each index is created alone in the collection, ingested with all 1.22M documents, warmed until latency stabilizes, measured, then deleted with a 15-minute cool down before the next configuration.
| Configuration | Embedding size | Embedding type |
|---|---|---|
| In memory | 1024 | float (baseline) |
| In memory | 512 | float |
| In memory | 256 | float |
| In memory | 1024 | binary |
| In memory | 512 | binary |
| In memory | 256 | binary |
| On disk (32×) | 1024 | float |
Evaluation methodology
For each configuration, we create a vector index in Amazon OpenSearch Serverless (Classic collection), ingest all 1,215,851 products, wait for merges to settle, then run an adaptive warm-up until latency stabilizes before measuring. We measure 1,000 queries × 3 repetitions at concurrency 1 and concurrency 10. Configuration order was interleaved so data type and dimension are decorrelated from time. The main benchmark (Table 1) uses semantic search (k-NN only). We separately evaluate hybrid search (semantic + keyword with BM25) in Table 2. We evaluate:
- Retrieval latency: Latency is measured as the time taken to retrieve relevant matches from the vector index as reported by the Amazon OpenSearch results. This doesn’t include the time to convert text to embeddings.
- Retrieval performance: We use the Normalized Discounted Cumulative Gain (NDCG) metric to score the retrievals for each query. This metric measures the quality of ranked retrieval results by considering both the relevance of retrieved documents and their position in the ranking. Higher-ranked relevant documents contribute more to the overall score than those ranked lower. The score is normalized against the ideal possible ranking to fall between 0–1, which is especially important in product search, where users are more likely to look at top results.
- Index size: We report the ANN (Approximate Nearest Neighbor) index size, which is the in-memory structure that drives search compute cost and determines capacity requirements. This differs from total store size, which includes the _source JSON copy of each document and varies with document text volume.
Results
Table 1: Semantic search (k-NN only) performance across seven Amazon OpenSearch Serverless configurations (1,215,851 indexed vectors, 5,000 queries, k=10). Latency is server-side at concurrency 1 unless noted. Deltas are paired bootstrap against the 1024-float in-memory baseline. See Table 2 for hybrid search results.
- Reducing dimensions doesn’t always reduce quality. On this dataset, 512-float was statistically indistinguishable from the 1024-float baseline (NDCG 0.3628 vs 0.3627, p = 0.87) at half the index size (2.79 vs 5.34 GiB) and lower latency (25 vs 31 ms p50). Dropping to 256 dimensions showed a measurable 4.4 percent quality loss. The gap between “lossless” and “lossy” dimension reduction will depend on the embedding model and dataset.
- Binarization offers large index size reductions, but the quality cost depends on the number of dimensions. At 1024 dimensions, binary embeddings reduced index size by 13.4× (0.40 vs 5.34 GiB) with a 5.2 percent NDCG loss and comparable latency (22 vs 31 ms p50). At 256 dimensions the quality cost rose to 28.3 percent while the incremental size saving was much smaller (5.0×). On this dataset, the trend was clear: the binary penalty grows as dimensions shrink, suggesting that reducing precision at higher dimensions is more efficient than reducing both precision and dimensions.
- Disk mode (on_disk 32×) preserves quality at the cost of latency. At 1024 dimensions, disk mode achieved NDCG 0.3610 (−0.5 percent vs baseline) with the same 0.40 GiB index size as 1024-binary, but at approximately 3× higher latency (99 ms p50 vs 31 ms in-memory). Both 1024-binary and on_disk reduce the index by 13.4×, but disk mode retained significantly more quality (−0.5 percent vs −5.2 percent). The approximately 3× latency ratio was consistent across p50, p95, and p99. At small corpus sizes this penalty may not appear because the index fits in page cache. It emerges at production scale.
| Configuration | NDCG@10 | Δ vs baseline | p50 (ms) | p95 (ms) | p99 (ms) | Index size (ANN) | p50 @ conc 10 |
|---|---|---|---|---|---|---|---|
| 1024 float | 0.3627 | baseline | 31 | 44 | 52 | 5.34 GiB | 161 ms |
| 512 float | 0.3628 | +0.0002 | 25 | 37 | 62 | 2.79 GiB | 149 ms |
| 256 float | 0.3468 | −4.4% | 22 | 35 | 47 | 1.51 GiB | 85 ms |
| 1024 binary | 0.3438 | −5.2% | 22 | 37 | 55 | 0.40 GiB | 70 ms |
| 512 binary | 0.3200 | −11.8% | 19 | 30 | 47 | 0.32 GiB | 57 ms |
| 256 binary | 0.2600 | −28.3% | 17 | 24 | 32 | 0.28 GiB | 52 ms |
| 1024 float, on_disk 32× | 0.3610 | −0.5% | 99 | 139 | 176 | 0.40 GiB | 255 ms |
Hybrid search results
Table 2: Hybrid search comparison at 1024 dimensions (1,215,851 vectors, 5,000 queries, k=10). Hybrid uses normalization-processor with 0.7 semantic / 0.3 lexical weighting.
| Method | 1024-float NDCG | float p50 | 1024-binary NDCG | binary p50 |
|---|---|---|---|---|
| Keyword (BM25) | 0.3141 | 11 ms | 0.3177 | 17 ms |
| Semantic (k-NN) | 0.3633 | 30 ms | 0.3451 | 17 ms |
| Hybrid | 0.3850 | 38 ms | 0.3658 | 35 ms |
Hybrid search provides a consistent quality lift over semantic-only search. On this dataset, hybrid improved NDCG by +6.0 percent over semantic-only for both float (0.3633 → 0.3850) and binary (0.3451 → 0.3658). In particular, 1024-binary with hybrid (0.3658) exceeded 1024-float with semantic-only (0.3633), at 13× less memory (0.40 vs 5.34 GiB). This suggests that turning on hybrid search can offset the quality cost of binarization.
Hybrid search adds latency. The fusion step roughly doubles sequential latency (30 → 38 ms for float, 17 → 35 ms for binary) and the gap widens under concurrency.
Note: This dataset (product search) favors keyword matching: BM25 alone reached NDCG 0.314, only 13 percent behind semantic. On natural-language RAG queries the absolute hybrid lift may differ. The fusion weight (0.7/0.3) was set for demonstration, not tuned.
Use case 2: Deep research agent
Deep research agents represent a significant evolution beyond traditional RAG systems. While standard RAG performs a single retrieval-generation cycle, deep research agents tackle complex, multi-turn research tasks through dynamic reasoning, adaptive planning, and iterative information retrieval. These agents can search for information, analyze findings, adapt their approach based on intermediate results, and synthesize comprehensive reports over extended periods.
A key characteristic of deep research agents is their tolerance for higher latency in exchange for thoroughness. Unlike real-time search applications where users expect sub-second responses, deep research workflows may run for minutes or hours, making cost-efficiency and scalability far more important than raw query speed.
The vector storage layer for this use case must efficiently handle tens of millions of embeddings at minimal cost while supporting batch operations for periodic re-indexing, flexible metadata filtering, and elastic scaling to millions of vectors.
Why S3 Vectors is the best fit for this use case
For deep research agents that operate over very large embedding collections, Amazon S3 Vectors is a practical and efficient vector storage option. It significantly lowers the cost of storing and querying vectors compared to traditional vector databases, which makes it feasible to work with billions of embeddings derived from large document collections. Amazon S3 Vectors scales elastically without infrastructure provisioning, supporting tens of millions of vectors per index and thousands of indexes per bucket, which suits long-running research systems with growing datasets. It supports a wide range of embedding dimensions and is optimized for batch ingestion and retrieval, enabling efficient background processing of large collections. It integrates with other AWS services, such as Amazon Bedrock Knowledge Bases (the fully managed RAG capability) and Amazon OpenSearch, so teams can combine low-cost storage with more specialized retrieval or RAG workflows when required. Its pay-as-you-go pricing model further supports research workloads with variable or unpredictable usage patterns.
Dataset
We use a subset of English Wikipedia, comprising over 6 million articles. For our benchmarking, we created vector indexes at multiple scales to evaluate how Amazon S3 Vectors performs as the dataset grows:
| Configuration | Target Vectors |
|---|---|
| XSmall | 5,000 |
| Small | 250,000 |
| Medium | 500,000 |
| Large | 1,000,000 |
Each Wikipedia article is chunked into 300-token segments using a token-based splitter.
Vector index construction
We construct vector indexes using Amazon Titan Text Embedding v2, which produces 1024-dimensional float32 embeddings. Our ingestion pipeline uses the following configuration:
| Parameter | Value |
|---|---|
| Embedding Model | Amazon Titan Text Embedding v2 |
| Embedding Dimensions | 1024 |
| Distance Metric | Cosine Similarity |
| Chunk Size | ~300 Tokens |
Results
We measured query latency across four index sizes using 100 research-style questions generated from Wikipedia content. Each query retrieves the top 50 most similar vectors. Latency measurements exclude embedding generation time to isolate Amazon S3 Vectors performance.
Query example:
What factors influence the career trajectories of government officials and policymakers?
| Index Size | Vector Count | p50 (ms) | p95 (ms) | p99 (ms) |
|---|---|---|---|---|
| XSmall | 5,314 | 82 | 180 | 220 |
| Small | 250,514 | 205 | 416 | 527 |
| Medium | 500,401 | 266 | 386 | 479 |
| Large | 1,000,413 | 294 | 395 | 506 |
The key findings are as follows:
- Sub-linear scaling: Query latency grows much slower than index size. Going from 5K to 1M vectors (200x increase) only increases p50 latency by approximately 3.5x (82ms → 294ms). This demonstrates the efficient indexing structure of Amazon S3 Vectors.
- Stabilizing tail latency at scale: The p50 → p95 gap widens from approximately 100ms at 5K vectors to approximately 210ms at 250K but then narrows and holds steady at approximately 100-120ms from 500K to 1M vectors. This suggests that once the index reaches moderate scale, worst-case performance becomes predictable and adding more vectors doesn’t increase tail latency proportionally.
- Sub-second queries at scale: Even at 1 million vectors, p99 latency stays under 510ms. For a deep research agent that spends seconds reasoning over retrieved context, this retrieval overhead is acceptable.
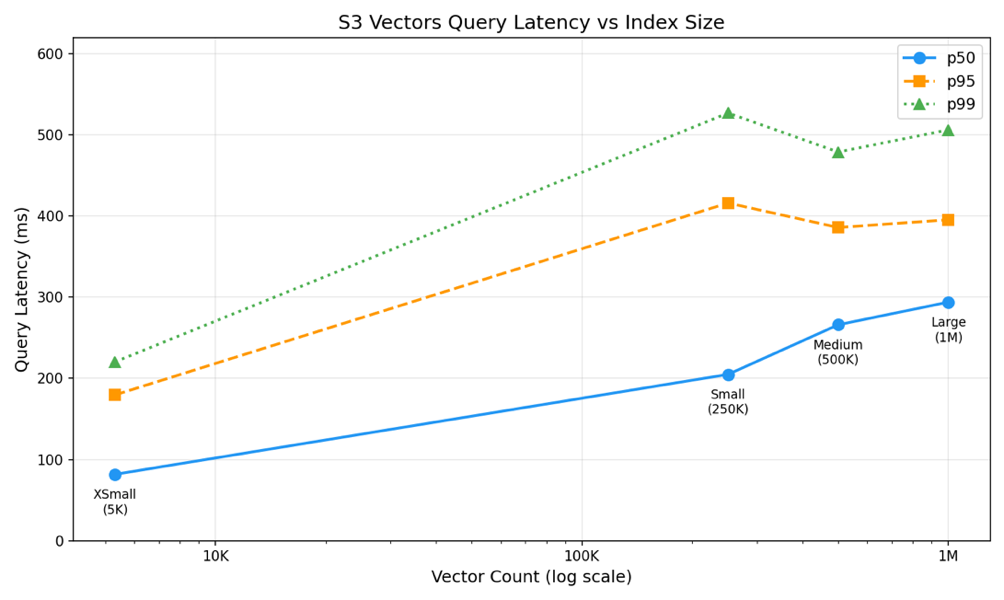
Figure 2: Amazon S3 Vectors query latency (p50, p95, p99) as a function of index size, from 5K to 1M vectors, showing sub-linear scaling with median queries under 300 ms even at 1M vectors
Integration with Amazon OpenSearch for hybrid search workflows
For research workloads that require advanced search capabilities beyond pure vector similarity, Amazon S3 Vectors integrates with Amazon OpenSearch Service through two complementary patterns.
The first uses Amazon S3 Vectors as a cost-effective storage engine directly within Amazon OpenSearch managed clusters, allowing teams to use the hybrid search, aggregations, and complex filtering of Amazon OpenSearch while maintaining the low storage costs of Amazon S3 Vectors.
The second pattern supports one-time exports from S3 vector indexes to Amazon OpenSearch Serverless collections when specific subsets of data require high query throughput or sub-100ms latency for real-time applications. With this tiered approach, research teams can store their full corpus cost-effectively in Amazon S3 Vectors while selectively promoting high-priority vectors to Amazon OpenSearch for performance-critical queries. Both integrations preserve vector dimensions and metadata, supporting smooth transitions between storage tiers as research requirements evolve.
Use case 3: Customer-facing RAG chatbot
Customer-facing chatbots have become essential tools for businesses to provide immediate, personalized support to users. When powered by RAG, these chatbots can deliver accurate, contextual responses by grounding their answers in trusted knowledge sources. However, the diverse types of source data and ways that users formulate their questions mean that it is important to be able to tune the RAG querying to find results that match customer expectations.
A typical use case for a customer-facing chatbot is to provide answers to customer questions based on the content of an internal knowledge base. The knowledge base will have been built up over time in response to customer queries and projects that have built or changed internal systems. They’re likely to contain answers to customer questions, but won’t always include matching keywords or direct references to terms in the question. The requirements for a knowledge base retrieval system are:
- Able to find source material from indirect questions.
- Provide answers quickly.
- Scale to include large knowledge bases.
Why Aurora is the best fit for this use case for large knowledge bases
For customer-facing RAG chatbots with large knowledge bases, Amazon Aurora PostgreSQL with pgvector balances the capacity and performance of S3 and Amazon OpenSearch, and provides the ability to change indexing methods to optimize retrieval for any given dataset.
Amazon Aurora Serverless may also be used for use cases such as development environments where automatic database scaling has cost or performance benefits.
Performance analysis and optimizations for Aurora PostgreSQL
PostgreSQL offers multiple indexing algorithms for vector search, including HNSW and IVFFlat. HNSW (Hierarchical Navigable Small World) builds a multi-layer graph for fast approximate nearest neighbor search, offering faster query times at the cost of higher memory usage and slower index builds. IVFFlat (Inverted File with Flat compression) partitions vectors into clusters for efficient search, using less memory but requiring periodic reindexing as data changes. For a detailed comparison of these algorithms, see Optimize generative AI applications with pgvector indexing: A deep dive into IVFFlat and HNSW techniques. The ability to A/B test different indexes on the same dataset helps teams optimize retrieval performance for their specific use case. Key optimization factors include:
- Database provisioning: Instance sizing and warm-up considerations.
- Index selection : HNSW vs IVFFlat trade-offs for different query patterns.
- Index parameters : Configuration options for each algorithm type.
Amazon Relational Database Service (RDS) provides a wide variety of instance sizes and deployment options such as multiple availability zones and serverless operation. This helps you tune the cost and performance of the database using skills familiar to cloud development and operations teams. The ability to rapidly switch between index types supports testing against real-world customer queries to determine which approach delivers better results.
Dataset
The test environment used a knowledge base of book summaries with the following characteristics:
- 500,000 chunks in the vector database.
- 5,000 randomized queries with 1024-dimensional embeddings.
- Amazon Aurora v15.15.
- Queries executed against the RDS API interface for standardized performance measurement.
- Provisioned database instances that had been running for at least 15 minutes to eliminate startup latency.
Vector index construction
Two vector index types were constructed for comparison: HNSW and IVFFlat. Both indexes used 1024-dimensional embeddings and were configured with the pgvector extension. All other parameters were kept consistent across both index types to make the comparison fair.
Results
The following table presents query latency measurements for both index types across 5,000 queries:
| Index Type | p50 (ms) | p95 (ms) | p99 (ms) |
|---|---|---|---|
| HNSW | 31.91 | 38.20 | 89.00 |
| IVFFLAT | 35.94 | 42.38 | 94.08 |
The key findings are:
- Comparable performance : There was a consistent difference in median performance between HNSW and IVFFlat for this dataset, with both achieving sub-50ms median query times but HNSW was 4ms faster.
- Low latency : Both index types deliver latencies suitable for real-time chatbot responses, with median times under 50ms.
- Consistent tail latency : The p95 latency remains under 60ms for both index types, indicating predictable performance for most queries.
These results demonstrate that Amazon Aurora PostgreSQL provides a balanced approach for customer-facing RAG chatbots, offering latency between the high-performance Amazon OpenSearch and cost-optimized Amazon S3 Vectors, while maintaining the flexibility to optimize indexing strategies based on actual usage patterns.
Selection guidance for Amazon Bedrock Knowledge Bases
The following guidance applies specifically to selecting among the three vector store backends available in Amazon Bedrock Knowledge Bases. For the full AWS vector solution selection framework covering all six services, see the decision model in AWS vector solutions: Build agentic AI where your data lives. If your data already lives in an AWS data store that supports vectors, the recommended approach is to add vector search to that existing service rather than introducing a new one.
Step 1: Profile your application
Start by identifying which pattern your application most closely resembles:
| . | Real-time Search | Conversational AI | Background Processing |
|---|---|---|---|
| Example | Product catalog, autocomplete, faceted search | Customer support chatbot, internal knowledge assistant | Research agents, batch analysis, document processing |
| Latency tolerance | <50ms | <100ms | <1 second |
| Query pattern | High volume, concurrent | Moderate, session-based | Low frequency, complex |
| Hybrid search needed? | Often critical | Sometimes useful | Rarely needed |
| Cost sensitivity | Lower (performance is the priority) | Moderate | Higher (cost-efficiency is the priority) |
Most applications fall clearly into one of these categories. If yours spans multiple (for example, a research agent that also powers a user-facing summary view), consider a tiered architecture where different vector stores serve different parts of the workflow.
Step 2: Match your profile to a vector database
After you know your application profile, you can map it to a vector database:
| If your primary requirement is… | Then start with… | Because… |
|---|---|---|
| Low latency (<50ms) with hybrid search | Amazon OpenSearch Service | Provides single-digit millisecond latency with in-memory HNSW indexing and native support for combining lexical and vector search |
| Balanced latency (~100ms) with relational data needs | Aurora PostgreSQL with pgvector | Delivers sub-50ms query times, supports A/B testing of index types (HNSW vs IVFFlat), and integrates naturally with existing PostgreSQL workflows |
| Cost-efficient storage at massive scale | Amazon S3 Vectors | Reduces vector storage costs by up to 90% compared to traditional vector databases, scales elastically to millions of vectors with no infrastructure to manage |
| Minimal operational overhead | Amazon S3 Vectors | Fully managed with pay-as-you-go pricing—no provisioning, patching, or capacity planning |
Step 3: Consider your growth path
Your choice today doesn’t need to be permanent. These services can complement each other as your needs evolve:
- Start with Amazon S3 Vectors if you’re building a prototype or cost-sensitive research workload. If you later need faster queries for a subset of your data, you can export vectors to Amazon OpenSearch or Amazon Aurora without re-embedding.
- Start with Amazon Aurora PostgreSQL if you need to join vector results with relational data in a single query. It is the only option here that can do this. It’s also a natural fit if your team already runs PostgreSQL, since the familiar operational model reduces the learning curve.
- Start with Amazon OpenSearch if sub-20ms latency or hybrid search is a day-one requirement. You can use Amazon S3 Vectors as a cost-effective backing store for your full corpus while Amazon OpenSearch serves real-time queries.
The tiered storage pattern is particularly powerful for applications that grow beyond a single use case. Use Amazon S3 Vectors for the full corpus and Amazon OpenSearch Service or Amazon Aurora for performance-critical subsets.
Conclusion
Building an effective RAG solution with Amazon Bedrock Knowledge Bases requires selecting a vector store that balances your application’s performance requirements with operational and cost constraints.
Through our analysis of three distinct use cases, a clear picture emerges of how each Amazon Bedrock Knowledge Bases vector store backend fits different needs. Amazon OpenSearch Serverless is well suited where real-time performance and hybrid search are required, delivering low-latency results with the flexibility to combine semantic and keyword search. Amazon Aurora PostgreSQL with pgvector provides a balanced middle ground for conversational applications, delivering sub-100ms latency with the operational familiarity of PostgreSQL and the ability to iterate on indexing strategies. Amazon S3 Vectors addresses cost-sensitive, large-scale workloads, so teams can store and query millions of embeddings without dedicated infrastructure overhead.
The examples and figures in this post come from separate workloads tailored to each database rather than a head-to-head benchmark on a shared dataset, so the numbers illustrate the shape of each option’s tradeoffs rather than a direct apples-to-apples comparison. Understanding these tradeoffs and measuring them against your specific workload is the key to making the right fit.
As your RAG application matures, you may find that a tiered architecture gives you the best of all worlds: scale, performance, and cost-efficiency working together. This approach uses Amazon S3 Vectors for cost-effective storage of your full embedding corpus while selectively promoting high-traffic vectors to Amazon OpenSearch Service or Amazon Aurora.
We encourage you to use the benchmarking methodologies outlined in this post to evaluate these options against your own data and query patterns. The right vector store is ultimately the one that best fits your workload’s latency, cost, and retrieval quality requirements.
About the authors
Deepak Dalakoti
Deepak Dalakoti, PhD, is a Deep Learning Architect at the Generative AI Innovation Centre in Sydney, Australia. With expertise in AI, he partners with clients to accelerate their generative AI adoption through customized, innovative solutions. Outside the world of AI, he enjoys exploring new activities and experiences.
Petar Vuk Avramovic
Petar Vuk Avramovic is a Delivery Consultant in Public Sector Professional Services at AWS, based in Sydney, Australia. He works with customers to navigate complex challenges, using technology and innovation to deliver meaningful business outcomes. Petar has a particular interest in helping organisations realise the value of AI through practical, thoughtful adoption. Guided by his favourite Leadership Principle, Customer Obsession, he is passionate about working backwards from customer needs to create solutions that deliver real impact. Outside of work, Petar is a football fanatic and enjoys cooking with his wife.
Rhys Lewis
Rhys Lewis is a Senior Delivery Consultant in Public Sector Professional Services at AWS, based in Auckland, New Zealand. Rhys has a background in application development, infrastructure and security so that he brings a practitioner’s perspective to solving real-world problems. He is particularly focussed on the AI transition, and how it unleashes productivity for customers.