Wood Mackenzie 基于 Amazon Bedrock AgentCore 打造共享智能体平台
英文标题:A shared agentic platform for Wood Mackenzie, on Amazon Bedrock AgentCore
Wood Mackenzie 构建了名为 APEX(Agentic Platform for Energy eXperience)的共享式智能体 AI 平台,旨在让各产品团队无需重复建设运行时、身份认证、可观测性和安全护栏等基础设施,即可部署生产级 Agent。该平台基于 Amazon Bedrock AgentCore,可兼容多种智能体框架和模型,并支持自动扩缩容、身份与权限控制、工具网关、记忆、评估和可观测性能力。Wood Mackenzie 表示,其内部有 88% 的 AI 概念验证项目未能进入大规模部署,而评估、可观测性、治理和重复基础设施是主要障碍。APEX Studio 则作为统一控制平面,帮助团队从创建、部署到监控智能体,实现标准化的生产运营。
 1.3 MB
 101.1 KB
 124.1 KB
 345.0 KB
 141.2 KB
 346.5 KB
 318.3 KB
 662.1 KB
 205.4 KB
 282.4 KB
 310.1 KB
 25.8 KB
 17.7 KB
 269.8 KB
中文
构建一个可运行的智能体原型只需要一个下午。真正让它投入生产,工作量才会迅速膨胀。当一个智能体必须服务不止一名用户时,新的工程层面问题便会出现,而判断该智能体在真实流量下是否做对了事也至关重要。并发、会话隔离、身份、持久化状态、扩缩容和安全护栏,都是大多数团队每次都会从头构建的层;尽管为每个智能体提供标准化平台会是更具可重复性的做法。
结果是,实验与生产之间存在巨大鸿沟。截至 2026 年初的行业调研显示,企业 AI 实验几乎已无处不在,但仅约四分之一的组织在至少一个职能领域将智能体扩展至生产环境。在 Wood Mackenzie 内部,我们发现 88% 的 AI 概念验证项目从未进入大规模部署。不同分析机构给出的原因大体一致,而且大多是架构问题,而非模型问题。Forrester 认为,智能体失败主要源自模糊性、协调失当和不可预测的系统行为,而不是常规软件缺陷。最常被提及的单一阻碍是评估与可观测性:团队无法可靠地预先判断一个非确定性智能体何时会出错,而标准回归测试也无法捕捉这类问题。治理和身份问题紧随其后,很大一部分高管表示,他们无法立即关闭一个行为失常的智能体。其底层问题是基础设施重复建设:每个团队都重新实现认证、护栏、记忆和追踪,并将模型硬编码,以至于更换供应商就意味着重写代码。
这正是共享智能体平台所要解决的问题。无需让每个团队重复建设相同的基础能力,一个运行时即可处理编排、安全、可观测性、身份和连接能力,而团队可以将精力投入到真正能使其产品差异化的业务逻辑中。
本文将介绍我们如何构建 APEX(Agentic Platform for Energy eXperience,即面向能源体验的智能体平台):这是一个共享平台,使每个团队都能交付智能体,而不必重复发明基础设施。APEX 构建在 Amazon Bedrock AgentCore 之上;这是一个可使用任意框架或模型,大规模构建、连接和优化智能体的平台。我们将说明为何选择 AgentCore 而不是自托管方案,架构如何组成,APEX Studio 如何为团队提供单一控制平面来运营平台,以及我们如何将交互式 AI 引入实际应用,服务 Woody 等内部用户和 Lens 等外部用户。我们还将深入讨论,同一套基础设施如何通过身份感知的授权机制同时服务两类用户,如何弥合阻碍大多数智能体项目的评估和治理缺口,以及随着多智能体系统成为默认模式,平台将走向何方。
为什么需要共享平台,以及为什么选择 AgentCore
在 APEX 出现之前,三个应用都在各自构建智能体技术栈的路上:Woody、Lens AI 和 ST Trading App。如果任其发展,每个应用都会搭建自己的运行时、接入自己的身份系统、添加自己的可观测性能力,并硬编码自己的模型。我们将为同一份基础设施成本付费三次,最终得到三个无法共享记忆、工具或评估能力的技术栈。
AgentCore 通过提供能够满足企业级智能体部署需求的平台,解决了这一问题。我们根据生产级平台的要求评估了 AgentCore,包括托管模式、成本模式、是否模型无关、可扩展性、治理能力和企业支持。
| 框架 | 托管方式 | 成本模式 | 模型无关 | 可扩展性 | 治理 | 企业支持 |
|---|---|---|---|---|---|---|
| LangChain | 自托管 | 免费/企业版 | 是 | 手动 | 自行实现 | 社区 |
| LangChain | 自托管/ LangSmith | 免费 + LangSmith | 是 | 手动 | LangSmith | 社区 |
| CrewAI | 自托管/ CrewAI-Cloud | 免费/云服务 | 是 | 有限 | 基础 | 社区 |
| n8n | 自托管/云服务 | 免费/专业版 | 否 | 中等 | 工作流 | 社区 + 专业版 |
| 前沿模型直连 | 供应商托管 | 按 Token 计费 | 否 | 供应商管理 | 无 | 供应商 SLA |
| Bedrock AgentCore | AWS 托管 | 按使用量付费 | 是 | 自动扩缩容 | 原生 Amazon Bedrock Guardrails 和 Policy | AWS 企业级 SLA |
AgentCore 为我们提供的是托管平台,而不是需要我们自行运营的库。它可与任意开源框架配合使用,包括 Strands Agents、LangGraph、LangChain、LlamaIndex、CrewAI、Google ADK、OpenAI Agents SDK;也可支持任意模型,无论该模型是否运行于 Amazon Bedrock。它同时支持模型上下文协议(Model Context Protocol,MCP)和智能体对智能体协议(Agent-to-Agent,A2A)。这意味着我们不必在开源灵活性与 AWS 服务安全性之间二选一。我们得以标准化平台层,同时让各团队自由选择其框架和模型。
以下五项能力促使我们做出了这一选择:
- 托管基础设施。 无需运营集群。AWS 负责扩缩容、修补和可用性,因此平台团队可以专注于智能体能力,而不是后端底层事务。AgentCore 于 2025 年 10 月正式发布(GA);在 GA 阶段,所有服务均增加了对 Amazon Virtual Private Cloud(VPC)、AWS PrivateLink、AWS CloudFormation 和资源标签的支持。
- 真正的模型无关性。 Claude、GPT-4.1、Amazon Nova、Mistral 和 Llama 都可以通过统一平台访问。团队可以使用一个模型进行规划、使用另一个模型执行;可以通过替换供应商进行性价比测试;也可以在某个模型出现回归问题后迁离该模型,而不会丢失对话上下文,也无需改动业务逻辑。
- 自动扩缩容。 AgentCore runtime 是 Amazon Bedrock AgentCore 的一项能力,可在无需进行容量规划的情况下,从零扩展至数千个并发智能体调用;同时提供完整会话隔离,执行窗口最长可达 8 小时。
- 原生护栏与身份能力。 内容过滤、个人身份信息(PII)检测和策略执行都是托管能力,而不是每个团队都要重新实现的功能。Amazon Bedrock AgentCore 中的 Policy 可与 Gateway 集成,实时拦截每一次工具调用,并将自然语言规则转换为 AWS 开源策略语言 Cedar。因此,开发、合规和安全团队无需编写自定义代码,即可编写和审计规则。AgentCore Identity 是 Amazon Bedrock AgentCore 的一项能力,增加了 AWS Identity and Access Management(IAM)集成、VPC 隔离和加密功能,使智能体能够满足合规要求,并能在既定访问控制下代表用户或自主执行操作。
- AWS Enterprise Support。 AWS Enterprise Support 提供 24/7 支持,以及技术客户经理(TAM)和客户团队支持,帮助客户基于自身需求影响包括 AgentCore 在内的产品路线图。
AgentCore 采用按使用量计费,无需预先承诺或支付最低费用。每项服务独立计费,因此团队可以仅采用某一项能力,例如 Amazon Bedrock AgentCore 的 AgentCore memory,而无需迁移整个智能体。运行时计费基于按秒计算的活跃 CPU 和内存消耗,且 CPU 在 I/O 等待期间不产生费用。这对智能体工作负载尤其重要,因为它们通常有 30% 至 70% 的时间用于等待模型响应、工具调用或数据库查询。若采用预分配计算资源,您仍需为这部分空闲时间付费;使用 AgentCore 则无需如此。
解决方案概述
APEX 采用分层组织,如图 1 所示。最上层是最终用户,他们与三个应用交互:Woody、Lens AI 和 ST Trading App。这些应用连接至 APEX 前端;该前端提供了一套框架,产品团队无需每次重新构建后端连接,便可将智能体能力嵌入用户界面。APEX 后端则是 AgentCore 发挥作用的地方。
后端之外还并列两条基础设施轨道。WM 基础设施即代码(IaC)框架使用 AWS Cloud Development Kit(AWS CDK)和 GitHub 来配置并对平台资源进行版本控制,护栏则通过代码定义。MCP 层通过标准协议而非定制集成,将平台连接至第三方和外部访问渠道,包括 AWS Marketplace 与合作伙伴系统。
用户通过 APEX 前端 SDK 访问三个应用。APEX 后端运行在 AgentCore(Runtime、Identity、Gateway、Memory、Observability)上,并包含 Orchestrator、用于检索的向量数据库、通过 Amazon Bedrock 模型目录进行的模型访问,以及 Amazon Bedrock Guardrails。WM IaC Framework 通过 AWS CDK 和 GitHub 配置资源,MCP 层则连接外部系统。
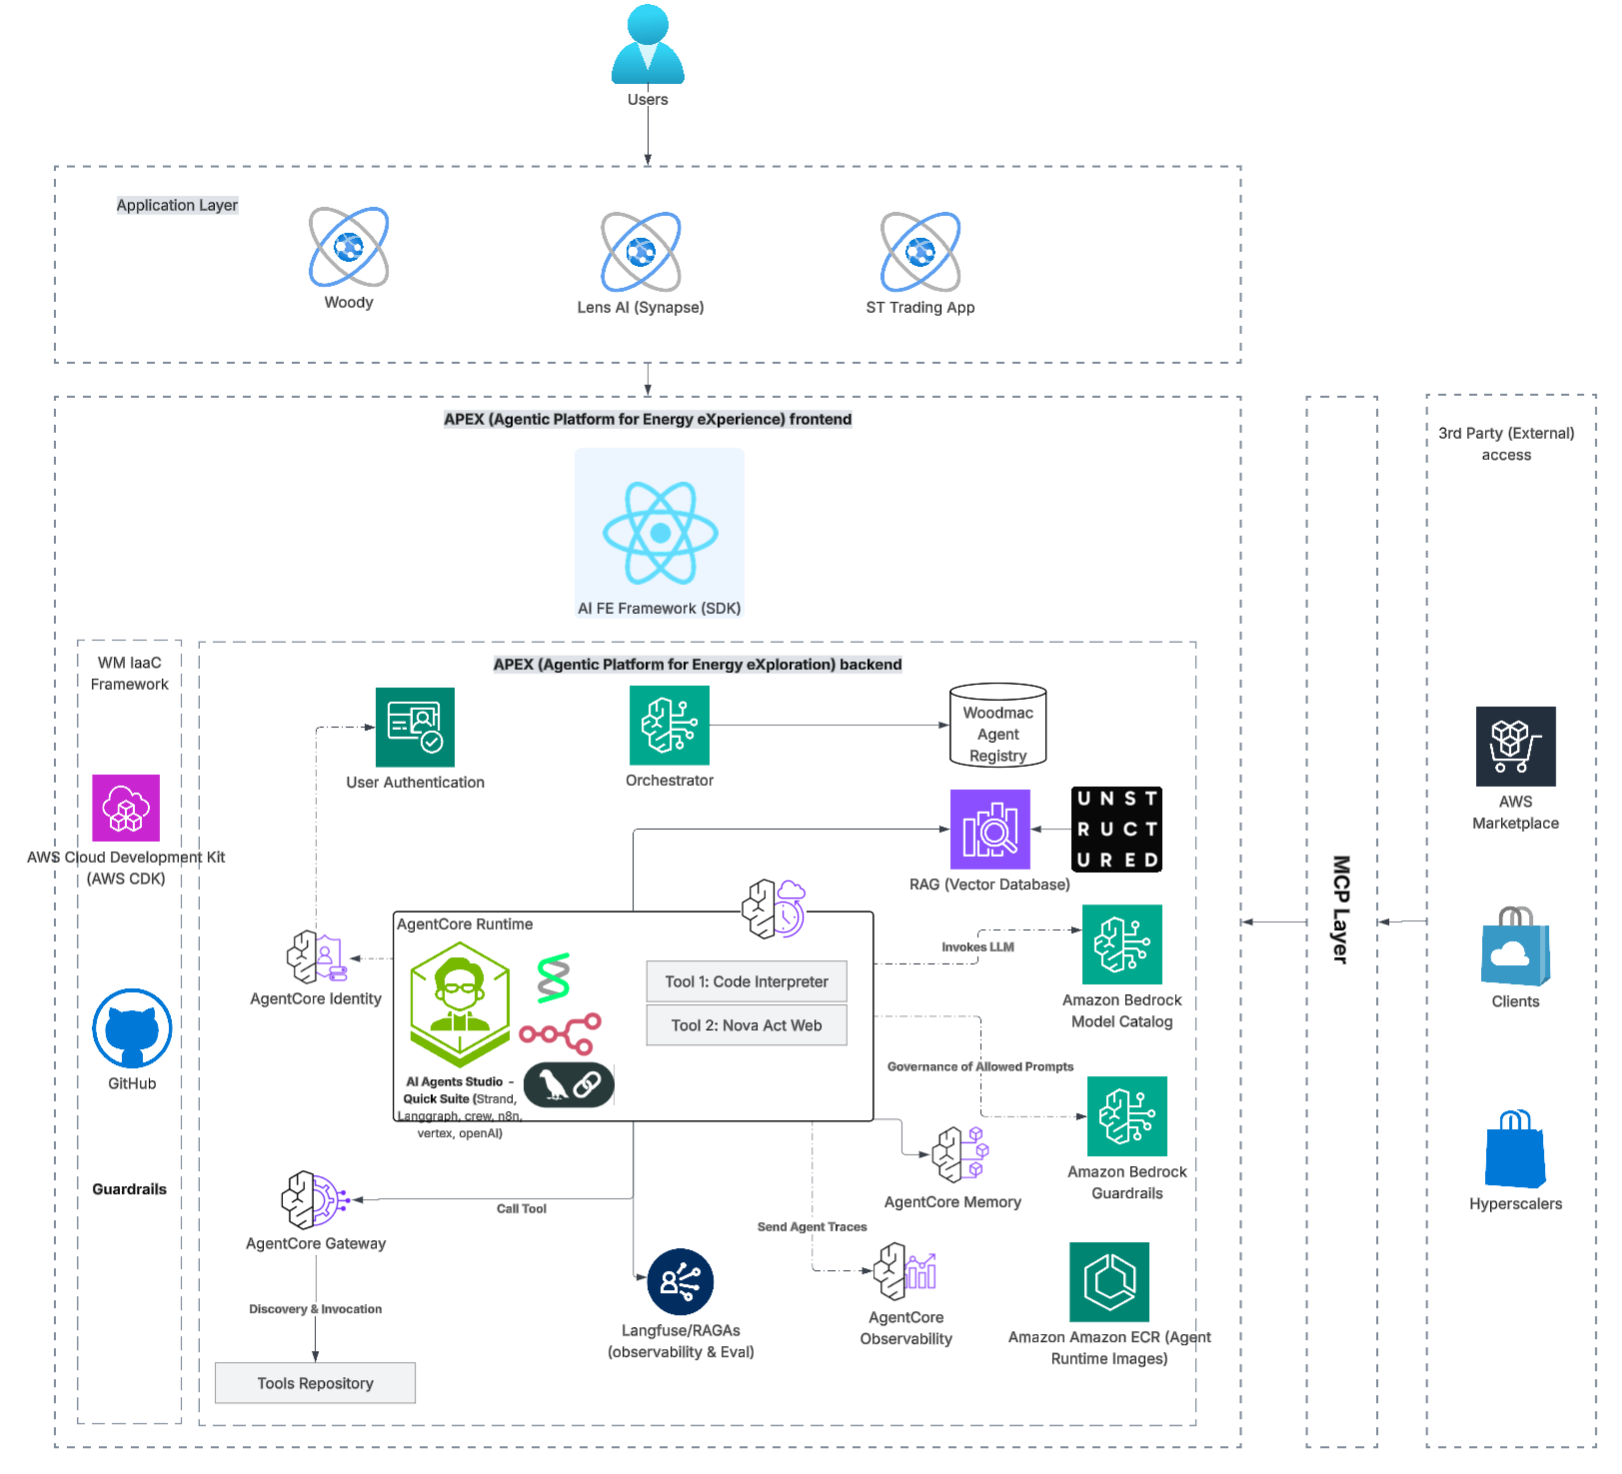
图 1:APEX 参考架构
在后端内部,一个请求会流经以下组件。
用户认证和 AgentCore Identity 确定调用者是谁,以及其有权执行哪些操作。身份与授权被嵌入每一次智能体调用,而不是仅在边缘入口检查一次;因此,代表用户执行操作的智能体会在每次下游工具和数据调用中携带该用户的权限。与所选身份提供商进行联合身份认证同样重要。我们使用 Okta 作为事实来源。
Orchestrator 负责路由请求,并查询 Woodmac Agent Registry。这是一个统一位置,用于在组织内发现、共享和复用智能体、工具及技能,并内置治理和审批工作流。通过它,一个团队的智能体可供另一团队使用,而无需复制代码。
AgentCore runtime 在无服务器、会话隔离环境中托管智能体代码。在运行时内部,我们运行 AI Agents Studio(基于 Amazon Quick,并支持 Strands Agents、LangGraph、CrewAI、n8n、Vertex 和 OpenAI),因此每个团队都可以保留自己偏好的框架。运行时通过 Amazon Bedrock 模型目录调用模型;模型无关性在此变得具体:智能体按名称指向模型,我们无需重写智能体即可切换供应商。
工具 以可组合的构建模块形式暴露给智能体。该架构展示了 Wood Mackenzie 如何使用 Code Interpreter 工具进行安全代码执行,以及使用 Amazon Nova Act web 工具执行浏览器操作。这些工具通过 AgentCore Gateway 访问;AgentCore Gateway 是 Amazon Bedrock AgentCore 的一项能力,可将 API、AWS Lambda 函数和现有 MCP 服务器转化为兼容智能体的工具,并提供统一的安全端点用于发现和调用。Gateway 从 Tools Repository 获取工具以进行发现和调用,并支持 IAM、OAuth 2.1 和 API 密钥认证。
基于向量数据库的检索增强生成(RAG) 让智能体以我们自身的内容为依据,包括非结构化文档,使回答基于检索到的事实,而不只依赖模型的参数化记忆。我们使用 Amazon Bedrock Knowledge Bases 作为以无服务器、托管方式为智能体提供 RAG 的方案。
AgentCore memory 为智能体提供短期和长期上下文,使对话可跨会话持续存在,并让智能体共享状态,而非各自维护独立存储。
Amazon Bedrock Guardrails 和 Policy 对允许的提示词进行治理,并拦截工具调用,执行内容过滤、PII 检测以及此前所述的基于 Cedar 的规则。
可观测性与评估 决定了智能体能否在生产环境中存活。智能体输出具有非确定性,因此难题并不是 它是否能工作,而是 我们能否知道它何时停止正常工作。AgentCore Observability 是 Amazon Bedrock AgentCore 的一项能力,可将兼容 OpenTelemetry 格式的遥测数据发送至 Amazon CloudWatch,涵盖会话数量、延迟、时长、Token 使用量和错误率。随后,Wood Mackenzie 能够从一个会话向下追踪单个请求,直至单独的 span;每个组件的日志会在相应步骤呈现,而不是分散在各个日志组中。在此基础上,AgentCore Evaluations 是 Amazon Bedrock AgentCore 的一项能力,可为帮助性、工具选择和准确性等质量维度提供内置评估器,也支持自定义的基于模型的评分,使我们能够针对真实流量为智能体评分。
APEX Studio:控制平面
此前介绍的架构是运行时。APEX Studio 则是用于运营该运行时的后台:这是一个统一界面,团队无需接触底层基础设施,即可构建、部署和监控智能体。它是 AgentCore 面向人的控制平面,使团队能够从想法走向上线智能体,而无需在每个步骤都提交工单。
如图 2 所示,Studio 仪表板一目了然地展示平台运行状态、活跃智能体、工作流和连接器,以及近期部署及其状态,使运营人员能够了解哪些内容正在生产环境运行,哪些仍处于预发布阶段。六项能力覆盖智能体生命周期。
Agent Builder 是模板驱动的智能体创建能力:团队配置智能体的人设、工具和护栏,而不是手动连接这些组件。这是 Golden Path 的实际体现:新智能体从一条已铺设好的模板路径起步,而不是从空白代码仓库开始。
Workflow Designer 支持可视化的多步骤编排,包括分支、循环和人工参与步骤,使多步骤流程能够在一个位置完成组合和审核,而不是分散编码在多个服务中。
连接器
English / 原文
Building a working agentic prototype takes an afternoon. Getting it to production is where the work explodes. The moment an agent has to serve more than one user, a new layer of engineering appears and it’s critical to tell whether the agent is doing the right thing on real traffic. Concurrency, session isolation, identity, persistent state, scaling, and guardrails are all layers that most teams rebuild from scratch every time, even though a standardized platform for each agent is a more repeatable approach.
The result is a wide gap between experimentation and production. Industry surveys through early 2026 put enterprise AI experimentation near universal while only about a quarter of organizations have scaled agents into production in even one function. Internally at Wood Mackenzie, we have found that 88 percent of AI proofs-of-concept never reach widescale deployment. The reasons are consistent across analysts, and they are mostly architectural rather than model-related. Forrester attributes agent failures largely to ambiguity, miscoordination, and unpredictable system behavior rather than ordinary bugs. The most-named single blocker is evaluation and observability: teams cannot reliably tell ahead of time when a non-deterministic agent will be wrong, and standard regression tests do not catch it. Governance and identity follow close behind, with a large share of executives reporting they could not immediately shut down a misbehaving agent. Underneath all of it is duplicated infrastructure: each team re-implements authentication, guardrails, memory, and tracing, and hardcodes a model so that swapping providers means rewriting code.
This is the problem a shared agentic platform solves. Instead of every team rebuilding the same foundation, one runtime handles orchestration, safety, observability, identity, and connectivity, and teams spend their effort on the business logic that differentiates their product.
In this post we show how we built APEX (Agentic Platform for Energy eXperience), a shared platform so every team can ship agents without reinventing infrastructure. APEX is built on Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale, with any framework or model. We cover why we selected AgentCore over self-hosted solutions, how the architecture is composed, how APEX Studio gives teams a single control plane to operate it, how we bring interactive AI into real applications for both internal users like Woody and external consumers like Lens. We will also dive into how the same infrastructure serves both under identity-aware entitlements, how we close the evaluation and governance gaps that stall most agent programs, and where the platform is heading as multi-agent systems become the default.
Why a shared platform, and why AgentCore
Before APEX, three applications were each on their way to building their own agent stack: Woody, Lens AI, and the ST Trading App. Left alone, each would have stood up its own runtime, wired its own identity, bolted on its own observability, and hardcoded its own model. We would have paid the same infrastructure tax three times and ended up with three stacks that could not share memory, tools, or evaluation.
AgentCore resolves this problem by providing a platform capable of meeting the needs of an enterprise scale agentic deployment. We evaluated AgentCore against the requirements of a production platform: hosting model, cost model, whether it is model agnostic, scalability, governance, and enterprise support.
| Framework | Hosting | Cost Model | Model Agnostic | Scalability | Governance | Enterprise Support |
|---|---|---|---|---|---|---|
| LangChain | Self-Hosted | Free/Enterprise | Yes | Manual | DIY | Community |
| LangChain | Self-Hosted/ LangSmith | Free + LangSmith | Yes | Manual | LangSmith | Community |
| CrewAI | Self-Hosted/ CrewAI-Cloud | Free/ Cloud | Yes | Limited | Basic | Community |
| n8n | Self-Hosted/ Cloud | Free/ Pro | No | Moderate | Workflow | Community + Pro |
| Frontier Model Direct | Provider-hosted | Per-token | No | Provider-Managed | None | Provider SLA |
| Bedrock AgentCore | AWS managed | Pay-per-use | Yes | Automatic scaling | Native Amazon Bedrock Guardrails and Policy | AWS Enterprise SLA |
AgentCore provides us a managed platform rather than a library we would need to operate ourselves. It works with any open source framework, including Strands Agents, LangGraph, LangChain, LlamaIndex, CrewAI, Google ADK, OpenAI Agents SDK, and with any model whether or not it runs on Amazon Bedrock. It supports both the Model Context Protocol (MCP) and the Agent-to-Agent (A2A) protocol. That meant we didn’t need to choose between open source flexibility and AWS service security. This allowed us to standardize the platform layer while leaving each team free to pick its own framework and model.
Five capabilities decided it for us:
- Managed infrastructure. There’s no cluster to operate. AWS handles scaling, patching, and availability, so our platform team focuses on agent capabilities instead of backend plumbing. AgentCore reached general availability (GA) in October 2025, and at GA all services added support for Amazon Virtual Private Cloud (VPC), AWS PrivateLink, AWS CloudFormation, and resource tagging.
- True model agnosticism. Claude, GPT-4.1, Amazon Nova, Mistral, and Llama are all reachable through a single platform. A team can plan with one model and execute with another, run a price-performance test by swapping providers, or move off a model that shipped a regression, without losing conversation context and without touching business logic.
- Automatic scaling. AgentCore runtime, a capability of Amazon Bedrock AgentCore, goes from zero to thousands of concurrent agent invocations with no capacity planning, with complete session isolation and execution windows up to 8 hours.
- Native guardrails and identity. Content filtering, personally identifiable information (PII) detection, and policy enforcement are managed capabilities rather than something each team reimplements. Policy in Amazon Bedrock AgentCore integrates with the Gateway to intercept every tool call in real time and converts natural-language rules into Cedar, the AWS open source policy language, so development, compliance, and security teams can author and audit rules without custom code. AgentCore Identity, a capability of Amazon Bedrock AgentCore, adds AWS Identity and Access Management (IAM) integration, VPC isolation, and encryption, so agents support your compliance requirements and can act on behalf of a user or on their own under defined access controls.
- AWS Enterprise Support. AWS Enterprise Support provides 24/7 support as well as a technical account manager (TAM) and account team relationship that helps customers influence the roadmap for products like AgentCore based on our needs.
AgentCore uses consumption-based pricing with no upfront commitments or minimum fees. Each service is billed independently, so a team can adopt a single capability such as AgentCore memory, a capability of Amazon Bedrock AgentCore, without migrating its entire agent. Runtime billing is based on active CPU and memory consumption calculated per second, and CPU charges don’t accrue during I/O wait. This matters for agentic workloads, which typically spend 30–70 percent of their time waiting on model responses, tool calls, or database queries. With pre-allocated compute you would pay for that idle time. With AgentCore, you do not.
Solution overview
APEX is organized in layers, shown in Figure 1. At the top, end users interact with three applications: Woody, Lens AI, and the ST Trading App. Those applications talk to the APEX frontend, which exposes a framework so product teams can drop agentic capabilities into a user interface without rebuilding the connection to the backend each time. The APEX backend is where AgentCore does the work.
Two infrastructure tracks sit alongside the backend. The WM infrastructure as code (IaC) Framework uses the AWS Cloud Development Kit (AWS CDK) and GitHub to provision and version platform resources, with guardrails defined in code. The MCP layer connects the platform to third-party and external access, including AWS Marketplace and partner systems, over a standard protocol rather than bespoke integrations.
Users reach three applications through the APEX frontend SDK. The APEX backend runs on AgentCore (Runtime, Identity, Gateway, Memory, Observability) with an Orchestrator, a vector database for retrieval, model access through the Amazon Bedrock model catalog, and Amazon Bedrock Guardrails. The WM IaC Framework provisions resources through AWS CDK and GitHub, and the MCP layer connects external systems.
Figure 1: APEX reference architecture
Inside the backend, a request flows through these components.
User Authentication and AgentCore Identity establish who is calling and what they are entitled to do. Identity and entitlements are woven into every agent invocation rather than checked once at the edge, so an agent acting on a user’s behalf carries that user’s permissions through every downstream tool and data call. Federation to your identity provider of choice is also important. We use Okta as our source of truth.
The Orchestrator routes the request and consults the Woodmac Agent Registry, a single place to discover, share, and reuse agents, tools, and skills across the organization with built-in governance and approval workflows. This is how one team’s agent becomes available to another without copying code.
AgentCore runtime hosts the agent code in a serverless, session-isolated environment. Inside the runtime we run AI Agents Studio (built on Amazon Quick with Strands Agents, LangGraph, CrewAI, n8n, Vertex, and OpenAI), so each team keeps its preferred framework. The runtime invokes models through the Amazon Bedrock model catalog, which is where model agnosticism becomes concrete: the agent points at a model by name and we swap providers without rewriting the agent.
Tools are exposed to the agent as composable building blocks. The architecture shows how Wood Mackenzie uses a Code Interpreter tool for secure code execution and an Amazon Nova Act web tool for browser actions. These tools are reached through AgentCore Gateway , a capability of Amazon Bedrock AgentCore, which turns APIs, AWS Lambda functions, and existing MCP servers into agent-compatible tools and provides a single secure endpoint for discovery and invocation. The Gateway pulls from a Tools Repository for discovery and invocation, and supports IAM, OAuth 2.1, and API key authentication.
Retrieval Augmented Generation (RAG) over a vector database grounds the agent in our own content, including unstructured documents, so responses are based on retrieved facts rather than the model’s parametric memory alone. We use Amazon Bedrock Knowledge Bases as a serverless and managed way to provide RAG to our agents.
AgentCore memory gives the agent short-term and long-term context, so a conversation persists across sessions and agents can share state instead of each maintaining its own store.
Amazon Bedrock Guardrails and Policy govern allowed prompts and intercept tool calls, enforcing content filtering, PII detection, and the Cedar-based rules described earlier.
Observability and evaluation determine whether an agent survives in production. Agent output is non-deterministic, so the hard question isn’t does it work but can we tell when it stops working. AgentCore Observability, a capability of Amazon Bedrock AgentCore, emits telemetry in OpenTelemetry-compatible format to Amazon CloudWatch, covering session count, latency, duration, token usage, and error rates. Wood Mackenzie can then trace a single request from a session down to an individual span, with logs from each component surfaced at the right step instead of scattered across log groups. On top of that, AgentCore Evaluations, a capability of Amazon Bedrock AgentCore, gives us built-in evaluators for quality dimensions such as helpfulness, tool selection, and accuracy, plus custom model-based scoring, so we can score agents against real traffic.
APEX Studio: The control plane
The architecture described earlier is the runtime. APEX Studio is the back office that operates it, a single interface where a team builds, deploys, and monitors agents without touching the underlying infrastructure. It’s the human-facing control plane over AgentCore, and it’s how a team gets from idea to a live agent without filing a ticket for each step.
The Studio dashboard, shown in Figure 2, surfaces the platform’s operational state at a glance, active agents, workflows, and connectors, along with recent deployments and their status, so an operator can see what is running in production and what is still in staging. Six capabilities cover the agent lifecycle.
Agent Builder is template-driven agent creation, where a team configures an agent’s persona, its tools, and its guardrails rather than wiring those by hand. This is the Golden Path in practice: a new agent starts from a paved template, not a blank repository.
Workflow Designer is visual multi-step orchestration with branching, loops, and human-in-the-loop steps, so a multi-step process is composed and reviewed in one place instead of encoded across scattered services.
Connector Registry lets a team browse, configure, and publish MCP-compatible data connectors. It’s the operator’s view of the same gateway and tools layer described earlier, which keeps tool publishing governed and reusable across teams.
Live Chat Testing provides real-time agent interaction for validation before a production deploy. This is where the evaluation discipline starts. An operator exercises the agent against real inputs before it reaches users, which is the first line of defense against the non-deterministic failures that stall most agent programs.
App Deployment covers the full application lifecycle from build to production launch, and Monitoring Dashboard shows agent health, cost, latency, and accuracy metrics in one view, fed by AgentCore Observability and Evaluations. Together they close the loop from shipping an agent to watching how it behaves once it is live.
Underneath the Studio is an embedded software development lifecycle (SDLC) integration we call vibe coding: a team can create an agent through natural language, with automated testing, a preview, and one-click production deployment. The point is the same one that runs through the whole platform: the operator expresses intent and the platform handles the build, the test harness, and the deploy, so the time from idea to a governed production agent is measured in hours.
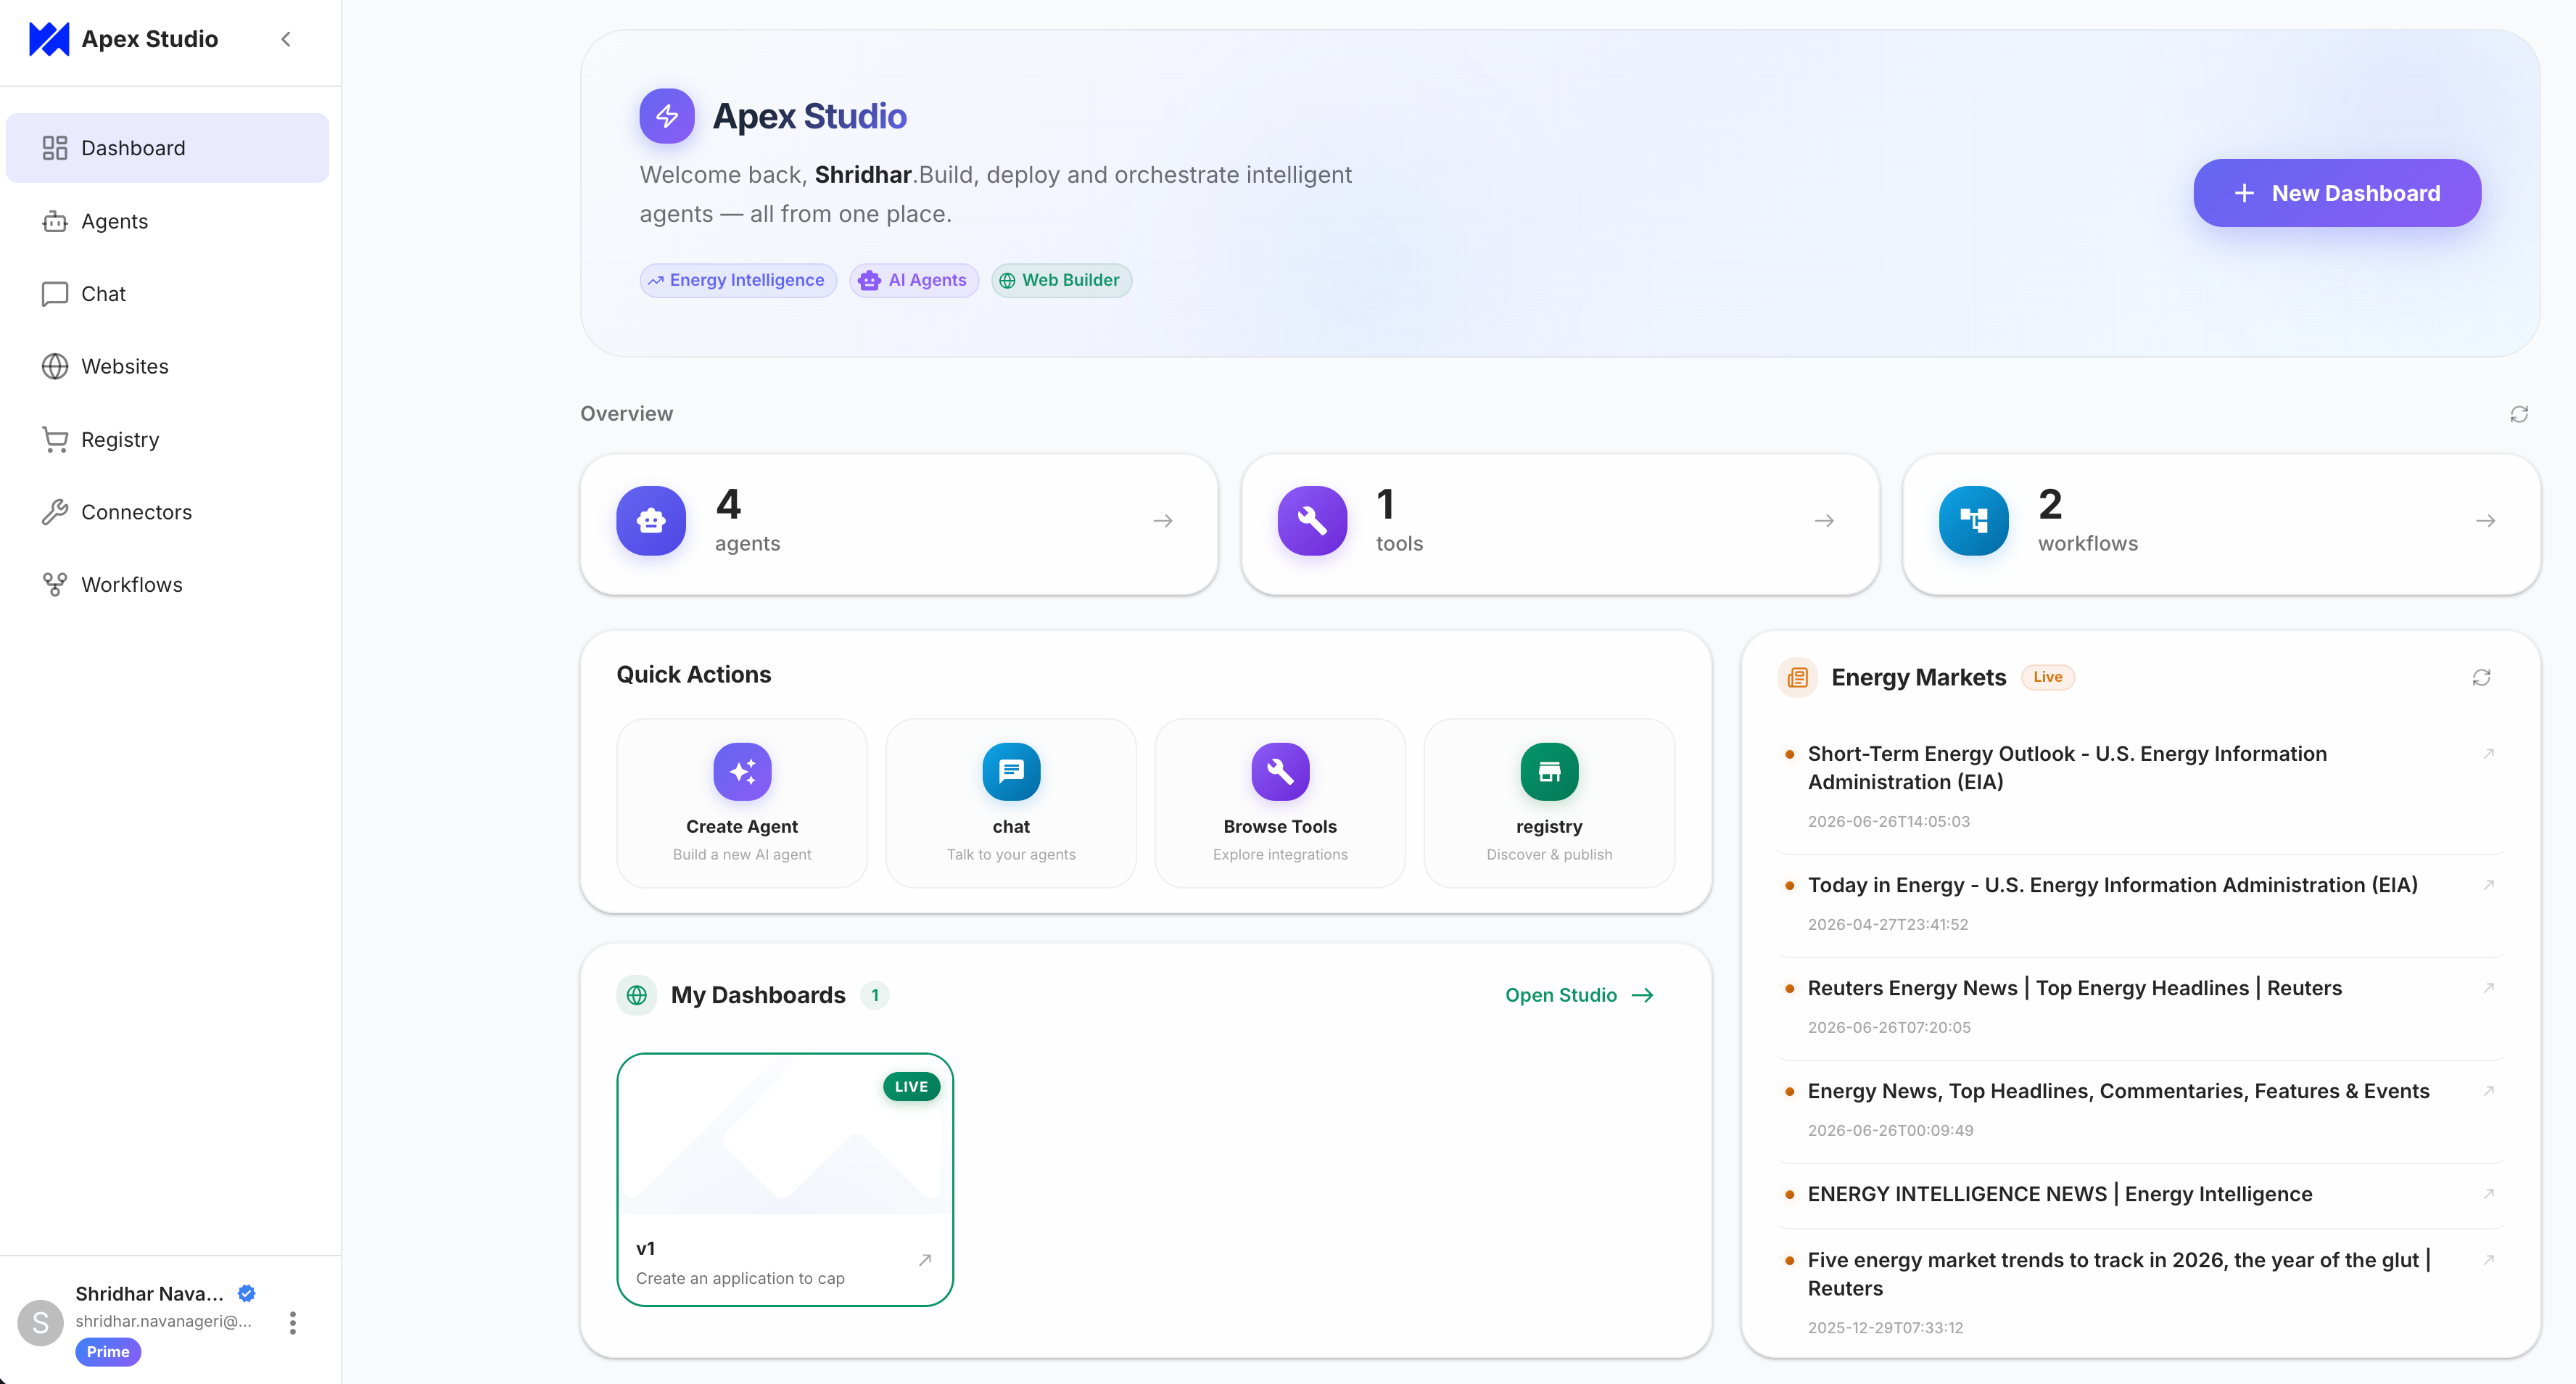
Figure 2: APEX Studio control plane
The dashboard shows active agents, workflows, and connectors with recent deployment status, and exposes Agent Builder, Workflow Designer, Connector Registry, Live Chat Testing, App Deployment, and a Monitoring Dashboard over AgentCore.
The single integration pattern that does the most work in APEX is the hub-and-spoke model we built on AgentCore Gateway, shown in Figure 3. Without it, every consumer would maintain a bespoke connection to every data service. With N consumers and M services, that is an N by M integration problem: each new application or agent multiplies the number of point-to-point connections we must build, secure, and maintain, and each connection reimplements the same cross-cutting concerns.
The hub-and-spoke model avoids that. Every application and agent connects through one gateway instead of holding its own connection to each data service. On the consumer side, an internal analyst, a client chatbot, and a trading agent all speak to the same hub. On the data side, the gateway fans out to Lens Direct for analytics and curves, Short Term Trading for real-time execution, Digital Content for upstream models, and the P&R Dataset calculators. Adding a new consumer or a new data service means wiring one spoke to the hub, not rebuilding the full mesh.
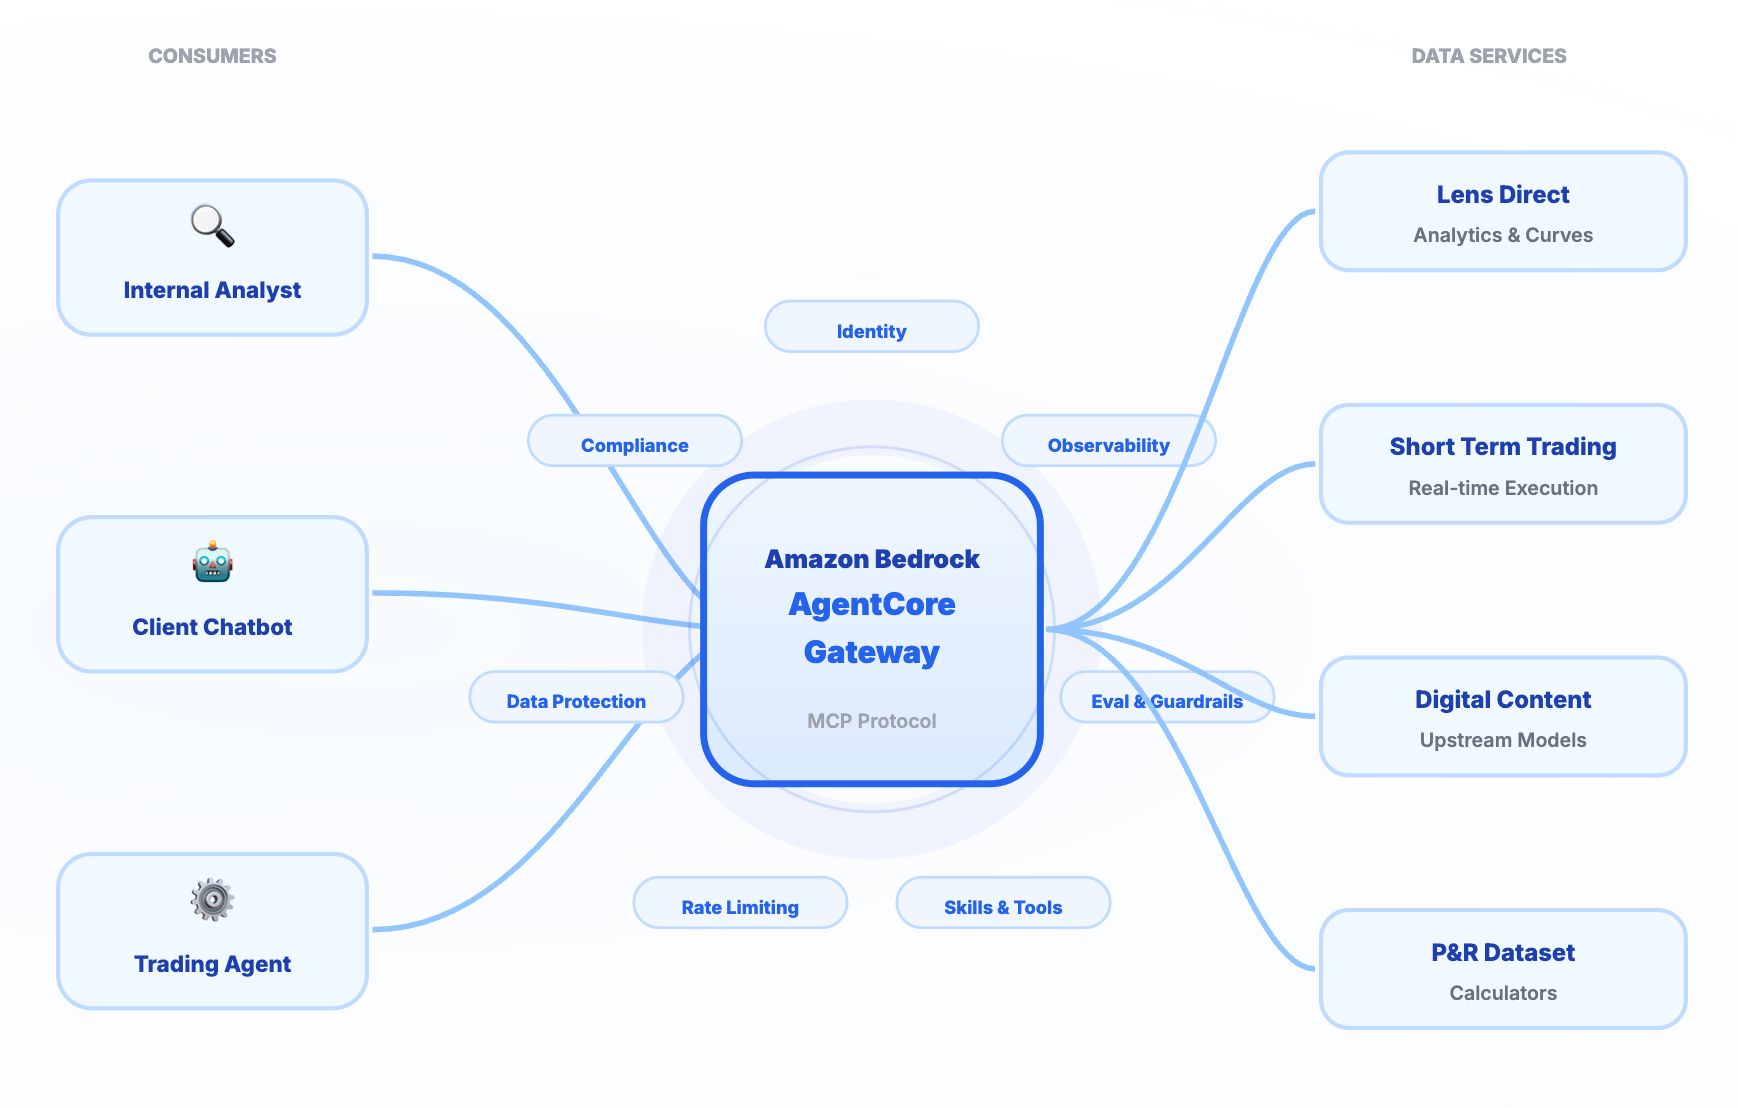
Figure 3: Unified MCP Gateway
Consumers (internal analyst, client chatbot, trading agent) connect through a single Amazon Bedrock AgentCore Gateway speaking the MCP protocol, which fans out to data services (Lens Direct, Short Term Trading, Digital Content, P&R Dataset). Cross-cutting concerns are enforced once at the hub.
The gateway speaks the Model Context Protocol (MCP), so it presents a consistent tool interface regardless of what sits behind each spoke. AgentCore Gateway turns existing APIs, AWS Lambda functions, and existing MCP servers into agent-compatible tools, and acts as a single secure endpoint for agents to discover and invoke those tools without custom integration code. It supports IAM, OAuth 2.1, and API key authentication, and AWS partner tools procured through AWS Marketplace can be imported into the gateway directly.
Because traffic funnels through one hub, the cross-cutting concerns are enforced once at the gateway rather than re-implemented in every consumer or spoke: identity, observability, evaluation and guardrails, skills and tools, rate limiting, data protection, and compliance. A policy change applies everywhere the moment it lands at the hub, and every tool call inherits the same identity context, the same telemetry, and the same guardrails. This is also where the MCP server option matters for external access: exposing our data services through a governed MCP endpoint means partners can reach them through a single, controlled interface for direct AI-powered data access rather than through a sprawl of point integrations.
Generative UI: Dynamic components with AG-UI, A2UI, and Strands
A platform is only useful if the agent can surface its work to a user, and rebuilding a streaming, stateful interface for every agent would reintroduce the exact duplication APEX exists to remove. We solve the presentation layer the same way we solved connectivity: with shared protocols. The APEX frontend SDK is built on two complementary protocols, with CopilotKit providing the web components and tooling.
AG-UI is the transport. It’s the bi-directional, event-driven runtime connection between an agentic backend and a user-facing application, carrying a stream of typed events such as token streaming, tool calls, and state updates over standard HTTP or Server-Sent Events. It works across stacks, from web to mobile to the command line.
A2UI is the payload. It’s a declarative generative UI specification, originated by Google, that an agent uses to return UI as a JSON blueprint of components rather than text or executable code. The client renders each component from its own catalog of trusted, native widgets, which keeps the UI matched to the host application’s styling and avoids arbitrary code execution. AG-UI carries A2UI blueprints to the frontend, and CopilotKit supports A2UI as a launch partner. In short, A2UI describes what the agent wants to display, AG-UI delivers it, and the client renders it.
The agents themselves are Strands agents running in AgentCore runtime. Strands integrates with AG-UI directly, and the combination gives us three capabilities that the ST Trading App, Lens AI, and Woody all reuse rather than rebuild.
Streaming chat. AG-UI handles the streaming of messages between users and the agent, so a conversational surface is a configured component rather than a hand-built transport layer.
Tool-based generative UI. This is where dynamic components come from. The agent does not return only text. AG-UI shares tool information with the client, and the client maps a tool invocation to a rendered component. When an agent calls a tool, the frontend renders the matching component with the tool’s arguments, so a curve-analytics request from Lens Direct or a real-time execution result from Short Term Trading comes back as a live widget rather than a wall of text. For richer cases the agent emits an A2UI blueprint and the client renders it from its trusted component catalog, so the agent can compose an interface, a chart, a form, a result card, without the frontend hardcoding it in advance. A tool the agent already exposes becomes a UI element with a small render binding on the client, which is the composable-building-blocks principle applied to the interface: a single widget or a full workflow, assembled from the same parts.
Shared state. Strands agents are stateful, and AG-UI synchronizes that state in both directions. The agent sees changes the user makes in the interface, and the interface reflects state the agent updates, so a user editing a parameter and an agent revising a calculation stay in sync without custom wiring.
Deployment follows the standard AgentCore path. The Strands agent is configured and launched onto AgentCore runtime, which exposes the POST /invocations interaction endpoint and a GET /ping health check. Authentication is handled through AgentCore Identity using an OAuth authorizer backed by Amazon Cognito, so the same identity model that governs tool calls at the gateway also governs the UI session. The frontend then connects to the deployed runtime endpoint with a bearer token, and the generative UI is live in production.
The result is that a team adds a new agent-backed feature by writing agent logic and binding tools and component blueprints, while streaming, state synchronization, identity, and the production runtime all come from the platform.
AG-UI in Lens: Interactive AI on a live dashboard
The clearest example is Synapse AI, the generative AI assistant embedded in our Lens application. A user viewing the Lens Power Summary dashboard can open the assistant in a side panel and ask a question in plain language, such as which countries have the most renewable capacity. The agent does not answer from a generic web search. It calls a tool, extractWidgetConfig, that reads the configuration and data of the ranking widgets already on the dashboard the user is looking at, then returns a ranked table of solar and wind capacity by country rendered inline in the conversation.
This is AG-UI doing exactly what it is for. The agent’s reasoning steps and tool calls stream into the panel as typed events as they happen, so the user sees the agent think and then act rather than waiting on a spinner. The result comes back not as a paragraph but as a structured table the agent composed, rendered by the client from its component catalog. And because the assistant reads the dashboard’s own widget state, the response is grounded in the data the user already trusts, not a disconnected query. The interactive assistant is a configured surface on top of a Strands agent, so Lens got a grounded, streaming, in-context analyst without building a transport layer, a state-sync mechanism, or a rendering pipeline of its own.
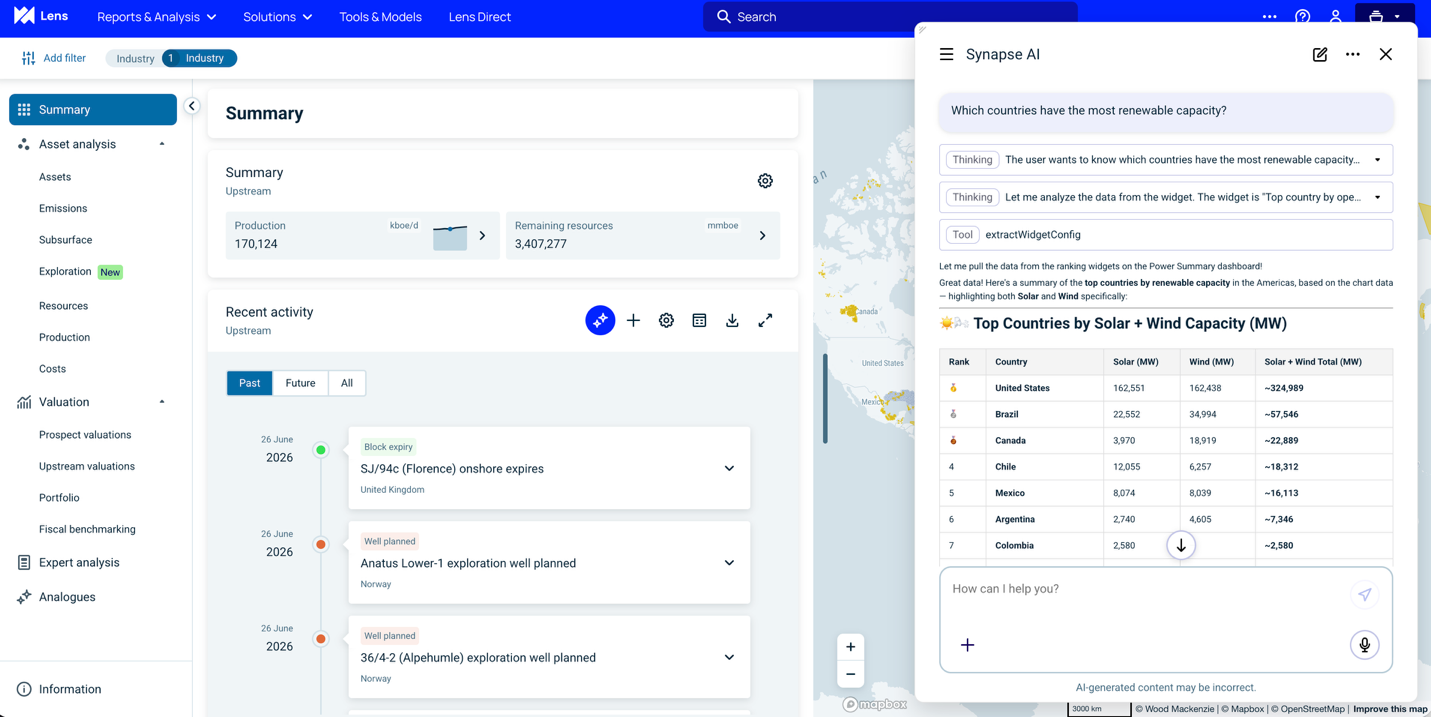
Figure 4: Synapse AI inside Lens
The user asks a question against the Power Summary dashboard. The agent streams its reasoning, calls the extractWidgetConfig tool to read the dashboard’s ranking widgets, and renders a ranked solar-and-wind capacity table inline in the assistant panel.
Woody, our internal Wood Mackenzie application, shows the same protocol carrying a longer-running workflow that chains several tools into a finished deliverable. In one flow, an analyst gives Woody a single instruction: research the impact of the Iran conflict on oil prices using both web sources and the Lens Direct dataset, generate charts, and produce a PowerPoint presentation.
What follows is the agent planning and then executing across multiple tools. It first reasons about the task and checks which tools it has available, then uses them in sequence: a web search agent tool for open source research, the Lens Direct MCP server for our proprietary data, a Vega-Lite charting tool to generate the visualizations, and a PowerPoint generator to assemble the output. The agent streams its reasoning and its access status as it goes, web research complete, Lens Direct data retrieved, then delivers a research package: four interactive charts covering the oil price trajectory, supply disruption and buffer mechanisms, a price-scenario comparison, and Strait of Hormuz flow, plus a downloadable 15-slide presentation. One natural-language request became a coordinated multi-tool workflow ending in an artifact the analyst can use directly.
Two things in this flow matter for the platform argument. First, the agent mixes a public web tool, a proprietary MCP data connector, a charting tool, and a document generator in a single run, and each of those is an independent building block reached through the gateway. Swapping the charting library, adding a new data connector, or pointing the same workflow at a different model does not change the agent’s logic, because the tools are composed rather than hardcoded. Second, the agent reached our proprietary data through the Lens Direct MCP server, the same connector pattern an external consumer would use, which is the bridge to the next point.
Woody also handles higher-stakes operations with the human in the loop. In a separate flow, an analyst asks Woody to create and train an internal natural-gas demand model. The agent works against the model’s GitHub branch and then pauses at an explicit checkpoint, flagging that a GUIDANCE.md file needs review and listing the exact fixes required in train.py or inference.py before training can start, and it will not proceed until the analyst confirms. A Task Tracker side panel renders the live run state, the model parameters such as heating and cooling degree days, gas price, storage levels, and renewable generation, alongside the structured results payload, and stays in sync with the agent through AG-UI shared state. This is the Workflow Designer’s human-in-the-loop pattern enforced at runtime: the agent takes no consequential action without approval, which is the control that lets us give it real responsibility over a model pipeline.
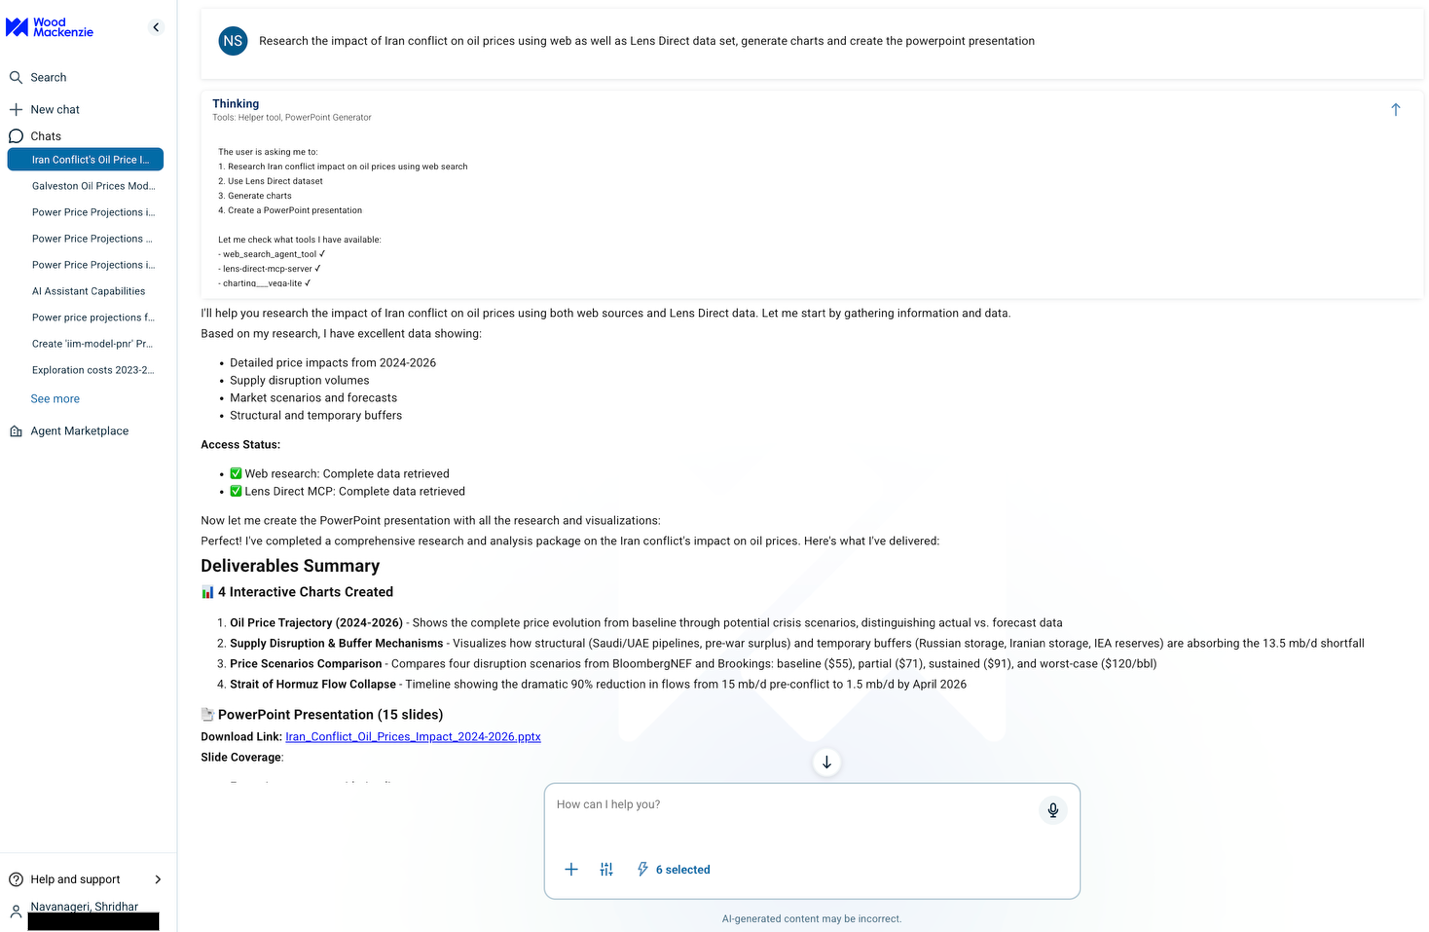
Figure 5: Agentic workflow in Woody
From one instruction, the agent plans across tools, a web search agent, the Lens Direct MCP server, a charting tool, and a PowerPoint generator, then delivers four interactive charts and a fifteen-slide presentation. A separate Woody flow drives model training with a human-in-the-loop checkpoint and a live Task Tracker panel.
One platform, internal and external, governed by entitlements
The Lens and Woody examples run on the same infrastructure. Woody serves internal users, analysts and researchers inside Wood Mackenzie, and Synapse in Lens serves external consumers, while the MCP connectors expose our data to partner systems. All three are the same AgentCore runtime, the same gateway, the same model catalog, and the same observability and guardrails. What differs is not the stack but the access and entitlement controls applied at the hub. Identity is carried through every agent invocation, so the entitlements that govern what an internal analyst can train and deploy are the same mechanism that governs what an external consumer can query and what a partner’s MCP client can reach. We don’t run one platform for employees and a second for customers. We run one platform and let identity-aware authorization decide what each caller sees and does.
That single foundation is what makes the workflows composable in the normal way teams already work. Because agents are registered in the Woodmac Agent Registry, tools and connectors are published through the gateway, and models are selected from the catalog, a team assembles a workflow by picking the agents, tools, and connectors it needs and snapping them together, the same Lego-block model whether the consumer is an internal researcher or an external client. The Iran-conflict research flow and the model-training flow are built from the same shelf of parts in different combinations. Adding a new connector, swapping a tool, or composing two agents into one workflow is a configuration change in APEX Studio, not a re-platforming exercise, and every combination inherits the identity, guardrails, and tracing enforced at the hub.
Platform engineering principles
APEX isn’t only an architecture diagram. It is governed by six principles that determine how we build and operate it.
Composable building blocks. Every capability is an independent block that works alone or compounds into a larger workflow. A team can take only AgentCore memory, or only the Gateway, or assemble the full set into an autonomous workflow. Pick what you need, snap it together, ship a product.
Fuel the flywheel. Solving a problem for one team produces a generalized solution for all of them. When we built identity-aware tool access for Lens AI, the ST Trading App inherited it.
Abstract the undifferentiated heavy lifting. Security, compliance, infrastructure, data, and AI are centralized in the platform so product teams spend their time on what differentiates their product, not on undifferentiated plumbing. The unified MCP Gateway is the clearest example: identity, rate limiting, and compliance are enforced once at the hub, not rebuilt in every consumer.
Componentize for reuse. Golden paths and reusable SDKs alleviate boilerplate. The frontend SDK and the agent registry are how a new team starts from a paved path instead of a blank page.
Decoupled evolution. We keep a strict separation between platform code and business logic. Because AgentCore services are managed and versioned independently, we can upgrade the platform underneath a team without disrupting its agent.
Compounding value. More adoption lowers the marginal cost of the next innovation. The platform is a value multiplier: each team that joins makes the next team faster.
Where this goes next: Multi-agent systems
The single agent is the starting point, not the destination. The clear industry direction through 2026 is multi-agent systems, where agents owned by different teams, and eventually different organizations, coordinate to complete work that no single agent can. That shift turns on two open protocols that sit at different layers. MCP is the vertical layer that connects an agent to tools and data, which is what our gateway already standardizes. The Agent-to-Agent (A2A) protocol is the horizontal layer that lets agents discover, delegate to, and collaborate with one another. The two-layer stack, MCP for tools and A2A for agents, is becoming the default architecture for enterprise agent deployments, A2A has moved to Linux Foundation governance with broad vendor backing, and AgentCore runtime already supports A2A.
APEX is built to grow into this rather than be rebuilt for it. Because every agent is registered in the Woodmac Agent Registry and reached through governed endpoints, a Lens analytics agent, a Short Term Trading execution agent, and a research agent can be composed into a single workflow where one agent delegates a subtask to another, and every hop still carries the same identity context, guardrails, and tracing enforced at the hub. The composable-building-blocks principle that lets us assemble tools into one agent today is the same principle that will let us assemble agents into a team tomorrow.
Three concrete extensions follow from the architecture already in place. First, agent-to-agent workflows across our own domains, so a trading question can pull a curve from the analytics agent and a calculation from the P&R agent without a human stitching the steps together. Second, governed external collaboration, where the same MCP server endpoint that gives partners direct data access can expose select agents for cross-organization A2A coordination under the entitlements and audit trail we already enforce. Third, deeper autonomy with control, pairing AgentCore Evaluations on live traffic with Policy enforcement on every tool call so that as agents take on longer-running, higher-stakes tasks, the guardrails scale with them. The platform layer absorbs each of these as a new capability, not a rewrite, which is the whole point of building it once.
Conclusion
Most agent programs stall not because the model is inadequate but because the infrastructure around it is missing: no shared runtime, no consistent evaluation, no governed identity, and duplicated plumbing rebuilt for every use case. By standardizing on Amazon Bedrock AgentCore, we turned three parallel agent-building efforts into one shared platform. A team can now build an agent in hours rather than months, swap models without touching business logic, and ship to production with guardrails, tracing, identity, and evaluation in place from the first invocation. The platform layer is managed and model-agnostic, scales automatically, and bills only for the resources each agent actually consumes.
The result is that our teams spend their time on the business logic that differentiates the energy products our customers use, and not on rebuilding authentication, memory, and observability for the fourth time. As more teams adopt APEX the marginal cost of the next agent keeps falling, and because the platform is built on the open MCP and A2A protocols, the same foundation that runs single agents today extends to the multi-agent systems coming next. To learn more, explore the Amazon Bedrock AgentCore documentation, review AgentCore pricing, or leave a comment.
About the authors
Shridhar Navanageri
Shridhar is the VP of architecture, Platform Engineering, and AI at Wood Mackenzie. With over two decades of cloud and engineering leadership across global enterprises, he directs the strategy and production deployment of enterprise agentic AI architectures, centralized platform tools, developer experience, and modern data ecosystems. At Wood Mackenzie, Shridhar leads the design of scaled AI workflow platforms built on Amazon Bedrock AgentCore, leveraging agentic orchestration, Model Context Protocol (MCP) integrations, and advanced RAG systems, and serverless gateway architectures to transform how energy analytics are delivered.
Andrew Brown
Andrew is a Sr. Solutions Architect who has been working at AWS in the Energy Industry for over five years. He is a member of the AI/ML Technical Field Community and specializes in Deep Learning and High Performance Computing.