insight Simon Willison 2026-09-23T17:12 正文 ok 171 words

Gemini 3.8 TTS Playground

英文标题:Gemini 3.8 TTS Playground

Google 发布了两款新的 Gemini 文本转语音模型:`gemini-3.8-flash-tts` 与 `gemini-3.8-flash-lite-tts`。两款模型提供超过 2,000 种语音,并支持仅使用 30 秒、且用户拥有使用权的音频样本创建自定义声音。本文作者利用 Gemini API 开放的 CORS 策略,通过 GPT-6 Astra 快速开发了一个自带 API Key 的多说话人 TTS Playground。实测显示,使用 Gemini 3.8 Flash TTS 生成 1 分 18 秒音频约需 20 秒,成本为 2.74 美分,为开发者构建多角色语音应用提供了较直接的 API 能力与成本参考。
打开原文相关 4.8 · 机会 3
media96.7 KB

中文

Google 今日发布了两款新的 Gemini 文本转语音模型:gemini-3.8-flash-tts 和 gemini-3.8-flash-lite-tts。

它们提供了超过 2,000 种声音的语音库,并支持仅使用“一段 30 秒的、属于你本人声音或你拥有使用权的声音音频样本”创建自定义声音。

我借助 GPT-6 Astra,以 vibe coding 的方式开发了这个自带 API Key 的 Playground 界面,并利用了底层 Gemini API 开放的 CORS 策略。
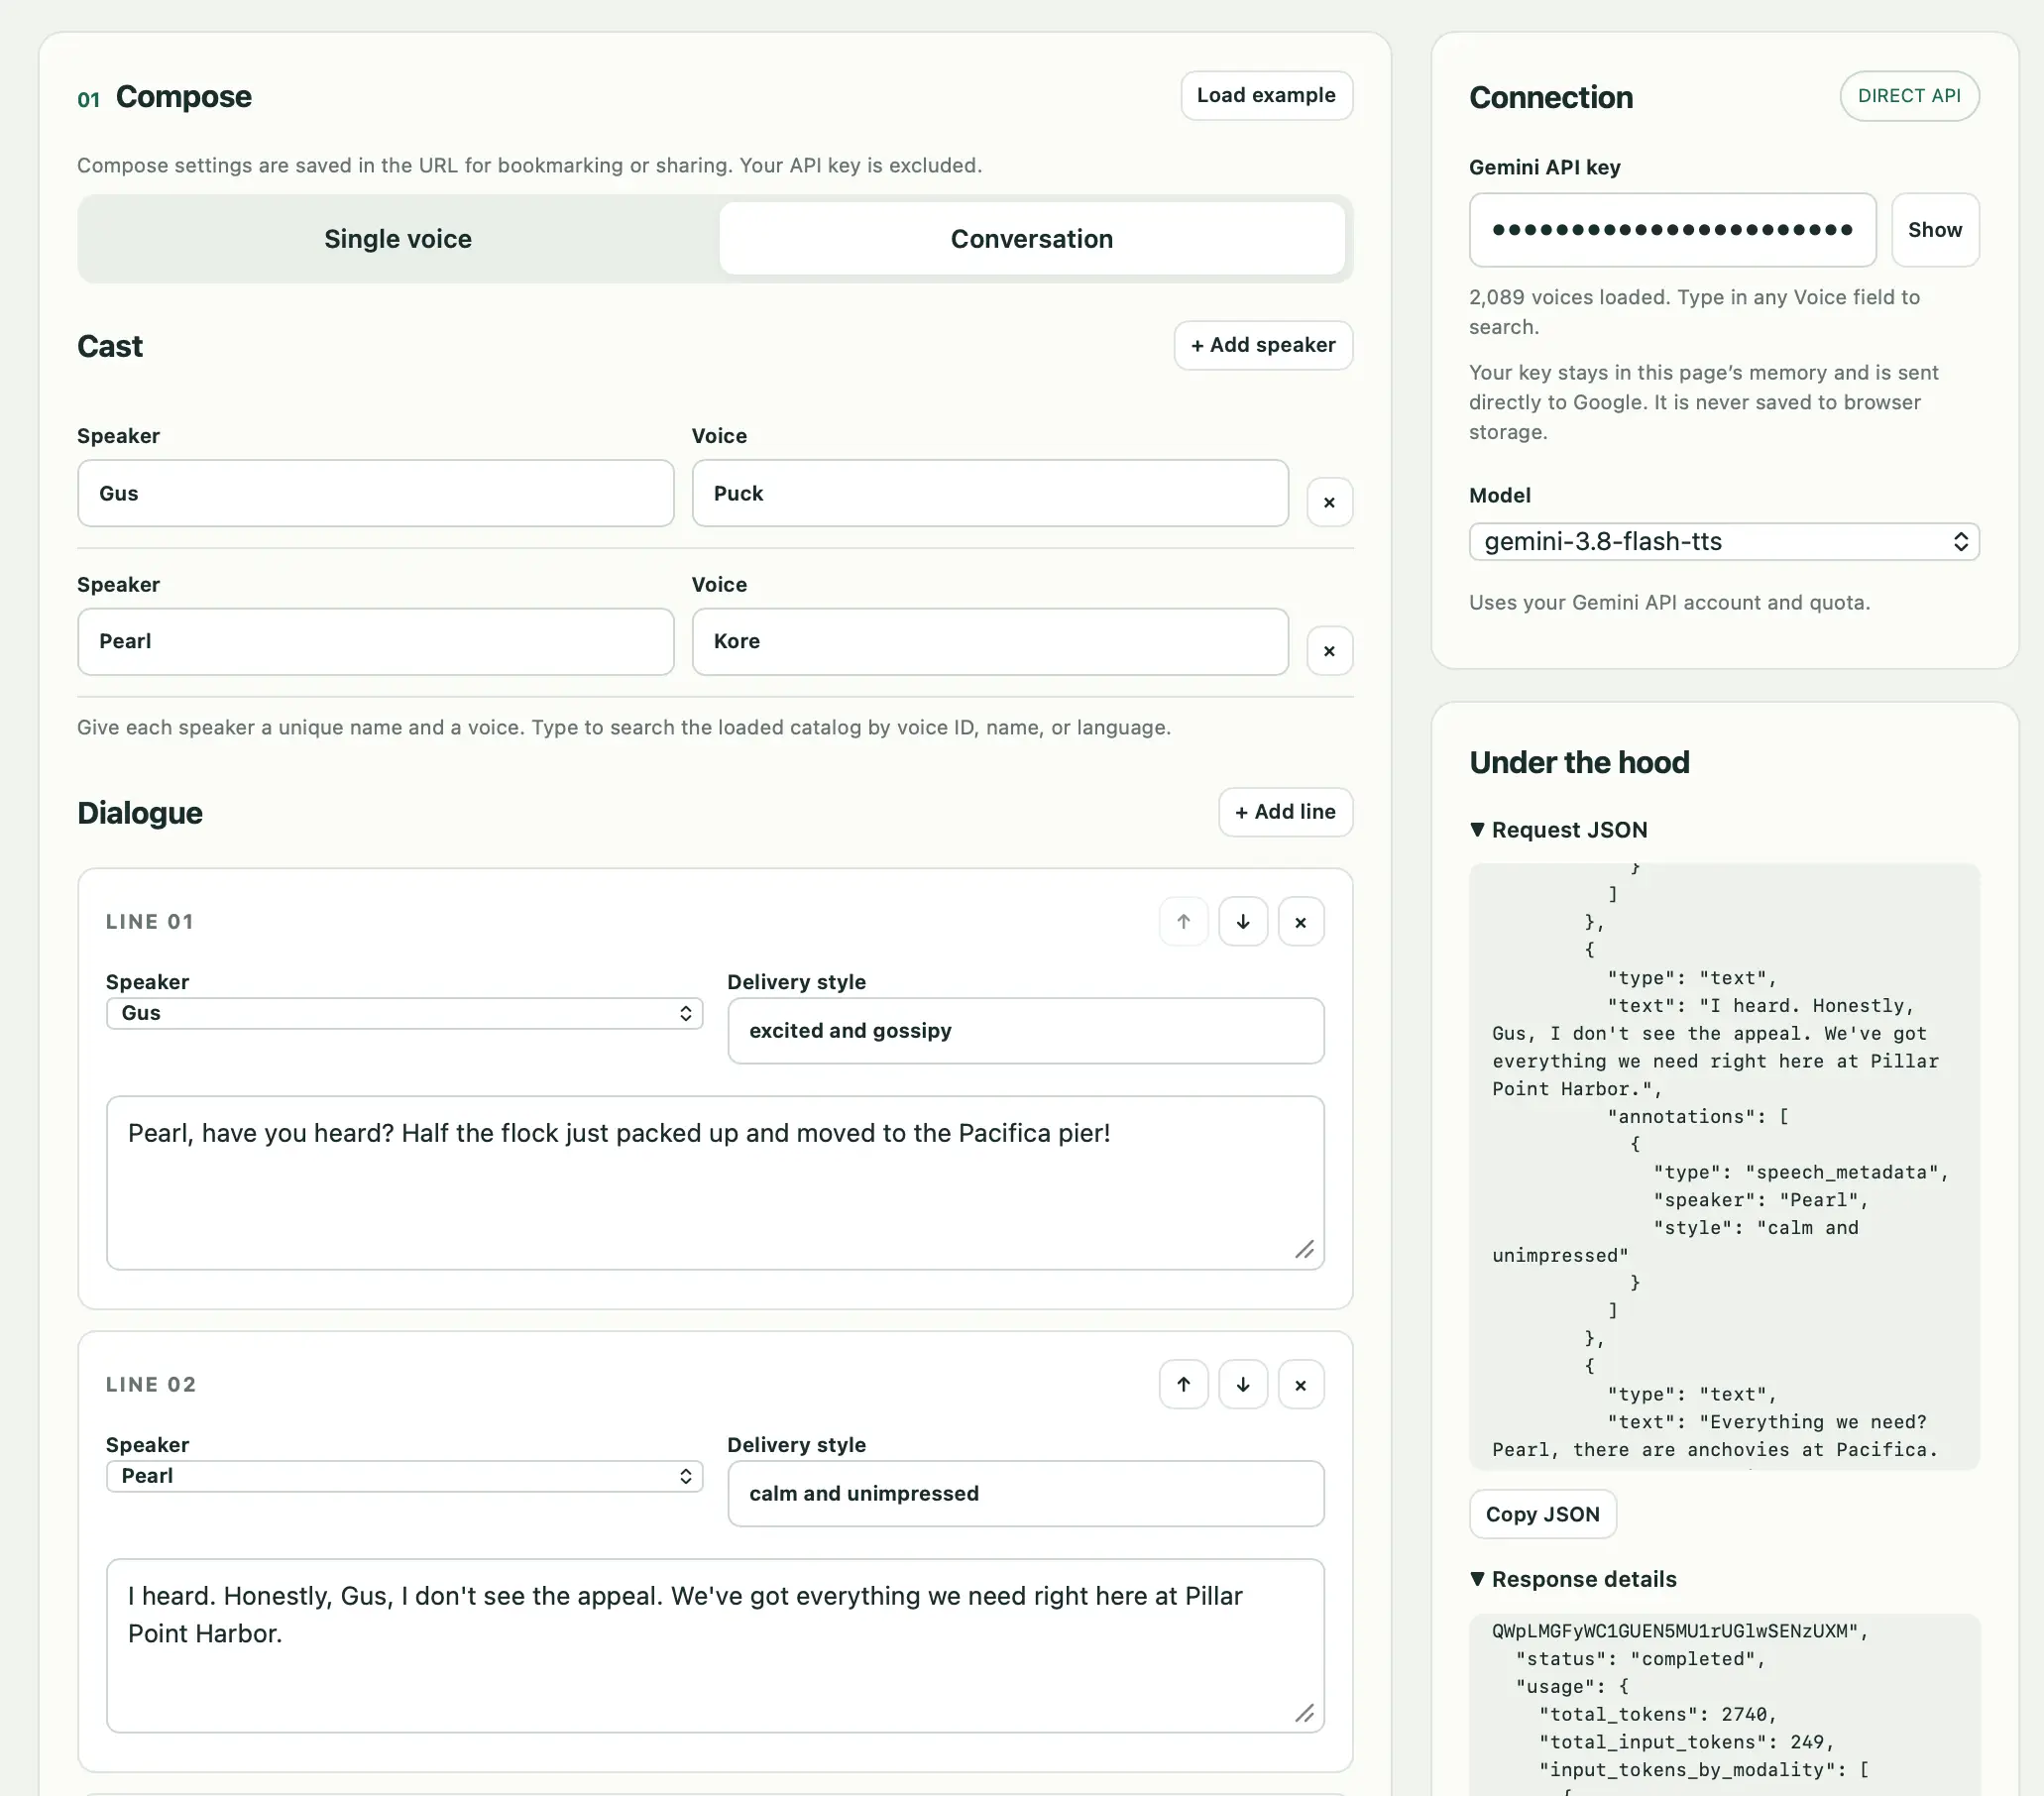
用于编写多说话人文本转语音对话的 Web 应用截图,左侧为 Compose 面板,右侧为 Connection 和 Under the hood 面板。左侧面板:“01 Compose”,包含“Load example”按钮;提示“Compose 设置会保存在 URL 中,以便收藏或分享。你的 API key 不会被包含。”切换项包括“Single voice”和“Conversation”(已选择 Conversation)。在“Cast”区域,有“+ Add speaker”按钮;说话人“Gus”,声音为“Puck”,带有删除 × 按钮;说话人“Pearl”,声音为“Kore”,带有删除 × 按钮。提示文字为:“为每位说话人设置唯一名称和声音。可在任意 Voice 字段中输入内容,按 voice ID、名称或语言搜索已加载的语音目录。”在“Dialogue”区域,有“+ Add line”按钮。“LINE 01”带有上移、下移和 × 按钮;Speaker 下拉框为“Gus”;Delivery style 为“excited and gossipy”;文本为“Pearl, have you heard? Half the flock just packed up and moved to the Pacifica pier!”。“LINE 02”带有上移、下移和 × 按钮;Speaker 下拉框为“Pearl”;Delivery style 为“calm and unimpressed”;文本为“I heard. Honestly, Gus, I don't see the appeal. We've got everything we need right here at Pillar Point Harbor.”右侧面板:“Connection”,带有“DIRECT API”徽标;“Gemini API key”字段显示为掩码圆点,并有“Show”按钮;提示“已加载 2,089 种声音。可在任意 Voice 字段中输入内容进行搜索。”以及“你的密钥仅保留在当前页面内存中,并直接发送给 Google,绝不会保存至浏览器存储。”Model 下拉框为“gemini-3.8-flash-tts”,并注明“使用你的 Gemini API 账户和配额。”在“Under the hood”面板中,展开的“▼ Request JSON”区域展示 JSON 代码片段和“Copy JSON”按钮;展开的“▼ Response details”区域展示 JSON 代码片段。

该 API 的一个值得注意的特性是:它可以轻松定义由多个角色参与的完整对话,并为每个角色分别指定不同的声音和语音风格指令。

下面是一段简短的音频演示:两只鹈鹕正在讨论是否应搬去Pacifica Pier。我让 Claude 4.5 Opus 编写脚本,并生成了一个使用该工具渲染脚本的 URL。

您的浏览器不支持 audio 元素。

使用 Gemini 3.8 Flash TTS(而非价格更低的 Flash-Lite)生成 1 分 18 秒音频大约需要 20 秒,成本为 2.74 美分。

English / 原文

Google released two new Gemini text-to-speech models today - gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts.

They come with a library of over 2,000 voices, plus the ability to create a custom voice with "just a 30-second audio sample of your voice or a voice you have the rights to use".

I vibe coded this bring-your-own-key playground interface with GPT-6 Astra, taking advantage of the open CORS policy of the underlying Gemini API.

Screenshot of a web app for composing multi-speaker text-to-speech conversations, with a Compose panel on the left and Connection and Under the hood panels on the right. Left panel: "01 Compose" with a "Load example" button. "Compose settings are saved in the URL for bookmarking or sharing. Your API key is excluded." Toggle with "Single voice" and "Conversation" (Conversation selected). "Cast" section with "+ Add speaker" button. Speaker "Gus", Voice "Puck", with a remove × button. Speaker "Pearl", Voice "Kore", with a remove × button. "Give each speaker a unique name and a voice. Type to search the loaded catalog by voice ID, name, or language." "Dialogue" section with "+ Add line" button. "LINE 01" with up, down and × buttons; Speaker dropdown "Gus"; Delivery style "excited and gossipy"; text "Pearl, have you heard? Half the flock just packed up and moved to the Pacifica pier!" "LINE 02" with up, down and × buttons; Speaker dropdown "Pearl"; Delivery style "calm and unimpressed"; text "I heard. Honestly, Gus, I don't see the appeal. We've got everything we need right here at Pillar Point Harbor." Right panel: "Connection" with a "DIRECT API" badge. "Gemini API key" field showing masked dots with a "Show" button. "2,089 voices loaded. Type in any Voice field to search." "Your key stays in this page's memory and is sent directly to Google. It is never saved to browser storage." "Model" dropdown "gemini-3.8-flash-tts". "Uses your Gemini API account and quota." "Under the hood" panel with an expanded "▼ Request JSON" section showing a JSON code excerpt, a "Copy JSON" button, and an expanded "▼ Response details" section showing a JSON code excerpt.

A notable feature of the API is that it makes it easy to define a full conversation between multiple characters, each with different voices and voice style instructions.

Here's a short demo clip of a conversation between two pelicans debating if they should move to the Pacifica Pier. I had Claude 4.5 Opus write the script and generate a URL to render it using the tool.

Your browser does not support the audio element.

It took ~20 seconds to generate 1m 18s of audio using Gemini 3.8 Flash TTS (not the cheaper Flash-Lite), at a cost of 2.74 cents.