更好的工具让 Copilot 代码审查变得更糟。我们究竟是如何真正改进它的。
英文标题:Better tools made Copilot code review worse. Here’s how we actually improved it.
GitHub 团队将 Copilot 代码审查从专用代码探索工具迁移到共享的 Unix 风格工具(grep、glob、view)后,基准测试显示审查成本反而上升、发现的问题减少。问题不在工具本身,而在于指导代理的工作流指令。通过将指令调整为围绕拉取请求差异进行聚焦式审查,团队将平均审查成本降低了约 20%,同时保持了审查质量。这一过程展示了为 Agent 打造与产品形态匹配的工作流指令比工具本身更重要。
 75.6 KB
 33.6 KB
 84.8 KB
 40.0 KB
 58.0 KB
 27.6 KB
 124.7 KB
 50.1 KB
 75.4 KB
 34.5 KB
 67.7 KB
 32.0 KB
 84.0 KB
 40.3 KB
 240.4 KB
 33.4 KB
 22.3 KB
 55.8 KB
 36.1 KB
 106.3 KB
中文
给智能体更好的工具,它就应该干得更好。至少直觉上是这样。
当你打开一个拉取请求时,Copilot 代码审查会读取差异(diff)并探索周围代码,在问题发布前找出那些真正重要的。为此,它曾使用自己的代码探索工具。所以,当我们换用维护得更好、支持 Copilot CLI 的共享工具—— grep、glob 和 view 时,我们预计这会是一次干净的升级。
结果,在我们的基准测试中,审查成本反而更高了,捕获的问题也更少了。
但工具本身不是问题。问题出在指令上。一旦我们按照审查者实际阅读拉取请求的方式重写了指令,之前的倒退就变成了胜利:平均审查成本降低约 20%,同时保持了相同的审查质量。
这就是调整围绕工具的工作流如何让我们找到了修复方案的故事。
如果你在某个智能体框架之上构建过应用,你可能也继承了它的工具。它们能工作,所以你会一直留着它们,直到某天你的用例与它们最初的设计目标偏离得足够远,它们开始悄悄地妨碍你。这就是我们当时的处境。在尝试使用共享的 CLI 工具之前,Copilot 代码审查使用自己的代码探索工具。那个工具层受到早期智能体系统的启发,包括 SWE-agent 风格的仓库导航 和 GitHub Copilot Autofix 的思路:列出目录、搜索文件、搜索目录、读取代码。那些工具能用,但它们是专为 Copilot 代码审查定制的,并且是为当时模型的行为方式设计的。早期的智能体编程模型进行的工具调用更少,并且更不擅长自动拉取必要的上下文。这意味着在模型进行的少数工具调用中包含所有相关信息就更加重要。
与此同时,Copilot CLI 框架拥有一套受 Unix 启发的共享代码探索工具:grep、glob 和 view。越来越多的 Copilot 智能体产品也在使用该框架,包括 GitHub Copilot 云智能体,因此框架的改进可以让多个产品受益。我们希望在可能的情况下清理和共享基础设施,于是我们尝试在 Copilot 代码审查中使用来自 Copilot CLI 框架的工具。目标是减少重复的工具实现,创建一个共享的场所来改进代码探索工具,并更容易地将这些改进推广到各个 Copilot 产品中。
从纸面上看,迁移看起来很简单:
| 旧的 Copilot 代码审查 | GitHub Copilot CLI | 用途 |
|---|---|---|
| list_dir | glob | 在打开代码之前发现候选文件和目录。 |
| search_file 和 search_dir | grep | 在代码中搜索匹配的文本、符号或调用点。 |
| read_code | view | 在知道路径或范围后读取相关的文件内容。 |
现有的审查工具并非轻薄封装。当搜索目录或读取代码范围时,它们可以返回匹配或请求的行,外加额外的周围代码上下文。这增加了令牌成本,但也符合早期模型经常因自动包含附近上下文而受益的特点。
最初,我们期望这会是一次简单的迁移:用一组工具替换另一组。但当我们用共享工具进行离线基准测试时,审查智能体变得既低效又低效。平均成本增加了,有用评论的数量下降了。
追踪记录揭示了浏览循环
我们的内部 Copilot 代码审查基准测试很有用,因为它们展示的不仅是最终得分。它们显示了智能体所走的路径,包括它调用了哪些工具、返回了多少输出、在哪里发生了错误,以及它是在缩小证据范围还是在扩大搜索。
当我们首次在离线基准测试中尝试共享的 Copilot CLI 工具时,智能体经常表现得像是在浏览仓库,而不是在调查一个拉取请求。它会广泛搜索、猜测可能的路径、广泛阅读、找到更多要搜索的东西,然后把那些额外的上下文带向下一步。
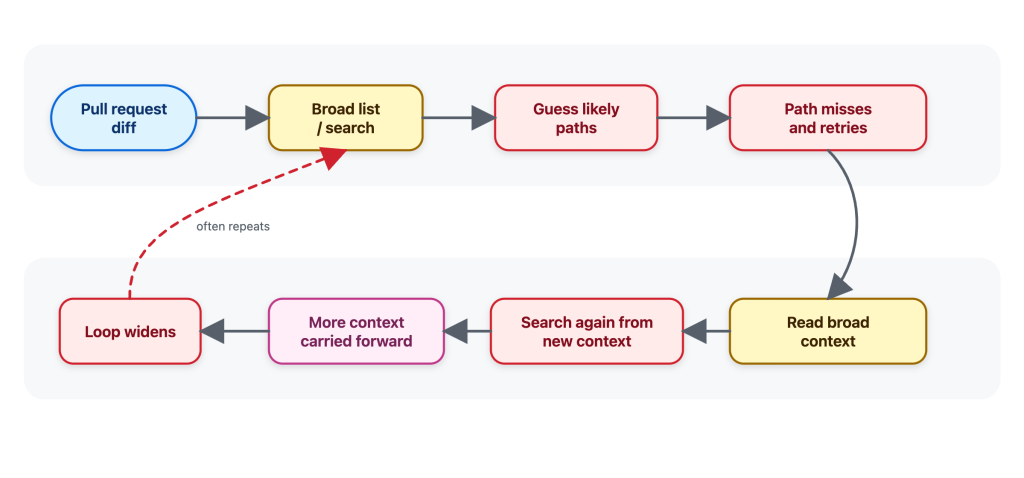 图 1:之前——观察到的通用行为的简化图示:扩大搜索、猜测路径和累积上下文。
这种模式可以理解。当任务是“理解这个仓库”时,广泛的探索可能有用。但这通常不是审查者审查拉取请求的方式。
当我审查一个拉取请求时,我从差异开始并提出有针对性的问题:
- 这个函数在哪里被调用?
- 这个配置键在别处是否被使用?
- 有没有相同模式的测试或辅助函数?
- 能解释此行为的最小附近代码范围是什么?
在知道自己在找什么之前,我并不想打开仓库的很大一部分。我想要回答该问题所需的最小上下文,不要让审查被不相关的代码过载。
这很重要,因为每个工具结果都会成为智能体工作上下文的一部分。额外的文件内容可能会被带到后续的推理中,增加成本,有时还会让审查失去焦点。工具结果不是用完即弃的打印输出;对智能体而言,它是留在上下文窗口中的额外令牌。
追踪记录让这种差异变得可见。共享工具不是问题。指令给了智能体错误的直觉,导致它无法进行高效且有效的审查。
工具本身是能用的,但它们的指令是针对在 Copilot CLI 中的使用而调整的,并暗示了错误的工作流:智能体像使用通用编码助手而非审查者那样使用 grep、glob 和 view。编程助手在进行更改前可能会映射整个区域,以确保它不会破坏代码的某个其他角落。而另一方面,审查者通常从差异开始,询问更改是否引入了问题,然后寻找确认或否定该问题所需的最窄的附近证据。
通用编码辅助工具指令,比如 Copilot CLI 或 Copilot 云智能体使用的那些,对交互式助手很有意义。开发者可能会要求它理解一个仓库、规划一项更改、编辑文件,并在多个回合中继续。
Copilot 代码审查的任务更窄:从拉取请求差异开始,收集足够的周围证据来判断更改是否引入了一个真正的问题,并避免加载对那个审查问题不必要的上下文。
因此很明显,在没有额外提示工作的情况下,我们不能简单地用 Copilot CLI 的工具替换之前的 Copilot 代码审查工具。问题变成了:如何设计能在代码审查场景中有效使用这些共享工具的工具指令?
接下来的迭代让指导变得专门为代码审查而定。我们希望 Copilot 代码审查遵循的工作流是:
- 从差异开始,形成具体的审查问题。
- 在路径不确定时使用
glob,使用grep查找候选文件、符号和调用点。 - 在读取文件之前批量处理廉价的发现操作。
- 只在智能体知道需要哪个文件或行范围时才使用
view。 - 批量进行聚焦的读取,而不是在一次搜索和一次读取之间交替。
用过度简化的形式来说,这就是我们编码的行为:
通用姿态: 使用可用工具来检查可能相关的仓库上下文。
审查形态指导: 从差异开始。首先用 grep 和 glob 缩小范围;用 view 读取确切的证据。如果 grep 未能找到相关上下文,用更简单的转义搜索重试。如果路径错误,转向 glob 而不是猜测附近的路径。
例如,设想差异更改了一个授权辅助函数,它决定一个操作是否被允许。一个相关的审查问题不是“向我展示调用此辅助函数的每个文件的完整内容”。它可以是更窄的问题:“是否有任何处理请求的调用方依赖于旧的行为?”
预期的路径很短:
从差异中更改的辅助函数开始
用 grep 查找该辅助函数的调用方
用 glob 查找可能的路由、处理程序或控制器文件
用 view 读取最相关的调用方范围
判断是否有任何调用方改变了风险
指导还改变了智能体从失败的搜索中恢复的方式。如果某个输入导致 grep 失败,更好的下一步是一次更简单、纠正后的搜索。如果路径错误,更好的下一步是 glob,而不是猜测邻近的路径并读取碰巧存在的任何内容。这促使智能体避免让小工具故障演变成更大的探索循环。
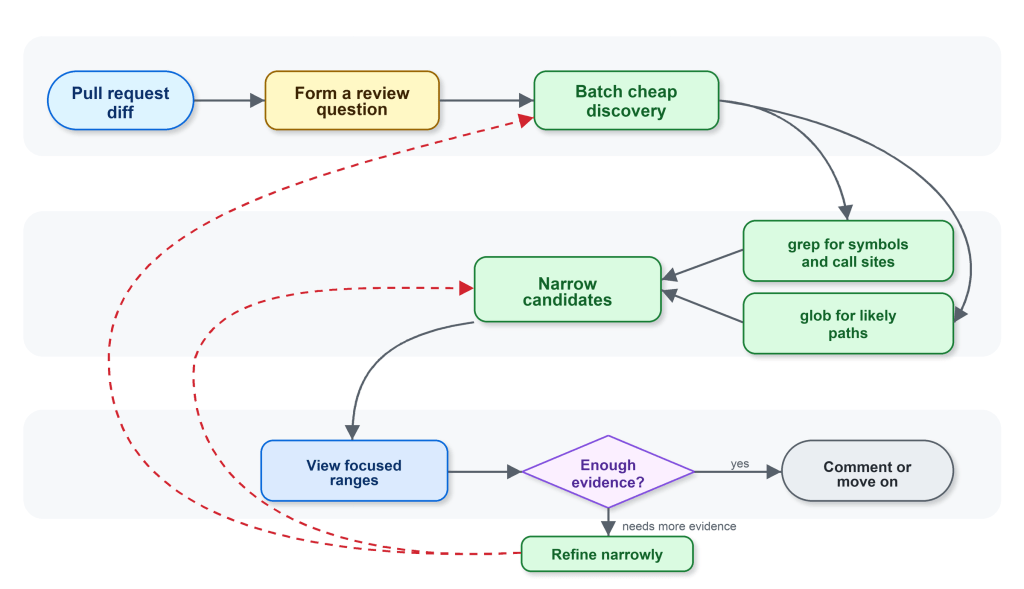 图 2:之后——提示引导出的审查形态行为的简化图示:锚定于差异,用 grep 和 glob 缩小范围,然后用 view 读取聚焦的范围。
改变在措辞上很小,但在效果上很大。它改变了智能体的节奏,从“浏览、读取、再次搜索”变成了“提问、缩小、读取、决定”。
基准测试让我们调试行为,而不仅仅是分数
共享框架给了我们工具。内部 Copilot 代码审查基准测试给了我们反馈回路。
我们可以运行相同的审查示例,比较工具追踪记录,更新指令,然后再次运行。这让我们能够提出具体的问题:
- 智能体是先缩小范围,还是先广泛阅读?
- 它是否批量处理了独立的搜索?
- 它是否只在有理由时才调用
view? - 工具指令的更改是减少了工具错误,还是仅仅把它们转移到了别处?
- 追踪记录是否始终聚焦在来自差异的证据上?
- 审查是否仍然保留了我们所关心的质量指标?
最有用的信号不是“指令变得更好了”。它更具体。智能体进行的工具调用次数相似,但将更多时间花在了相关证据上,而不是反复扩大搜索。
这将产品层面的结果与可理解的工程行为联系了起来。我们不用猜测分数为什么变动,而是可以检查产生该分数的工作流。
结果:平均审查成本降低约 20%
在生产环境中,调整后的行为显示平均审查成本降低约 20%,与对照组相比。重要的是,它没有显示出任何可能阻碍发布的质量信号。
这种降低并非来自工具本身,而是来自围绕工具的工作流。共享的代码探索工具、Copilot 代码审查定制的工具指令和内部基准测试让智能体的行为变得足够可见,可以进行调整。
这种认知方式在使用智能体构建时很重要。人们很容易将工具视为实现细节,用另一个工具替换一个工具,然后比较最终答案。但对智能体而言,工具界面是产品体验的一部分。它改变了智能体会注意到什么、如何搜索、携带多少上下文、以及何时决定证据足够。
工具描述和系统指令更接近于 API 文档。不清晰的 API 文档会让开发者感到困惑,并导致低效或错误的决策。不清晰的工具提示对 LLM 也会产生同样的效果;措辞上的微小变化可能影响成本、质量和调查的形态,因为它改变了智能体分配注意力的方式。
我们还尝试在 CLI 中应用同样的聚焦式工具指令,但并未产生类似的胜利。这是一个有用的反例,也是对该经验的一个重要保障。
Copilot 代码审查锚定于一个差异和一个审查问题。Copilot CLI 处理更广泛的交互式编程任务,其中探索可能是工作的一部分。可能没有单一的差异锚点,用户可能在多个回合中改变方向,合适的上下在开始时可能并不明显。同样的 grep、glob 和 view 工具可以支持这两个产品,但围绕这些工具的工作流必须与产品匹配。
结论是,当指令和基准测试与工作匹配时,共享工具才能规模化。
作者
Napalys Klicius 是 GitHub 的软件工程师,专注于构建智能体系统。他的职业生涯从模型检查到低级 C++ 无人机系统和静态分析,最近更多地转向教导智能体如何检查代码而不迷失方向。
English / 原文
Give an agent better tools and it should do better work. That’s the instinct, anyway.
When you open a pull request, Copilot code review reads the diff and explores the surrounding code to find the problems that matter before they ship. To do that, it used its own code exploration tools. So when we swapped in the better-maintained, shared tools that power the Copilot CLI, grep, glob, and view, we expected a clean upgrade.
Instead, in our benchmarks, we found that the cost of reviews was higher and fewer issues were being caught.
But the tools weren’t the problem. The instructions were. Once we rewrote them for the way a reviewer actually reads a pull request, the regression flipped into a win: roughly 20% lower average review cost , while maintaining the same review quality.
This is the story of how adjusting the workflows around the tools led us to a fix.
If you’ve built on top of an agent framework, you’ve probably inherited its tools too. They work, so you keep them, until the day your use case drifts far enough from what they were designed for that they quietly start working against you. That’s the situation we were in. Before trying to use the shared CLI tools, Copilot code review used its own code exploration tools. That tool layer was inspired by earlier agentic systems, including ideas from SWE-agent-style repository navigation and GitHub Copilot Autofix: list directories, search files, search directories, and read code. Those tools worked, but they were specific to Copilot code review, and they were designed for how models behaved at the time. Earlier agentic coding models made fewer tool calls and were worse at automatically pulling in necessary context. This meant it was more important to include all relevant information in the few tool calls that the model made.
Meanwhile, the Copilot CLI harness has a shared set of Unix-inspired code exploration tools: grep, glob, and view. That harness is also used by a growing number of Copilot agent products, including GitHub Copilot cloud agent, so harness improvements can benefit more than one product. We wanted to clean up and share infrastructure where possible, so we experimented with using the tools from the Copilot CLI harness in Copilot code review. The goal was to reduce duplicated tool implementations, create one shared place to improve code exploration tools, and make it easier to carry those improvements across Copilot products.
On paper, the migration looked simple:
| Old Copilot code review | GitHub Copilot CLI | Purpose |
|---|---|---|
| list_dir | glob | Discover candidate files and directories before opening code. |
| search_file and search_dir | grep | Search code for matching text, symbols, or call sites. |
| read_code | view | Read the relevant file contents once a path or range is known. |
The existing review tools were not thin wrappers. When searching for a directory or reading a code range, they could return the matched or requested lines plus extra surrounding code context. That added token cost, but it also matched how earlier models often benefited from having nearby context included automatically.
Initially, we hoped this would be a simple migration: swap one set of tools for another. But when we tested the shared tools in offline benchmarks, the review agent became less efficient and less effective. Average cost increased, and the number of useful comments dropped.
The trace revealed a browsing loop
Our internal Copilot code review benchmarks were useful because they show more than a final score. They show the path the agent took, including which tools it called, how much output came back, where errors happened, and whether it was narrowing toward evidence or widening the search.
When we first tried the shared Copilot CLI tools in offline benchmarks, the agent often behaved as if it was browsing a repository instead of investigating a pull request. It would search broadly, guess likely paths, read broadly, find more things to search, and carry that extra context forward.
Figure 1: Before — a simplified illustration of the general-purpose behavior we observed: widening the search, guessing paths, and accumulating context.
That pattern is understandable. Broad exploration can be useful when the task is “understand this repo.” But it’s not how a reviewer would usually review a pull request.
When I review a pull request, I start from the diff and ask targeted questions:
- Where is this function called?
- Is this config key used anywhere else?
- Is there a test or helper with the same pattern?
- What is the smallest nearby code range that explains this behavior?
I do not want to open a large part of the repository before I know what I am looking for. I want the minimal context needed to answer the question, without overloading the review with unrelated code.
That matters because every tool result becomes part of the agent’s working context. Extra file contents can be carried forward into later reasoning, increasing cost and sometimes making the review less focused. A tool result is not a disposable printout; for an agent, it’s extra tokens that stay in the context window.
The traces made that difference visible. The shared tools were not the problem. The instructions were giving the agent the wrong instincts to do an efficient and effective review.
The tools themselves worked, but their instructions were tuned for their use within the Copilot CLI and implied the wrong workflow: the agent used grep, glob, and view like a broad coding assistant instead of a reviewer. A coding assistant may map a whole area before making a change to ensure it doesn’t break some other corner of the code. On the other hand, a reviewer usually starts from the diff, asks whether the change introduced a problem, and then looks for the narrowest nearby evidence required to confirm or dismiss it.
General coding-assistant tool instructions, like the ones used by Copilot CLI or Copilot cloud agent, make sense for an interactive assistant. A developer may ask it to understand a repository, plan a change, edit files, and continue over multiple turns.
Copilot code review has a narrower job: start from a pull request diff, gather enough surrounding evidence to decide whether a change introduces a real issue, and avoid loading context that is not needed for that review question.
It was therefore clear that we couldn’t simply replace the previous Copilot code review tools with the tools from the Copilot CLI without additional prompting work. The problem became: how do we design tool instructions that use these shared tools effectively in a code review setting?
The next iterations made the guidance specific to code review. The workflow we wanted Copilot code review to follow was:
- Start from the diff and form specific review questions.
- Use
globwhen the path is uncertain andgrepto find candidate files, symbols, and call sites. - Batch cheap discovery before reading files.
- Use
viewonly when the agent knows which file or line range it needs. - Batch focused reads instead of alternating between one search and one read.
In oversimplified form, this was the behavior we encoded:
Generic posture: Use the available tools to inspect repository context that may be relevant.
Review-shaped guidance: Start from the diff. Narrow first with grep and glob; read exact evidence with view. If grep fails to find relevant context, retry with a simpler escaped search. If a path is wrong, pivot to glob instead of guessing nearby paths.
For example, imagine the diff changes an authorization helper that decides whether an operation is allowed. A relevant review question is not “show me the full contents of every file that calls this helper.” It could instead be the narrower: “are any request-handling callers relying on the old behavior?”
The intended path is short:
start from the helper changed in the diff
grep for callers of that helper
glob for likely route, handler, or controller files
view the most relevant caller ranges
decide whether any caller changes the risk
The guidance also changed how the agent recovered from failed searches. If an input made grep fail, the better next step was one simpler, corrected search. If a path was wrong, the better next step was glob, not guessing neighboring paths and reading whatever happened to exist. That nudged the agent away from letting a small tool failure turn into a larger exploration loop.
Figure 2: After — a simplified illustration of the review-shaped behavior the prompt guided toward: stay anchored to the diff, narrow with grep and glob, then read focused ranges with view.
The change was small in wording and large in effect. It changed the rhythm of the agent from “browse, read, search again” to “ask, narrow, read, decide.”
Benchmarks let us debug behavior, not just scores
The shared harness gave us the tools. The internal Copilot code review benchmarks gave us the feedback loop.
We could run the same review examples, compare tool traces, update the instructions, and run again. That let us ask concrete questions:
- Did the agent narrow first, or read broadly first?
- Did it batch independent searches?
- Did it call
viewonly when it had a reason? - Did a tool-instruction change reduce tool errors, or just move them somewhere else?
- Did the trace stay focused on evidence from the diff?
- Did the review still preserve the quality metrics we cared about?
The most useful signal was not “the instructions are better.” It was more concrete. The agent was making a similar number of tool calls, but spending more of them on relevant evidence instead of repeatedly expanding the search.
That connected product-level outcomes to understandable engineering behavior. Instead of guessing why a score moved, we could inspect the workflow that produced it.
The result: roughly 20% lower average review cost
In production, the tuned behavior showed roughly 20% lower average review cost compared with the control. Importantly, it did not show a quality signal that could block shipping.
The reduction did not come from the tools by themselves, it came from the workflow around them. Shared code exploration tools, Copilot code review custom tool instructions, and internal benchmarks made the agent’s behavior visible enough to tune.
That framing matters when building with agents. It can be tempting to treat tools as implementation details by swapping one tool for another, then comparing the final answer. But for an agent, the tool surface is part of the product experience. It changes what the agent notices, how it searches, how much context it carries forward, and when it decides it has enough evidence.
Tool descriptions and system instructions are closer to API documentation. Unclear API docs can leave a developer confused and lead to inefficient or wrong decisions. Unclear tool prompting can do the same for an LLM; a small wording change can affect cost, quality, and the shape of the investigation because it changes how the agent spends its attention.
We also tried to apply the same kind of focused tool instructions in the CLI, where it did not produce the same kind of win. That is a useful counterexample, and an important guardrail for the lesson.
Copilot code review is anchored to a diff and a review question. Copilot CLI handles broader, interactive coding tasks where exploration can be part of the job. There may be no single diff anchor, the user may change direction over multiple turns, and the right context may not be obvious at the start. The same grep, glob, and view tools can support both products, but the workflow around those tools has to match the product.
The takeaway is that shared tools scale when the instructions and benchmarks match the job.
Written by
Napalys Klicius is a Software Engineer at GitHub building agentic systems. His career has taken him from model checking to low-level C++ drone systems and static analysis, and more recently to teaching agents how to inspect code without getting lost.